
The metadata extraction framework extracts standard and custom metadata from a Salesforce org. Data 360 stores the metadata in a metadata data lake object (mDLO). A metadata extraction pipeline monitors the metadata's lifecycle, extraction, and ingestion into the catalog. The extraction pipeline handles bulk (Day 0), incremental metadata ingestion, and refresh between the Salesforce org and Data 360.
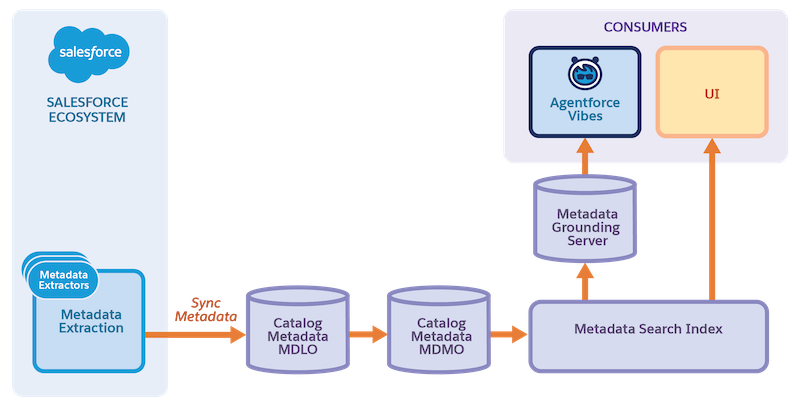
After you turn on Salesforce Catalog, Data 360 runs an initial full sync to extract and ingest your org's metadata. Provisioning the catalog can take time depending on the size of your org.
After the initial sync completes, Salesforce Catalog keeps your metadata current through two mechanisms:
- Incremental metadata sync: For supported metadata types, Salesforce Catalog detects changes as they happen, such as adding a custom field, modifying an object, or updating an agent definition. It updates the catalog without waiting for the next scheduled refresh.
- Daily full refresh: Every 24 hours, Salesforce Catalog runs a complete metadata refresh to ensure coverage across all metadata types, including types not yet supported by incremental sync.