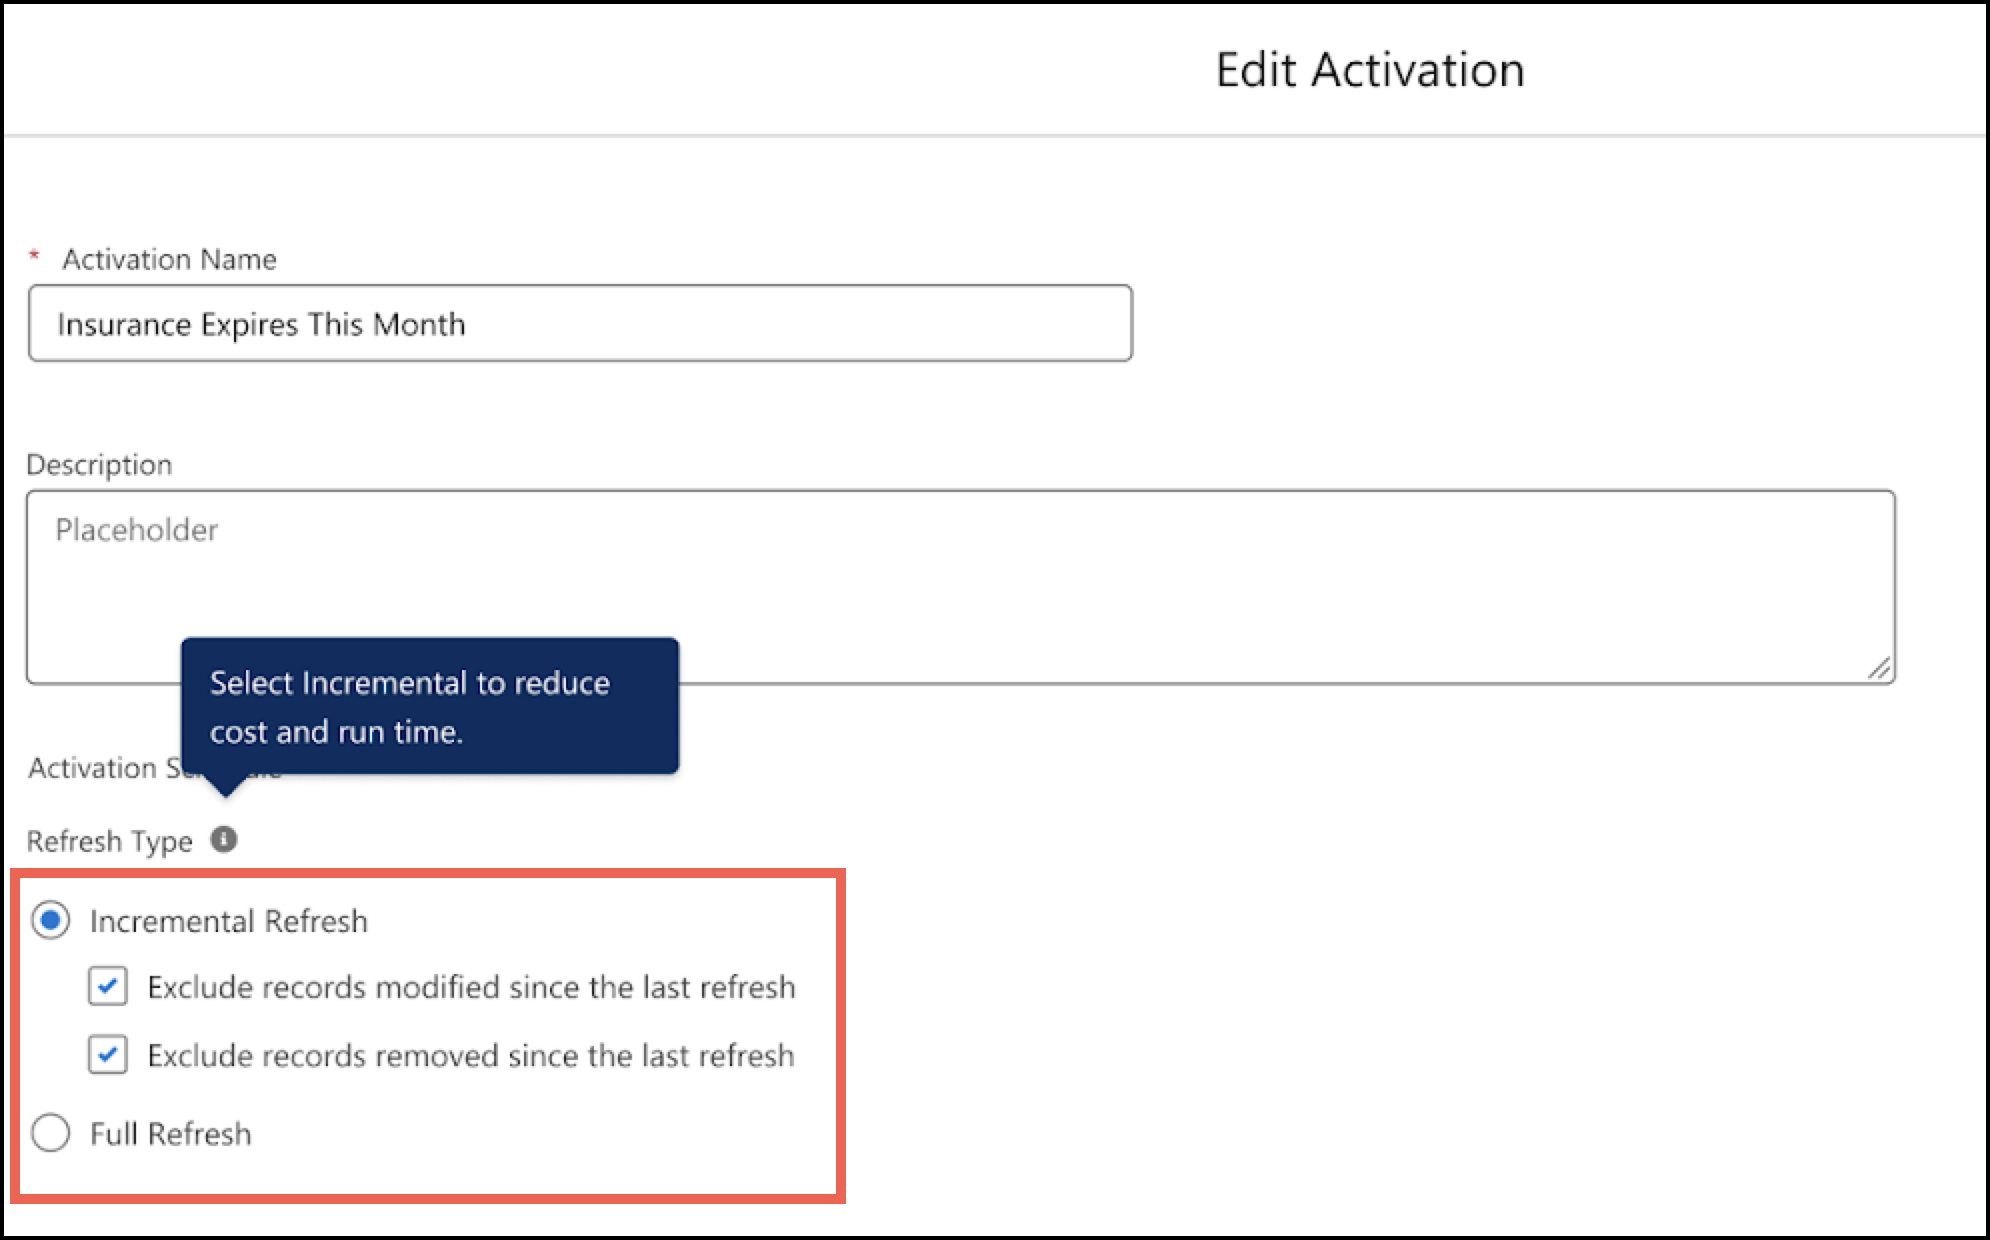
Time zone support lets you view time-specific data...
...
` and `
` tags, or raw text separated by line breaks `
Type
Metadata Field Examples
DMO (Knowledge Articles)
UDMO (External blob store connectors)
File Path
UDMO (Webcrawler or Sitemap connectors)
Configure fields to prepend to chunks from DMOs or UDMOs in the search index advanced setup for vector or hybrid search.
If a record’s prepended value reaches the max token limit that you set for the search index, then Data 360 doesn’t create any chunks and the record doesn’t appear in search results. To avoid this, select fields to prepend within the chunk size limit.
## Code Extension
Use a custom chunking function when built-in chunking strategies don't meet your content or retrieval requirements. Custom functions are useful when chunk boundaries must follow domain-specific logic, such as preserving related sections from complex PDFs or applying prompt-driven chunking through LLM gateway calls.
By using code extension, deploy a custom function and select it as the chunking strategy in search index Advanced Setup. For the end-to-end workflow to author, validate, deploy, and use a custom chunking function, see [Use Custom Functions in Data 360](https://developer.salesforce.com/docs/data/data-cloud-code-ext/guide/function/use-custom-function.html).
#### See Also
- [_Salesforce Help_: Create Vector Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
- [_Salesforce Developer_: Code Extension in Data 360](https://developer.salesforce.com/docs/data/data-cloud-code-ext/guide/use-custom-code.html)
- [_Salesforce Help_: Govern Content for AI Consumption](https://help.salesforce.com/s/articleView?id=005460254&type=1&language=en_US)
# Citations for Content Chunks
Verify the accuracy of AI responses grounded in your unstructured data with inline citations for content chunks. When you create a search index in Data Cloud, the index creates citations for each chunk.
Data Cloud adds these citations for unstructured data.
| File Type | Citations |
| --- | --- |
| PDF | Page number, file type |
| Excel | Page number, page name, and file type |
| PowerPoint | Page number, file type |
| Audio and video files | Start and end time stamps, file type |
| Other file formats | File type |
Citations use this JSON structure.
- PDF
```json
{
type: pdf,
page_number: 1
}
```
- Excel
```json
{
type: xlxs,
page_number: 1,
page_name: Sheet1
}
```
- Audio and video files
```json
{
type: mp4,
start_time: 0.0,
end_time: 10.4
}
```

Note If you have existing search indexes, [rebuild those indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_rebuild_search_index.htm&release=264.0.0&type=5 "If a Data 360 search index doesn't process properly, you can trigger a full rebuild of the index from the list page or the object record view.") for Data Cloud to add the `citation__c` field to the chunk DMO and populate it with citations.
# Classification Tags in Data 360
Classifications provide additional context and meaning within a taxonomy. They allow you to categorize data based on predefined criteria such as sensitivity or intended use, making it easier to manage, protect, and use data appropriately.
For example, you can classify healthcare data subject to HIPAA regulations as PII Sensitive to indicate its need for special handling. Classifiers can also group tags that require common policy actions. This approach allows you to apply policies consistently across all objects that share the same classification. For instance, if you define a masking policy for data classified as Sensitive, you need to set up the policy only one time. As new data objects are created, simply assigning them the Sensitive classification (when appropriate) automatically enforces the policy without the need to recreate or modify it.
# Clean Room Activation
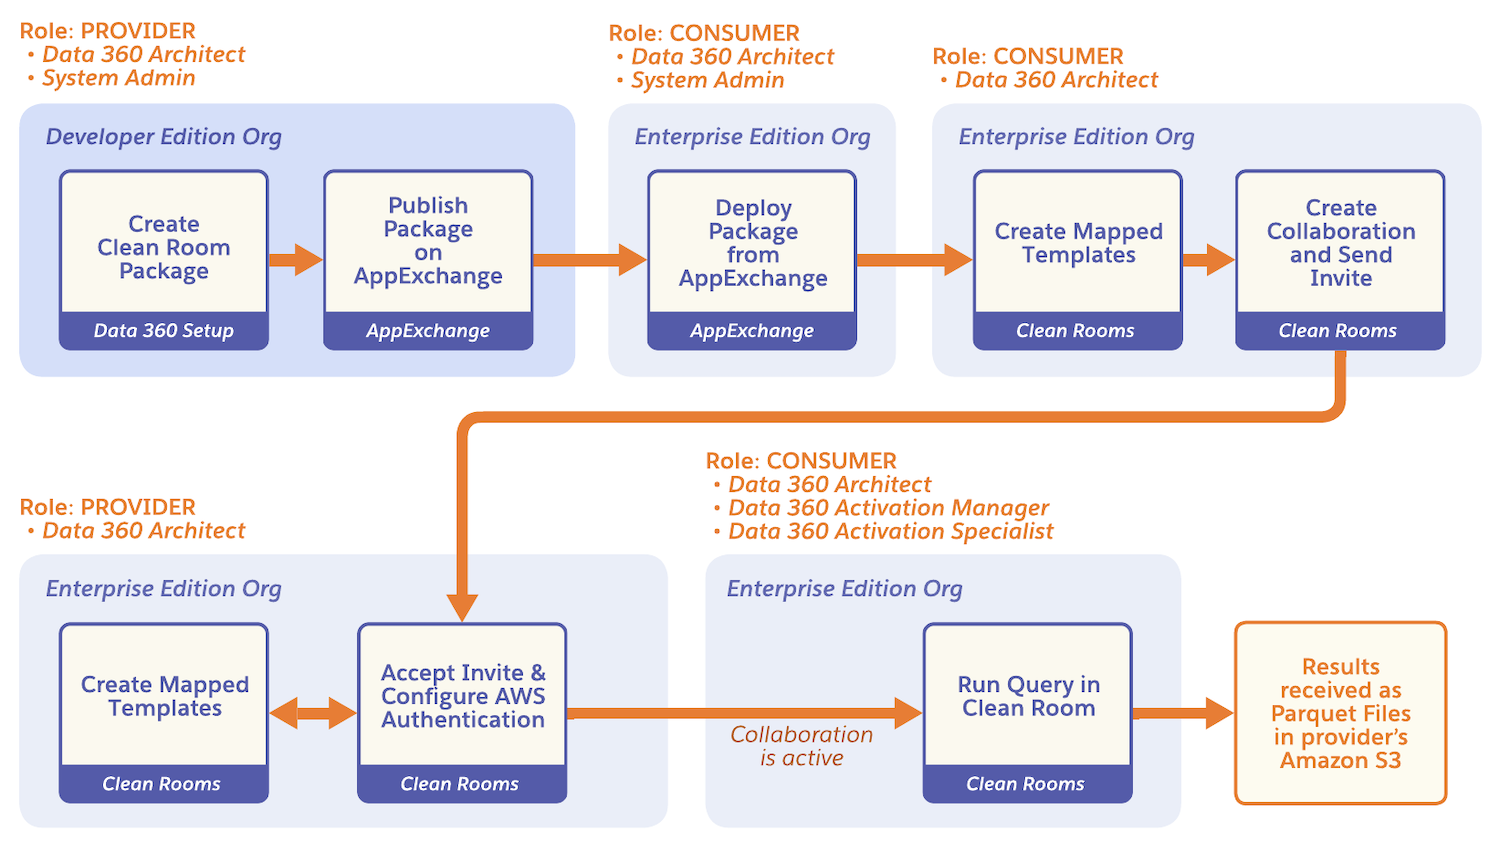
The clean room activation use case is a privacy-first way to activate first-party data in a provider's advertising platform. Data 360 matches the data in the clean room, then delivers the shared audience list directly to the provider's Amazon S3 bucket. The provider activates it from there, in the demand-side platform (DSP) or media system they already use, without building a new integration.
### Required Editions
Creating AppExchange clean room packages: Developer Edition Deploying packages, creating collaborations, and accepting invitations: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
A retailer (consumer) wants to reach its loyalty program customers with targeted ads on the media network's (provider) platform. The retailer initiates a clean room collaboration with the media network (provider). The retailer runs the activation query. Data 360 matches the retailer's customer list against the media network's audience data and writes the matched records directly to the media network's S3 bucket. The media network activates the retailer's ad campaigns to the matched audiences. The retailer never sees the matched individuals. They see only how many rows the query processed in the Clean\_Room\_Audit\_Log DMO. See [Activation Use Case Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_activation_use_case.htm&release=264.0.0&type=5 "The activation use case provides consumers with a privacy-first method to activate their first-party audience data through a provider's media or advertising platform. Rather than transferring entire segment lists, consumers identify matched audiences within the clean room. Data 360 writes the matched records directly to the provider's Amazon S3 bucket for use in campaign activation.") for the terms and conditions of this use case.
## Privacy and Data Ownership
Clean room activation makes sure that the provider receives matched audience data without the consumer losing control of their first-party data.
- The matched audience list exists only in the provider's Amazon S3 bucket.
- Data 360 has write-only access to the specific S3 path that the provider configures. The consumer's org has no access to the provider's S3 bucket.
- The consumer's org records only the number of rows processed per query run in the Clean\_Room\_Audit\_Log DMO.
- An AWS Identity and Access Management (IAM) role with a scoped trust policy restricts writes to the provider's S3 bucket to this specific collaboration only.
- **[Set Up Clean Room Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_set_up_clean_room_activation.htm&release=264.0.0&type=5)**
After a clean room activation collaboration is active, the provider receives matched audience data directly in their Amazon S3 bucket. The provider can then use the data to run targeted campaigns in their advertising platform or downstream media system.
- **[Configure an AWS Identity Provider for Clean Room Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_configure_aws_trust_relationship.htm&release=264.0.0&type=5)**
For each clean room activation collaboration invitation, configure your AWS account so that Data 360 can securely write query results to your S3 bucket, then accept the invitation in Data 360.
#### See Also
- [_Salesforce Help_: Activation Use Case Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_activation_use_case.htm&language=en_US)
# Clean Room Collaboration Templates
A collaboration template contains details about the required metadata attributes and the terms of the collaboration. Providers can create custom collaboration templates that support multiple use cases. If you’re a provider using Data 360 clean rooms, you can also use Salesforce-provided templates.
Each use case template contains these components.
| Component | Description |
| --- | --- |
| Access permissions | The functions that each role can perform, such as contributing data, querying, and accessing results. |
| Metadata | The mandatory and optional attributes needed for the use case. |
| Allowed queries | The queries and associated SQL snippets to support the use case. All clean room queries are in SQL. |
| Results | The granularity of the results, and where they’re returned. |
| Privacy rules | The privacy measures, such as minimum thresholds, row-level restrictions, and query limits. |
| Query Parameters | The filters applied on the attributes for added insights, such as segment and date range. |
- **[Salesforce-Provided Collaboration Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_sf_collaboration_templates.htm&release=264.0.0&type=5)**
Data 360 provides a predefined template to identify segments that overlap. If you’re initiating a collaboration by allowlisting a trusted provider, use the Salesforce-provided collaboration template for the collaboration.
- **[Custom Collaboration Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_custom_collaboration_templates.htm&release=264.0.0&type=5)**
Custom collaboration templates are JSON files that providers can create to specify the required metadata attributes and the terms of the collaboration. Custom templates can support multiple use cases and multiple queries under each use case. To create a custom template, copy the sample JSON, specify the field values, and upload the template while creating a package. You can also download the sample JSON from Data 360 Setup when you’re creating the clean room package.
# Clean Room Consumers
Consumers are advertisers seeking insights from providers’ data to find appropriate audiences for their products. To initiate a clean room collaboration, deploy a clean room package from AppExchange, or allowlist a provider. If you allowlist a provider, you don’t need the clean room package to initiate a clean room collaboration. Use the Salesforce-provided collaboration template to initiate the collaboration.
In an Enterprise Edition home org, [create a collaboration](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_collaboration.htm&release=264.0.0&type=5 "To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.") to invite a provider. When you save a collaboration, the provider automatically receives an invitation to the collaboration. After the provider accepts the invitation, run permitted queries on the combined dataset. A DMO stores the query results. You can’t receive or accept collaboration invitations in Developer Edition.

Note Allowlisting isn’t available if your provider uses AWS Clean Rooms. An AWS collaboration always starts with a clean room package, so deploy the package from AppExchange instead.
## Collaborate with an AWS Clean Rooms Provider
If your provider uses AWS Clean Rooms instead of Data 360, you still manage your entire side of the collaboration in Data 360. The differences are on the provider’s side. See [Collaborating with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5 "As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.").
# Clean Room Packages on AppExchange
If you want your use case template to be publicly discoverable by potential collaborators, create a clean room package in Data 360 and then publish it on AppExchange. Only an AppExchange partner can publish a package to AppExchange.
### Required Editions
Available in: Developer Edition You can’t receive or accept collaboration invitations in Developer Edition. Manage collaborations in an Enterprise Edition home org.
- **[Create a Clean Room Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_clean_room_package.htm&release=264.0.0&type=5)**
Providers can offer clean room packages that contain collaboration templates on AppExchange. Consumers interested in collaborating on your data can download the clean room package and initiate a collaboration.
- **[Publish a Clean Room Package to AppExchange](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_publish_package_to_appexchange.htm&release=264.0.0&type=5)**
After creating a clean room package in Data Cloud Setup, use data kits to package it. Then use the package manager to create a managed package and publish it on AppExchange. You can only publish managed packages on AppExchange.
- **[Deploy a Clean Room from an AppExchange Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_deploy_cr_from_appexchange.htm&release=264.0.0&type=5)**
To initiate a collaboration with a provider, install a clean room package from AppExchange and deploy it in Data 360 .
# Clean Room Providers
Providers are publishers or companies that own a platform and can offer access to data or advertising space to other companies. Data 360 Clean Rooms enable providers to collaborate using Salesforce Data 360 clean rooms or AWS Clean Rooms.
- If you’re a provider who uses Data 360 clean rooms, use Salesforce-provided collaboration templates or custom collaboration templates to offer use cases to consumers.
- If you’re a provider who uses AWS Clean Rooms, use a Developer Edition packaging org to create custom collaboration templates supporting the use cases you want to offer. See [AWS Clean Rooms Providers](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_providers.htm&release=264.0.0&type=5).
Providers can offer use cases in multiple ways.
- To offer clean room use cases that are publicly discoverable by potential collaborators, [create and publish your clean room packages on AppExchange](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_offer_usecase_on_appexchange.htm&release=264.0.0&type=5 "If you want your use case template to be publicly discoverable by potential collaborators, create a clean room package in Data 360 and then publish it on AppExchange. Only an AppExchange partner can publish a package to AppExchange. ") from a Developer Edition org. Providers using AWS Clean Rooms must use this method.
- To distribute your collaboration template to a specific collaborator as a proof of concept, create your clean room package as an unmanaged package instead. With this method, you can't offer upgraded or revised versions of the package.
- To collaborate with a specific consumer without a package, have the consumer [add your Enterprise Edition home org to their Data Cloud Org Allowlist](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_allowlist_clean_room_provider.htm&release=264.0.0&type=5 "To collaborate directly with a trusted provider, add them to your Data 360 org allowlist. When you add a collaborator to your allowlist, you don't need a clean room package to create a clean room collaboration with them.") and use the Salesforce-provided collaboration template.
## AWS Clean Rooms Providers
If you use AWS Clean Rooms to collaborate with a consumer using Data 360, your only action in Data 360 is to create and publish your clean room package. See [Collaborating with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5 "As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.") for the full flow.
#### See Also
- [_AWS Documentation_: Creating a Membership and Joining a Collaboration](https://docs.aws.amazon.com/clean-rooms/latest/userguide/create-membership.html)
# Clean Rooms
Use a clean room to collaborate securely on audience data with other parties without exposing raw data or compromising confidentiality. Providers can use their data to help companies find appropriate audiences for their products and services. Consumers can use the insights to refine their targeting strategies. Use case templates enforce rules around input data, supported queries, and privacy regulations.
### Required Editions
Creating and distributing AppExchange clean room packages: Developer Edition Managing collaborations and accepting invitations: Enterprise Edition (home org)

Note This feature isn't available in Government Cloud.
- **[Billing Considerations for Clean Rooms](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_billing_considerations_for_clean_rooms.htm&release=264.0.0&type=5)**
Clean rooms uses Data 360 to ingest data securely into a clean room collaboration. Use of Clean rooms impacts the consumption of credits in these usage types.
- **[Data 360 Clean Room Collaboration Process Overview](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_how_clean_room_works.htm&release=264.0.0&type=5)**
In a clean room collaboration, you and another party can run permitted queries on each other's data while keeping raw records private. The provider specifies which data to share, under what terms, using a collaboration template. Data 360 enforces appropriate privacy and security measures, and gives both parties full visibility into how their metadata is accessed and queried.
- **[Clean Room Collaboration Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_use_case_templates.htm&release=264.0.0&type=5)**
A collaboration template contains details about the required metadata attributes and the terms of the collaboration. Providers can create custom collaboration templates that support multiple use cases. If you’re a provider using Data 360 clean rooms, you can also use Salesforce-provided templates.
- **[Clean Rooms Privacy and Security](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_privacy_security_features.htm&release=264.0.0&type=5)**
Data Cloud clean rooms use robust privacy and security measures to keep your data secure. To collaborate, both parties must agree to the terms and conditions. All sensitive data must be encrypted with the SHA256 hashing algorithm before it enters the clean room. Hashing helps protect user identities and reduces risks if the data environment were ever compromised.
- **[Queries in Clean Rooms](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_queries_in_clean_rooms.htm&release=264.0.0&type=5)**
Run queries in a clean room to compare your data with a collaborator's data and gain insights, without exposing raw records.
- **[Prepare Your Data for a Clean Room](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_prepare_data.htm&release=264.0.0&type=5)**
To share segments in a clean room, complete these steps to prepare your data. Preparation includes required steps such as ingesting the data, mapping the data lake object (DLO) to a data model object (DMO), hashing fields to protect personal information, and creating segments. You can share segments only in a clean room.
- **[Make Segment Names Available in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_make_segment_name_available.htm&release=264.0.0&type=5)**
Segment names are stored in the Salesforce Platform. To include them in your clean room query results, make them available in Data 360 by connecting to the Market Segment data by using the CRM Connector. If you don't ingest segment names into Data 360, your query reports only contain the segment IDs.
- **[Clean Room Packages on AppExchange](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_offer_usecase_on_appexchange.htm&release=264.0.0&type=5)**
If you want your use case template to be publicly discoverable by potential collaborators, create a clean room package in Data 360 and then publish it on AppExchange. Only an AppExchange partner can publish a package to AppExchange.
- **[Allowlist a Clean Room Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_allowlist_clean_room_provider.htm&release=264.0.0&type=5)**
To collaborate directly with a trusted provider, add them to your Data 360 org allowlist. When you add a collaborator to your allowlist, you don't need a clean room package to create a clean room collaboration with them.
- **[Map Data for a Clean Room Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_map_data_for_a_usecase.htm&release=264.0.0&type=5)**
Create a mapped template to save your data mappings for a specific use case. You can create a template before a clean room collaboration is active. You can also map your data while creating a collaboration or accepting an invitation to collaborate.
- **[Delete Clean Room Mapped Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_delete_mapped_template.htm&release=264.0.0&type=5)**
You can delete a mapped template if it’s not associated with an active clean room collaboration.
- **[Clone Clean Room Mapped Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_clone_mapped_template.htm&release=264.0.0&type=5)**
Clone a mapped template to reuse its data mappings as a starting point for a new template, without mapping each attribute from scratch.
- **[Create a Clean Room Collaboration and Invite a Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_collaboration.htm&release=264.0.0&type=5)**
To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.
- **[Accept or Reject a Clean Room Invitation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_accept_reject_invitation.htm&release=264.0.0&type=5)**
If you’re a provider, when you receive an invitation to a Data 360 clean room collaboration, you can accept or reject the request. If you accept, you can choose how to map your data for the collaboration.
- **[Collaborate in a Clean Room](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_in_clean_room.htm&release=264.0.0&type=5)**
Set up a query in a Data 360 clean room collaboration to compare a consumer segment with the provider's data, without exposing raw records. Run a query manually for an immediate output, or schedule it to run each time the segment publishes.
- **[View Clean Room Query Results](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_view_clean_room_query_results.htm&release=264.0.0&type=5)**
Check the latest output for a clean room query whenever a manual or scheduled run completes.
- **[Manage Scheduled Queries](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_manage_scheduled_queries.htm&release=264.0.0&type=5)**
Review the queries scheduled to run on segment publish in a collaboration, check their status, and delete a schedule that you no longer need.
- **[Cancel a Query Run](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_cancel_a_query_run.htm&release=264.0.0&type=5)**
Cancel a query run that's in progress when you no longer need the result or you started the run by mistake.
- **[End a Clean Room Collaboration](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_end_collaboration.htm&release=264.0.0&type=5)**
When you end a clean room collaboration, you can’t restart it. If you have permissions to run queries and receive results in the collaboration, you can still access query results and query logs from past query runs.
- **[Clean Room Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_clean_room_activation.htm&release=264.0.0&type=5)**
The clean room activation use case is a privacy-first way to activate first-party data in a provider's advertising platform. Data 360 matches the data in the clean room, then delivers the shared audience list directly to the provider's Amazon S3 bucket. The provider activates it from there, in the demand-side platform (DSP) or media system they already use, without building a new integration.
- **[Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_identity_boost.htm&release=264.0.0&type=5)**
Use identity boost to collaborate with identity providers in a clean room and enrich your first-party data with missing contact points. Use the enriched data in your activations to improve match rates.
- **[Validating Clean Rooms in a Sandbox Org](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_sandbox.htm&release=264.0.0&type=5)**
To verify query results, test your clean room packages, configurations, and data mappings in a Developer or Developer Pro Data 360 sandbox. When the query run yields expected results, deploy the mapped templates from a sandbox org to a production org.
#### See Also
- [_Trailhead_: Data 360 Clean Rooms Quick Look](https://trailhead.salesforce.com/content/learn/modules/data-360-clean-rooms-quick-look)
# Clean Rooms Privacy and Security
Data Cloud clean rooms use robust privacy and security measures to keep your data secure. To collaborate, both parties must agree to the terms and conditions. All sensitive data must be encrypted with the SHA256 hashing algorithm before it enters the clean room. Hashing helps protect user identities and reduces risks if the data environment were ever compromised.
Query results are aggregated, so no individual data is released. To prevent the reidentification of individuals or exposure of sensitive information within small groups, query results must contain a minimum number of records. Because running repeated queries on the same data can reveal specific and identifiable details about individuals, you can’t run more than 100 queries in a 24-hour period.
Query logs record all data access, queries, and activities performed within the clean room. The logs are stored in the Audit log DMO, and both parties have access to them.
# Clone a Data 360 Sandbox
Create a Data 360 sandbox by cloning an existing configured sandbox to save time and maintain environment consistency. Cloning saves time by automatically copying data model objects, relationships, identity resolution rules, and data stream definitions from the source sandbox to the clone.
### Required Editions
User Permission Set
Needed
To clone a Data 360 sandbox:
Permission set:
Data Cloud Architect
Manage Sandboxes
Before you begin:
- Provision Data 360 in the source sandbox.
- Check your org has available sandbox licenses for the clone type you want to create.
- Log in to the default data space.
1. Log in to your production org or the org containing the source sandbox.
2. From Setup, enter Sandboxes in the Quick Find box, then select **Sandboxes**.
3. Select the sandbox that you want to clone and click **Clone**.
If Clone is unavailable, verify that the source sandbox is in **Active** status. You can't clone a sandbox during refresh, maintenance, or deletion.
4. Enter a name and description for the new sandbox.
5. Select the sandbox type (Developer, Developer Pro, Partial Copy, or Full) and click **Create**.
Avoid making changes in your source org during the sandbox cloning process. When your sandbox is ready for use, you receive an email notification that your sandbox has completed copying.
6. After the cloning process is complete, log in to the new sandbox from your production org just like any other sandbox.
Verify that the clone copied all configurations in **Data Cloud Setup**.
# Clone a Data Graph
When you clone a data graph, the clone inherits the data space and primary data model object (DMO) from the original data graph. You can’t change the data space or primary DMO, but you can select different related objects and fields. You can also change the cloned data graph’s name, API name, filter settings, and description.
### Required Editions
User Permission
Set Needed
To clone a data graph:
Permission set:
1. Go to the **Data Graphs** tab.
2. From a data graph list view, click the dropdown menu next to the data graph label, and select **Clone**.
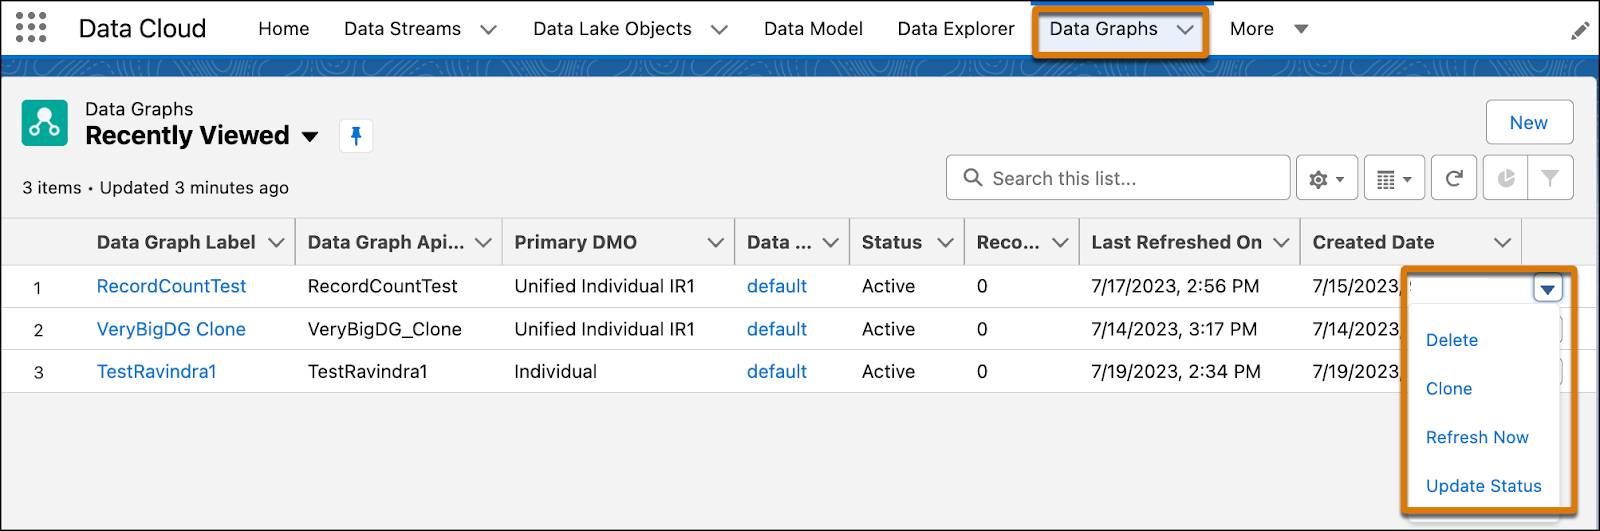
# Clone a Data Share
You can create a data share by cloning an existing one. You can add or remove data objects during cloning.
### Required Editions
User Permissions
Needed
To clone data shares:
Permission set:
1. In Data 360, go to the Data Shares tab.
2. Click the data share that you want to clone.
3. On the data share object home page, click **Clone**.
4. For Label, enter the data share’s display name and an optional description.
The API name is auto-populated to match the label, but you can change it.
5. Select the relevant data space. If you don’t have more than one data space provisioned, select **Default**.
6. Click **Next**.
7. Select or deselect data objects.
8. Click **Save**.
# Clone an Insight
Create a calculated insight using metrics from an existing insight. You can duplicate the SQL function from the calculated insights record in Data 360 and edit the attributes such as dimensions and filters.
### Required Editions
Available in: Lightning Experience
1. Go to the Calculated Insights tab.
2. Open the calculated insight, and click **Clone**.
3. Enter the new calculated insight name.
4. Make your changes.
5. To run your changes, click **Save and Run**.
# Clone Clean Room Mapped Templates
Clone a mapped template to reuse its data mappings as a starting point for a new template, without mapping each attribute from scratch.
### Required Editions
Available in: Enterprise Edition (home org)
User Permissions Needed
To clone a mapped template:
Permission set:
1. In Data 360, on the Clean Rooms tab, go to **Mapped Templates**.
2. Click the mapped template that you want to clone to open it.
3. Click **Copy**.
Data 360 opens a copy of the template with the same data mappings.
4. Review the mapped attributes, and change any mappings that you want to update for the new template.
5. Enter a new name for the template, and add an optional description.
6. Click **Save**.
# Clustering
Use clustering in Data 360 to uncover hidden patterns and natural groupings in your data.
For example, identify emerging customer profiles, recurring support issues, and behavioral trends. You can also group transaction records into segments such as loyal customers, big spenders, or at-risk customers. You can write record-level clustering results to an output data model object (DMO) for downstream use in segmentation, personalization, reporting, automated campaigns, and other Data 360 workflows.
## Clustering Use Cases
Use clustering when you want to discover meaningful groups based on multiple variables and don't have clear rules for defining those groups.
Clustering can help you:
- Segment records automatically: Group customers, accounts, products, cases, or custom records based on multiple attributes.
- Discover cross-attribute patterns: Identify non-obvious patterns and relationships across selected variables.
- Discover emerging groups: Identify clusters that aren't represented by existing segments or business rules.
- Track trends over time: Use a trained clustering model when you need to compare consistently defined clusters over time.
- Identify outliers: Find records that don't fit well within an identified cluster and require further investigation.
- Enrich data for downstream models: Write record-level cluster assignments to a DMO for use as input variables in custom multiclass classification, forecasting, and other downstream models.
Clustering sometimes isn't the best approach when you already know the criteria that define each group and require predictable membership. Use business rules when the criteria can be defined explicitly. Use multiclass classification when you have labeled examples and want a model to predict a known category.
## Clustering Considerations
Before you create clusters, identify:
- The source object that contains the records you want to group. A trained clustering model can use a DMO or Calculated Insight Object (CIO), while unsupervised clustering uses one DMO.
- The relevant numerical, categorical, or supported text fields.
- The purpose of the clusters, such as exploration, segmentation, personalization, reporting, or downstream modeling.
- Whether cluster definitions must remain consistent across runs.
- Whether identifying outliers is important.
- Whether the input data contains enough meaningful variation to distinguish groups of records.
## Clustering Workflow Selection
Choose a workflow based on how you intend to use the clusters. Clustering identifies groups based on similarities in the input data. Business context is required to determine whether those groups are meaningful and appropriate for downstream use.
| Consideration | Structured Clustering | Unsupervised Clustering |
| --- | --- | --- |
| Primary purpose | Reusable segmentation and activation | Exploration and dynamic analysis |
| Process | Train a model, and then run inference | Run a predict job |
| Separate training | Required | Not required |
| Model artifact | Saved for reuse | Not stored or versioned |
| Cluster definitions | Locked after training | Recalculated for each run |
| ID and label continuity | Stable across inference runs | Not guaranteed across runs |
| New records | Assigned to existing clusters | Included when all clusters are recalculated |
| Data sources | A primary DMO or CIO, with supported related DMOs and CIOs | One DMO containing the input data |
| Common uses | Campaigns, journeys, recurring reports, and shared segment definitions | Exploration, preprocessing, discovery of variables, data reduction, and outlier analysis |
For example, a support organization clusters supported case attributes to identify patterns associated with login failures, billing questions, and product defects. The organization uses a trained clustering model when the groups must remain stable for case routing and reporting. It uses unsupervised clustering to explore emerging issues dynamically.
## Trained Clustering Models
A trained clustering model creates stable, reusable clusters. During training, the model analyzes training data and identifies groups of similar records. Saving the model locks the cluster definitions. You can then assign business-friendly labels to the clusters. During subsequent inference runs, the model assigns new records to the best-matching existing clusters. Cluster IDs and their associated labels retain the same meaning across inference runs.
Use a trained clustering model when:
- Downstream processes require consistent cluster definitions.
- New records must be assigned to existing clusters.
- Reports and dashboards compare the same groups over time.
- Campaigns, journeys, or personalization rules depend on stable cluster IDs or labels.
- Teams need shared segment definitions.
For example, a retailer trains a clustering model that identifies Loyal Customers, Occasional Shoppers, and At-Risk Customers. The model assigns new and updated customers to these existing clusters. Marketing uses the stable labels in recurring campaigns while analysts monitor changes in each segment's size over time.
## Data Sources for Trained Clustering Models
A trained clustering model can use:
- A DMO as the primary source.
- A DMO as the primary source with fields from supported related DMOs and CIOs.
- A CIO as the primary source with fields from supported related DMOs and CIOs.
A related DMO or CIO is available when it has a one-to-one or many-to-one relationship with the primary object. To review a DMO's related objects, open the DMO and select the **Relationships** tab. Eligible fields appear in the model builder under **Add additional related fields to your data (Optional)**.
## Unsupervised Clustering
Unsupervised clustering dynamically discovers groups without predefined labels or a separate model-training step. During each clustering job, the algorithm processes the selected dataset and generates clusters without storing or versioning a trained model artifact.
An unsupervised clustering job uses one DMO containing the input data. Because clusters are recalculated for every run, cluster IDs, record assignments, and distributions can change when records or job settings change. A cluster from one run isn't guaranteed to represent the same group in a later run, even if the two clusters have the same ID.
Use unsupervised clustering to:
- Perform one-time exploration or ad hoc analysis.
- Discover patterns in the current dataset.
- Work without requiring reusable cluster IDs.
- Dynamically preprocess data for another analysis or model.
- Reduce a large dataset to a smaller set of representative groups.
- Identify outliers or records that don't fit established patterns.
Don't use unsupervised cluster IDs as permanent segment definitions. If downstream processes require clusters to retain the same meaning across runs, use a trained clustering model.
For example, a retailer runs an unsupervised clustering job on product data using supported fields such as price, sales volume, seasonality, and product descriptions. The resulting clusters help analysts identify everyday sellers, seasonal products, and long-tail products. When the product catalog changes and the job runs again, the clusters are recalculated to reflect the current data.
## Clustering Input Types
Depending on the selected workflow and configuration, clustering can analyze structured data, supported unstructured content, or a combination of input types.
**Structured Data**
Structured data includes numerical and categorical fields. For example, a team can evaluate account revenue, transaction counts, and support engagement to identify potential account tiers.
**Unstructured Data**
Unstructured data includes customer feedback, support case descriptions, comments, notes, and product descriptions. Clustering can identify similarities and themes in text without requiring predefined categories. Unstructured content is an input type, not a separate clustering workflow. Availability depends on the selected workflow, algorithm, and configuration.
## Clustering Algorithm Selection
Choose an algorithm based on the characteristics of your data, whether you know approximately how many clusters you want, and whether identifying outliers is important.
**K-Means**
K-means groups records into a specified number of clusters based on similarity. The default is four, but you can adjust the number or let the model determine an appropriate number based on your data. Use K-means when you:
- Know approximately how many clusters you want.
- Expect most records to belong to a cluster.
- Plan to divide the dataset into a fixed number of clusters.
For unsupervised K-means, every clustering job processes the current dataset and recalculates all clusters. Later runs can produce different cluster IDs, record assignments, and distributions.
For example, an analyst configures unsupervised K-means to divide accounts into four clusters based on annual revenue, purchase frequency, and service activity. The resulting clusters provide an initial view of potential account tiers for further analysis.
**HDBSCAN**
HDBSCAN identifies clusters based on areas of higher data density and doesn't require you to specify the number of clusters in advance. It's suited to noisy data and can identify records that don't fit well within a cluster as outliers. Use HDBSCAN when:
- You don't know the expected number of clusters.
- Groups can have different sizes or densities.
- Your data contains noise or records that might not belong to a meaningful group.
- Identifying outliers is important.
For example, a support organization uses HDBSCAN to group cases based on supported case attributes and descriptions. Most cases form recognizable issue clusters while unusual cases are identified as outliers for separate investigation.
## Clustering Results
Depending on the workflow, algorithm, and job configuration, the output DMO can include:
- Cluster ID: The identifier of the cluster to which a record is assigned.
- Cluster label: A business-friendly name associated with the cluster, when supported.
- Input variables: Selected input values included for downstream analysis.
- Top contributors: The fields that contributed most to the clustering result, when supported.
- Outlier information: An indication that a record doesn't fit well within an identified cluster, when supported by the algorithm.
Labels don't change the lifecycle of the underlying clusters. In a trained clustering model, labels remain associated with locked cluster definitions. In unsupervised clustering, cluster assignments and IDs can change with every run. Don't assume that matching IDs represent the same groups across different unsupervised runs.
Use clustering results to:
- Create or refine customer and other business segments.
- Personalize experiences and campaigns.
- Route or prioritize support cases.
- Monitor changes in customer, product, or support populations.
- Identify emerging issues or unusual records.
- Provide cluster assignments as input variables for downstream models.
- Analyze cluster characteristics in reports and dashboards.
Before using clusters in customer-facing actions and automated processes, review the results and apply business context.
- **[Use Clustering on Structured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_cluster_use.htm&release=264.0.0&type=5)**
Use clustering models in Data 360 to automatically group data model object (DMO) records by shared characteristics. Run a predict job or batch data transform to assign new records to saved clusters, and use the results across Salesforce.
# Code Extension
Bring your custom Python code into Data 360 to extend Data 360's native capabilities by using code extension. If the native Data 360 features don't meet your business requirements, deploy your custom logic to supported Data 360 features.
Code extension supports two types of custom code, which differ in how they run.
- Scripts run as a batch data transform—a job that you run on demand or schedule.
- Functions run as part of the search index pipeline, where they control how content is chunked for search and AI retrieval.
The code extension workflow involves collaboration between developers and users with a Data Cloud Architect permission set. Developers author and validate custom Python code locally by using Salesforce CLI with the Code Extension plugin and the Data Custom Code Python SDK as the toolchain. Then they prepare it for deployment.
Data 360 users manage code execution, monitoring, and migration from a sandbox to production. In a sandbox, upload custom code packages and use the custom code in the relevant Data 360 feature—a batch data transform for a script, or a search index for a function—then run it. Monitor deployment status, execution history, and logs. After validation, package the custom code and dependencies into a data kit. In production, install the data kit, run the custom code to process production data, and monitor execution.
- **[Billing Considerations for Code Extension](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_code_extension.htm&release=264.0.0&type=5)**
Using code extension in Data 360 impacts the consumption of credits used for billing for orgs operating Data 360 under a Data Cloud license.
#### See Also
- [_Salesforce Developer Help_: Code Extension in Data 360](https://developer.salesforce.com/docs/data/data-cloud-code-ext/guide/use-custom-code.html)
# Collaborate in a Clean Room
Set up a query in a Data 360 clean room collaboration to compare a consumer segment with the provider's data, without exposing raw records. Run a query manually for an immediate output, or schedule it to run each time the segment publishes.
### Required Editions
Available in: Enterprise Editions (home org)
User Permissions Needed
To run a clean room query:
Data Cloud Architect OR Data Cloud Activation Manager OR Data Cloud Activation Specialist
## Run a Query
Run a query to get insights on your collective data. To run a query, the collaboration must be active.
1. In Data 360, go to the **Clean Rooms** tab.
2. Under **Collaborations**, open the collaboration to run the query on.
3. Click **Set Up Query**.
4. For **Run Options**, select **Run now**.
5. If the use case includes more than one query, select a query for **Query Name**.
6. For **Query Run Name**, enter a descriptive name that identifies this run in the Collaboration Results tab.
7. For **Consumer Segment**, select the segment to compare.
8. If the query uses parameters, enter a value for each parameter.
9. Click **Run Query**.
After the run completes, the result appears on the Collaboration Results tab. If a schedule already runs for the segment, Data 360 asks you to confirm. Click **Run Anyway** to run the query now. A manual run doesn't change the scheduled run.
## Schedule a Query to Run on Segment Publish
Schedule a query to run automatically each time the consumer segment publishes. To schedule a query on segment publish, the collaboration must be active and the consumer segment must already have a publish schedule.
1. In Data 360, go to the **Clean Rooms** tab.
2. Under **Collaborations**, open the collaboration to run the query on.
3. Click **Set Up Query**.
4. For **Run Options**, select **Schedule based on segment publish**.
5. For **Schedule Name**, enter a descriptive name that identifies this schedule later.
6. If the use case includes more than one query, select a query for **Query Name**.
7. For the **Consumer Segment**, select the segment to compare. Review the Segment Publish Summary to confirm the segment's Type, Frequency, Run Every, Start Date and Time, and End Date and Time.
8. If the query uses parameters, enter a value for each parameter.
9. Click **Schedule Query**.
The schedule appears on the Scheduled Queries tab.

Note You can schedule only one query run for each consumer segment. For a custom template that uses parameters, you can schedule one run for each combination of segment and parameter values.
# Collaboration with an AWS Clean Rooms Provider
As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.
## Requirements and Restrictions
- When the provider of a clean room collaboration is using AWS Clean Rooms, they can only support custom collaboration templates in their clean room package.
- You can't allowlist a provider if they're using AWS Clean Rooms. The AWS collaboration flow always starts with a clean room package. When you allowlist, you can collaborate without a clean room package, but this option is only applicable with a Data 360 partner.
## AWS Collaboration Process Overview
Here's the sequence of steps in a clean room collaboration with an AWS provider.
- Provider configures clean room package in Data Cloud Setup.
- Creates a clean room package in a Developer Edition packaging org. The package contains a custom collaboration template that specifies the terms of the collaboration. See [Create a Clean Room Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_clean_room_package.htm&release=264.0.0&type=5 "Providers can offer clean room packages that contain collaboration templates on AppExchange. Consumers interested in collaborating on your data can download the clean room package and initiate a collaboration.").
- Publishes the package on AppExchange. This step is the provider's last action in Data 360. After the provider publishes the package, they wait for a consumer to send them a collaboration invitation. See [Publish a Clean Room Package to AppExchange](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_publish_package_to_appexchange.htm&release=264.0.0&type=5 "After creating a clean room package in Data Cloud Setup, use data kits to package it. Then use the package manager to create a managed package and publish it on AppExchange. You can only publish managed packages on AppExchange.").
- Provider and consumer collaborate in a clean room.
- Consumer tasks in Data 360: Deploys the package from AppExchange, creates a clean room collaboration for the use case, and sends an invitation to the provider. See [Create a Clean Room Collaboration and Invite a Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_collaboration.htm&release=264.0.0&type=5 "To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.").
- Provider tasks in the AWS Clean Rooms Console: Receives and accepts the invitation. For the steps the provider performs, see [Setting up AWS Clean Rooms](https://docs.aws.amazon.com/clean-rooms/latest/userguide/setting-up.html).
- Consumer tasks in Data 360: Runs queries against the shared dataset, according to the permissions defined in the collaboration template.
# Combine Rows from Different Data Sources Using the Append Node
Use an append node to combine rows from multiple input data sources into a single result.
1. In a batch data transform that has at least one input node, click the Add Node button () between two nodes or at the end of the data transform.
2. Select **Append**.
3. Select the data to append to the batch data transform.
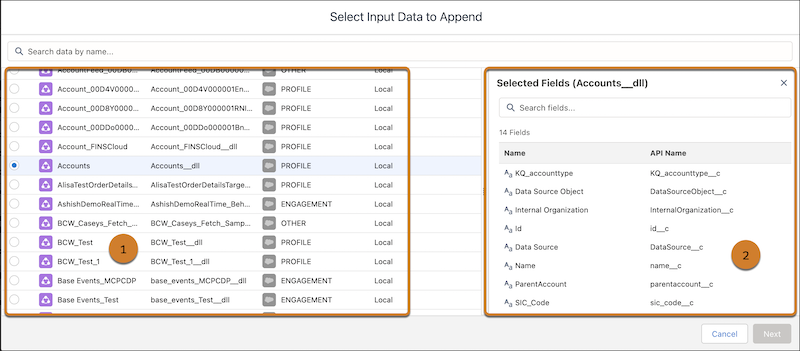
1. Select the object that you want to add (1).
2. Under Selected Fields (2), choose which of the object’s columns (also called fields) to include in the appended data, or click **Name** to select all columns.
3. Click **Next**.
4. Choose how to map columns.
- To automatically map all columns each time your batch data transform runs, turn on **Map all columns**.
- To manually map two columns, enter the column name from the appended rows next to its corresponding batch data transform column.
A batch data transform maps all columns from both data objects based on matching column API names. To map columns that don’t have corresponding API names, select **Allow schema merge**.

Note If a column is mapped for one source and not the other, the append node inserts null values for all source rows that the column doesn’t apply to. If a numeric column isn’t mapped to a source and null numeric handling isn’t enabled, the append node inserts zeroes instead of nulls for those source rows.
5. To add a column from the appended rows that doesn’t exist in the batch data transform, click **+** and select the column. Leave the batch data transform column blank.
6. Click **Apply** to add the node to the batch data transform.
7. Click **Save**.
When you run the batch data transform, the append node combines rows from both data objects into the same source data.
# Compare Data Federation Methods
Data can be federated via live queries, accelerated queries to the local data cache, or via file federation. Each option supports different use cases. Performance, data freshness, and credit consumption considerations vary.
Understanding the differences between the three types of data federation helps you select the right method for your use case.
## Live Query Federation
Live queries run in real time and return fresh results from the data source.
- **Use Cases:** Live query data federation is best for interactive analysis and real-time dashboards. Optimized for infrequent queries. Live query data federation supports real-time personalization and dynamic workflows.
- **Data Source Location:** External data lakehouses
- **Data Freshness:** Queries run in real time. Overall data freshness depends on how often the source data is updated. Live query data federation supports sub-second decisioning.
- **Performance Drivers:** Highly dependent on the external source system's performance. Optimized when predicates and aggregations can be pushed down to the source.
- **Credit Consumption Considerations:**
- Credits are consumed per query based on the number of rows accessed. Credits are primarily consumed in the Data Federation and Data Shared Accessed usage type.
- Live queries can be cost effective for infrequent queries. However, frequent queries on infrequently changing data can result in repeatedly consuming credits to query the same data, making this option more expensive than accelerated queries.
## Accelerated Query Federation
When acceleration is enabled for query federation, Data 360 maintains a local data cache that is updated at set intervals. Accelerated queries access the local data cache instead of querying the data source directly.
- **Use Cases:** Accelerated data federation is best when queries are frequent and data doesn’t change frequently. Enabling acceleration improves performance for frequent access patterns by keeping a local cache that’s updated on scheduled intervals. Accelerated data federation is suitable for dashboards and segmentation. If your data changes more frequently than your cache is updated, acceleration isn’t suitable for sub-second decisions.
- **Data Source Location:** External data lake
- **Data Freshness:** Freshness depends on the selected cache interval, which is configurable from 15 minutes to 7 days.
- **Performance Drivers:** Reduces latency compared to repeated live queries.
- **Credit Consumption Considerations:**
- Credits are consumed per row of data added to or updated in the cache. Credits are consumed in the Batch Data Pipeline usage type when the cache is updated.
- Credits are also consumed by use of data queries when the cache is queried.
- The accelerated query cache can contribute to usage of your org’s Data 360 storage.
- Credit consumption for accelerated queries is similar to credit consumption for the same amount of batch data via batch data ingestion.
## File Federation
In file federation, Data 360 uses metadata from the data source to build virtual tables, which are used to access and read files in the data source.
- **Use Cases:** File federation is best for large-scale batch processing and for AI and machine learning model training. File federation is ideal for historical analytics and petabyte-scale reporting. It isn’t suitable for real-time dashboarding.
- **Data Source Location:** Cloud object stores or cloud data lakes
- **Data Freshness:** Freshness depends on how often the source files are updated.
- **Performance Drivers:** Performance depends heavily on object format, partitioning, and external system throughput. Use partitioned, columnar formats (Parquet).
- **Credit Consumption Considerations:**
- When using an AWS setup that is in the same region as your Data 360 tenant, credits aren’t consumed for rows accessed. For example, if the customer has data in S3 in US-East-1 and their Data 360 tenant is also in US-East-1, then there credits aren’t consumed for rows accessed from the customer’s data source by Data 360.
- If your AWS setup in a different region than your Data 360 tenant or uses a different cloud, such as Azure, then the you consume credits for rows accessed.
# Compare Standard Salesforce CRM and Data Cloud One Companion Connections
You can connect a Salesforce org to Data 360 using a standard Salesforce CRM connection or a Data Cloud One companion connection paired with a standard connection. The table lists some of the differences between these types of connections.
| Capability | STANDARD CONNECTION ONLY | COMPANION CONNECTION PAIRED WITH A STANDARD CONNECTION |
| --- | --- | --- |
| Connects Data 360 to a Salesforce org |  |  |
| Allows Data 360 to ingest CRM data |  |  |
| Allows Data 360 to sync metadata with Salesforce orgs |  |  |
| Allows connected orgs to use features powered by Data 360 |  |  |
| Allows connected orgs to access Data 360 features in the Data Cloud One app |  |  |
| Allows connected orgs to use Data 360 data in platform features |  |  |
| Impacts credit consumption under the Batch Data Pipeline billing usage type |  |  |
| Available to Data 360 orgs with a Data 360 license |  |  |
| Available to Data 360 orgs with a Data Cloud license |  |  |
# Compose the Email in Content Builder
Let’s walk through the steps to create the first welcome email in this campaign.
1. In Marketing Cloud Engagement, go to **Content Builder**.
2. To create your email message, click **\+ Create** and **Email Message**.
3. Select **Template** for the email creation method.
Emails can be created in many ways in Content Builder including from a template or HTML. In this example, we explain how to create an email from a template.
4. Choose the desired template and click **Select**.
5. Define email properties including an email name and description and click **Next**
6. To use the personalization in the Data 360 data extension, drag a **Code Snippet Block** to the email canvas. 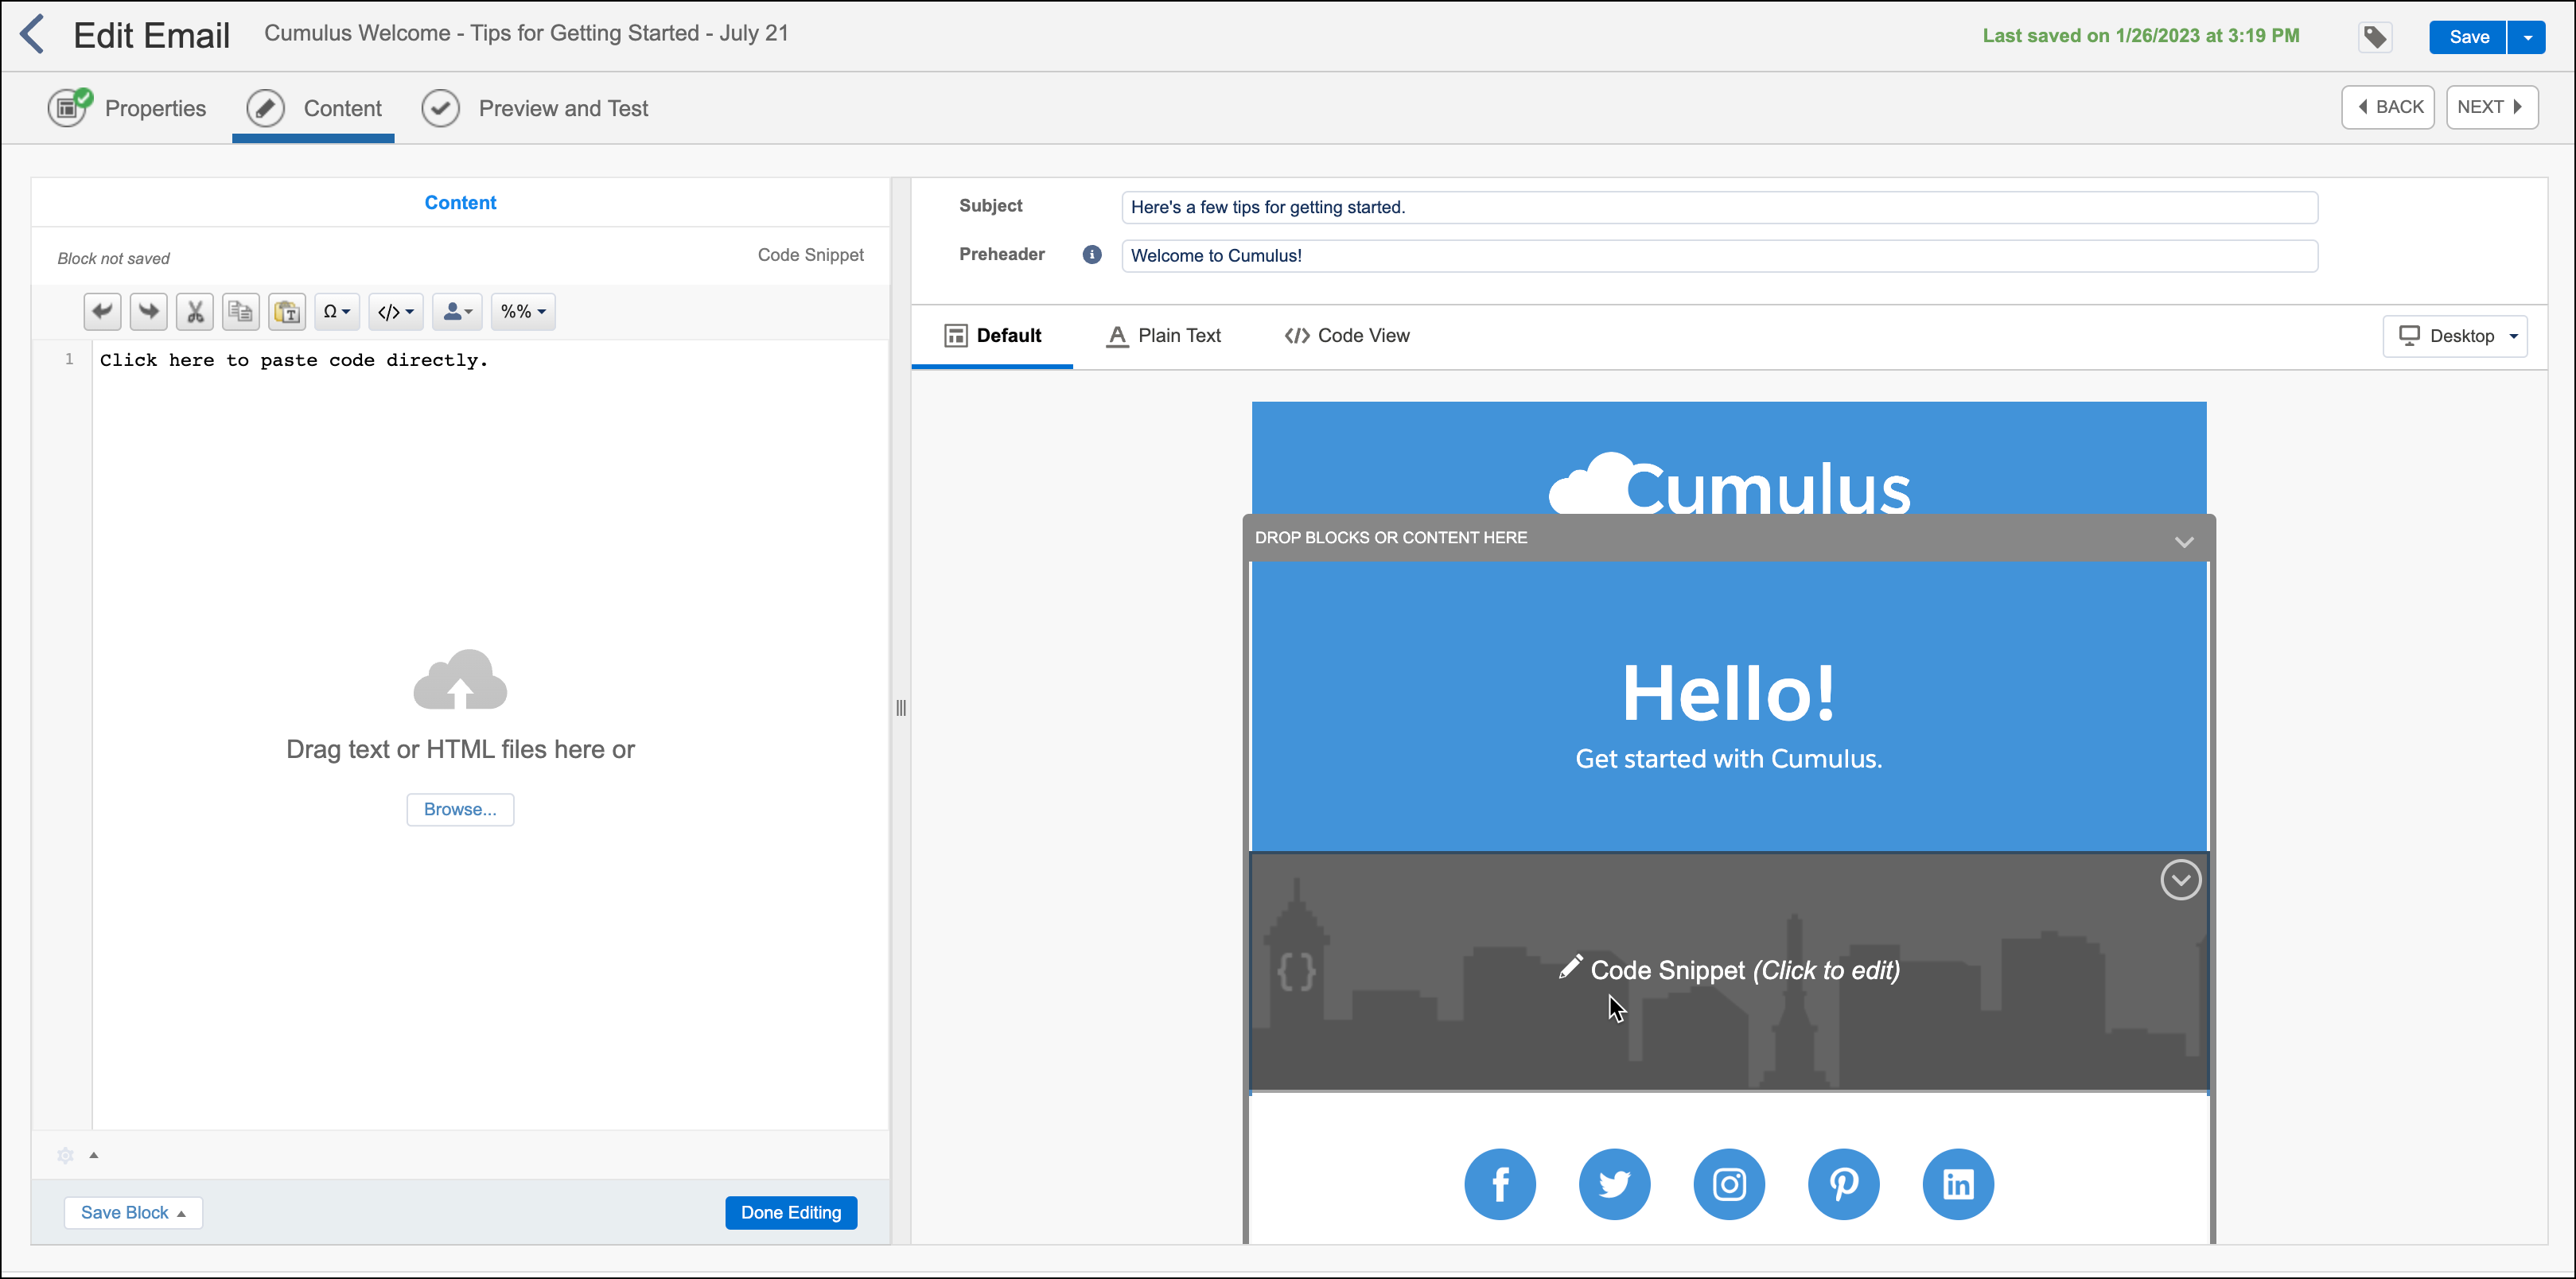
7. In this use case, the personalized elements include the customer’s first name, insurance policy number, policy type, and policy start date. Code the content using GTL, SSJS, or AMPscript to use the JSON formatted content in the data extension.
8. Click **Preview and Test** and select the data extension from Data 360.
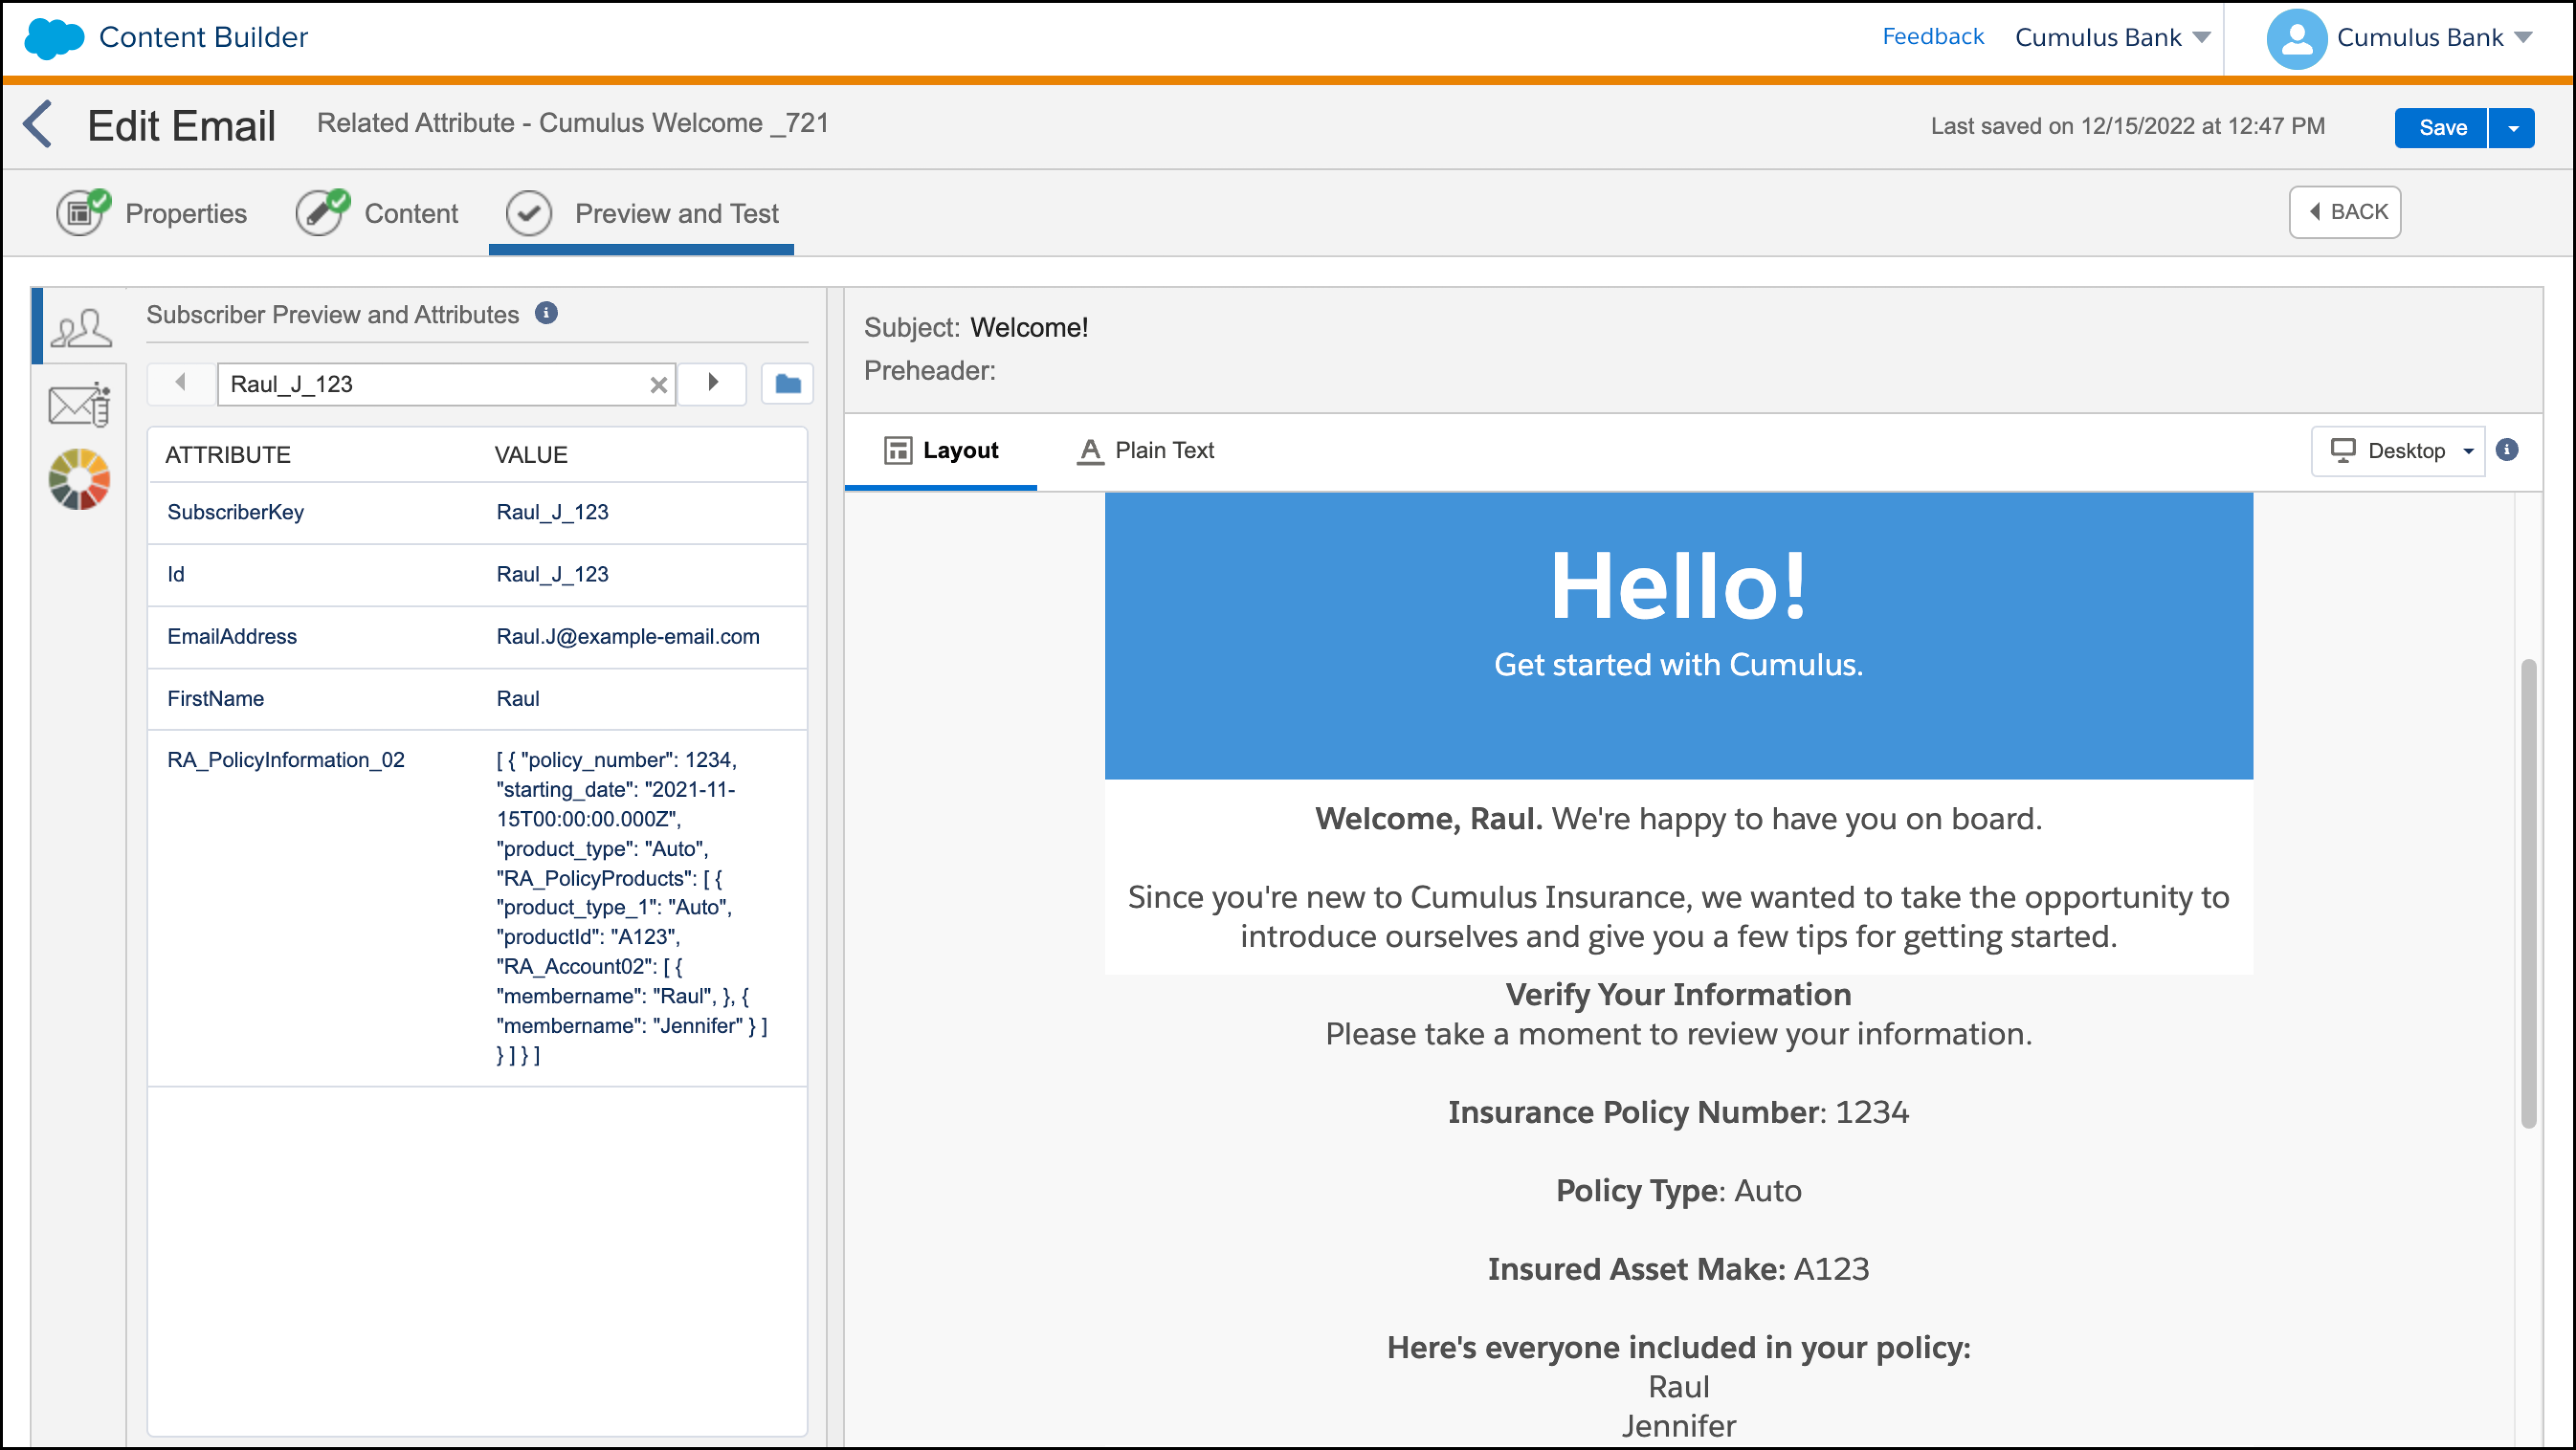
9. After testing, click **Save and Exit**.
10. Complete these steps for the remaining two email messages.
You can parse this data with either GTL, SSJS, or AMPscript.

Example Sample GTL parsing
```html
%%[ set @JSONData = [RA_PolicyInformation_02] ]%%
{{.datasource RA_PolicyInformation_02 type=variable}}
{{.data}}
{ "target" : "@JSONData"}
{{/data}}
Verify Your Information
Please take a moment to review your information.
Insurance Policy Number : {{RA_PolicyInformation_02.policy_number}}
Policy Type : {{RA_PolicyInformation_02.product_type}}
{{.datasource RA_PolicyProducts type=nested}}
{{.data}}
{ "target" : "RA_PolicyInformation_02.RA_PolicyProducts" }
{{/data}}
Insured Asset Make: {{RA_PolicyProducts.productId}}
Here's everyone included in your policy:
{{.datasource RA_Account type=nested}}
{{.data}}
{ "target" : "RA_PolicyProducts.RA_Account02" }
{{/data}}
{{RA_Account.membername}}
{{/datasource}}
{{/datasource}}
{{/datasource}}
```
Sample SSJS parsing
```html
```
Sample AMPscript parsing
```html
%%[
var @i, @j, @k, @PolicyRowset, @PolicyCount, @PolicyRow, @PolicyNumber, @ProductType, @PolicyProductsRowset, @PolicyProductCount, @PolicyProductRow, @PolicyProductId, @MemberRowset, @MemberCount, @MemberRow, @MemberName
set @PolicyRowset=BuildRowsetFromJson(RA_PolicyInformation,"$.[*]", false)
set @PolicyCount=rowcount(@PolicyRowset)
for @i = 1 to @PolicyCount do
set @PolicyRow=row(@PolicyRowset, @i)
set @PolicyNumber=field(@PolicyRow, "policy_number")
set @ProductType=field(@PolicyRow, "product_type")
OutputLine(V("
Verify Your Information "))
OutputLine(V("Please take a moment to review your information.
"))
OutputLine(V("
"))
OutputLine(concat("
Insurance Policy Number : ", @PolicyNumber, "
"));
OutputLine(V("
"));
OutputLine(concat("
Policy Type : ", @ProductType, "
"));
OutputLine(V("
"));
set @PolicyProductsRowset = BuildRowsetFromJson(RA_PolicyInformation, concat("$.[", Subtract(@i, 1), "].RA_PolicyProducts[*]"), false)
set @PolicyProductCount = rowcount(@PolicyProductsRowset)
for @j = 1 to @PolicyProductCount do
set @PolicyProductRow=row(@PolicyProductsRowset, @j)
set @PolicyProductId=field(@PolicyProductRow, "productId")
OutputLine(concat("
Insured Asset Make: ", @PolicyProductId, "
"));
OutputLine(V("
"));
OutputLine(V("
Here's everyone included in your policy: "));
set @MemberRowset = BuildRowsetFromJson(RA_PolicyInformation, concat("$.[", Subtract(@i, 1), "].RA_PolicyProducts[", Subtract(@j, 1), "].RA_Account02[*]"), false)
set @MemberCount = rowcount(@MemberRowset)
for @k = 1 to @MemberCount do
set @MemberRow=row(@MemberRowset, @k)
set @MemberName=field(@MemberRow, "membername")
OutputLine(concat(@MemberName, "
"));
next @k
next @j
next @i
]%%
```
#### See Also
- [_Salesforce Developer_: Guide Template Language Syntax Guide](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/gtlSyntaxGuide.html)
- [_Salesforce Developer_: Content Areas Within Template and Layout](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/gtlContentAreas.html)
- [_Trailhead_: Marketing Cloud Engagement Programmatic Languages](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-programmatic-languages)
- [_Salesforce Developer_: Build Row Set From JSON](https://review-app-sdmarkdoc-pr-196.herokuapp.com/docs/marketing/marketing-cloud/guide/buildrowsetfromjson.html)
# Composite Key
Use a composite key to uniquely identify a record.
In Data Cloud, you can assign composite keys only for Bring Your Own Lake (BYOL) data shares. To assign a composite key, use one of these options.
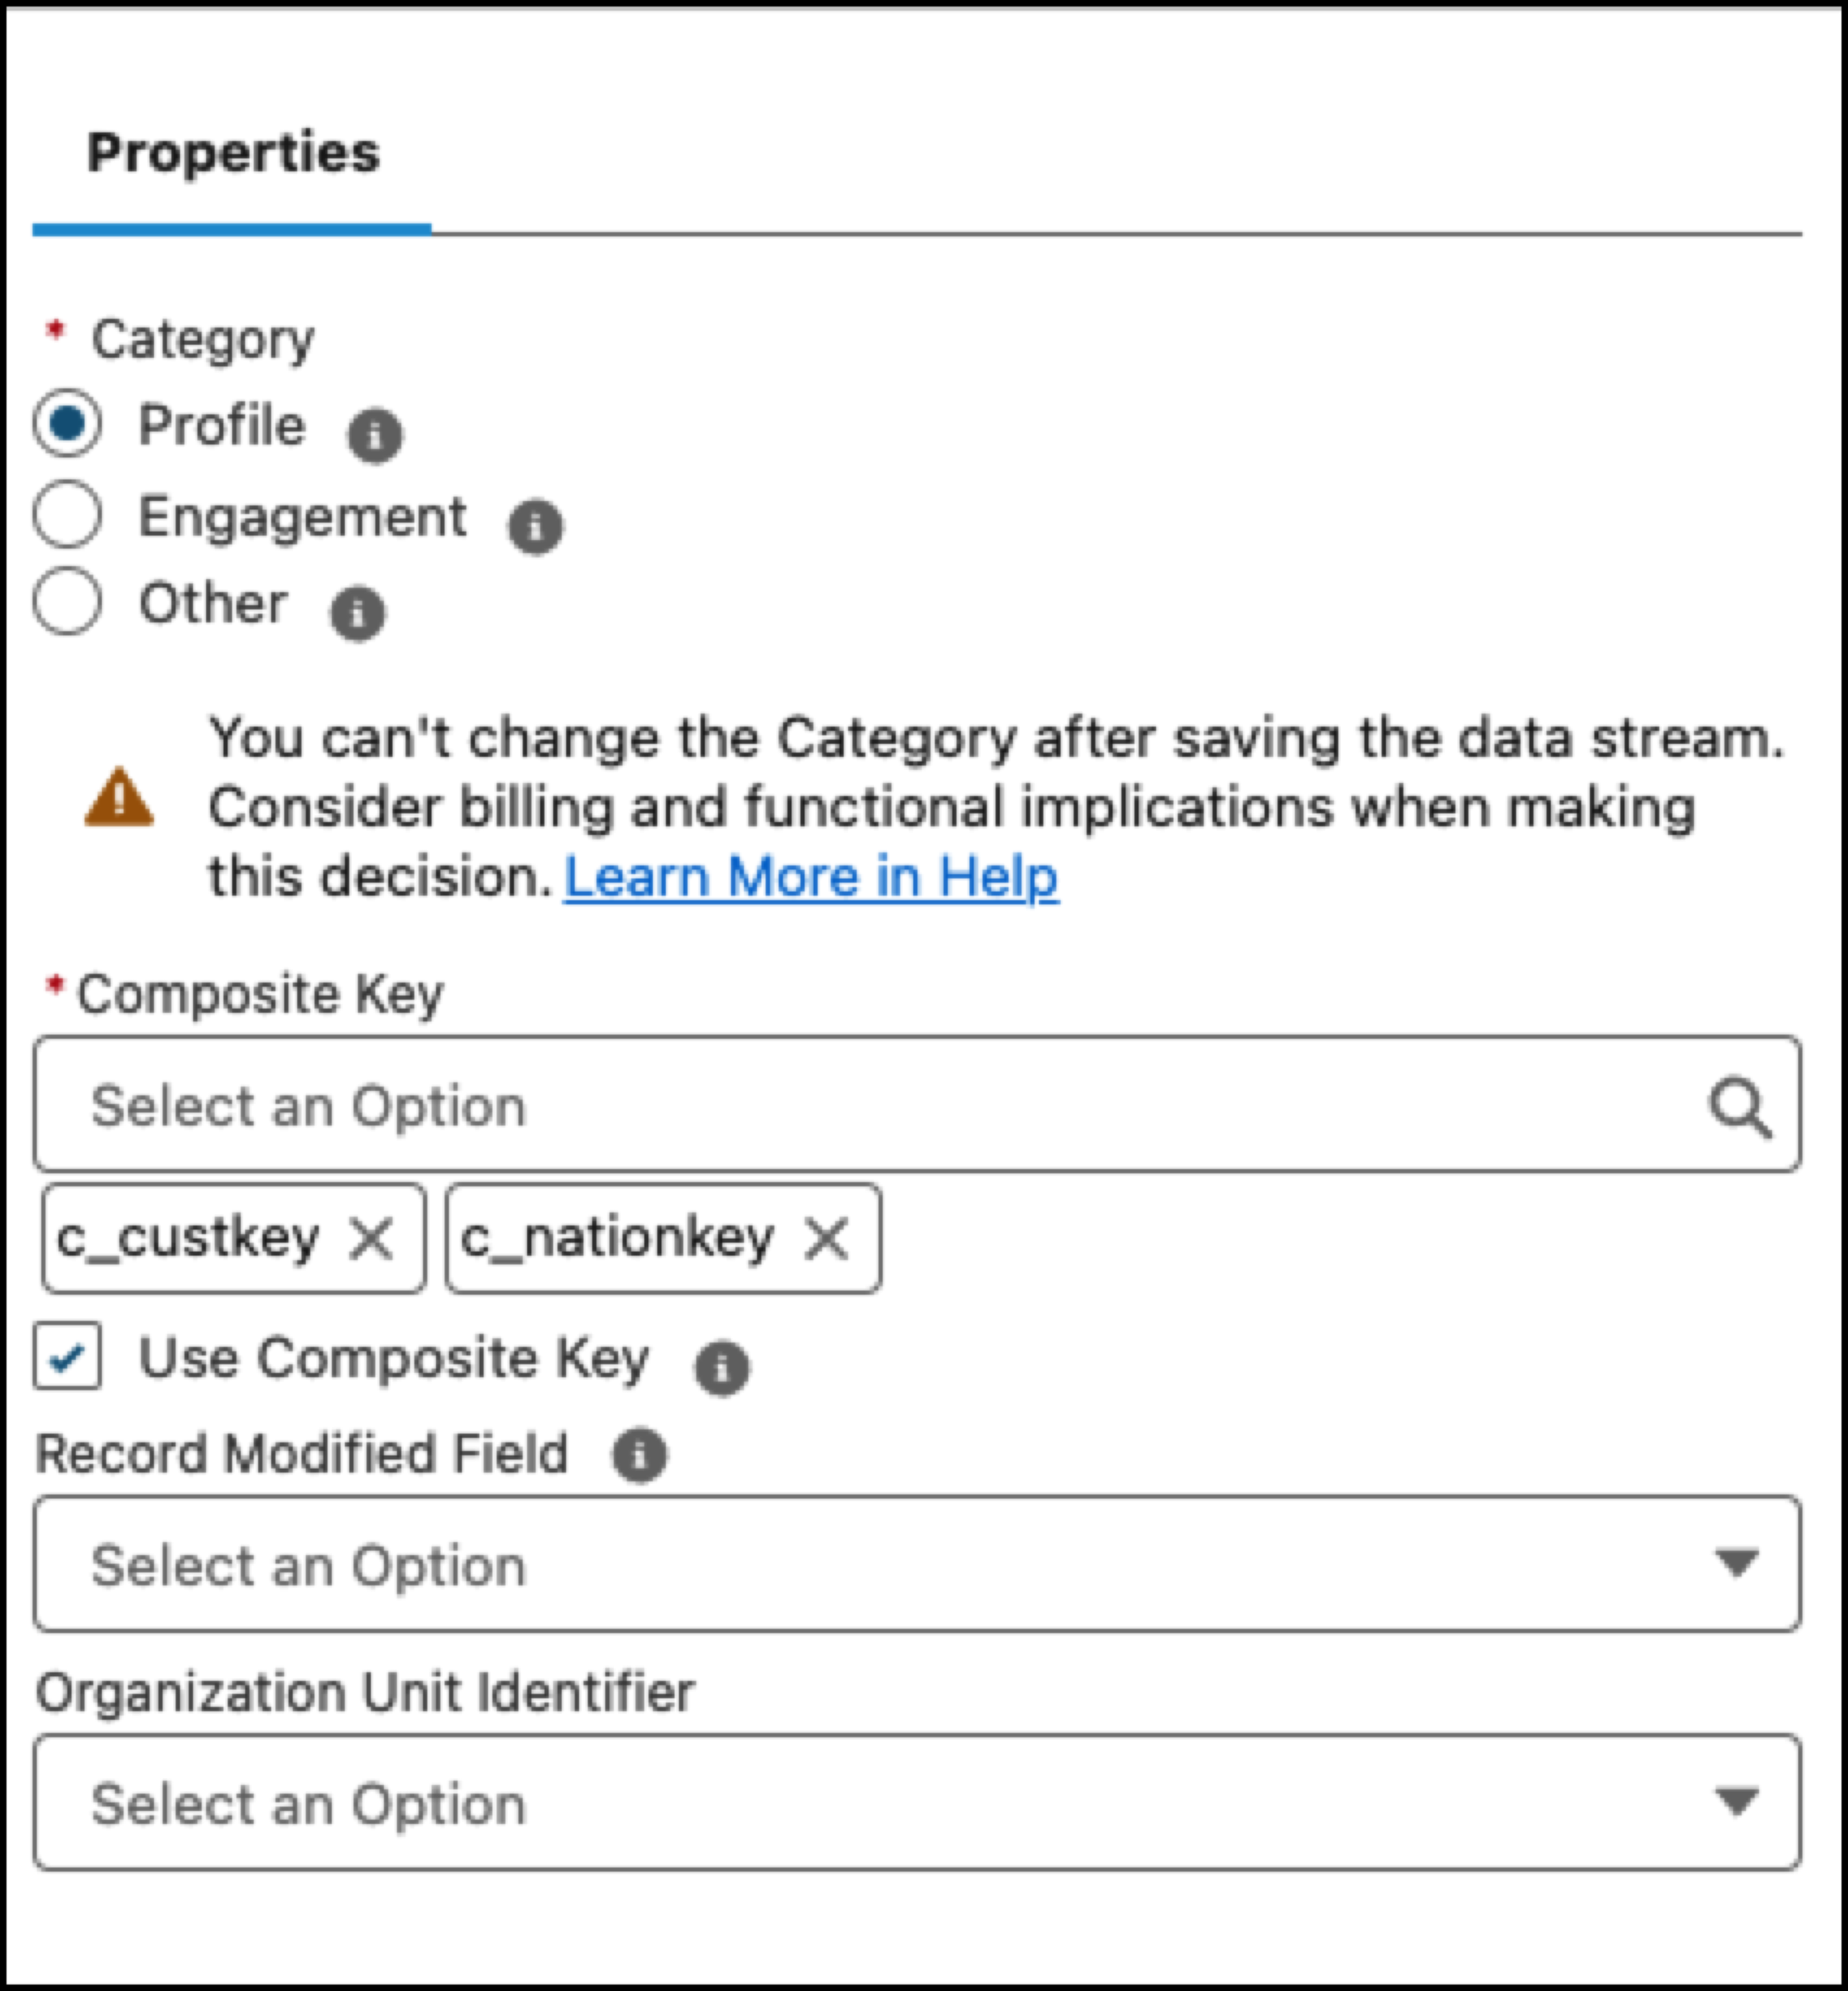
- Search for and select the appropriate fields in the data source table to designate as a composite key.
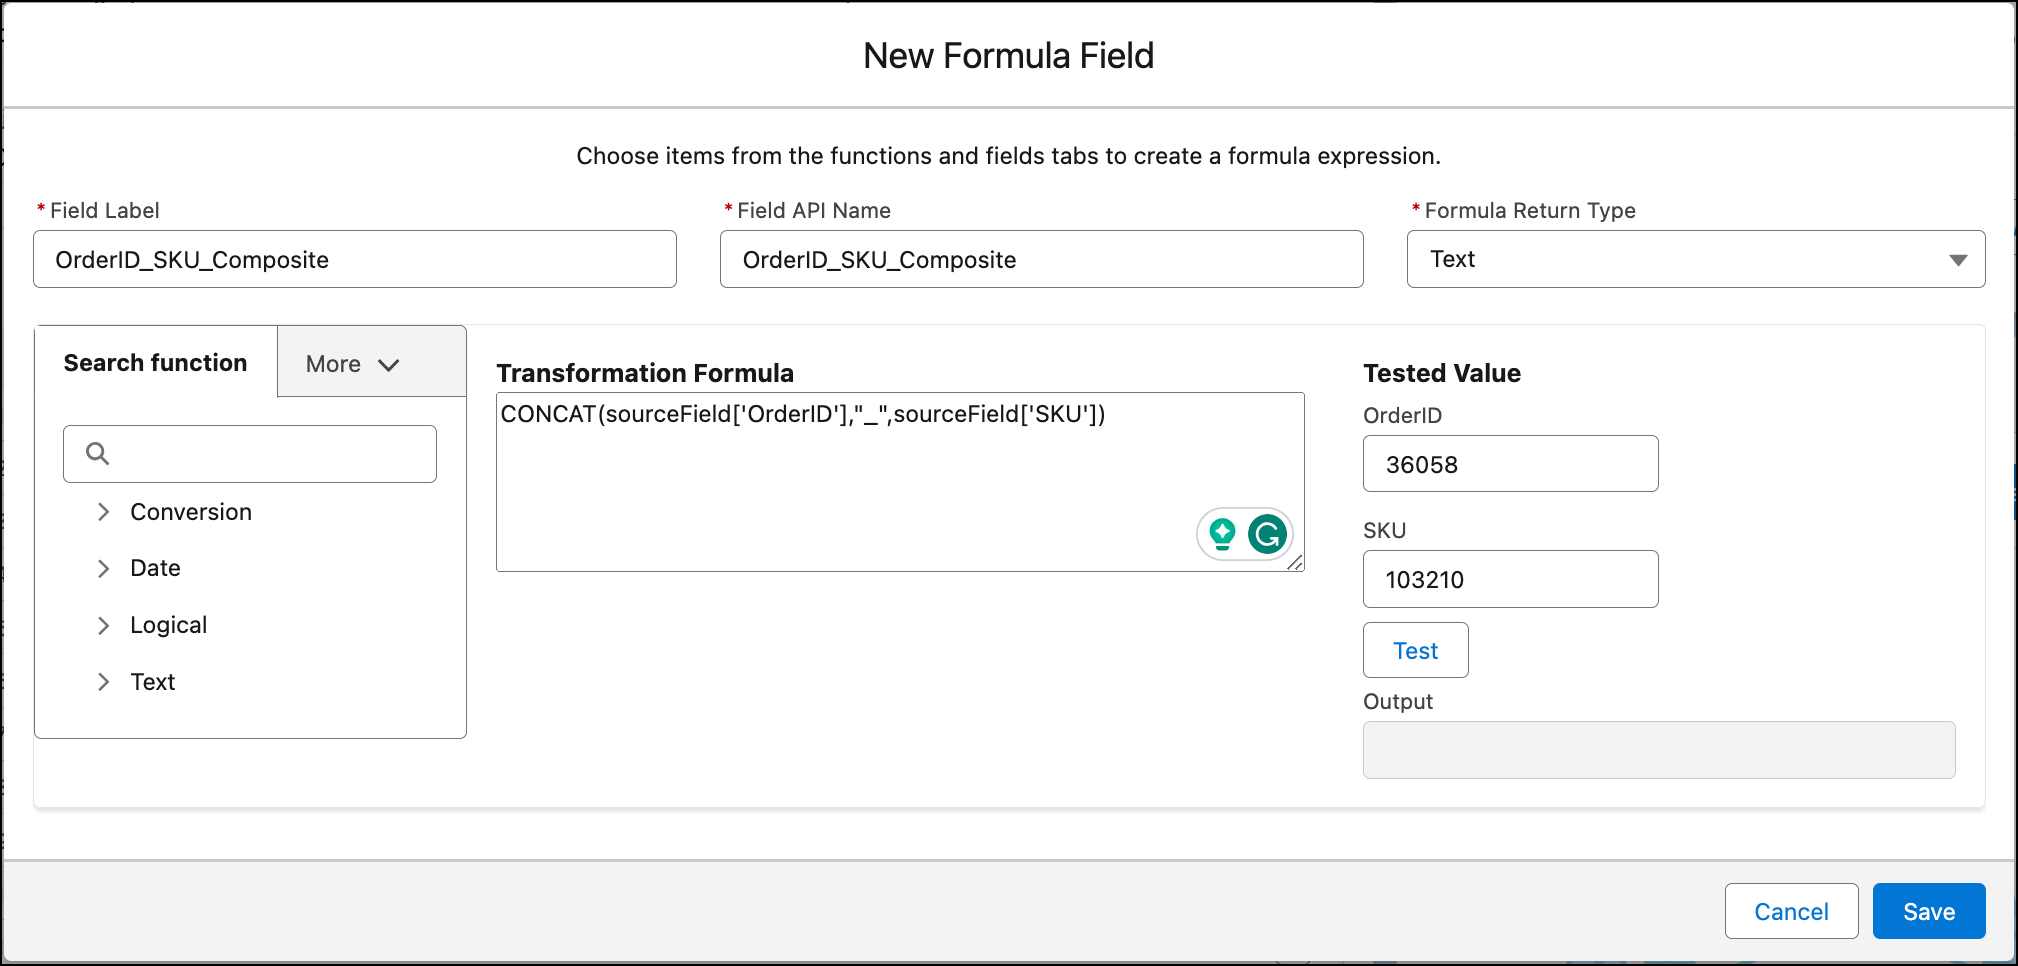
- In cases where the data source table has an existing primary key or not all rows have unique values, use the [formula field](https://help.salesforce.com/s/articleView?id=data.c360_a_formula_expression_library.htm&type=5&language=en_US) to define a formula that can combine two or more source fields to generate a composite key.

Note A formula is ideal for file-based data sources such as Amazon S3, Google Cloud Storage, Microsoft Azure, and Secure File Transfer (STFP).
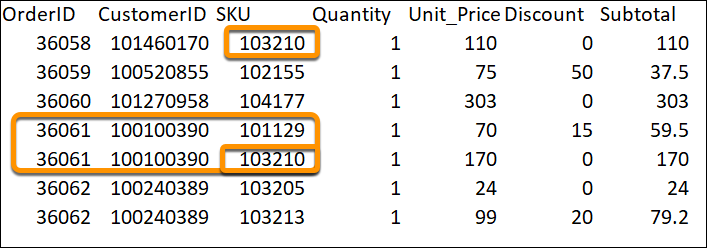
For example, in this Sales Order Detail database, not all rows have unique values. By combining the Order ID and SKU fields, you can use a formula to generate a composite key and configure it as the primary key for your data source.
Use the formula field functionality to define a formula that can transform your fields to provide a composite key.
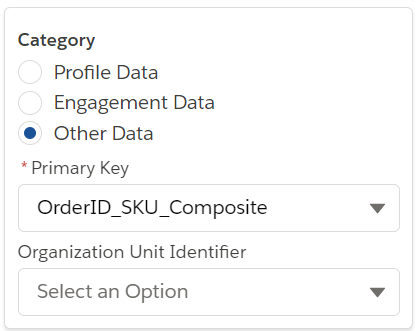
After you create the formula field “OrderID\_SKU\_Composite”, it can be configured as the primary key for your data source.
# Configurations
Use these configuration steps to welcome new loyalty members to your program.
## Connect Loyalty Management to Marketing Cloud Engagement
Implement Marketing Cloud Connect to connect Marketing Cloud Engagement and Loyalty Management.
- Configure Marketing Cloud Engagement and Marketing Cloud Connect.
- In Salesforce, assign the Loyalty Management permission set to the Marketing Cloud Connect system user.
- In Salesforce, for the Marketing Cloud Engagement system user profile, select **Marketing User**.
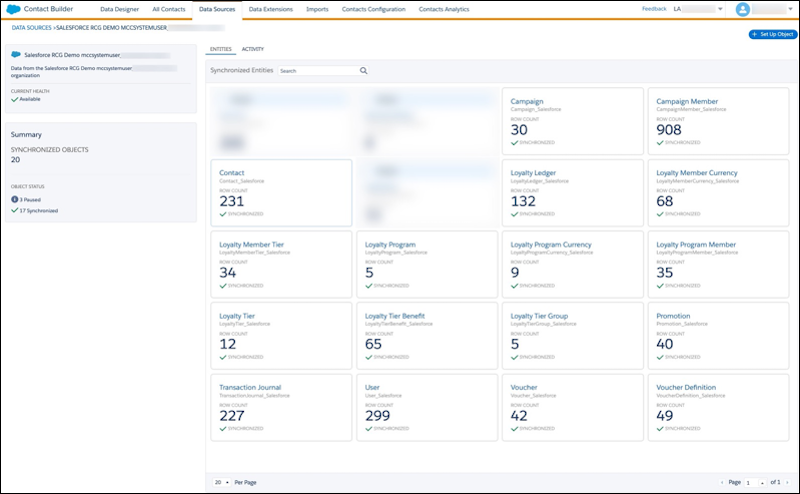
- To ensure proper mapping, synchronize the Loyalty [data extensions](https://help.salesforce.com/s/articleView?id=xcloud.content_block.htm&type=5&language=en_US) in this order.
- Contact and User
- Loyalty Program and Campaign
- Loyalty Tier Group and Campaign Member
- Loyalty Program Currency, Loyalty Program Member, Loyalty Tier, Loyalty Tier Benefit, and Voucher Definition
- Loyalty Member Currency, Loyalty Member Tier, Promotion, and Transaction Journal
- Loyalty Ledger and Voucher
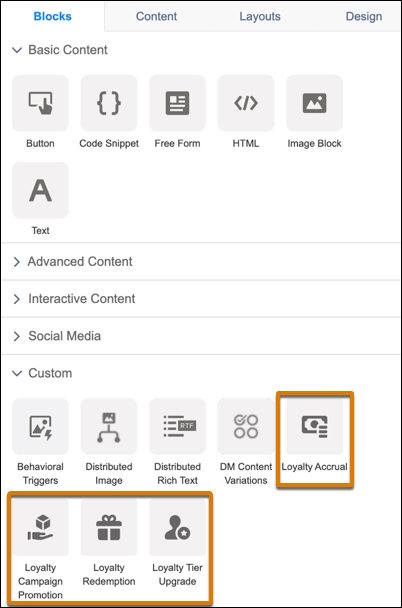
- Install the [Loyalty Management Content Blocks managed package](https://sf-industries.my.salesforce-sites.com/loyaltymanagementcontentblocks) for Marketing Cloud Engagement.
## Welcome New Loyalty Members to Your Program via Marketing Cloud Engagement
- Build an email in Marketing Cloud Engagement welcoming members to your loyalty program.
- [Create a Welcome Journey](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_welcome_campaigns.htm&type=5&language=en_US) in Marketing Cloud Engagement to deliver personalized loyalty welcome emails to members.
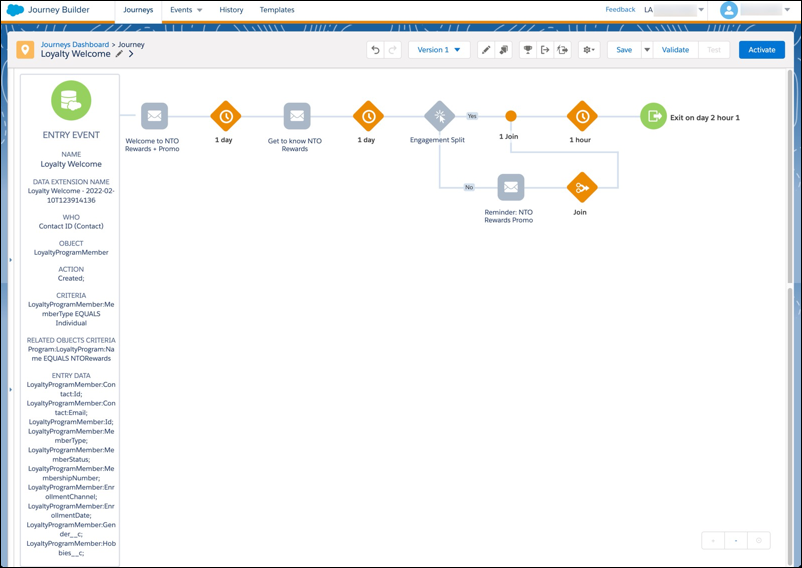
- Add wait periods, splits, and defined customer touchpoints.
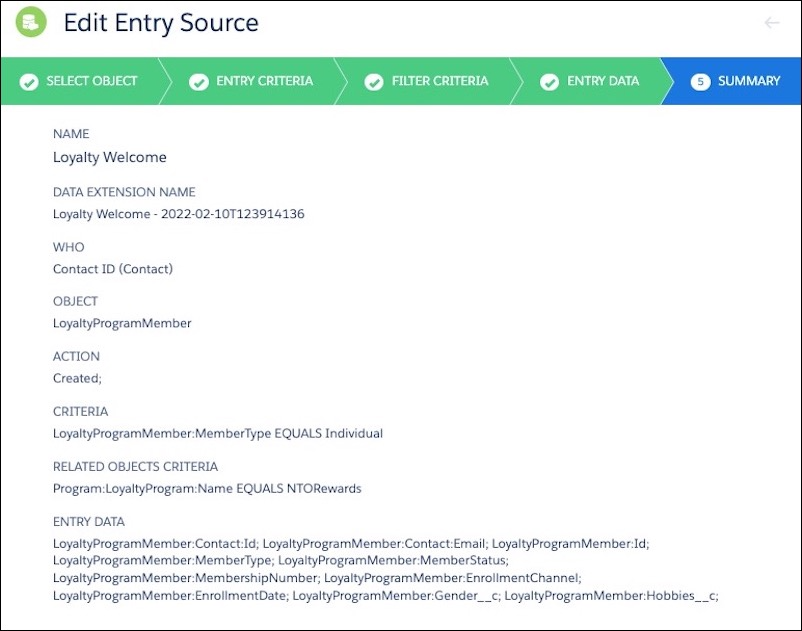
- To capture newly enrolled loyalty members, [define a Salesforce data entry](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_configure_salesforce_data_event.htm&type=5&language=en_US) based on the Loyalty Program Member object.
Some marketing campaigns related to your Loyalty Program require using queries for journey entry. Use the query’s resulting data extension for the journey entry. To include [decisions splits](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_use_decision_splits.htm&type=5&language=en_US), create additional queries. Consider Marketing Cloud Engagement query performance when designing your solution.
- Query activities time out after 30 minutes. Multiple factors can cause query timeouts.
- If the query activity is part of an automation, don’t add other activities to the same step of the automation.
Alternatively, you can use an [API entry event](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_admit_contacts_via_api.htm&type=5&language=en_US) to add the loyalty member to the journey directly from B2C Commerce or Salesforce Flow. To initiate the journey using REST API event, see [Interaction: Fire the Event](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/postEvent.html).
#### See Also
- [_Salesforce Help_: Marketing Cloud Connect](https://help.salesforce.com/s/articleView?id=mktg.mc_co_marketing_cloud_connect.htm&type=5&language=en_US)
- [_Salesforce Help_: Integrate Loyalty Management with Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=xcloud.loyalty_mc_integration.htm&type=5&language=en_US)
- [_Salesforce Help_: Configure Marketing Cloud Connect](https://help.salesforce.com/s/articleView?id=mktg.mc_co_configure_the_marketing_cloud.htm&type=5&language=en_US)
- [_Salesforce Knowledge_: Campaign Object Syncing Permissions](https://help.salesforce.com/s/articleView?id=000383948&type=1&language=en_US)
- [_Salesforce Help_: Optimizing a SQL Query Activity](https://help.salesforce.com/s/articleView?id=mktg.mc_as_optimize_the_query_activity.htm&type=5&language=en_US)
- [_Salesforce Help_: SQL Reference](https://help.salesforce.com/s/articleView?id=mktg.mc_as_sql_reference.htm&type=5&language=en_US)
- [_Salesforce Help_: Optimize Journey Builder Performance](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_optimize_sending_in_journey_builder.htm&type=5&language=en_US)
- [_Salesforce Help_: Journey Entry Source: Data Extension](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_data_extension.htm&type=5&language=en_US)
# Configure a Data Extension to Store a Data Action Payload
If you’re using a Marketing Cloud Engagement data action target to enrich a data action, configure a data extension to store the data action payload.
1. Create a data extension with two attributes: one for storing the subscriber key, and the other for storing the nested JSON payload.
- Subscriber key
- Name: Match the Data Cloud object’s field API name
- Data Type: Match the Data Cloud object’s field data type
- Nested JSON payload
- Name: Match the Data Cloud data graph API name
- Data Type: Text
- Length: Up to 4000 characters (the length can vary based on your output payload and the number of supported characters in Marketing Cloud.)
2. For both attributes, select **Nullable** and leave **Default Value** empty.
After creating the data extension, parse the data graph data from the attribute using a supported scripting language in Email Studio.

Example Sample AMPscript to parse the nested JSON payload
```
%%[
SET @NESTEDDG = Concat('[', AttributeValue("WebinarDataGraph"), ']')
/* Extract root level fields */
SET @RS = BuildRowsetFromJson(@NESTEDDG, '$.[*]', 1)
SET @Row = Row(@RS, 1)
SET @Id__c = Field(@Row, "Id__c")
SET @PersonName__c = Field(@Row, "PersonName__c")
SET @TitleName__c = Field(@Row, "TitleName__c")
SET @LastName__c = Field(@Row, "LastName__c")
/* Extract nested JSON array pzn_UnifiedLoyaltyBalance__cio */
SET @LoyaltyArray = BuildRowsetFromJson(@NESTEDDG, '$.[*].pzn_UnifiedLoyaltyBalance__cio[*]', 1)
SET @LoyaltyArrayRow = Row(@LoyaltyArray, 1)
SET @totalpoints__c = Field(@LoyaltyArrayRow, "totalpoints__c")
SET @unifiedindividualid__c = Field(@LoyaltyArrayRow, "unifiedindividualid__c")
]%%
```
#### See Also
- [_Salesforce Help_: Create a Data Extension in Contact Builder](https://help.salesforce.com/s/articleView?id=sf.mc_cab_create_a_new_data_extension.htm&language=en_US)
- [_Salesforce Help_: Personalization in the Journey Builder Email Activity](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_personalization_in_the_journey_builder_send_email_activity.htm&type=5&language=en_US)
- [_Salesforce Help_: Create a Data Action in Data 360](https://help.salesforce.com/s/articleView?language=en_US&id=sf.c360_a_create_a_data_action_in_customer_data_platform.htm)
# Configure a Key Qualifier Field
After creating a data stream, add key qualifiers to your data lake object (DLO) fields to create fully qualified keys (FQK). Configure key qualifiers for all DLO fields that contain either a primary or foreign key. You can add up to 20 active key qualifiers. A key qualifier is active when it's used for a DLO field. Data 360 automatically adds and removes key qualifiers to and from data model object (DMO) fields. You can't edit these system fields.
### Required Editions

Note To add key qualifiers to a companion org, add them to the home org and wait at least 10 minutes for the companion org to sync with the home org.
1. Go to the Data Lake Objects tab.
2. Select the DLO and the DLO field.
3. For the field, click , and select **Add Key Qualifier**.
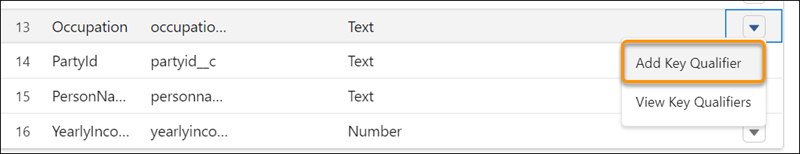
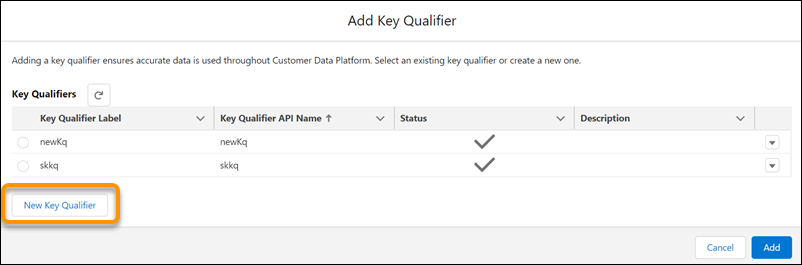
4. You can either add an existing key qualifier or create one.
1. To add an existing key qualifier, select a key qualifier label, and click **Add**.
2. To create a key qualifier, click **New Key Qualifier** and enter a label, API name, and an optional description.
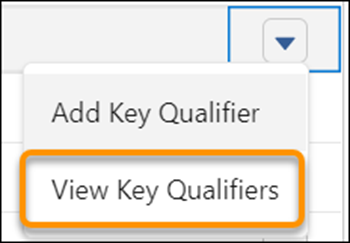
3. To view existing key qualifiers and fields that share key qualifiers, click  for the data lake object field, and select **View Key Qualifiers**. Filter or search to target your results.
# Configure a Propensity to Buy Template (Beta)
Configure the Propensity to Buy (beta) template to automatically create the data transforms, output data model objects, and predictive model required to generate propensity scores. Query the scores to assess a customer's likelihood of making a purchase within your specified prediction window.
### Required Editions

Note This template is unavailable in the Developer edition.
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
## Set Up and Query the Template
1. Configure and run the template.
1. Click the App Launcher, search for Data Cloud, and then select it.
2. Click the **AI Models** tab.
3. From the Predictive section, click **Create from Template**.
4. Select Propensity to Buy, and then click **Next**.
5. Specify a name and description for your template configuration.
The system names all generated data transforms and model assets based on the configuration name that you provide.
6. Select the target data space, the product that you want to evaluate, and the time horizon (prediction window). Optionally specify a product category.
7. To run the template configuration, click **Train**.
2. Monitor the template installation.
To monitor the template installation, from Setup, go to **App Hub** > **Scoring**, and **Templates**.
https://
/lightning/setup/AppHub/home (Org Setup → App Hub)
https:///lightning/setup/ScoringFramework/home (Org Setup → Scoring)
https:///lightning/setup/TemplateStudio/home (Org Setup → Templates)
- The template installations create these seven assets: 3 transforms, 3 output DMOs, and 1 model. To verify that all assets are successfully created and executed, go to these Data 360 tabs: DataTransforms, Data Model Object, and AI Models.
- Propensity Training Transform
- Propensity Inference Transform
- Propensity Scoring Transform
- Propensity Scoring Model
- PropensityTraining\_\_dlm(output DMO)
- PropensityInference\_\_dlm (output DMO)
- PropensityScoring\_\_dlm (output DMO)
Asset names vary depending on the configuration name that you specify. For example, if you name your configuration "Shirt", the template automatically creates these assets.
Shirt Scoring Transform Definition
ShirtPropensityScoringData1\_\_dlm
Shirt - Propensity Scoring Model
3. Query propensity scores.
To validate the generated scores that predict purchase likelihood within your specified prediction window, run a query on the
PropensityScoring\_\_dlm
data lake object (DLO) in the Query Editor. For example, run this query on your data space to return the first 1,000 records.
```
SELECT Id__c, ProductPropensityScore__c FROM PropensityScoringData__dlm
ORDER BY Id__c DESC LIMIT 1000
```
Replace **PropensityScoringData\_\_dlm** with the name of your output DMO with predictions. For example, ShirtPropensityScoringData1\_\_dlm.
To verify that your template assets were successfully created and executed based on your configuration name, first go to the Data Transforms tab and verify that these assets exist. Then go to the AI Models tab and verify that your model is active. Check that your template created the seven assets based on your configuration name.
## Considerations
**Data Requirements**
Use at least 6 months of purchase history and behavioral engagement data, such as browse and cart events, for the individuals in your data space. Model Builder requires at least 400 records to build a model. Limited transaction history or sparse engagement data can result in scores that don't reflect purchase intent.
Individuals with no purchase history or minimal engagement data receive low-confidence scores. Treat these scores as insufficient data rather than low purchase intent. Products need historical sales data to produce meaningful propensity scores.
**Score Interpretation**
The ProductPropensityScore\_\_c value represents the relative likelihood that an individual purchases the specified product or product category within the configured prediction window. Most individuals receive low scores because the base purchase rate for a single product is typically below 5%.
Segment scores by decile or percentile for activation. For example, target the top 10–20% of scored individuals instead of applying a fixed numeric threshold. Score distributions vary by product and data volume.
**Time Horizon and Freshness**
The prediction window affects the model's predictions. Shorter windows favor recent behavioral signals, such as active cart events, while longer windows weigh historical purchase patterns more heavily.
Scores are point-in-time predictions and become unreliable after the prediction window passes. To keep scores current, rerun the inference transform at a cadence equal to or shorter than the configured prediction window.
**Scheduling and Execution**
The template creates Training, Inference, and Scoring batch data transforms that run in sequence. The transforms aren't automatically scheduled after initial creation. Manually rerun or schedule the transforms and model retraining to keep scores current. Execution time increases with data volume.
**Scale**
The template generates scores for each individual-product or individual-product category combination. The output DMO (PropensityScoring\_\_dlm) can grow significantly when a data space contains many individuals and products. Plan your storage and query strategy accordingly.
Each template configuration targets one product or product category. To score multiple products, create a separate configuration for each product or select a product category during configuration.
**Credit Consumption**
The template consumes credits when it creates transforms for training and scoring data. Because this template is deterministic, it doesn't consume agentic credits.
**Other**
The template supports only the standard Data Cloud objects and fields listed in [Propensity to Buy Template (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_template_propensity_to_buy.htm&release=264.0.0&type=5 "The Propensity to Buy template establishes a starting point for predicting which customer will buy a product or product category within a particular time frame. The template preconfigures model details, prediction inputs, and selects an algorithm. To align the model with your data, customize default variables and set a prediction window—the number of days used to calculate the purchase likelihood. After model training, Model Builder generates purchase likelihood scores on your records so you can identify high-value customer segments and drive targeted marketing campaigns."). You can't add custom DMOs or custom fields to the model configuration. Scoring is batch only. Real-time, event-triggered scoring isn't supported.
# Configure an AWS Identity Provider for Clean Room Activation
For each clean room activation collaboration invitation, configure your AWS account so that Data 360 can securely write query results to your S3 bucket, then accept the invitation in Data 360.
### Required Editions
Available in: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
User Permissions Needed
To accept a clean room activation invitation:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
Data 360 uses an AWS IAM role with an OpenID Connect (OIDC) trust policy to write collaboration results directly to the provider's S3 bucket. The provider maintains full ownership of the data — Data 360 has write-only access to the specific S3 path you configure, scoped to this collaboration only.
1. Complete the prerequisites.
1. If you don't have access to a dedicated AWS environment, create one.
2. In Data 360, go to the Clean Room tab and open the pending activation collaboration invitation and note these values.
- **Consumer Salesforce Domain URL** — used as the identity provider URL
- **External ID** — a unique identifier scoped to this collaboration
Set Up Your AWS Environment
1. Add Salesforce as an OpenID Connect (OIDC) identity provider.
An identity provider tells AWS which external system is allowed to request access to your AWS resources. Without this step, AWS doesn't recognize tokens issued by Data 360 and rejects the connection.
1. In the AWS Management Console, go to **IAM** > **Identity providers** and click **Add provider**.
2. For the **Configure provider** field, choose **OpenID Connect**.
3. For the **Provider URL**, enter the Consumer Salesforce Domain URL followed by `/services/connectors`.
For example: `https://yourorg.my.salesforce.com/services/connectors`
4. For **Audience**, enter the Consumer Salesforce Domain URL without any path suffix.
For example: `https://yourorg.my.salesforce.com`
5. Click **Add provider**.
2. Select or create an S3 bucket for activation results.
This is the bucket where Data 360 writes the matched audience output after the consumer runs an activation query. You can use an existing bucket or create a dedicated one.
Note the S3 bucket name and path — you enter this value as the **Amazon S3 URL** in Data 360, in the format `s3://your-bucket-name/optional-prefix/`.

Note Data 360 appends collaboration-specific metadata to your provided path. If you provide `s3://my-results/`, the final data resides at: `s3://my-results/[Collaboration Name]/[Query Name]_[Timestamp]/[Data Files]`. Each query run creates a folder. Results are written as parquet files.
3. Create the necessary IAM roles.
See [Creating a role using custom trust policies (console)](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-custom.html).
On the **Add permissions** screen, add permissions that can check whether an appropriate bucket exists and can be written to. See [Amazon S3 Bucket Policies and Permissions](https://help.salesforce.com/s/articleView?id=c360_a_s3_bucket_policies.htm&language=en_US&type=5) for the permission policies you can apply to the role.
Copy the Amazon Resource Name (ARN) of the IAM role. You enter this value in the Accept Clean Room Collaboration Invitation wizard.
4. Apply the trust policy to the IAM role.
In the **Custom trust policy** section, click **Edit trust policy** and replace the existing JSON with the following template.
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"Federated": "arn:aws:iam::[YOUR_ACCOUNT_ID]:oidc-provider/[SALESFORCE_CONSUMER_URL]/services/connectors"
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
"[SALESFORCE_CONSUMER_URL]/services/connectors:sub": "[EXTERNAL_ID]"
}
}
}
]
}
```
Replace the placeholders with the following values.
| Placeholder | Required Value | Where to find the Value |
| --- | --- | --- |
| `` | Your 12-digit AWS account ID. | Top-right menu in the AWS console. |
| `` | The Consumer Salesforce Domain URL without `https://`. For example: `yourorg.my.salesforce.com`. | **Consumer Salesforce Domain URL** on the Data 360 invitation screen. This value appears in two places in the policy — the Principal ARN and the Condition key. |
| `` | The External ID value. | **External ID** on the Data 360 invitation screen. |
5. Before returning to Data 360, confirm that you have these values from AWS — you enter them in the acceptance wizard.
| Value | Where to find it in AWS |
| --- | --- |
| Amazon IAM Role ARN | The Role ARN you copied when creating the IAM role in step 3 |
| Amazon S3 URL | The S3 bucket path from step 2, in the format `s3://your-bucket-name/optional-prefix/` |
Accept the Collaboration Invite in Data 360
1. Return to the Accept Clean Room Collaboration Invitation screen in Data 360 and complete the standard acceptance steps: select a data space and create a mapped template.
2. In the **AWS Trust Relationship** section, verify that the **External ID** and **Consumer Salesforce Domain URL** values shown on screen match what you used in the trust policy in AWS.
These values are read-only — they're shown here so that you can confirm that your AWS setup is correct before proceeding.
3. In the **AWS Connection Settings** section, enter the values you noted at the end of Step 2.
- **Amazon IAM Role ARN** — the ARN of the role you created
- **Amazon S3 URL** — the S3 path where results are written
4. Click **Test Connection**.
Data 360 verifies the OIDC trust, IAM permissions, and S3 path access. If the test fails, check that:
- The `sub` condition in the trust policy exactly matches the **External ID** shown on screen.
- The OIDC provider URL and Audience in AWS match the **Consumer Salesforce Domain URL** from the invitation.
- The `` placeholder in the trust policy doesn't include `https://`.
- The IAM role ARN is correct and the role has S3 write permissions.
5. Click **Next** and accept the invitation.
# Configure and Test a Model in Model Playground
Create, edit, and evaluate your model configuration in Model Playground without the need for setup or specialized technical expertise. Model Playground uses a trust layer, which ensures data privacy and security.
- **[Create a Model Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_configure.htm&release=264.0.0&type=5)**
After you add a foundation model, you can create an associated model configuration for a specific use case.
- **[Data Masking](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_data_masking.htm&release=264.0.0&type=5)**
Data masking settings in your Salesforce org and Model Playground determine the privacy of sensitive information and how that data is surfaced in a prompt response. Org-level settings are enabled by default.
- **[Edit a Model Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_configured_edit.htm&release=264.0.0&type=5)**
Try different prompts and adjust your hyperparameters to evaluate how well the model responds to your prompts. However, if your model is already associated with prompts, create a new model instead. Updating model settings can affect the performance of associated prompts.
- **[Test Your Prompt](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_configured_prompts.htm&release=264.0.0&type=5)**
Before you put a model into production, test it using prompts in Model Playground to evaluate the generated responses based on your model’s hyperparameter settings.
- **[Create a Prompt Template](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_prompt_templates.htm&release=264.0.0&type=5)**
If you're satisfied with your model's response to one or more test prompts in Model Playground, create your prompt templates.
#### See Also
- [_Salesforce Help_: Set Up Einstein Trust Layer](https://help.salesforce.com/s/articleView?id=ai.generative_ai_trust_setup.htm&type=5&language=en_US)
# Configure Automatic Content Tagging (Beta)
Configure automatic content tagging for unstructured files and define a confidence threshold. Data 360 approves tags that meet or exceed the threshold, but others require manual review.
### Required Editions
Content tagging is applied to unstructured content and requires a search index to be populated first. Once you enable automatic tagging, the system applies it to all new unstructured data in the selected objects.
To use automatic content tagging, provision your org with the Dynamic Data Masking SKU. This license enables the security and governance policies that allow Data 360 to classify and mask sensitive data. See [Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&type=5&language=en_US).

Note Content tagging and unstructured data masking is a pilot or beta service that is subject to the Beta Services Terms at [Agreements - Salesforce.com](https://www.salesforce.com/company/legal/agreements/) or a written Unified Pilot Agreement if executed by Customer, and applicable terms in the [Product Terms Directory](https://ptd.salesforce.com/). Use of this pilot or beta service is at the Customer's sole discretion.
To configure automatic content tagging:
1. In Data Cloud, go to the Data Governance tab.
2. From the left navigation, go to **Tag Assignments** > **Content Tagging**, and select the **Objects Selected for Automatic Content Tagging** dropdown.
3. To edit the content tagging settings, click **Edit**.
Content tagging is applied to unstructured content and requires a search index to be populated first. Once you enable automatic tagging, the system applies it to all new unstructured data in the selected objects.
You can tag UDLOs up to 5 GB per object. For larger data, split it into multiple UDLOs and create separate search indexes. When the total size exceeds 5 GB, rebuilding the search index removes all existing tags, leaving previously protected data unprotected.
4. To enable automatic tagging, select **Enable Automatic Content Tagging**.
5. From the **Automatic Content Tagging Threshold** dropdown, select the confidence threshold for tags to be automatically approved. The confidence threshold controls how strictly tags are automatically approved.
- Low: Tags are applied to all data, regardless of accuracy.
- Medium: Tags are applied only to data with moderate to high accuracy.
- High: Tags are applied only to data with high accuracy, reducing errors but limiting automatic tagging.
6. Click **Save Settings**.
7. To review discovered content tags and see how many were applied based on the tagging threshold, go to **Tags** > **Tag Manager** and select the search index for your UDLO.
# Configure Communication Capping Parameters and Values
Define communication capping parameters such as channels and departments that are relevant to your organization and business strategy. You must configure the capping parameters and values before creating capping rules.
### Required Editions
User Permissions Needed
To configure communication capping:
System Admin profile
1. Click the gear icon, and then select **Data Cloud Setup**.
If you don’t see this option, refresh your page, or log out and log back in with your admin user credentials.
2. In the Quick Find box, enter and select **Communication Capping**.
3. Under Enterprise Parameters, from the dropdown list, select the communication channels.
4. To apply capping to specific lines of business or category, click **Add New Enterprise Parameter**.
1. Select **User defined**, and enter a parameter name and values. For example, if your organization handles multiple lines of business, you could add Department as a user-defined parameter and add values such as insurance, mortgage, credit card, etc. You can add up to two parameters and arrange them in the preferred order by using the sorting icon.
2. To apply capping to a city, select **City** and enter the city names in the Values field.
5. Under Functional Parameters, select how often you want to run capping rules.
1. Daily
2. Monthly - counts communications in the current calendar month, from the first day through the last day of the month. The count resets on the first day of the next month.
Limits are applied at both the profile and parameter levels.
- Profile limits apply rules to individual profiles. Use these to ensure compliance to regulations and prevent message fatigue. For example, limit emails to 10 per day for any individual customer.
- Dimension limits apply capping rules to all customers that fit certain parameter values. Use these when managing budgets across multiple parameters. For example, limit emails to 10000 per day for all HNI customers targeted by Insurance.
After defining the capping parameters and values, configure communication capping in Data 360.
# Configure Harmonization for Structured Data
Use this workflow to configure harmonization for structured data such as Salesforce Knowledge.
### Required Editions
User Permissions Needed
To view harmonized content
System admin profile OR Data 360 Architect permission set
Before you begin:
- Confirm that you have enabled the following in your org.
- Data 360
- Lightning Knowledge
- Confirm that the Salesforce Experience site has knowledge [enabled](https://help.salesforce.com/s/articleView?id=experience.networks_knowledge_access.htm&type=5&language=en_US), your org has a [knowledge base](https://help.salesforce.com/s/articleView?id=service.knowledge_whatis.htm&type=5&language=en_US), and your users have been granted access to [Lightning Knowledge](https://help.salesforce.com/s/articleView?id=service.knowledge_setup_users_lex.htm&type=5&language=en_US).
- Verify that you’ve created a [layout](https://help.salesforce.com/s/articleView?id=service.knowledge_lightning_page_layouts.htm&type=5&language=en_US) page for your Lightning Knowledge component.
#### See Also
- [_Salesforce Help_: Content and Knowledge Harmonization](https://help.salesforce.com/s/articleView?id=data.c360_a_harmonize_content_for_consistent_viewing.htm&release=264.0.0&type=5 "Use Harmonization to transform knowledge articles and unstructured content ingested into Data 360. Harmonization normalizes and enriches content, resulting in a single harmonized schema suited for consistent rendering in the Content Viewer. Access the viewer through Data 360's Data Explorer or in Service Cloud's Enterprise Knowledge component.")
- [_Salesforce Help_: Content Harmonization Known Limitations](https://help.salesforce.com/s/articleView?id=data.content_harmonization_known_limitations.htm&language=en_US)
- [_Download_: Salesforce Customer Data 360 Rate Card](https://www.salesforce.com/en-us/wp-content/uploads/sites/4/documents/platform/data-cloud-platform-services-rate-sheet-dc-9-04.pdf)
## Step 1. Ingest content into Data 360
Get your Knowledge content into Data 360 through the [CRM Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&type=5&language=en_US).
## Step 1: Create a Harmonization Configuration and Pair It with a DMO
Create a harmonization configuration, give it a name and pair it with a data model object (DMO).
1. From the **App Launcher**, open **Data Cloud**
2. Click **Content Processing** (open the More menu, if you don’t see it).
3. Click **Harmonization**.
4. Click **New**.
5. From the **Data Space** dropdown, select the data space you want to bring knowledge content from.
6. From the **DMO Type** dropdown, select **Structured**.
Optionally, you can filter for the DMO you want to use to hold your knowledge content with the search bar.
7. From the results list, select the DMO, for example Knowledge\_\_kav\_Home.

Note If you’re ingesting data from a Companion org, select the DMO specific to that remote connection (for example, Knowledge\_\_kav\_Remote ).
8. In the **Harmonization Details** section, enter a name for the **Harmonization Configuration Name**. The **Harmonization Configuration API Name** automatically populates with the name that you provide, but you can change it. The API name must be unique.
9. Click **Next**.
## Step 2: Create a Default and Fallback Layout
Knowledge page layouts are used to determine the fields displayed and their order when rendering harmonized Knowledge Articles.
When setting up the Data Stream for the [CRM connector](https://help.salesforce.com/s/articleView?id%3Ddata.c360_a_set_up_crm_connection&language=en_US), only the fields you reference in your Knowledge page layout are included in the data stream field mapping. These fields are also mapped to the Knowledge Article Version DMO.
When Knowledge is used with Data 360, and the Knowledge Object Layout isn’t available for a user, the [Content Viewer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer&language=en_US) uses the fallback layout you set. Make sure that the fields you set have field level permissions or use fields available to all users.
1. Select and arrange fields from the list of available fields. To select, move the field to the **Fallback Layout Fields** list. To remove, move the field back to the DMO Fields list. Arrange the order in the **Fallback Layout Fields** list with the up and down arrows. The final order that you select here dictates how Salesforce Knowledge appears.
2. Click **Next**.
## Step 3: Harmonize Attachments (Optional)
Use these instructions to harmonize attachements.
When using the [CRM connector](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector&language=en_US), to ingest knowledge articles, you can decide if you want to harmonize the knowledge article only, or the knowledge article and any files [attached](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_content_document&language=en_US) uses the fallback layout you set. Make sure that the fields you set have field level permissions or use fields available to all users.
If you skip this step, you’ll need to create a new harmonization configuration to include the attachments in the future should you wish to include attachments in the harmonization.
1. From the list of identified attachments, select which attachments[attachments](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_content_document&language=en_US) you want to include with your harmonized content.
2. Click **Next**.
## Step 4: Review Details
Review details and start the harmonization process.
Review details and start the harmonization process. Once it begins, incremental updates occur every 45 minutes. To finalize the settings and complete the harmonization configuration, click **Save**.
## Step 5: Validate Rendering and View Harmonized Content
Validate the harmonized content rendered correctly and use the Content Viewer to see the results.
1. Use the [Harmonization dashboard](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector&language=en_US)to monitor the process.
2. Go to **Data Explorer**, locate your project, click the harmonized data model object (HDMO) record and click **View** to preview.
If you need to change the settings for the HDMO, delete the old HDMO and create a new one. To run the harmonization job at any time, check the HDMO from the [dashboard](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer.htm&type=5&language=en_US) and select **Run Now**. To delete an HDMO, select **Delete**.
Next Step: View Content Viewer User Engagement Insights in Data Explorer
# Configure Harmonization for Unstructured Content
Use this workflow to create an unstructured content harmonization configuration for Data 360 content. The content must be ingested with a supported connector.
### Required Editions
User Permissions Needed
To view harmonized content
System admin profile OR Data 360 Architect permission set
## Step 1: Ingest Content with a Supported Connector
1. Ingest content into Data 360 with any of the [supported connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_harmonize_content_for_consistent_viewing.htm&language=en_US). When you see the checkmark in the UDLO configuration screen to enable Harmonization, check the box. Keep in mind that enabling this feature in the connector uses system defaults which means AI Enrichments (Summary and Q&A) are disabled. If you are comfortable with these settings, you don’t need to proceed any further. If not, continue to complete the steps.
2. Remember its name, as you will need to find the DMO in the Harmonization Dashboard.
3. Confirm the UDMO has completed the ingestion process.
## Step 2: Create a Harmonization Configuration and Pair It with a UDMO
Create a harmonization configuration, give it a name and pair it with a data model object
1. From the **App Launcher**, open **Data Cloud**
2. Click **Content Processing** (open the More menu, if you don’t see it).
3. Click **Harmonization**.
4. Click **New**. The **Select the DMO to Harmonize** screen appears.
5. From the **Data Space** dropdown, select the data space you want to bring content from.
6. To filter the DMOs from the search results you can search by the DMO name or search by the DMO Type. To search by the DMO name, put the name of the DMO into the search field. To search by DMO Type use the dropdown and select **Unstructured** to filter for unstructured DMOs.
7. From the results table, select the row containing the DMO you want to harmonize.
8. In the **Harmonization Configuration Details** section, enter a name for the **Harmonization Configuration Name**. The **Harmonization Configuration API Name** automatically populates with the name that you provide, but you can change it. The API name must be unique.
9. In the **Enable AI Enrichment** section, the Generate summary and Q&A for the content option is activated. Keep it **Active** if you want each harmonized content item to include an AI generated summary at the top of the document as well as a list of Questions and Answers generated by AI for the document. If you do not want to enable this feature, turn off the toggle and confirm it reads **Inactive**.
**Note:**This feature is not completely enabled until you also enable Einstein Generative AI in your org. You can do this afterwards. Note also that this feature is subject to billing and consumption credits once enabled. Salesforce recommends changing the toggle to **Inactive** if you are not going to enable Einstein.
10. Click **Next**.
## Step 3: Review Details
Review details and start the harmonization process.
Review the details of your harmonization configuration. To finalize the settings and complete the harmonization configuration, click **Save**.
## Step 4: Validate Rendering and View Harmonized Content
Validate the harmonized content rendered correctly and use the Content Viewer to see the results.
1. Use the Harmonization [dashboard](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer.htm&type=5&language=en_US) to monitor the process.
2. Go to Data Explorer, locate your project, click the harmonized data model object (HDMO) record and click **View** to preview.
3. Notice that the layout contains a summary and Q&A section (if you enabled it).
If you need to change the settings for the HDMO, delete the old HDMO and create a new one. To run the harmonization job at any time, check the HDMO from the [dashboard](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer.htm&type=5&language=en_US) and select **Run Now**. To delete an HDMO, select **Delete**.
Next Step: [View Content Viewer User Engagement Insights in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_content_viewer_user_engagement_insights_in_data_explorer.htm&release=264.0.0&type=5 "Data 360 automatically creates an engagement telemetry data stream and a data lake object (DLO) to track user engagement with the Content Viewer. The Content Viewer is available only for harmonized content. You can view engagement data from the Data Explorer tab.")
# Configure Identity Resolution Match Rules
Specify how identity resolution identifies matching records in Data 360.
### Required Editions
Permission Sets Needed
To configure match rules
Permission set:
To create or edit match rules:
1. Go to the record homepage of your identity resolution ruleset.
2. In Match Rules, click **Configure** or **Edit**.
3. Click **Add Match Rule**.
Select a default match rule or click **Custom Rule** to create your own. To create a match rule based on party identifier or an external identity link, create a custom rule.
4. Click **Next**.
5. Edit, add, or delete criteria for your match rule. To create a match rule based on party identifier, select the Party Identification data model object and the Identification Number field. To create a match rule based on an external identity link, select the Identity Match data model object and the Identity Match Type field.

Tip Matching on a single contact point isn’t recommended to avoid over grouping, except for unique external identifiers like a party identifier. Matching on single data point, such as phone number or email alone, could mix household members with a shared contact point into a single unified profile. By adding more match criteria, like name or email, you’re less likely to mix household members into a single unified profile.

Note Each ruleset must have at least one match rule. You can't delete the last match rule from a ruleset. To stop a ruleset from running, delete it.
6. To set up cross-object matching, case sensitive matching, or allow blank values to match, click Configure to access the advanced criteria settings. For cross-object matching, the object you want to match to must be modeled properly.
7. Name your match rule with 80 characters or less.
8. Click **Save**.
After saving the ruleset, optionally add filter conditions to control which source records enter the matching process.
To filter records, open the Filters section of the ruleset and define conditions using fields from the primary data model object.
- **[Configure Real-Time Matching in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_configure_real_time_matching.htm&release=264.0.0&type=5)**
You can configure any ruleset for real-time matching after its first ruleset run is completed by creating a real-time data graph based on the ruleset’s output unified profile data model object.
# Configure Omnichannel Journey Settings
Next, Cumulus configures their omnichannel settings. When a journey uses the Omnichannel Credit Limit Alert data extension Entry Source, Journey Builder defaults all orchestration, personalization, and sending lookups based on the value of the MobilePush Key. This Key is represented by the MobilePush SubscriberKey selected from the Calculated Insight. This action enables you to natively send messages using MobilePush activities.
However, the MobilePush Key doesn't natively have an email address or phone number saved to it. To send messages to Email and SMS activities, use the Journey Settings feature to tell Journey Builder which addresses in the data extension to use for those send activities.
1. In Journey Builder, select **Settings** and click **Journey Settings**.
2. For Contact Entry, select **Re-entry only after exiting**.
3. For Default Email Address, select **Use attributes from Entry Source** and then select the **Email Address** attribute from the dropdown.

Note To use an email address from another data extension, select Use attributes from [Contacts](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_journey_contact_data.htm&type=5&language=en_US) and then choose an attribute from the Contact Model.
4. For Default Mobile Number, select **Use attributes from Entry Source** and then select the **Phone Number** attribute from the dropdown.
5. Click **Done**.
# Configure Omnichannel Journey Settings in Marketing Cloud Engagement
After the scheduled activation, a data extension is added to the Marketing Cloud Engagement business unit identified in activation. Edit this data extension and update its send relationship to relate the MobilePush Key attribute to SubscriberKey. As a result, Journey Builder defaults all orchestration, personalization, and sending lookups based on the value of the MobilePush Key (representing the MobilePush SubscriberKey selected from the Calculated Insight you created).
# Configure Periodic Full Refresh Interval
The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered. By default, the full refresh configurable interval is disabled (set as None). You can configure its value during a bundle or multi-object data stream deployment or for an existing data stream.
### Required Editions
User Permissions Needed
To configure periodic full refresh
System admin profile OR
Data 360 Architect permission
set
Configure a periodic full refresh interval during a bundle or multi-object deployment. This interval is used to determine when the full refresh is triggered.

Note When your data stream is in [streaming mode](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org."), you can't configure the periodic full refresh interval. To sync your data, you can set a full refresh on demand by clicking the **Refresh Now** button for that stream on the **Data Streams** tab. [Learn more about full and incremental refresh on demand](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5 "Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge_kav objects.").
## Configure Periodic Full Refresh Interval During a Bundle or Multi-Object Data Stream Deployment
Configure a periodic full refresh interval during a bundle or multi-object deployment. This interval is used to determine when the full refresh is triggered.
1. In Data 360, go to the Data Streams tab.
2. Click **New** on the top right to create a new data stream.
3. Select **Salesforce CRM** as the connected source.
4. Select the relevant Salesforce org.
5. On the **View Bundles** tab, select a bundle and click **Next** [(learn more about Starter Data Bundles)](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360a-starter-data-bundles.html).
6. Select the included fields and click **Next**.
7. The object table opens. Edit per object the value indicated on the **Full Refresh Interval** column. Choose between **None**, **10 Days**, **25 Days**, or **50 Days**, depending on your organization’s needs.
## Configure Periodic Full Refresh Interval for an Existing Salesforce CRM Connector Data Stream
Configure a periodic full refresh interval for an existing Salesforce CRM connector data stream. This interval is used to determine when the full refresh is triggered.
1. In Data 360, go to the Data Streams tab.
2. Select a Data Stream for the Salesforce CRM connector.
3. From the menu on the top right, select the **Edit Data Stream** option.
4. A modal titled Edit Data Stream opens. For **Full Refresh Interval**, choose between **None**, **10 Days**, **25 Days**, or **50 Days**, depending on your organization’s needs.
# Configure Periodic Full Refresh Schedule
The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered.
### Required Editions
The full refresh schedule is based on a number of variables:
- The date and time of the most recent full refresh.
- A full refresh configurable interval. By default, this interval is disabled (set as None), but you can configure its value during a bundle data stream setup, or for an existing data stream.

Note For existing data streams of developer edition orgs, the periodic full refresh is now disabled by default to save costs where the refresh is not required. To customize the full refresh time, configure the value of the periodic full refresh interval.
- The number of days to reach Friday at 11 PM (server time).
- A random 0.5-1 hour addition.

Example
Suppose a full refresh occurred on December 4th, and the full refresh interval is set to 10 days. The next routine full refresh occurs on December 20, based on this calculation.
- Last full recent refresh: December 4th (Wednesday)
- Plus 10 days: December 14th (Saturday)
- Plus 6 days until Friday: December 20th (Friday)
- Plus random 0.5-1 hour
**Full Refreh Schedule**

#### See Also
- [_Salesforce Help_: Configure Full Refresh Interval](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_full_refresh_interval.htm&release=264.0.0&type=5 "The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered. By default, the full refresh configurable interval is disabled (set as None). You can configure its value during a bundle or multi-object data stream deployment or for an existing data stream.")
# Configure Real-Time Matching in Data 360
You can configure any ruleset for real-time matching after its first ruleset run is completed by creating a real-time data graph based on the ruleset’s output unified profile data model object.
### Required Editions
User Permissions
Needed
To create or edit identity resolution rulesets
Permission set:
1. Set up required mappings.
2. Create an identity resolution ruleset.
3. Run identity resolution.
4. After the run is complete, set up a real-time data graph based on the unified profile created by the ruleset.
5. The real-time data graph is refreshed from the unified individual DMO every 24 hours during the pilot period.
6. During real-time matching, identity resolution matches a specific customer profile to a unified profile in the data graph to return real-time profile data.
# Configure Snowflake Trust Relationship for Clean Room Identity Boost
For each collaboration invitation for the identity boost use case, complete the required Snowflake setup and then accept the invitation in Data 360. Data 360 tests the Snowflake connection automatically on acceptance.
### Required Editions
Available in: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
User Permissions Needed
To create a Snowflake Data Federation connection in Data 360 :
System Admin profile or permission set:
Before you begin:
- Complete [Plan Your Snowflake Environment for Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_plan_snowflake_for_identity_boost.htm&release=264.0.0&type=5 "Before accepting identity boost collaboration invitations, decide how to isolate customer data in your Snowflake account and which region to use. These decisions affect the architecture of every collaboration that you accept, so make them before you receive your first invitation.").
- Open the pending collaboration invitation in Data 360 and note these values from the Accept Clean Room Collaboration Invitation wizard — you need them in the setup steps that follow:
- **External ID** — a unique identifier generated by Data 360 for this collaboration
- **Consumer Salesforce Domain URL** — the consumer's Salesforce org domain
Set Up Your Snowflake Environment
1. In your Snowflake worksheet, open the SQL Editor and complete these tasks to set up the data containers, permissions, and service user.

Note These code examples are for guidance only. Test and validate all code in a sandbox before using it in production.
2. Create a dedicated database and schema for this customer so that their data stays isolated from other collaborations.
```sql
CREATE DATABASE CUSTOMER_DB;
CREATE SCHEMA CUSTOMER_DB.ENRICHED_OUTPUT;
```
Note the database and schema names — you enter them in Data 360 when accepting the invitation.
3. Create the output tables.
These are the tables that your enrichment job writes to. Define all column names in double quotes to preserve case. Without double quotes, Snowflake automatically uppercases column names, which causes errors when Data 360 reads the tables.

Important Define a primary key on each output table. Data 360 reads primary-key metadata when it discovers your tables, and the collaboration can't become active if any output table is missing a primary key. For the email and phone tables, define the primary key on the contact-point value column rather than the party ID, because a party ID can repeat across records.
```sql
-- 1. Bridge Table: links consumer Individual IDs to your internal IDs
CREATE OR REPLACE TABLE CUSTOMER_DB.ENRICHED_OUTPUT.PartnerIndBridgeTable (
"SourceId" VARCHAR(255), -- Consumer's Individual ID
"PartnerIndividualId" VARCHAR(255) -- Your internal unique identifier
);
-- 2. Individual Table: enriched name and identity attributes
CREATE OR REPLACE TABLE CUSTOMER_DB.ENRICHED_OUTPUT.PartnerBoostedIndividualTable (
"IndividualId" VARCHAR(255), -- Matches PartnerIndividualId in bridge table
"ssot__FirstName__c" VARCHAR(255),
"ssot__LastName__c" VARCHAR(255),
"EnrichmentTimestamp" TIMESTAMP_NTZ
);
-- 3. Email Table: enriched email addresses
CREATE OR REPLACE TABLE CUSTOMER_DB.ENRICHED_OUTPUT.PartnerBoostedEmailTable (
"PartyId" VARCHAR(255), -- Links to IndividualId in table 2
"EnrichedEmail" VARCHAR(255),
"EnrichmentTimestamp" TIMESTAMP_NTZ
);
-- 4. Phone Table: enriched phone numbers
CREATE OR REPLACE TABLE CUSTOMER_DB.ENRICHED_OUTPUT.PartnerBoostedPhoneTable (
"PartyId" VARCHAR(255), -- Links to IndividualId in table 2
"EnrichedPhone" VARCHAR(50),
"EnrichmentTimestamp" TIMESTAMP_NTZ
);
```

Note The table names shown here are examples. Use the actual names declared in the additional metadata JSON you provide when accepting the invitation. Data 360 uses the `objectApiName` values in that JSON to find the tables in your Snowflake schema.
4. Deploy your enrichment job and configure it to target this customer's schema.
Set up your job code to read from the Snowflake data share that Data 360 creates in your environment after acceptance, run identity resolution against your identity graph, and write enriched output to the database and schema you created.
Don't run the job yet — the consumer's data is not available in your Snowflake environment until after you accept the invitation in Data 360.

Note If you use a single Snowflake account for multiple customers, the enrichment job can access all databases in that account. Scope the job's execution role strictly to this customer's database and schema, and regularly audit role grants to confirm no cross-customer access.
5. Create a dedicated role for Data 360.
A dedicated role is a named set of permissions that you assign to the Snowflake OIDC service user.
```sql
CREATE ROLE IF NOT EXISTS DATACLOUD_SF_ROLE;
```
6. Grant the role access to a warehouse, database, and schema.
To see the warehouses available in your account, go to **Admin** > **Warehouses** in the Snowflake console and note the name of the warehouse you want to use. These commands give the role permission to use the warehouse and to access this customer's database and schema.
```sql
GRANT USAGE ON WAREHOUSE MY_WH TO ROLE DATACLOUD_SF_ROLE;
GRANT USAGE ON DATABASE CUSTOMER_DB TO ROLE DATACLOUD_SF_ROLE;
GRANT USAGE ON SCHEMA CUSTOMER_DB.ENRICHED_OUTPUT TO ROLE DATACLOUD_SF_ROLE;
```
Replace `MY_WH` with the warehouse name, `CUSTOMER_DB` with the database you created, and `ENRICHED_OUTPUT` with the schema you created. Note the warehouse name — you enter it in Data 360 when accepting the invitation.
7. Grant the role permission to read the output tables.
Data 360 reads the enriched output tables after the enrichment job runs to create the enriched DMOs in the consumer's org. These grants give the role SELECT access on all output tables — both your existing tables and any tables that you create later.
```sql
GRANT SELECT ON ALL TABLES IN SCHEMA CUSTOMER_DB.ENRICHED_OUTPUT TO ROLE DATACLOUD_SF_ROLE;
GRANT SELECT ON FUTURE TABLES IN SCHEMA CUSTOMER_DB.ENRICHED_OUTPUT TO ROLE DATACLOUD_SF_ROLE;
```
8. Create a service user with Workload Identity Federation (OIDC) trust.
This is a dedicated Snowflake user that Data 360 uses to connect to your Snowflake account and read the enriched output tables. Unlike a regular user, it has no password — instead, it trusts login tokens issued by the consumer's Salesforce org. Only Data 360, authenticated as that specific consumer's org, can log in as this user.
Use the **External ID** and **Consumer Salesforce Domain URL** that you noted in the Before you begin section.
```sql
CREATE OR REPLACE USER sf_oidc_user
WORKLOAD_IDENTITY =
(
TYPE = OIDC
ISSUER = 'https://yourcompany.my.salesforce.com/services/connectors'
SUBJECT = 'your-external-id'
OIDC_AUDIENCE_LIST = ('https://yourcompany.my.salesforce.com')
)
TYPE = SERVICE
DEFAULT_ROLE = DATACLOUD_SF_ROLE;
```
- `ISSUER` — Enter the Consumer Salesforce Domain URL followed by `/services/connectors`. This tells Snowflake which Salesforce org can issue login tokens for this user. For example, `https://yourcompany.my.salesforce.com/services/connectors`.
- `SUBJECT` — Enter the External ID. This pins the trust to this specific collaboration — even if the same Salesforce org sends a token, that token can't access a different customer's data.
- `OIDC_AUDIENCE_LIST` — Enter the Consumer Salesforce Domain URL without a path suffix. For example, `https://yourcompany.my.salesforce.com`.

Note Create a service user — don't convert an existing user. Changing an existing Snowflake user to a service user removes that person's ability to log in to Snowflake interactively and mixes their day-to-day permissions with machine access. Doing so makes the account harder to audit and harder to revoke. A dedicated service user keeps Data 360's access fully isolated and easy to remove. If you use a single Snowflake account for multiple customers, include the customer name in the service username to avoid conflicts — for example, `Customer1_DC_User`.
Note the service username — you enter it in Data 360 when accepting the invitation.
9. Assign the role to the service user.
```sql
GRANT ROLE DATACLOUD_SF_ROLE TO USER sf_oidc_user;
```
The service user has the permissions that you set up.
10. Before moving to Data 360, confirm that you have these values from your Snowflake environment — you enter them in the acceptance wizard.
| Field in Data 360 | Value in Snowflake |
| --- | --- |
| Snowflake Account URL | The full URL of your Snowflake account, for example, `https://myorg.snowflakecomputing.com` |
| Service User | The name you gave the service user |
| Data Warehouse Name | The warehouse name that you used |
| Database Name | The database name that you created |
| Schema Name | The schema name that you created |
Accept the Collaboration Invite in Data 360
1. Return to the Accept Clean Room Collaboration Invitation wizard in Data 360 and complete these acceptance steps: select a data space, and then create or select a mapped template.
2. In the **Snowflake Trust Relationship** section, verify that the **External ID** and **Consumer Salesforce Domain URL** values shown on the page match what you used in the `SUBJECT` and `ISSUER` fields when creating the service user in Snowflake.
These values are read-only. Data 360 shows them here so that you can confirm that your Snowflake setup is correct before you proceed.
3. In the **Snowflake Connection Settings** section, enter the values you noted in the setup steps.
- **Snowflake Account URL**: the full URL of your Snowflake account, for example, `https://myorg.snowflakecomputing.com`
- **Service User**: the name of the service user you created in Snowflake
- **Data Warehouse Name**: the warehouse name associated with the service user
- **Database Name**: the database that you created in Snowflake
- **Schema Name**: the schema that you created in Snowflake
4. Click **Test Connection**.
Data 360 attempts to connect to your Snowflake account using the service user. If the test fails, check that the `SUBJECT` and `ISSUER` values in your Snowflake service user exactly match the **External ID** and **Consumer Salesforce Domain URL** shown on the page. Also check that your Snowflake account is in a region compatible with the consumer's Data 360 region.
5. Click **Next** and accept the invitation.
# Configure the Data 360 Engagement Timeline Widget
The Data 360 engagement timeline widget shows engagement data in a chronological format on Account, Contact, Lead, and Person Account records. Configure up to 10 types of engagements at once, and your users can sort them newest or oldest first.
### Required Editions
Available in: Lightning Experience Available in: Data 360 Developer , Enterprise , Performance , and Unlimited Editions
User Permissions Needed
To configure the Data 360 engagement timeline:
Customize Application
Before you configure the widget, enable Data 360. To view the timeline after it's configured, your users need a Data 360 license and access to the configured data space. This configuration does not support control-by-parent. Users must have explicit object-level access to the engagement objects to view records.
You configure the Data 360 engagement timeline on a record page in the Lightning App Builder.
1. Go to an Account, Contact, Lead, or Person Account record. From the gear icon menu, select **Edit Page**.
2. Drag the Data 360 engagement timeline widget to where you want it on the page.
3. From the **Timeline** dropdown menu, select **Create with Unified Profile**.
4. For **Timeline Name**, enter a name.
The widget shows this name.
5. For **Match On Field**, select the field that matches engagement records.
6. For **Data Space**, select a data space.
7. For **Unified Profile Object**, select a unified profile object.
8. For **Engagement Data**, click **Add Object**.
You can configure up to 10 types of engagement objects. Repeat steps 9–16 for each engagement object type that you add.
9. For **Engagement Object**, select the type of engagement object to configure.
10. For **Show Icon**, select the icon for this engagement object type.
11. For **Profile Relationship**, select the engagement-to-profile relationship.
12. For **Title Field**, select the field to show as the engagement's title.
13. For **Subtitle Field**, select the field to show as the engagement's subtitle.
14. For **Timestamp**, select the timestamp that orders the engagements.
15. For **Details Fields**, select any additional fields to show for each engagement.
16. To filter the engagement data for this engagement object, add up to two filters. For each filter, select the field to filter on and the filter operator, and then enter the filter value.
17. Click **Done**.
18. In the upper-right corner of the page, click **Save**.
19. To return from the Lightning App Builder, click the back arrow in the upper-left corner of the page.
# Configure the Data 360 Profile Engagements Lightning App
Use the Lightning App Builder to set up the Data 360 Profile Engagements app to show engagement activity related to a unified profile.
User Permissions Needed To create and save Lightning pages in the Lightning App Builder Customize Application
The app is added by default to the profile explorer’s profile detail page. You can also add it to the Contact record home page in a connected Salesforce org.
1. Go to the Lightning page where you want to configure the app.
2. From the page’s Setup menu, select **Edit Page** to access the Lightning App Builder.
3. Add the Data Cloud Profile Engagements app to the record home page. If it’s already added, click the app to select it.
4. Select a data space. If Default is the only data space option, select **Default**.
5. Select a primary data model object (DMO).
The profile data is drawn from this object.
6. Wait while the unified individual link object is populated.
7. Click **Select** to open the Engagement DMO selection window. Move up to five DMOs from Available to Selected, and then click **OK**.
The app displays data from selected objects, including activity name and date for all objects. For Standard DMOs from default data spaces, it also shows the Engagement Channel Action name.
8. Save and activate the component.
9. By default, data from the last 7 days is displayed. Click the filter icon to choose to display data from the last 30 days or 90 days.
# Configure the Data 360 Profile Insights Lightning App
Use the Lightning App Builder to set up the Data 360 Profile Insights app to show from a measure from a selected calculated insight.
User Permissions Needed To create and save Lightning pages in the Lightning App Builder Customize Application
The app is added by default to the profile explorer’s profile detail page. You can also add it to the Contact record home page in a connected Salesforce org.
1. Go to the Lightning page where you want to configure the app.
2. From the Setup menu on the page, click **Edit Page** to access the Lightning App Builder.
3. Add the Data Cloud Profile Insights app to the record home page. If it’s already added, click the app to select it.
4. Select a data space. If Default is the only data space option, select **Default**.
5. Select a primary data model object (DMO).
The profile data is drawn from this object.
6. Wait while the unified individual link object is populated.
7. Select a calculated insight.
The app can only display measures from a calculated insight with a single dimension.
8. Select a numeric measure to show in the app. If the measure is an amount of money, select **Format as Currency**.
9. Save and activate the component.
# Configure the Data 360 Profile Related Records Lightning App
Use the Lightning App Builder to set up the Data 360 Profile Related Records app to show records related to a unified profile.
User Permissions Needed To create and save Lightning pages in the Lightning App Builder Customize Application
The app is added by default to the profile explorer’s profile detail page. You can also add it to the Contact record home page in a connected Salesforce org.
1. Navigate to the Lightning page where you want to configure a Data Cloud Lightning app.
2. From the Setup menu on the page, click **Edit Page** to access the Lightning App Builder.
3. Add the Data Cloud Profile Related Records app to the record home page. If it’s already added, click the app to select it.
4. Select a data space. If Default is the only data space option, select **Default**.
5. Select a primary data model object (DMO).
The profile data is drawn from this object.
6. Wait while the unified individual link object is populated.
7. Select a related data model object. The app shows records from fields in the object you select.
Only objects directly related to the Unified Individual DMO are available.
8. Click **Select** to open the Select Fields window. Move up to 10 fields from Available to Selected, then click **OK**. Data from selected fields is shown in the app.
9. Select the icon to display on the profile related records app.
10. Save and activate the component.
# Configure the Journey Entry to Use the Activated Data Extension Audience
Next, Cumulus configures its journey entry source.
1. In Marketing Cloud Engagement, navigate to Journey Builder.
2. Click **Create New Journey**.
3. Select **Multi-Step Journey**, and then click **Create**.
4. Name the journey 30-Day Credit Limit Alert.
5. For the Entry Source, drag a Data Extension type onto the canvas.
6. Click the Data Extension icon.
7. Select the folders **Shared Items > Shared Data Extensions > CDP Segments**.
8. Select the **Omnichannel Credit Limit Alert** data extension to use as the Entry Source.
9. Add a filter if applicable, and then click **Done**.
10. Under the configured Data Extension Entry Source, click the **Schedule** icon.
11. Click the **Recurring** journey type.
12. Set the schedule as often as needed.
13. Click **Summary**.
14. Click **Contact Evaluation**.
15. Select **Evaluate new records only**.
16. Select **All records in the file**.
17. Click **Summary**.
18. Click **Done**.
# Configure User Permissions for an External Salesforce Org Connection in Data 360
For non-admin users to connect an external Salesforce org to Data 360, they must have the required user permissions assigned by the main Data 360 account.
1. To connect to Data 360, log in as an admin to the external Salesforce org that you want to connect to Data 360.
2. From Setup, in the Quick Find box, enter Permission Sets, and then select **Permissions Sets**.
3. To create a permission set, click **New**.
4. For Label, enter a name for the permission set.
For example, ManageDataCloudConnections.
5. Make sure Session Activation Required is unchecked for the permission and click **Save**.
To disable session activation on an existing permission set, select the permission set and click edit properties.
6. Assign the following System and User Permissions.
A user must have these system permissions:
- API Enabled
- Connect Org to Data 360
- Customize Application
- Manage Custom Permissions
- View Roles and Role Hierarchy
- View Setup and Configuration
A user must have these user permissions:
- Assign Permission Sets
- Manage Profiles and Permission Sets
7. For each permission, click **Edit**, and then click **Enable**.
8. Click **Save**.
9. In the Permission Changes Confirmation dialog, click **Save**.
10. Click **Manage Assignments**.
11. Click **Add Assignments** and assign this permission set to the user who’s connecting your external CRM org to Data 360.
12. To finish, click **Assign**.
The user now has the appropriate access to connect the external Salesforce org to Data 360.
# Configure Users and Install Service Cloud Data Bundle
Set up Data Cloud users, add the appropriate permission sets, and then install Service Cloud data bundle. These steps are all done within Data Cloud Setup.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
## Set Up a Salesforce Connection in Data Cloud
A data source and data action target are automatically created for the org where you set up Data Cloud. To connect other Salesforce orgs including Sandbox orgs, you must manually set up a connection. If this step isn’t needed, you can skip this section.
1. Go to **Data Cloud Setup**, and under Salesforce Integrations, select **Salesforce CRM**.
2. Click **New**.
3. Click **Connect to a Salesforce org** or **Connect to a Sandbox org**.
4. You can connect to a Data Cloud sandbox or a Salesforce sandbox org as a data source org. Click **Next**.
5. Create an alias for your org using up to 15 alphanumeric characters. You can't change the alias later. Click **Save**.
6. Log in to the org using your Salesforce credentials. The login for a Salesforce production or developer org is https://salesforce.com. The login for a sandbox org is https://test.salesforce.com.
7. Click **Allow** in the Allow Access menu.
Your org is now available from the Salesforce CRM Connectors page.
## Add Users and Permission Sets
Now you can create users with Data Cloud permissions or update existing users to have Data Cloud permission sets.
1. Go to Data Cloud Setup, under User Management, click **Users**.
2. Add new users or edit an existing user.
3. Select a user and click **Permission Set Assignments.**

Note Learn about Data Cloud [standard permission sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&type=5&language=en_US).
4. Click **Edit Assignments**.
5. Select the appropriate Data Cloud permission set and click **Add**.
6. Click **Save**.
Repeat these steps for all users needing access to Data Cloud features.
## Install Service Cloud Data Bundle
After connecting Data 360 to a Salesforce CRM org, install standard (sometimes called starter) data bundles to quickly deploy data within Data 360. A data bundle maps Salesforce objects to Data Cloud data model objects (DMOs).
1. From Setup, select **Data Cloud Setup**.
2. Under Salesforce Integrations, select **Salesforce CRM**.
3. Under Standard Data Bundles, click the dropdown arrow for Service Cloud and click **Install**.
4. In the data kit install interface, select **Install for Admins Only** and click **Install**.
5. When the installation completes, click **Done**.
# Configure Users and Install the Sales Cloud Data Bundle
Set up Data Cloud users, add the appropriate permission sets, and then install the Sales Cloud data bundle. These steps are all done within Data Cloud Setup.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
## Set Up a Salesforce Connection in Data Cloud
A data source and data action target are automatically created for the org where you set up Data Cloud. To connect other Salesforce orgs including Sandbox orgs, you must manually set up a connection. If this step isn’t needed, you can skip this section.
1. Go to **Data Cloud Setup**, and under Salesforce Integrations, select **Salesforce CRM**.
2. Click **New**.
3. Click **Connect to a Salesforce org** or **Connect to a Sandbox org**.
4. You can connect to a Data Cloud sandbox or a Salesforce sandbox org as a data source org. Click **Next**.
5. Create an alias for your org using up to 15 alphanumeric characters. You can't change the alias later. Click **Save**.
6. Log in to the org using your Salesforce credentials. The login for a Salesforce production or developer org is https://salesforce.com. The login for a sandbox org is https://test.salesforce.com.
7. Click **Allow** in the Allow Access menu.
Your org is now available from the Salesforce CRM Connectors page.
## Add Users and Permission Sets
Now you can create users with Data Cloud permissions or update existing users to have Data Cloud permission sets.
1. Go to Data Cloud Setup, under User Management, click **Users**.
2. Add new users or edit an existing user.
3. Select a user and click **Permission Set Assignments.**

Note Learn about Data Cloud [standard permission sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&type=5&language=en_US).
4. Click **Edit Assignments**.
5. Select the appropriate Data Cloud permission set and click **Add**.
6. Click **Save**.
Repeat these steps for all users needing access to Data Cloud features.
## Install the Sales Cloud Data Bundle
After connecting Data 360 to a Salesforce CRM org, install standard (sometimes called starter) data bundles to quickly deploy data within Data 360. A data bundle maps Salesforce objects to Data Cloud data model objects (DMOs).
1. From Setup, select **Data Cloud Setup**.
2. Under Salesforce Integrations, select **Salesforce CRM**.
3. Under Standard Data Bundles, click the dropdown arrow for Sales Cloud and click **Install**.
4. In the data kit install interface, select **Install for Admins Only** and click **Install**.
5. When the installation completes, click **Done**.
# Configuring Data Model Preferences
Learn more about how to configure data model preferences in Data 360.
When ingesting a data stream that includes consumer consent preferences fields, map the fields custom objects or attributes within the Data 360 data model.
If you’re storing consent on standard or custom data model object (DMO), define the appropriate relationships between those objects and the Individual DMO.
If you’re storing consent on multiple DMOs (standard or custom), define the appropriate relationships between those objects.x

Tip We recommend that consent preferences be mapped to objects from the [Privacy Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_privacy_data_model.htm&type=5&language=en_US) but they can be mapped to custom objects as well.
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
# Connect a Databricks Model
To consume predictions in Salesforce, connect your Databricks model with Data 360 and define the prediction criteria for your use case.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In AI Models (formerly Einstein Studio), on the Predictive tab, click **Add Predictive Model**.
2. To choose your model type, click **Connect a Databricks model**. Then click **Next**.
3. To connect the endpoint and access your model inferences, specify these details. Then click **Next**.
- Name—Endpoint name
- URL—Endpoint URL
- Authentication—Key-based and JWT (API gateway required for both)
- Auth Header—Authorization header
- Secret Key—Bearer
- Request Format—The format for requesting data from the application or server
- DataFrame split
- Response Format—The format for providing data from a server response.
- JSON
4. To add schema, click **Enter the inputs and outputs**.
1. To add inputs (variables) that can impact your prediction, click **Add Input**. Then specify a name, an API name, and select the data type. Save your work as you add the inputs.
2. To add your outputs, click **Add Output**. Then specify a name, an API name, a data type, and the JSON Key in a format similar to “$.predictions”. Save your work as you add the outputs.

Important You must position the inputs in the order that matches your Databricks Select Query. To move an input, drag it to the preferred position in the Inputs section.
5. Click **Next**.
6. Review your model settings.
7. To update your model settings, click the section where you want to make changes. Then navigate through the flow to review all settings.
8. If you’re satisfied with your settings, click **Save**.
9. Name your model and click **Save & Connect**. After the model is connected, you can find it on the model list view on the Predictive Models tab.
10. To view your model details, click the model. You can activate, edit, or delete a model on this page.
11. After the model is active, go to the Usage tab to create prediction jobs to consume your predictions.
12. If you created a batch prediction, click **Run** to refresh your prediction scores.

Note With streaming predictions, new inferences are initiated only when there’s a change in the input on your Data Model Object (DMO).
#### See Also
- [_Salesforce Help_: Get Predictions From Your Model](https://help.salesforce.com/s/articleView?id=data.c360_a_get_predictions_from_your_model.htm&release=264.0.0&type=5 "There are many ways in which you can consume predictions, prescriptions, and top factors returned from predictive models.")
# Connect a Model
Connect predictive and generative AI models hosted outside Salesforce and use them with Salesforce data to predict future outcomes. Select your data source, define your predictive criteria, and train your model to reveal predictive inferences and insights using AI and machine learning.
- **[Bring Your Own Model](https://help.salesforce.com/s/articleView?id=data.c360_a_bring_your_own_model.htm&release=264.0.0&type=5)**
Bring Your Own Model (BYOM) lets you connect models built in external platforms with Data 360. BYOM provides direct access to Salesforce data in external ML platforms and uses a zero-copy approach, which eliminates the need to duplicate data. After you connect a model, you can easily consume predictions. Creating, training, and deploying models requires coding expertise for setup in the external platform, but connecting the models to Salesforce is simple.
- **[Salesforce-Enabled Large Language Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_salesforce_enabled_models.htm&release=264.0.0&type=5)**
Use a Salesforce-enabled foundation model to power your generative AI experiences with Prompt Builder. Some models use geo-aware request routing to accommodate data residency requirements. As a result, the provider can host their model in multiple regions while working within the boundaries of the Einstein Trust Layer.
- **[Bring Your Own Large Language Model](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models.htm&release=264.0.0&type=5)**
The Bring Your Own Large Language Model (BYOLLM) capability enables you to add a foundation model hosted on an external platform and connect it with AI Models (formerly Einstein Studio). You can use the foundation model to create a model configuration to power your generative AI. Evaluate the model’s response to your prompts in Model Playground with different settings before you deploy the model to production.
- **[Configure and Test a Model in Model Playground](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_foundation_models_test.htm&release=264.0.0&type=5)**
Create, edit, and evaluate your model configuration in Model Playground without the need for setup or specialized technical expertise. Model Playground uses a trust layer, which ensures data privacy and security.
#### See Also
- [_Salesforce Help_: Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
# Connect a SageMaker Model
To consume your predictions in Salesforce, connect your SageMaker model with Data 360 and define the prediction criteria for your use case.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In AI Models (formerly Einstein Studio), on the Predictive tab, click **Add Predictive Model**.
2. To choose your model type, click **Connect an Amazon SageMaker model**. Then click **Next**.
3. To connect the endpoint and access your model inferences, specify these details. Then click **Next**.
- Name—Endpoint name
- URL—Endpoint URL
- Authentication—Key based or JWT (API gateway required for both)
- Audience—Alphanumeric string or combination for JWT authentication.
- Auth Header—Authorization header
- Secret Key—Alphanumeric string or combination.
- Request Format—Format for requesting data from the application or server.
- JSON dense
- CSV
- Response Format—Format for providing data from a server response.
- JSON
- CSV
4. To add schema, click **Enter the inputs and outputs**.

1. To add inputs (variables) that can impact your prediction, click **Add Input**. Then specify a name, an API name, and select the data type. Save your work as you add the inputs.
2. To add your outputs, click **Add Output**. Then specify a name, an API name, a data type, and the JSON Key in a format similar to “$.predictions”. Save your work as you add the outputs.

Important You must position the inputs in the order that matches your SageMaker Select Query. To move an input, drag it to the preferred position in the Inputs section.
5. Click **Next**.
6. Review your model settings. Then save your work.
7. To update your settings, click the section where you want to make changes. Then navigate through the flow to review all your settings.
8. If you're satisfied, click **Save**.
9. Name your model. Then click **Save & Connect**. After the model is connected, you can find it on the models list view, Predictive Models tab.
10. To view your model details, click the model. You can activate, edit, or delete a model on this page.
11. After the model is activated, go to the Usage tab. Here you can create prediction jobs that enable you to consume predictions from the model.
12. If you created a batch prediction, click **Run** to refresh your prediction scores.

Note With streaming predictions, new inferences are initiated only when there’s a change in the input on your Data Model Object (DMO).
#### See Also
- [_External_: Bring your Own AI Models to Data Cloud](https://developer.salesforce.com/blogs/2023/08/bring-your-own-ai-models-to-salesforce-with-einstein-studio)
- [_Salesforce Help_: Get Predictions From Your Model](https://help.salesforce.com/s/articleView?id=data.c360_a_get_predictions_from_your_model.htm&release=264.0.0&type=5 "There are many ways in which you can consume predictions, prescriptions, and top factors returned from predictive models.")
# Connect a Vertex AI Model
To consume predictions from a Vertex AI model in Salesforce, connect it with Data 360 and define the prediction criteria for your use case.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
Gather information about your model endpoint and the authentication details.
1. In AI Models (formerly Einstein Studio), on the Predictive tab, click **Add Predictive Model**.
2. To choose your model type, click **Connect a Google Cloud Vertex AI model**. Then click **Next**.
3. To connect the endpoint and access your model inferences, specify these details. Then click **Next**.
- Name—Endpoint name
- URL—Endpoint URL
- Authentication—Google Service Account Credential or Key-based
- Service Account Email—Google Service account email
- Private Key ID—Unique ID
- Private Key—Key
- Auth Header—Authorization header
- Secret Key—Alphanumeric string or combination
- Request Format—Format for requesting data from the application or server.
- NumPy with instances
- NumPy with inputs
- JSON dense
- Response Format—Format for providing data from a server response.
- JSON
4. To add schema, click **Enter the inputs and outputs**.

1. To add inputs (variables) that can impact your prediction, click **Add Input**. Then specify a name, an API name, and select the data type. Save your work as you add the inputs.
2. To add your outputs, click **Add Output**. Then specify a name, an API name, a data type, and the JSON Key in a format similar to “$.predictions”. Save your work as you add the outputs.

Important You must position the inputs in the order that matches your Vertex AI Select Query. To move an input, drag it to the preferred position in the Inputs section.
5. Click **Next**.
6. Review your model settings.
7. To update your model settings, click the section where you want to make changes. Then navigate through the flow to review all settings.
8. If you’re satisfied with your settings, click **Save**.
9. Name your model and click **Save & Connect**. After the model is connected, you can find it on the model list view on the Predictive Models tab.
10. To view your model details, click the model. You can activate, edit, or delete a model on this page.
11. After the model is active, go to the Usage tab to create prediction jobs to consume your predictions.
12. If you created a batch prediction, click **Run** to refresh your prediction scores.

Note With streaming predictions, new inferences are initiated only when there’s a change in the input on your Data Model Object (DMO).
#### See Also
- [_Salesforce Help_: Get Predictions From Your Model](https://help.salesforce.com/s/articleView?id=data.c360_a_get_predictions_from_your_model.htm&release=264.0.0&type=5 "There are many ways in which you can consume predictions, prescriptions, and top factors returned from predictive models.")
# Connect and Reorganize Nodes or Branches in a Batch Data Transform
Connect disconnected nodes or branches to append data from any node to any other node in a batch data transform. You can also create a branch at an intermediate node, and append it to another path in the batch data transform.
1. To create a branch and join or append it to another path, hover over a node to see the Branch button (). Then drag the Branch button on top of a node in the other path.
1. In the Connect Nodes box, select to append the data.
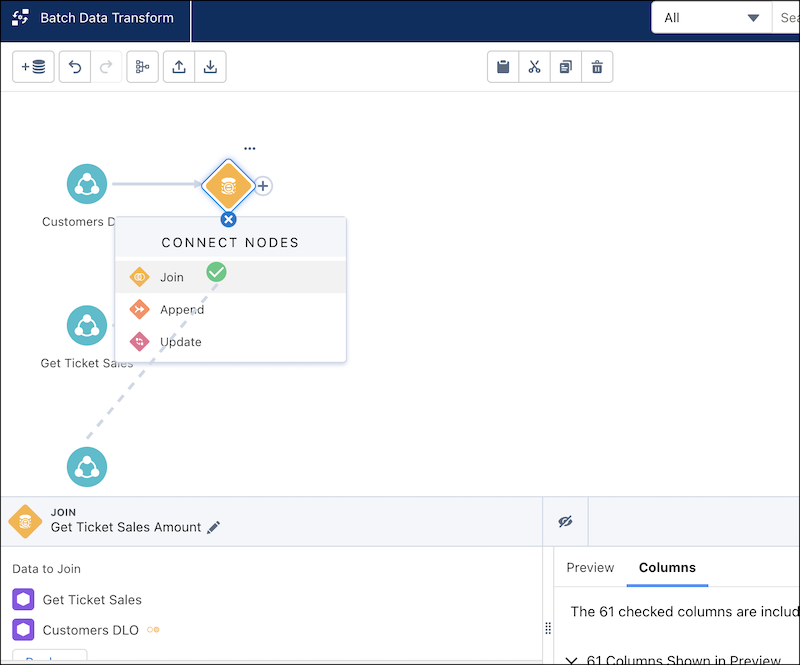
2. To append data to another node, drag the Add Node button () for a node or a Branch button on top of the predecessor.
1. Then select to append the data in the Connect Nodes box. This canvas joins aggregated account data back to the account records.
3. To make the flow of data easier to view, reposition the data transform nodes in the canvas. Select and move individual nodes, or drag your mouse to select as many nodes as you want. Pull the group of nodes around to rearrange, or delete them all at once.
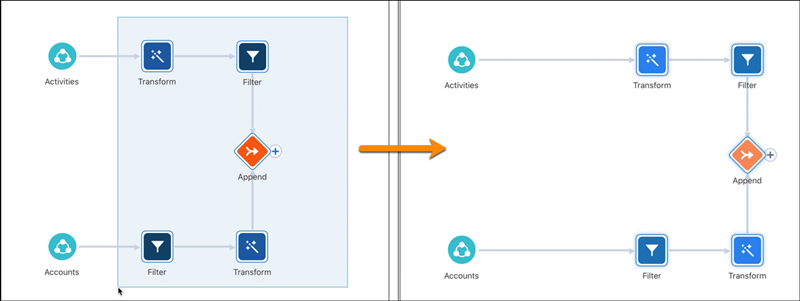
For example, you can move upstream nodes after a downstream node in the canvas, where nodes flow right to left.
# Connect Data
To get started with Data 360, you connect a data source, through either data federation or data ingestion. Data federation sets up direct connectivity with data sources. It uses a zero copy integration that eliminates the need to ingest data into Data 360. During data ingestion, data is brought into Data 360 in its original form and stored in a data lake object (DLO).

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
## Connectors
You can connect data sources, such as Amazon S3, Marketing Cloud Engagement, and Google Storage, to Data 360 using a dedicated connector. Select the data source connector that you want to import data from, and then indicate the objects or dataset that you want to connect. Data 360 retrieves a sample of your data and provides a recommended source schema for your review. Find detailed integration and connector documentation in the [Data Cloud Integration Guide](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-data-cloud-integrations.html).
## Data Streams
A data stream uses a connector to establish a connection with a data source. A data stream acts as a pipeline for connecting data to Data 360. The ingested data is organized into a schema and stored as data lake objects (DLOs).
When creating a data stream, you specify the category and optionally the event time, primary key, and organization unit identifier. You can enhance your data using formula fields to clean and adjust raw data. You can also configure the scheduling details to manage how often data is refreshed.
- **[Data Object Concepts and Schema in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_schema_setup_concepts.htm&release=264.0.0&type=5)**
During ingestion, Data 360 retrieves a sample of your data and recommends a source schema. You can then review and modify the recommended schema.
- **[Data Sources in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_connectors.htm&release=264.0.0&type=5)**
Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.
- **[Data Streams in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_streams.htm&release=264.0.0&type=5)**
Data streams are the connections and associated data ingested into Data 360.
- **[Private Connect for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_data_cloud.htm&release=264.0.0&type=5)**
Private Connect uses Amazon Web Services (AWS) PrivateLink to establish a point-to-point network integration between your AWS virtual private cloud (VPC) and your Data 360 tenant. Private Connect provides a connection from Data 360 to your data source without exposing your network traffic to the public internet.
#### See Also
- [_Salesforce Help_: Data Types and Date Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.")
- [_Salesforce Help_: Supported File Formats and Delimiters](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_file_formats.htm&release=264.0.0&type=5 "Data 360 supports various files and compression formats for your data stream sources.")
# Connect Salesforce CRM Orgs to Data 360
Connect your Salesforce orgs to Data 360 to ingest data from Salesforce objects for processing and unification in Data 360. Depending on the type of connection that you select, you can send back only data actions or harmonized Data 360 data. To access Data 360 data and features in your Salesforce CRM orgs, set up a Salesforce companion connection. Platform components, such as Flow, Apex, CRM, and data enrichment, can also access Data 360 data across companion orgs.
You can connect some orgs using standard CRM connections and others using Data Cloud One companion connections in the same architecture. Select the type of connection that best suits your company’s needs for profile unification and unified data sharing.
## Example
NTO Sales provisioned Data 360 on their org. The NTO Customer Service org and NTO Sporting Goods Retail org are connected to Data 360 via companion connections, enabling bidirectional data sharing of selected data spaces between these orgs and Data 360. They can set up features powered by Data 360 for their users and access to the Data Cloud One app. NTO Materials Research is connected via a standard Salesforce CRM connection. Its data is ingested into Data 360 and unified along with data from NTO's service and retail orgs, but the materials research org can only receive data actions back.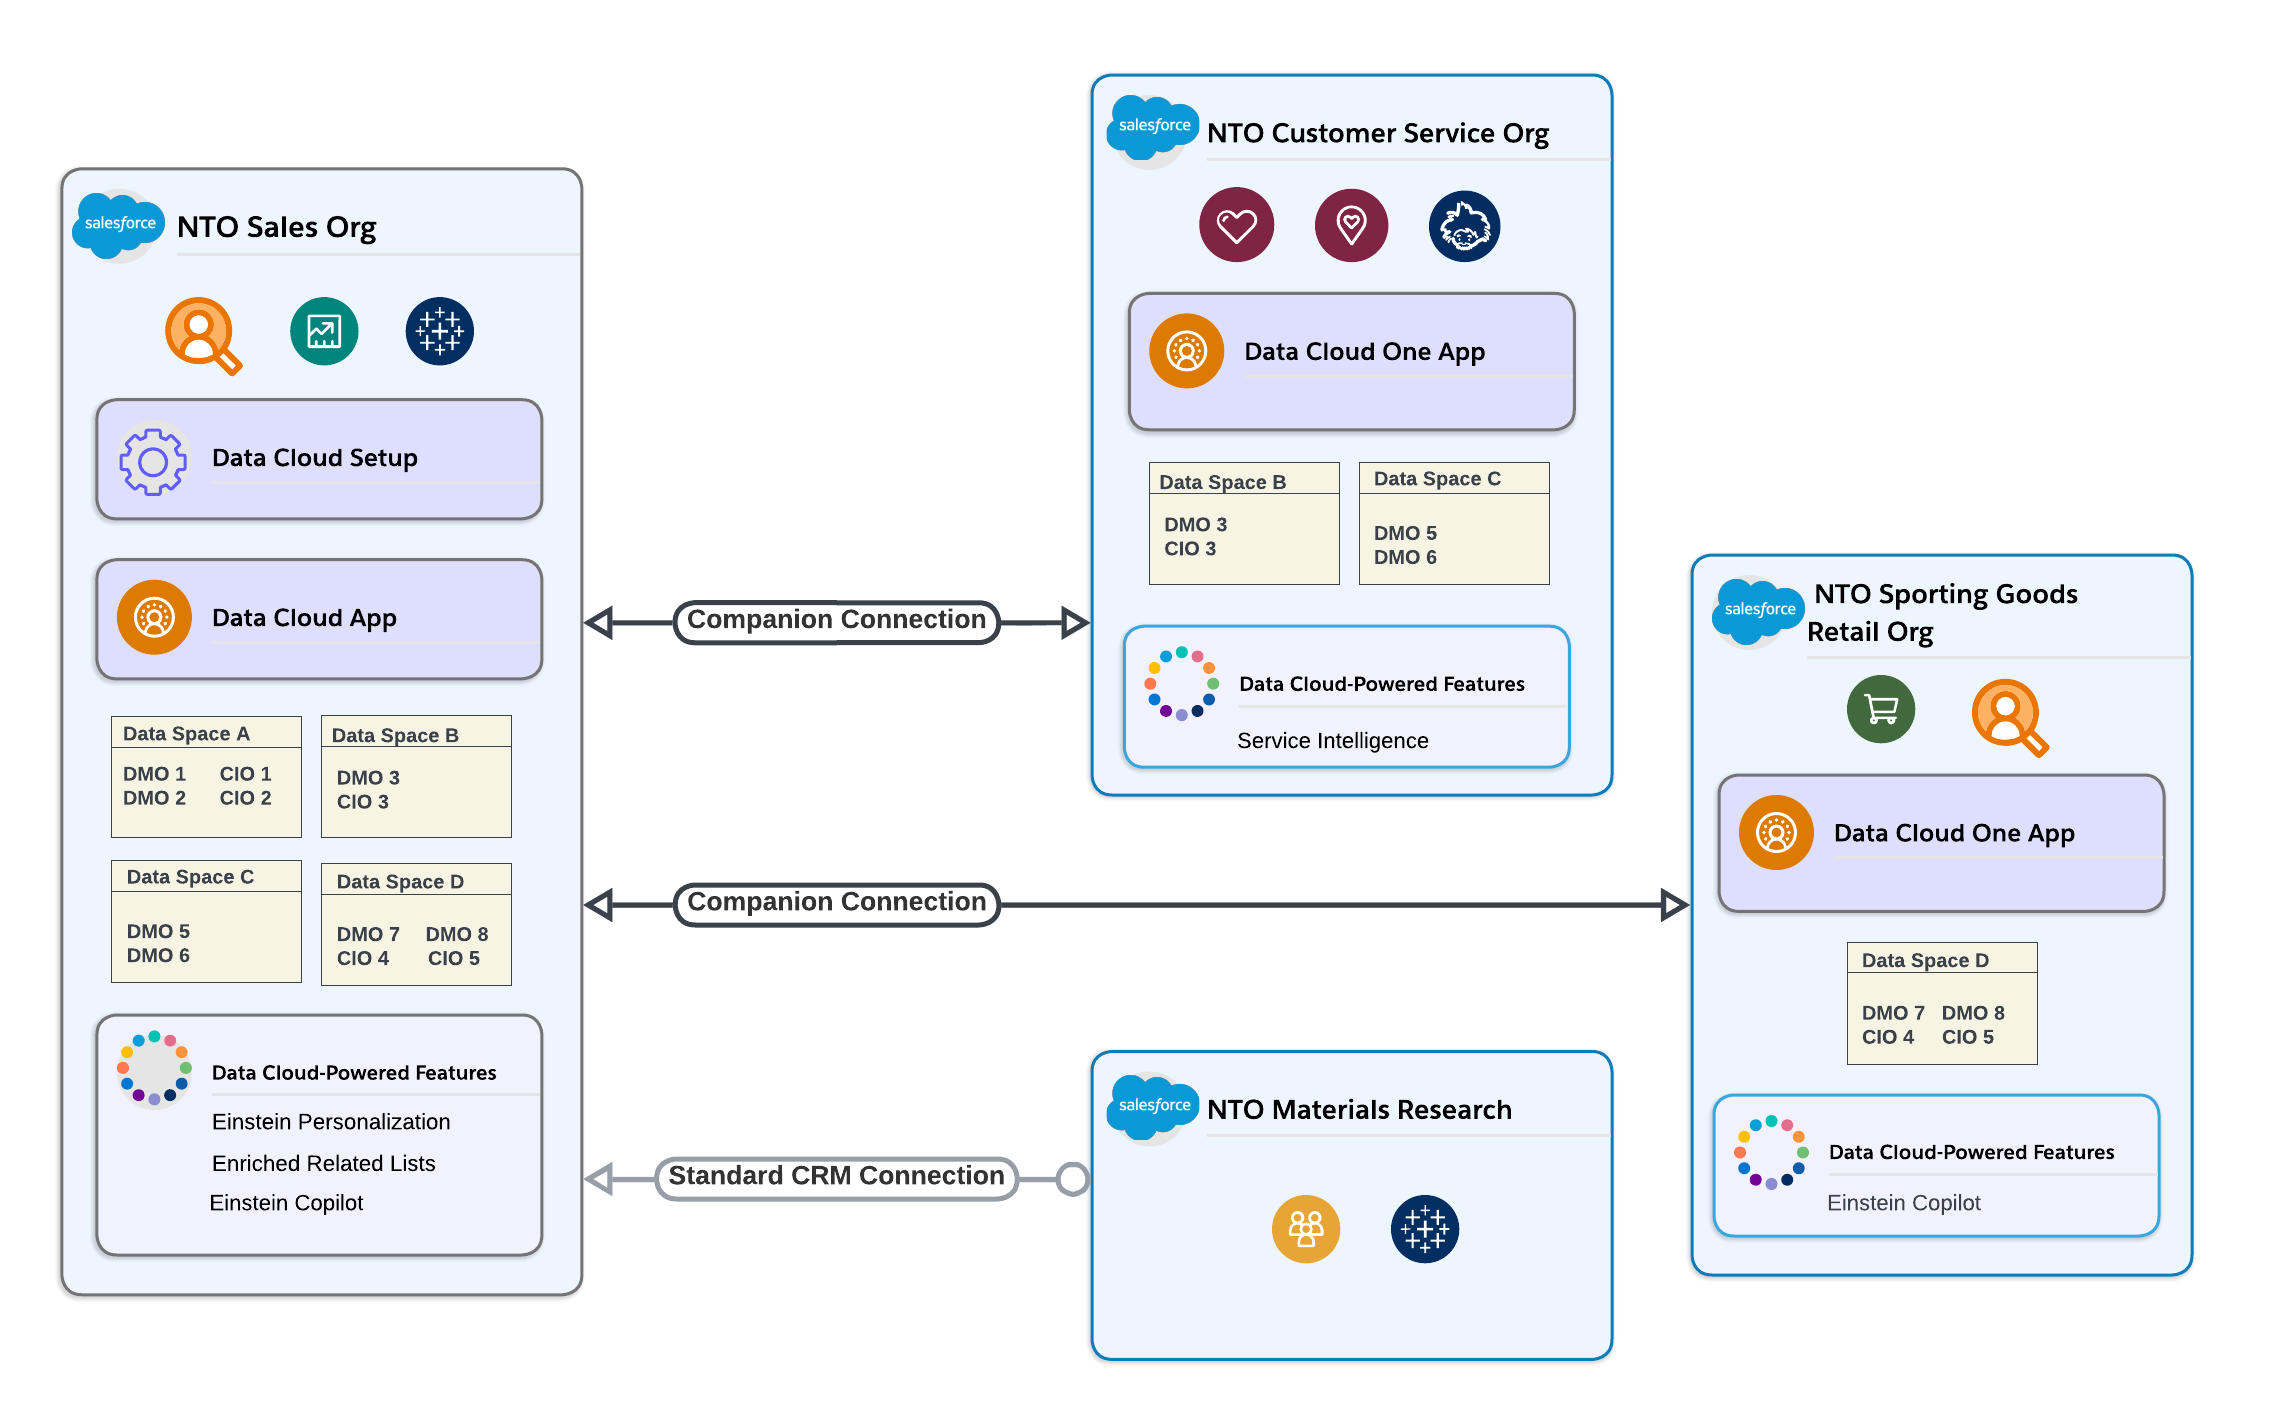
## Home Org
The home org is the Salesforce org that Data 360 is provisioned on. It's automatically connected to Data 360 for you.
## Companion Org
A companion org is any org that is connected to Data 360 via a Data 360 companion connection. Your home org can't be a companion org because it's connected by default. Users in companion orgs have access to a subset of Data 360 functionality in the Data Cloud One app. Data 360 data is available in companion orgs to power platform features like Flow and Enrichments.
## Standard Salesforce CRM Connector
A standard Salesforce CRM connection from Data 360 to a Salesforce org enables Data 360 to ingest data and send back data actions. Standard connections don't sync metadata back to connected orgs and don't give connected orgs access to Data 360 features or data. You can't set up features powered by Data 360 if your org is connected to Data 360 only via a standard connection.
## Data 360 Companion Connection
Use a Data 360 companion connection to create a bidirectional connection between a single Data 360 and one or more Salesforce orgs. A companion connection builds on the capabilities of a standard Salesforce CRM connection by syncing unified metadata back to the companion org. You can set up features powered by Data 360 when your org is connected to Data 360 via a companion connection.
## Data Cloud One App
The Data Cloud One app is available on any companion org. The Data Cloud One app gives users on the companion org access to some Data 360 features. Not all Data 360 features are accessible in Data Cloud One.
- **[Compare Standard Salesforce CRM and Data Cloud One Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_compare_salesforce_connections.htm&release=264.0.0&type=5)**
You can connect a Salesforce org to Data 360 using a standard Salesforce CRM connection or a Data Cloud One companion connection paired with a standard connection. The table lists some of the differences between these types of connections.
#### See Also
- [_Salesforce Help_: Multi-Org Architecture Strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_architecture_strategy.htm&type=5&language=en_US)
# Connect Salesforce Data to Data 360
Data drives Data 360 functionality. In Data 360, you can connect to many data sources. To get started with standard connections, connect Data 360 to a Salesforce CRM org and install standard data bundles. Then, ingest and further map and refine your data.
### Required Editions
This multi-step solution includes multiple roles and permission sets to complete steps in Data 360.  Bookmark this page or keep it open in a separate window to refer to this topic.
## Task 1: Install Data Bundles
After connecting Data 360 to a Salesforce CRM org, the Data Cloud Architect can install standard (sometimes called starter) data bundles to quickly deploy data within Data 360. A data bundle maps Salesforce objects to the Data 360 data model object (DMO) structure. You can also customize a bundle.
1. From Setup, select **Data Cloud Setup**.
2. Under Salesforce Integrations, select **Salesforce CRM**.
3. Under Standard Data Bundles, click the dropdown arrow for either Sales Cloud or Service Cloud and click **Install**.
4. In the data kit install window, select **Install for Admins Only** and click **Install**.
5. When the installation completes, click **Done**.
## Task 2: Create a Salesforce CRM Data Stream
Now that the data kit is installed, you can create a data stream to flow data from a Salesforce CRM source.
[Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&type=5&language=en_US) in Data 360 (Data Cloud Architect permission set—Under 5 minutes).
## Task 3: Map Data
During data ingestion, data is brought in as is—fields and their data types are imported without transformation. In the previous task, you created a Salesforce CRM data stream to bring data into Data 360. Data ingested by all data streams is written to data lake objects (DLOs). A data bundle maps standard fields, but sometimes you must manually create and map required fields for identity resolution, such as the phone number field. This field matches two or more accounts or individuals that have the same name and phone number. The Data Cloud Architect completes these steps.
1. In Data Cloud, on the Data Streams tab, select the **Contact** data stream.
2. In the Data Mapping section, click **Review**.
The data lake objects (DLOs) and the object that you selected are listed on one side of the screen. The searchable data model objects (DMOs) are listed on the other side.
3. Under Data Lake Objects, click the **Business Phone** field.
4. Under Data Model entities, use the search box to find the Formatted E164 Phone Number field in the Contact Point Phone object. To expand the section, click **Unmapped**.
5. Click the **Formatted E164 Phone Number** field to map it to Business Phone on the left.
A solid line connects the two fields.
6. Click **Save**.
Continue these steps based on your business use case and any other required fields.

Note View a data stream’s status from the Data Stream tab. If you don’t see a status, click the dropdown and select **Refresh Now**.
You have now connected Data 360 to your Salesforce CRM org, installed a standard bundle, and ingested and mapped your data. With this ingested data, you can drive personalization and engagement and unlock insights across Salesforce Customer 360 applications and beyond.
## Related Content
- Salesforce Help: [Data Modeling Requirements for Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_requirements.htm&type=5&language=en_US)
- Salesforce Help: [Create Identity Resolution Rulesets](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_ruleset_create.htm&type=5&language=en_US)
- Salesforce Help: [Enhance Data with Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_insights.htm&type=5&language=en_US)
- Salesforce Help: [Create and Activate Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&type=5&language=en_US)
- Trailhead: [Create a Data Stream in Data 360](https://trailhead.salesforce.com/content/learn/projects/create-a-data-stream-in-data-cloud)
# Connect Tableau in Data 360
Set up a connection to Data 360 from Tableau. Different steps are required depending on which Tableau product and version you use.
Data 360 was previously called Data Cloud and Customer Data Platform (CDP). The Customer Data Platform connector was deprecated in October 2023 and is no longer available. Existing assets that use the CDP connector must be recreated using the Salesforce Data Cloud connector.
You can connect to these Tableau products from Data 360 using the Salesforce Data Cloud connector.
- Tableau Server helps to organize and share Tableau dashboards and workbooks. Using the Salesforce Data Cloud connector requires Tableau Server version 2023.3. Starting with version 2024.2, the Customer Data Platform connector is no longer available in the user interface. See [Connect Tableau Server to the Data 360](https://help.tableau.com/current/server-linux/en-us/config_oauth_sfdc_cdp.htm).
- Tableau Desktop is a visualization tool that turns your customer data into interactive visual representations like dashboards and workbooks. Using the Salesforce Data Cloud connector requires Tableau Desktop version 2023.2 or later. Starting with version 2024.1, the Customer Data Platform connector is hidden in the user interface, and is removed entirely from Tableau Desktop 2024.3 and later. See [Connect Tableau Desktop to the Data 360](https://help.tableau.com/current/pro/desktop/en-us/examples_data_cloud.htm).
- Tableau Prep cleans and shapes customer data to optimize analysis. Using the Salesforce Data Cloud connector requires Prep Web Authoring, Conductor version 2023.2, or Prep Builder 2023.2. See [Connect to the Data 360](https://help.tableau.com/current/prep/en-us/prep_connect.htm#considerations-when-using-builtin-connectors).
- Tableau Cloud is used for authoring, sharing, distributing, and collaborating on content. The Salesforce Data Cloud connector was released for Tableau Cloud in October 2023. Starting in June 2024, the Customer Data Platform connector is no longer available in the user interface. See [Connect Tableau Cloud to the Data 360](https://help.tableau.com/current/online/en-us/config_oauth_sfdc_cdp_online.htm).
# Connect Unstructured Data Using MuleSoft Direct (Beta)
Ingest unstructured data from external sources that include Confluence, Google Drive, SharePoint, and Sitemap using MuleSoft Direct for Data 360.

Note The MuleSoft Direct Connector is a pilot or beta service that is subject to the Beta Services Terms at [Agreements - Salesforce.com](https://www.salesforce.com/company/legal/agreements/) or a written Unified Pilot Agreement if executed by Customer, and applicable terms in the [Product Terms Directory](https://ptd.salesforce.com/?_ga=2.247987783.1372150065.1709219475-629000709.1639001992). Use of this pilot or beta service is at the Customer's sole discretion.
Use Feature Manager to enable the MuleSoft Direct connector.
For more set up instructions and reference, see the [MuleSoft Direct connector documentation](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-mulesoft-direct.html) in Salesforce Developers.
# Consent Management
Learn more about Consent Management in Data 360.
Many data protection and privacy regulations require you and your company to honor a consumer’s requests for how you contact them and how you use their personal data. Data 360 provides multiple methods for you to ingest and store your consumer’s consent preferences.
- **[Ingesting Consent Preferences](https://help.salesforce.com/s/articleView?id=data.c360_a_ingesting_consent_preferences.htm&release=264.0.0&type=5)**
Ingest consent preferences from wherever you’re storing them using connectors. Common storage locations include data extensions (Marketing Cloud Engagement Connector), Sales or Service Cloud standard or custom objects (Salesforce CRM Connector), or external sources (Cloud Storage Connector).
- **[Configuring Data Model Preferences](https://help.salesforce.com/s/articleView?id=data.c360_a_configuring_data_model_preferences.htm&release=264.0.0&type=5)**
Learn more about how to configure data model preferences in Data 360.
- **[Using Consent Preferences in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_using_consent_preferences_in_segmentation.htm&release=264.0.0&type=5)**
Learn more about how to use consent preferences in segmentation in Data 360.
- **[Checking Consent Preferences at Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_checking_consent_preferences_activation.htm&release=264.0.0&type=5)**
Learn more about how to verify your consent preferences when using the Activation functionality of Data 360.
# Considerations for Data Cloud One in a Sandbox Org
Avoid common mistakes by reviewing these considerations before setting up a Data Cloud One cluster. Create sandbox orgs from your production orgs before establishing Data Cloud One connections, or clean up Data 360 metadata before recreating your Data Cloud One cluster. You can’t use Data Cloud One to connect a sandbox org to a production org.

Warning
We recommend first creating sandboxes orgs from your production orgs, then creating Data Cloud One connections. Your connections aren't copied to sandbox orgs. You can't reestablish a Data Cloud One connection until you've cleaned up copied Data 360 metadata from the sandbox companion org.

Note
To create a Data Cloud One sandbox, activate the Ingestion API connector and make sure the remote\_connection\_full-sync\_feed and remote\_connection\_incremental-sync\_feed data streams are active.
## What Copies to a Sandbox and What Doesn't
These items are copied to sandbox orgs.
- Data 360 and Data Cloud One Companion Org licenses
- Data 360 metadata
These items aren't copied to sandbox orgs. Manually add or create them.
- Data 360 data
- Data Cloud One companion connections
Because Data 360 data isn’t copied into your sandbox orgs, we recommend populating your sandbox orgs with sample data. Using a small set of representative data lets you save on data processing costs while testing your configurations.
## Best Practices for Setup and Maintenance
- **Create or refresh Home and Companion sandboxes as close together in time as possible.**
The closer together they're created or refreshed, the smaller the chance of metadata drift between them.
- **Establish Data Cloud One companion connections immediately after creation of the sandboxes.**
Connecting right after creation further reduces the likelihood of metadata drift.
- **Don't delete Data 360 metadata on the Home sandbox org before connecting sandboxes of its companion orgs.**
This is especially important for metadata that the companion org depends on. If you delete the metadata on the Home sandbox first, there is a higher chance of metadata drift, and you'll need to delete the drifted entities on the companion sandbox before the connection can complete.
- **Manually activate Data 360 on your Home org sandbox.**
Data 360 doesn’t turn itself on in sandbox orgs. To turn it on, go to Data Cloud Setup Home.
- **Disconnect companion sandbox orgs from home before refreshing them.**
Refreshing a sandbox completely destroys the existing org and generates a new org ID, which breaks your Data Cloud One connection but doesn’t remove it. Log in to your Home org and go to Data 360 Setup to disconnect the companion org, then reestablish the connection.
- **Match production org licenses.**
If you license Data Cloud One companion orgs after setting up sandboxes, add the Data Cloud One Companion Org license to your sandbox by [matching production licenses](https://help.salesforce.com/s/articleView?id=xcloud.overview_licenses_and_sandbox.htm&type=5&language=en_US).
## Cost Considerations in Data 360 One Sandbox Orgs
When you use Data 360 data services or other services that consume credits, credits are decremented from your production Home org’s consumption cards. Usage is discounted in sandbox orgs.
#### See Also
- [_Salesforce Help_: Create a Sandbox in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_create.htm&release=264.0.0&type=5 "Develop, test, and train on Data 360 without affecting your production org. Data 360 supports all sandbox types—Developer, Developer Pro, Partial Copy, and Full Copy—but provisions only metadata. Even when you create Partial Copy or Full Copy sandboxes, your production data stays protected. No data is replicated to Data 360 sandboxes.")
# Considerations for Data Kits in Data 360
Review these considerations for data kit creation, publishing, and deployment to ensure successful implementation and avoid common issues.
- Create your standard data kit from Developer Edition orgs only.
- **Data Connector Framework (DCF) Data Streams:** The Data Connector Framework (DCF) controls how you set up and manage connectors in Data 360. When you deploy DCF-based data streams in a standard data kit, you can either use a packaged connector or select a preconfigured connector in the target org during deployment.
- **Non-DCF Data Streams**: When you deploy the non-DCF data stream, select a preconfigured connector in the target org. The connector details aren't included during the deployment process.
- **DevOps Data Kit:** When you deploy data streams using a DevOps data kit, Data 360 automatically adds the connector information to the target org.
- **Data Model Objects (DMOs):** When you deploy standard and custom Data Model Objects (DMOs) from a sandbox, the associated relationships and tags are automatically added during the deployment process. However, tags that are explicitly assigned to other DMO types, such as derived DMOs or curated DMOs, aren't included in the deployment.
- When you add a data model object to a standard data kit, custom data models are added as is. If you select a standard data model, only the custom mappings and custom fields added on top of the data model are packaged.
- **Zero Copy Data Stream**: For Zero Copy data streams using Google BigQuery, Snowflake, Databricks, or Redshift connections, make sure that the database, schema, and table names are consistent between your publisher and target orgs.
- **Data Lake Objects (DLOs)**: When you add DLOs to a data kit using the **Add** option under the Data Kits tab, only standalone DLOs are displayed on the page.
- **DLO-to-DMO Mapping:** To ensure the Output DLO-to-DMO mappings are carried over during deployment, the Output DLOs themselves must be explicitly added to the Data Kit configuration.
- **Unstructured Data Lake Objects (UDLOs)**: When you add a UDLO to a data kit, the mapped unstructured data model object (UDMO) is automatically included in the data kit.
- **Calculated Insights**: When you add an insight to a data kit, manually add the insight's dependencies. Dependencies can include child-calculated insights, data model objects, data lake object, and data graphs. Without the dependencies, the deployment of the insight can fail.
- **Activations**: When building a data kit, add and save your activations in small batches. Attempting to save a large number of activations simultaneously can cause the operation to time out and fail.
- **Batch Data Transforms**: When you deploy a batch data transform in a data kit, the transform's schedule is included in the deployment. The schedule is active in the destination org after installation.
# Considerations for Data Stream Field Disablement
There are few restrictions to consider when planning to disable a data stream field.
### Required Editions
Available in: Lightning Edition
## Common Considerations
You can't disable these types of data stream fields.
- Fields used as part of the Primary Key, Event Date Time, Organization Unit Identifier or Record Modified fields.
- System-generated fields such as Data Source, Data Source Object, cdp\_sys\_SourceVersion, and Internal Organization.
- Fields used as source fields in any other formula field.
- Fields of a data stream that is deployed from a Package.
- Fields of data stream ingesting data from Marketing Cloud Engagement Bundle and Mobile SDK streams.
## Considerations for Disabling a Field in CRM
- To delete a field from your connected CRM, first disable that field from Data 360 to avoid ingestion errors in data streams.
- After you disable a field, you can delete the field through the connected Salesforce CRM Object Manager admin tool. Then remove the field from the Data 360 permission set in that connected Salesforce CRM.
# Considerations for Deleting Data
Keep the following in mind when you delete data in Data 360.
- You can delete a streaming data transform at any time.
- Deleting a streaming data transform doesn’t affect its source or target objects. Data that was written to the target object remains in the target object.
- If multiple streaming data transforms read from the same source and write to the same target, filtering conditions can be overridden. If a transform contains a `WHERE` clause and others don’t, the unfiltered source data enters the target. If the data source updates and there are changes to corresponding rows in the target that no longer meet the transform’s `WHERE` criteria, then the results from the earlier transforms are removed from the target.
- You can delete ingested data in a source object by submitting the records to delete through the data stream. For more information, see [Delete Ingested Records in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_stream_records.htm&release=264.0.0&type=5 "You can delete data ingested into Data 360. Your data stream must have an upsert refresh mode. The deletion process depends on the type of connector that you’re using.").
- If an existing record in a source object is updated so that it no longer matches the `WHERE` filter, that record is deleted from the target object.
- When multiple data transforms write to the same target object, a record isn’t deleted until all data in fields other than the primary key field is deleted. When only the primary key remains, the record is deleted.
- Duplicate primary keys in the source object cause unexpected behavior.
# Considerations for Formula Fields in Data 360
Refer to these considerations when creating formula fields in Data 360.
## Raw Data Fields
If you want to reference a raw data field in a formula, use the syntax, sourceField\[‘Header Label’\] where Header Label corresponds to the column name in your raw data. The syntax sourceField\[‘Header Label’\] is case-sensitive.
- sourceField is the prefix, sourcefield is incorrect..
- The casing of the Header Label corresponds to the raw data. For example, if the file contains ‘address’, the reference must be ‘address’. If the file contains ‘Address’, the reference must be ‘Address’.
- References to the Header Label must be in single quotes. If the file has a column called ‘address’, the syntax must be sourceField\[‘address’\], not sourceField\[‘Address’\].
## Free Form Text
To reference a string in your formula, you can use single or double quotes. For example, if you want to check if a value within a raw data field is equal to some string, both expressions are valid:
- sourceField\[‘Eye Color’\] == “blue”
- sourceField\[‘Eye Color’\] == ‘blue’
For a given term, don’t mix single and double quote references. For example, the following expressions aren’t valid:
- sourceField\[‘Eye Color’\] == ‘blue”
- sourceField\[‘Eye Color’\] == “blue’
## Delimiters
If you use a delimiter in your formula, and it's a valid regex character, it must be escaped with a '\\\\'.
```sql
REPLACE('dd.mm.yy','\\.','_')
Output
dd_mm_yy
```
## Numeric Data Types
The output of formula fields that use numeric data types varies depending on the input. For example, these two formulas yield different results where the sourceField\['ColumnX'\] is 1.54.
| Formula | Result |
| --- | --- |
| `0 - sourceField['ColumnX']` | \-1 |
| `0.0 - sourceField['ColumnX']` | \-1.54 |
# Considerations for Sandbox in Data 360
Refer to these considerations when creating a sandbox and deploying changes from a sandbox in Data 360.
## Licensing and Setup Requirements
To use Data 360 in a sandbox, provision Data Cloud licenses in production and create the Data 360 tenant. To create the tenant, from Setup, find and select **Data Cloud Setup**, and click **Setup**. Complete the tenant setup before Data 360 is available in the sandbox. If the production isn't operating Data 360 under a Salesforce Data Cloud license, you can't turn on Data 360 in sandbox.
## Provisioning Data 360 in a Sandbox
To set up Data 360 in a sandbox that was created before Data 360 was provisioned in your production org, you can use the license match feature. This feature allows you to inherit Data Cloud licenses from the production org without refreshing the sandbox. However, there are a few important considerations to keep in mind:
- The production org must have Data 360 provisioned for the license match to work.
- The license match process copies only Data Cloud licenses. The license match doesn't copy organization preferences, values, metadata, or permissions. You must set up custom configurations, integrations, and other metadata manually in the sandbox.
- Complete Data 360 provisioning in your sandbox first. Confirm that provisioning is active before you activate Agentforce or Einstein features.
To enable Data 360 in a sandbox org, the source production org that the sandbox is created from must be operating Data Cloud under a Data Cloud license. If the source production org is operating Data Cloud under a Salesforce Data Cloud license, you can't turn on Data 360 in the sandbox org.
## Data 360 Sandbox Storage and Limits
- Data 360 sandboxes follow production limits and guidelines. They don't have the storage restrictions of Salesforce sandboxes, such as the 200-MB limit for Developer sandboxes. For limits related to Data 360, see [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&type=5&language=en_US).
## Considerations When Creating a Sandbox
- If you have a Data 360 component in your production org that was added from a developer-controlled managed package, the component is copied over to the sandbox but you can't edit it or change the status. In this case, re-create the component in the sandbox.
- When some Data 360 components that depend on data ingestion are copied to the sandbox, record count and date fields reflect the values from production. You see these production values until data is ingested in the sandbox. You could see this behavior in data streams, data lake objects, segments, and identity resolution.
- You can't use a sandbox template when you create a Data 360 sandbox.
- After a data lake object (DLO) is replicated in a sandbox, you can’t delete it there. You can delete the DLO only from production.
- Unified Messaging is supported in a sandbox that's created after May 9, 2025.
- The Data 360 connectors for Einstein Conversation Insights features aren't supported in sandbox orgs. Einstein Conversation Insights features that rely on Data 360, such as Sales Signals, aren't testable in sandbox.
- Digital Wallet billing streams are replicated to the sandbox org. The streams are read only in the production org and remain read only in the sandbox org.
## Considerations When Deploying Changes from a Sandbox
When you're ready to move changes from a sandbox org to another sandbox or a production org, here are the key things to keep in mind.
- Use change sets, Salesforce command line interface, or metadata API to deploy changes from one sandbox to another sandbox.
- If you create a data space in a sandbox that doesn’t exist in the production org, and you want to deploy components from that data space, you must first manually create the data space in production. The data space isn’t created when you deploy the data kit.
- You can deploy a calculated insight from the default data space and a custom data space.
- When you deploy standard and custom data model objects (DMOs) from a sandbox, the associated relationships and tags are automatically added during the deployment process. However, tags that are explicitly assigned to other DMO types, such as derived DMOs or curated DMOs, aren't included in the deployment.
- When you deploy Lightning Pages that include related lists for DMOs, the deployment fails if the list references relationship lookup fields. Validation fails because the API names for relationship lookups are unique to each environment and don’t match between the source and target orgs.
- If you create or modify a Marketing Cloud Engagement (MCE) connection, a business unit for ingestion, or a business unit mapping to a data space, you can’t include it in a data kit and deploy it back to the source org. In this case, create or modify these features in the source org.
- In a Marketing Cloud Engagement Enterprise Attributes bundle data stream in a sandbox, you can perform these actions, but the resulting changes aren’t deployed back to production.
- Disable a field
- Modify a formula field
- Add a formula field
- You can deploy only a data action target with a home org connection back to production. Cross-org connections aren’t supported.
- If you build an Einstein Studio model in a sandbox, you can see the training metrics there. After you deploy the model, it’s usable in production, but the metrics aren’t visible.
- When you add a supported data stream, Data 360 includes the connector metadata. When you deploy the data stream for the first time, Data 360 deploys the connector in an inactive state. To begin data ingestion, configure credentials and activate the connection in the target org. For subsequent deployments, if an active connector exists in the target org, the deployment ignores changes to attributes. This change applies to all data stream connectors.
- If you remove the data stream, you must remove the connector metadata from the DevOps data kit.
- When you delete an object type from the source org, the deployed data kit retains the corresponding object in the target org. To exclude the object from future deployments, create a data kit that contains only the required components. Don’t update the deployed data kit.
## Considerations When Deploying Changes Across Orgs
- To move metadata across production orgs, deploy the data from production org one to sandbox org one. Then, deploy those changes from sandbox one to the sandbox linked to production org two before the final push into production org two.
## Considerations When Using Segments in a Sandbox
- If you create an audience segment for Provisional Audience Limiting or Static Attribute in a sandbox, you can’t deploy the segment to production. You must manually re-create the segment in production.
- You can deploy a segment membership DMO that has no relationships from a sandbox to production. However, deploying a segment membership DMO with relationships isn't supported.
- When you deploy a new segment, its publish schedule defaults to Don’t Publish. If the segment already exists in production, its schedule isn’t affected.
## Considerations When Using Data Graphs in a Sandbox
- Data graphs are replicated from production to sandbox but have a status of Processing. After the associated transform runs successfully, the data graph status changes to Active. To manually activate a data graph, refresh it on the data graph page.
- If you deploy a data transform or a data graph from a sandbox, and it doesn’t automatically run after it’s deployed in production, update its status from the list view.
## Considerations When Using Activations and Activation Targets in a Sandbox
- You can create an activation in a sandbox, and you can deploy Amazon S3, Marketing Cloud Engagement, SFTP, GCS, or Microsoft Azure activations from sandbox to production.
- Before deploying an activation target from a sandbox to production, you must enable the corresponding connection for the activation target in the production environment.
- Activations and activation targets are copied from production to a sandbox, but you can’t activate them in a sandbox until the underlying connector is enabled.

Note Activations copied to a sandbox retain their production segment and activation IDs. As a result, for a Marketing Cloud Engagement (MCE) activation target, they point to the same shared data extension key. To prevent clearing or overwriting production data, keep sandbox activation targets inactive or ensure they use a completely isolated Enterprise ID (EID) or destination during the authentication process.
- Data action targets, streaming data transforms, and batch data transforms are replicated from production to sandbox, but you must explicitly activate them.
- For Ecosystem Activation Targets, to enable the publish schedule, disable the platform and re-enable it.
- Loyalty activation targets copied from production to sandbox aren’t functional, and you can’t manually update the target status on the Data Cloud Activation Targets page.
- If you edit the title of a Marketing Cloud Engagement activation target, a new activation target is created instead of editing the existing target.
- When building a data kit, add and save your activations in small batches. Attempting to save a large number of activations simultaneously can cause the operation to time out and fail.
## Considerations When Using Data Streams and Connections in a Sandbox
- If you create a connection in the sandbox and deploy that connection to production, you must reauthenticate it in the production org. After you configure the connection, the data flows into the sandbox.
- If you have a data stream that’s based on an S3 connection and that connection contains the org ID in its path, the org ID is changed from the production org ID to the sandbox org ID when you create a sandbox. If the connection path name changes, the data isn’t refreshed for those sandbox data streams. For example, if you have an S3 stream path of parentpath/productionOrgID/fileName.csv, the sandbox S3 stream path is parentpath/sandboxOrgID/fileName.csv. You must either edit the sandbox stream path and change the org ID to the production org ID or add the files to the new path.
- If you configure a connection in the sandbox and a data stream based on that connection continues to have a status of NEEDS\_ACTIVATION, contact Salesforce Customer Support.
- After you create a sandbox, you must re-create connections based on the Amazon Kinesis connector.
## Considerations When Using Zero Copy Data Stream in a Sandbox
- For Zero Copy data streams using Google BigQuery, Snowflake, Databricks, Redshift, or newly launched connectors supporting Zero Copy connections, you can use different database, schema, and table names between your production and sandbox environments.
- When you activate a Google BigQuery connection in a sandbox org, you can modify the Google BQ project ID, service account email, and private key to match the sandbox org. If your sandbox uses different database, schema, or table names, you can update these values after activation.
- During Snowflake connection activation in a sandbox org, you can update the account URL, username, and private key for the sandbox. If the database, schema, and table names differ in your sandbox environment, you can update these values after activation.
- For Databricks connections in a sandbox, you can change the authentication details, connection URL, and HTTP path. If your sandbox uses different database, schema, or table names, you can update these values after activation.
- In a sandbox setup for a Redshift connection, you can change the authentication details, connection URL, and database. If your sandbox environment uses different database, schema, or table names, you can update these values after activation.
## Considerations When Using Unstructured Data and Search Indexes in a Sandbox
- When the data source used for a search index is a CRM object (DMO):
- Data lake objects (DLOs), data model objects (DMOs), and the search index are copied from the production org to the sandbox.
- In the sandbox org, you need to activate the CRM home org connection and activate the CRM data streams. The search index runs automatically after data is ingested into the DLO.
- When the search index is created through the Agentforce Data Library (ADL):
- UDLOs, UDMOs, DLOs, DMOs, CRM data streams, and the search index are automatically created in the production org.
- UDLOs, UDMOs, DLOs, DMOs, CRM data streams, and the search index are copied from the production org to the sandbox.
- In the sandbox org, you need to activate the CRM home org connection and activate CRM data streams. You don't need to do anything for the UDLOs and UDMOs. The search index runs automatically after Knowledge data is ingested into the DLO. Any files that are uploaded to the ADL in the sandbox org are indexed automatically.
- When the data source for a search index is an external blob store (for example, S3, GCS, or Azure):
- UDLOs, UDMOs, and the search index are copied from the production org to the sandbox.
- In the sandbox org, you must create an external client app and setup file notifications on your blob store and point these file notifications to the sandbox org.
- In the sandbox org, you need to recreate the UDLO and remap it to the UDMO. The search index runs automatically after data is ingested into the UDLO.
# Considerations for Selecting Related Attributes in Data 360 Activations
Related attributes are data fields that belong to data model objects (DMO) connected to your primary or activation DMO. These attributes help you access information from other objects that are linked through a defined relationship path. There’s a direct relationship with the DMO, related attributes, and the filters you can apply.

Note For engagement data, activation supports a 90-day lookback window. If related attributes are selected for an activation with a rapid segment publish, the lookback window is seven days. Activation considers engagement data within this window, and any records outside of this window aren't considered when selecting your output values. Profiles might be included in the activation if an engagement date falls within a 24-month window for a segment. Specific engagement records might not be included in the activation if they fall outside the 90-day lookback window.
When selecting related attributes, consider these guidelines:
- You can activate up to 25 values per related attribute.
- You can select up to 300 related attributes per activation.
- You can use up to 8 DMOs per activation.
- You can use up to 10,000 activations with related attributes. After reaching that limit, you can choose to delete related attributes from existing activations, delete unused activations, or create activations with only direct attributes.
- The segment size is checked at the time of activation. If the segment has more than 150 million records and contains related attributes when you publish, the segment doesn’t activate.
- A single customer (or Individual) can have multiple Sales Orders, each tied to different order details. You can select attributes from different DMOs across multiple paths from your activation DMO. For example:
- Individual → Engagement (email, website)
- Individual → Sales Order → Order Details
- When applying filters on DMOs, you can use attributes from the filtered DMO itself or any of its related child DMOs. Attributes from unselected or inactive DMOs can also be used for filtering. Filters are optional. If no filter is applied, the activation considers all data from the selected DMO.
- The segmentation and activation attribute libraries achieve different purposes so they behave differently. In segmentation, the entire DMO hierarchy is displayed. In activation, the DMOs that are one hop away from the object are displayed. To get to other DMOs, click through the hierarchy.
- Activation doesn’t automatically acquire segmentation filters. To activate specific values for your attribute, apply filters to your activation. Use segmentation filters to find users who qualify for the segment. Use activation filters to find attributes for message personalization.
## Related Attributes Filtering
Related Attributes filtering allows users to include only relevant data in the activation payload, by applying specific filter conditions. This makes sure that the activated data aligns with the campaign’s intent.
For example, a marketer wants to send an email to customers about their orders currently in the Shipping In Progress state. They’ll select attributes like Order ID and Order Details for activation, and apply a filter where Order Status = "Shipping In Progress". This ensures that only orders matching this status are included in the output.
- Filters applied upstream are inherited downstream, ensuring consistent filtering throughout the activation.
- A locked or grayed-out filter view in child DMOs indicates inherited filters.
- DMOs at the same level on different paths don't inherit each other’s filters.
Here's an example:
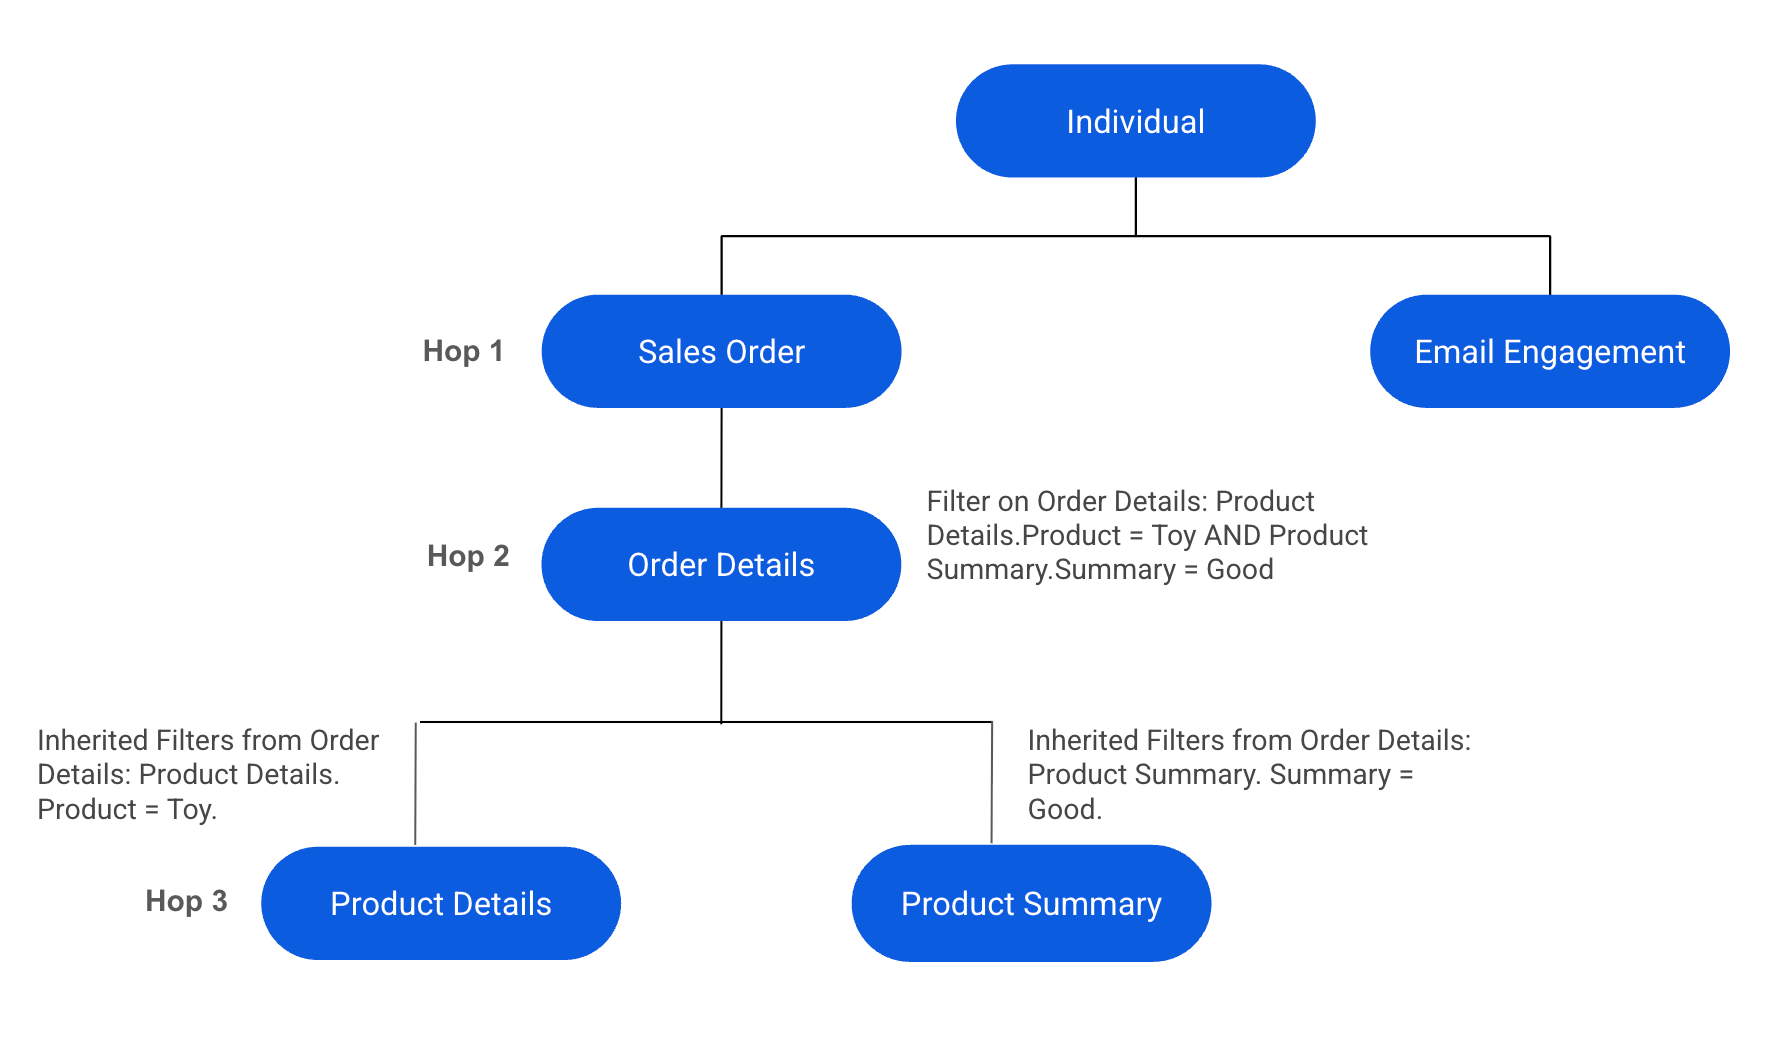
DMO Attribute and Filter Mapping
| DMO Name | Attributes Selected | Notes |
| --- | --- | --- |
| Individual DMO | First Name, Last Name | |
| Sales Order DMO | Sales Order ID, Order | |
| Order Details DMO | Total Purchase Amount | Filters applied on Order details: Product Details.Product = Toy AND Product Summary.Summary = Good |
| Product Detail DMO | Product Name | Filters inherited from Order Details: Product Details. Product = Toy. |
| Product Summary DMO | Summary | Filters inherited from Order Details: Product Summary. Summary = Good. |
To retrieve all Sales Order IDs where the order includes the Product Name Toy and has a Product Summary marked as Good, you need to apply the filters on the Sales Order DMO.
As a result, only those sales order IDs that match the filter criteria are included. The filtering logic flows downstream from the DMOs where the filters are applied. This means that if you are activating attributes from Order Details, Product Detail, and Product Summary, they will all inherit the upstream filters applied on Sales Order. These filters affect the Order Details and Sales Order DMOs.
Filters aren't applied upstream, so any DMO upstream of Sales Order, such as the Individual DMO, remains unaffected. Consequently, the inherited filter also makes sure that all attributes downstream of Sales Order are implicitly filtered to show only details related to Toy and summaries marked as Good.
## Understanding DMO Counts
- When related attributes are selected from multiple paths, each data model object involved counts toward the DMO limit.
- DMOs used only for filtering also count toward the limit.
- However, if a DMO is already included for attribute selection, using additional attributes from the DMO for filters doesn't add to the count. For example, if you select an attribute from Product Details for activation and also use an attribute from the same DMO for filtering, it still counts as one DMO in the limit calculation.
Here are some examples of the DMO count:
- Selecting an attribute from Product Details results in a DMO count of three: Sales Order, Order Details, and Product Details. If an attribute from Product Summary is then added, it only increments the count by one, as the initial DMOs aren't recounted.
- If you activate attributes from Order Details without applying any filters, the path traverses through Sales Order, resulting in a DMO count of two.
- If you activate attributes only from Product Details and Product Summary without applying any filters, the DMO count is four.
Activation supports these segmentation operators:
Operator Type
Operator Value
Date
Numeric
Text
# Considerations for Using Joins
Unlike a lookup, a join creates a separate record for each match in the output data when multiple rows match. Before using a join, ensure that you understand the implications of duplicate rows.
## Don’t double count measures when aggregating records from a join
In this example, both input data source objects have duplicate key values.
A left join duplicates the `Opp_ID` 1 record in the left object because it has multiple matches in the right object.
Notice that the duplicated records repeat the opportunity amount for Alice. If you added all opportunity amounts to get the total, you’d double count the amount for Alice. To prevent duplicate records, use a lookup instead of a join.
## Refrain from using joins when the join keys have a many-to-many relationship.
When the join keys have a many-to-many relationship, the output data can become significantly larger than the input data sources. For instance, if four records on the left and five records on the right have the same key value, the join adds 20 (4\*5) records to the output. In a more extreme case, if 10,000 records on the left and 5,000 on the right share the same key value, the join creates 50 million records in the output.
To illustrate why this occurs, consider these input data sources that have duplicate key values.
A left join duplicates each record in the left object five times because it has five matches in the right object.
To prevent duplicate records, use a lookup instead of a join. If you must use a join, try adding more key fields to make the keys have more unique values.
To create a fully qualified key (FQK), always add a key qualifier field to a join. And replace any null values in a key qualifier field. See [Join Objects in a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join.htm&type=5&language=en_US).
# Considerations for Using Multiple Currencies in Data Cloud
Keep these considerations in mind when using multiple currencies in Data Cloud.
- Data Cloud supports only static conversion rates and ignores dated conversion rates that are enabled in your Salesforce CRM org.
- If a currency’s conversion rate isn’t specified in your Salesforce org, Data Cloud returns a null value for the currency field. To avoid this issue, add currency conversion rates in your Salesforce org or use your own conversion rate DMO.
You can test the conversion rate using the Data Cloud Query Service conversion function in the Query Editor.
`select Order_ID__c, Sales__c, try_convert_currency(Sales__c, 'USD', 'EUR') as Sales_EUR, Profit__c, cdp_sys_record_currency__c from orders_same_currency__dll limit 10`
- If you connect multiple CRM orgs to Data Cloud, use the same list of currencies and conversion rates in each org.
- Data Cloud doesn’t support currency conversions across different CRM orgs connected to it. For example, assume that Data Cloud syncs conversion rates for US dollars (USD) and euros (EUR) from CRM org 1, and Japanese yen (JPY) and Indian rupee (INR) from CRM org 2. In this scenario, Data Cloud doesn’t support these conversions: USD to JPY, USD to INR, EUR to JPY, and EUR to INR. To avoid null values in your conversions, add USD and EUR currency rates to org 2, and JPY and INR currency rates to org 1.
- A currency field in a DMO can support different currencies. For example, the Amount field in a Sales Order DMO can be in USD for one order and in EUR for another. To help with currency conversions in such instances, the `cdp_sys_record_currency` field, which contains the ISO currency code value, is included by default.
- You can’t use a single-currency org in a sandbox org.
Keep these additional considerations in mind when using multiple currencies in calculated insights.
- All currency fields in a calculated insight must be in the same currency. For example, if a calculated insight includes two measures with currency values, all fields for both measures must be in the same currency.
- When using a calculated insight to aggregate currency values, the currency values must be converted into a single currency.
- When using the builder to create a calculated insight, the builder automatically manages the conversion logic. But, the user must select the currency for the insight output.
- When creating a calculated insight with currency fields using SQL, to adhere to syntax standards, include the `try_convert_currency` function using this syntax:
`try_convert_currency(Source Currency Field, Source Currency ISO, Target Currency ISO)`
- When using the builder to create a calculated insight that includes the currency data type, the builder automatically adds the `currency_type_c` field. When creating a calculated insight with currency fields using SQL, the user must add this field manually.
# Considerations for Working with Streaming Data Transforms
Considerations for working with streaming data transforms can significantly affect the performance, reliability, and success of your data processing pipeline.
## Creating Data Transforms
This diagram demonstrates four possible scenarios for working with data lake objects, data streams, and streaming data transforms.
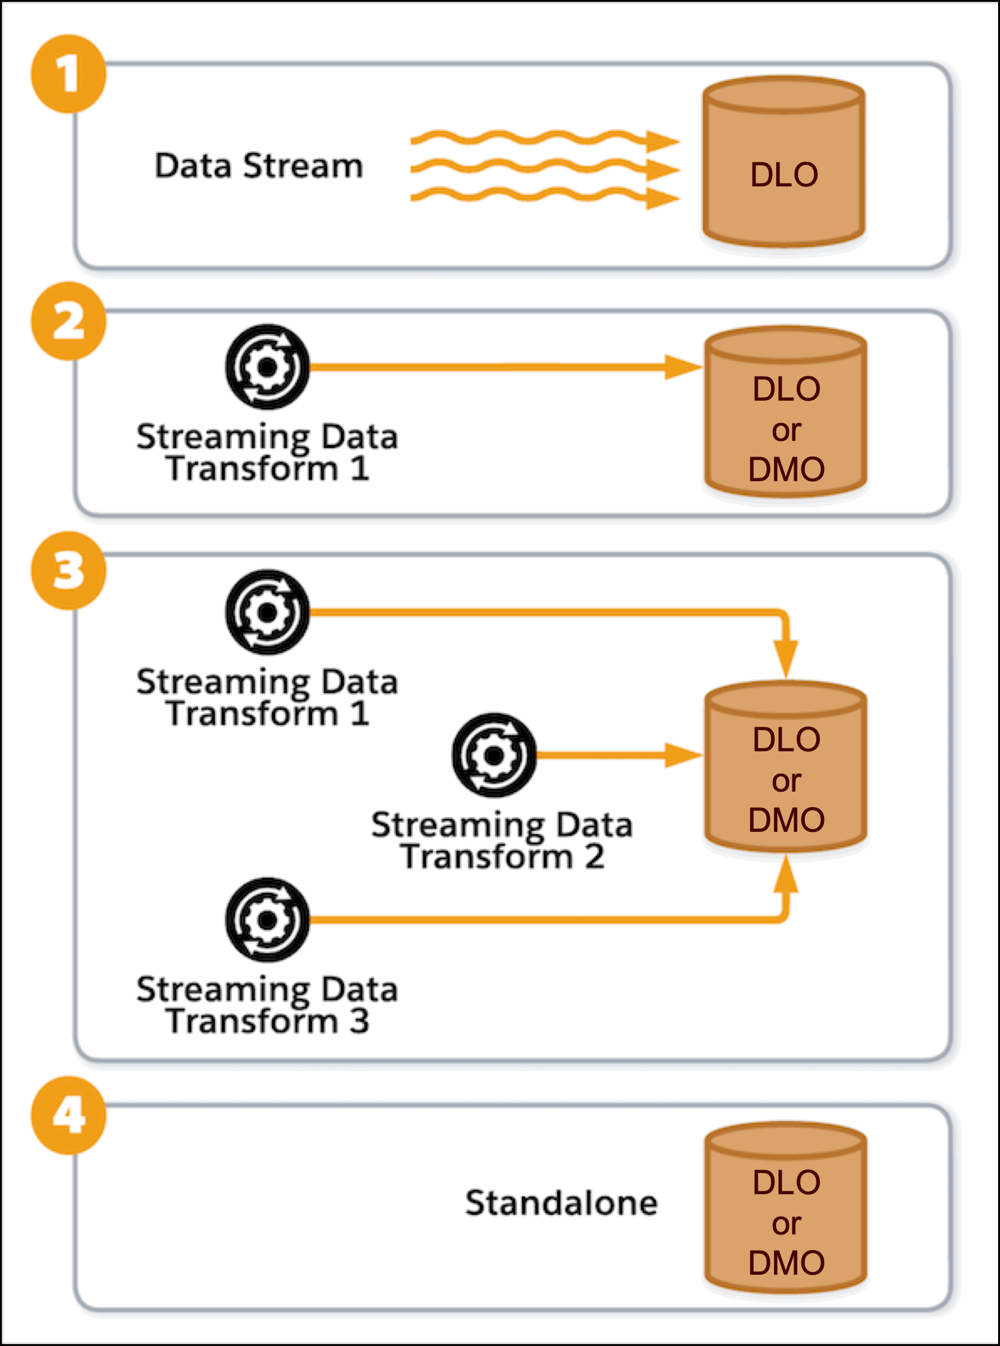
- At any given time:
- A DLO can receive data from at most, one data stream (1).
- A DLO or DMO can receive data from one or more data transforms (2, 3).
- A DLO or DMO can be standalone (4).
A standalone DLO can occur when a data stream is created and then detached from the DLO. It can happen when the data stream is deleted, but the data lake object is retained.
A standalone DMO can occur when a data transform is created and then deleted. The DMO remains, even though the transform that previously wrote to it no longer exists.
This diagram shows the case of a data stream writing to a DLO. While the data stream is connected to the DLO, you can't create streaming data transforms that write to it.
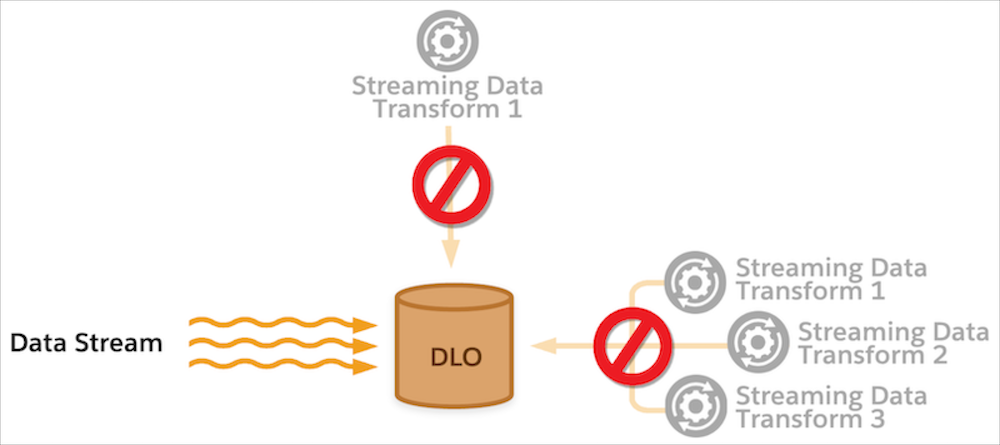
- You can’t change a streaming data transform after saving it. If you must change your streaming data transform, delete it and create another one.
- When you write the results of a streaming data transform to a data lake object, you can’t map the system fields, Data Source and Data Source Object.
- If a streaming data transform contains SQL syntax or other validation errors, you can’t save it. Syntax errors appear on the left side of the editor. Entering incorrect API names for the source object and target objects creates a validation error.
- Your streaming data transform SQL defines the field mappings for the primary key and other fields in the target objects. All SQL statements require a primary key. If the target object is categorized as Engagement, include a mapping for the `Event DateTime` field.
- To determine whether you’re using supported functions, review the Support Functions section.
- You aren’t required to use a `WHERE` clause in your streaming data transform statement. Using a `WHERE` statement is helpful if you must select specific records from the source object.
- Subqueries are not supported for streaming data transforms.
## Using Fully Qualified Keys
Use fully qualified keys to connect multiple data sources in Data 360 and avoid key conflicts when records from one or more sources use the same primary or foreign keys. You can’t use a key qualifier field in a data transform as a data source or as a destination. If a data transform references a key qualifier field, the streaming data transform fails validation and an error is displayed.
## Processing Data Transforms
- When a streaming data transform is created, it can take up to 30 minutes to read records from the source object, process, and begin writing to the target object. After the initial sync, streaming data transforms pick up new or updated records from the source object within a few minutes. Simultaneously active streaming data transform jobs can affect processing time.
- The Last Run Time field shows when the streaming data transform finished processing data records from the source object.
- To stop a streaming data transform, delete it.
- A DLO is available for selection as a target DLO only when its status is Active. If you don’t see the DLO that you want to use, check its status.
- You can use only DLOs created through the UI as target DLOs for streaming data transforms. You can’t use a DLO created by data stream as a target.
- A DMO is available for selection as targets only after you've created them using the "Create New" option during the setup of a new transform.
- If the streaming data transform status is Error, click **Retry**.
## Sharing Target Objects
More than one streaming data transform can read from the same source object or write to the same target object. When multiple streaming data transforms write to the same target object, avoid unintentional overwrites in the target object.
If streaming data transforms write to the same target object and generate the same primary key, these situations can occur.
- If the transforms write to different fields without any overlap, the state of the record in the target object is the same no matter which order the transforms run in.
- If the streaming data transforms write to the same fields, the state of the record in the target object is indeterminate. Transforms that run later overwrite the data written by the previous transforms. After all streaming data transforms run, the target object contains the data written by the last streaming data transform to run.
## Tracking and Preserving Record Lineages and Values
- DLOs and DMOs contain these lineage fields to track and preserve record lineage: Data Source, Data Source Object, and Internal Organization. When a streaming data transform updates a target object, it copies the lineage field values from the source object to the target object.
- When multiple streaming data transforms write to the same target object, the lineage fields are updated each time a transform runs with the field values from that streaming data transform’s source object.
# Consolidate Customer Service Data for Improved Support
Data Cloud provides you with a 360 view of your customers by unifying and harmonizing all customer service data in Service Cloud.
## About this Guide
This multi-step solution requires various users to complete steps in Data Cloud and Service Cloud. This solution helps you ingest data, unify that data, and create an insight, and view unified profiles.
To complete this use case, review the features used, permissions required, and associated skills.
Products or Features
Roles and Permissions
Data Cloud Architect permission set
Associated Skills
Let's review the high-level steps we cover in this guide.
## Configure Users and Install Data Bundles
Set up Data Cloud users, add the appropriate permission sets, and then install data bundles.
## Ingest and Map Data
Use a starter data bundle to create a data stream for Service Cloud. Then map required fields for Identity Resolution.
## Unify Service Data with Identity Resolution
Link multiple sources of data into a unified profile using an identity resolution ruleset that contains match and reconciliation rules based on the Individual data model object. Then view the profile in Profile Explorer.
- **[Configure Users and Install Service Cloud Data Bundle](https://help.salesforce.com/s/articleView?id=data.c360_a_conf_connect_dc4service.htm&release=264.0.0&type=5)**
Set up Data Cloud users, add the appropriate permission sets, and then install Service Cloud data bundle. These steps are all done within Data Cloud Setup.
- **[Ingest and Map Data from Service Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_ingest_map_dc4service.htm&release=264.0.0&type=5)**
In Data Cloud, you can connect to many data sources. Many of the Salesforce connectors have a starter data bundle to help you quickly set up a data streams, create data lake objects, and map to the data model automatically. However, you must map custom objects and some required fields to the Customer 360 Data Model to use Identity Resolution.
- **[Unify Service Data with Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_unify_data_dc4service.htm&release=264.0.0&type=5)**
Link multiple sources of data into a unified profile using an identity resolution ruleset. A ruleset contains match and reconciliation rules based on the Account data model object or the Individual data model object.
- **[Analyze Service Data with Calculated Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_analyze_ci_dc4service.htm&release=264.0.0&type=5)**
Calculate multidimensional metrics on your data within Data Cloud. You can create metrics at the profile, segment, and population levels. For example, evaluate performance at the channel level or use product metrics to understand purchasing and browsing behavior.
- **[Next Steps with Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_summary_dc4sales.htm&release=264.0.0&type=5)**
The use cases detailed in this guide give you a glimpse into how you can use Data Cloud to power your unified Customer 360. When you connect and unify more data sources, the more useful your unification, insights, and analytics become.
# Contact Point and Activation Membership Filtering
Personalize marketing communications by having more control on who you’re reaching out to through contact points and the activation membership in Data 360. Use filters to control the volume and variety of data to use in marketing segments.
To understand how Contact Point and Activation Membership Filtering works, review these use cases for the fictional insurance company, Cumulus Bank and Financial Services.
## Use Case: Email a Contract Renewal Notification (B2B)
Email decision-makers at a specific business about an expiring contract using their primary work email address.
## Use Case: Email a New Service Promo Notification (B2C)
Email customers about new services that have provided consent and opted in to receive advertisements.
## Use Case: Text a Policy Change SMS Notification (B2C)
Send an SMS message to customers living in California about their upcoming policy changes that have consented and provided their phone number.
## Related Content
To guide you through these use cases, we suggest these resources.
 [_Salesforce Help_: Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_targets.htm&release=264.0.0&type=5 "Depending on your use case, data can be activated to various targets, from file storage, external activation, or to other data model objects (DMOs) in Data 360. Once you know where you want to act on the segmented data from Data 360, create activation targets for each platform.")
 [_Salesforce Help_: Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_for_a_segment.htm&release=264.0.0&type=5 "Activation is the process that publishes a segment to activation platforms in Data 360. Before you activate your segments, it's important to review some activation concepts.")
 [_Salesforce Help_: Contact Points and Source Priority Order](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_points.htm&release=264.0.0&type=5 "Contact point selection determines which objects and fields are included in an activation and sent to an activation target. Use the source priority order to determine which contact point value is selected for the activation.")
 [_Salesforce Help_: Data Cloud Glossary of Terms](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&type=5&language=en_US)
 [_Trailhead_: Segmentation and Activation](https://trailhead.salesforce.com/content/learn/modules/customer-360-audiences-segmentation)
1. **[Email a Contract Renewal Notification (B2B) Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc1_contract_main.htm&release=264.0.0&type=5)**
Cumulus Bank wants to email decision-makers at a specific business about an expiring contract. Before sending the email, the bank ensures that it has consent for each email address to receive emails about contract renewals.
2. **[Email a New Service Promo Notification (B2C) Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc2_service_main.htm&release=264.0.0&type=5)**
Cumulus Bank wants to send an email message to customers about new services. They want to ensure that only customers who have provided consent and opted in to receive advertisements are the ones receiving the emails.
3. **[Text a Policy Change SMS Notification (B2C) Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc3_policy_main.htm&release=264.0.0&type=5)**
Cumulus Bank wants to send a SMS message to notify their customers living in California to check their account about upcoming policy changes. They want to ensure they’re including all phone contact points available for their customers that have provided consent.
# Contact Points and Source Priority Order
Contact point selection determines which objects and fields are included in an activation and sent to an activation target. Use the source priority order to determine which contact point value is selected for the activation.
You can include these contact points when creating an activation. Each activation target type can receive different contact points. For contact point values to be sent to an activation, certain data model object (DMO) fields must contain your contact point values.
To add contact points to your activations, first complete all required data stream mappings and add the data model relationships. For more information, see [Data Mapping Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_required_data_mappings.htm&type=5&language=en_US).
To learn how to model and map digital identifiers to the ContactPointDigitalId DMO to successfully use the activation toolkit for external platforms, see [Ingest and Model Digital Identifiers for JSON-based External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_map_digital_identifiers_activation_toolkit.htm&release=264.0.0&type=5 "Ingest and model your digital identifier data by using the standard ContactPointDigitalId data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.").
Contact Point
Description
Supported Platforms (Activation Targets)
Required Mappings and Relationships
Required Fields
Phone Number
Selecting phone as a contact point adds attributes related to phone for your
activation.
Contact Point Phone.Party→ Individual.Individual Id (ManyToOne)
Contact Point Phone:
The Country code has to be in ISO 3166 two-letter format for Marketing Cloud
Engagement. For example, US –United States and
JP –Japan.
Email Address
Selecting email as a contact point adds attributes related to email for your
activation.
Contact Point Email.Party →Individual.Individual Id (ManyToOne)
Contact Point Email:
Mobile App (MobilePush)
Selecting MobilePush as a contact point adds attributes related to mobile apps
for your activation.
Contact Point App.Party → Individual.Individual Id (ManyToOne)
Contact Point App:
Mobile Advertiser ID (MAID)
Selecting MAID as a contact point adds attributes related to MAID as attributes
for your activation.
Contact Point App:
Device:
The OS Name field value must be iOS or
Android . Values aren’t case-sensitive.
Over-the-top (OTT) ID
Selecting OTT as a contact point adds attributes related to OTT as attributes
for your activation.
Contact Point App:
Device:
The OS Name field value must be RokuOS ,
AndroidTV , tvOS ,
FireOS , Tizen ,
SmartCast , or WebOS . Values aren’t
case-sensitive.
WhatsApp
Selecting WhatsApp as a contact point adds attributes related to WhatsApp for
your activation.
Contact Point OTT Service.Party → Individual.Individual Id (ManyToOne)
Contact Point OTT Service:
The Country code has to be in ISO 3166 two-letter format for Marketing Cloud
Engagement. For example, US –United States and
JP –Japan.
Contact Point Digital Id
This contact point doesn’t appear on the Channel
Selection page. After you add attributes from the Contact Point Digital Id DMO,
it's displayed in the Contact Point Filter section when creating or updating an
activation.
Selecting Digital ID as a contact point adds attributes related to the digital
ID for your activation.
Contact Point Digital Id.Individual → Individual.Individual Id
(ManyToOne)
Contact Point Digital ID:
## Source Priority Order
Use source priority order to determine which contact point value is selected for an activation when multiple values are available. Also, to reorder which contact point value is selected for segment members with data from multiple sources. You can change the priority by adding, reordering, or deleting sources.
All contact points remain part of the Unified Individual DMO after unifying your source data in Identity Resolution. Identity Resolution reconciliation rules only reconcile fields for the unified individual object, not unified contact point objects. Use source priority to make sure that you deliver a contact point from your desired data source to your activation target regardless of your reconciliation rules. If the Email Type didn't select Any, then the Primary Flag must be mapped on the corresponding contact point DMO for contact points to match.
| Value | Description |
| --- | --- |
| Primary | If the Primary Flag field is mapped in Data Streams, Primary is listed as an option. |
| Any | If the Primary Flag field isn’t mapped, the activation retrieves a contact point value from any available source. |
| Personal | If the For Personal Use field is mapped in Data Streams, Personal is listed as an option. The value for the For Personal Use field must be 1. |
| Business | If the For Business Use field is mapped in Data Streams, Business is listed as an option. The value for the For Business Use field must be 1. |
To use values only from specific sources in your activation, delete Any Source and Any Type for the source priority order. Expect the population count of your activation to be lower because you’re selecting values from fewer data sources.
## Default Source Priority Order
Each platform has a default source priority order. For external platforms, the creator of the platform determines the default source priority order. For B2C Commerce Cloud and MobilePush, the default source priority order is always the same and can’t be changed.
Platform
Priority
Source
Type
Marketing Cloud Engagement (Phone, Email, and WhatsApp)
1
Marketing Cloud Engagement
Primary
2
Any
Any
Marketing Cloud Personalization (formerly Interaction Studio)
1
Marketing Cloud Personalization
Primary
2
Marketing Cloud Engagement
Primary
3
Any
Any
Cloud File Storage (Amazon S3, SFTP, Google Cloud Storage, Microsoft Azure)
1
Any
Any
MobilePush (in Marketing Cloud Engagement)
1
Marketing Cloud Engagement
Primary

Example A user creates an activation for a segment with source data from Marketing Cloud Engagement and Amazon S3, and adds the Email Address contact point to the activation. With the default source priority order, the activation selects an email address from Marketing Cloud Engagement for each individual who has one. If the individual doesn’t have an address, an email address is selected from Amazon S3. If the user removes the Any Source and Any Type, the segment is smaller because the activation selects email addresses only from the Marketing Cloud Engagement source to include in the activation.
#### See Also
- [_Salesforce Help_: Create Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_add_activation_target.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
- [_Salesforce Help_: Ingesting Consent Preferences](https://help.salesforce.com/s/articleView?id=data.c360_a_ingesting_consent_preferences.htm&release=264.0.0&type=5 "Ingest consent preferences from wherever you’re storing them using connectors. Common storage locations include data extensions (Marketing Cloud Engagement Connector), Sales or Service Cloud standard or custom objects (Salesforce CRM Connector), or external sources (Cloud Storage Connector).")
- [_Salesforce Help_: Data Ingestion and Modeling](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion_and_modeling.htm&release=264.0.0&type=5 "Data federation and data ingestion bring data from external data sources into Data 360. Data modeling is the next important phase to process data in Data 360.")
# Container Paths
Some containers have multiple paths back to the segmentation entity. When a container has multiple access paths, you can select a path to help Data 360 understand how to build your segment. The paths available when you first create a filter may differ from those available when you edit it later. This is expected behavior driven by relationship-cardinality rules.
## Why path selection matters
When you configure a related attribute filter, the Container Path dropdown lists every valid path from the container object back to your segment-on entity. The path you choose tells the segmentation engine which relationship to traverse, and therefore which group of records to use when building your segment.
For example, an order for a used car has a Buyer ID and a Seller ID, both relating back to the individual. Choosing a path when using order attributes as filter criteria determines which group is used to build the segment: car buyers or car sellers.
## What drives the paths in the dropdown
Data 360 derives the dropdown from the Attribute Library Metadata (ALM) — the model of every relationship between objects in your data graph. ALM finds every path between the container object and your segment-on object, then keeps only the paths that produce a reliable, unambiguous result set.
Paths shown:
- Paths whose hops all narrow toward the segment-on object (each hop maps many records to one)
- Paths whose hops all expand away from the container (each hop maps one record to many)
Paths not shown:
- Paths that mix both directions. It narrows on some hops, and expands on others. Mixing directions can multiply or collapse rows and produce duplicate or ambiguous records.

Example
A marketer wants to send a thank-you offer to customers who recently purchased a kitchen appliance. They build a segment on Individual with a filter on the Product container: `Product.Category = Kitchen Appliances`.
Product connects to Individual through two different relationships in the data model, so the Container Path dropdown shows two paths:
- `Product.OrderId > Order.PurchaserId > Individual.Individual ID` — individuals who bought a kitchen appliance.
- `Product.CaseId > Case.SubmittedBy > Individual.Individual ID` — individuals who complained about a kitchen appliance.
Both paths are valid, but they build very different audiences. For a thank-you campaign, the marketer chooses the first path. For a service-recovery campaign, they would choose the second.
# Content and Knowledge Harmonization
Use Harmonization to transform knowledge articles and unstructured content ingested into Data 360. Harmonization normalizes and enriches content, resulting in a single harmonized schema suited for consistent rendering in the Content Viewer. Access the viewer through Data 360's Data Explorer or in Service Cloud's Enterprise Knowledge component.
### Required Editions
The Harmonization dashboard contains a record of all harmonized content. From each record, you can view the harmonized content in the Content Viewer. Access the viewer in two ways:
- **From Data 360:** View harmonized files with the Content Viewer in [Data 360's Data Explorer tab](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer.htm&language=en_US&type=5).
- **From the Service Console:** View Salesforce Knowledge in the Enterprise Knowledge component in your Service Console. With consistent harmonized content, service reps see relevant and full documents and can explore more content without leaving the Service Console. See [Get Started with Enterprise Knowledge (Beta)](https://help.salesforce.com/s/articleView?id=service.knowledge_ek_about.htm&language=en_US&type=5)
## Billing Considerations
Data Harmonization and rendering can affect credit [consumption](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&type=5&language=en_US) in these areas:
- Data Pipeline and Ingestion: Data 360 calculates usage based on the number of records processed during every ingestion. For incremental ingestion, Data 360 only processes new or updated files. For Content Viewer engagement telemetry, events count as another data stream and as processed rows.
- Data Harmonization and Processing: When you create or update a search index, Data 360 calculates usage based on the amount of data processed in megabytes.
- Data Queries: Every search action against the index triggers a data query and counts as consumption. Every question in an Agentforce conversation that triggers a search counts as a data query. Every request to render a page counts as consumption.
- Data Storage: These operations count toward storage:
- File ingestion
- Table creation, such as data lake object (DLO), data model object (DMO), harmonized DLO, harmonized DMO, and engagement telemetry DLO.
- Chunk generation and index DMOs, which happens when you create a vector or hybrid index by using unstructured data.
- The transcription DMO, if Data 360 processes audio and video files.
- LLM gateway calls for AI enrichment, based on the number of tokens in the request and the response. Salesforce counts these calls as standard Flex credits or standard Einstein requests. The requests occur when the harmonized DMO (HDMO) sends files to an LLM for AI enrichment, specifically for generating Q&A summaries and FAQs.
## Supported Connectors
You can enable the harmonization of content that is ingested into Data 360 through unstructured data connectors.
- Structured Data Connectors
- [CRM](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector&language=en_US)
- Unstructured Data Connectors
- [GitHub](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-github-unstructured-data-stream.html)
- [GitHub](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-github-unstructured-data-stream.html)
- [Google Drive](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-googledrive-udlo.html)
- [Guru](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-a-guru-unstructured-data-stream.html)
- [Microsoft SharePoint](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-microsoftsharepoint-udlo.html)
- [Web Content (Crawler)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-crawler-udlo.html)
- [Web Content (Sitemap)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-sitemap-udlo.html)
- [YouTube](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-youtube-unstructured-data-stream.html)
- [Zendesk](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-zendesk-udlo.html)
- [Amazon S3](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-connector)
- [Azure Blob Storage](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-azureblob-connector.html)
## Limitations and Considerations
See [Content Harmonization Known Limitations](https://help.salesforce.com/s/articleView?id=data.c360_a_content_harmonization_known_limitations.htm&release=264.0.0&type=5 "Certain functionalities aren't available for content harmonization. Keep these limitations in mind while harmonizing content and viewing it on the Content Viewer.")
## Get Started with Content and Knowledge Harmonization
To get started ask yourself: "What kind of content do I have?" If your content is in a Salesforce Org, follow the [Structured Data Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_harmonization_for_structured_data.htm&release=264.0.0&type=5 "Use this workflow to configure harmonization for structured data such as Salesforce Knowledge."). If your content is in any of the sources listed in the unstructured connectors, follow the [Unstructured Data Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_content_harmonization.htm&release=264.0.0&type=5 "Use this workflow to create an unstructured content harmonization configuration for Data 360 content. The content must be ingested with a supported connector.").
- **[Configure Harmonization for Structured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_harmonization_for_structured_data.htm&release=264.0.0&type=5)**
Use this workflow to configure harmonization for structured data such as Salesforce Knowledge.
- **[Configure Harmonization for Unstructured Content](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_content_harmonization.htm&release=264.0.0&type=5)**
Use this workflow to create an unstructured content harmonization configuration for Data 360 content. The content must be ingested with a supported connector.
- **[View Harmonized Content Consistently in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_harmonized_content_consistently_in_data_explorer.htm&release=264.0.0&type=5)**
The harmonized Unstructured Data Model Object (UDMO) record page, available through the Content Viewer in Data 360’s Data Explorer tab or in Service Cloud's Enterprise Knowledge component, provides you with a unified, in-app experience od all data interactions (structured knowledge and unstructured content). Through the Content Viewer, your harmonized content is presented in a standard, consistent format, regardless of its source.
- **[Content Viewer User Engagement Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_content_viewer_user_engagement_insights.htm&release=264.0.0&type=5)**
When you enable content harmonization, Data 360 automatically starts collecting information about user interaction with the Content Viewer, providing you with insights to improve your content.
- **[View Content Viewer User Engagement Insights in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_content_viewer_user_engagement_insights_in_data_explorer.htm&release=264.0.0&type=5)**
Data 360 automatically creates an engagement telemetry data stream and a data lake object (DLO) to track user engagement with the Content Viewer. The Content Viewer is available only for harmonized content. You can view engagement data from the **Data Explorer** tab.
- **[Stop Engagement Data Collection](https://help.salesforce.com/s/articleView?id=data.c360_a_stop_engagement_data_collection.htm&release=264.0.0&type=5)**
User engagement data is collected by default to generate valuable insights, but you can choose to stop data collection for a specific engagement data stream by deleting the engagement data stream and associated Data Lake Object (DLO).
- **[Content Harmonization Known Limitations](https://help.salesforce.com/s/articleView?id=data.c360_a_content_harmonization_known_limitations.htm&release=264.0.0&type=5)**
Certain functionalities aren't available for content harmonization. Keep these limitations in mind while harmonizing content and viewing it on the Content Viewer.
- **[Content Harmonization Troubleshooting Guide](https://help.salesforce.com/s/articleView?id=data.c360_a_content_harmonization_troubleshooting_guide.htm&release=264.0.0&type=5)**
Tips for troubleshooting issues that can occur when you harmonize content in Data 360.
#### See Also
- [_Salesforce Help_: Content Harmonization Known Limitations](https://help.salesforce.com/s/articleView?id=data.content_harmonization_known_limitations.htm&language=en_US)
- [Configure Harmonization for Structured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_harmonization_for_structured_data.htm&release=264.0.0&type=5 "Use this workflow to configure harmonization for structured data such as Salesforce Knowledge.")
# Content Harmonization Known Limitations
Certain functionalities aren't available for content harmonization. Keep these limitations in mind while harmonizing content and viewing it on the Content Viewer.
### Required Editions
## Limitations for Unstructured Content Harmonization
**Harmonization Process**:
- See [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&release=264.0.0&type=5 "Data 360 supports multiple file formats and connector types for unstructured data.") for a list of supported file types and sizes for unstructured data.
- The harmonization pipeline currently skips files that fail to harmonize, but still indexes these files for search.
- The harmonization process doesn’t yet automatically generate a table of contents; file-splitting isn’t available yet.
- The harmonization process currently doesn’t retain document styling.
- You can’t currently view real-time progress or status of harmonization processing.
**Content Viewer Experience**:
- The Content Viewer doesn’t currently convert PDF files into HTML. It displays them using the built-in PDF viewer.
- Non-PDF files that aren’t harmonized automatically open in the original source view.
- The Content Viewer reformates the harmonized output into a consistent, unified style, discarding the unique styling of the original source.
- Relative links currently appear broken. See [Content Harmonization Troubleshooting Guide](https://help.salesforce.com/s/articleView?id=data.c360_a_content_harmonization_troubleshooting_guide.htm&release=264.0.0&type=5 "Tips for troubleshooting issues that can occur when you harmonize content in Data 360.")
# Content Harmonization Troubleshooting Guide
Tips for troubleshooting issues that can occur when you harmonize content in Data 360.
### Required Editions
## Troubleshooting for Unstructured Content Harmonization
**Relative Links Appear Broken**
- **Solution**: Update the relative links in the source content, to use a full path.
**Harmonized Content Isn’t Displayed on Data 360’s Data Explorer Tab**
- **Solution**:
- **UDMO**: Confirm that you are looking at the Harmonized UDMO, and not a different data object.
- **File Format Compatibility**: Check that the file types are supported for harmonization. Unsupported formats are only visible to view in their source platform. [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&release=264.0.0&type=5 "Data 360 supports multiple file formats and connector types for unstructured data.").
- **Website Content Setup (If Applicable)**: For content ingested from a website through a Web Content connector, verify that pages and elements are correctly defined. See instructions for [Crawler](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-udlo.html) and [Sitemap](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-udlo.html) web content.
**Images Don't Display**
- **Solution**:
- **Image Source**: Check the original website or file to confirm the image exists, is publicly accessible, and is not blocked by CORS or domain restrictions.
- **Image Ingestion**: Locate the image record in the UDLO to verify that it was successfully ingested. Images that rely on lazy-loading or dynamic loading on a website aren't captured by the connector.
# Content Object Data Mappings
Content data streams enable you to upload and ingest files that you’ve attached to Knowledge objects. Manually map the listed fields of the Content Document and Content Document Link objects to DMOs in Data 360.
## Content Version
DMO Object API Name: ContentVersion\_\_dlm
Select all fields when you create the data stream. Required mappings happen automatically.
## Content Document
This table lists required field mappings for the Content Document DLO. DMO Object API Name: `ssot_ContentDocument__dlm`
| DLO FIELD LAbel | Description | DMO Field API Name | DMO Field label |
| --- | --- | --- | --- |
| `LatestPublishedVersionId` | The ID of the latest document version (ContentVersion) | `ssot__LatestPublishedVersionId__c` | Latest Published Version |
| `ContentDocumentId` | The ID of the content document | ssot\_\_ContentDocumentId\_\_c | Content Document Id |
## Content Document Link
This table lists required field mappings for the Content Document Link DLO. DMO Object API Name: `ContentDocumentRelationship__dlm`
| DLO FiEld Label | Description | DMO Field API Name | DMO Field label |
| --- | --- | --- | --- |
| `ContentDocumentLinkId` | Primary key | `ssot__Id__c` | Content Document Relationship Id |
| `ContentDocumentId` | The ID of the content document | `ssot__ContentDocumentId__c` | Content Document |
| `LinkedEntityId` | The ID of the linked object. Can include Chatter users, groups, records (any that support Chatter feed tracking including custom objects), and Salesforce CRM Content libraries | `ssot__RelatedItemId__c` | Related Item |
| `LastModifiedDate__c` | The last modified data time | `ssot__LastModifiedDate__c` | Last Modified Date |
#### See Also
- [_Salesforce Help_: Map a Custom DMO](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&release=264.0.0&type=5 "Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.")
# Content Viewer User Engagement Insights
When you enable content harmonization, Data 360 automatically starts collecting information about user interaction with the Content Viewer, providing you with insights to improve your content.
### Required Editions
## Collected Events
Data 360 collects these event types:
- “Document View” event, triggered when users view your harmonized content in the Content Viewer. This metric tells you how often your harmonized content is accessed. A high number indicates good discoverability and initial interest. You can track this over time to see trends.
- “Page exit” event, triggered when users leave the Content Viewer. This metric indicates user engagement and satisfaction. A high exit rate shortly after a "document view" can signal that the content isn't meeting user expectations, is difficult to read, or isn't relevant to users’ initial search. This metric provides a percentage indicator of how deep the user scrolled through the content. For example, 100% means the user scrolled all the way to the bottom of the page before they exited.
- “Open in source” event, triggered when users click the link leading to the harmonized content in its source platform, for example, Google Drive. This event can indicate high user trust and the need for more information, which can indicate a content gap.
- “Link clicked” event, triggered when users click any link within the Content Viewer. This data indicates that the content has successfully piqued the user's interest, prompting them to seek further information or explore related resources.
## Collected Data Attributed
These are some of the attributes that can be displayed for the above events.
DAta
description
data type
example
Title
The title of the harmonized file or record
Text
How to display a title
Document ID
The ID of the harmonized file or record
Text
646b1f986e7ba1ba1b2be01b3a0ffdeb
Updated Date
The date the harmonized file was last updated
DateTime
2024-06-01T12:00:00Z
Created Date
The date and time the harmonized file was created
2024-05-01T09:00:00Z
Source
The source of the file
Confluence
Format
The format of the orignal file
PDF
Source Object ID
The ID of the original DLO
HUDMO-001
Language
The language of the file displayed
Text
In large file-splitted PDFs, the overarching PDF
title/ID
Text
en-US
Referral Context
The page the user was on before getting to this content page
Text
https://previous-page.com/
URL
The URL of the current page the event was triggered on
"https://docs.example.com/doc-12345
Interaction Name
The type of the event
Document View
Application
The application, agent, or cloud in which the Content Viewer page was
opened
Service Cloud
Context
The context in which the page was viewed
Data 360 Record Page
Country
The country code in which the user is located
IN
Selected Language
The language selected by the user
en-US
Organization ID
The 15-character ID of the Salesforce org
00D000000000123
Domain
The domain of the authenticated user (N/A for anonymous users)
@salesforce.com
Event ID
The globally unique identifier (GUID) for the event
{{$guid}}
Session ID
The unique session ID
sessionID
User ID
The unique user ID
dfb8e760b101c6e5d1449d518d1bda3b
Device
The device used to log in to Salesforce
Tablet
User Type
Application type of the request
A—App
C—Customer Portal
P—Partner Portal
G—guest
A
Browser Model
The specific version of the web browser where the article was viewed
Chrome 124.0.0.0
Browser Name
The name of the client browser using the website where the article was
viewed
Chrome
Scroll Depth
The maximum scroll position achieved by the user in percentage
Number
50
Link Clicked
The URL of the clicked page
Text
# Control and Metadata Change Events
Set up notifications for your Data 360 data in Flow Builder and create reports to see your Data 360 statuses.
### Required Editions
Data 360 supports several configuration objects with control events notifications, so you don’t have to view object records in Lightning Experience to receive the latest updates. With these event notifications, you can also get accurate visibility on the use of Data 360 in reports and dashboards. Set up notifications for your Data 360 data in Flow Builder and create reports to see your Data 360 statuses.
You can set up process flows on top of these Data 360 configurations.
## Data Stream
- ImportRunStatus
- Field Values: PENDING, IN\_PROGRESS, SUCCESS, FAILURE
- LastRefreshDate
- Field Values: Date
- LastNumberOfRowsAddedCount
- Field Values: Number
- TotalNumberOfRowsAdded
- Field Values: Number
- TotalRowsProcessed
- Field Values: Number
## Segment (MarketSegment)
- SegmentStatus
- Field Values: INACTIVE, COUNTING, PROCESSING, ACTIVE, ERROR
- Last SegmentStatusDateTime
- Field Values: Date
- LastSegmentStatusErrorCode
- LastSegmentMemberCount
- Field Values: Number
- LastSegmentRemainderCount
- Field Values: Number
- LastSegmentExcludedCount
- Field Values: Number
- PublishStatus
- Field Values: PUBLISHING, SUCCESS, ERROR, NOT\_PUBLISHED
## Activation (MarketSegmentActivation)
- LastPublishStatus
- Field Values: PUBLISHING, SUCCESS, ERROR, PARTNER\_ERROR, SEGMENT\_ERROR
- RecordCount
- Field Values: Number (Long)
- LastPublishedDate
- Field Values: DateTime
## Calculated Insights (MktCalculatedInsight)
- LastRunDateTime
- Field Values: Date
- LastRunStatusDateTime
- Field Values: Date
- LastRunStatus
- Field Values: NONE, PENDING, PROCESSING, SUCCESS, ERROR, ABORTED
- LastCalcInsightStatusErrorCode
- Field Values: PROCESSING\_FAILED, CREATE\_FAILED, DELETE\_FAILED, VALIDATION\_FAILED
## Identity Resolution (IdentityResolution)
- LastRunStatus
- Field Values: SUCCESS, ERROR, IN\_PROGRESS
- ErrorCode
- Field Values: NO\_ERROR, PUBLISHING\_ERROR, DELETING\_ERROR, UNKNOWN\_ERROR, NO\_MATCH\_RULES\_ERROR
- LastRunStatusDateTime
- Field Values: Date
- SourceCount
- Field Values: Number (Long)
- MatchCount
- Field Values: Number (Long)
- UnifiedCount
- Field Values: Number (Long)
- ConsolidationRate
- Field Values: Number (Double)
## DataObjectMetadataChgEvent (Platform Event)
- EventType
- SchemaVersion
- EventPublishDate
- Field Values: Date
- EventCreationDate
- Field Values: Date
- SourceTableDeveloperName
- Field Values: Text
- Trigger
- Field Values: Text (Create, Update, Delete)
- PreviousValue
- Field Values: Text
- CurrentValue
- Field Values: Text

Example
```sql
"EventType": "DataObjectMetadataChgEvent",
"SchemaVersion": "1.0",
"EventPublishDate": "2021-08-03T12:09:32.675Z",
"EventCreationDate": "2021-08-03T12:09:31.571Z",
"SourceTableDeveloperName": "Ind2__dll",
"Trigger": "Update",
"PreviousValue": "{"fields":[{"name":"address__c","displayName":"Address","type":"STRING"},{"name":"birthdate__c","displayName":"birthdate","type":"DATE_TIME"},{"name":"childrencount__c","displayName":"childrencount","type":"NUMBER"},{"name":"DataSource__c","displayName":"Data Source","type":"STRING"},{"name":"DataSourceObject__c","displayName":"Data Source Object","type":"STRING"},{"name":"emailnew__c","displayName":"EmailNew","type":"STRING"},{"name":"firstname__c","displayName":"FirstName","type":"STRING"},{"name":"gender__c","displayName":"gender","type":"STRING"},{"name":"id__c","displayName":"id","type":"STRING"},{"name":"InternalOrganization__c","displayName":"Internal Organization","type":"STRING"},{"name":"lastname__c","displayName":"LastName","type":"STRING"},{"name":"maritalstatus__c","displayName":"maritalstatus","type":"STRING"},{"name":"maritalstatusname__c","displayName":"maritalstatusname","type":"STRING"},{"name":"occupation__c","displayName":"occupation","type":"STRING"},{"name":"partyid__c","displayName":"partyid","type":"NUMBER"},{"name":"personname__c","displayName":"personname","type":"STRING"},{"name":"phone__c","displayName":"Phone","type":"STRING"},{"name":"socialhandle__c","displayName":"SocialHandle","type":"STRING"},{"name":"yearlyincome__c","displayName":"yearlyincome","type":"NUMBER"}],"category":"Profile","name":"Ind2__dll","displayName":"Ind2","primaryKeys":[{"name":"id__c","displayName":"id","indexOrder":"1"}]}"
"CurrentValue": "{"fields":[{"name":"address__c","displayName":"Address","type":"STRING"},{"name":"birthdate__c","displayName":"birthdate","type":"DATE_TIME"},{"name":"childrencount__c","displayName":"childrencount","type":"NUMBER"},{"name":"DataSource__c","displayName":"Data Source","type":"STRING"},{"name":"DataSourceObject__c","displayName":"Data Source Object","type":"STRING"},{"name":"emailnew__c","displayName":"EmailNew","type":"STRING"},{"name":"firstname__c","displayName":"FirstName","type":"STRING"},{"name":"gender__c","displayName":"gender","type":"STRING"},{"name":"id__c","displayName":"id","type":"STRING"},{"name":"InternalOrganization__c","displayName":"Internal Organization","type":"STRING"},{"name":"lastname__c","displayName":"LastName","type":"STRING"},{"name":"maritalstatus__c","displayName":"maritalstatus","type":"STRING"},{"name":"maritalstatusname__c","displayName":"maritalstatusname","type":"STRING"},{"name":"occupation__c","displayName":"occupation","type":"STRING"},{"name":"partyid__c","displayName":"partyid","type":"NUMBER"},{"name":"personname__c","displayName":"personname","type":"STRING"},{"name":"phone__c","displayName":"Phone","type":"STRING"},{"name":"socialhandle__c","displayName":"SocialHandle","type":"STRING"},{"name":"yearlyincome__c","displayName":"yearlyincome","type":"NUMBER"}],"category":"","name":"Ind2__dll","displayName":"Ind2","primaryKeys":[{"name":"id__c","displayName":"id","indexOrder":"1"}]}",
```
## SearchIndexJobStatusEvent (Platform Event)
- ApiName
- Field Values: Text
- ErrorCode
- Field Values: Text
- EventCreationDate
- Field Values: DateTime
- EventPublishDate
- Field Values: DateTime
- EventType
- Field Values: Text
- IndexRefreshedOn
- Field Values: DateTime
- SchemaVersion
- Field Values: Text
- RuntimeStatus
- Field Values: Ready, In Progress, or Failed
Using these object types, create flows in Flow Builder to monitor your data streams for results or changes.
# Control Data Graph Access
Data graph governance in Data 360 controls how you access data by enforcing permissions at the object and field levels, so you see only the data you’re permitted to access. Governance policies are defined using tags inherited from source data model objects (DMOs) and applied to the data graph.
### Required Editions
When you query a data graph, Data 360 evaluates access dynamically:
- Removes objects you don’t have access to
- Removes or masks restricted fields
- Filters metadata for inaccessible objects and fields
Instead of denying the entire data graph, Data 360 returns only the data you can access.
Granular governance works with existing data graphs without requiring changes. Existing APIs continue to function. The difference is in how data is returned. Restricted objects and fields are filtered out. When granular governance is enabled, Data 360 automatically backfills governance tags for existing data graphs before the feature is enabled.
- Data graphs that were previously visible: Governance tags are automatically propagated to the data graph at rollout. Access becomes more granular. Instead of the entire data graph being blocked or fully accessible, you see only the objects and fields you're authorized to access. This is not a breaking change. Previously blocked objects and fields remain blocked, while accessible ones continue to be available.
- Data graphs that were not previously visible: Granular governance applies based on the governance tags propagated from source DMOs and the policies available. Individual objects and fields that you have access to become accessible, even if the data graph was previously inaccessible as a whole.

Note With granular governance, access restrictions on child DMOs no longer prevent access to the entire data graph. As a result, users may gain visibility into objects or fields that are permitted by policy, even if the data graph was previously inaccessible as a whole. If you rely on child DMO restrictions to block access to an entire data graph, review your governance configuration and apply the appropriate governance tags or an explicit deny policy to the output DMO to prevent unintended visibility.
## Governance Enforcement
Data 360 enforces governance policies across all access points. Under granular governance, Calculated Insights (CI) operate on an **all-or-none basis**. If you do not have access to even one field of a CI, you cannot see the entire CI node in the data graph response. This is different from regular DMOs, which are granularly pruned (allowing partial field visibility).
- API: Data 360 APIs enforce access controls on both data and metadata responses, including:
- [Data Graph Query API](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-v1-data-graphs-name-id.html)
- [Data Graph Lookup API](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-v1-data-graphs-lookup.html)
- [Data Graph Metadata API](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-v1-data-graphs-metadata.html)
- UI: Governance is also enforced in the Data Graph UI. Objects and fields that you don’t have access to are hidden or masked.
## Tags in Data Graphs
Tags define governance policies and control access to data in a data graph. Data graphs inherit tags from source data model objects (DMOs), and tags are applied at both the object and field levels.
Tags applied to a DMO are associated with the corresponding object in the data graph, and tags applied to DMO fields are associated with the corresponding fields. These tags determine which objects and fields users can access when querying the data graph.
Data graphs don't support direct tag assignment or management. All tags are managed at the DMO level and reflected in the data graph through propagation.
When you create a data graph, it automatically inherits tags from the underlying DMOs and fields.
To add tags, apply them to the source DMO or its fields, and then use the DMO UI to propagate them to data graphs and other services.
To update or remove tags, modify or remove them on the source DMO or its fields. Changes to tags on source DMOs aren't applied immediately to existing data graphs. A data graph can temporarily reflect previously applied tags until tags are reapplied to synchronize it with the latest configuration.
Tag Manager doesn't support data graph objects or fields. Manage all tag additions, updates, and removals at the DMO level. To reflect updated tag configurations in a data graph, reapply tags on the data graph. Reapplying tags removes all existing tags on the data graph and replaces them with the current tags inherited from source DMOs and fields.
- **[Reapply Tags for a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_dg_reapply_tags.htm&release=264.0.0&type=5)**
After updating or removing tags at the DMO level, reapply tags to synchronize a data graph with the latest tag configuration from its source DMOs. When you reapply tags, all existing tags on the data graph are removed and replaced with the current tags from source DMOs and fields.
# Controlling External User Access in Data 360
Use data governance policies to control what external users can access in your Data 360-powered apps. By defining clear, policy-based access, you make sure that unidentified external users and authenticated external users see only the data intended for them.
### Required Editions
Data 360 supports these user types with different levels of trust and access. Internal users have the highest level of trust, while unidentified external users have the lowest.
- **Unidentified External User:** An unauthenticated user who accesses a Data 360-powered application without signing in. These users don't require Data 360 user permissions. Policies for unidentified external users govern access.
- **Authenticated External User:** An authenticated user, such as a customer or partner, who accesses Salesforce through an external-facing application. These users don't require Data 360 user permissions. Policies for authenticated external users govern access.
- **Internal User:** An authenticated user in your Salesforce organization, such as an employee or contractor. Assigned permissions, data space access, and applicable governance policies govern access to Data 360 data. External-user access policies don't govern internal users.
User Permissions Needed
To create data access policies for external users:
Permission set:
Many apps powered by Data 360 involve external users, such as customers or partners. To prevent accidental exposure of sensitive information, Data 360 includes built-in guardrails that restrict access by default.
Data 360 denies external users access to all data unless you explicitly grant access through classification and policies. Classification determines whether an object is eligible for external access, and policies determine who can access it.
- **Unidentified external users:** Data 360 denies access to all objects unless you classify the object as public by applying the standard `ExternalData.Visibility.Public` tag.
- **Authenticated external users:** Data 360 denies access to all objects unless you classify the object as portal or public by applying the standard `ExternalData.Visibility.Portal` or `ExternalData.Visibility.Public` tags.
- **Internal users:** Data 360 allows access based on internal policies and classifications, without requiring external visibility tags.
Granting access to external users requires classification, policy creation, and for authenticated external users, data space access through permission sets. For more information, see [Data Tagging and Classification in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_using_tagging_and_classification_dg.htm&type=5&language=en_US) and [Create an Object or Field-Level Access Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_ols_fls_policy.htm&type=5&language=en_US).
## Policy Authorization Levels
Policies include an authorization level that defines the user type: Internal, Authenticated External, or Unidentified External. Set this level when you create the policy. This selection adds uneditable default conditions in the policy based on the selected authorization level. You can't change the authorization level after saving the policy.
Policies follow a cascading logic based on the user’s authorization level.
- Allow policies cascade up: If you grant access to an unidentified external user, authenticated external and internal users also receive that access.
- Deny policies cascade down: If you deny access to an internal user, this also applies to authenticated and unidentified external users.
All existing policies automatically apply only to internal users.
## Object Classification and Visibility
Classify the target object before you create an Allow policy to grant access to an external user. Only objects you classify as `Data Categorization.Access Level.Portal` or `Data Categorization.Access Level.Public` are eligible for external access. This process makes sure that you only expose data explicitly marked for external use.
External Visibility Classification
| Object Access | Preconfigured Tag | Classification |
| --- | --- | --- |
| Unidentified and Authenticated External Users | `ExternalData.Visibility.Public` | `Data Categorization.Access Level.Public`: The most permissive level. |
| Authenticated External Users only | `ExternalData.Visibility.Portal` | `Data Categorization.Access Level.Portal`: Restricted to authenticated external users. |
## Safeguards and Governance Considerations for External Access
Review these considerations before you configure external access.
- **Automatic guardrails:** When you create an object-level Allow policy for external users, the system automatically adds default conditions.
- In the resource section, a condition requires you to classify the objects as `Data Categorization.Access Level.Portal` or `Data Categorization.Access Level.Public`.
- In the principal section, a condition requires you to grant access only to the selected authorization level, such as unidentified external users or authenticated external users. This condition prevents a broad Allow policy from accidentally exposing internal data or granting access to unintended user types.
- **Security access controls:** Create object-level security (OLS), field-level security (FLS), or row-level security (RLS) policies for objects shared with authenticated external users to ensure that users can access only the data intended for them.
- **Legacy policy protection:** To maintain security, Data 360 automatically restricts all policies created before the introduction of authorization levels to internal users.
- **Permission set and data space assignment:** Don't assign the Data 360 User permission set or explicit data space assignment to authenticated external users or unidentified external users. The Data 360 User permission set is for internal Salesforce users only. External users gain access to Data 360 data exclusively through DMO/DLO object tagging and explicit data governance Allow policies.
## Unidentified External User Access Through AI Agents
Unidentified external user policies don’t apply when the user interacts with an AI agent running with Agent Service Account (ASA) with internal org-wide default access. Because these agents run queries in the context of an internal integration user, internal user policies apply instead.
To provide secure access in this scenario:
- Use an internal user policy restricted by a custom permission.
- Assign it only to the agent’s integration user.
- Limit access to public objects.
## Digital Agent External User
Starting in Summer ‘26, you can select Digital Agent External User in the Agent Creator. When selected, this maps to an unauthenticated Unidentified External User in Data 360.
To provide secure access:
- Tag public objects with the preconfigured `ExternalData.Visibility.Public` tag.
- Use an Unidentified External User policy restricted by a custom permission.
- **[Troubleshoot External User Access Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_troubleshoot_external_user_access.htm&release=264.0.0&type=5)**
Resolve common issues with authenticated external user and unidentified external user access to Data 360.
#### See Also
- [_Salesforce Release Notes_: Control External User Access with Data Governance Policies](https://help.salesforce.com/s/articleView?id=release-notes.rn_cdp_2026_summer_external_user_access_governance.htm&release=262&type=5&language=en_US)
# Conversion API (CAPI) Activations to Ad Audiences Partner Platforms
Conversion API (CAPI) activation targets send online and offline conversion events from a data model object (DMO) to supported advertising platforms. CAPI uses streaming DMO activation instead of audience segment activation.
### Required Editions
## Supported CAPI Targets
The Ad Audience license supports these CAPI activation targets. To create a CAPI activation target, see [Create an External Platform Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&release=264.0.0&type=5 "To publish segments to your external advertising platforms like Amazon Ads, create an external platform activation target in Data 360. An external platform can have multiple activation targets, but you can attach only one activation target to an external platform account.").
- [LinkedIn CAPI](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-linkedincapi-connector.html)
- Meta CAPI
- TikTok CAPI
- Snapchat CAPI
- Pinterest CAPI
## CAPI Activation Limits and Considerations
- Each CAPI streaming activation sends up to 30,000 events. When an activation exceeds the limit, Data 360 truncates the activation file and drops the remaining events. To increase the limit to up to 200,000 events, contact your Salesforce account executive.
- CAPI uses streaming DMO activation. You select a data model object (DMO) as the event source. You can’t activate a segment to a CAPI target.
- Each advertising platform enforces API rate limits and a maximum event lookback window. The platform rejects events that exceed its rate limit or fall outside its lookback window.
- Data 360 sends events to the partner platform continuously, at a fixed interval of 5 seconds.
- To expand the customer records available for identity enrichment, create a data graph and associate it with the CAPI activation. See [Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graphs.htm&type=5&language=en_US).
- Mapping optional attributes such as first name, last name, country code, and external IDs improves user match rates on the partner platform.
# Convert a Data Cloud Home Org to a Data Cloud One Companion Org
To convert a home org into a companion org, first remove all Data Cloud data from your org, then connect it as a companion org to a different Data Cloud instance. You can’t convert an org that has Data Cloud enabled.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
1. Delete or update processes that rely on Data Cloud data.
Processes and features that aren’t updated break when Data Cloud is turned off.
2. Contact your account executive to exchange your Data Cloud home org license for a Data Cloud One companion org license.

Note After replacing your Data Cloud home org license, you can't access Data Cloud data, metadata, configurations and data spaces, though they remain in your org for a grace period of 120 days. To connect an org as a Data Cloud One companion org, delete all metadata, data, and data spaces.
3. Follow the [Data 360 cleanup](https://help.salesforce.com/s/articleView?id=data.c360_a_lifecycle_management_cleanup.htm&language=en_US) process to delete all Data Cloud data from your org.
After your Data Cloud instance and its data have been removed, initiate the connection from a home org to connect it as a companion org.
# Copy a Segment
In Data 360, you can copy an existing segment to populate it with the same filters and customizations as an existing segment.
### Required Editions
Permission Sets Needed
To delete a segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. Go to **Segments**.
2. Select the segment that you want to copy.
3. Click **Copy**.
4. Name the new segment and choose a publish schedule.
5. Click **Save**.
# Copy and Paste a Batch Data Transform
Use the toolbar or keyboard shortcuts to copy and paste nodes within a single batch data transform or across multiple ones. To use this feature, enable clipboard access permissions in your browser.
### Required Editions
User Permissions Needed
To copy a batch data transform
Permission set:
1. In a batch data transform, select one or more nodes to copy or cut.
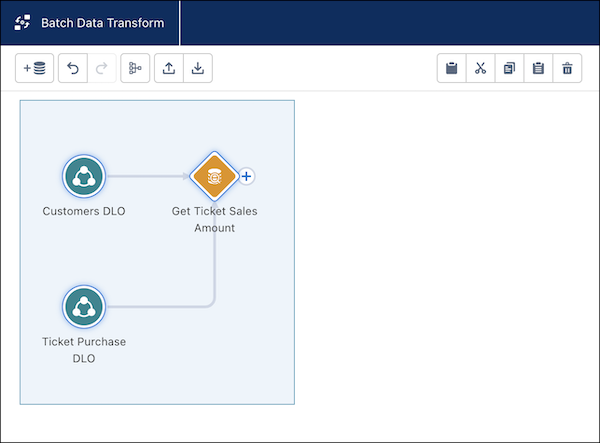
2. From the toolbar, click the copy icon or press Ctrl+c to copy. To cut, click the cut icon or press Ctrl+x. To duplicate, which copies and pastes in one step, click the duplicate icon. To delete a node, click the trashcan icon or press Ctrl+d.
3. Click the paste icon or press Ctrl+v to paste.
The copied image displays below the original.
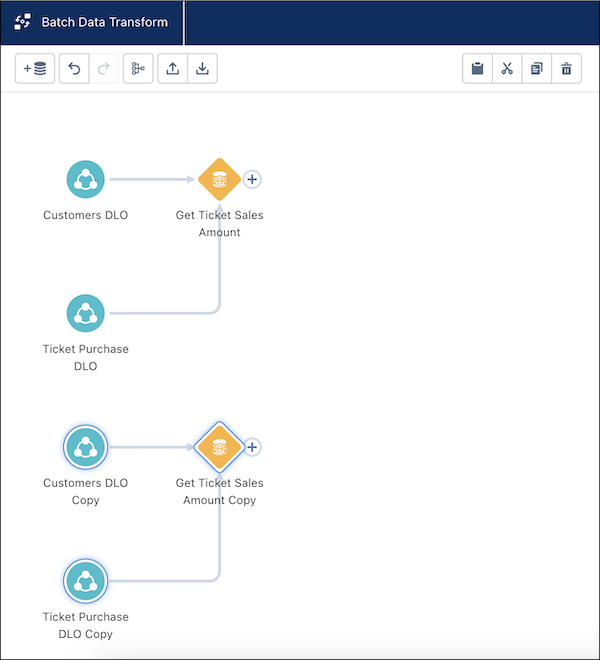
# Copy Field Enrichment Matching
Copy Field enrichments enhance the records in your org by adding data from other data sources. To avoid returning data that isn’t relevant to the records in your org, the enrichment matches data from your org to data in Data Cloud. How the data is matched determines what data is returned.
## Linking Fields
To match records in your org to data in Data Cloud, enrichments use associations to other objects. To create the associations used by copy field enrichments, create a Unified Individual or Unified Account object.
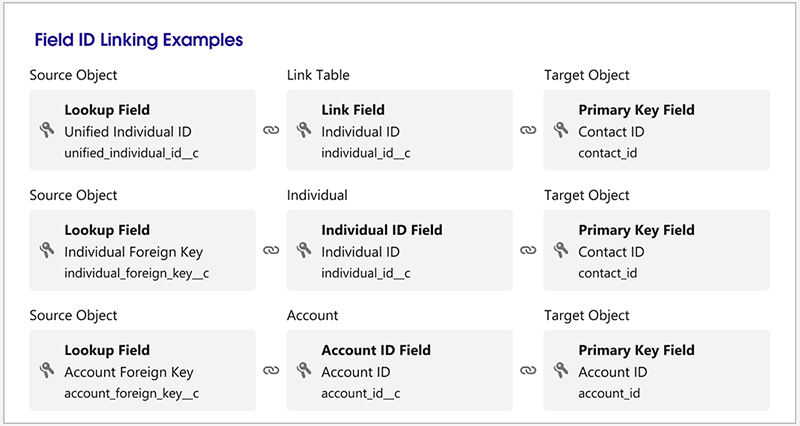
## Copy Field Matching
Copy field enrichments match records differently, depending on which ID matching type and object you select.
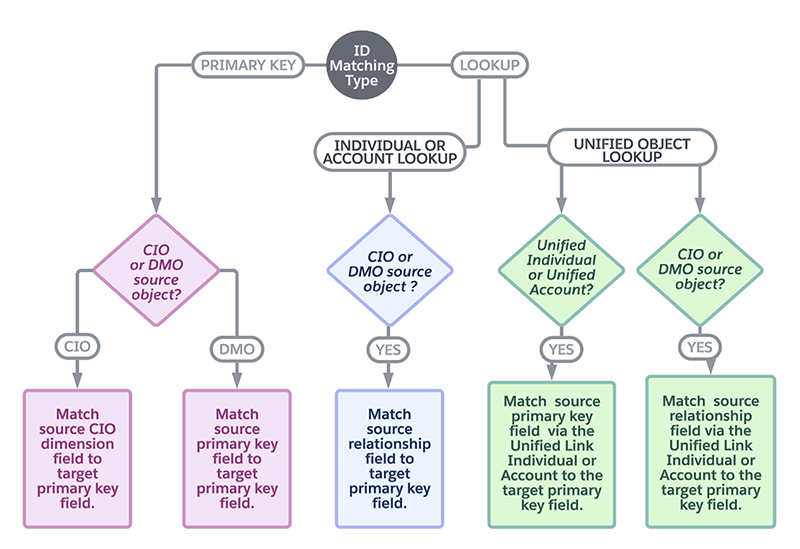
## Example: Copying a Nickname field via the Primary Key
If Data Cloud has a Nickname field on the Individual DMO, you can copy data for any individuals that match the primary key values for the Contact object in your org
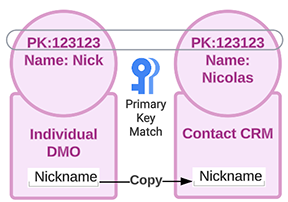
## Example: Copying a Mileage field from a Calculated Insight Object via an Individual DMO or Account DMO Lookup
If you have a calculated insight object that has a relationship with an Individual DMO or Account DMO on its dimension, you can use that relationship to match records for individuals that have the same primary key as a Contact object in your org.
## Example: Copying a Mileage Field from a Calculated Insight Object via a Unified Individual DMO or Unified Account DMO Lookup
If you have a calculated insight object that has a relationship with a Unified Individual DMO or a Unified Account DMO on its dimension, you can use that relationship to match records for individuals that have the same primary key as a Contact object in your org.
## Example: Copying a Nickname from a Unified DMO
If you have a Unified Individual DMO, you can use the Unified Link Individual DMO to match the UID for the Data Cloud object and the primary key for the Contact object.
# Create a B2C Commerce Activation Target
To publish segments to Commerce Cloud, create an activation target in Data 360.
### Required Editions
User
Permissions Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activation Targets tab, click **New**.
2. Select **B2C Commerce**, and click **Next**.
3. Enter a name and an optional description.
1. Select the data space that you want to associate your activation target with.
2. Select the connector.
The selected data space determines the available connectors.
3. Click **Save**.
Your Commerce Cloud activation target is created.
# Create a B2C Commerce Data Stream
The only way to create and map B2C Commerce data streams is to create a data bundle called B2C Commerce Order Bundle. This data bundle includes specific entities, some of which support custom field attributes for mapping to a data model object (DMO), and it doesn't allow for individual data stream deployment. This deployment requires you to be a Data 360 admin.
### Required Editions
User Permissions Needed
To create a data stream
Permission set: Data Cloud Architect
1. Enable Commerce Einstein tracking in your B2C Commerce instance.
The Order Bundle includes these entities:
- Bundle Product (supports custom field attributes)
- Goods Product (supports custom field attributes)
- Master Product (supports custom field attributes)
- Product Catalog
- Product Category
- Product Category Product
- Product Option
- Product Option Value
- Product Product Option
- Sales Order
- Sales Order Customer
- Sales Order Product
- Sales Order Product Option Value
- Customer Profile
2. In Data 360, go to the Data Streams tab and click **New**.
3. Select the B2C Commerce data source and click **Next**.
4. Select a B2C Commerce instance and click **Next**.
Only a B2C Commerce production instance can be selected. If you have only one instance connected to Data 360, it’s selected by default.
5. Select the order bundle that includes the order, product, and customer data.
If you have only one instance, its order bundle is selected by default.
6. Review the fields to include in your data stream, and deselect the fields that you don’t want.
7. To add a formula field, click **New Formula Fields**.
1. Add a display name for the Field Label. Refer to the list of reserved field names below. Don't use any of the names from this list in your formula fields.
2. If desired, update the Field API name.
3. Enter the Formula Return Type, which is the field’s data type.
4. Define a formula using the search function, attributes, and transformation formula options.
5. Click **Save**.
8. Review the data stream and click **Next**.
9. Click **Deploy**.
Allow at least 24 hours for the data to ingest.
When you establish a connection between B2C Commerce and Data 360, the B2C Commerce Connector ingests 30 days of historical data. For example, if you establish a connection on May 1, the connector ingests historical data from April 2 to May 1. From that date forward, the connector continues to ingest data.

Note For customers who have opted out of tracking using the B2C Commerce standard do-not-track (DNT) cookie, the B2C Commerce Connector prevents data ingestion. If a customer opts in to data tracking, and later opts out, new data isn’t ingested into Data 360, but previously ingested data remains. Customers can use the Data 360 data deletion feature to remove user data.
**Reserved Field Names**: The following standard field names are reserved and can’t be used as B2C Commerce custom attributes when imported into Data 360. If custom attributes using reserved field names are encountered, this may cause inaccurate data to be ingested into Data 360, and require transforming the data for that field by, for example, creating a formula field.
- version
- productId
- tenantId
- masterProductId
- simpleProduct
- optionProduct
- mastered
- bundledProduct
- name
- shortDescription
- longDescription
- minOrderQuantityValue
- minOrderQuantityUnit
- stepQuantityValue
- stepQuantityUnit
- unit
- unitQuantityValue
- unitQuantityUnit
- unitMeasure
- taxClassID
- sku
- manufacturerName
- manufacturerSKU
- brand
- upc
- ean
- validFrom
- validTo
- createdDate
- modifiedDate
Rights of ALBERT EINSTEIN are used with permission of The Hebrew University of Jerusalem. Represented exclusively by Greenlight.
#### See Also
- [_Salesforce Help_: Salesforce B2B Commerce and D2C Commerce](https://help.salesforce.com/s/articleView?id=commerce.comm_intro.htm&language=en_US)
- [_Salesforce Help_: B2C Commerce Order Bundle Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_order_bundle_data_mappings.htm&release=264.0.0&type=5 "The B2C Commerce Order Bundle shows a sample of the key mappings organized by source objects. You can view all the mappings by reviewing your data streams after the bundle is deployed.")
# Create a Batch Data Transform
Create a batch data transform with data lake objects or data model objects by using the in-app builder.
### Required Editions
User Permission Sets
Needed
To create batch data transforms
Permission set:
1. In Data Cloud, on the Data Transforms tab, click **New**.
If the Data Transforms tab isn’t visible, click **More** and select **Data Transforms**.
2. Select **Batch Data Transform**, and then click **Next**.
3. Select the data source.
If you selected data model objects as the source, select a data space from the dropdown menu. The data transform output applies only to the specified data space.

Note A data transform that runs on data model objects is restricted to a data space. You can't associate a data transform that runs on data lake objects with a data space.
4. Select the initial input data for the batch data transform.
1. Click **Add Input Data**, and select the objects that you want to add.
2. Under Selected Columns, choose which of the object’s columns to include in your input data, or select **Name** to select all columns.
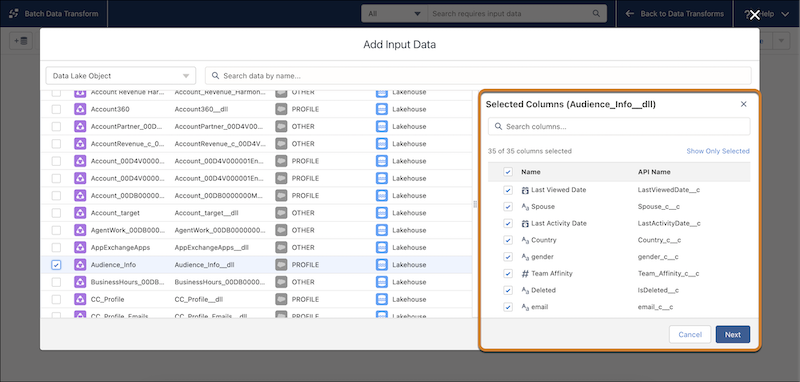
If you added multiple source objects, select each object one at a time and then choose its columns. Selected Columns shows only the columns for the selected object.
3. Click **Next**.
An input node for each input data selection is added to the canvas.
1. To set a currency for the transform, click settings and select **Set Currency**.
5. Add a node to the batch data transform by clicking the Add Node button () between two nodes or at the end of the batch data transform. Then, select the node type.
To show the Add Node button between two nodes, hover the cursor on the connecting line.
6. Preview the results of each node and transformation that you added by selecting the node or transformation in the canvas.
To edit or delete a node, select the node, click , and then select the appropriate action. To edit or delete a transformation in a Transform node, select the Transform node, select the transformation step, and then click  or .
7. To connect, join, or append nodes in the canvas, drag the Add Node button () next to a node or Branch button () on top of another node in the canvas. Select one of the Connect Nodes options.

8. End the data transform with one or more output nodes.
9. Select either **Replace** or **Upsert** for the output Write Mode.
Upsert loads all input data in every run, merging it into the output. Replace attempts incremental transforms, loading only changes from previous runs into the output. For more information, see [Write the Batch Data Transform Results to a Data Lake Object Output Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_output_node_dlo.htm&release=264.0.0&type=5 "To use your batch data transform as input to identity resolution, calculated insights, or segmentation, you write the results to a new or existing data lake object (DLO) in an output node. The object that holds the output is called a target data lake object. You can’t save a batch data transform without an output node.").
10. Select the object to write the results to.
- If your data source is a data lake object, select the object to write the results to, and then click **Apply**.
- If your data source is a data model object, select the object to write the results to or create a new object.
11. From the Batch Transform canvas, click **Save**.
12. Enter a descriptive name that indicates the specific manipulation or operation being performed on the data. A definition name is auto-populated in the Definition Name field. One transform can be associated with up to five transform definitions and are combined into a single composite transform. Each definition distinguishes the particular manipulation that definition applies to the transform.
13. Click **Save.**
#### See Also
- [_Salesforce Help_: Data Spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces.htm&release=264.0.0&type=5 "A data space is a logical partition to organize your data for profile unification, insights, and marketing in Data 360. You can segregate your data, metadata, and processes into categories, such as brand, region, or department, and then enable users to see and work on data only in the context of their category. You can also merge and analyze data in data spaces.")
# Create a Batch DMO Activation in Data 360
Create a batch DMO activation to export an entire data model object (DMO). You can configure your activation to filter records, add additional attributes, and rank the audience before you publish.
### Required Editions
User Permissions
Needed
To create an activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
## Create an Activation
1. From the Activations tab, click **New** and select the **Data Model Object (DMO)** activation type.
2. Select **Batch**.
3. Select the data space.
4. Select the DMO that you want to activate.
5. Select an activation target.
6. (Optional) Select your contact points. The order of attributes in the activation doesn’t match the order in the CSV file output.
7. When you map contact points, select an existing path or click **Edit** to add, reorder, or delete sources and change source types and priority for each contact point.
8. Click **Next**.
9. To control what records activate, in Activation Membership, click **Add Filters**.
1. Drag attributes from a DMO to create a filter for the activation membership. For filters using related attributes, you can access a DMO up to two relationships from your activation membership, limited to a single path.
- You can add currency attributes to your activation payload. The Record Currency field isn’t automatically included in the payload, but you can add it if necessary.
- You can use currency attributes to sort related attributes. The currency conversion is implicitly performed, and the data is sorted accordingly.
Note: For an engagement DMO, activation applies a default 90-day lookback filter. Activation considers engagement data within this window, and any records outside of this window aren't included in the activation output.
2. Click **Save**.
10. In Contact Points, click **Edit Filters**.
1. Drag attributes to create a filter for the contact point. Attributes are only available from the selected contact point DMO and consent DMOs. To manage consent, select attributes from the Contact Point Consent (L3) and Contact Point Subscription Consent (L4) DMO.
2. Click **Save**.
Under Contact Point, the value is 1 for **Max. # of Attribute Values** because only one value is sent for each contact point channel.
3. For Sort By, select an attribute and an operator to organize your data.
4. Click **Continue**.
## Configure Activation Attributes
1. To activate more attributes, click **Add Attributes**.
2. Drag up to 100 additional attributes to the canvas. If you select different columns with similar information, all the unique combinations are added to the output.
- Direct Attribute—Attributes of the Activation Membership DMO.
- Related Attribute—Attributes from any object in the DMO if a path to that object from the Activated On object exists and all the relationships along that path are either 1:1 or N:1.
- Calculated Insights—Add your Calculated Insights metrics to the activation, and apply dimension filters for more granular insights.
3. To provide a unique attribute name in the output file, click the **Edit** icon.
When you activate additional attributes, primary or foreign key fields aren’t available as an option because they aren’t exposed for activation. To see primary or foreign key fields during activation, create a formula field that copies those fields. The formula field is included as an additional attribute for activation. In the lakehouse, number data type fields are stored as decimals, not integers. Therefore in activation, the fields appear as decimals, except for primary keys.
4. Save your changes.
5. (Optional) For SFTP, Google Cloud Storage, and Microsoft Azure activation targets, you can remove the default attribute that's included automatically based on the Activation Membership object chosen during activation creation. However, if you remove the primary key attribute of the activated entity, it’s added back to the activation output automatically.
## (Optional) Refine the Audience
1. To include campaign-specific data, expand Campaign Data, and click **Add Campaign Attribute**.
You can include up to 20 standard attributes (Activation Name, Activation ID, Segment Name, Segment ID, Activation Run ID, and Activation Publish Start Time) and custom attributes. Each campaign attribute forms a new column in activation output.
1. You can modify or remove campaign attributes when editing an activation. To remove all campaign attributes, choose the **Delete All** option from the **Add Campaign Attribute** dropdown menu.
You can also manage campaign-specific data through the [Activation Connect APIs](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=Summary).
2. To use the same audience for multiple fixed-size campaigns across different channels with varying budgets, expand **Provisional Audience Limiting**, then click Rank Attributes.
1. Drag up to three attributes to the canvas in your preferred hierarchy for ranking and move them up or down to rearrange.
2. Select the sorting order (ascending or descending) for each attribute and the attribute path, then click **Save**.
3. To remove an attribute, select the dropdown menu, then click **Remove Attribute**
To rank attributes, you can include direct attributes and calculated insights.
3. To limit the audience for this activation, enter a number from 1 through 10,000. The audience is selected randomly. If you ranked attributes, the audience is prioritized based on the ranking. To extend the audience limit to a maximum of 1 million, contact Salesforce Customer Support.
4. Click **Next**.
## Save the Activation
1. Enter a name and description for your activation.
- Key qualifier attributes are added to activations automatically
- Your description can have up to 200 characters

Important Don’t include these characters in the name: + ! @ # $ % ^ \* ( ) = { } \[ \] \\ . < > / " : ? | , \_ &
2. Choose a refresh type for the DMO publish.
A full refresh publishes all records in the DMO. An incremental refresh publishes only the added, updated, and deleted records since the last successful refresh. You can exclude modified or deleted records from the payload if they’re not needed.
3. Click **Save**.
4. Click **Publish Now** to trigger the activation.
When you activate to file storage targets like Amazon S3, SFTP, GCS, or Azure,
- The order of attributes or columns in the activated file can change. Use the column headers to identify and match the corresponding column data at the destination.
- The Update Action field in the activation file in your file storage target corresponds to the Delta Type field in the [Audience DMO Schema Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_audience_dmo_schema_attributes.htm&language=en_US&type=5).
- A metadata JSON file is added to the same directory as your activated data files.
- For S3 (Legacy) and Amazon S3 targets, this metadata JSON file serves as a confirmation that the write operation to your destination is complete and the data is ready for consumption.
- For SFTP, GCS, and Azure targets, the metadata file and the activated data files may arrive in any sequence. Hence, the presence of the metadata file doesn’t indicate that activation is complete. To check if the activation is complete, use the [Get activation history](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&type=5&language=en_US) connect API, or view the publish status in the Activation History section on the [activation record home](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&type=5&language=en_US).
- The metadata JSON file includes:
- Activation ID and name
- Data space ID and name
- Activated record count
- Refresh ID and publish type
- Attribute names and their corresponding data types
If you use this batch DMO activation to create an activation-triggered flow, after the activation completes, the flow starts automatically and sends the activated data to the API-based destination configured in the flow. For more information, see [Create an Activation-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_activation_triggered_flow.htm&language=en_US).
To view linked activation-triggered flows for the activation, open the activation record and check the **Associated Flows** section. This section shows only activation-triggered flows that you have permission to view. The section is hidden if there are no linked activation-triggered flows or if you don’t have access to any linked flows.
#### See Also
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
# Create a Calculated Insight from a Package
Create a calculated insight from an installed Salesforce package in Data 360.
### Required Editions
User Permission Sets
Needed
To create calculated insights:
Permission set:
1. In Data Cloud, go to the Calculated Insights tab, and click **New**.
2. From the Data Space dropdown, select a data space.
You can use only the data spaces that you have access to. Only the objects that are included in the data space are available to create a calculated insight.
3. Click **From a Package**, and then click **Next**.
4. Choose an installed package, and then click **Next**.
The Calculated Insight Name, Calculated Insight API Name, and SQL Query fields are auto-filled.
5. Click **Save and Run**.
You can view your insight on the record home page. After it’s created, you can’t edit the calculated insight. However, if it has no dependencies, you can delete it from the package.
#### See Also
- [_Salesforce Help_: Packaging in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_packaging_in_customer_360_audiences.htm&release=264.0.0&type=5 "A package can contain small individual components or a large set of related apps. You create a data kit with the packageable features and add the data kit to a package. You can distribute this package to other Salesforce users and orgs, including people outside your company.")
- [_Salesforce Help_: Create and Install Your Package](https://help.salesforce.com/s/articleView?id=data.c360_a_create_install_package.htm&release=264.0.0&type=5 "Use a managed package to build a Data 360 app and distribute it on AgentExchange. Packaging is the container that you fill with metadata, and it holds the set of related features, customizations, and schema that make up your app. A package can include many different metadata components, and you can package a single component, an app, or library.")
# Create a Calculated Insight to Select the MobilePush SubscriberKey
Data 360 has numerous controls to select and activate a channel contact point. However, for some scenarios, you must create a Calculated Insight to filter or select a specific channel contact point. For example, Data 360 doesn’t support activating the Email, SMS, and MobilePush channels together.

Note If your Omni-Channel journey includes Email and SMS but not MobilePush, you can skip this step.
The Calculated Insight output includes the attribute MobilePush Key, which you can add as a direct attribute when you activate the Unified Individual. This action ensures that the activated data extension in Marketing Cloud Engagement has the contact point values for the Email, SMS, and MobilePush channels. Journey Builder can use these contact points to orchestrate Omni-Channel journeys.

Note Marketing Cloud Engagement requires a [SubscriberKey to execute MobilePush sends](https://help.salesforce.com/s/articleView?id=mktg.mc_mp_who_receives_your_message.htm&type=5&language=en_US).
Using this SQL, Cumulus creates a Calculated Insight that searches all of a Unified Individual’s MobilePush SubscriberKeys and selects the SubscriberKey with the most recent app engagement.
`select rk.ssot__Id__c as UnifiedIndividual_Id__c,rk.ssot__PartyId__c as MobilePush_SubscriberKey__c,count(*) as NUMRECORDS FROM ( select UnifiedIndividual__dlm.ssot__Id__c as ssot__Id__c ,ssot__ContactPointApp__dlm.ssot__PartyId__c as ssot__PartyId__c, rank() over (PARTITION by ssot__ContactPointApp__dlm.ssot__PartyId__c order by ssot__DeviceApplicationEngagement__dlm.ssot__EngagementDateTm__c desc) as rank__c FROM UnifiedIndividual__dlm INNER JOIN IndividualIdentityLink__dlm ON UnifiedIndividual__dlm.ssot__Id__c = IndividualIdentityLink__dlm.UnifiedRecordId__c LEFT JOIN ssot__ContactPointApp__dlm ON ssot__ContactPointApp__dlm.ssot__PartyId__c = IndividualIdentityLink__dlm.SourceRecordId__c LEFT JOIN ssot__DeviceApplicationEngagement__dlm ON ssot__DeviceApplicationEngagement__dlm.ssot__IndividualId__c = IndividualIdentityLink__dlm.SourceRecordId__c WHERE IndividualIdentityLink__dlm.ssot__DataSourceId__c = 'YOUR_SFDATASOURCE' ) rk where rk.rank__c = 1 group by rk.ssot__Id__c, rk.ssot__PartyId__c`
# Create a Calculated Insight Using Builder
Create a calculated insight without using SQL by using the builder tool in Data 360.
### Required Editions
User Permission Sets
Needed
To create calculated insights:
Permission set:
1. In Data Cloud, go to the Calculated Insights tab, and click **New**.
2. From the Data Space dropdown, select a data space.
You can use only the data spaces that you have access to. Only the objects that are included in the data space are available to create a calculated insight.
3. Click **Calculated Insight**.
4. Click **Use Visual Builder** and click **Next**.
5. If your Insight includes currency fields, select the **Insight Currency** value at the top of the page.
6. Click **Select an Object**, select the object, and then click **Next**.
7. Add the nodes by clicking **+** next to the object.
You must select at least one aggregate node.
8. Add measures and dimensions to your insight by clicking **Aggregate**.
You must select at least one measure.
1. Under Measures, click **+**.
2. Select a metric function and the field that you want to calculate, and then click **Next**.
3. Enter the metric name, and click **Apply**.
4. Under Dimensions, click **+**.
5. Select the field that you want to group by, and click **Next**.
6. Enter the dimension name, and click **Apply**.
9. To save the aggregate node, click **Apply**.
10. (Optional) Add or modify data using a join, case, filter, transform, or arithmetic expression in your insight. See [Working with Nodes in Visual Insight Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_working_with_nodes_in_builder.htm&release=264.0.0&type=5 "Visual Insight Builder uses a low-code, drag-and-drop interface to simplify the creation of streaming, calculated, and real-time insights. Visual components replace complex code, allowing you to develop metrics and expressions, regardless of technical expertise.").
11. Click **Save and Run**.
12. Enter the calculated insight name, and click **Next**.
The Calculated Insight API Name field is auto-filled.
13. From the Schedule dropdown, select a schedule.
14. Select the start date and time of the schedule.
15. Click **Enable**.
You can now view your insight on the record home page.
# Create a Calculated Insight Using SQL
Write SQL expressions to create your metrics and dimensions from mapped objects and fields. You can create a calculated insight in Data 360 using SQL.
### Required Editions
User Permission Sets
Needed
To create calculated insights:
Permission set:
DMO names are case-sensitive for calculated insights. When creating a calculated insight with SQL, verify that the DMO references match the casing found in the API name. This can be confirmed by reviewing the Object API Name column on the Data Model tab.
1. In Data Cloud, go to the Calculated Insights tab, and click **New**.
2. From the Data Space dropdown, select a data space.
You can use only the data spaces that you have access to. Only the objects that are included in the data space are available to create a calculated insight.
3. Click **Calculated Insight**.
4. Click **Use SQL Authoring** and click **Next**.
5. Enter the calculated insight name.
The Calculated Insight API Name field is auto-filled.
6. Enter the new insight SQL query expression.
The SQL statement character limit is 131,021.
1. When your insight includes currency measures, you must use the `TRY_CONVERT_CURRENCY` function.
1. Use the NOW function to define a relative time window and the SECOND\_ADD and SECOND\_ADD functions to create more granular time period logic. See [SQL Functions for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_aggregates.htm&release=264.0.0&type=5 "Use these aggregate, datetime, analytical, formatting, math and statistical, and boolean functions when you author calculated insights in Data 360. The Aggregatable column indicates whether a function's output can be rolled up across fewer dimensions when queried in segments or activations.").
7. To check whether your SQL expression is valid, click **Check Syntax**.
If it isn’t valid, you can’t continue.
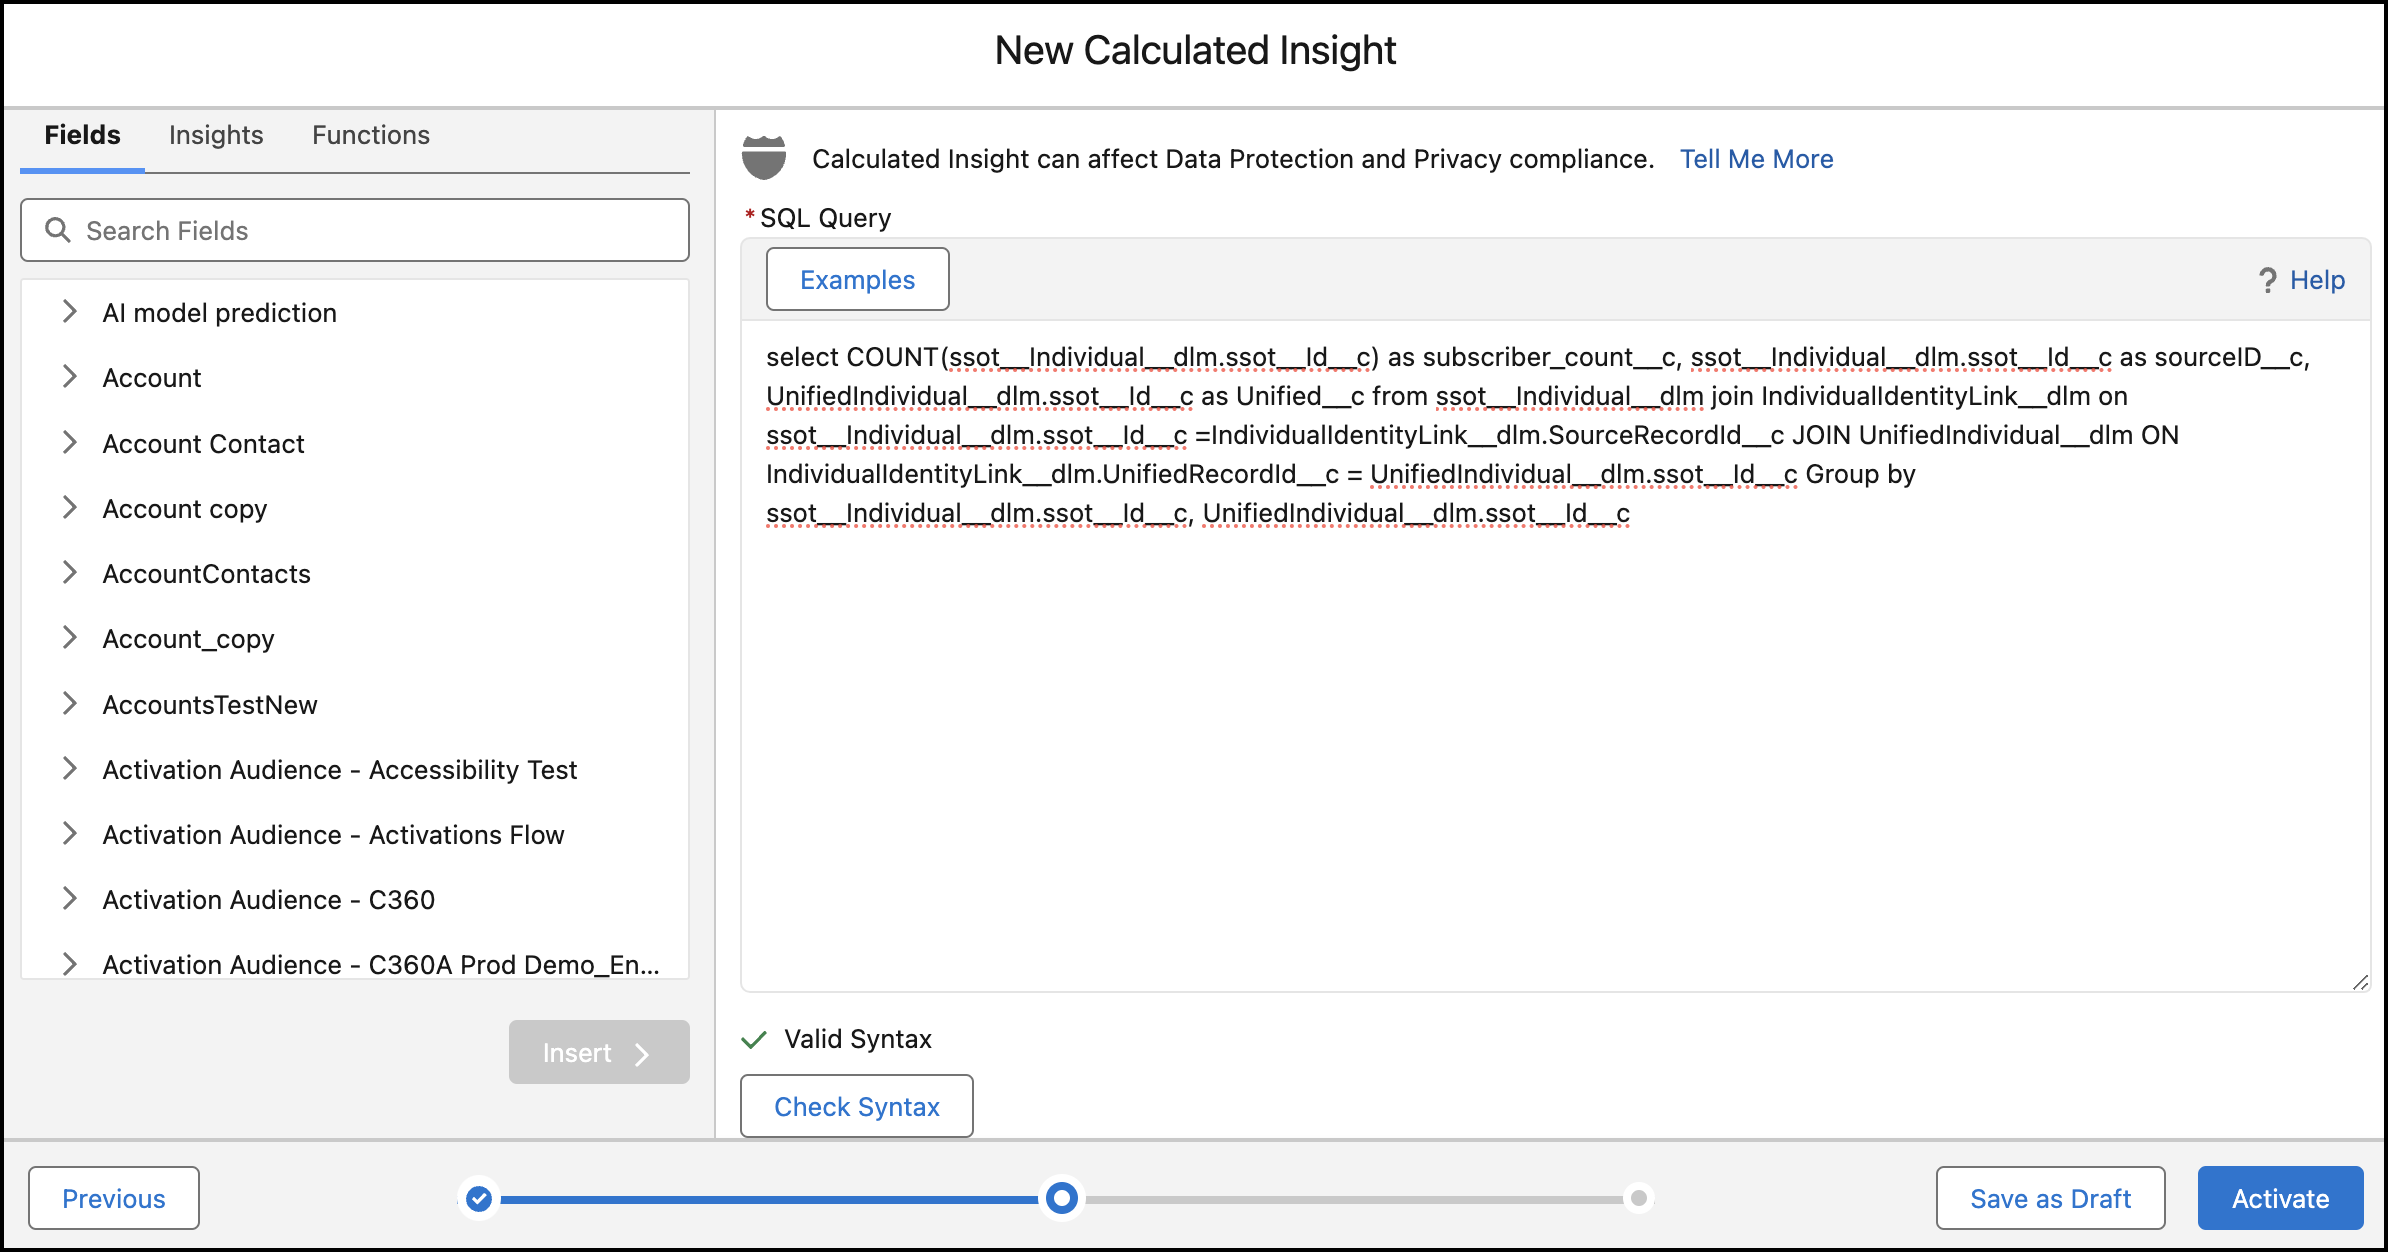
8. Click **Activate**.
9. From the Schedule dropdown, select a schedule.
10. Select the start date and time of the schedule.
11. Click **Enable**.
The calculated insight appears on the record home page.
#### See Also
- [_Trailhead_: Data 360 Insights Using SQL](https://trailhead.salesforce.com/content/learn/modules/customer-data-platform-insights-using-sql?trail_id=enhance-data-in-customer-data-platform)
# Create a Classification in Data 360
In Data 360, define sensitivity or usage levels to categorize data and drive governance policies such as masking and access control.
### Required Editions
| User permission needed | |
| --- | --- |
| To create a classification: | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Classifications**.
3. Click **New** and select the source taxonomy.
4. If you’re creating a child classification, select its parent classification.
5. Enter a unique classification name and an optional description.
The classification API name is auto-filled based on the classification name, but you can change it.
6. Click **Next**.
7. (Optional) Attach tags to your classification. You can also attach tags at a later time.
Tags are hierarchical. If you attach a parent tag, all its child tags are included.
8. Save your classification.
# Create a Clean Room Collaboration and Invite a Provider
To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.
### Required Editions
Available in: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
User Permissions Needed
To create a collaboration:
Permission set:
1. In Data 360, go to the Clean Rooms tab.
2. Under Collaborations, click **New**
3. Select the data space where you want to create the collaboration.
4. Select the provider and the use case that you want to collaborate on.
5. If you received a key from the provider, enter it in the Provider Verification Key field.
6. Choose how to map your data, and click **Next**.
You can’t edit an existing template, so if you don’t have a mapping that fits the requirements, create one.
7. Select the mapped template that you want to use or map your data.
1. Select your role for the use case that you’re mapping data for.
2. Select the collaboration query.
3. Select a data space and the data model object.
8. Click **Next**.
9. Name the collaboration and add an optional description.
The name and description appear on your and the provider’s list of collaborations. Use a unique and descriptive name to identify the collaboration easily.
10. Click **Save** to send the provider an invitation to the collaboration.
When you create the collaboration, Data 360 adds the `Clean_Room_Audit_Log` DMO to your data space. The DMO stores the details about the queries run on your data.

Note If your provider uses AWS Clean Rooms instead of Data 360, the provider accepts this invitation in AWS Clean Rooms, not in Data 360. You manage the collaboration and run queries in Data 360 against the aggregated data. See [Collaboration with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5 "As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.").
# Create a Clean Room Package
Providers can offer clean room packages that contain collaboration templates on AppExchange. Consumers interested in collaborating on your data can download the clean room package and initiate a collaboration.
### Required Editions
Available in: Developer Edition
User Permissions Needed
To create a clean room package:
Data Cloud Architect permission set
Before you begin:
- Sign up for a Salesforce Developer Edition org at developer.salesforce.com.
- Enable Data 360 on this Developer Edition org through the appropriate setup flow.
- Go to **Setup** | **Package Manager** and register a namespace prefix for your Developer Edition org or package.
1. Get the information to identify your data share target.
1. In Data Cloud, on the Data Share Targets tab, click **New**.
You’re not actually creating a data share target at this point. You’re gathering information to create the package.
2. Select **Salesforce Data Cloud** and click **Next**.
3. From the New Data Share Target window, note your Org ID, Offcore Tenant ID, and the Domain URL.
4. You can now close this window.
2. In Data Cloud Setup, in the Quick Find box, enter Clean Room Collaboration and select **Clean Room Packages**.
3. Click **New**.
4. Select the package type.
1. Select **Data Collaboration Package** for use cases such as segment overlap and activation, where both parties analyze joined datasets to derive insights while keeping raw data private.
2. Select **Identity Boost Package** for identity boost use cases where the provider enriches a consumer’s dataset with additional contact attributes to improve activation match rates. Use a custom collaboration template for identity boost packages.
5. In the Create a Clean Room Package window, enter the package details.
1. Enter a descriptive name to identify your package (for example, your company name and use case).
2. Select the Clean Room Platform that you want to use. Data 360 sets the Source Data Platform by default.
3. Enter the name of your company as the Provider Name.
4. Enter the URL for your company logo.
6. Click **Next**.
7. If you selected Salesforce Data Cloud as the Clean Room Platform, enter your organization ID, Offcore Tenant ID, and Domain URL.
1. If you’re creating a Data Collaboration Package, select the collaboration template type.
2. If you chose to use Salesforce-provided collaboration templates, select the use case.
8. If you selected AWS Clean Rooms as the Clean Room Platform, enter your **AWS Account ID**.
9. Select the **Supported Regions** for the clean room package.
10. To use a custom collaboration template, create one using the sample template.
1. Click **Download Customizable Template**.
2. In the sample template, fill in the required values to create your custom collaboration template. A custom collaboration template can have multiple use cases and multiple queries for each use case.
3. Upload the JSON file.
The supported use cases appear.
11. Add an optional description.
12. Click **Create**.
To create another package with similar values, clone the package and make required changes.
Data 360 creates the package, and the supported queries appear along with related details. To make the package publicly available, publish it on AppExchange. See [Publish a Clean Room Package to AppExchange](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_publish_package_to_appexchange.htm&release=264.0.0&type=5 "After creating a clean room package in Data Cloud Setup, use data kits to package it. Then use the package manager to create a managed package and publish it on AppExchange. You can only publish managed packages on AppExchange."). To distribute your clean room package to specific collaborators, create an unmanaged package instead.
# Create a Communication Capping Activation Target
Create a governed target for which segment membership is prioritized and filtered during activation in Data Cloud. You can set a cap for Marketing Cloud Engagement, Microsoft Azure, and SFTP targets.
### Required Editions
Permission Sets Needed
To create activation targets and use Communication
Capping:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. In Data Cloud, click **Activation Targets**, and then click **New**.
2. Select the activation platform, and click **Next**.
3. Select **Communication Capping Activation Target,** and click **Next**.
4. Enter a name for the activation target, and an optional description.
5. Select a data space.
The communication capping activation targets can be defined only on data spaces already associated with the communication capping instance.
6. For SFTP or Microsoft Azure, select the connector.
7. Click **Next**.
8. Enter the target details, and then click **Save**.
The communication capping activation targets are retrieved through metadata association and displayed in the Target Mapping tab on the Communication Capping page.
After creating the communication capping activation target, map it to parameters.
# Create a Communication Capping Configuration
Create the communication capping configuration and associate it with a data space in Data Cloud. You can apply it to either all configured parameters or a specific subset. Each organization is limited to one active communication capping configuration.
### Required Editions
Permission Sets Needed
To use Communication Capping:
One of these permission sets:
1. In Data Cloud, click **Communication Capping**, and then click **New**.
2. Select the parameters for which you want to create the capping rules.
3. Select one or more data spaces to which the communication capping instance has been applied.
4. Enter a name and an optional description for the communication capping.
5. Click **Save**.
After creating communication capping configuration, create the capping rules.
# Create a Container for Segmentation
When a filter is defined using a related attribute, a container is created on the canvas with options to define the rules that you need. You can include up to 20 filters within a container.
### Required Editions
Permission Sets Needed
To create a container:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
If you’re using hierarchical aggregation, map the Account ID and Parent Account fields on the Data Model tab. See [Map Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&release=264.0.0&type=5 "Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.").
1. On the Segments tab, locate the segment that you want to create a container for.
2. From the dropdown menu, click **Edit Rules**.
3. To add a container to the segmentation canvas, drag a related attribute from the library.
4. In the container, add attributes, select the type of aggregation, and define filters.
5. If the container has more than one access path to the segmentation entity, select a container path.
6. To edit or delete a filter, use the icons in the container header.
7. To define segment filters based on aggregate values across multiple levels, select **Hierarchical Aggregation**.
You can use hierarchical aggregation with segments that are based on Account and Unified Account. You can create up to five containers, and each DMO can have up to three hierarchical levels. If you exceed this limit, an error message appears when you attempt to save the segment filter definition.
8. To use a batch segment output in a real-time segment:
1. Under Related Attributes, find your segment membership DMO, which ends with Latest. For example, Individual Latest.
1. Create a rule where Segment Id equals the name of the batch segment ID you want to use as output.
9. Save your changes, and recount your population.
To manually update the population count, click the **Recount** icon. Below each container, a ribbon shows the population for that container. Refresh to run or update the count.

Note Container population count uses the same approximate count option as segment count when that feature is enabled.
10. To finalize the segment, click **Done**.
- **[View Filter and Container Level Counts](https://help.salesforce.com/s/articleView?id=data.c360_a_view_filter_count.htm&release=264.0.0&type=5)**
Use the population counts displayed in the ribbon under each filter or container to evaluate their impact on your segment. Filter-level counts apply to direct attributes; container-level counts apply to related attributes (containers). Counts are available on both the Include and Exclude tabs.
#### See Also
- [_Salesforce Help_: Container Path](https://help.salesforce.com/s/articleView?id=data.c360_a_container_path.htm&release=264.0.0&type=5 "Some containers have multiple paths back to the segmentation entity. When a container has multiple access paths, you can select a path to help Data 360 understand how to build your segment. The paths available when you first create a filter may differ from those available when you edit it later. This is expected behavior driven by relationship-cardinality rules.")
# Create a Copy Field Enrichment
Add information from Data 360 data model objects (DMO) to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.
### Required Editions
Available in: Enterprise , Performance , Unlimited , and Developer Editions
User Permissions
Needed
To view enrichments in Setup:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
Set the Data Cloud permission set, such as Data Aware Specialist, feature
permission to allow data space access.
To create or update enrichments:
Customize Application AND Data Cloud User AND Write Access to Data Action AND
Write Access to Data Space Definition
If you enabled enhanced security data spaces, you also need the permission
Customize Data Actions on the Dataspace Scope.
Object Permissions
Needed
To view enrichments in Setup:
Data Action Definition object Read permission
To create or update enrichments:
Data Action object Create, Update AND Data Action Definition object Create,
Update, and Delete
Before you begin this task, read [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org."). Then perform the steps in [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.").
1. From Setup, select **Integrations**, **Enrichments**, and then **Copy Fields**.
You can also create copy field enrichments from Object Manager.
2. Click **New**.
3. Under Source Object, select a data space.
You must have at least one unified object in the data space to copy fields for any object associated with the unified object. Different data spaces have different views of the data available. For example, a data space can have a view for a specific brand or different data spaces for reporting vs. customer-facing data.
4. Select a **Data Cloud Object**.
More information on which objects are supported is available in the [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.") topic.
You can only create one enrichment for each Data Cloud source object and CRM target object combination. If one exists, click **Open Existing Enrichment**. You can edit the enrichment and add or remove fields to copy.
5. Select the ID Matching Method that determines what data to copy into your org.
There are several different matching methods available, including Individual Lookup, Account Lookup, Unified Individual Lookup, Unified Account Lookup, Primary Key, and Non-Primary Unique Key. If you created a lookup relationship in Data 360 to your source CRM object, you can select the appropriate lookup matching method. By default, the primary key of the CRM object is matched to the primary key of the Data 360 object. Usually, the primary key is the best data to match records. However, for ML Prediction DMOs, any unique key can be used, in which case you should select non-primary unique key as the matching method. Enforce a database constraint on the unique key column to guarantee unique values, and index the column for optimal performance.

Note If you select Primary Key ID matching, the enrichment doesn’t filter the target objects by the data source ID. If the source object is a DMO, the Key Qualifier is used to filter the target object. If the source object is a CIO, there’s no filtering.
You want to see the nickname “Nick Anderson” entered for your loyalty program on his contact page. The nickname is captured in a CustomerLoyaltyProgram custom DMO. The primary key for that object is a program ID, which doesn’t match the primary key of the CRM object that you want to match. However, there’s also a CRM ID field in CustomerLoyaltyProgram that has data that matches the Customer ID for your CRM object. You create a Data Cloud lookup to CRM ID for Unified Individual and select **Use the Unified Individual Lookup** as the matching ID method.
6. Under Target Object, select a **Target Object**, and click **Next**. This is the object in your org that you’re copying data into.
7. Select the fields that you want to copy by clicking the plus sign, and click **Save**.
8. For each Data Cloud object field, search for a Salesforce org field that you want to copy data into and select it.
9. To ensure that only relevant data is copied, define a filter. With a filter, only data from source objects that match your filter criteria is copied.
Reducing the amount of copied data can conserve credits.
1. Select the conditions to be met.
2. Select the source object fields to filter on.
3. Select the operator and the value.
For example, to copy data only from accounts with more than 1,000 employees or from aerospace accounts, create a filter with these conditions.
- Any Condition Is Met (OR)
- Employee Cloud Greater Than 1,000
- Account Type Equals Aerospace
10. Enter an enrichment label that you can use to identify the enrichment.
11. Enter an API name that uniquely identifies the enrichment.
By default, the API name is generated as SourceObject\_TargetObject\_DataSpace
12. Save your enrichment.
- If you’re using the CRM connector to ingest your data, click **Save and Start Sync**.
- In the rare case that you’re using a data stream other than the CRM connector to ingest your data, specify the key qualifier for the data stream and click **Save and Start Sync**.

Note If you get an error message saying that incorrect permissions are detected, follow [Step 3: Configure Integration User Field Permissions for Copy Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "You must have fields in your org to copy data into. If you don’t want to overwrite existing data or you don’t have an existing field, you must create a field. Before starting this task, make sure that you created all the fields that you want to copy into. A Salesforce admin for your org must set integration permissions for all fields. This task takes about 5 minutes, unless you have a large number of fields that you want to copy.") to add the correct permissions.
The first sync is a full data sync that takes hours or days, depending on the number of records to copy. If you have existing data in the field you’re copying to, this data is overwritten as part of the sync and can’t be recovered.
13. [Monitor the full sync bulk job](https://help.salesforce.com/s/articleView?id=xcloud.monitoring_async_api_jobs.htm&type=5&language=en_US) or use the Sync History tab to examine sync logs.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
#### See Also
- [_Salesforce Help_: Enrichment Troubleshooting](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_troubleshooting.htm&release=264.0.0&type=5 "Diagnose issues with enrichments and fix them.")
- [_Salesforce Help_: Syncing Copy Field Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_syncing_copy_field_enrichments.htm&type=5&language=en_US)
- [_Salesforce Help_: Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_syncing_copy_field_enrichments.htm&release=264.0.0&type=5 "Learn how data is copied and synced between Data 360 and your org for copy field enrichments. Get tips for troubleshooting data syncing and changing enrichments.")
- [_Salesforce Help_: Copy Field Enrichment Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_copy_field_enrichment_matching.htm&release=264.0.0&type=5 "Copy Field enrichments enhance the records in your org by adding data from other data sources. To avoid returning data that isn’t relevant to the records in your org, the enrichment matches data from your org to data in Data Cloud. How the data is matched determines what data is returned.")
# Create a CRM Data Stream from Financial Services Cloud (FSC) Objects
Add the permissions and license requirements in your Salesforce CRM org to ingest FSC objects.
### Required Editions
User Permissions
Needed
To set permissions:
System admin profile OR
Data Cloud Architect permission set
Be aware of the FSC Data Model you’re using and want to ingest into Data 360. In Financial Services Cloud terms, these are called sectors: Commercial Banking, Insurance, Mortgage, Retail Banking, and Wealth Management.
1. Log in to the Salesforce org containing the objects and fields that you want to ingest into Data 360.
2. Set object permissions.
1. From Setup, in the Quick Find box, enter Permission, and then select **Permission Sets**.
2. Select the **Data Cloud Salesforce Connector** permission set.
3. From Apps, select **Object Settings**.
4. Enable Read and View All Records permissions for the FCS objects.
3. Enable the FCS license.
1. From Setup, in the Quick Find box, enter Company Information.
2. Select **Permission Set Licenses** and click **Go to list**.
3. Select the associated license for the Financial Cloud Extension or Financial Services Cloud Foundations and click **Enable for Integrations**.
Make sure that the user connecting to Salesforce CRM has Financial Services Cloud permissions.
4. Enable Interaction Summary.
1. From Setup, in the Quick Find box, enter Feature Settings.
2. Select **Financial Services Guided Setup**, then select **Interaction Summary Settings.**
3. Enable **Interaction Summary**.
5. Set Permission for the user.
1. From Setup, in the Quick Find box, enter User.
2. Select the current active user and click **Permission Set Assignments**.
3. Click **Edit Assignments** and enable **ManageSalesforceCDPConnections**.
6. Enable Know Your Customer.
1. From Setup, in the Quick Find box, enter Feature Settings.
2. Select **Financial Services** and click **General Settings**.
3. Enable **Know Your customer.**
7. Enable System Permissions.
1. From Setup, in the Quick Find box, enter Users then select **Permission Sets**.
2. Select the **Data Cloud Salesforce Connector** permission set.
3. From System, select **System Permissions**.
4. Enable the following permissions.
\- Grants access to the Interaction Summary objects and fields
\- User license to access Mortgage in Financial Services Cloud
\- Grants access to objects and fields for risk assessment, identity verification, and screening of accounts, contacts, or leads
\- User license to access the Document Checklist feature
\- Financial Accounts User
8. Enable compliant data sharing for the Interaction and Interaction Summary objects.
1. From Setup, in the Quick Find box, enter Compliant Data Sharing, and then select **Object Enablement Settings**.
2. Enable Interaction.
To share an interaction and to access the Interaction Participant object, make sure that compliant data sharing is enabled for the Interaction object.
3. Enable Interaction Summary.
To share an interaction summary and to access the Interaction Summary Participant object, make sure that compliant data sharing is enabled for the Interaction Summary object.
9. Enable data sharing.
1. From Setup, in the Quick Find box, enter Users then select **Permission Sets**.
2. Select the **Data Cloud Salesforce Connector** permission set.
3. From System, select **System permissions**.
4. Enable **UseCompliantDataSharing**.
- **[Financial Services Cloud Bundle Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_mappings_fsc.htm&release=264.0.0&type=5)**
The Financial Services Cloud data bundle for Data Cloud helps financial services firms increase employee productivity, accelerate time to value, and deepen customer trust with every interaction. These data mappings relate to Financial Services Cloud bundle available for the Salesforce CRM connector. You can add to or customize the data mappings.
# Create a Custom Data Model Object
If a standard data model object doesn’t meet a business need, you can create a custom data model object (DMO) to store information that is unique to your business. You can create a custom data model object from an existing DMO, from a file, or from scratch.
1. On the Data Model tab, click **New**.
2. Select the method of creation, in this case, select **New**.
3. Click **Next**.
4. Enter the details for Object Label, Category, and Object Description.
The Object API Name is auto-filled. The Data Source, Data Source Object, and Internal Organization fields are also added.
The Object API Name must be unique across standard and custom DMOs, excluding the ssot\_\_ prefix.
5. To add a field, click **Add Field**.
1. Enter the details for Field Label, Field API Name, and Data Type.
2. Select a primary key field.
3. Optionally, enable value suggestion for the field.
6. Click **Save**.
You can now use your custom DMO.
#### See Also
- [_Salesforce Help_: Use Value Suggestions in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_suggested_values_in_segments.htm&release=264.0.0&type=5 "You can enable value suggestions for data model object (DMO) fields if the data type is Text. Enable or deactivate the feature in the DMO record home. You can enable value suggestions for up to 500 attributes for your entire org. It can take up to 24 hours for suggested values to appear.")
- [_Salesforce Help_: Data Lineage Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lineage_fields.htm&release=264.0.0&type=5 "Data 360 adds fields to a data object to capture data source details.")
# Create a Custom Data Model Object from a CSV File
Use a custom data model object (DMO) to store information that is unique to your business. You can add a custom DMO by uploading a CSV file.
The CSV file must have four columns in this order. If the CSV file has a header row, the columns can have any name, but the column contents must follow the order.
- Field Label
- Field API Name
- Data Type
- Primary Key
1. On the Data Model tab, click **New**.
2. Click **From File**.
3. Click **Next**.
4. If the CSV file has a header row, select the header row option so that Data 360 ignores the top row.
5. To upload the CSV file, click **Choose File**.
6. Click **Next**.
7. Enter the object details for Object Label, Category, and Object Description. Object API Name is auto-filled.
8. Review the field attributes uploaded from the CSV file.
9. Click **Save**.
You can now use your custom DMO.

Example
Example File Upload
| Field Label | Field API Name | Data Type | Primary Key |
| --- | --- | --- | --- |
| test-new-field-1 | test\_new\_field\_1 | Text | TRUE |
| test-new-field-2 | test\_new\_field\_3 | Number | FALSE |
| test-new-field-3 | test\_new\_field\_3 | Datetime | FALSE |
#### See Also
- [_Salesforce Help_: Data Lineage Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lineage_fields.htm&release=264.0.0&type=5 "Data 360 adds fields to a data object to capture data source details.")
# Create a Custom Data Model Object from an Existing Data Model Object
Use a custom data model object (DMO) to store information that is unique to your business. You can create a DMO by copying an existing standard or custom DMO.
1. On the Data Model tab, click **New**.
2. Click **From Existing**.
3. Click the tab for the type of DMO that you want to copy, either standard or custom.
4. Select the DMO.
5. To view the DMO’s fields, click the dropdown next to its name.
6. Click **Next**.
7. Enter the details for Object Label, Category, and Object Description. The Object API Name is auto-filled.
The Object API Name must be unique across standard and custom DMOs, excluding the ssot\_\_ prefix.
8. Review the field attributes.
9. Click **Save**.
You can now use your custom DMO.
# Create a Custom Field for a Custom Object in Data Cloud
Add custom fields to your custom objects. You can capture your unique business data by storing it in custom fields. When you create a custom field, you can configure where you want it to appear and optionally control security at the field level.
### Required Editions
1. Click **Setup**.
2. Click **Object Manager** and select your custom object.
3. Click **Fields & Relationships**.
4. Click **New**.
5. Select the field type, then click **Next**.
6. Enter the field label and starting number, and then click **Next**.
7. Select the profiles that can access the custom field, and then click **Next**.
8. Select the Dynamic Forms-enabled Lightning record pages that should include the field, then click **Next**.
If you don’t have any Dynamic Forms-enabled Lightning record pages for the object, this step doesn’t appear.
9. Select the page layouts where you want to add the custom field.
10. Click **Save**.
# Create a Custom Object in Data 360
Create a custom object to integrate data actions with a flow. Custom objects store information that’s specific to your company or industry. It helps you track everything related to your business in one place.
### Required Editions
1. Click **Setup**.
2. On the Object Manager tab, click **Create**, and then click **Custom Object**.
3. Enter the label and plural label.
The Object Name and Record Name fields are auto-filled.
4. Select **Launch New Custom Tab Wizard after saving this custom object**.
5. Click **Save**.
6. On the New Custom Object Tab page, click **Tab Style** and select how you want the icon to look.
7. Click **Next**, and then click **Next** again.
8. Click **Save**.
- **[Create a Custom Field for a Custom Object in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_custom_field_in_custom-object.htm&release=264.0.0&type=5)**
Add custom fields to your custom objects. You can capture your unique business data by storing it in custom fields. When you create a custom field, you can configure where you want it to appear and optionally control security at the field level.
# Create a Custom SQL Retriever
Use a custom SQL retriever to query Data 360 objects using a SQL statement. To build your query, select an object, write a SQL query, specify parameter values, and configure citations. Review and run your query to validate accurate results before you save and activate the retriever.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, test, and
delete)
Allow users to manage models in AI Models
OR
Data Cloud Architect
permission set
To access data with retrievers
For the Knowledge object: read access to the object AND Allow View Knowledge
app permission.
For all other standard objects: read access to the object AND
appropriate sharing rules. For more information see, Set Your Internal Organization-Wide Sharing
Defaults
## Select a Retriever Type and Data Space
1. In AI Models, select **Retrieve**, then **New Retriever**.
2. Select **Custom SQL Retriever** as the retriever type. Click **Next**.
3. Select the data space that contains your data. Click **Next**.
## Define Retriever Search Query
1. In the Query tab, browse the list of objects and select an object.
2. Write a SQL query in the query editor.
3. Alternatively, select **Generate Query** to generate a query based on an existing search index. Configure your retriever options such as the data model object, search index configuration, pre-filters, and number of results to return.
4. Specify the parameter values for the query, such as the main search string and any default values.
The retriever substitutes these values at run time to help with testing and evaluation.
5. Review your SQL query for errors and suggestions.
## Run and Activate a Custom SQL Retriever
1. To test your SQL query, click **Run**.
2. Validate the results from your SQL query.
3. Optionally, configure the number of results to return and citations settings in **Retriever Configuration**.
4. To review retriever details, click **Next**.
Save your Custom SQL Retriever.
5. Activate the retriever.
**Generate Custom SQL Query**
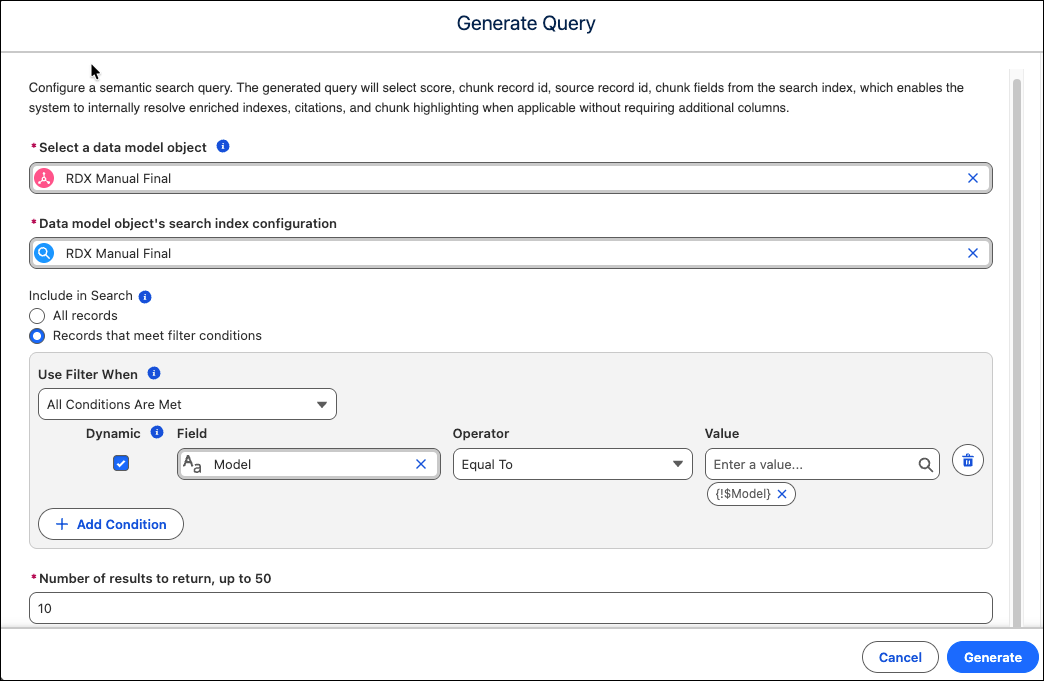
**Custom SQL Retriever Details**
After you activate the custom SQL retriever, use it in Prompt Builder, Flow, and Agents.
#### See Also
- [_Salesforce Help_:Ground with Knowledge Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&language=en_US)
- [_Salesforce Help_: Search for AI, Automation, and Analytics](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&type=5&language=en_US)
# Create a Custom Taxonomy in Data 360
Custom taxonomies allow you to define your own categories and subcategories based on your specific data, use cases, or business needs. You can create tags, group them into a hierarchy, and align them with internal policies or specialized regulatory requirements.
### Required Editions
Create a tag or classification taxonomy from scratch or copy an existing one. When you clone a standard or custom taxonomy, all tags or classifications, along with their hierarchy and associations, are duplicated.
| User permission needed | |
| --- | --- |
| To create a custom taxonomy: | Data Cloud architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Taxonomies**.
3. Click **New** and select the taxonomy type. Or, to clone an existing taxonomy, click the taxonomy dropdown and select **Clone**.
4. Enter a unique name for your taxonomy and an optional description.
The taxonomy API name is auto-filled based on your taxonomy name, but you can change it.
5. Click **Save**.
# Create a Data 360 Activation Target
Create an activation target in Data 360 to publish segments and batch data model objects (DMO) to the Audience DMO. You can access data from segments and DMOs without a direct connection to an internal or external target system by publishing the data to the Audience DMO.
You can then retrieve the data using Query APIs, similar to querying any other DMO. Alternatively you can create an activation-triggered flow to connect to an external API based destination using MuleSoft connectors in Flow or External Services (HTTP Callouts), where the flow reads the activated data from Audience DMO and pushes it to the connectors/APIs configured in activation-triggered flow. For more information, see [Create an Activation-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_activation_triggered_flow.htm&language=en_US&type=5) and to find the supported actions for MuleSoft connectors, see [Third-Party Connectors](https://help.salesforce.com/s/articleView?id=platform.automate_flow_ref_third_party_connectors.htm&language=en_US&type=5).
User Permissions
Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activation Targets tab, click **New**.
2. Select Data 360, and click **Next**.
3. Enter a unique, easily recognizable name.
4. Enter a short description and select a data space.
5. Click **Save**.
Your Data 360 activation target is created.
#### See Also
- [_Salesforce Help_: Audience Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_audience_data_model_object.htm&type=5&language=en_US)
- [_Salesforce Help_: Create a Data Cloud Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_cloud_activation.htm&type=5&language=en_US)
# Create a Data 360 Loyalty Activation Target
To publish segments for use with Loyalty Cloud, create an activation target in Data 360. You can create one activation target for Salesforce.
### Required Editions
User Permissions
Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activation Targets tab, click **New**.
2. Select Data 360 (Loyalty), and click **Next**.
3. Enter a name and an optional description.
1. Select the data space you want to associate your activation target with.
Each data space can have only one Data Cloud Loyalty activation target.
2. Click **Save**.
Your Data 360 Loyalty activation target is created.
When you activate a DMO, the subsequent DMO activations are upserts of modified records and don’t change the unmodified older records.
# Create a Data 360 Object from a Segment
Activations to the Data 360 activation target use segments and attributes to create objects. Each Data 360 org can have one Data 360 activation target, and each activation target can have multiple objects. The same object can be selected for multiple segments.
### Required Editions
User Permissions
Needed
To create an object from a segment:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. Go to the **Activations** tab.
2. Click **New**.
3. Select a segment.
4. Select a Data 360 activation target.
5. Select a data model object (DMO) from Activation Membership, and click **Continue**.
6. To create an object, add a name and API name and then click **Next**.
You can also select an existing object.
7. Review the default attributes (segment ID, segment ID Name, and segment ID Last Processed).
8. To add attributes, click **Add Attributes**.
1. Drag attributes onto the canvas, and click **Save**.
9. Click **Next**.

Important After the activation is created, attributes can’t be changed.
10. Name your activation and click **Save**.
View all Data 360 objects in **Data Model** or **Data Explorer**.

Note Users aren’t removed from a curated DMO, even if they no longer meet the segment filter criteria.
# Create a Data 360 Sandbox
Develop, test, and train on Data 360 without affecting your production org. Data 360 supports all sandbox types—Developer, Developer Pro, Partial Copy, and Full Copy—but provisions only metadata. Even when you create Partial Copy or Full Copy sandboxes, your production data stays protected. No data is replicated to Data 360 sandboxes.
### Required Editions
User Permission Set
Needed
To create a Data 360 sandbox:
Permission set:
This process includes multiple steps in Data 360 and Salesforce Platform. Bookmark () this page or keep it open in a separate window to refer to this topic.
Before you begin, complete these prerequisites.
- Using Data Cloud One? Before creating sandboxes and connecting them with Data Cloud One, make sure that your production orgs don't have companion connections yet. If you create companion connections between your production org and Data 360 home org before creating a sandbox, the metadata in that sandbox has to be cleaned up. This clean-up can take several weeks. Contact Salesforce Customer Support for details. For other Data Cloud One sandbox limitations, see [Using Data Cloud One with a Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_sandboxes.htm&language=en_US).
- Provision Data 360 in your production org.
## Step 1: Create a Data 360 Sandbox
See [Create a Sandbox](https://help.salesforce.com/s/articleView?id=platform.data_sandbox_create.htm&language=en_US).
## Step 2: Enable Data 360 in an Existing Sandbox
Use the license match feature to set up Data 360 in a sandbox created before Data 360 was provisioned in your production org. This feature inherits Data 360 licenses from the production org without you refreshing the sandbox. However, there are a few important considerations to keep in mind:
- Make sure that the production org has Data 360 provisioned for the license match to work.
- The license match process copies only Data 360 licenses. The license match doesn't copy organization preferences, values, metadata, or permissions. You can set up custom configurations, integrations, and other metadata manually in the sandbox.
- Complete Data 360 provisioning in your sandbox first. Confirm that provisioning is active before you activate Agentforce or Einstein features.
1. Enable Data 360 in your production org. See [Turn on Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_provision.htm&type=5&language=en_US).
2. In the sandbox org, go to Setup, enter **Company Information** in the Quick Find box, and then select it.
3. Click **Match Production Licenses**.
Allow up to 24 hours for the license synchronization to complete. If you attempt to access Data Cloud Setup before the license sync completes, the Data Cloud Setup menu is unavailable.
## Step 3: Turn On Data 360 in the Sandbox
1. Log in to your sandbox.
2. From Data Cloud Setup, click **Get Started**.
Setup can take a few minutes. If you created a sandbox before Data 360 sandbox was generally available, you must refresh the sandbox before you can successfully provision Data 360 in the sandbox.
Wait until sandbox copy creation completes before changing your production org. Modifying production during this process can misconfigure your metadata.
When you create a sandbox, it displays the production org ID. After you activate the sandbox, the ID updates to the sandbox org ID.
## Step 4: Configure the Connections
When you create a Data 360 sandbox, connections are replicated, but the authorization data isn't, so the connections in the sandbox org have a status of Inactive. Activate each sandbox connection, and provide the authorization information to bring data into the sandbox.
After you turn on Data 360, wait about 1 hour before performing this step so that the background processing can complete.
1. In your sandbox org, select **Data Cloud Setup**.
2. In the Quick Find box, enter the connector type you want to activate.
For non-CRM connectors, enter Other Connectors. Select the connectors from the list. From the dropdown list, select **Activate**.
For Salesforce CRM home org connector, enter Salesforce CRM. Select the connector from the list. From the dropdown menu, select **Activate**. The CRM connection changes from your production org ID to your sandbox org ID.
For other Salesforce CRM connectors, follow the steps for the CRM home org connection. You can activate the connection to any production or sandbox org. Enter the org credentials for the connection, and click **Log In**. Confirm the connection by entering the Data 360 org identifier. You can find this ID on the modal under Data 360 Org Details. This identifier specifies which Data 360 org retrieves data from your source org.
3. Check the checkbox to agree to create the connection and click **Activate**.
After you activate a connection, the data streams or other components that use the connection become active.
## Step 5: Activate Data Actions and Data Action Targets
If you have data actions or data action targets in your production org, they’re replicated in a sandbox, but you must explicitly activate them.
1. In your sandbox, in the Data 360 app, click **Data Actions**, or **Data Action Targets**.
2. From the dropdown list, select **Enable**.
## Step 6: Activate Data Share Targets
If you have data share targets in your production org, they’re replicated in a sandbox, but they’ll be in an inactive state and you must explicitly activate them.
1. In your sandbox, in the Data 360 app, click **Data Share Targets**.
2. Open an inactive data share target and click **Edit**.
3. Add the connection configuration details and click **Save**. The data share target turns active.
#### See Also
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- [_Salesforce Help_: Deploy Data 360 Changes from a Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_deploy.htm&release=264.0.0&type=5 "You can make Data 360 changes in a sandbox and then deploy them to a production org or another sandbox org. Additionally, you can deploy changes from one production org to another production by using a sandbox. Use a DevOps data kit and a change set to deploy the changes to a production org.")
- [_Salesforce Help_: Using Data Cloud One with a Sandbox Org](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_sandboxes.htm&language=en_US)
# Create a Data Action in Data 360
Use a data action to send an alert or event to targets such as Salesforce Platform, Webhook, or Marketing Cloud Engagement, or Amazon Kinesis. Create the data action to focus on near real-time events and insights at different levels, including the channel, product, account, service, or individual.
### Required Editions
User Permission Sets
Needed
To create a data action:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, go to the Data Actions tab, click **New**.
2. Choose to create a data action from scratch or import from data kits and packages.
3. Select the data action target, and click **Next**. If the selected data action target is in the draft state, the data action also moves to a draft status.
4. Select a data space.
5. Select either a data model object (DMO) or calculated insight object (CIO) type. For Marketing Cloud Engagement targets, the selected object type must be from the Marketing Cloud data stream.
If there are multiple Marketing Cloud Engagement instances (EIDs) and the subscriber key is from a CIO, add the Field API Name “DataSource\_\_c” to your expression when creating the CIO.
6. Select a primary object, and click **Next**.
To trigger a data action when change events are identified, select a DMO, CIO, or an accelerated DMO that’s linked to an external data lake object (DLO), such as Amazon Redshift, Google BigQuery, Snowflake, or Databricks. If you select an accelerated DMO, verify that the acceleration process is complete. If you select a DMO, make sure that the primary key field of the DLO is mapped to the DMO.
7. For Amazon Kinesis targets, select a partition key which is an identifier used to route data records to specific shards in Kinesis data stream.
8. To enrich your data action, select a related object.
A DMO or a data graph mapped to an external DLO is available as a related object. For an object to appear as a related object in a data action, the primary object must have either a many-to-one or one-to-one relationship with the related object.
1. If you use a DMO as a related object:
- Add up to 10 related attributes to your data action.
- Select a subscriber key value. A subscriber key is the unique identifier of a message recipient in Engagement. It determines the email address to use for communication.
- Include the cdp\_sys\_record\_currency field when selecting a currency data type. Without this field, Data 360 treats the currency attribute as a number.
2. If you use a data graph as a related object:
- Select the related object lookup path where the data is available. You can’t select attributes individually, as the entire payload is sent to the data action target.
- For a Marketing Cloud Engagement data action target, configure the data extension to store the data action payload. See [Configure a Data Extension to Store a Data Action Payload.](https://help.salesforce.com/s/articleView?id=data.c360_a_data_extension_data_action_payload.htm&language=en_US) .
9. Select an event rule and an action rule.
Use the event rule to create an action based on record changes. The action rule evaluates your data action and can include OR and AND conditions.
10. To add more conditions, click **Add Condition**.
11. Select the object, attribute, and operator, and enter a value that can trigger the data action.
12. For orgs where multicurrency option is enabled, select a currency for the data action target. Your output data reflects the selected currency.
13. Select when to trigger the data action for the Record Updated event rule.
The Trigger Data Action for Updated Records option is available only if you select the Record Updated event rule. If any action rule condition uses a change operator such as Has Increased or Is Changed, you can’t change the Trigger Data Action for Updated Records setting. To change this setting, remove all change operators from the conditions.
14. Click **Next**.
15. Enter the action name.
The Action API Name field is automatically populated.
16. Click **Save and Publish**. You can view your data action on the record home page.
After you create the data action, it takes about 15 minutes to complete the configuration. It then sends the events in near real-time and is triggered only when a row is added, updated, or deleted in the primary object. For subsequent changes, the event is triggered immediately.
Data actions created by integration users, such as a Copy Fields enrichment or Data Cloud-triggered flow using Flow Builder, are read-only. You can’t delete, disable, or edit these data actions.
- **[Supported Operators for Event and Action Rule Conditions](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_operators_for_event_and_action_rules.htm&release=264.0.0&type=5)**
To trigger a data action, you can select one or more event rules based on the record actions and specify when to publish data using OR and AND conditions.
- **[Monitor the Event Activity of a Data Action](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_event_activity_data_action.htm&release=264.0.0&type=5)**
Track key metrics for a data action, such as events identified, processed, published, and failed in the Event Activity dashboard. Get enhanced visibility into your data as it moves through the data action pipeline in near real time. This gives you transparency around the volume of events and data delivery.
#### See Also
- [_Salesforce Help_: Caching or Acceleration in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&language=en_US)
# Create a Data Extension in Data 360
Quickly create a data extension for Journey Builder API Events of a data action directly in Data 360. This automated process removes the need to go to Marketing Cloud Engagement.
### Required Editions
User Permission Sets Needed
To create a data extension in data action:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, go to the Data Actions tab.
2. Open a data action with draft status and click **Create Data Extension**.
3. Click **Create**. The data extension is created in the folder path Data Extensions-> Salesforce CDP-> Data Actions Data Extensions in Marketing Cloud Engagement.
4. Create a [Journey builder API event](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_api_entry_source_use_case_1.htm&type=5&language=en_US) in Marketing Cloud that uses this data extension name.
5. In Data 360, edit the corresponding data action target and select the Journey Builder API Event that you created. After saving, the status of the data action target and the data action becomes active.
- After the data extension is created, if the schema for the DMO or CIO attributes is updated, click **Sync Data Extension** to get the latest changes to the data extension.
- The data extension created within Data 360 isn’t deleted if the corresponding data action and the data action target are deleted.
#### See Also
- [_Salesforce Help_: Configure a Data Extension to Store a Data Action Payload](https://help.salesforce.com/s/articleView?id=data.c360_a_data_extension_data_action_payload.htm&language=en_US)
- [_Salesforce Help_: Create a Data Action in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_action_in_customer_data_platform.htm&language=en_US)
# Create a Data Graph
Before creating a data graph in Data 360, decide which existing data model object (DMO) to use as the primary DMO. The primary DMO determines which related objects you can include in the data graph.
### Required Editions
Data graphs created from scratch use the API name that you specify. Data space-aware API naming for data graphs deployed through data kits doesn't apply to data graphs created from scratch.

Note Data graphs created from scratch retain the API name that you specify. Data graphs created through DataKit deployment can have automatically generated API names based on the target dataspace, depending on your organization's configuration.
User Permission Set
Needed
To create a data graph:
Permission set:

Note To create a data graph from a data kit, see [Create a Data Graph from a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_graph_data_kit.htm&release=264.0.0&type=5 "Avoid the time involved in creating a data graph manually by using a data graph from a published data kit. You can deploy a data kit containing data graphs using both managed and unmanaged packages. Changes that you make to the original data graph don’t affect the data graph in the data kit.").
1. From the App Launcher, search for and select **Data Graphs**.
2. Click **New**, and click **Start from Scratch**.
1. Choose a near real-time data graph or a real-time data graph.
2. Select or enter a value for each property field.
3. Click **Next**.
3. If you're creating a real-time data graph, set the consumption limits, and click **Next**.
Consumption limits can impact cost and performance. See [Record Caching and User Session Length in Real-Time Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_record_caching_in_rt_data_graphs.htm&release=264.0.0&type=5 "Configure your real-time data graph to manage the number of records held in the cache and user session length.").
4. Select fields from the primary DMO to include in the data graph.
The primary key field, related key qualifier field, and applicable foreign key fields are selected by default and added to the data graph for the primary DMO and its related objects.
5. To add related objects, click **+** or search for a DMO, and select fields for each related object.
If a DMO has more than one path, choose a path from the list of results. Longer paths add more levels to your data graph.
To apply filter settings, go to the Filters tab. The available filter settings depend on the DMO category.
In real-time data graphs, the relationship join must use the primary key of the parent data model object (DMO). If a relationship requires a non–primary key field from the parent DMO, it isn’t supported for real-time data graph.
When you create a real-time data graph, you can’t add DMOs that create an N:1 relationship. If you select a DMO that results in an N:1 relationship, the system blocks the selection and displays an error message. Real-time data graphs support only 1:1 and 1:N relationships. This restriction applies to newly created real-time data graphs.
6. To view the structure of the JSON blob, click **Preview**.
7. Save your work.
- To save the data graph without making it active, click **Save Draft**. The data graph is saved in draft status.
- To create the data graph, click **Save and Build**.
8. Select a refresh interval for the data graph.
- Every 30 Minutes
- Every 1 Hour
- Every 4 Hours
- Daily
- Weekly
- Monthly
- Streaming
Real-time data graphs update continuously and reflect the most current changes in DMOs for all real-time events. Whereas, standard data graphs adhere to a scheduled refresh.
The default refresh interval is daily. Selecting a shorter refresh interval can raise costs. You can't select a refresh interval for draft data graphs.
Streaming is validated at the Save and Build step. If unsupported features are present, you can’t proceed. Remove incompatible elements and try again. N:1 relation between DMOs and ad hoc filters are not supported with streaming data graphs.
The processing time to create an active data graph depends on the size of the primary DMO and related objects, anywhere between 15 minutes and several hours. You can check the processing status on the Data Graphs tab. If the status is Error, the data graph couldn’t be created. Contact your Salesforce account executive for help with resolving the error.
After the data graph is created, you can view, edit, clone, refresh, and delete it. You can also query the metadata and the JSON blob data using Data 360 Metadata API and Query API. Draft data graphs can't be cloned or refreshed.

Tip To see details about a DMO while creating a data graph, select the DMO in the data graph tree editor. To jump to the DMO record, click **View in Data Model**.
# Create a Data Graph from a Data Kit
Avoid the time involved in creating a data graph manually by using a data graph from a published data kit. You can deploy a data kit containing data graphs using both managed and unmanaged packages. Changes that you make to the original data graph don’t affect the data graph in the data kit.
### Required Editions
When you deploy a data graph through a supported data kit workflow, Data 360 uses the target data space to determine the data graph API name. For deployments to non-default data spaces, Data 360 prefixes the API name with the data space name to help prevent naming conflicts across data spaces.
User Permission Set
Needed
To create a data graph from a data kit:
Permission set:
1. From the App Launcher, search for and select **Data Graphs**.
2. Click **New**, and click **Use a Data Kit**.
3. Select a data kit.
Only installed data kits are shown.
4. Select a data graph from the installed data kit and select **Next**.
Only data graphs with a primary DMO that matches the data kit data graph's primary DMO are shown. If the data kit data graph’s primary DMO is a unified DMO, the DMO suffixes don’t have to match. For example, the data kit’s data graph has a primary DMO with the API name UnifiedIndividualR1, but only data graphs with the primary DMOs UnifiedIndividualR2 and UnifiedIndividualR3 exist. Then those two data graphs are shown.
You can edit properties, related objects, and fields of new data graphs created from an unmanaged package. These aren't editable for data graphs created from a managed package. All the related objects and fields that the data graph references must exist in your org. If any don’t exist, you must create them or remove them from the data graph.
# Create a Data Share
Select the Data 360 objects that you want to include in a data share to share with an external system.
### Required Editions
User Permissions
Needed
To create data shares:
Permission set:
To comply with data policies and regulations, data sharing includes the `IndividualGDPRState__dll` object, which provides individuals with consent information. You can use Individual ID to link and honor the consent data for an individual at the data share target.
1. In Data 360, on the Data Shares tab, click **New**.
2. Enter these details and click **Next** .
- Label - The display name of the data share. For Google BigQuery, the character limit is 20, but you can add details in Description. For Snowflake, there’s no character limit.
- Name - The API name for the data share in Data 360. It's auto-populated to match the label name. You can choose to use a different name.
- Data Space - A data space is a logical partition to organize your data for profile unification, insights, and marketing in Data 360. Choose “Default” for data space if you don’t have any other data space provisioned in your org.
- Provide consent for admins or privileged users in the receiving organization other than Salesforce Data Cloud to view and query all records of the data lake objects (DLOs) mapped to data model objects (DMOs) in the data share.
- Description - Any relevant details of the data share.
3. Select the Data 360 objects that you want to include in the data share.
You can’t share an external data lake object (DLO) or a data model object (DMO) mapped to an external DLO with an external data lake.
4. Click **Save**.
# Create a Data Share Target to Connect with Amazon SageMaker
To establish connectivity with an Amazon Redshift account, create an Amazon SageMaker data share target in Data 360.
### Required Editions
1. In Data Cloud, on the Data Shares Target tab, click **New**.
2. For the connection type, select Amazon Redshift, and click **Next**.
3. Enter the display name of the data share target and your AWS account ID.
Data 360 populates the API name to match the label name, but you can use a different one.
4. To connect without account verification, select the **Skip authentication** checkbox.
5. After you save, the S3 Tenant Folder populates a link.
6. Click the S3 Tenant folder link, and open the S3 folder. If you have configured PrivateLink for your Amazon Redshift instance, Data 360 Private Connect isn't required to share data from Data 360 to Amazon Redshift. The S3 Tenant folder link authenticates access to the folder containing the verification token.
7. Open the verification text file, and copy the verification token.
8. Enter the verification token in the data share target, and save the changes.
You’re routed back to Data 360, and the data share target becomes active.
# Create a Data Share Target to Connect with Databricks
To establish connectivity with a Databricks account, create a data share target in Data 360.
### Required Editions
1. In Data Cloud, on the Data Shares Target tab, click **New**.
2. Select Databricks as the target, and click **Next**.
3. Enter the name of the data share target. Data Cloud populates the API name, but you can use a different one.
4. Copy and share the Core Tenant ID and Tenant Endpoint details with your Databricks admin. The Databricks admin [creates a connection in Databricks](https://docs.databricks.com/aws/en/query-federation/salesforce-data-cloud-file-sharing) to generate Databricks Account URL and Connection URL.
5. Enter the Databricks Account URL and Connection URL received from your Databricks admin and click **Save**.
# Create a Data Share Target to Connect with Google BigQuery
To establish connectivity with a Google BigQuery account, create a data share target in Data 360.
### Required Editions
1. In Data 360, on the Data Shares Target tab, click **New**.
2. For the connection type, select **Google BigQuery**, and click **Next**.
3. Enter these details.
1. For Label, enter a display name up to 20 characters for the data share target.
The API name is auto-populated to match the label name, but you can use a different API name.
2. For Google Cloud Principal, enter a verified user or group email address.
Each principal has its identifier, which is typically an email address. The principal must be a valid Google Workspace domain.
3. To connect without authenticating, select the **Skip authentication** checkbox, or choose **User**, **Group**, or **Service Account** for Type.

Note You can’t create multiple data share targets with the same Google Cloud Principal and Type.
4. Click **Save**.
The Google sign-on page appears.
5. Authenticate the Google Cloud Principal.
You’re redirected to Data 360, and the data share target becomes active.
# Create a Data Share Target to Connect with Snowflake
Create a data share target in Data 360 to establish connectivity with a Snowflake account.
### Required Editions

Important You can’t create legacy Snowflake data share targets. [Create a Snowflake V2 data share target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflakev2.htm&type=5&language=en_US) instead, and link your existing and new data shares to it. Migrate existing data shares that are linked to a legacy Snowflake data share target to a Snowflake V2 data share target. See [Migrate Data Shares with Legacy Snowflake Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_migrate_data_shares_legacy_snowflake.htm&type=5&language=en_US). Don’t unlink an existing data share from its legacy target until you verify that the Snowflake V2 connection works. Downstream processes in Snowflake can refer to the database that was created using the legacy target.
User Permissions Needed
To create a data share target:
Data Cloud Architect permission set

Note Private Connect for Data 360 is a feature that allows you to share data with Snowflake instances without exposing the data to the public internet. If your Snowflake instance is secured in a VPC, you can create a secure connection between your instance and Data 360. To use Private Connect for Data 360, create a private connect network route. The network route is used to validate that you're sharing data with the correct instance.
Private Connect for Data 360 only supports AWS PrivateLink with Snowflake service within the same cloud service provider geographical region. This means that cross-region connectivity is not supported. For example, if your Data 360 instance is in the US West region, then the Private Connect for Data 360 service will only be available for use with Snowflake within the US West region.
1. In Data Cloud, on the Data Shares Target tab, click **New**.
2. For the connection type, select **Snowflake**, and click **Next**.
3. Enter these details.
- Label - The display name of the data share target. There’s no character limit.
- API Name - This field is auto-populated to match the label name, but you can use a different name.
- Account Url - Enter the value of OAUTH\_AUTHORIZATION\_ENDPOINT and convert any underscores to hyphens and ignore the subdirectory and subsequent parts. For example, if your OAuth Authorization Endpoint URL is `https://nto_america_dev_instance.example.computing.com/oauth/authorize`, you can use `https://nto-america-dev-instance.example.computing.com` for the Account Url.

Note If PrivateLink is enabled on Snowflake account and [IP allowlisting](https://help.salesforce.com/s/articleView?id=data.c360_a_allowlist.htm&type=5&language=en_US) is used for data sharing capability, then use the Public URL of the OAuth Authorization Endpoint for the Account Url.
4. To connect without authenticating, select the **Skip authentication** checkbox or enter the Client ID and Client Secret that are generated in Snowflake.
Refer to [Get User Credentials from Snowflake](https://help.salesforce.com/s/articleView?id=data.c360_a_get_user_details_snowflake.htm&release=264.0.0&type=5 "Gather the user information and authentication details in Snowflake to create a data share target.").
5. Enter a description for the data share target and click **Save**.
6. On the Snowflake login page, enter the username and password from the previous step and authenticate to Snowflake with a Data Cloud architect permission set. You route back to Data Cloud and the data share target turns to active status.
When sharing data with Snowflake via a custodian account, OAuth authentication uses Private Connect for Data 360 to securely authenticate the customer's Snowflake account. After the data share is linked to a data share target, data sharing from Salesforce happens through a secure public IP that follows Hyperforce security and privacy guidelines. Salesforce leverages Snowflake's built-in [secure data sharing](https://docs.snowflake.com/en/user-guide/data-sharing-intro) feature to share data between the Salesforce custodian account and Snowflake customer account. The OAuth authentication process happens only once, hence the security integration object created in Snowflake is no longer necessary for Salesforce Data 360.
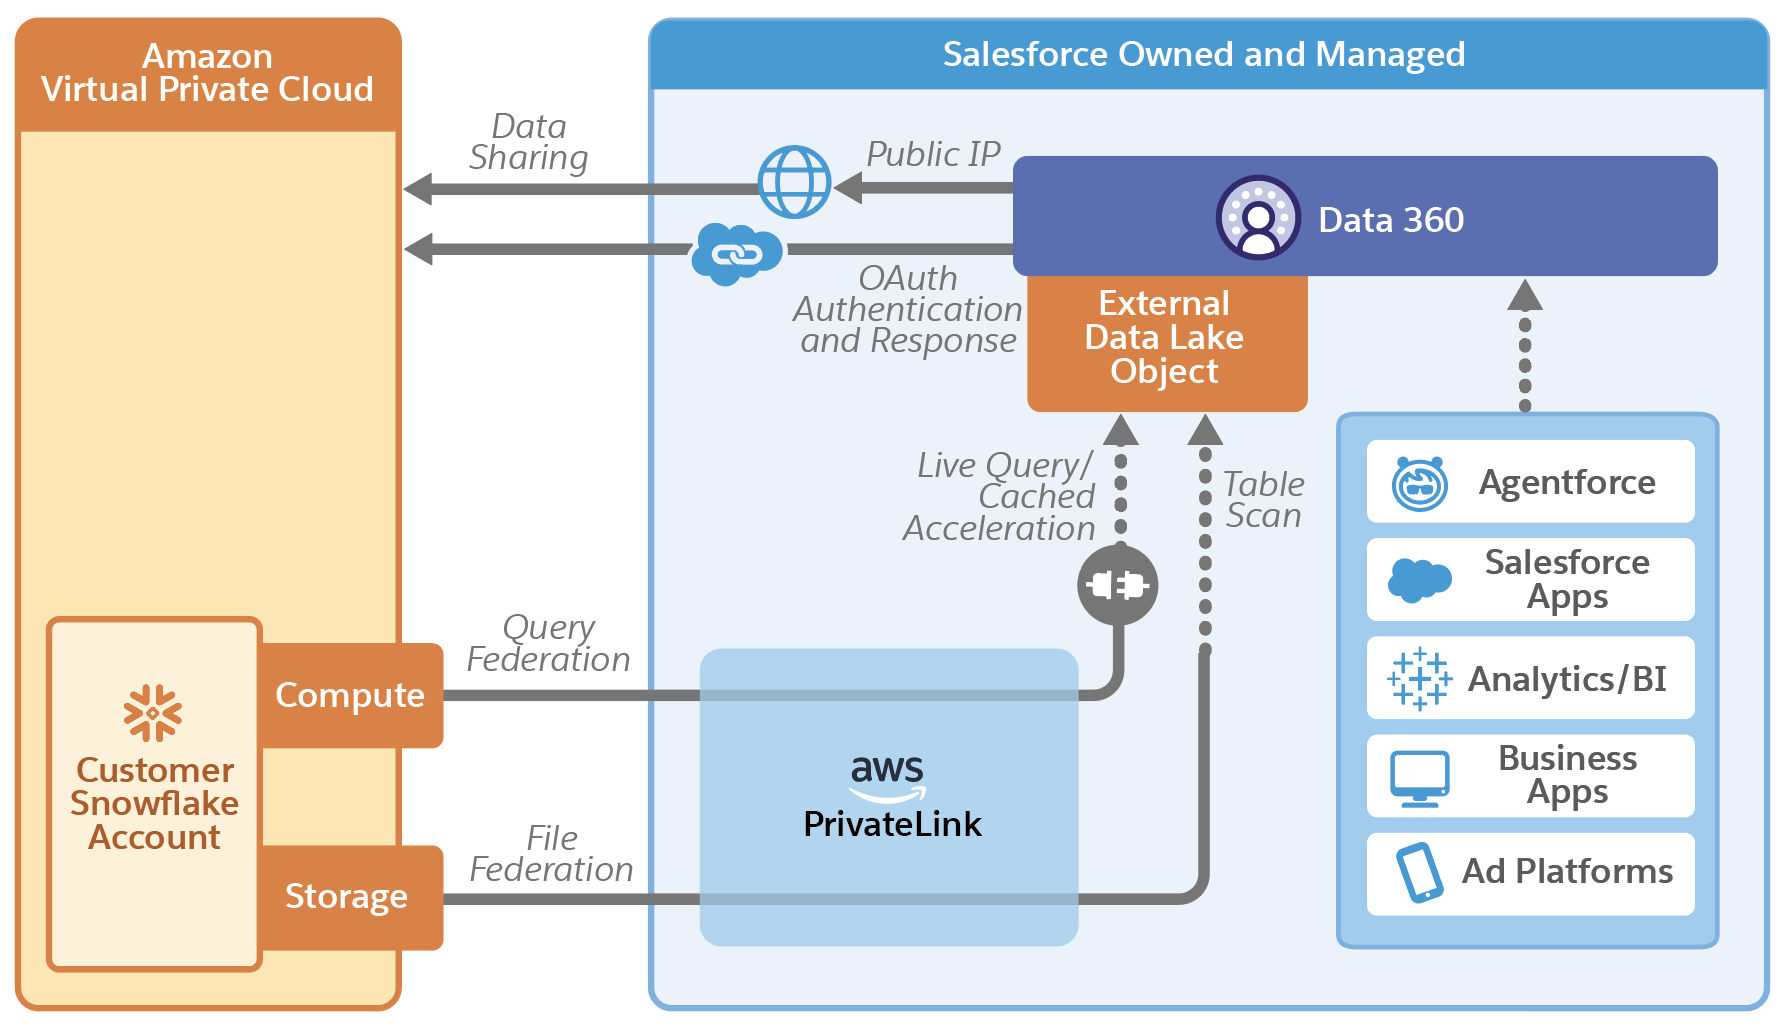
#### See Also
- [_Salesforce Help_: Private Connect for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_data_cloud.htm&release=264.0.0&type=5 "Private Connect uses Amazon Web Services (AWS) PrivateLink to establish a point-to-point network integration between your AWS virtual private cloud (VPC) and your Data 360 tenant. Private Connect provides a connection from Data 360 to your data source without exposing your network traffic to the public internet.")
# Create a Data Space
Every Data Cloud org is created with a default data space. Until you create other data spaces, all Data Cloud objects are mapped to the default data space. To segregate your brand, region, or department data and services, create more data spaces.
### Required Editions
Permission Sets Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set

Note The standard Data Cloud and Customer Data Platform licenses are limited to just one data space. To create additional data spaces, you must purchase an add-on license. For more information, see [Data Cloud Standard Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&type=5&language=en_US).
1. Go to **Data Cloud Setup**.
2. Under Feature Management, click **Data Spaces**.
3. Click **New**, and give the data space a unique name that identifies its brand, region, or department.
4. Enter a unique data space prefix, starting with a letter and including up to three alphanumeric characters.
After you save the data space, you can’t change its prefix because it becomes part of the API name used to differentiate objects that exist in multiple data spaces.
For example, the Individual DMO is in two data spaces: data space 1 with prefix DS1, and data space 2 with prefix DS2. When the Individual DMO is mapped to the data spaces, the object API names are DS1\_Individual\_dlm and DS2\_Individual\_dlm.
5. Add an optional description about the purpose of the data space.
6. Click **Save**.
# Create a Data Stream from a Data Kit
When you create a data stream from a data kit in your target org, the data model objects are available automatically. When adding a data model to a data kit, a custom data model is added as is. If you’re adding a standard data model, only the custom mappings and custom fields are packaged.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:
Before you begin, make sure that the connection to the CRM org is created in the target org and that all objects referenced by the data stream are in the target org. If an object isn’t in the target org, you might see an error that the specified object can’t be found or get an insufficient privileges error.
1. In Data 360, go to the Data Streams tab.
2. Click **New**.
3. Select **Installed Data Kits & Packages** and click **Next**.
4. From the installed data kit, select the data stream definition that you want to use.
5. Select the connected source and click **Next**.
6. Select a Salesforce org and a data bundle.
7. Click **Next**.
8. Review and optionally edit your data fields, and then click **Next**.
By default, all fields from a data kit are deployed. However, to prevent deployment errors, you can deselect fields that aren’t in the org or instance using the data kit. A data kit requires fields with mappings, formula fields, and their source fields to be deployed.
9. Click **Deploy**.
File-based connector deployments automatically append an uneditable timestamp to the name of the data stream.
# Create a Data Stream from a Marketing Cloud Engagement Data Extension
A data extension is a table within Marketing Cloud Engagement that contains your data. Use that data in Data 360 by creating a data stream in Data 360 from a Marketing Cloud Engagement data extension.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:
Before completing these steps, consider the frequency of data extracts since they can't be edited.
Marketing Cloud Engagement only processes full extracts daily. Since Data 360 checks hourly, you see 24 refreshes in the Data Stream tab, but only one extract processes.
Marketing CloudEngagagement process delta extracts hourly. If you create a data stream with a delta extract selected, a full extract and ingestion occurs on the first run. After that, only deltas have hourly extracts. For both extract modes, the remaining refreshes show zero rows processed due to no new data from Engagement.
1. In Data Cloud, go to Data Streams, and click **New**.
2. Select **Marketing Cloud** as the data source, and click **Next**.
3. From Connections, select the Marketing Cloud Engagement connection you want to configure.
4. For the connections business units, select the appropriate data spaces needing mapping.
5. Choose a data extension.
1. Select a business unit in the context filter dropdown to view its data extensions.
2. Select the data extension to import.
6. (Optional) Change the object label or object API name.
7. Select the category and define the primary key.
8. Review the field list, and optionally edit the field label, field API name, and data type.
9. (Optional) To cleanse your source data or get new fields, add formula fields.
10. Configure the data stream name, extract mode, and refresh mode.
If a data extension extracation has previously occurred, the extract mode and the refresh mode are unavailable. Deleting and recreating the stream doesn’t enable these modes. To extract data using a different method, create a data extension with a unique name to use with the new data stream.

Note Delta extracts require a number or date field.
11. Click **Deploy**.
12. To map the data source object to the data model, go to Data Streams home page and click **Start Data Mapping**.
When the data extension is extracted for the first time, it takes up to 24 hours for data to be available in the system. After the first 24 hours, data is populated according to the frequency indicated in the data stream settings. Delta extracts load the previous 90 days of data when the data stream is initially configured. Subsequent runs load only new or updated records. For Engagement type, Data 360 extracts the last 90 days of data and for Profile type, the entire dataset is extracted.
- **[Data Extension Considerations for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_extensions.htm&release=264.0.0&type=5)**
If you ingest a data extension into Data 360, you should be aware of some core functionality within Marketing Cloud Engagement and how they operate within Data 360.
- **[Extract Mode for a Marketing Cloud Engagement Data Extension in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_extract_settings.htm&release=264.0.0&type=5)**
Marketing Cloud Engagement Connector Extract mode dictates how Data 360 exports and imports data from Marketing Cloud Engagement.
- **[Refresh for Data Extension Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_refresh_now.htm&release=264.0.0&type=5)**
For a data extension data stream with the refresh mode of upsert, you can choose to perform either an incremental or a full data refresh.
# Create a Data Transform Platform Event Flow
Create a platform-triggered flow for data transform event actions.

Note In some cases, running a platform event for data transforms can result in duplicate actions being performed. To prevent duplicate actions when running a platform event for data transforms, consider it in a decision condition, or alternatively create a data transform record event flow.
1. In Data Cloud, select **Setup**.
2. In the Quick Find box, enter Flows, and select **Flows**.
3. Click **New Flow**.
4. Select **View All**, then click **Platform Event—Triggered Flow**.
5. In the right pane, from the Choose Platform Event drop-down, select **Data Transform Event**.
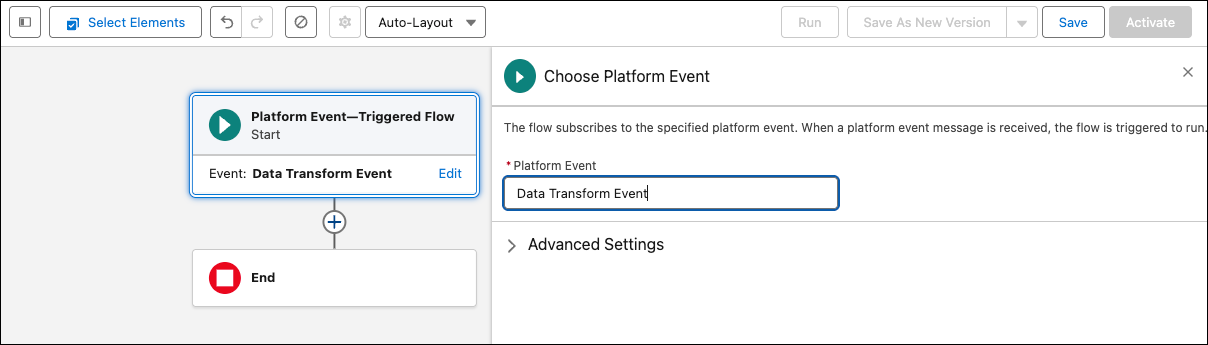
6. Under Advance Setting, choose the workflow user.
7. From the left pane, click to add an element. For example, add a decision action.
8. In the right pane, enter a label for the action.
9. Define the outcome details and condition requirements. You can add more conditions as needed.
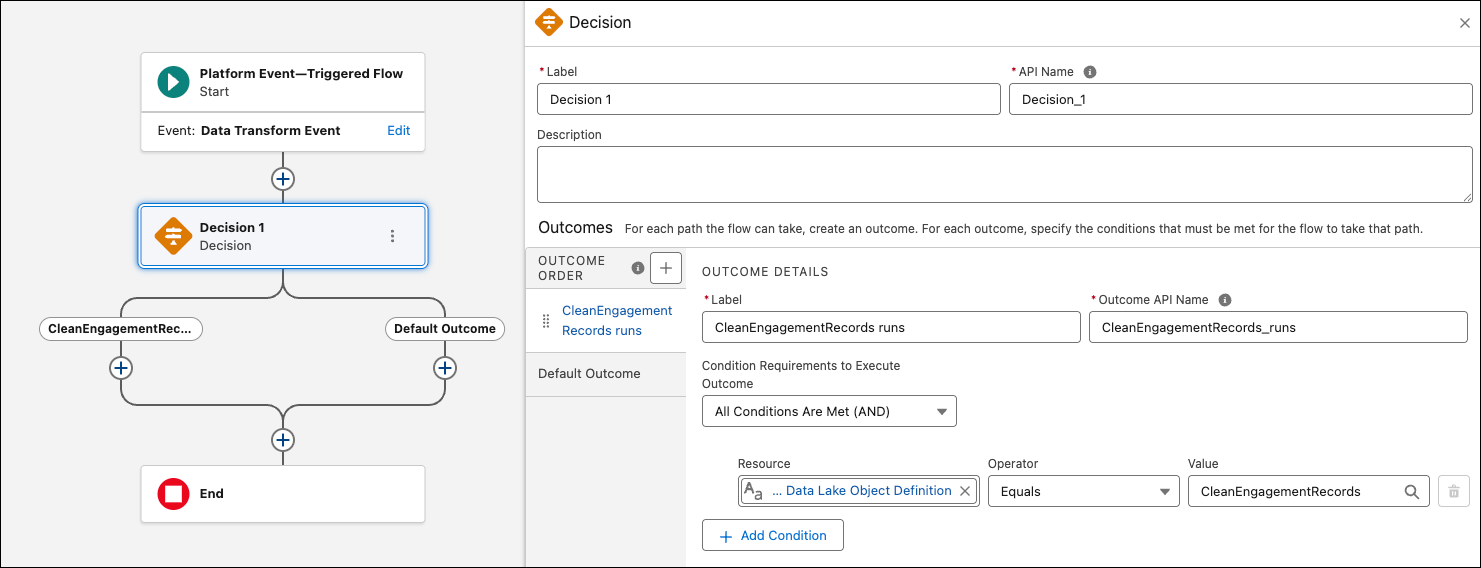
10. From the left pane, add an element to trigger the flow action based on the conditions. For example, you can select Run Batch Data Transform if the conditions are met and send an email if the conditions are not met.
11. Enter the details for the action.
12. Click **Save**.
13. Enter the flow label, click **Save**, and then click **Activate**.
# Create a Data Transform Record Event Flow
Create a record-triggered flow for data transform event actions. With a record-triggered flow, you can update another record, send a notification, or initiate a process.
1. In Data Cloud, select **Setup**.
2. In the Quick Find box, enter Flows, and select **Flows**.
3. Click **New Flow**.
4. Select **View All**, then click **Record-Triggered Flow**.
5. In the right pane, from the Select Object drop-down, select the Data Transform object.
6. Select when to trigger the flow.
7. From the Condition Requirements dropdown, select **All Conditions Are Met (AND)**.
8. Define the condition. In this example, the transform CleanEngagementRecord is specified and the Data Transform Status value is set to Error. You can then add an action based on the condition requirements.
# Create a Direct-DMO Related List Enrichment
Add information to a Salesforce object related list from a Data Cloud DMO by using a direct relationship between the DMO and the Salesforce object. The direct relationship doesn't require that you complete identity resolution for the DMO. For example, a Vehicle object in Automotive Cloud can have a related list of Vehicle Telematics Event DMO records from Data Cloud.
### Required Editions
User Permissions
Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To create or update enrichments:
Customize Application
To view the related list:
You have access through the Data Cloud.
User permission set to the data
space
Alternatively, if you enabled enhanced security data spaces, in the user
permission set data access level for the data space, make sure to enable the
controlled by parent setting.
Object Permissions
Needed
To view enrichments in Object Manager:
Data Model Objects object Read permission
To create or update enrichments:
Data Model Objects object Create, Update, and Delete permissions

Important Read [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.") before starting this task.

Note It's not possible to hyperlink data in the related list to the corresponding CRM object's record detail page.

Note CRM–DMO relationships do not sync from home to companion orgs. You must create the relationship directly on the companion org.
To create a direct-DMO related list enrichment:
1. Create a direct relationship between the Salesforce object and the DMO. In the Data Cloud app, click **Data Model**, and then click your DMO.
2. On the DMO detail page, in the Relationships tab, click **Edit**, and then click **New Relationship**.
3. Select a DMO field that identifies the DMO record, such as an ID, and that's used to match the DMO record with the Salesforce record.

Note To find out which Salesforce objects are available for enrichment, see "Supported Source and Target Objects for Direct-DMO Related Lists" in [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&language=en_US&type=5). If you have person accounts enabled, you can also add the related list to a person account.
4. For cardinality, select **N:1**.
The 1:1 cardinality isn't supported for the direct-DMO relationship.
5. For Related Object, select **CRM** to relate the object to a Salesforce object, and then select a field.
The field you select identifies the record, such as an ID, and is used to match the Salesforce record with the DMO record. The fields list is filtered to show only ID and string fields.
6. Save your work.
7. Add a dynamic related list to the object's record page. See [Create Dynamic Related Lists in Lightning App Builder](https://help.salesforce.com/s/articleView?id=platform.lightning_app_builder_create_dynamic_related_list.htm&type=5&language=en_US).
8. For Related List, select the relationship you created.
9. Add any fields to show in the related list, and then save your work.
 [Create a Permission Set for a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_permset.htm&release=264.0.0&type=5 "Control which users can see a related list enrichment by assigning them to a permission set that has access to the Data Cloud data space.")
**Supported Source and Target Objects for Direct-DMO Related List Enrichments**
You can create a direct-DMO related list enrichment on these target objects.
- Account
- Asset
- Case
- Contact
- Contract
- Custom Object
- Fleet
- FinancialAccount
- Lead
- Product
- Opportunity
- Order
- Vehicle
- Work Order
- Work Order Line Item
**Targeting Person Accounts**
Starting in Winter '26, you can link direct-DMO related list enrichments to Person Account objects. To ensure your relationships are configured correctly and effectively, follow these considerations.
You can use matching fields to link data between a DMO and a record page, like a Person Account. A Person Account combines fields from Account and Contact objects into a single view. So when you choose matching fields for a Person Account, you’ll see a list of available fields from its Account and Contact sources. You can use these fields to match records between your source DMO and the target Person Account object.
This improves flexibility for creating relationships. For example, you can match records based on business-centric Account fields (like AccountNumber) or person-centric Contact fields (like PersonEmail).
Your source DMO must contain a field that logically corresponds to the matching field that you select for the target Person Account object. For example, if you set your matching field to PersonEmail, your DMO must have a field that contains the customer’s email address.
Recommended Matching Fields for Person Accounts
| Matching field | source object | use case |
| --- | --- | --- |
| ContactId | Contact | Recommended when your source DMO is keyed to the Salesforce Contact ID of the individual. |
| AccountId | Account | Recommended when your source DMO is keyed to the Salesforce Account ID of the Person Account record. |
| PersonEmail | Contact | A common and effective choice for matching records based on the customer's email address. |
Let’s say you want to display a list of a customer’s recent support tickets from an external system on their Person Account record page. The support ticket data is in an ExternalTickets DMO, which contains a Customer\_Email\_\_c field. Follow these steps to set this up.
1\. In Setup, navigate to **Data Cloud Enrichments**.
2\. Click **New** to create a new enrichment.
3\. Select **Related List Enrichment** and **Direct DMO**.
4\. For the enrichment, set **Source DMO** to ExternalTickets and **Target CRM Object** to Contact.
5\. For the **Matching Fields**, set **Source DMO Field** to **Customer\_Email\_\_c** and **Target CRM Object Field** to Email (on the Contact object).
6\. Save the enrichment.
7\. Add the related list to the Account with the **Person Account** record type. The relationship should have the **\_\_pr** suffix.
#### See Also
- [_Salesforce Help_: Enrichment Troubleshooting](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_troubleshooting.htm&release=264.0.0&type=5 "Diagnose issues with enrichments and fix them.")
- [_Salesforce Help_: Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.")
# Create a Document Schema Configuration Manually
Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the document schema builder to manually define the structure of the document schema by adding fields and tables.
### Required Editions
User Permissions
Needed
To create Document AI configurations:
Permission set:
If you choose, you can create Document AI configurations using the Data Cloud Connect API. See the [Data Cloud Connect API reference](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=postDocumentAIConfigExtractData) for details.
**Before you begin**
- To use Document AI in Data Cloud 360, [turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) and [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5).
- Ensure that you've followed the unstructured data workflow and have created an unstructured data model object (UDMO) to reference your source files.
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
## Create an output DLO
Configure an output DLO to represent the schema definition of the data extracted from your source file.
1. From the App Launcher, select Data Cloud.
2. Click **Process Content** | **Document AI** | **New**.
3. Click **From a Source Object**.
4. Select the UDMO that contains the documents you want to process.
1. To process files from an existing source, select a UDMO that contains documents for processing, and click **Next**.
2. To process files ingested through the Salesforce CRM connector, select the **Content Document Version** UDMO.
Choose the CRM object whose file attachments you want to process, such as Account or Contact, and click **Save**. The available objects come from your Content Document Relationship records.
5. Use the toggles to select which file types are available for your document schema configuration, and click **Next**.
6. Select which LLM you want to use, and click **Next**.
7. On the Configure a Data Lake Object page, click **Add**.
8. Click From Scratch, and in the New Data Lake Object dialog, supply values for the DLO Name and API Name, and then click **Next**.
## Add Fields to Extract
Configure the fields to extract and define the structure of the document schema.
1. In the document schema builder, click **Create Manually** and then click **Confirm**.
2. In the Outputs panel, select the Fields tab and then click **Add Field**.
3. Provide a name, API Name, and Category for the field.
4. To add more fields, click **Add**.
5. Click **Test** and verify the results of the extraction.
6. Select **Save Draft** to revisit your configuration later or **Publish** to activate your configuration.
## Add Tables to Extract
Configure the tables to extract.
1. In the Outputs panel, select the Tables tab.
2. Click **Add Table**.
3. Provide a name, API Name, and Category for the table.
4. Click the Columns tab, click **Add New Column**, and provide a name, API Name, and Category for the column.
5. Continue adding columns until the table is complete.
6. To configure more tables, click **Add New** and repeat the steps to add the table columns.
7. Click **Test** and verify the results of the extraction.
8. Select **Save Draft** to revisit your configuration later or **Publish** to activate your configuration.
You can view the document schema configuration on the details page. To instead populate the schema from a JSON file, review [Import a Document Schema Configuration from JSON](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_no_source.htm&release=264.0.0&type=5).
#### See Also
- [Document AI Example Schemas](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_schema_ref.htm&release=264.0.0&type=5 "The following prompts are JSON-formatted schemas that you can use when creating an Document AI configuration in Data 360. Use these examples as starting points, or modify them for your specific use cases.")
- [Manage Document AI Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_manage_configs.htm&release=264.0.0&type=5 "View, edit, publish, export, and rebuild Document AI configurations. Package Document AI configurations in data kits. Save Document AI configurations as drafts, and refine your extraction schemas over multiple sessions.")
# Create a Document Schema Configuration Using Auto-Extraction
Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the auto-extraction option in the document schema builder to have an LLM define the structure of the document schema. The builder auto-populates all fields, tables, and columns.
### Required Editions
User Permissions Needed
To create Document AI configurations
Permission set:
If you choose, you can create Document AI configurations using the Data Cloud Connect API. See the [Data Cloud Connect API reference](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=postDocumentAIConfigExtractData) for details.
**Before you begin**
To use Document AI in Data Cloud 360, [turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) and [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5).
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
## Turn On Einstein Generative AI
Before getting started, turn on Einstein to use generative AI features in Document AI. After you turn on Einstein, we’ll need a few minutes while we sync Einstein and Data Cloud.
1. System admin: From Setup, in the Quick Find box, enter Einstein Setup, and then select **Einstein Setup**.

Note If you can’t find **Einstein Setup**, ensure that your org meets the prerequisites for any generative AI features you plan to use. For more support, contact your Salesforce Account Executive (AE).
2. Enable **Turn on Einstein**.
## Create an Output DLO
Configure an output DLO to represent the schema definition of the data extracted from your source file.
1. From the App Launcher, select Data Cloud.
2. Click **Process Content** | **Document AI** | **New.**
3. Click **From a Source Object**.
4. Select a UDMO that contains documents for processing, and click **Next**.
5. Use the toggles to select which file types are available for your document schema configuration, and click **Next**.
6. Select which LLM you want to use, and click **Next**.
7. On the Configure a Data Lake Object page, click **Add**.
8. Click From Scratch, and in the New Data Lake Object dialog, supply values for the DLO Name and API Name, and then click **Next**.
## Auto-extract the Document Schema
Use the document schema builder to auto-extract the document schema, including fields, tables, and columns.
1. In the document schema builder, click **Using auto-extraction** and then click **Next**.
Document Al auto-extracts all data from the source and auto-populates a document schema.
2. Click **Test** and verify the results of the extraction.
3. Select **Save Draft** to revisit your configuration later or **Publish** to activate your configuration.
You can view the document schema configuration on the details page. To instead populate the schema from a JSON file, review [Import a Document Schema Configuration from JSON](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_no_source.htm&release=264.0.0&type=5).
#### See Also
- [Document AI Example Schemas](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_schema_ref.htm&release=264.0.0&type=5 "The following prompts are JSON-formatted schemas that you can use when creating an Document AI configuration in Data 360. Use these examples as starting points, or modify them for your specific use cases.")
- [Manage Document AI Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_manage_configs.htm&release=264.0.0&type=5 "View, edit, publish, export, and rebuild Document AI configurations. Package Document AI configurations in data kits. Save Document AI configurations as drafts, and refine your extraction schemas over multiple sessions.")
# Create a Document Schema Configuration Without a Source Object
Configure a document schema to use in programmatic API workflows. Use the document schema builder to define a new document schema.
### Required Editions
User Permissions Needed
To create Document AI configurations:
Permission set:
You can also create Document AI configurations using the [Data Cloud Connect API reference](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=postDocumentAIConfigExtractData).
**Before you begin**
- To use Document AI in Data Cloud 360, [turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) and [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5).
- Ensure that you’ve followed the unstructured data workflow and have created an unstructured data model object (UDMO) to reference your source files.

Note When you create a schema configuration without a source object, Data Cloud doesn't create an output DLO as it doesn’t store any data when you use this option.
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
## Create a Document Schema Configuration
1. From the App Launcher, select Data Cloud.
2. Select **Process Content** | **Document AI** | **New**.
3. Select **Without a Source Object**.
4. In the document schema builder, select **Create Manually** and then select **Confirm**.
5. In the Outputs panel, select the Fields tab and then select **Add Field**.
6. Provide a name, API Name, and Category for the field.
7. (Optional) Add a prompt to provide Document AI with specific instructions about how to populate the field.
8. To add more fields, select **Add**.
9. In the Outputs panel, select the Tables tab, and then select **Add Table**.
10. Provide a Name, API Name, and Category for the table.
11. (Optional) Add a prompt to provide Document AI with specific instructions about how to populate the table.
12. Select the Columns tab, select **Add New Column**, and provide a name, API Name, and Category for the column.
13. Continue adding columns until the table is complete.
14. To configure more tables, select **Add New** and repeat the steps to add the table columns.
15. In the Outputs panel, select the Schema tab.
16. (Optional) Add a prompt to provide Document AI with global instructions that apply to the entire document. For example, you can set instructions to ignore specific sections or define a primary extraction language.
17. Select **Test** to verify the extraction results.
18. Select **Save Draft** to revisit your configuration later or **Publish** to activate your configuration.
Review the document schema configuration on the details page.
## Import a Document Schema Configuration from JSON
Instead of building a document schema from scratch, import a JSON file [exported](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_manage_configs.htm&release=264.0.0&type=5) from another org or environment to populate the output fields and tables.
1. From the App Launcher, select Data Cloud.
2. Select **Process Content** | **Document AI** | **New**.
3. Select **Without a Source Object**.
4. In the document schema builder, for the method to add fields and tables, select **Import from JSON** and then select **Next**.
5. Paste the exported JSON into the **JSON Schema** field and then select **Next**.
6. Deselect any fields or tables that you don't want to import.
7. Select **Insert**.
8. Select **Save Draft** to revisit your configuration later or **Publish** to activate your configuration.
You can view the document schema configuration on the details page.
# Create a Dynamic Data Masking Policy for Structured Data in Data 360
Protect sensitive information by restricting data visibility based on user roles and permissions.
### Required Editions
Before You Begin
Review these important considerations to ensure your masking policies work as expected.
- If a field used in a data graph is governed by a masking policy, users can’t access this data graph.
- If a Boolean field is masked, the value is always displayed as False, regardless of the field’s actual value.
User Permissions Needed
To create a dynamic data masking policy:
Permission set:
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Policies**.
3. Click **New**, select **Dynamic Data Masking**, and click **Next**.
4. In Policy Builder, enter a unique policy name, and an optional description.
The policy API name is auto-filled based on your policy name, but you can change it.
5. Click **Next**.
6. Select **Rules**, and select the resources to protect. In the **Resource** dropdown, select **Field in Structured Data**.
By default, the rule applies across all data spaces. As new data spaces are added, these rules apply to their resources.
7. To restrict policies to specific data space scopes, click **Customize Scope**, deselect **Apply to the resources in all Data Spaces in Data Cloud**, and select the desired data spaces.
8. Click **Save**.
9. Select the action you want to take on the resource. From the Action dropdown, select **Mask**.
10. Select one of the following masking methods.
- Redaction - Replace masked characters with X. Select the number of characters to redact.
- Nullification - Replace data with NULL.
- Datetime Rounding - Simplify date and time display by showing only the year or the year and month.
- Numeric Rounding - Round numbers to the nearest whole number or the specified decimal places.
11. Define the conditions when this action must take place. For example, set a condition to trigger the rule if the **Financial Data.Account Info** tag is present in the object. Or, if the **Personal Data.Digital Identifier.Browsing History** tag is not present in the object.
12. To add more conditions, click **Add Condition**.
13. To group your conditions into different sets, click **Add Group**. You can use the OR operator to take action when any group meets the rule conditions.
14. Click **Save and Activate**.
# Create a Dynamic Data Masking Policy for Unstructured Data (Beta)
Define a masking policy to protect sensitive information in unstructured files such as PDFs and text documents.
### Required Editions

Note Content tagging and unstructured data masking is a pilot or beta service that is subject to the Beta Services Terms at [Agreements - Salesforce.com](https://www.salesforce.com/company/legal/agreements/) or a written Unified Pilot Agreement if executed by Customer, and applicable terms in the [Product Terms Directory](https://ptd.salesforce.com/). Use of this pilot or beta service is at the Customer's sole discretion.
| User permission needed | |
| --- | --- |
| To create a dynamic data masking policy: | Data Cloud Architect permission set |
To create a dynamic data masking policy:
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Policies**.
3. Click New, select **Dynamic Data Masking**, and click **Next**.
4. In Policy Builder, enter a unique policy name and an optional description. The policy API name is automatically filled based on your policy name, but you can change it.
5. Click **Next**.
6. Select Rules, and select the resources to protect. In the Resource dropdown, select **String in Unstructured Data**.
By default, the system applies the rule across all data spaces. As new data spaces are added, the system rules apply to their resources.
7. To restrict policies to specific data space scopes, click **Customize Scope**, deselect **Apply to the resources in all Data Spaces in Data Cloud**, and select the desired data spaces.
8. Click **Save**.
9. Select the action to take on the resource. From the Action dropdown, select **Mask**.
10. Select one of these masking methods:
- Redaction - Replace masked characters with X. Select the number of characters to redact.
- Nullification - Replace data with NULL.
11. Define the conditions when this action takes place.
For example, set a condition to trigger the rule if the `Financial Data.Account Info` tag is present in the object. Or set a condition if the `Personal Data.Digital Identifier.Browsing History` tag isn't present in the object.
12. To apply the policy to users, select **Users**.
13. Apply the policy to all users or to users who meet specific AND and OR conditions. The conditions are based on custom permissions assigned to users.
14. To add more conditions, click **Add Condition**.
15. You can also group your conditions into different sets and use the OR operator to take action when a group meets the rule conditions. To add a group, click **Add Group**.
16. Click **Save and Activate**.
# Create a Dynamic Segment
Create a dynamic segment based on a Data Model Object (DMO) and run segment queries without persisting data in Segment Membership DMOs. Define attribute filters with placeholders that accept dynamic values at execution time.
### Required Editions
Permission Sets Needed
To create a segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist

Note You can’t schedule or publish a dynamic segment via the Data 360 user interface or by using the connect API. Run a dynamic segment by using an API call via [broadcast flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_broadcast_flow.htm&language=en_US) and provide dynamic values at runtime.
1. In Data 360, click **Segments**.
2. Click **New**.
3. Select **Use a Visual Builder**.
4. Select **Dynamic Segment**, and click **Next**.
5. Enter the segment details.
1. Select a data space.
2. For Segment On, select the DMO that your segment is built on.
3. Give your segment a unique name that’s easily identifiable.
4. Enter the lookback period for your segment.
The default is 90 days. You can set the lookback up to 2 years. If you select Days from the dropdown, you can set a period of up to 360 days.
When creating a segment, the lookback options are based on your organization's maximum allowed period, for example, up to 2 years. This setting defines the initial data range you can select. When you're in the segment, you can apply specific criteria in a container, which can differ from the default lookback period. So, if the segment-level lookback is set to 90 days and the container criteria specifies 60 days, the container criteria takes precedence, and data is pulled for only 60 days.
6. Click **Save**.
# Create a File Storage Activation Target
Create an activation target in Data 360 to publish segments and batch data model objects (DMOs) to external file storage activation platforms like Amazon S3, SFTP, Google Cloud Storage (GCS), or Microsoft Azure blob storage.
### Required Editions
User
Permissions Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Prerequisites:
- As an admin, configure connection to your file storage target in Data 360. See, [Data Target Configuration in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_target_configuration_in_data_cloud.htm&type=5&language=en_US).
- **S3 (Legacy)**: Have your access key and secret key ready. Ensure the S3 credentials have these permissions: PutObject, GetObject, ListBucket, DeleteObject, and GetBucketLocation. It is recommended to enable Server-Side Encryption (SSE-S3). Learn more about [enabling SSE-S3 encryption](https://docs.aws.amazon.com/AmazonS3/latest/userguide/default-bucket-encryption.html).
- **Amazon S3**: Provide Modify/Write permission for the folder or directory where the activated files reside.
- **SFTP, GCS, Microsoft Azure**: Provide Rename permission in the target system for the activated files and Modify/Write permission for the folder or directory where the activated files reside.
1. Go to the Activation Targets tab and click **New**.
2. In File Storage, choose your activation platform, and click **Next**.
Note: A file storage target is present only if its respective target connection is set up. For more information, see [Data Target Configuration in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_target_configuration_in_data_cloud.htm&type=5&language=en_US).
3. Enter a unique name and an optional description.
4. Configure your activation target platform-specific settings:
- S3 (Legacy)
1. Enter the S3 bucket and folder details.
2. Provide the S3 Access Key and Secret Key.
3. Select the target file format.
4. Select the data space you want to associate your activation target with and click Save.
- Amazon S3, SFTP, GCS, and Microsoft Azure Blob Storage
1. Select the connector, the data space, and click Next.
2. Parent Directory: Inherited from the target connection setup. It is mandatory to have a non-root parent directory. For more information, see [Data Target Configuration in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_target_configuration_in_data_cloud.htm&type=5&language=en_US).
3. Child Directory: The directory name is case-sensitive. For SFTP, GCS, and Azure targets, the child directory you provide must already exist in the target location, because Data 360 doesn’t create a directory if it’s missing. For Amazon S3 targets, you can enter any value for the child directory, and Data 360 creates the folder during the activation process if it’s missing.
- Create a folder within child directory: If selected, activated files are added to a separate folder. The folder name uses `` for segment-based activations and `` for non-segment activations. If not selected, files remain in the child directory. The system automatically replaces folder names containing any character (except alphanumeric and underscore) with a hyphen (-). Folder names are limited to 200 characters if exceeds 200 characters, with any additional characters automatically truncated.
4. File Format: Select the activated file format and delimiter for CSV files.
5. Compression Format: Select the compression format for the activated file. PGP encryption is supported only for CSV and JSON, but not Parquet.
6. File Name Type: Select **Predetermined** or **Custom** file name. For predetermined file names, any characters (except alphanumeric and underscore) in the SegmentName and ActivationName are replaced with a hyphen (-).
- If you select ``, the file name uses `` for all activation types.
- If you select ``, non-segment activations use `` as the file name.
- If you select ``, non-segment activations use `` as the file name.
7. Data/Time Suffix: Select the file name suffix format, it represents the segment refresh timestamp in UTC format. The timestamp ranges from a specific date to milliseconds of the day.
8. Limit type: Activated data is automatically split into multiple files when configured limits are reached, such as maximum records per file (default: 100,000) or maximum file size (default: 500 MB).
For example,
- For an activation payload with 450,000 records and a 100,000 record limit, the payload is split into multiple files to ensure no single file exceeds 100,000 records.
- For an activation payload totalling 3 GB and a 500 MB limit, the payload is split into multiple files to ensure no single file exceeds the 500 MB size limit.

Note File splitting is non-deterministic, and the final number and size of output files may vary between runs based on data characteristics, file format, compression, encryption, and processing behavior.
5. Click **Save**. Your activation target is created.
#### See Also
- [_Salesforce Help_: File Name Examples for File Storage Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_file_name_examples.htm&language=en_US)
- [_External_: AWS Help: Setting default server-side encryption behavior for Amazon S3 buckets](https://docs.aws.amazon.com/AmazonS3/latest/userguide/bucket-encryption.html)
- [_Salesforce Help_: Create an Activation for File Storage Target](https://help.salesforce.com/s/articleView?id=data.c360_a_add_activation_target.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
# Create a Formula Field
When you create a Data 360 data stream, you can choose to generate more fields. These supplemental fields can be hard-coded or derived from other fields in the data stream.
Before you begin, refer to [Considerations for Formula Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_considerations_formula_fields.htm&release=264.0.0&type=5 "Refer to these considerations when creating formula fields in Data 360.") to understand the guardrails applicable for creating a formula field.

Note Formulas are refreshed during a full or incremental data stream refresh, and get recalculated only if a record has changed.
1. On the New Data Stream page, click **New Formula Field**.
2. Provide the following:
1. Field Label: The field label acts as the display name for a data stream field.
2. Field API Name: The field API name acts as the programmatic reference for a data stream field.
3. Formula Return Type: The data type corresponding to the newly derived field.
Options include: Text, Number, DataTime, Date, Email, Phone, URL, Percent, and Boolean.

Note The Salesforce connectors and Connector services don’t support these data types: Email, Percent, Phone, Boolean, and URL for the Formula Return Type.
3. Construct your formula in the syntax editor. Within the editor, you can reference a combination of:
1. Fields present in the data stream.
2. Free form text
3. Functions
4. Operators
4. Validate the constructed formulas using the formula testing panel:
1. Inputs: The panel displays all source fields referenced in your formula.
2. Text Boxes: Next to each referenced source field in the input, type in a sample value to evaluate the expression.
3. Test Button: To evaluate the expression that is returned based on the sample value inputs, click the Test Button.
4. Output: See the expected output value.
5. Click **Save**.
The formula expression gets added as a new field in the data stream. The formula is assessed for any syntax errors. Before you deploy the data stream, delete a formula expression field as an inline action.
- **[Considerations for Formula Fields in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_considerations_formula_fields.htm&release=264.0.0&type=5)**
Refer to these considerations when creating formula fields in Data 360.
- **[Supported Library Functions](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_library_functions.htm&release=264.0.0&type=5)**
In the Data 360 data library, you can choose functions and operators. You can nest functions.
- **[Supported Library Operators](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_library_operators.htm&release=264.0.0&type=5)**
Learn more about the supported library operators in the Data 360 syntax editor.
# Create a Hybrid Search Index with Advanced Setup
Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.
### Required Editions
User Permissions
Needed
To create a search index configuration:
Permission set:
Before creating a search index, review the Unstructured Data and Search Index Guidelines and Limits in [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&type=5&language=en_US) and search index considerations in the [Search Reference.](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.") Familiarize yourself with the concepts of chunking unstructured data, vectorization, and the chunk and index data model objects.
## Enable Agentforce for Generative AI Capabilities (Optional)
Some capabilities in search index, including image processing, enriched index, and LLM-based content processing and parsing require generative AI features available through Agentforce. If you want to use those capabilities, contact your admin to [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US) in your org. Enable Amazon Bedrock Models (Amazon and Anthropic) in Einstein Setup to use enriched indexing.
## Select a Search Type and Source Object
To get started specify the type of search you want to perform and select a source DMO.
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index** > **New**.
3. Click **Advanced Setup** > **Next**.
4. Select Hybrid Search for **Search Type**.
5. Select a data space and a source object.

Note A DMO that has mappings from one or more external DLOs can only be used as the data source if caching is enabled for all those external DLOs. For more information see, [Caching in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&type=5&language=en_US).
6. Click **Next**.
## Set Up Parsing and Visual Data Preprocessing
Next, extract and prepare text, metadata, tables, and images from unstructured documents for chunking.
LLM-Parsing and preprocessing options are available for PDF, HTML, DOCX, and PPTX file types from UDMOs and files attached to DMO records. These options aren't available for use with DMO records.
You cannot select both LLM-based parsing and LLM-based Visual Data Preprocessing options for a single search index. See [LLM-based parsing and preprocessing](https://help.salesforce.com/s/articleView?id=data.c360_a_llm_parsing_preprocessing.htm&release=264.0.0&type=5 "Use LLM-based parsing and preprocessing to extract and prepare text, metadata, tables, and images from unstructured documents for chunking.") for more information about these options.
With LLM-based parsing and LLM-based Visual Data Preprocessing you can override the default GPT-4o model to use any supported LLM that best fits your business needs and your content. You can only select LLMs that are approved for use by your admin. If your org admin turns off a model that is currently in use, your previously processed content remains accessible. However, Search Index will fail to process any further content. For more more information supported models, see [Search Index Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&type=5&language=en_US).
1. On the Parsing page, choose one of these options.
Default Parser Extract text with built-in settings. LLM-based Parser Extract all text, images, and other visual elements using an LLM. Docling Parser Extract text from tables, spreadsheets, slide decks. Understand document layouts using Docling Parser.
2. If you choose Default Parser, click **Next.**
3. If you choose to parse your documents using an LLM, complete these steps.
1. From the dropdown list, select the appropriate model.
2. Use the default prompt as is, or edit it for your specific use case.
It's highly recommended to customize the prompt for your use case and documents.
3. Click **Next**.
4. If you choose the Docling parser, click **Next**.
By default, additional pre-processing is turned-off. Optionally, enable image processing when you set up chunking strategies to parse images and complex tables.
5. If you chose the default parser, on the Preprocessing page, choose one of these options.
No Preprocessing Use parsed text and visual data as is. LLM-based Visual Data Preprocessing Capture context from visual data using an LLM. (Available only if you selected the default parser in the previous step.)
6. If you choose No pre-processing, click **Next**.
7. If you choose to pre-process your documents using an LLM, complete these steps.
1. From the dropdown list, select the appropriate model.
2. Use the default prompt as is, or edit it for your specific use case.
It's highly recommended to customize the prompt for your use case and documents.
3. Click **Next**.
## Set Up Chunking and Vectorization
Next, set up chunking for your data and select an embedding model to create searchable vectors for each chunk.
1. If your search index is on a DMO, on the Chunking page, select fields to chunk and the [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.").
1. To add or remove fields, click **Manage Fields** and save your work.
Search Indexes don't support date and datetime fields for chunking. Only numerical and text fields are available for chunking data.
2. (Optional) Update the chunking strategy and modify the settings.
3. If your search index is on a DMO of a Salesforce object with file attachments that you want to include, click **Include Attachments** and select the ContentDocumentVersion UDMO.
4. Add a file extension or set a chunking strategy based on the file type. To add a file extension for a new file type, click **Add File Extension**, and then optionally update the chunking strategy and modify the settings for an existing file type.
5. (Optional) To add additional fields to a chunk, select the **Prepend fields to each chunk** toggle and select a field from the list. You can add a maximum of two fields.
6. To enrich generated chunks with additional metadata, turn on the **Enrich Content Chunks** toggle.
7. Click **Next**.
2. If your search index is on a UDMO, add a file extension or set a [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.") based on the file type.
1. To add a file extension for a new file type, click **Add File Extension**. If you have images to process, add the JPEG, JPG, and PNG file extensions.
2. (Optional) Update the chunking strategy and modify the settings for an existing file type.
For image files with extensions, such as JPEG, JPG, or PNG, image processing is enabled by default. To include image processing for PDF files, turn on image processing.
If you selected LLM-based parsing or LLM-based visual data preprocessing in previous steps, image processing doesn't apply even if you turn it on.
3. (Optional) To add additional fields to a chunk, select the **Prepend fields to each chunk** toggle and select a field from the list. You can add a maximum of two fields.
4. To enrich generated chunks with additional metadata, turn on the **Enrich Content Chunks** toggle.
5. When you select the Docling parser, optionally, turn-on LLM-based image processing to parse images and complex tables using an LLM. For better data extraction with tables, select Section-Aware chunking. Section-Aware chunking processes tables optimally such as retaining the header information across table chunks. For more information on supported file formats see, [Docling Parser](https://help.salesforce.com/s/articleView?id=data.c360_a_docling_parser.htm&type=5&language=en_US).
3. If you have audio or video files to transcribe, click **Configure**, and in the transcription window, select the following:
1. Select the default transcription model from the dropdown.
2. To add a timestamp to each speaker entry, select **Include timestamp**.
4. Click **Next**.
5. On the Vectorization page, from the dropdown list, select an embedding model. If your search index includes images to process, select the [appropriate embedding model (beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5).
The model determines how Data 360 measures your unstructured data objects for semantic relevance when building search results.
6. Click **Next**.
## Configure Fields for Filtering and Ranking Factors
To enhance the precision and relevance of search results, specify fields that users can use to filter their searches.
1. On the Fields for Filtering page, optionally add fields from the Source object or related objects to provide more ways to filter a search. You can select up to ten filter fields.
Data 360 picks up the pre-filter fields when you generate vector embeddings. If you change the values in those pre-filter fields, Data 360 picks them up when you generate or refresh those vector embeddings. The cardinality of object relationship between the source object and the related object must be either 1:1 or N:1.
For example, if the indexed unstructured data includes case conversation transcripts, filtering on the Status field in the Case object can improve the relevance of semantic search results when searching the conversation transcripts.
2. Click **Next**.
3. (Optional) To better rank the hybrid search results, click **Add Ranking Factor**.
For example, you can select **RECENCY** as the ranking factor and choose the **LastModifiedDate** field in the DMO to rank the search results. For the object contributing to the ranking factor, you can select the object that the search index is built on or a related object. If you select a related object, select the field for the relationship.
You can add up to two ranking factors, recency of records and popularity of records.
## Review and Build the Index
1. Review the configuration and the target data model objects.
2. Click **Save**.
When you build the search index, Data 360 creates a hybrid search index for the data. Next, create a Retriever in the **AI Models** tab. Agentforce agents can use the search index with Retrievers in prompt templates.
#### See Also
- [_Salesforce Help_: Search Index Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.")
- [_Salesforce Help_: Search Index Grounding](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_grounding.htm&release=264.0.0&type=5 "To add your data to Data 360’s search index, you must first chunk it. Chunking break your data into meaningful chunks, and Data 360 turns those chunks into machine-readable vector embeddings.")
- [_Salesforce Help_: Manage Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_manage.htm&release=264.0.0&type=5 "Create, view, edit, and delete search index configurations.")
- [_Salesforce Help_: Ground with Retriever Augmented Generation (RAG)](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&type=5&language=en_US)
# Create a Marketing Cloud Account Engagement Data Stream
To begin the flow of data, create a data stream and then configure the connector in Marketing Cloud Account Engagement.
Before you start, [connect Account Engagement to Data Cloud](https://help.salesforce.com/articleView?id=mktg.mcae_data_cloud_add_business_units.htm&language=en_US).
1. In Data 360, go to the Data Streams tab and click **New**.
2. Select the Account Engagement data source, and click **Next**.
3. Select a business unit.
4. Select the type of data that you want to ingest.
5. Click **Deploy**.
6. In Marketing Cloud Account Engagement, configure the Data Cloud connector. To learn more, see [Configure the Data Cloud Connector in Account Engagement](https://help.salesforce.com/articleView?id=mktg.mcae_data_cloud_configure_connector.htm&language=en_US).
#### See Also
- [_Salesforce Help_: Using Account Engagement Data with Data 360](https://help.salesforce.com/s/articleView?id=mktg.mcae_data_cloud_use_cases.htm&type=5&language=en_US)
- [_Salesforce Developer_: Email Activity Mappings to Data 360](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_mcae_email_activity.htm)
# Create a Marketing Cloud Engagement Activation Target
To publish segments and batch data model objects (DMO) to Marketing Cloud Engagement business units, create an activation target in Data 360.
### Required Editions
User Permissions
Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activation Targets tab, click **New**.
2. Select **Marketing Cloud Engagement**, and click **Next**.
3. Enter a name and an optional description.
The name can’t be more than 128 characters, start with an underscore, be all numbers, or include these characters: @ %^ = < ' \* + # $ / \\\\ ! ? ( ) { } \[ \] , . \\ \\
1. Select the data space you want to associate your activation target with.
Data spaces associated with each business unit (BU) based on the Data Streams setup, where each BU mapped to one or more data spaces are displayed. This means data from multiple MCE orgs (EIDs and BUs) can be combined within the same data space. A warning is shown to indicate the risk of records from different EIDs being merged into the same data space.
2. Click **Next**.
4. Select a Marketing Cloud Connection and include the required business units from the available list.
5. To add or remove business units to receive the published segments or DMOs, click the arrows between the two columns.
When an activation target has multiple BUs, the activation filters the contacts by the BUs. The segment activates as a Shared Data Extension (SDE) and not as a Data Extension (DE) to Engagement. If an activation target has multiple business units configured, modify the activation target configuration to include one business unit only.
6. Click **Save**.
- **[Ensuring Integrity in Marketing Cloud Engagement Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_data_mixing_multieid.htm&release=264.0.0&type=5)**
When multiple Marketing Cloud Engagement (MCE) orgs (EIDs) are involved in an Activation, unintended data mixing can occur. This happens when subscriber keys from different EIDs are brought into the same data space and are later activated to a specific EID, which can cause data integrity issues.
#### See Also
- [_Salesforce Help_: Create a Marketing Cloud Engagement Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
# Create a Marketing Cloud Engagement Data Action Target
Send automated emails and journeys to customers based on behavioral or transactional event data routed from Data 360. Trigger emails and journeys to customers from data model objects (DMOs) and calculated insights. For example, a customer purchases an item and searches for “installation manual” on your website. You trigger an event that sends the customer an email with a how-to video or installation instructions.
### Required Editions
User Permission Sets
Needed
To create Marketing Cloud Engagement data action targets:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Before you create a data action target, complete these prerequisites.
- Set up the Marketing Cloud Engagement connection in Data 360.
- Create the email template in Content Builder through Email Studio, and complete all mandatory fields. Use a template-based, text-only, or HTML email type.
- The subscriber list in Marketing Cloud Engagement includes the subscriber key, first and last names, and email address.
- Create a data extension for Journey Builder API Events of a data action with a single click in Data 360 without navigating to Marketing Cloud. To learn more, see [Create a Data Extension in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_extension_in_data_cloud.htm&language=en_US). Or, to manually create the data extension in Marketing Cloud, ensure that you first create the intended journey in Journey Builder for the API Event.

Note The journey entry source must be an API Event type, and all fields in its data extension must be nullable. The data extension attribute names for a primary object and related object must start with the object API name of the data model object that you selected in Data 360, followed by an underscore, and the attribute API name. For example, Shopping\_Events\_\_dlm\_deviceId\_\_c or Individual\_deviceId\_\_c. You can use the same data extension for primary and related objects. If you have multiple data actions that use these objects, reuse the data extensions.
- Select the business units, and enable the mapping in Data 360.
1. In Data 360, go to the Data Actions Target tab, click **New**.
2. Enter the data action target name.
The API Name field is automatically populated.
3. For the data action target type, select **Marketing Cloud**.
4. Select the business unit where the subscriber is present.
If multiple Marketing Cloud Engagement instances (EIDs) are connected to a Data 360 org, the business unit list shows all associated business units.
5. For the destination, select either **Email** or **Journey Builder API Event**.
6. Select the email template or Journey Builder API Event that you want to send when the data action conditions are met.
If you don’t select the Journey Builder API Event, the status of the data action target and any corresponding data action is set to draft. To set them to active, use the automated way of [creating a data extension](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_extension_in_data_cloud.htm&release=264.0.0&type=5 "Quickly create a data extension for Journey Builder API Events of a data action directly in Data 360. This automated process removes the need to go to Marketing Cloud Engagement.") for the data action within Data 360 and select the Journey Builder API Event for the data action target.
7. To filter subscribers, select **Send events only to subscribers of the selected business unit**.
Select this option if you don’t want to send an email template or journey to a subscriber whose subscriber key isn’t mapped to the selected business unit but is available in the parent business unit in Engagement.
8. Click **Save**.
If you modify an existing email template and want to send another email, create another data action target with the updated email template.
#### See Also
- [_Salesforce Help_: Set Up Marketing Cloud Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_marketing_cloud_connection.htm&release=264.0.0&type=5 "After you create your Data 360 instance, control the scope of data ingestion and activation from Marketing Cloud Engagement and other sources. Before integrating with Data 360, make sure that your Engagement user’s default business unit (BU) is set to the Enterprise ID (EID). Set up your data sources to tell Data 360 where to pull data from, also known as ingest, for data mapping and segments. You can connect multiple EIDs to a single Data 360 org, where each EID has its own connection to Data 360. For each of these connections, you can set up multiple data streams using data bundles or data extensions. Each connection also has its own business unit-to-data space mapping configuration. Data 360 supports only Engagement Enterprise 2.0 account connections.")
# Create a Marketing Cloud Personalization Activation Target
To publish segments to Marketing Cloud Personalization (formerly Interaction Studio), create an activation target in Data 360.
### Required Editions
User Permissions
Needed
To create an activation target
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activation Targets tab, click **New**.
2. Select **Marketing Cloud Personalization**, and click **Next**.
3. Enter a unique, easily recognizable name.
1. Select the data space that you want to associate your activation target with.
2. Select an organization.
3. Select the dataset.
Organizations and datasets are only available if they’re associated with the selected data space and haven’t already been used together.
4. Click **Save**.
Your Marketing Cloud Personalization activation target is created.
#### See Also
- [_Salesforce Help_: Data 360 Activation ETL Data Feed](https://help.salesforce.com/s/articleView?id=mktg.mc_pers_etl_activation_data_feed.htm&type=5&language=en_US)
# Create a Marketing Cloud Personalization Data Stream
To begin the flow of data from a Marketing Cloud Personalization (formerly Interaction Studio) starter bundle, create a data stream.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:
To create data streams from a Marketing Cloud Personalization starter bundle, first set up a connection to Marketing Cloud Personalization by completing the steps outlined in [Set Up a Connection to Marketing Cloud Personalization](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_interaction_studio_connector.htm&release=264.0.0&type=5 "After you create your Data 360 instance, connect to Marketing Cloud Personalization (formerly Interaction Studio) to enrich customer profiles with user profile data and events.").
1. Navigate to the Data Streams tab.
2. Click **New**.
3. Select the Marketing Cloud Personalization data source (**Interaction Studio**) in **Connected Sources**.

Important Select your datasets while setting up a connection to see Marketing Cloud Personalization as a Connected Source.
4. Click **Next**.
5. To ingest data for the stream, choose your desired Marketing Cloud Personalization dataset.
6. Name your dataset and create a unique Selection ID Suffix. The suffix is a way to indicate that all data streams created by this bundle came from the chosen dataset.
7. Click **Next**.
8. Multiple new data streams are created from your chosen dataset. Review the proposed data stream names. To edit the data stream names, click the pencil icon.
9. Click **Deploy**.
Your Marketing Cloud Personalization data streams are deployed. User profile and engagement data are ingested from the point of creation onwards, not historically. Existing user profiles in Marketing Cloud Personalization are ingested as new engagement events happen for these profiles.

Note When Marketing Cloud Personalization sends two updates to Data 360 in close succession, the connector assigns an order based on the arrival time. Sometimes, this can result in an unexpected sequence. This is an uncommon scenario, as it's rare for multiple copies of a profile to be sent in such close proximity.
# Create a Microsoft Azure Container SAS Token
Container Shared Access Signature (SAS) tokens give access to files in your Microsoft Azure Storage container.
To create SAS tokens:
1. Sign in to the Microsoft Azure portal and go to your Azure Storage account.
2. In your Microsoft Azure container, from Settings, click **Shared access tokens**.
3. Create a SAS token with these settings.
- Signing Method - Account Key
- Required Permissions - read, write, list, delete, tag. To add the tag permission, generate the token using the [Azure Storage Explorer](https://azure.microsoft.com/en-gb/products/storage/storage-explorer/) app and follow the steps in [Get the SAS for a blob container](https://learn.microsoft.com/en-us/azure/vs-azure-tools-storage-explorer-blobs#get-the-sas-for-a-blob-container). Refer to the See Also section for more information on the permissions supported for each resource type.
- Allowed Protocols - HTTPS only
4. Copy the Blob SAS Token and Blob SAS Url. They’re used in [Set Up a Microsoft Azure Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_a_microsoft_azure_target_connection.htm&release=264.0.0&type=5 "After you create your Data 360 instance, you can set up a Microsoft Azure Blob Storage Connection.")
We recommend that you regenerate the SAS token before expiry to avoid invalid credential errors when connecting to Data 360. Data 360 Azure Storage Service Connector doesn't support Azure account or Azure file tokens.
#### See Also
- [_External_: Permissions for a directory, container, or blob](https://learn.microsoft.com/en-us/rest/api/storageservices/create-service-sas#permissions-for-a-directory-container-or-blob)
# Create a MobilePush Journey in Marketing Cloud Engagement
With the data extension located and content reviewed, Cumulus can now build the Push campaign.
You can build this campaign in Journey Builder.
1. In Marketing Cloud Engagement, go to **Journey Builder**.
2. Click **Create New Journey**.
3. Select **Multi-Step Journey** and then click **Create**.
4. For the entry source, drag a **Data Extension** activity to the canvas.
5. To select the Gold Status data extension, click **data extension activity** and then **Select Data Extension**.
6. Drag the **Push Notification activity** to the canvas.
7. Click **Push Notification activity** and add the activity name, Gold Status, and the description, Gift Card Offer.
8. Click **New Message.**
9. Add the title Congrats, %%=v(@First\_Name)=%%!! and the subtitle Receive a $100 Gift Card.
10. Add the message with SSJS scripting.
```html
Congrats, %%=v(@First_Name)=%%!! You have recently reached
%%=v(@loyalty_tier)=%% status for
%%=v(@program_name)=%%. To thank you for being such a loyal member
with us, we're giving you a $100 gift card for your favorite delivery service!
```
11. For Open Behavior, select **Open the App** so that the customer can view the gift card within the Cumulus app.
12. Preview the message and then click **Save**.
13. On the Message Configuration tab, select the Cumulus app from the dropdown.
14. Click **Summary** to review the information, and click **Done**.
15. Review the wait steps, and click **Save**.
16. To ensure that all information has been completed, click **Validate**.
17. Test the journey and the check **Activate** when ready.
The campaign is ready for customers.
# Create a Model Configuration
After you add a foundation model, you can create an associated model configuration for a specific use case.
1. In AI Models (formerly Einstein Studio), click **New Configuration**.
2. In the Model Playground, select **Create model**.
3. Select the foundation model that you want to use.
4. In Advanced Settings, define the hyperparameters that control your model’s learning process.
These values are important for training and influencing prompt responses.
- Temperature
Determines the creativity of a response with a value from 0 through 2. A lower value generates more consistent responses. A higher value (such as 0.7-0.9) generates more random responses. Specify a value based on how coherent or creative you want the generated text to be.
Only Anthropic models have this setting available for testing.
- Frequency Penalty
Discourages frequent use of the same tokens (words, phrases, or code) in a response. Specify a value from -2.0 through 2.0. To reduce repetition in the generated text, use a higher value.
- Presence Penalty
Encourages the use of different tokens in a response. Specify a value from -2.0 through 2.0. To include tokens that haven’t been used in the generated text, use a higher value.
5. Define your prompt settings.
- Go to the Prompt section, and click **Settings**.
- Specify the stop sequence and data masking for each prompt that you enter.
6. To start over and define your model configuration settings, click **Restore Default**.
7. To exit Model Playground and view your model on the Generative tab, click **Close**.
# Create a Model from Scratch
Create a model that uses historical data to predict future outcomes. Select and structure your data source and define the desired outcome. Then train the model to reveal predictive inferences and insights by using AI, machine learning, and statistical analysis.
### Required Editions
User Permissions Needed
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
Permission sets
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
To train a model, here are some data requirements to consider.
Requirement
Minimum
Maximum
Number of rows
400
20 million
5 million for the XGBoost algorithm
Number of variables (fields or columns)
3 (1 outcome variable plus 2 other fields)
50 with manual selection
350 with automatic selection. From these
fields, Autopilot considers only the 50 most relevant ones.
Using predictive models to generate inferences consumes Data 360 credits for billing. Learn more about how predictive AI impacts credit consumption in [Billing Considerations for Predictive AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_usage_inference.htm&release=264.0.0&type=5 "Predictive models in AI Models (formerly Einstein Studio) use Data 360 to ingest, query, and store data, and to create inferences. Using Data 360 services can impact the consumption of credits used for billing in these usage types.").
1. Choose Type
Based on your use case, select a binary, regression, or multiclass model.
2. Select Data
Select the source of data to train your model with. Einstein uses the data to train and test the model.
When selecting a data source, consider some guiding questions.
| Question | Guidance |
| --- | --- |
| What outcome (such as a KPI) do you want to predict? | Predictive modeling detects patterns related to three types of use cases: regression (continuous numbers), binary classification (two-value text outcomes), or multiclassification (from 3 through 10 possible outcomes). Ideal data candidates for predictive modeling often involve KPIs associated with large volumes of data and many business decisions. |
| Which variables do you want to include? | Deciding which variables to include impacts the quality and interpretability of a predictive model. When variables are meaningful and relevant, it becomes simpler for stakeholders and business users to understand the relationships between factors and trust the predicted outcomes. |
| Where can you find this information? | Understanding where the data comes from is valuable in assessing quality, identifying bias, and adhering to data governance and compliance. |
3. Select Training Data
Use all records in the data source to train the model. Or, specify conditions to restrict the records used to train the model.
1. To select a specific subset of data to train the model, click **Filtered Set of Records**.
2. Define your filter condition.

Important
Filter your training set to use less than 20 million rows.
Logic
Description
Condition Requirements
All Conditions Are Met—if all conditions are true, the filter is applied.
If one of the conditions is false, the filter isn’t applied.
Any Condition Is Met—if one condition is true, the filter is
applied.
Field
Based on the data source. The data attribute or variable to use when
applying the filter.
Operator
Defines the relationship between the field and condition. The available
operators depend on the field type.
Value
Specific value to assess the field. For text fields, select one or
multiple values. For numeric fields, enter a value. For date fields, use the
calendar to select a date.
4. Set Goal
Select a business problem that you want to solve. Examine the key performance indicators (KPIs) you want to improve. Explore which candidate KPIs can benefit the most from deploying an AI-powered solution.
1. Select the field that you want to predict values for. Decide which outcome variable you want to explore, and at what granularity. The outcome variable can be a KPI value (such as revenue, discount, cost measure, or duration) or other quantifiable outcome. You can also use categories (text fields) with two values (binary) as an outcome variable.
2. Choose whether to maximize or minimize your goal. Model Builder builds and trains a model to optimize the outcome variable accordingly. For example, you can maximize net margin or minimize customer churn.
5. Prepare Data
Select what fields to include as the model's variables. Make sure that the variables are relevant to the prediction outcome you want. Refine data to provide better results by using variables that are accurate, complete, and representative of real-world business operations in terms of volume and diversity. Don’t use fields that contain sensitive data or personally identifiable information (PII).
Some fields that are available when you select a data source might not be available as model variables during data preparation. Model Builder automatically reviews the fields in your data and can exclude fields that aren't suitable for model training.
A field can be excluded for these reasons:
- **Constant values:** Fields with the same value (no variation), or that are entirely empty, are excluded because they don't provide useful predictive information.
- **Missing values:** Fields with a high proportion of missing values can be excluded.
- **No data available:** This can occur if data hasn't finished populating, such as when a data transform is still running. Fields with no data are excluded.
- **Identifier fields:** Fields whose values are mostly unique, such as customer IDs, record IDs, email addresses, URLs, or phone numbers. These fields are excluded because they don't provide useful predictive information.
- **Free-text fields:** Text fields that can't be converted into model variables, such as unstructured notes, can be excluded.
- **High-cardinality fields:** Text or categorical fields in which most values are distinct can be excluded because they can behave like identifiers.
- **Low variance:** Numeric fields with little variation can be excluded.
- **Redundant fields:** Duplicate or highly correlated fields can be excluded when they provide little additional information.
- **Aggregate fields:** Aggregate fields aren't supported as model variables. As a result, they’re unavailable during data preparation.
The number of fields and filtering depend on the training mode. Standard supports fewer fields, while Autopilot supports more candidate fields and performs automated variable selection.
6. Select Algorithm
The algorithm is the approach, or the computational procedure, the model uses to learn from the data and make predictions. You can also turn on **Automatic Selection**, so Model Builder can automatically select an algorithm with the highest impact on your prediction and use case.
1. Choose the algorithm for your model.
| Algorithm | Description |
| --- | --- |
| **GLM** | Default. Generalized Linear Model (GLM) is an equation-based algorithm that typically completes quickly. It works best when the relationship between the variables and the outcome is relatively simple. Only GLM can produce explanations based on the interaction between variables, such as the combined impact of region and month together. |
| **GBM** | Gradient Boosting Machine (GBM), is a tree-based algorithm where the decision trees are built sequentially to better fit the data. It handles data complexity such as different relationships between variables and varied data distributions better, compared to GLM. |
| **XGBoost** | Extreme Gradient Boosting (XGBoost), is an extension of GBM that’s optimized for efficiency. It's a tree-based algorithm where groups of decision trees are built sequentially to better fit the data, while avoiding overfitting. |
7. Review and Train
Train your model after reviewing the details.
1. Review the details of the model. Optionally, click the pencil icon to edit a step.

Note
You can edit all steps when creating a model. After you create the model, you can't edit steps such as: Choose Type, Select Data, and Set Goal.
2. Click **Save** to enter a name and an optional description for your model, and click **Save & Train** to create the model.
Model Builder analyzes your data and trains the model based on your settings. Model creation takes time, and you can track its progress as it builds.
After the model is created, you can find it in the Predict section in AI Models. See [AI Models Home](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_mm_manage_models.htm&type=5&language=en_US).
- **[Address Data Issues](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_common_data_issues.htm&release=264.0.0&type=5)**
Handle common issues that you can encounter when you prepare data for model building and after you train a model.
- **[Apply Transformations to Your Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_use_transformations.htm&release=264.0.0&type=5)**
Transform modeling data to improve the reliability, accuracy, and explainability of predictions. For models created from scratch, Model Builder automatically transforms unstructured text and replaces missing data. You can also manually transform variables in binary or regression models.
# Create a Nested Segment in Data 360
Reuse filters and maintain consistency in your data by using an existing segment built on profile objects to build a new nested segment. A nested segment is a combination of an outer segment and inner segment. Each nested segment can have up to 50 filters in each tab.
### Required Editions
Permission Sets
Needed
To create a nested segment:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In the segment canvas, click the **Segments** tab.
The list shows the segments that you can nest. You can’t nest dynamic segments and segments in error or inactive state, so they aren’t listed.
2. Click the segment that you want to reuse. You can view the description next to the segment name.
You can’t use an outer nested segment as an inner segment, and the inner and outer segments must be in the same Segment On entity. If you edit the rules of an inner nested segment, the changes are applied to all the outer segments attached to it.
3. Click **Edit Rules**.
4. Drag your segment to the canvas.
You can open the segment in a different tab to review its content by clicking the arrow icon next to the segment’s name.
5. On the Include or Exclude tab, select the publish behavior.
1. **Use Last Published Membership**: Use the segment population from the most recent publish of the child segment.
This option is recommended when:
- The segment contains complex, computationally intensive logic.
- You prefer improved performance over real-time freshness.
- The child segment’s data is relatively stable and refreshed at predictable intervals.

Note Ensure the child segment is published at least once. Its population doesn't refresh with the parent segment's publish schedule.
2. **Use Segment Criteria**: Copy the filter criteria of the child segment into the parent segment.
This option is recommended when:
- Real-time updates are critical, and changes in the child segment must immediately reflect in the parent segment.
- The child segment’s filters are simple, as the parent segment’s total filter limit (50 filters per tab) includes both child and parent filters.

Note For rapid segments and segments that use grouping, ranking, and limiting rules, only the Last Published Membership option is available. The Segment Criteria option isn’t supported for these segment types.
6. Click **Done**, and then click **Save**.
# Create a Permission Set for a Related List Enrichment
Control which users can see a related list enrichment by assigning them to a permission set that has access to the Data Cloud data space.
### Required Editions

Important Queries that Salesforce users make against Data Cloud data can impact your billing. Before you enable broad access, review your Data Cloud allocation and usage.
User Permissions
Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To create or update enrichments:
Customize Application
To view the related list
You have access through the Data Cloud.
User permission set to the data
space
Object Permissions
Needed
To view enrichments in Object Manager:
Data Model Objects object Read permissions
To create or update enrichments:
Data Model Objects object Create, Update, and Delete
1. Create a permission set, or use an existing permission set. In policy-based governance orgs, any cloned or custom permission set must be manually enrolled in the data governance policy via **Data Cloud Setup –> Data Space Management** after creation.
2. Give your permission set access to the data space that your enrichment queries data from.
1. In your CRM org, in Setup, search for and select **Permission Set**s.
2. Select a permission set.
3. For Apps, select **Data Cloud Data Space Management**.
4. Under Data Spaces, click **Edit**.
5. Enable the data space that your enrichment queries data from, and click **Save**.
3. Allow controlled by parent queries.
1. Select your permission set.
2. For Apps, select **Data Cloud Data Space Management.**
3. Select the data space.
4. Under User Data Access Level for This Data Space, select the options to allow controlled by parent access.
5. Save your work.
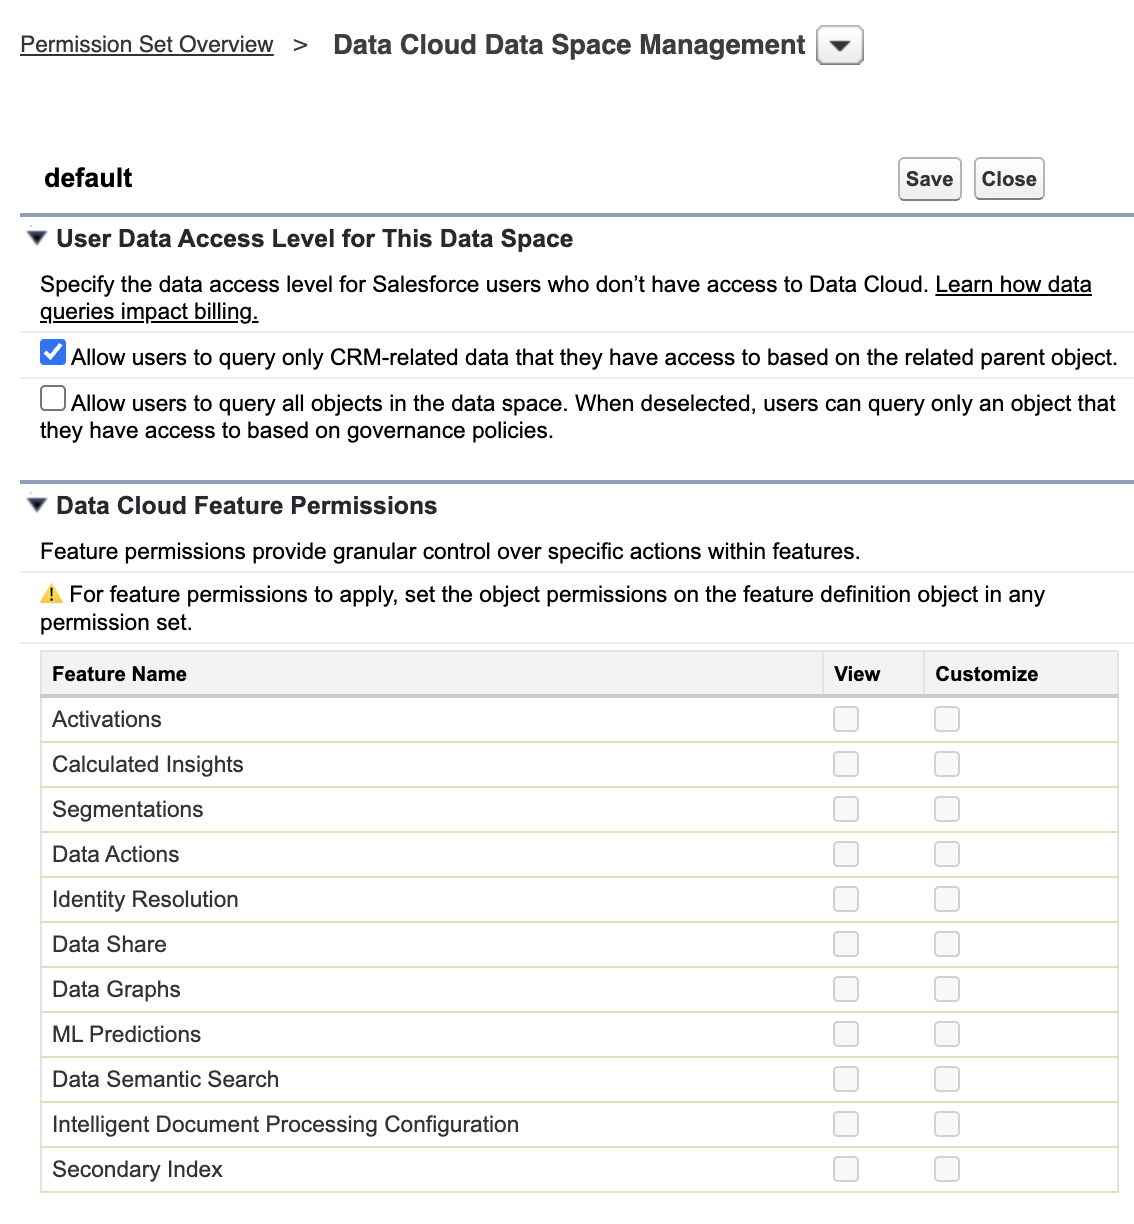
4. Assign your permission set to users so that they can view your related list.
# Create a Platform Event-Triggered Flow
Automate your business process and launch a flow internally when a data record changes. A flow collects data and performs actions in Salesforce or an external system.
### Required Editions
1. From **Setup**, in the Quick Find box, enter Flows, and then select **Flows**.
2. Click **New Flow**.
3. Select **Start From Scratch**, then click **Platform Event - Triggered Flow**, and then click **Create**.
A platform event-triggered flow runs when an event message is received.
4. For the platform event, select **Data Object Data Change Event**.
5. Click **Add Element**, and then click **Create Records**.
6. Enter the label, API name, and description for your record.
7. For How to set record field values, select **Manually**
8. From the Object dropdown, select your custom object.
9. Set the field values for your custom object.
10. To prevent duplicate records, turn on Check for Matching Records.
11. Add conditions and specify what happens when matching records are found.
12. Click **Save**.
13. Enter the flow label and flow API name.
14. Click **Save**.
Click **Activate** to activate the flow after building it.
#### See Also
- [_Salesforce Help_: Build a Flow](https://help.salesforce.com/s/articleView?id=platform.flow_build.htm&type=5&language=en_US)
- [_Salesforce Help_: Data Actions in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_actions_cdp.htm&release=264.0.0&type=5 "Monitor data changes in data model objects and calculated insight objects in Data 360, and send the change data events to the Salesforce Platform Event, Marketing Cloud Engagement, Webhook, or Amazon Kinesis targets.")
- [_Salesforce Help_: Data Action Targets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_action_target_in_customer_data_platform.htm&release=264.0.0&type=5 "The result of a data action is triggered in a data action target. The target receives the data action in near real time. You can send a data action to a target to drive event-based orchestration.")
- [_Salesforce Help_: Flow Types](https://help.salesforce.com/s/articleView?id=platform.flow_concepts_type.htm&type=5&language=en_US)
- [_Trailhead_: Build Flows with Flow Builder](https://trailhead.salesforce.com/content/learn/trails/build-flows-with-flow-builder)
# Create a Prompt Template
If you're satisfied with your model's response to one or more test prompts in Model Playground, create your prompt templates.
- In the Generative tab, go to your model, and click the action menu option to create a prompt template.
- From your model details, create your prompt template.
#### See Also
- [_Salesforce Help_: Create a Prompt Template](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_build_template.htm&type=5&language=en_US)
- [_Trailhead_: Prompt Fundamentals](https://trailhead.salesforce.com/content/learn/modules/prompt-fundamentals)
# Create a Real-Time Data Action in Data 360
Create a real-time data action to send an alert or an event and get responses in real time. Use a real-time data action to focus on real-time events and insights at different levels, such as the channel, product, account, service, or individual level.
### Required Editions
User Permissions Needed
To create a real-time data action:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
To view, save, and activate an automation event-triggered flow with a custom real-time
data graph event as the trigger:
Data Cloud Architect
OR
All of these permissions:
Manage Flow
View Setup
View All Data
Data Cloud User
Create, read, update, delete, and View All on Data Action Targets, Data Action Target
Definitions, Data Actions, Data Action Definitions, Data Action Target Relations
Read on Data Model Object, Data Model Field, and Calculated Insights Object
1. In Data 360, on the Data Actions tab, click **New**.
2. Choose Real-Time Data Action, and click **Next**. You're redirected to the Flows page.
3. Create an automation event-triggered flow with the event **Custom Real-Time Data Graph Event**. See [Create an Automation Event-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_automation_event_triggered_flow.htm&language=en_US).
Automation Event-Triggered Flow is available only with Salesforce Foundations enabled. Contact your account executive for more information.
# Create a Real-Time Insight Using Builder
You can create real-time insights with a real-time data graph and related data model objects (DMOs). A related DMO is a DMO not defined in the real-time data graph but can be used as a real-time dimension.
### Required Editions
User Permissions
Needed
To create a real-time insight:
Permission set:
1. In Data Cloud, go to the Calculated Insights tab, and click **New**.
2. Select the data space your source data graph lives in.
3. Click **Real-Time Insights**.
4. Click **Use Visual Builder** and click **Next**.
5. Click **Select an Object**.
6. If your Insight includes currency fields, select the **Insight Currency** value at the top of the page.
7. Select a real-time data graph as your input data and click **Next**.
8. (Optional) Add a relative time filter to display data based on a period relative to the current date and time.
1. Select the **DateTime** field to configure your start time.
2. Choose the **Relative DateTime** operator.
3. Select **Interval**.
4. Enter the Interval value. See [Define Relative Time-Window Metrics](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_relative_time_metrics.htm&release=264.0.0&type=5 "Get real-time Data Cloud insights with metrics based on rolling time windows. Determine metrics using relative timeframes, such as a specified number of past seconds, minutes, or days.") and [Working with Nodes in Visual Insight Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_working_with_nodes_in_builder.htm&release=264.0.0&type=5 "Visual Insight Builder uses a low-code, drag-and-drop interface to simplify the creation of streaming, calculated, and real-time insights. Visual components replace complex code, allowing you to develop metrics and expressions, regardless of technical expertise.").
9. Add measures and dimensions to your insight by clicking **Aggregate**.
You must select at least one measure.
1. Under Measures, click **+**.
2. Select a metric function and the field that you want to calculate, and then click **Next**. Only Sum and Count are supported for real-time insights.
3. Enter the metric name, and click **Apply**.
4. Under Dimensions, click **+**.
5. Select the field that you want to group by, and click **Next**.
To select a related DMO, toggle **Show related fields**.
6. Enter the dimension name, and click **Apply**.
7. Click **Next**.
8. Name the metric and click **Apply**.
9. To save the aggregate node, click **Apply**.
10. Name the insight. The Insight API Name field is auto-filled. Click **Save and Enable**.
# Create a Real-Time Segment
Create a real-time segment that completes on demand in milliseconds. To make the segment available in your real-time data graph, add the Segment ID and Timestamp fields from the segment membership DMO object to the real-time data graph. You can’t use a real-time segment with exclusion criteria and nested batch segments. You also can't use segment counts and manual publish with a real-time segment.
### Required Editions
User
Permissions Needed
To create a real-time segment
Permission set:
1. In Data 360, click **Segments**.
2. Click **New**.
3. Select **Use a Visual Builder**.
4. Select **Real-Time Segment**, and click **Next**.
5. Enter the segment details.
1. Select a data space.
2. Give your segment a unique name that’s easily identifiable.
3. Select the real-time data graph to build the segment on.
6. Click **Save**.
#### See Also
- [_Salesforce Help_: Create a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_graph.htm&release=264.0.0&type=5 "Before creating a data graph in Data 360, decide which existing data model object (DMO) to use as the primary DMO. The primary DMO determines which related objects you can include in the data graph.")
# Create a Record-Level Policy in Data 360
Define who can access specific records within an object based on user and data attributes.
### Required Editions
Before completing this task, review these considerations.
- When you create a record-level security policy (RLS) on a DMO or a calculated insight object, the policy applies only to the data space where the object is available. This is because the API name includes the data space prefix, and policies are authored based on this API name.
- If an RLS with Join policy uses a masked field as the join key, the join operates on the masked value, which can lead to inaccurate results. Avoid using masked fields in RLS with Join queries.
- Unmask primary key and foreign key fields to maintain accurate object relationships and effective data joins.
- RLS policies aren’t enforced when creating segments and calculated insights because these operations run in system context.
- Currently, the RLS policy filters records only for users who meet the policy criteria. Other users see all records because the default Day 0 Allow All object-level security (OLS) policy remains in effect. In an upcoming change, any RLS permit policy disables the Day 0 Allow All policy. Users who don’t meet the RLS criteria lose access to all records governed by the RLS policy. For example, if an RLS policy grants access only to US Opportunity records, users without the required permission no longer see any Opportunity records after this change.
- Hierarchy data is synchronized periodically. It can take up to 15 minutes for changes in the source system to be reflected in Data 360.
- Index custom user fields before using them in policies for optimal performance.
User Permissions Needed
To create a data access policy:
Permission set:
1. In Data 360, go to the Data Governance tab.
2. In the left pane, click **Policies**.
3. Click **New**, select **Data Access**, and click **Next**.
4. In Policy Builder, enter a unique policy name, and an optional description.
The policy API name is auto-filled based on your policy name, but you can change it.
5. Select the user authorization level. For more information, see [Controlling External User Access in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_control_external_user_access.htm&type=5&language=en_US).
6. Click **Next**.
7. Select **Rules**, and select the resources to protect. In the **Resource** dropdown, select **Record**.
By default, the rule applies across all data spaces. As new data spaces are added, these rules apply to their resources.
8. To restrict policies to specific data space scopes, click **Customize Scope**, deselect **Apply to the resources in all Data Spaces in Data Cloud**, and select the desired data spaces.
9. Click **Save**.
10. Select the action you want to take on the resource. From the Action dropdown, select **Allow access** or **Deny access**.
11. Define the conditions when this action must take place. For example, allow access when **Account.Country** equals **United States**. Or, allow access when **Opportunity.OwnerId** equals **$User.Id**. Trigger the rule when objects meet any or all specified conditions.
Reference standard user attributes in resource conditions using the $User variable. Standard user attributes include:
- $User.CallCenterId
- $User.CompanyName
- $User.ContactId
- $User.Department
- $User.Division
- $User.Email
- $User.ProfileId
- $User.UserRoleId
- $User.Title
- $User.Id
- $User.OrganizationId
- $User.Username
12. To add a hierarchy-based rule, use the Hierarchy operator (Is Hierarchically Above In) and select the appropriate hierarchy, such as a manager, role, or territory hierarchy, to grant access. For example, allow a manager to view records owned by their team, while team members view only their own records. Or, users assigned to the North America territory can access records across all regions within North America, including the United States, Canada, and Mexico.
You must successfully ingest a hierarchy for it to appear as an option in the operator. To ingest hierarchical data, see [Ingest Hierarchical Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ingest_hierarchy_data.htm&release=264.0.0&type=5 "Bring Salesforce CRM organizational hierarchies such as Role, Manager, and Territory into Data 360. After ingestion, you can reference these hierarchies in hierarchy-based record-level security (RLS) policies.").
13. To add more conditions, click **Add Condition**. Add up to five conditions to a record-level security (RLS) policy.
14. Group your conditions into different sets and use the OR operator to act when any group meets the rule conditions.
15. To add a group, click **Add Group**.
16. Click **Add Join Block** to add a custom join block. Custom joins let access rules reference external mapping or lockup tables and enable dynamic and context-aware access conditions.
17. Select the objects and fields to be referenced by the rule.
18. To add more join sections, click **Add Join**. Add up to three joins.
To remove a join, click the delete button. If there are dependencies in the join, remove them before deleting a join.
19. To add filters and criteria for the join block, click **Add Filter**.
20. To apply the policy to users, select **Users**.
Apply the policy to all users or to users who meet specific AND and OR conditions. The conditions are based on custom permissions or standard user attributes assigned to users.
Standard user attributes include:
- Call Center ID
- Company Name
- Department
- Division
- Profile ID
- Title
21. To match multiple values, use the CONTAINS operator: `Department__c CONTAINS SALES_NW, SALES_SW, SALES_NE`
22. Related object fields are supported using relationship notation. For example: `AssignedBrands__r.BrandName__c equals GAP`
`Departments__r.DepartmentCode__c CONTAINS DEPT-001, DEPT-002`
23. Click **Save and Activate**.
# Create a Record-Triggered Flow in Data Cloud
Create a record-triggered flow to publish platform events of Data 360 actions. You can use the published platform event to resume your paused auto-launched flow. With a record-triggered flow, you can update another record, send a notification, initiate a process, or maintain data consistency. A record-triggered flow runs only when a record is created or updated. It can update a record 10 times faster than a record-change process.
### Required Editions
User Permissions Needed
To create record-triggered flow:
Permission set:
1. In Data 360, click , and select **Setup**.
2. In the Quick Find box, enter Flows, and select **Flows**.
3. Click **New Flow**.
4. Select **Start From Scratch**, then click **Record-Triggered Flow**, and then click **Create**.
5. From the Object dropdown, select the Data Cloud action that you want to publish custom events for.
6. Select **A record is created or updated**.
7. From the Condition Requirements dropdown, select **All Conditions Are Met (AND)**.
8. Define the condition. You can add more conditions as needed.
9. Select **Only when a record is updated to meet the condition requirements** and **Actions and Related Records**.
10. Click **Done**.
11. On the canvas, click **Add Element**, and then click **Create Records**.
12. Enter the label name and select **Use separate resources, and literal values**.
13. From the Object dropdown, select the custom platform event that you want to publish.
14. Select a field, and set values for your custom platform event.
15. Click **Done** and then click **Save**.
16. Enter the flow label, click **Save**, and then click **Activate**.
The record-triggered flow is triggered every time the record is updated and the conditions are met.
When the flow is triggered, the custom platform event is published. Resume your paused autolaunched flow with the published platform event.
# Create a Related List Enrichment
Add information from Data Cloud DMOs to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.
### Required Editions
You must have access as a Data Cloud user to use enrichments. You must have completed identity resolution and created a Unified Individual DMO or a Unified Account DMO.
User Permissions
Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To create or update enrichments:
Customize Application
To view the related list
You have access through the Data Cloud.
User permission set to the data
space
Alternatively, if you enabled enhanced security data spaces, in the user
permission set data access level for the data space, make sure to enable
‘controlled by parent’.
Object Permissions
Needed
To view enrichments in Object Manager:
Data Model Objects object Read permissions
To create or update enrichments:
Data Model Objects object Create, Update, and Delete
Read [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.") before starting this task.
You can create a related list for a DMO that is an Engagement type DMO with a single many-to-one relationship to the Unified Individual DMO or the Individual DMO by using a primary key of Individual ID or Unified Individual ID. For example, if you want to create a related list for all the email engagements for a lead, select Email Engagement as the object.
You can also create a related list for a Unified Contact Point DMO, such as Contact Point Email.

Note You must have completed Identity Resolution and have created a Unified Individual, even if you’re using a DMO that’s related to Individual.
1. From the Contact, Lead, or Account object management settings, select **Data Cloud Related Lists**.
2. Click **New**.
3. Click **Related List** and **Start**.
4. Select a **Data Space**. The data space determines the objects that you can create a related list for. Different data spaces have different views of the data available. For example, if each brand has its own data space, or if there are different data spaces for HQ reporting vs. customer-facing data.
5. Select a **Data Cloud Object**.
6. Enter a **Lookup Field** that identifies the ID used to retrieve matching records from Data Cloud. For example, if you want to retrieve records for an individual as a customer, you use the Customer ID field. If you want to retrieve records for an individual as a supplier, you use the Supplier ID field.
7. Click **Next**.
8. This step changes if enhanced security data spaces are enabled for your org:
- If enhanced security data spaces aren’t enabled, select **Enable Controlled by Parent Permissions** and click **Next**.
- If enhanced security data spaces are enabled, skip to the next step.
9. Enter a **Related List Label** that is displayed on the record page for your org object.
10. Select the page layouts that you want to add the related list to. The list is automatically added as the last field in the page, but you can drag it to the correct location in the page layout editor.

Note If you have person accounts enabled, you can also add the related list to a person account. See [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.").
11. Save your work.
If you want to filter the data shown in the related list, create a dynamic related list and add filter conditions. For example, if you want to make sure only data related to a specific data space is displayed in the related list, add that filtering condition in the dynamic related list.
 [Create a Permission Set for a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_permset.htm&release=264.0.0&type=5 "Control which users can see a related list enrichment by assigning them to a permission set that has access to the Data Cloud data space.")
**Supported Source and Target Objects for Related Lists**
You can create a related list enrichment on these target objects.
- Account
- Contact
- Lead
#### See Also
- [_Salesforce Help_: Enrichment Troubleshooting](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_troubleshooting.htm&release=264.0.0&type=5 "Diagnose issues with enrichments and fix them.")
- [_Salesforce Help_: Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.")
# Create a Role-Based Access Control Policy in Data 360
Manage object permissions for users asigned to a data space.
### Required Editions
User Permissions Needed
To manage objects and field permissions:
Permission set:
1. From Setup, in the Quick Find Box, enter Permission Sets, and then select **Permission Sets**.
2. Select a permission set.
3. Select **Data Space Management**.
4. Select a data space.
5. To manage access to the objects and fields in that data space, select **Manage Objects and Fields Access**.
6. Select the objects that the users can access with this permission set.
7. Click **Save**.
# Create a Salesforce CRM Data Stream
Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:
**Considerations**
- If the objects selected for the data stream support change events, Data 360 adds the selections to a Change Data Capture standard channel named DataCloudEntities. Make sure that you don't modify the selections for this standard channel in Metadata API or Tooling API. Updating the channel selections using the API can result in unexpected synchronizations of Salesforce objects that weren't intended by the Data 360 administrator. For more information, see [Change Data Capture](https://developer.salesforce.com/docs/atlas.en-us.change_data_capture.meta/change_data_capture/cdc_intro.htm).
- The Event object fields: Attendees, Email, and Phone aren’t supported because the value for these fields is retrieved from other objects.
- You can't ingest metadata from CRM when creating a CRM data stream.
- To process the data stream using the streaming process, the object must be included in the list of objects that support change events. See [StandardObjectNameChangeEvent](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_associated_objects_change_event.htm). Additionally, there are several scenarios in which streaming isn’t available and the processing mode changes to batch, as listed in [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.")
- Data 360 runs a query to verify that your data is accurate before starting the extraction process. If the validation process takes over 2 minutes, it stops automatically. The status updates to Failed, and Data 360 retries the validation.
- When creating a data stream, you can select multiple objects. For each selected object, a separate data stream is created. This feature is supported during deployment and redeployment, allowing you to add new source and formula fields, or to reconfigure data spaces. Multiple object deployment applies to the interface and does not affect other methods of CRM datastream creation, such as through the Connect API.
1. In Data 360, go to the **Data Streams** tab and click **New**.
2. Select the Salesforce CRM data source and click **Next**.
3. To create your data stream, select a Salesforce org.
If you have only one Salesforce org connected to Data 360, it’s selected by default.
4. Select the **View Objects** tab.
5. Select up to 30 Salesforce objects to include in the data stream and click **Next**.
6. Select an object category from the dropdown menu: Profile, Engagement, or Other. Refer to [Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.") to see considerations for each category.
7. You can change the **Data Lake Object Label** and **Data Stream Name**, but accept the default **Data Lake Object API Name**. Data 360 generates this name from the object API name and Connection Alias that you specify when you [Set Up a CRM Salesforce Org Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_crm_connection.htm&release=264.0.0&type=5 "A data source and data action target are automatically created for the org where you set up Data 360. To connect other Salesforce orgs, manually set up a connection.").
If you customize the DLO API name when moving data from a source org to a target org, Data 360 doesn’t preserve the customized name in the deployment. Instead, it creates the DLO in the target org with the system-generated API name. As a result, downstream components, such as data transforms, identity resolutions, and data space filters, can fail to deploy in the target org..
8. Review the objects and fields to include in the data stream and deselect the fields that aren't required.
By default, all fields for an object are selected. To allow the stream to be ingested in a faster streaming mode, exclude batch ingested fields. For periodic batch mode processing, leave them in. To learn more, see [CRM connector streaming considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.").
9. (Optional) Click **New Formula Field** and add these fields.
1. Field Label—the display name for a data stream field.
2. Field API Name—the programmatic reference for a data stream field.
3. Formula Return Type—the data type corresponding to the new field. The options are number, text, and date.
4. Transformation Formula— the calculation can include input from other fields in the same row or across rows.
10. Click **Next**.
11. Select a **Data Space**.
12. To determine which records in the DLO are available on the associated data space, you can click **Set Filter**, then **Add Filter**.
The filter doesn't prevent the ingestion of records from the connected data source or filter out records before they're ingested into Data 360. See [Understanding Data Space Filters on Data Streams](https://help.salesforce.com/s/articleView?id=002721752&type=1&language=en_US).
The refresh schedule is set by default. For more information, see [Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.").
13. Click **Deploy**.
You've now created a Salesforce CRM data stream. If you disable a field in the future, redeploy the stream to enable the field again. To create more data streams, repeat these steps.
- **[Disable or Re-enable Salesforce CRM Connector Data Stream Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_disable_or_reenable_data_stream_field.htm&release=264.0.0&type=5)**
Disable fields in a Salesforce CRM connector data stream to stop new data ingestion, clear existing data for that field, and remove it. If you need a field again later for a standard or custom data lake object (DLO), re-enable it. Give a new field a different name than any disabled field.
- **[Store or Remove Deleted CRM Connector Data Stream Records](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_store_deleted_data_stream_records.htm&release=264.0.0&type=5)**
Store soft deleted data stream records that have been in the Salesforce Recycle Bin for up to 15 days. To store deleted data stream records, create a Deleted Record data lake object (DLO). You can use this DLO to view your stored records and use them in Data 360. For example, you can use the Deleted Record DLO to store deleted contacts outside of your Recycle Bin. You can only store deleted records of structured data streams.
#### See Also
- [_Salesforce Help_: Disable or Re-enable a Salesforce CRM Connector Data Stream Field](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_disable_or_reenable_data_stream_field.htm&release=264.0.0&type=5 "Disable fields in a Salesforce CRM connector data stream to stop new data ingestion, clear existing data for that field, and remove it. If you need a field again later for a standard or custom data lake object (DLO), re-enable it. Give a new field a different name than any disabled field.")
- [_Salesforce Help_: CRM Connector Streaming Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.")
- [_Salesforce Help_: Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.")
- [_Salesforce Help_: Unsupported Objects and Object Types in CRM Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_unsupported_objects_types.htm&release=264.0.0&type=5 "When you create a Salesforce CRM data stream, the CRM connector doesn’t support the ingestion of all objects or object types from the connected CRM orgs. Use only supported objects and object types for your data stream.")
- [_Salesforce Help_: Manage Big Objects](https://help.salesforce.com/s/articleView?id=platform.custom_index.htm&type=5&language=en_US)
- [_Salesforce Help_: Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.")
- [_Salesforce Help_: Set Up a Salesforce Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_crm_connection.htm&release=264.0.0&type=5 "A data source and data action target are automatically created for the org where you set up Data 360. To connect other Salesforce orgs, manually set up a connection.")
# Create a Salesforce CRM Starter Bundle
Create a data stream using a starter bundle to begin the flow of data from a Salesforce CRM source into Data 360.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:

Note The data source objects: Phone, URL, Email, and Percent are not supported when creating a data stream using a starter bundle.
You can configure only one starter bundle at a time. If you don’t see the starter bundle you’re looking for, make sure that your Salesforce admin has provided permissions for the Salesforce objects.
1. Go to the Data Streams tab and click **New**.
2. Select the Salesforce CRM data source and click **Next**.
3. Select the Salesforce org where your data resides.
If you have only one org connected to Data 360, it’s selected by default.
4. On the Data Bundles tab, choose a starter bundle.
5. Review the list of Salesforce objects and their fields to be ingested.
6. Deselect any fields not needed in your data stream.
7. Click **Next**.
8. Review the list of objects and their fields, and click **Next**.
9. Review the list of data streams and click **Deploy**.
10. Click one of the data streams to review the field list.
11. To see how data lake objects (DLOs) are mapped to data model objects (DMOs), click **Review Mappings**.
You’re ready to start using your bundle data.
# Create a Salesforce Platform Event Data Action Target
Send a data action to the core event bus to build a flow application based on a trigger generated in Data 360.
### Required Editions
User Permission Sets
Needed
To create Salesforce Platform Event data action targets:
Permission set:
1. In Data 360, navigate to the Data Actions Target tab, and click **New**.
2. Choose to create a data action target from scratch or import from data kits and packages.
3. Enter the data action target name.
The Action Target API Name field is auto-filled.
4. Select **Salesforce Platform Event** for the target type.
5. Select a Salesforce Org.
6. Click **Save and Publish**.
When you send an event to Salesforce Platform using a data action, Data Cloud defines the standard event DataObjectDataChgEvent and uses it for publishing messages.
# Create a Search Index Configuration from a Data Kit
After you have deployed your data kit in Data 360, you can create a new search index configuration from a index it contains.
### Required Editions
User Permissions Needed
To create a search index configuration:
Permission set:
If the Object API name referenced in the data kit is available in the org where you create the search index, that object is automatically selected. If there’s no match for that Object API name, no object is selected. You can change this selection and choose a different object.
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index** > **New**.
3. Click **Data Kit Setup**.
4. Select a search index from your data kit.
5. On the Select Source DMO page, select a data space and an object.
A search index configuration is created for each object that you select. You can’t select an object that has mappings from one or more external data lake objects.
6. Click **Next**.
7. If your search index is on a DMO, on the Chunking page, select fields to chunk and the chunking strategy.
1. To add or remove fields, click **Manage Fields** and save your work.
2. (Optional) Update the chunking strategy and modify the settings.
3. Click **Next**.
8. If your search index is on a UDMO, on the Chunking page, add a file extension or set a chunking strategy based on the file type.
1. To add a file extension for a new file type, click **Add File Extension**.
2. (Optional) Update the chunking strategy and modify the settings for an existing file type.
3. Click **Next**.
9. On the Vectorization page, from the dropdown list, select an embedding model and then click **Next**.
The model determines how Data 360 measures your unstructured data objects for semantic relevance when building search results.
10. Click **Next**.
11. On the Fields for Filtering page, optionally add fields from the source object or related objects to provide more ways to filter a search. You can select up to ten filter fields.
Data 360 picks up the pre-filter fields when you generate vector embeddings. If you change the values in those pre-filter fields, Data 360 picks them up when you generate or refresh those vector embeddings. The cardinality of object relationship between the source object and the related object must be either 1:1 or N:1.
For example, if the indexed unstructured data includes case conversation transcripts, filtering on the Status field in the Case object can improve the relevance of semantic search results when searching the conversation transcripts.
12. Click **Next**.
13. Review the configuration and the target data model objects, and click **Save.**
# Create a Search Index Configuration with Easy Setup
Follow a few automated steps to create a hybrid search index configuration for a data model object (DMO) or an unstructured data model object (UDMO). Data 360 automatically applies defaults for the chunking and vectorization strategies, and creates chunk and index model objects.
### Required Editions
User Permissions
Needed
To create a search index configuration:
Permission set:
Before creating a search index, review the Unstructured Data and Search Index Guidelines and Limits in [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&type=5&language=en_US) and search index considerations in the [Search Reference.](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.") Familiarize yourself with the concepts of chunking unstructured data, vectorization, and the chunk and index data model objects.
Easy Setup includes these defaults.
- Chunking strategy: Passage extraction
- Embedding model: E5-Large V2
- Search Type: Hybrid Search
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index** > **New**.
3. Click **Easy Setup** > **Next**.
4. From the New Search Index Configuration page, select a Data Space and one or more UDMOs or DMOs. A search index configuration is created for each object that you select.

Note A DMO that has mappings from one or more external DLOs can only be used as the data source if caching is enabled for all those external DLOs. For more information see, [Caching in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&type=5&language=en_US).
5. Add a Search Index Configuration Name and Search Index Configuration API Name.
6. Click **Next**.
7. Review the configuration and the target data model objects, and click **Save.**
8. Create a retriever in AI Models (formerly Einstein Studio) to retrieve data from a search index.
Use retrievers in prompt templates and agent actions to get relevant results. For more information see, [Create an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_create.htm&release=264.0.0&type=5 "To improve the relevancy of the content returned to a prompt for a particular use case, create a custom individual retriever in AI Models (formerly Einstein Studio). To customize the retriever, select its search index, define filters, and specify what information it returns.").
Data 360 creates a hybrid search index for the DMO or UDMO selected.
#### See Also
- [_Salesforce Help_: Search Index Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.")
# Create a Secondary Index
Create secondary indexes in Data 360 to improve query performance and reduce credit usage on data lake objects (DLOs) or materialized data model objects (DMOs) by optimizing data retrieval beyond primary key fields.
### Required Editions
User Permissions Needed
To view secondary indexes
One of these permission sets:
Data Cloud User
Data Cloud Activation Manager
Data Cloud Activation Specialist
To create or delete secondary indexes
Permission set:
To create a secondary index on a DLO or DMO, you must have data space access to that object. For more information about data space aware objects, see [Data Space Aware Objects and Features](https://help.salesforce.com/s/articleView?id=data.c360_a_data_space_aware_features.htm&release=264.0.0&type=5 "User access to data space-aware objects and features is controlled by setting the object permissions and feature permissions in the user's permission sets. Not all objects and features are data space aware.").
1. In Data Cloud, navigate to **Secondary Indexes** tab.
1. From the App Launcher, find and select Data Cloud.
2. Select the **Secondary Indexes** tab if it's available. Otherwise, choose **More** and select **Secondary Indexes**.
2. Choose **New** on the Secondary Indexes page to open the **New Secondary Index** window.
3. Enter a **Name** for your new secondary index and optionally provide a **Description**.
Ensure that the name of your secondary index is descriptive and provides context that it is an index. Secondary indexes are saved as a new DLO.
4. Search for and select the DLO or materialized DMO that you want to index.
Search by object name or browse available objects.
5. Choose the field to use for the secondary index, and then click **Next**.
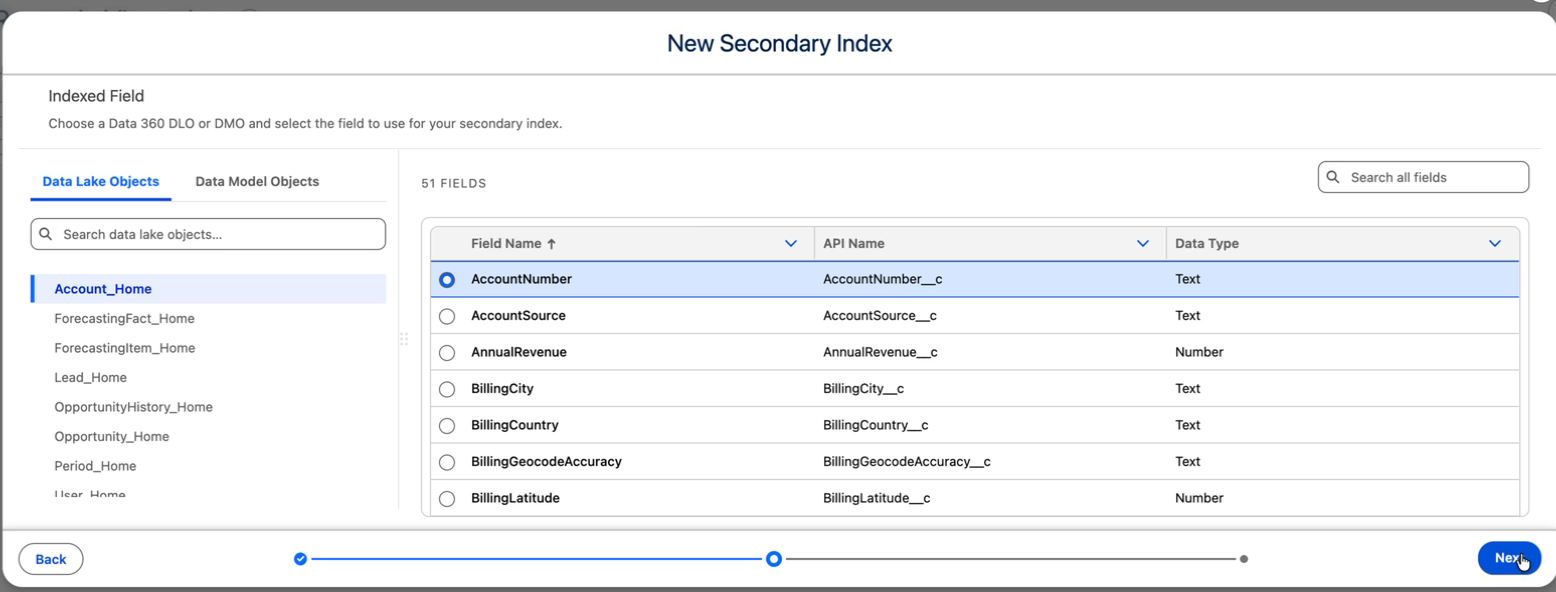
6. Set a refresh rate for your index, and then click **Save**.
Select a **Frequency** of **Hourly**, **Daily**, or **Weekly**, and set the **Daily Start Time** and **Time Zone**. For an hourly or daily refresh, set **Run Every**. For an hourly or weekly refresh, also select one or more **Scheduled Day(s)**.

Note You can't edit secondary indexes after creation. To change a secondary index, delete and recreate it. Recreating a secondary index incurs the cost of index creation. You can change how often the index refreshes at any time. See [Schedule a Secondary Index Refresh](https://help.salesforce.com/s/articleView?id=data.c360_a_schedule_secondary_index_refresh.htm&release=264.0.0&type=5 "Set how often Data 360 refreshes a secondary index so that the index stays current with the underlying object. Choose a refresh frequency that keeps the index fresh enough for your queries without refreshing more often than your data changes.").
# Create a Segment from a Data Kit
Instead of creating a segment from scratch in Data 360, use a predefined segment from a data kit. You can edit and fine-tune the segment.
### Required Editions
Permission Sets Needed
To create a segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, click **Segments**.
2. Click **New**.
3. Select **Create from a Data Kit**, and click **Next**.
4. Select a data kit and a predefined segment.
If the segment has a child segment or calculated insight, make sure that the API name is the same as this segment.
5. Click **Next**.
6. Enter the segment details.
1. Select a data space.
2. For Segment On, select a data model object (DMO).
If you’re using a non-unified object, such as Account or Contact, the object is already chosen.
3. Give your segment a unique, recognizable name and enter an optional description.
4. Click **Next** and check the dependencies.
If the segment has dependency errors, contact your admin.
7. Select a publish type and schedule.
8. Click **Save**.
# Create a Segment to Qualify the Correct Unified Individuals
Cumulus creates a segment that qualifies the Unified Individuals they want to use for their journey.
1. Log in to Data 360 and navigate to the **Segments** tab.
2. Click **New**.
3. To choose which data model object (DMO) to segment the audience on, select **Unified Individual**.
4. Name the segment Omnichannel Credit Limit Alert and add a description.
5. Select a publish schedule of **Don’t refresh**.

Note Refreshes overwrite and reset the required Send Relationship setting on the resulting data extension.
6. Add a start date and time and an expiration date.
7. Click **Save**.
8. To build the segment, click **Edit Rules**.
9. Drag the **Credit Limit Met** attribute to the interface.
10. Select an operator of **True**.
11. Click **Done**.
12. Add additional attributes and save additional criteria as needed.
13. Click **Save**.
# Create a Semantic Enrichment
Add business context to improve how the Data 360 Data Q&A Agent interprets and responds to questions about your data.
### Required Editions
Semantic enrichments teach the agent about your business terminology, calculation methods, data quality rules, and conventions. The more context you provide, the more accurate and relevant the agent's responses become.
## Before You Create an Enrichment
Consider what type of context you want to provide:
- Are you defining a business term or metric?
- Are you explaining how to calculate something?
- Are you providing data quality guidance for a specific field?
- Are you describing a relationship between objects?
- Are you setting a default filter or condition?
This helps determine the right scope (data space, object, or field) and how to phrase the enrichment statement.
## Create an Enrichment
1. Navigate to the Semantic Enrichments list view.
2. Click **New Semantic Enrichment**.
3. Enter a **Name** that clearly identifies the enrichment's purpose. Example: "Active Customer Definition" or "Revenue Field Guidance".
4. Select the **Scope**:
- **Object:** Applies to a specific Data Lake Object (DLO) or Data Model Object (DMO). Use for object-specific guidance.
- **Field:** Applies to a specific field within an object. Use for field-level interpretation.
5. If you selected **Object** or **Field** scope, choose the target object or field from the dropdown.
6. In the **Semantic Statement** field, write your enrichment in clear, plain language. Be specific about when and how the rule applies. You can write multi-sentence enrichments for complex business rules. Examples:
- "Active customers are those with status = 'Active' and at least one order in the last 90 days."
- "Use amount\_usd\_\_c for revenue calculations. This field represents deal size in US dollars."
- "When filtering email\_address, always use lowercase comparisons because some legacy data has mixed case values."
- "High-value opportunities are defined as amount\_usd\_\_c greater than $100,000 and stage equals either 'Proposal' or 'Negotiation'. For regional analysis, use region\_\_c field, not the billing address state. Historical high-value opportunities from before 2023 used a different threshold of $50,000 due to inflation adjustments."
7. (Optional) Add **Tags** to organize related enrichments. Use consistent tags like "revenue," "customer-segmentation," or "data-quality" to make enrichments easier to find and manage later. Tags are for organization only and don't affect which enrichments the agent retrieves.
8. (Optional) Check **Critical** if this enrichment must always be considered by the agent. Use it for foundational business rules or data quality constraints. Marking too many enrichments as Critical causes context bloat and slows down queries, so use it sparingly.
9. (Optional, but recommended) Add **Lookup Summaries** to improve semantic enrichment retrieval. These are keywords or phrases that you expect to appear in users' questions. For example, if the semantic statement defines customer lifetime value, add lookup summaries such as "CLV" and "customer lifetime value."
10. Click **Save**.
## Writing Effective Semantic Statements
A semantic statement teaches the agent how to turn a plain-language question into the right query against your data. Every effective statement answers three questions:
- **What is the rule?** The instruction the agent should follow.
- **Why does it exist?** The reasoning behind it.
- **What happens if it's ignored?** The wrong answer you're trying to prevent.
The "why" matters most. A rule with no reasoning gets followed literally and breaks on any question you didn't anticipate. A rule with reasoning lets the agent handle cases you never wrote down. Compare a weak statement that gives only the rule with a strong statement that adds the reasoning and consequence:
- **Weak (rule only):** "Always filter Status = 'Active'."
- **Strong (rule, reasoning, and consequence):** "Always filter Status = 'Active' on every query. The table stores both active and archived customer records. Without this filter, results mix in archived customers who are no longer relevant. This applies even when the user asks about one named customer."
Follow these guidelines when you write a statement:
Be specific
Instead of "Use the revenue field," write "Use amount\_usd\_\_c for revenue calculations because it represents deal size in US dollars and is consistently populated."
Explain the why
Don't just state a rule—explain the reason. "Filter by status = 'Active' because inactive customers shouldn't appear in reporting."
Use examples
When defining calculations, show the formula or logic. "Customer lifetime value = total\_revenue / months\_active \* average\_customer\_lifespan\_months."
State conditions clearly
If a rule only applies in certain cases, say when. "For opportunity queries, exclude stage = 'Closed Lost' unless explicitly requested."
Avoid jargon
Write in plain language the agent can parse. If you must use domain-specific terms, define them.
## Best Practices for Semantic Statements
- **One rule per statement.** Don't combine unrelated rules. When the agent retrieves a statement, it pulls the whole thing, so a statement that covers five topics adds four irrelevant rules every time one matches.
- **Lead with the rule, then explain the why.** State the instruction first, then the reasoning, then the consequence of getting it wrong.
- **Say what not to do.** If two fields or values are easy to confuse, name the wrong one explicitly. "Never use the ship date for revenue questions" is as valuable as naming the right field.
- **Spell out values the agent can't guess.** The agent sees field names, not the values inside them. List the valid set when it's short and non-obvious.
- **Clarify formats and units.** If a number is stored as a multiplier, a percentage, or in cents, say so. Otherwise "less than 2x" or "over 50%" gets misread.
- **Attach each statement to the narrowest correct target.** A rule about one field belongs on that field. A rule spanning several fields belongs on the object. This keeps unrelated questions clean and surfaces the right rule at the right time.
- **Use Critical only for rules that apply to almost every question.** A Critical statement is always applied. Non-critical statements are pulled in only when the question matches their lookup summaries. Reserve Critical for universal rules and keep the count small.
- **Write lookup summaries in the words your users actually type.** These are the trigger phrases that surface a non-critical statement. Use real phrasing, synonyms, and abbreviations, not technical descriptions.
## Types of Context You Can Add
Semantic statements can capture many kinds of business context. Common types include:
| **Context Type** | **Example Semantic Statement** |
| --- | --- |
| Business rules and required filters | "Always filter Channel = 'Retail' unless the user names a different channel. The table combines retail, wholesale, and internal test orders. Without this filter, totals are inflated by wholesale and test data that most business questions don't want." |
| Term and metric definitions | "'Revenue' refers to net revenue after discounts and refunds. Always calculate using Net\_Amount. Using Gross\_Amount overstates revenue by including refunded sales." |
| Field values and enumerations | "Valid values for Fulfillment\_Status are 'Pending', 'Shipped', 'Delivered', and 'Returned'. When the user says 'open orders' or 'not yet shipped', filter Fulfillment\_Status = 'Pending'." |
| Formats, units, and thresholds | "Satisfaction\_Score is stored on a 0-to-100 scale, not a percentage. When the user says 'low satisfaction', filter Satisfaction\_Score < 60. When they say 'high satisfaction', filter Satisfaction\_Score > 85." |
| Date routing | "For revenue and sales questions, filter on Order\_Date. For delivery and logistics questions, filter on Ship\_Date. Order\_Date is when the sale happened; Ship\_Date is when it left the warehouse. Using Ship\_Date for revenue puts a sale in the wrong period." |
| Groupings and hierarchy | "'By region' means group by Sales\_Region. 'By product' means group by Product\_Category, not the individual Product\_Name. Users asking 'by product' want category-level rollups, not one row per SKU." |
| Output preferences | "For 'top N' questions such as 'top 5 customers', order by the measure and limit to N rows. Return a ranked list with the customer name and the measure. Don't collapse it to a single computed value." |
## Test Your Enrichment
After creating an enrichment, test it by asking the agent a question that should trigger it. Review the agent's response and check the **View More Details** section to see if the enrichment was applied correctly. If the agent didn't use the enrichment as expected:
- Make sure the enrichment is **Active**.
- Check that the scope (data space, object, or field) matches your question.
- Revise the semantic statement to be more specific or add relevant tags.
- If the enrichment is foundational, mark it as **Critical**.
## Next Steps
See [Manage Semantic Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_semantic_enrichments.htm&release=264.0.0&type=5 "Edit, deactivate, or delete semantic enrichments as your data model and business rules evolve.") to learn how to edit, deactivate, or delete enrichments as your data model evolves.
# Create a Shopping Cart Insight
Create a shopping cart insight to understand customer interactions and optimize their journey. This process involves selecting an individual data model, choosing real-time or batch processing, and defining event values. Gain valuable insights into shopping trends and improve conversion rates.
### Required Editions
User Permissions Needed
To create shopping cart insights:
Data Cloud Architect
You also need view access for all related DMOs and Data Graphs to create an insight that references them.
1. In Data Cloud, go to the Calculated Insights tab, click **New**.
2. Choose a **Dataspace**.
3. Click **Create from Template**.
4. Click **Shopping Cart**.
5. Choose the type of individual data model object to use as the model for your customer.
If you chose **Unified Individual**, choose an **Identity Resolution Ruleset**.
6. Select how the insight processes data.
If you chose **Real-Time**, choose a data graph.
7. Review the prerequisites page and fix any incomplete prerequisites. Your connected data graph and data model objects (DMOs) must contain specific fields and relationships to create this Shopping Cart Insight.
8. Define Details shopping cart insight details.
1. Provide the **Shopping Cart Insight Name**. The **API Name** is automatically populated.
2. Provide the **Description**.
3. Provide the **Event Value**s for the actions in your engagement events. The value must match and is case-sensitive.
# Create a Snowflake V2 Data Share Target
Create a Snowflake V2 data share target in Data 360 to establish connectivity with a Snowflake account.
### Required Editions
User Permissions Needed
To create a data share target:
Data Cloud Architect permission set
1. In Data Cloud, on the Data Share Target tab, click **New**.
2. For the connection type, select **Snowflake V2**, and click **Next**.
3. Enter these details.
- Label - The display name of the data share target. There’s no character limit.
- API Name - This field is auto-populated to match the label name, but you can use a different name.
- Enrollment ID - Snowflake returns this value when you create the corresponding connection. For more information, see [Snowflake documentation](https://docs.snowflake.com/en/user-guide/data-integration/zero-copy/salesforce/setup).
4. Enter a description for the data share target and click **Save**.
# Create a Standard Segment in Data 360
Create a standard segment based on a data model object and then publish the segment to activation targets.
### Required Editions
Permission Sets Needed
To create a segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
Filter your unified data to define a specific audience based on the data model object (DMO) you select. After you create a segment, you publish it to activation targets on a defined schedule. You can choose between standard and rapid publish when you set the segment schedule.
1. In Data Cloud, click **Segments**.
2. Click **New**.
3. Select **Use a Visual Builder**.
4. Select **Standard Segment**, and click **Next**.
5. Enter the segment details.
1. Select a data space.
2. For Segment On, select the data model object (DMO) that your segment is built on.
3. Give your segment a unique name that's easily identifiable.
4. Set the **Lookback Window** for your segment.
The default is 90 days. You can set it up to 2 years. If you select Days from the dropdown, you can set a window of up to 360 days, depending on your organization's requirements.

Note The Lookback Window options are based on your organization's maximum allowed period. This setting defines the initial data range you can select. When you're in the segment, you can apply specific criteria in a container that may differ from the segment-level Lookback Window. For example, if the segment-level Lookback Window is set to 90 days and a container specifies 60 days, the container criteria takes precedence and data is pulled for only 60 days.
6. Click **Next**.
7. Choose how to publish the segment.
Both standard and rapid publish types support configurable lookback window in segmentation rules.
8. Define when and how often your segment publishes to activation targets.
If you plan to add segment filters, you can also select **Don't Refresh** and add the schedule later.
9. (Optional) Click **Preview** to view your segment audience and verify its accuracy. If you notice anomalies or missing members you expected to be included, review the segment rules and container configurations.

Note The segment preview feature is available to users with segment view or edit rules permissions and access to data in Data Explorer.
10. Click **Save**.
The maximum number of segments that you can have in Salesforce is 9,950.

Example
A retail company creates a standard segment targeting customers who made a purchase in the last 60 days. They select their UnifiedIndividual DMO, set a 60-day Lookback Window, and choose Rapid Publish with a 1-hour interval running Monday through Friday to quickly push updated audience data to their Marketing Cloud Engagement activation target.
After you create a segment, activate it by publishing to an activation target. You can also create additional segments using the same DMO or refine your segment rules using container criteria.
- **[Segment On](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_on.htm&release=264.0.0&type=5)**
Segment On defines the target object used to build your segment. You can choose an object marked as Profile or Engagement type during ingestion. For example, you can build a segment on Unified Individual, Unified Household, Account, Reservations, Sales Order, etc.
- **[Manage Data 360 Segment Schedules](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_segment_schedules.htm&release=264.0.0&type=5)**
The segment scheduling options provide you with granular control over segment publish frequency. You can schedule your segments to run at the frequency that best suits your needs.
- **[Publish a Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_segment.htm&release=264.0.0&type=5)**
After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.
- **[Segment Membership Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_membership_data.htm&release=264.0.0&type=5)**
Each time you publish a segment, a data model object (DMO) is created or updated to store segment membership information. To identify who's included in a segment, use the Segment Membership DMO (type Segment\_Membership). If there are no dependencies on the DMO, you can delete segment membership DMOs manually.
- **[Edit a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_segment.htm&release=264.0.0&type=5)**
After you create a segment in Data 360, you can edit its rules or properties to provide updates or change the purpose. Changing the segment name doesn’t change the segment API name.
#### See Also
- [_Salesforce Help_: Troubleshoot Segment Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_troubleshooting.htm&release=264.0.0&type=5 "Get tips for solving the most common segment errors in Data 360.")
- [_Salesforce Help_: Visual Segment Creation to Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segments_to_data_cloud.htm&release=264.0.0&type=5 "Segmentation enables data analysts to curate relevant portions of data from their analyses in Tableau and seamlessly transfer them as segments to Data 360.")
- [_Tableau Help_: Visual Segment Creation to Data 360](https://help.tableau.com/current/online/en-us/segments.htm)
# Create a Streaming Insight Using Builder
Use near real-time data in Data 360 by creating a streaming insight. A streaming insight focuses on data at a specific time. You can write SQL expressions to compute streaming metrics across dimensions from your real-time data sources. Use a streaming insight to perform cross-functional orchestration and optimize your data in Data 360.
### Required Editions
User Permission Sets
Needed
To create streaming insights:
Permission set:
Setting up streaming insights requires several prerequisites and steps. To ensure the best results, follow this action flow.
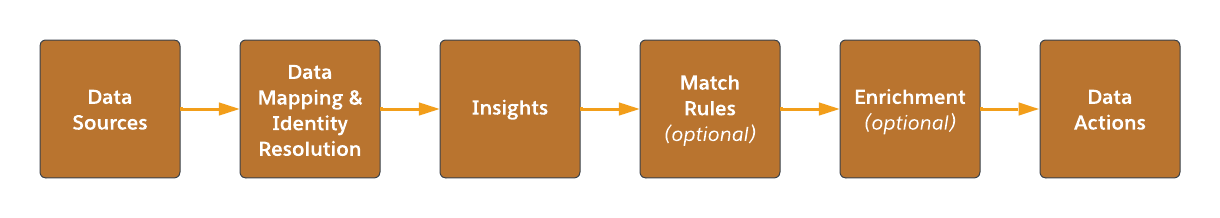
- Data sources—Map sources to different objects from Web & Mobile SDK and Marketing Cloud Personalization (formerly Interaction Studio) data streams.
- Identity resolution and data mapping—Ingest your data into Data 360, and create unified individuals with identity resolution.
- Insights—Streaming Insights are similar to calculated insights but have specialized functions to manage streaming data.
- Match rules—Enrich with unified individual data from customers.
- Enrichment—Enhance data actions with profile-related attributes.
- Data actions—Apply data actions on a streaming insight and evaluate if the action is necessary.
1. In Data Cloud, go to the Calculated Insights tab, click **New**.
2. From the Data Space dropdown, select a data space.
You can use only the data spaces that you have access to.
3. Click **Streaming Insight**.
4. Click **Use Visual Builder** and click **Next**.
5. Select the object, and then click **Next**.
Only the objects that are created from streaming data sources such as Web SDK and Mobile SDK are available to create a streaming insight.
6. If your Insight includes currency fields, select the **Insight Currency** value at the top of the page.
7. Add the nodes by clicking **+** next to the object.
You must select at least one aggregate node.
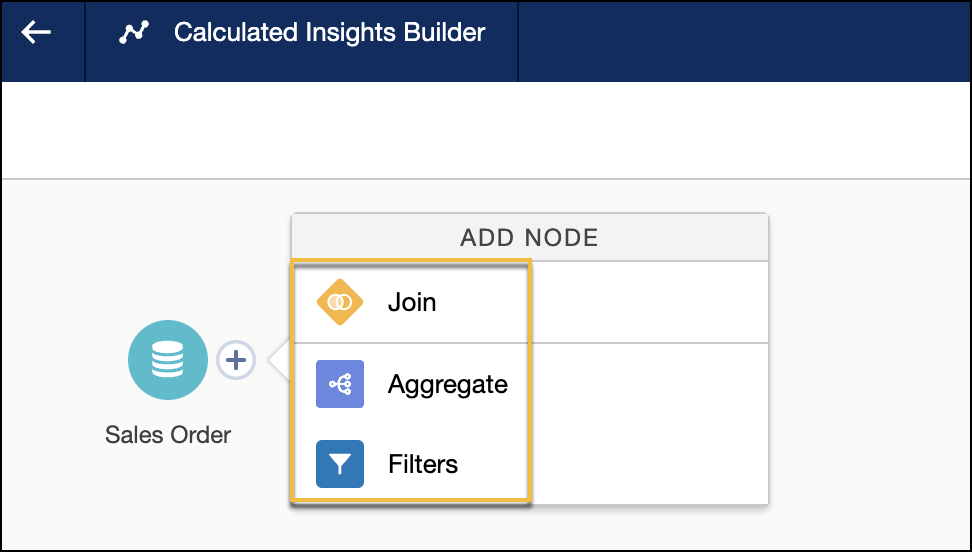
8. Add measures and dimensions to your insight by clicking **Aggregate**.
You must select at least one measure.
1. Enter a date and time window duration for your insight.
2. From the Granularity dropdown, select a time interval.
3. Under Measures, click **+**.
4. Select a metric function and the field that you want to calculate, and then click **Next**.
5. Enter the metric name, and click **Apply**.
6. Under Dimensions, click **+**.
7. Select the field that you want to group by, and click **Next**.
8. Enter the dimension name, and click **Apply**.
9. To save the aggregate node, click **Apply**.
10. (Optional) To enhance your insight with additional data, add the join and filters nodes.
11. Click **Save and Run**.
12. Enter the streaming insight name, and click **Next**.
The Streaming Insight API Name field is auto-filled.
13. Click **Save**.
You can now view your streaming insight on the record home page. The last run status of a streaming insight is always Processing.

Example
```sql
SELECT COUNT( RealTimeMobileEvents__dlm.pageviews__c ) as page_views__c,
ssot__Individual__dlm.ssot__Id__c as customer_id__c,
RealTimeMobileEvents__dlm.product__c as product__c,
WINDOW.START as start__c,
WINDOW.END as end__c
FROM
RealTimeMobileEvents__dlm
JOIN
ssot__Individual__dlm
ON
ssot__Individual__dlm.ssot__Id__c = RealTimeMobileEvents__dlm.deviceId__c
GROUP BY
window( RealTimeMobileEvents__dlm.dateTime__c ,'5 MINUTE'),customer_id__c, product__c
```
SQL Result
| start\_c | end\_c | customer\_id\_c | product\_c | page\_views\_c |
| --- | --- | --- | --- | --- |
| 2023-01-01 12.00 AM | 2023-01-01 12.05 AM | 1 | HK0012 | 1 |
| 2023-01-01 12.05 AM | 2023-01-01 12.10 AM | 2 | JK0078 | 2 |
| 2023-01-01 12.10 AM | 2023-01-01 12.15 AM | 3 | HK0078 | 1 |
After you create a streaming insight, validate it in Data Explorer.
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Source, Object Name, and Object API Name](https://help.salesforce.com/s/articleView?id=data.c360_a_source_object_name_and_object_api_name.htm&release=264.0.0&type=5 "When ingesting a data set into Data 360, name the data set source.")
- [_Trailhead_: Data 360 Insights](https://trailhead.salesforce.com/content/learn/modules/customer-data-platform-insights?trail_id=enhance-data-in-customer-data-platform)
# Create a Streaming Insight Using SQL
Write SQL expressions to compute streaming metrics across dimensions from your near real-time data sources. A streaming insight analyzes data at specific points in time. Streaming insights help build time series aggregations in near real time to orchestrate and optimize your data within Data 360.
### Required Editions
User Permission Sets
Needed
To create streaming insights:
Permission set:
Setting up streaming insights requires several prerequisites and steps. To ensure the best results, follow this action flow.

- Data sources—Map sources to different objects from Web & Mobile SDK, ingestion API, and Marketing Cloud Personalization data streams.
- Identity resolution and data mapping—Ingest your data into Data 360, and create unified individuals with identity resolution.
- Insights—Streaming Insights are similar to calculated insights but have specialized functions to manage streaming data.
- Match rules—Enrich with unified individual data from customers.
- Enrichment—Enhance data actions with profile-related attributes.
- Data actions—Apply data actions on a streaming insight and evaluate if the action is necessary.
- DMO—Streaming insights can only use the engagement DMO as primary DMO. Profile and Other DMO can be used as a right table join.
- Window function—Streaming insights require a window function aggregate. Define the window frame in the `SELECT` statement using `window.start` and `window.end`.
1. In Data Cloud, go to the Calculated Insights tab, and click **New**.
2. From the Data Space dropdown, select a data space.
You can use only the data spaces that you have access to.
3. Click **Streaming Insights**.
4. Click **Use SQL Authoring** and click **Next**.
5. Enter the streaming insight name, and click **Next**.
The Streaming Insight API Name field is auto-filled.
6. Enter a SQL query expression up to 131,021 characters.
7. When your insight includes currency measures, you must use the `TRY_CONVERT_CURRENCY` function.
8. To check whether your SQL expression is valid, click **Check Syntax**.
If it isn’t valid, you can’t continue.
9. Click **Save and Run**.
The streaming insight is displayed on the record home page. The last run status of a streaming insight is always Processing.
#### See Also
- [_Trailhead_: Data 360 Insights](https://trailhead.salesforce.com/content/learn/modules/customer-data-platform-insights?trail_id=enhance-data-in-customer-data-platform)
# Create a Tag in Data 360
Tags are essential for organizing, classifying, and managing data at scale. They act as metadata labels that describe the content, sensitivity, usage, or purpose of a data object or field. Tags can have one parent and multiple child tags, but they don't support more than one level of hierarchy.
### Required Editions
| User permission needed | |
| --- | --- |
| To create a tag | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. Click **New** and enter a unique tag name and an optional description.
Except for periods, all other characters and spaces are allowed in tag names.. The tag API name is auto-filled based on your tag name. You can change the API name.
3. Select the tag’s source taxonomy.
By default, the source taxonomy is the custom tag taxonomy.
4. (Optional) Select a tag parent.
If you select a tag parent, you can’t change the tag’s source taxonomy.
5. Click **Next**.
6. (Optional) Assign the tag one or more classifications.
7. Click **Save**.
# Create a Target DLO from the Data Lake Objects Tab
One way to create a new Target Data Lake Object (DLO) is via the Data Lake Objects tab.
1. On the Data Lake Objects tab, click **New**.
2. Decide whether to use an existing DLO as a template or create a new one.
3. Enter a name and API name.
You can’t change these names after the object is created.
4. Select the appropriate category for the data in this DLO.
Category selection affects billing and DMO mapping. You can’t change the DLO’s category after it’s created. [Learn more about categories in Salesforce Help](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.").
5. Review the DLO’s status. When the status is Active, you can add it to a streaming data transform.
Once you create your DLO, see [Set Up a Streaming Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_setup.htm&release=264.0.0&type=5 "When you set up a streaming data transform, it reads and processes all records in the source and writes the data to the target object. The source and target objects must be different objects.") and follow the steps to create a data transform using an existing DLO as the target object.
# Create a Vector Search Data Action in Data 360
Create a vector search data action to act on the unstructured data in near real time and send an alert or an event.
### Required Editions
User Permission Sets
Needed
To create a vector search data action:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, on the Data Actions tab, click **New**.
2. Choose Vector Search Data Action and click **Next**.
3. Select a Webhook or Salesforce Platform Event data action target, and click **Next**.
4. Select a data space.
5. Select a search index. Search index of vector search type is available for selection.
6. Configure search parameters, and click **Next**.
- Search context: The search text that returns the relevant results.
- Results Limit: The number of top results to return from the search. Enter a number between 0 and 10.
- Score Threshold: The threshold similarity score for vector search. Enter a decimal number between 0 and 1.
7. Enter the action name. The Action API Name field is auto-filled.
8. Click **Save and Publish**.
You can view your data action on the record home page.

Note If you are bringing data through Agentforce data library, you need to rebuild the search index to trigger the vector search data action.
#### See Also
- [_Salesforce Help_: Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&language=en_US)
# Create a Vector Search Index with Advanced Setup
When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.
### Required Editions
User Permissions
Needed
To create a search index configuration:
Permission set:
Before creating a search index, review the Unstructured Data and Search Index Guidelines and Limits in [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&type=5&language=en_US) and search index considerations in the [Search Reference.](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.") Familiarize yourself with the concepts of chunking unstructured data, vectorization, and the chunk and index data model objects.
## Enable Agentforce for Generative AI Capabilities (Optional)
Some capabilities in search index, including image processing, enriched index, and LLM-based content processing and parsing requires generative AI features available through Agentforce. If you want to use those capabilities, contact your admin to [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US) in your org. Enable Amazon Bedrock Models (Amazon and Anthropic) in Einstein Setup to use enriched indexing.
## Select a Search Type and Source Object
To get started specify the type of search you want to perform and select a source DMO.
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index** > **New**.
3. Click **Advanced Setup** > **Next**.
4. Select Vector Search for **Search Type**.
5. Select a data space and a source object.

Note A DMO that has mappings from one or more external DLOs can only be used as the data source if caching is enabled for all those external DLOs. For more information see, [Caching in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&type=5&language=en_US).
6. Click **Next**.
## Set Up Parsing and Visual Data Preprocessing
Next, extract and prepare text, metadata, tables, and images from unstructured documents for chunking.
LLM-based Parsing and preprocessing options are available for PDF, HTML, DOCX, and PPTX file types from UDMOs and files attached to DMO records. These options aren’t available for use with DMO records.
You cannot select both LLM-based parsing and LLM-based Visual Data Preprocessing options for a single search index. See [LLM-based parsing and preprocessing](https://help.salesforce.com/s/articleView?id=data.c360_a_llm_parsing_preprocessing.htm&release=264.0.0&type=5 "Use LLM-based parsing and preprocessing to extract and prepare text, metadata, tables, and images from unstructured documents for chunking.") for more information about these options.
With LLM-based parsing and LLM-based Visual Data Preprocessing you can override the default GPT-4o model to use any supported LLM that best fits your business needs and your content. You can only select LLMs that are approved for use by your admin. If your org admin turns off a model that is currently in use, your previously processed content remains accessible. However, Search Index will fail to process any further content. For more more information supported models, see [Search Index Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&type=5&language=en_US).
1. On the Parsing page, choose one of these options.
Default Parser Extract text with built-in settings. LLM-based Parser Extract all text, images, and other visual elements using an LLM. Docling Parser Extract text from images, tables, and document layouts using Docling Parser.
2. If you choose Default Parser, click **Next.**
3. If you choose to parse your documents using an LLM, complete these steps.
1. From the dropdown list, select the appropriate model.
2. Use the default prompt as is, or edit it for your specific use case.
It's highly recommended to customize the prompt for your use case and documents.
3. Click **Next**.
4. If you choose the Docling parser, click **Next**.
By default, additional pre-processing is turned-off. Optionally, enable image processing when you set up chunking strategies to parse images and complex tables.
5. If you chose the default parser, on the Preprocessing page, choose one of these options.
No Preprocessing Use parsed text and visual data as is. LLM-based Visual Data Preprocessing Capture context from visual data using an LLM. (Available only if you selected the default parser in the previous step.)
6. If you choose No pre-processing, click **Next**.
7. If you choose to pre-process your documents using an LLM, complete these steps.
1. From the dropdown list, select the appropriate model.
2. Use the default prompt as is, or edit it for your specific use case.
It's highly recommended to customize the prompt for your use case and documents.
3. Click **Next**.
## Set Up Chunking and Vectorization
Next, set up chunking for your data and select an embedding model to create searchable vectors for each chunk.
1. If your search index is on a DMO, on the Chunking page, select fields to chunk and the [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.").
1. To add or remove fields, click **Manage Fields** and save your work.
Search Indexes don't support date and datetime fields for chunking. Only numerical and text fields are available for chunking data.
2. (Optional) Update the chunking strategy and modify the settings.
3. If your search index is on a DMO of a Salesforce object with file attachments that you want to include, click **Include Attachments** and select the ContentDocumentVersion UDMO.
4. Add a file extension or set a chunking strategy based on the file type. To add a file extension for a new file type, click **Add File Extension**, and then optionally update the chunking strategy and modify the settings for an existing file type.
5. (Optional) To add additional fields to a chunk, select the **Prepend fields to each chunk** toggle and select a field from the list. You can add a maximum of two fields.
6. To enrich generated chunks with additional metadata, turn on the **Enrich Content Chunks** toggle.
7. Click **Next**.
2. If your search index is on a UDMO, add a file extension or set a [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.") based on the file type.
1. To add a file extension for a new file type, click **Add File Extension**. If you have images to process, add the JPEG, JPG, and PNG file extensions.
2. (Optional) Update the chunking strategy and modify the settings for an existing file type.
For image files with extensions, such as JPEG, JPG, or PNG, image processing is enabled by default. To include image processing for PDF files, turn on image processing.
If you selected LLM-based parsing or LLM-based visual data preprocessing in previous steps, image processing doesn't apply even if you turn it on.
3. (Optional) To add additional fields to a chunk, select the **Prepend fields to each chunk** toggle and select a field from the list. You can add a maximum of two fields.
4. To enrich generated chunks with additional metadata, turn on the **Enrich Content Chunks** toggle.
5. When you select the Docling parser, optionally, turn-on LLM-based image processing to parse images and complex tables using an LLM. For better data extraction with tables, select Section-Aware chunking. Section-Aware chunking processes tables optimally such as retaining the header information across table chunks. For more information on supported file formats see, [Docling Parser](https://help.salesforce.com/s/articleView?id=data.c360_a_docling_parser.htm&type=5&language=en_US).
3. If you have audio or video files to transcribe, click **Configure**, and in the transcription window, select the following:
1. Select the default transcription model from the dropdown.
2. To add a timestamp to each speaker entry, select **Include timestamp**.
4. Click **Next**.
5. On the Vectorization page, from the dropdown list, select an embedding model, and then click **Next**. If your search index includes images to process, select the [appropriate embedding model (beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5).
The model determines how Data 360 measures your unstructured data objects for semantic relevance when building search results.
## Configure Fields for Filtering
To enhance the precision and relevance of search results, specify fields that users can use to filter their searches.
1. On the Fields for Filtering page, optionally add fields from the Source object or related objects to provide more ways to filter a search. You can select up to ten filter fields.
Data 360 picks up the pre-filter fields when you generate vector embeddings. If you change the values in those pre-filter fields, Data 360 picks them up when you generate or refresh those vector embeddings. The cardinality of object relationship between the source object and the related object must be either 1:1 or N:1.
For example, if the indexed unstructured data includes case conversation transcripts, filtering on the Status field in the Case object can improve the relevance of semantic search results when searching the conversation transcripts.
2. Click **Next**.
## Review and Build the Index
1. Review the configuration and the target data model objects.
2. Click **Save**.
When you build the search index, Data 360 creates a hybrid search index for the data. Next, create a Retriever in the **AI Models** tab. Agentforce agents can use the search index with Retrievers in prompt templates.
#### See Also
- [_Salesforce Help_: Search Index Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.")
- [_Salesforce Help_: Manage a Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_manage.htm&release=264.0.0&type=5 "Create, view, edit, and delete search index configurations.")
- [_Salesforce Help_: Chunking Strategies](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.")
- [_Salesforce Help_: Ground with Retriever Augmented Generation (RAG)](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&type=5&language=en_US)
# Create a Waterfall Segment
If you’re running a campaign with multiple offers, use a waterfall segment to process a list of existing segments in a priority order. The primary goal is to ensure that an individual who qualifies for more than one segment is placed only into the highest-priority segment they match. This creates a series of mutually exclusive audiences, which is ideal for campaigns where you want to send customers only one, most-relevant offer.
### Required Editions
Permission Sets Needed
To create a waterfall segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, click **Segments**.
2. Click **New**.
3. Select **Use a Visual Builder**.
4. Select **Waterfall Segment**, and click **Next**.
5. Enter the segment details.
1. Select a data space.
2. For Segment On, select the data model object (DMO) that your segment is built on. The list displays the objects marked as Profile type during ingestion.
3. Give your waterfall segment a unique name that’s easily identifiable.
6. Click **Next**.
7. Define when and how often your waterfall segment publishes to activation targets.
If you plan to add segment filters, you can also select **Don’t Refresh** and add the schedule later. The processing schedule applies to the entire waterfall. Rapid segment publish isn’t available for waterfall segments.
8. Click **Save**.
9. Create the waterfall by dragging segments onto the canvas and ordering them according to priority.
You can add up to 20 segments. Only active segments that are based on the selected DMO and that aren’t already in a waterfall are listed. A segment can exist in only one waterfall. You can't include nested segments in a waterfall segment. Counts for each mutually exclusive segment are available after you save and publish the waterfall segment.
10. Click **Save**.
Saving your waterfall segment takes time. Leaving the waterfall page doesn’t affect processing.

Example
This example shows how a waterfall segment creates mutually exclusive audiences so a customer receives only one offer.
You have three separate promotional offers and three segments of customers you want to target:
- Offer 1 (Best Offer): 25% off for High-Value Customers
- Offer 2 (Mid-Tier Offer): 15% off for New Customers (Joined in last 90 days)
- Offer 3 (General Offer): 10% off for All Active Customers
A customer can be in multiple segments at once. For example, a High-Value Customer (Offer 1) might also be a New Customer (Offer 2) and is definitely an All Active Customer (Offer 3). You don't want to email this person three different offers; you want to send them only the best one they qualify for (the 25% off).
You create a waterfall segment and drag your existing segments onto the canvas in this priority order:
1. High-Value Customers (Priority 1)
2. New Customers (Priority 2)
3. All Active Customers (Priority 3)
When the waterfall segment runs, it evaluates each customer against the list in order and stops as soon as it finds a match:
- Customer A (Sarah): Sarah is a High-Value Customer and a New Customer.
- Does she match Priority 1 (High-Value)? Yes.
- Result: Sarah is placed into the High-Value Customers group. The waterfall stops processing her. She will not be placed in the New Customers or All Active Customers groups, even though she technically qualifies for them. She receives only the 25% off offer.
- Customer B (David): David is not a High-Value Customer, but he is a New Customer.
- Does he match Priority 1 (High-Value)? No.
- Does he match Priority 2 (New Customers)? Yes.
- Result: David is placed into the New Customers group. The waterfall stops processing him. He receives only the 15% off offer.
- Customer C (Maria): Maria is not High-Value and not a New Customer, but she is an Active Customer.
- Does she match Priority 1 (High-Value)? No.
- Does she match Priority 2 (New Customers)? No.
- Does she match Priority 3 (All Active Customers)? Yes.
- Result: Maria is placed into the All Active Customers group and receives the 10% off offer.
The final output of your waterfall segment is three distinct, non-overlapping lists of customers that ensures no one receives more than one promotion.
# Create a Webhook Data Action Target
Send a data action event to a webhook target and protect the message integrity with a Salesforce-generated secret key. A webhook is a type of API that’s event driven rather than request driven. The secret key validates the payload requests sent from Salesforce. The webhook transports the HTTP payload with events in the format of `DataObjectDataChgEvent`.
### Required Editions
User Permission Sets
Needed
To create a Webhook data action target:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, navigate to the Data Actions Target tab, and click **New**.
2. Enter the action target name.
The Action Target API Name field is auto-filled.
3. Select **Webhook**.
4. Enter the URL where you want to publish the webhook events, and click **Save**.
5. Generate the secret key.
You can generate a secret key only for an active or inactive data action target.
6. Copy the secret key to configure your webhook system.
```
{
"creationDateTime": "DateTime: Payload creation time at the service calling webhook",
"count": "Number: Count of events in this payload",
"schemas": [ { "schemaId": "Action Name of schema", schema : "Schema of Event Payload in Action" } ], //Array of Schemas for different event payload
"events": [Array of Data Object Data Change Event],
}
```
#### See Also
- [_Salesforce Developer_: Webhook Data Action Targets in Data 360](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_webhook_data_action_targets_in_customer_data_platform.htm)
# Create a Welcome Series in Journey Builder
Now that the emails are complete, you can create the journey.
1. In Marketing Cloud Engagement, go to **Journey Builder**.
2. Click **Create New Journey**.
3. Select **Multi-Step Journey** and then click **Create**.
4. For the entry source, drag a **Data Extension** activity to the canvas.
5. To select the **New Auto Policy** data extension, click the **data extension activity**.
6. Click **Summary** and then click **Done**.
7. Next drag an **Email** activity to the interface.
8. Click the **email activity** and then select the **Cumulus Welcome - Tips for Getting Started Email** after clicking **Select Message**.
9. Click **Summary** to review Message Configuration, Delivery Options, and Advanced Options. Click **Done**.
10. Repeat these steps for the other welcome emails.
11. Adjust the wait times between the emails to 3 days, 5 days, and 1 day.
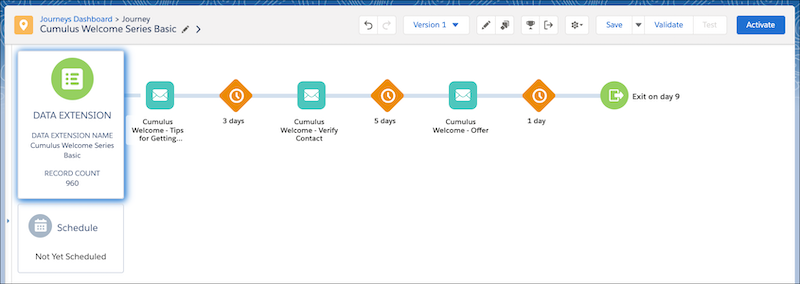
12. To make this journey an ongoing campaign, click **Schedule**, **Recurring**, and then **Select**.
1. Select a **Start Date**, **Start Time**, and **Time Zone**. For this campaign, select **Weekly**, on **Monday**, and ending **Never**.
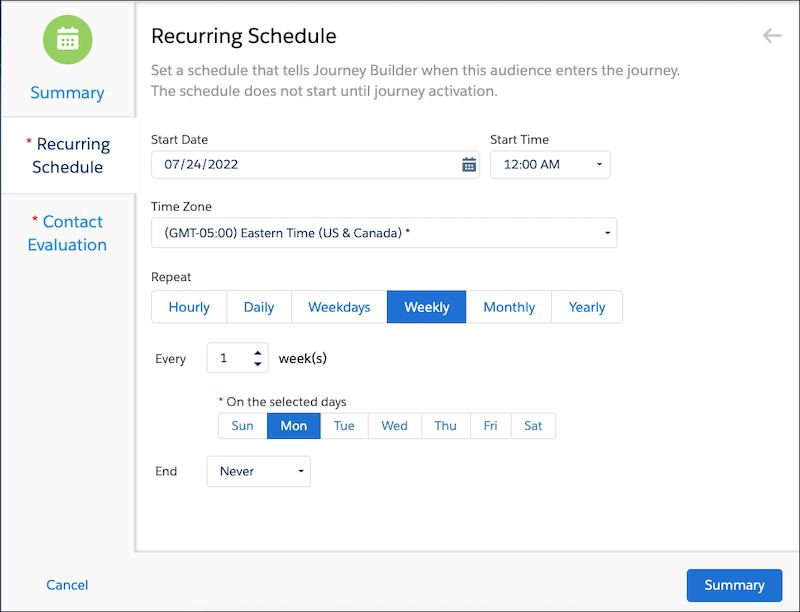
13. Click **Contact Evaluation** and select **Evaluate new records only**.
1. For the first run, select to evaluate **All records in the file**.
14. Click **Summary** and then **Done**.
15. Review the journey and click **Save**.
16. To ensure that all information has been completed, click **Validate**.
17. Test the journey, and then click **Activate** when ready.
The campaign is ready for customers.
#### See Also
- [_Salesforce Help_: Create a Multi-Step Journey in Journey Builder](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_create_multistep_journey.htm&type=5&language=en_US)
- [_Salesforce Help_: Use Data 360 in Journey Builder](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_c360a_using_audiences.htm&type=5&language=en_US)
- [_Trailhead_: Manage Campaigns with Journey Builders](https://trailhead.salesforce.com/en/content/learn/trails/manage-campaigns-with-journey-builder)
# Create Activations to Ad Audiences Partner Platforms
Activate your audience segments and company lists to advertising platforms.
### Required Editions
User Permissions
Needed
To create an API activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
Complete these tasks before you begin.
- [Set up an External Activation Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_external_activation_platform.htm&language=en_US&type=5): System admins must configure the platform including parameters, authentication details, and required mappings in Data Cloud Setup.
- [Create an activation target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activations.htm&language=en_US&type=5) and enable the target. You can use the same activation target for activating user segments and company lists.
- [Create an Audience Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&language=en_US&type=5) for your advertising campaign.
1. On the Activations tab, click **New**.
2. Select **Segment**.
3. Select a data space.
4. Select a segment to activate.
5. Select the activation target.
6. Select a DMO from Activation Membership.
7. Click **Continue**.
8. Depending on the target, select one of these.
- Select **User Match** for audience segment activation.
- Select **Company Match** for company list activation.
- Select **Device IDs** for sending anonymous audiences.
9. Map the data model attributes to their partner fields. Map the optional fields to increase the chances of finding a match.
10. Click **Next**.
11. For more refined output, add activation membership filters. Click **Add Filters**, drag attributes from the list to the canvas, and save the filter. See [Add Filters to the Activation Membership](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_membership_filtering.htm&language=en_US&type=5).
12. Click **Next**.
13. Enter a name and description for the activation.
14. Click **Save**. When the activation is complete, the audience segment or company list shows up on the target platform.
You can refresh Segment memberships manually or on a schedule. When a segment membership is refreshed, the activation is also updated.
# Create an Activation for a Data 360 Target
After you create a segment in Data 360, you can publish it to an activation target.
### Required Editions
User Permissions
Needed
To activate a segment:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
## Create an Activation
1. In Data Cloud, select the Segments tab, and then select a segment.
2. From Activations, click **New**.
3. Select the data space.
4. Select the Data Cloud activation target.
5. For Activation Membership, select a data model object (DMO).
6. Click **Continue**.
7. To include contact points in this activation, click **Select** next to the contact points. When you add a contact point, select an existing path, or click **Edit** to add, reorder, or delete sources and change source types and priority for each contact point.
8. Click **Next**.
## Configure Activation Attributes
1. To activate more attributes, click **Add Attributes**. You can add these types of attributes to your activation:
- Direct Attribute—Attributes of the Activation Membership DMO.
- Related Attribute—Attributes from any object in the DMO if a path to that object from the Activated On object exists and all the relationships along that path are either 1:1 or N:1. When you use a Data Cloud activation in an activation-triggered flow, flows support related attributes only up to two levels deep.
- Calculated Insights—Add your Calculated Insights metrics to the activation, and apply dimension filters for more granular insights.
2. Drag up to 100 additional attributes to the canvas. If you select different columns with similar information, all the unique combinations are added to the output.
3. To provide a unique attribute name, click the Edit icon.
4. Save your changes.
## (Optional) Refine the Audience
1. To include campaign-specific data, expand Campaign Data, and click **Add Campaign Attribute**.
You can include up to 20 standard attributes (Activation Name, Activation ID, Segment Name, Segment ID, Activation Run ID, and Activation Publish Start Time) and custom attributes. Each campaign attribute forms a new column in activation output.

Note For a waterfall segment, when you include the Segment Name and Segment ID standard attributes, the activation output displays the parent segment name and ID.
1. You can modify or remove campaign attributes when editing an activation. To remove all campaign attributes, choose the **Delete All** option from the **Add Campaign Attribute** dropdown menu.
You can also manage campaign-specific data through the [Activation Connect APIs](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=Summary).
2. To use the same audience for multiple fixed-size campaigns across different channels with varying budgets, expand **Provisional Audience Limiting**, then click **Rank Attributes**.
1. Drag up to three attributes to the canvas in your preferred hierarchy for ranking. You can rearrange the attributes by dragging them up or down.
2. Select the sorting order (ascending or descending) for each attribute and the attribute path, then click **Save**.
3. To remove an attribute, select the dropdown menu, then click **Remove Attribute**.
To rank attributes, you can include direct attributes and calculated insights.
3. To limit the audience for this activation, enter a number from 1 through 10,000. The audience is selected randomly. If you’ve ranked attributes, the audience is prioritized based on the ranking.
4. Click **Next**.
## Save the Activation
1. Enter a name and description for your activation.

Important Don’t include these characters in the name: + ! @ # $ % ^ \* ( ) = { } \[ \] \\ . < > / " : ? | , \_ &
2. Click **Save**.
Your segment publishes on the next scheduled publish for the selected activation target. When a segment is published to the Data Cloud activation target, the activated records update the Audience DMO. To view these records, on to the Data Explorer page, select the corresponding Audience DMO. Use the Query API to retrieve the activated records.
If you use a Data 360 activation to create an activation-triggered flow, after the activation completes, the flow starts automatically and sends the activated data to the API-based destination configured in flow. For more information, see [Create an Activation-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_activation_triggered_flow.htm&type=5&language=en_US). To view linked activation-triggered flows for the activation, open the activation record and check the **Associated Flows** section.
To view linked activation-triggered flows for the activation, open the activation record and check the **Associated Flows** section. This section shows only activation-triggered flows that you have permission to view. The section is hidden if there are no linked activation-triggered flows or if you don’t have access to any linked flows.
#### See Also
- [_Salesforce Help_: View Your Data in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_your_data.htm&language=en_US)
- [_Salesforce Help_: Audience Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_audience_data_model_object.htm&language=en_US)
- [_Salesforce Developer_: Query the activated data using Audience DMO API](https://developer.salesforce.com/docs/platform/connectapi/references/spec?meta=getAudienceDmoActivationRecords)
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
# Create an Activation for a DMO Using a Custom Event
When you create a DMO activation in Data 360 using a custom event, add the required attributes for a tailored activation experience. Conversion API (CAPI) activations to Ad Audience partner targets use DMO activation.
### Required Editions
Permission Sets Needed
To create an activation:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activations tab, click **New**.
2. Select the Data Model Object (DMO), and click **Next**.
3. Enter the details of your activation, and then click **Next**.
4. Click **Create a Custom Event**.
5. Map the Data Cloud attributes to the partner’s configured attributes.
1. For the partner attributes, edit the mapping and choose an attribute, and then click **Save**.
2. For user identifiers, map and select at least one attribute.
3. For the optional partner attributes, edit the mapping and choose an attribute, and then click **Save**.
4. Click **Next**.
6. (Optional) Add filters to the activation membership to make it more relevant to your event. The DMOs available for filtering depend on whether the activation uses a data graph.
1. Without a data graph, only attributes from the activated DMO are available for activation membership filtering.
2. When a data graph is used in the activation, you can filter on attributes from any DMO included in that data graph, up to 2 hops away from the activated DMO. This lets you apply more precise audience criteria using related DMOs you've already modeled in the data graph.
7. (Optional) Add consent and other contact point filters that are relevant to your campaign.
1. Select the maximum number of contact points sent per record.
2. Select an attribute to sort and rank your contact points. Click **Next**.
8. Provide a name, an optional description, and an activation start and end date.
#### See Also
- [Add Filters to Contact Points in Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_point_filtering.htm&release=264.0.0&type=5 "When activating a Data 360 segment, you can filter and sort contact points to ensure you are targeting the right audience on the right channel with the right permissions. This feature is essential for managing customer consent, preventing duplicate messages, and improving the personalization of your campaigns.")
- [Add Filters to the Activation Membership](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_membership_filtering.htm&release=264.0.0&type=5 "Data 360 activation membership filters allows you to send more personalized communications by adding custom filters to the activation membership. Add filters to ensure that only the intended audiences are being targeted.")
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_ad_audiences_capi_activations.htm&release=264.0.0&type=5 "Conversion API (CAPI) activation targets send online and offline conversion events from a data model object (DMO) to supported advertising platforms. CAPI uses streaming DMO activation instead of audience segment activation.")
# Create an Activation for a DMO Using a Standard Event
When you create an activation in Data 360 using a standard event, the required attributes from the data model object (DMO) are automatically added. Conversion API (CAPI) activations to Ad Audience partner targets use DMO activation.
### Required Editions
Permission Sets Needed
To create an activation:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Activations tab, click **New**.
2. Select the Data Model Object (DMO), and click **Next**.
3. Enter the details of your activation, and then click **Next**.
4. Click **Create a Standard Event**.
5. Select a standard event.
The events are defined by the customer engagement platforms.
6. Select an action source.
Action sources depend on the selected event.
The Activation Summary is updated as you choose the DMO, the event type, and the standard event.
7. Map the Data Cloud attributes to the partner’s configured attributes.
1. For the partner attributes, edit the mapping and choose an attribute, and then click **Save**.
2. For user identifiers, map and select at least one attribute.
3. For the optional partner attributes, edit the mapping and choose an attribute, and then click **Save**.
4. Click **Next**.
8. (Optional) Add filters to the activation membership to make it more relevant to your event. The DMOs available for filtering depend on whether the activation uses a data graph.
1. Without a data graph, only attributes from the activated DMO are available for activation membership filtering.
2. When a data graph is used in the activation, you can filter on attributes from any DMO included in that data graph, up to 2 hops away from the activated DMO. This lets you apply more precise audience criteria using related DMOs you've already modeled in the data graph.
9. (Optional) Add consent and other contact point filters that are relevant to your campaign.
1. Select the maximum number of contact points sent per record.
2. Select an attribute to sort and rank your contact points. Click **Next**.
10. Provide a name, an optional description, and an activation start and end date.
#### See Also
- [_Salesforce Help_: Add Filters to Contact Points in Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_point_filtering.htm&release=264.0.0&type=5 "When activating a Data 360 segment, you can filter and sort contact points to ensure you are targeting the right audience on the right channel with the right permissions. This feature is essential for managing customer consent, preventing duplicate messages, and improving the personalization of your campaigns.")
- [_Salesforce Help_: Add Filters to the Activation Membership](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_membership_filtering.htm&release=264.0.0&type=5 "Data 360 activation membership filters allows you to send more personalized communications by adding custom filters to the activation membership. Add filters to ensure that only the intended audiences are being targeted.")
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_ad_audiences_capi_activations.htm&release=264.0.0&type=5 "Conversion API (CAPI) activation targets send online and offline conversion events from a data model object (DMO) to supported advertising platforms. CAPI uses streaming DMO activation instead of audience segment activation.")
# Create an Activation for an External Platform
In Data 360, create an activation to publish a segment to an external platform, such as an AppExchange partner (Liveramp, Criteo, Tradedesk) or a strategic partner (Google, LinkedIn, Meta, or Amazon Ads) target. For supported Ad Audiences partner targets, you can use identity providers and enrich Data 360 identity attributes during activation.
### Required Editions
Permission Sets Needed
To create an activation:
Any one of these permission sets:
Make sure that you've completed these tasks before creating an activation:
- [Install a Managed Package](https://help.salesforce.com/s/articleView?id=xcloud.distribution_installing_packages.htm&type=5&language=en_US) - Install the managed package required for using external activation platforms.
- [Set Up an External Activation Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_external_activation_platform.htm&type=5&language=en_US) - Configure an external activation platform after installation. Set up platform parameters, authentication details, and required mappings.
- [Create an External Activation Target in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&type=5&language=en_US) - Define an activation target by specifying the destination system, data mapping, and scheduling details.
- To use Identity Boost, complete clean room collaboration setup with an enabled identity provider. Identity Boost supports one identity provider per activation. For more information, see [Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_identity_boost.htm&release=264.0.0&type=5 "Use identity boost to collaborate with identity providers in a clean room and enrich your first-party data with missing contact points. Use the enriched data in your activations to improve match rates.").

Note The identity provider is available only if the clean room collaboration is active.
1. On the Activations tab, click **New**.
2. Select a data space.
3. Select a segment to activate.
The segment must have an active publish schedule to ensure that near real-time membership data is sent.
4. Select an activation target.
If the privacy type isn’t set, update the external platform to include a privacy type.
5. Select a data model object (DMO) from Activation Membership. Unified Individual DMO isn't available for segments built on account or unified account objects for AppExchange partner targets.
6. Click **Continue**.
7. If you’re using a strategic partner target or AppExchange partner target, map each data model attribute to its partner field. On the mapping screen, map each partner field (right side) to the corresponding Data 360 data model attribute (left side). Pre-selected attributes cannot be deselected. Select and map optional fields as needed. In the **User Identifiers** section, ensure at least one attribute is selected.
1. Click the pencil icon to edit and select the object and field where the data resides.
2. Select the path to retrieve the data from the object.
3. Click **Save**.
4. Click **Next**.
8. To improve audience reach with attributes from a third-party identity provider, select an identity provider.
9. To activate more attributes, click **Add Attributes**. You can add two types of attributes to your activation.
- Direct Attribute—Attributes of the Activation Membership DMO.
- Related Attribute—Attributes from any object in the DMO if a path to that object from the Activated On object exists and all the relationships along that path are either 1:1 or N:1.
To include Digital Id as a contact point in activation of a JSON-based external activation platform, add the related attributes from the Contact Point Digital Id DMO.
10. For a more refined output, add activation membership filters. Click **Add Filters**, drag attributes from the list to the canvas, and save the filter. For more information, [Add Filters to the Activation Membership](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_membership_filtering.htm&release=264.0.0&type=5 "Data 360 activation membership filters allows you to send more personalized communications by adding custom filters to the activation membership. Add filters to ensure that only the intended audiences are being targeted.").
11. To add filters for each mapped Contact Point:
1. Select the maximum number of attribute values to be sent per contact point. This is enabled only for Contact Point Digital Id for activation of a JSON-based external activation platform.
2. Select a sort option for the attribute values.
3. If the Contact point digital ID is mapped for external platforms created by the ISVs, add the filter for the digital ID type attribute. Provide the filter values based on the external activation platform settings defined by the Data Cloud Architect for ID Type mapping to normalize ID type values. Based on the filtering, the corresponding records are activated to the external activation platform. For more information, see [Add Filters to Contact Points in Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_point_filtering.htm&release=264.0.0&type=5 "When activating a Data 360 segment, you can filter and sort contact points to ensure you are targeting the right audience on the right channel with the right permissions. This feature is essential for managing customer consent, preventing duplicate messages, and improving the personalization of your campaigns.").
4. Click **Next**.
12. Provide a name and optional description for the activation and save.
Use the activation name to find the activated audience within your strategic partner targets.
When the segment is published, the [Audience DMO](https://help.salesforce.com/s/articleView?id=data.c360_a_audience_data_model_object.htm&release=264.0.0&type=5 "Understand and analyze your activated audience over time using audience data model objects (DMOs). There are two types of related DMOs, audience and audience latest DMOs.") is updated with the activated records. To view these records, go to the Data Explorer page and select the corresponding Audience DMO. Use the Query API to retrieve the activated records.
- **[Ingest and Model Digital Identifiers for JSON-based External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_map_digital_identifiers_activation_toolkit.htm&release=264.0.0&type=5)**
Ingest and model your digital identifier data by using the standard `ContactPointDigitalId` data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.
#### See Also
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
- [_Salesforce Help_: Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_ad_audiences_identity_boost.htm&release=264.0.0&type=5 "Expand the addressable audience for your ad campaigns by enriching your first-party data with contact points from a certified identity provider. Identity Boost fills the coverage gaps in your first-party data so that you can reach more of your audiences in Ad Audiences partner activations.")
# Create an Activation for B2C Commerce Target
After you set the required data field mappings and create a segment in Data Cloud, create a B2C Commerce activation to publish the segment.
### Required Editions
User Permissions
Needed
To create an activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, click **Segments** and select a segment.
2. From Activations, click **New**.
3. Select a B2C Commerce activation target. In Activation Membership, the data model object (DMO) is chosen by default.
Unified Individual DMO isn't available for segments built on account or unified account objects.
4. Click **Continue**.
5. To filter the activation data, select one or more data sources.
If you select a B2C Commerce data source, all activated attributes must have valid values since they can’t be left blank or null. If you select a non-B2C Commerce data source (for example: Amazon S3), make sure CustomerNo and CustomerListId activated attributes have valid values.
Valid values are populated only when the field mappings are done correctly for all data sources.
6. Enter a name and description for your activation.
Don’t include these characters in the name field: + ! @ # $ % ^ \* ( ) = { } \[ \] \\ . < > / " : ? | , \_ &
7. Click **Save**.
Your segment publishes on the next publish scheduled for the selected activation target. Activated data can take up to 24 hours to be visible in B2C Commerce. Segment membership is refreshed once a day with activation data from the past 36 hours. If the data isn’t consistently activated to B2C Commerce, it might be removed from the segment. To avoid removal, schedule an activation every 24 hours or more frequently.
#### See Also
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
- [_Salesforce Help_: Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_targets.htm&release=264.0.0&type=5 "Depending on your use case, data can be activated to various targets, from file storage, external activation, or to other data model objects (DMOs) in Data 360. Once you know where you want to act on the segmented data from Data 360, create activation targets for each platform.")
- [_Salesforce Help_: Required Field Mappings to Activate to B2C Commerce](https://help.salesforce.com/s/articleView?id=data.c360_a_req_commerce_cloud_connector_activation_data_field_mappings.htm&release=264.0.0&type=5 "When activating a segment to B2C Commerce, certain data field mappings are required for B2C Commerce and non-B2C Commerce data sources.")
# Create an Activation for File Storage Target
After you create a segment in Data 360, you can publish it to an activation target.
### Required Editions
User Permissions
Needed
To create an activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
- Segments with over 10 million records and related attributes won't activate. This limit doesn't apply to segments with only direct attributes.
- You can have a maximum of 1000 activations that use related attributes.
## Create an Activation
1. In Data 360, click **Segments**.
2. Select the segment that you want to activate.
The segment size is checked at the time of an activation. Activation time varies based on segment size and the data in related attributes.
3. In Activations, click **New**.
4. Select a file storage activation target (S3 (Legacy), Amazon S3, SFTP, Google Cloud Storage, Microsoft Azure Blob Storage).
5. For Activation Membership, select an object, and click **Continue**.

Tip Use Activation Membership to add fields from different DMOs than your segment is built on to send to your activation target. For example, a Loyalty Cloud user creates a segment of top-tier customers from the Individual object so they can target their customers with a special promotion. In Loyalty Cloud though, each customer is identified by their Loyalty Program Member Id. So when creating an activation, the Loyalty Cloud user can add the Loyalty Program Member Id field to the segment by selecting the Loyalty Program Member DMO in Activation Membership. Now Loyalty Cloud can identify segment members by their Loyalty Member Program Id to target with the Loyalty Cloud promotion.
6. (Optional) Select your contact points. The order of attributes in the activation doesn’t match the order in the CSV file output.
7. When you map contact points, select an existing path or click **Edit** to add, reorder, or delete sources and change source types and priority for each contact point.
8. Click **Next**.
## Configure Activation Attributes
1. To activate more attributes, click **Add Attributes**.
2. Drag up to 100 additional attributes to the canvas. If you select different columns with similar information, all the unique combinations are added to the output.
- Direct Attribute—Attributes of the Activation Membership DMO.
- Related Attribute—Attributes from any object in the DMO if a path to that object from the Activated On object exists and all the relationships along that path are either 1:1 or N:1.
- Calculated Insights—Add your Calculated Insights metrics to the activation, and apply dimension filters for more granular insights.
3. To provide a unique attribute name in the output file, click the **Edit** icon.
When you activate additional attributes, primary or foreign key fields aren’t available as an option because they aren’t exposed for activation. To see primary or foreign key fields during activation, create a formula field that copies those fields. The formula field is included as an additional attribute for activation. In the lakehouse, number data type fields are stored as decimals, not integers. Therefore in activation, the fields appear as decimals, except for primary keys.
4. Save your changes.
5. (Optional) For SFTP, Google Cloud Storage, and Microsoft Azure activation targets, you can remove the default attribute that's included automatically based on the Activation Membership object chosen during activation creation. However, if you remove the primary key attribute of the activated entity, it’s added back to the activation output automatically.
When activating to file storage targets:
- Use the column headers to identify and match the corresponding column data at the destination. If an activation is run multiple times, the order of attributes or columns in the activated file is consistent.

Note For activations created prior to January 2026, you must edit and save your activation to ensure its future runs have consistent order of attributes or columns.
- If you edit an activation, the order of attributes or columns is reset in the activated file. However, the subsequent runs will have the same order of attributes or columns.
- The Update Action field in the activation file in your file storage target corresponds to the Delta Type field in the [Audience DMO Schema Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_audience_dmo_schema_attributes.htm&type=5&language=en_US). Additionally, a Version field is added to the activation file by default, but it can be ignored.
## (Optional) Refine the Audience
1. To include campaign-specific data, expand Campaign Data, and click **Add Campaign Attribute**.
You can include up to 20 standard attributes (Activation Name, Activation ID, Segment Name, Segment ID, Activation Run ID, and Activation Publish Start Time) and custom attributes. Each campaign attribute forms a new column in activation output.

Note For a waterfall segment, when you include the Segment Name and Segment ID standard attributes, the activation output displays the parent segment name and ID.
1. You can modify or remove campaign attributes when editing an activation. To remove all campaign attributes, choose the **Delete All** option from the **Add Campaign Attribute** dropdown menu.
You can also manage campaign-specific data through the [Activation Connect APIs](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=Summary).
2. Expand **Provisional Audience Limiting**, then click **Rank Attributes** to use the same audience for multiple fixed-size campaigns across different channels with varying budgets.
1. Drag up to three attributes to the canvas in your preferred hierarchy for ranking. You can rearrange the attributes by dragging them up or down.
2. Select the sorting order (ascending or descending) for each attribute and the attribute path, then click **Save**.
3. To remove an attribute, select the dropdown menu, then click **Remove Attribute**.
To rank attributes, you can include direct attributes and calculated insights.
3. To limit the audience for this activation, enter a number from 1 through 10,000. The audience is selected randomly. If you ranked attributes, the audience is prioritized based on the ranking. To extend the audience limit to a maximum of 1 million, contact Salesforce Customer Support.
4. Click **Next**.
## Save the Activation
1. Enter a name and description for your activation.
- Key qualifier attributes are added to activations automatically
- Your description can have up to 200 characters

Important Don’t include these characters in the name: + ! @ # $ % ^ \* ( ) = { } \[ \] \\ . < > / " : ? | , \_ &
2. Choose a refresh type for the segment publish.
A full refresh publishes all records in the segment. An incremental refresh publishes only the added, updated, and deleted records since the last successful refresh. You can exclude modified or deleted records from the payload if they’re not needed.
3. Click **Save**.
Your segment publishes on the next publish scheduled for the selected activation target. These items are added to your file storage activation platform when the segment is activated:
- Data files that contain the segment members with additional attributes.
- For S3 (Legacy) targets, your data files are stored in a subfolder named `Salesforce-c360-Segments` which is automatically created when the first segment is activated.
- A segment metadata JSON file in the same directory as your activated data files.
- For S3(Legacy) and Amazon S3 targets, this metadata JSON file serves as a confirmation that the write operation to your destination is complete and the data is ready for consumption.
- For SFTP, GCS, and Azure targets, the metadata file and the activated data files may arrive in any sequence. Hence, the presence of the metadata file doesn’t indicate that activation is complete. To check if the activation is complete, use the [Get activation history](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&language=en_US) connect API, or view the publish status in the Activation History section on the [activation record home](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&language=en_US).
The segment metadata JSON file includes:
- Segment ID and name
- Data space ID and name
- Record count
- Refresh ID and publish refresh type
- Attribute names and their corresponding data types

Note For the activated files that are generated in CSV format, the field values follow standard quoting rules where they are enclosed in double quotes:
- If a field contains a comma or a new line character, the entire value is quoted. For example: value1,value2 → "value1,value2".
- If a field contains double quotes, each quote is escaped with a backslash (\\). For example: "value1","value2" → ""value1","value2""
#### See Also
- [_Salesforce Help_: Preferred Attribute Name](https://help.salesforce.com/s/articleView?id=data.c360_a_preferred_attribute_name.htm&language=en_US)
- [_Salesforce Help_: Contact Points and Source Priority Order](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_points.htm&language=en_US)
- [_Salesforce Help_: Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_fully_qualified_keys.htm&language=en_US)
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&language=en_US)
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
# Create an Activation for Marketing Cloud Engagement Target
After you create a segment in Data 360, you can publish it to an activation target.
### Required Editions
User Permissions
Needed
To create an activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
- From Data 360 Setup, make sure that **Allow Profile Business Unit Mapping Data** is enabled.
- Segments are filtered by the business unit (BU).
- Make sure that the segment that you want to activate is in an active or published state. If you create an activation with a segment in a processing state, the activation can remain in an error state until the segment completes processing.
## Create an Activation
1. In Data 360, click the **Segments** tab, and then select a segment.
2. In Activations, click **New**.
3. Select an activation target.
4. For Activation Membership, select a data model object (DMO).
5. Click **Continue**.
6. To include contact points in this activation, click **Select** next to the contact points.
1. When you map the contact points, select an existing path, or click **Edit** to add, reorder, or delete sources and change source types and priority for each contact point. Marketing Cloud is selected by default.
2. Change the source priority order to Marketing Cloud and update the source priority based on the EID and BU configured in the activation target.
3. To prevent the activation from introducing new contacts to Marketing Cloud Engagement from other sources, remove **Any Source** and **Any Type** from your source priority.
To allow the activation to introduce contacts from other BUs for the activation target, keep **Any Source** and **Any Type** in your source priority.
7. Click **Next**.
## Configure Activation Attributes
1. To activate more attributes, click **Add Attributes**. You can add these types of attributes to your activation:
- Direct Attribute—Attributes of the Activation Membership DMO.
- Related Attribute—Attributes from any object in the DMO if a path to that object from the Activated On object exists and all the relationships along that path are either 1:1 or N:1. When you use a Data Cloud activation in an activation-triggered flow, flows support related attributes only up to two levels deep.
- Calculated Insights—Add your Calculated Insights metrics to the activation, and apply dimension filters for more granular insights.
Datetime values in a segment that’s activated to Engagement always convert from your Data 360 org’s time zone to Engagement server time, which is CST (UTC-6).
2. Drag up to 100 additional attributes to the canvas. If you select different columns with similar information, all the unique combinations are added to the output.
3. To provide a unique attribute name, click the Edit icon.
4. Save your changes.
## (Optional) Refine the Audience
1. To include campaign-specific data, expand Campaign Data, and click **Add Campaign Attribute**.
You can include up to 20 standard attributes (Activation Name, Activation ID, Segment Name, Segment ID, Activation Run ID, and Activation Publish Start Time) and custom attributes. Each campaign attribute forms a new column in activation output.

Note For a waterfall segment, when you include the Segment Name and Segment ID standard attributes, the activation output displays the parent segment name and ID.
1. You can modify or remove campaign attributes when editing an activation. To remove all campaign attributes, choose the **Delete All** option from the **Add Campaign Attribute** dropdown menu.
You can also manage campaign-specific data through the [Activation Connect APIs](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=Summary).
2. To use the same audience for multiple fixed-size campaigns across different channels with varying budgets, expand **Provisional Audience Limiting**, then click **Rank Attributes**.
1. Drag up to three attributes to the canvas in your preferred hierarchy for ranking. You can rearrange the attributes by dragging them up or down.
2. Select the sorting order (ascending or descending) for each attribute and the attribute path, then click **Save**.
3. To remove an attribute, select the dropdown menu, then click **Remove Attribute**.
To rank attributes, you can include direct attributes and calculated insights.
3. To limit the audience for this activation, enter a number from 1–10,000. The audience is selected randomly. If you’ve ranked attributes, the audience is prioritized based on the ranking.
4. Click **Next**.
## Save the Activation
1. Enter a name and description for your activation.

Important Don’t include these characters in the name field: + ! @ # $ % ^ \* ( ) = { } \[ \] \\ . < > / " : ? | , \_ &
2. Click **Save**.
Your segment publishes on the next publish scheduled for the selected activation target. When the segment publishes for the first time, and if the activation count is greater than zero, a data extension is created in Marketing Cloud Engagement, and the segment records are added to it. To check if your activation has run, review the [Publish History of Your Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&type=5&language=en_US). The related attributes are stored in a field of the activated data extension of an Engagement.
Every time the segment publishes and activates to Engagement, the data extension is updated with the records currently in the segment. As a result, the data extension contains the records in the segment from the most recent successful activation, and the records from the previous activation are removed. To use the attributes and values in email personalization, parse the JSON from the data extension using AMPscript, GTL, or SSJS.

Note Activation include only known profiles. The final audience automatically excludes any anonymous profiles within your segment.
#### See Also
- [_Salesforce Help_: Find Segments in Marketing Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_segments_in_marketing_cloud.htm&release=264.0.0&type=5 "After you create and activate segments to Marketing Cloud Engagement, view them in Contact Builder. A Data 360 segments subfolder is created when you publish your first activation.")
- [_Salesforce Help_: Business Unit Aware Integration: Marketing Cloud and Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation.htm&language=en_US)
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
# Create an Activation Template
Create an activation template to define reusable activation configuration logic, including channel selections, source priority, contact point filters, enrichment data, and membership filtering. Apply this configuration when creating new activations or reference it in segment-triggered flows. Templates are created based on the combination of DMO and the activation destination, which allows you to reuse the same template across all activation targets for a given destination.
### Required Editions
Before you create a template, make sure:
- The Data 360 org has at least one data space configured.
- The data model objects (DMOs) relevant to your activation are mapped.
User Permissions Needed
To create an activation template:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, go to **Activations** and click **New**.
2. Select **Template** and click **Continue**.
3. Select a data space.
4. Select a data model object (DMO), such as Individual or Unified Individual.
You can apply the template only to activations or flows that use the same DMO.
5. Select the activation platform.
Choose the platform type that matches your activation destinations, for example, Marketing Cloud, Data Cloud, S3, Ecosystem, or Ad Audiences partner targets.
6. Click **Next**.
7. Select the contact points to include in the template, such as email, phone (SMS), or WhatsApp.
8. (Optional) For each contact point, click **Edit** to define the source priority order.
1. Click **Add Another Source**.
2. Select a source (for example, Amazon S3) and specify a source object, such as Lead, Prospect, or Customer, to prioritize specific record types.
3. Arrange the rows in the source priority table so that higher-priority sources appear first.
9. (Optional) Click **Add Filters** for a contact point to define filter criteria applied to contact point DMOs or consent DMOs.
1. Click **Next**.
2. For each contact point, click **Add Filters** to add contact point filters.
3. Drag attributes from the attribute library to the canvas. Use attributes from contact point DMOs or consent DMOs (for example, to add GDPR or messaging consent filters).
4. Define the filter criteria. To apply nested logic, use AND or OR operators. You can nest up to three levels.
5. Click **Done**.
10. (Optional) Configure activation membership filtering to define criteria for which segment members are included.
1. Under **Activation Membership**, click **Add Filters**.
2. Drag attributes from the list to the canvas and define the filter criteria.
3. Click **Save**.
11. (Optional) To include direct or related attributes in the template, click **Add Attributes**.
1. Drag up to 100 attributes to the canvas.
2. (Optional) For each selected DMO, click **Add Filters** to apply attribute-level filters. Drag attributes from the attribute library to the canvas, define the filter criteria, and use AND or OR operators for nested logic up to three levels.
3. Click **Done**, and then click **Save**.
12. For each selected DMO, set the attribute limits.
1. Select the maximum attribute values to include per contact point.
2. Select how to sort the attribute data.
13. Click **Next**.
14. Enter a name and description for your template.
15. Click **Save**.
After you save the activation template, you can choose it when creating activations to supported platforms and DMOs. You can also use it in segment-triggered flows.
To use the template when creating an activation, see [Use an Activation Template When Creating an Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_use_activation_template.htm&release=264.0.0&type=5 "Use an activation template when creating an activation to automatically fill in settings like contact points, source priority, filters, and enrichment data. You can then review and adjust these settings before saving your activation.").
# Create an Allow All Policy in Data 360
To maintain broad user access without enforcing restrictions, create an Allow All policy in Data 360. This policy grants access to objects within the data spaces assigned to users through permission sets.
### Required Editions
User Permissions Needed
To create an Allow All policy:
Permission set:
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Policies**, and then click **New**.
3. Select **Data Access**, and then click **Next**.
4. In Policy Builder, enter a unique policy name and an optional description.
The policy API name is auto-filled based on your policy name, but you can change it.
5. Click **Next**.
6. Select **Rules**, and then select the resources to protect. In the **Resource** dropdown, select **Object**.
By default, the rule applies across all data spaces. As new data spaces are added, these rules apply to their resources.
7. To restrict policies to specific data space scopes, click **Customize Scope**, deselect **Apply to the resources in all Data Spaces in Data Cloud**, and select the desired data spaces.
8. Click **Save**.
9. Select the action you want to take on the resource. From the Action dropdown, select **Allow access**.
10. Define the conditions when this action must take place. From the Take Action On dropdown, select **All Objects**.
11. To apply the policy to users, select **Users**.
12. From the Take Action On dropdown, select **All Users**.
13. Click **Save and Activate**.
# Create an Amazon Kinesis Data Action Target
Send change data capture (CDC) events from Data 360 to an Amazon Kinesis data stream for near-real-time downstream processing.
### Required Editions
User Permission Sets Needed
To create Amazon Kinesis data action targets:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Before you create an Amazon Kinesis data action target, create and validate an Amazon Kinesis target connector. For more information, see [Set Up an Amazon Kinesis Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_an_amazon_kinesis_target_connection.htm&release=264.0.0&type=5 "Send data action events from Data 360 to an Amazon Kinesis data stream. Use an access key or Salesforce as an OpenID Connect identity provider.").
1. In Data 360, go to the Data Actions Target tab, and click **New**.
2. Enter the data action target name.
The API Name field is automatically populated.
3. For the data action target type, select **Amazon Kinesis**.
4. Select the Amazon Kinesis target connection that you created, and then click **Save and Publish**.
Create a data action that uses this target. Choose the data space and the data model object (DMO) or calculated insights object (CIO) whose record creation, update, and delete events you want to track. For more information, see [Create a Data Action](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_action_in_customer_data_platform.htm&release=264.0.0&type=5 "Use a data action to send an alert or event to targets such as Salesforce Platform, Webhook, or Marketing Cloud Engagement, or Amazon Kinesis. Create the data action to focus on near real-time events and insights at different levels, including the channel, product, account, service, or individual.").
#### See Also
- [_Salesforce Help_: Set Up an Amazon Kinesis Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_an_amazon_kinesis_target_connection.htm&language=en_US)
# Create an API Activation in Data 360
API activation expands where and how you can initiate activations. API activation gives you the flexibility to use a Data 360 activation from Flow by using an API call.
### Required Editions
User Permissions
Needed
To create an API activation
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. On the Activations tab, click **New**.
2. Select the **API Activation**, and click **Next**.
3. Select a data space.
4. For the ID Membership, select Individual or Unified Individual data model object (DMO). You must use a segment with the same DMO when you use this API activation in Flow.
5. Select an activation target.
6. For Activation Membership, select either the Individual or Unified Individual data model object (DMO). The DMOs listed are based on the ID Membership you selected.
7. Click **Continue**.
8. Configure the remaining activation steps depending on your selected activation target. See the respective activation target help in [Activation for Data 360 Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_targets.htm&type=5&language=en_US).
9. Save the activation. An API activation runs every 24 hours.
Use this API activation in a segment-triggered flow or an activation-triggered flow in Flow Builder and add the Send to Data 360 Activation action.
An API can be linked to one active flow. You can delete an activation only when the flow is in the Draft or Completed state. You can’t delete an activation if the flow is in Activated or Scheduled (for recurring flows) state.
#### See Also
- [_Salesforce Help_: Activation Type and Target Compatibility](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_schedule_activation_target_compatibility.htm&language=en_US)
- [_Salesforce Help_: Create a Segment-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_segment_triggered.htm&language=en_US)
- [_Salesforce Help_: Automate Data Delivery with Activation-Triggered Flows](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_activation_triggered_flow.htm&language=en_US)
# Create an Attribute Shortcut
Save a frequently used attribute and its data model path as a shortcut so that you and other segment builders can reuse it without navigating the full attribute library each time.
### Required Editions
Permission Sets Needed
To create attribute shortcuts:
Any one of these permission sets:
Before you create an attribute shortcut, make sure that you've set up your data model and that you understand the path from the segment-on object to the target attribute.
You create attribute shortcuts from within the segment builder while working with the attribute library. When you find an attribute you want to reuse across segments, you save it as a shortcut with a descriptive name. The shortcut captures the segment-on object, the path through related DMOs, and the target attribute. Other segment builders can then use the shortcut without extensive knowledge of the underlying data model configuration.
1. In Data 360, click **Segments**.
2. Open an existing segment and click **Edit Rules**, or create a new segment and go to the segment builder canvas.
3. In the attribute library panel, search for the attribute you want to save as a shortcut. You can use either the direct attributes or related attributes section.

Note For direct attributes that appear in more than one data model object, the left pane shows the path as you select the attribute. Confirm you're pulling from the intended object before saving it as a shortcut. How you navigate the attribute library determines the path for related attributes.
4. Select the attribute to add it to the segment canvas.
5. Click  to save as a shortcut.
The Save Attribute Shortcut window opens, showing the object path for the attribute.
6. Enter a name for the shortcut.
Choose a concise name that clearly describes the attribute's meaning and its relationship to the segment-on object. For example, use "Product Drill Up" rather than "unified\_email\_product\_path."
7. (Optional) Enter a description that explains what the shortcut represents.
8. Save the shortcut.
Data 360 saves your attribute shortcut and displays it in the Shortcuts tab of the attribute library panel.
9. Click **Done** to confirm the filter on the segment canvas.
## Edit an Attribute Shortcut
Update the name or description of an existing attribute shortcut from the Shortcuts tab in Data 360. Editing a shortcut changes its display information without changing the underlying attribute path or target field.
1. In Data 360, select **Shortcuts**.
2. Find the shortcut you want to update in the list.
3. In that row, click the dropdown arrow, and then select **Edit**.
4. In the Edit Attribute Shortcut dialog, update the **Attribute Shortcut Name**.
5. Update the **Description** to explain how the shortcut is used.
6. Review the Segment-On object in the Summary panel to confirm you're editing the correct shortcut.
7. Click **Save**.
## Delete an Attribute Shortcut
Permanently remove an attribute shortcut from the shortcut library in Data 360. Deleting a shortcut removes it from the library and doesn't affect the underlying attribute or segment-on object.
1. In Data 360, select **Shortcuts**.
2. Find the shortcut you want to remove in the list.
3. In that row, click the dropdown arrow, and then select **Delete**.
4. In the Delete shortcut dialog, review the shortcut name in the confirmation message.
5. Click **Delete** to permanently remove the shortcut.
# Create an Einstein Segment in Data 360
Describe your segment to get suggested related attributes that are based on the data found in your org. To avoid bias and inaccuracies, all demographic attributes are removed. Attributes that produce fewer than 10 results for the segment population are also removed to improve the segment's accuracy.
### Required Editions
User Permissions
Needed
To create a segment:
Permission set:
Some Data 360 features have guidelines to optimize performance. Other features have restrictions or incur billing charges based on usage. Learn more about feature usage in the [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&language=en_US).
Before you start building Einstein segments, review our recommendations on [writing good prompts](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_prompts.htm&release=264.0.0&type=5 "When creating a segment, use certain formats and language to get the best results possible. Provide descriptive names for data model objects (DMOs) and attributes to ensure that generative AI can understand them. OpenAI was trained on data that leans toward the United States, which influences Einstein’s responses. If you require a specific country, enter the name of the country in the prompt.").
1. In Data Cloud, click **Segments**.
2. Click **New**.
3. Click **Create with Einstein**.
4. Select the Segment Properties.
1. Select the data space that the Unified Individual DMO that you’re basing this segment on is associated with.
2. From the Segment On dropdown, select the Unified Individual DMO that you’re basing your segment on.
3. Click **Next**.
5. In the Einstein Segment Creation chat, enter a segment description of at least two words using simple phrases, and then press Enter. After you enter a description, all the words are translated for you into attributes and values based on the data that exists in your org.
6. In the Einstein Segment Creation chat, enter a segment description of at least two words using simple phrases, and then press Enter. After you enter a description, all the words are translated for you into attributes and values based on the data that exists in your org. A segment description is created based on the phrase that you entered (1), and the attributes related to the description are created. For example, Einstein generative AI translates “physical and mental well-being” into different values using the Primary Hobby attribute. Attributes are divided into suggested attributes (2) and additional attributes (3). The suggested attributes are the most relevant to your description and are selected by default. The additional attributes aren’t necessarily relevant to your description. You can deselect any of the suggested attributes and select any of the additional attributes.
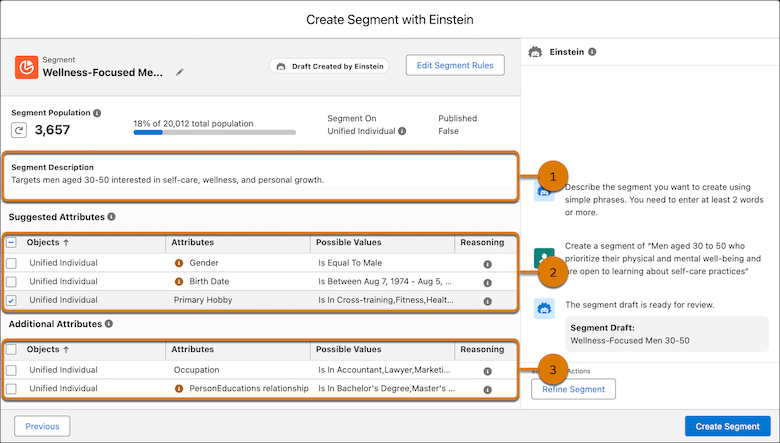
7. To edit the description or start over, click **Refine Segment**.
8. For an accurate population number, click **Count Population**. Counting takes time to complete. If you make changes to your segment draft, recount the population.
9. If you need to manually change any of the attributes or values this is done by clicking **Edit Segment Rules**. This action creates the segment and takes you to the Edit Rules tab. You can’t go back and make any changes in the editor afterwards. It’s recommended you do this only after you’re done creating your segment.
10. When you're satisfied with the segment and its attributes, click **Create Segment**.
**What to do next**: The new segment appears on the Segment list view. To use the segment, publish it.
#### See Also
- [_Salesforce Help_: Publish a Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_segment.htm&release=264.0.0&type=5 "After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.")
# Create an Ensemble Retriever
Use ensemble retrievers to get the most relevant information from multiple searches or data sources. In AI Models (formerly Einstein Studio), an ensemble retriever is a collection of individual retrievers. When you run an ensemble retriever, it runs all the individual retrievers, combines their results into a single list, reranks the list according to relevance to the search request, and returns just the most relevant information to the prompt or agent.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, and
delete)
Allow users to manage models in AI Models AND Access to Field Relationship Path
object
OR
Data Cloud Architect Permission Set
To access data with retrievers
For the Knowledge object, make sure that the user has read access to the
Knowledge object and has the App Permission: Allow View Knowledge
For all other
standard objects, make sure that the user has read access to the object and
appropriate sharing rules. For more information see, Set Your Internal Organization-Wide Sharing
Defaults
1. In AI Models on the Retrievers tab, click **New Retriever**.
2. Select **Ensemble Retriever** as the retriever type. Click **Next**.
3. Select the data space in Data Cloud where the data sources are located for your ensemble retriever. Click **Next**.
4. Select two or more individual retrievers to add to this ensemble retriever. Click **Next**.
- Ensemble retrievers don't support retrievers of type Code.
- Individual retrievers with dynamic filters can’t be part of an ensemble retriever.
Ensemble retrievers don't support retrievers of type Code.
5. Configure which information to return and how much.
1. Specify the maximum number of results to return.
2. Specify one or more fields that ground the prompt. For each field selected, enter a unique, descriptive label for the retrieved information.
3. Click **Next**.
6. Review your selections.
1. To change a selection, click the Edit icon.
2. Save your changes, and specify a retriever name and an optional description.
3. Save your changes.
When you create an ensemble retriever, AI Models creates the first version. Each time you edit and save an updated retriever, AI Models creates another version.

Note The ensemble retriever isn’t available for use in prompt templates until you activate a version.
#### See Also
- [Test an Ensemble Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_ensemble.htm&release=264.0.0&type=5 "Test an ensemble retriever configuration in the AI Models retriever playground before you use it in prompt templates or AI agents. Add or remove retrievers to an ensemble, configure test data, and result parameters to verify the retrieval logic.")
# Create an External Activation Platform Using JSON (ISV Partners)
Build an external activation platform in Data 360 Developer Edition using the Activation Toolkit to engage your customers.
### Required Editions
Available in: Developer Edition
User Permissions Needed
To access Data 360 Setup
System admin profile OR
Data Cloud Architect permission set
1. Click the gear icon and click **Data Cloud Setup**.
2. Click **External Activation Platform**.
3. Click **New**.
4. Select **JSON**.
5. Upload or copy the JSON in the textbox.
6. Click **Save**.
The new external activation platform based on the JSON file is created. For detailed field descriptions and JSON examples, see [JSON Metadata Usage and Examples](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_toolkit_isv.htm&release=264.0.0&type=5 "Here are the JSON examples followed by the field descriptions and best practices to help you define your external activation platform.").
- **[JSON Metadata Usage and Examples for External Activation Platforms](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_toolkit_isv.htm&release=264.0.0&type=5)**
Here are the JSON examples followed by the field descriptions and best practices to help you define your external activation platform.
# Create an External Activation Platform Using the Manual Workflow
Create an external activation platform in a Data 360 Developer Edition org to help you reach your customers on your platform.
### Required Editions
Available in: Developer Edition
1. Click the gear icon and click Data 360 Setup.
2. Click **External Activation Platform**.
3. Click **New**.
4. Click **Manual**.
5. Enter information about the platform that you want displayed for the Data 360 admin. A preview appears on the right-hand side.

Important The Developer Name you create in Data 360 is needed later when you create custom metadata.
6. Click **Next**.
7. For each field:
1. Configure the required AccountId field by clicking the dropdown button. Click **Edit**.
2. In the Help Text, provide instructions for your Data 360 admin on how to find their AccountId.

Note The Value stored in the AccountId field is in the file path and metadata file so you know where to ingest the data.
3. If you’d like to add more fields, click **Save & Add**. If you’re done adding fields, click **Save & Close**.
8. Click **Next**.
9. Select at least one Contact Point (also known as identifiers) you want to receive.

Note Select a hash method for Phone Number and Email Address Contact Points. The email address is trimmed of whitespace and converted to lowercase.
10. Click **Next**.
11. Select your Activation Schedule, Delivery Platform, and Data Delivery Options.

Warning Enter the S3 Bucket Name where you want segments delivered. We ask for your S3 AccessKey and SecretKey when you create custom metadata.
12. Click **Save**.
Your external activation platform is created.
# Create an External Platform Activation Target
To publish segments to your external advertising platforms like Amazon Ads, create an external platform activation target in Data 360. An external platform can have multiple activation targets, but you can attach only one activation target to an external platform account.
### Required Editions
Permission Sets Needed
To create activation targets:
Any one of these permission sets:
Make sure that you've completed these tasks before creating an external activation target:
- [Install a managed package](https://help.salesforce.com/s/articleView?language=en_US&id=xcloud.distribution_installing_packages.htm&type=5) required for using AppExchange-based external activation platforms.
- [Set up an external activation platform](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_external_activation_platform.htm&type=5&language=en_US) after installation. Set up platform parameters, authentication details, and required mappings.
- [Ingest and Model Digital Identifiers for JSON-based External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_map_digital_identifiers_activation_toolkit.htm&release=264.0.0&type=5 "Ingest and model your digital identifier data by using the standard ContactPointDigitalId data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.").
1. On the Activation Targets tab, click **New**.
2. Select an external activation platform, and click **Next**.
3. Enter a name and an optional description.
If the privacy type isn't set, update the external activation platform to include a privacy type.
4. Add the platform's account and login details, and click **Next**.
5. For certain advertising platforms, you’ll redirected to its site to enter your login details. Enter your login details, if required.
1. Grant access permissions to Data 360, and accept the terms of service.
You’re redirected to Data 360 and provided with the accounts that you have permission to upload audiences to.
2. Select the data space you want to associate your activation target with.
3. Select the Account Name and ID.
The selected data space determines which Account IDs are available to create a unique combination for single use.
For external activation targets for advertising audiences, you can create activation memberships only from the Individual DMO.
4. For Amazon Ads, if you have access to both an Amazon DSP account and AMC instance, you’re prompted to select an account for each.
If you select both DSP and AMC for a new activation target, make sure that your accounts are linked in Amazon Ads. Then, you can view the DSP account performance data in the AMC instance.
6. If you're using a platform installed from AppExchange, enter your Account ID.
Each account ID is unique and you can use it for only one activation target.
1. Select the data space you want to associate your activation target with.
7. Click **Save**.
- **[Requirements for External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_requirements_for_external_activation_targets.htm&release=264.0.0&type=5)**
Consider these requirements when creating an activation target to an external platform account in Data 360.
# Create an Individual Retriever
To improve the relevancy of the content returned to a prompt for a particular use case, create a custom individual retriever in AI Models (formerly Einstein Studio). To customize the retriever, select its search index, define filters, and specify what information it returns.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, and
delete)
Allow users to manage models in AI Models AND Access to Field Relationship Path
object
OR
Data Cloud Architect Permission Set
To access data with retrievers
For the Knowledge object, make sure that the user has read access to the
Knowledge object and has the App Permission: Allow View Knowledge
For all other
standard objects, make sure that the user has read access to the object and
appropriate sharing rules. For more information see, Set Your Internal Organization-Wide Sharing
Defaults
1. In AI Models on the Retrievers tab, click **New Retriever**.
2. Select **Individual Retriever** as the retriever type. Click **Next**.
3. Select Data Cloud as the data source for the retriever.
1. Select the data space in Data Cloud where the search index resides.
2. Select the data model object (DMO) associated with the search index.
3. Select the search index.
4. Click **Next**.
4. (Optional) Define filters to narrow the search results.
Retriever filters are available only if the search index that you selected has filter fields defined.
1. Select **Filter Documents to Return**, and specify up to 10 conditions to apply.
2. Select the condition requirements.
For example, to define a specific subset (such as Category = Hardware AND Language = German), select **All Conditions Are Met**. If different conditions support the same goal (such as Priority = High OR Escalated = True), select **Any Condition is Met**.
Select **Custom Condition is Met** to create a custom logic with numbered conditions (such as, 1. Car Make = Honda, 2. Car Model = Civic, 3. CarYear greater than 2000. Create a custom condition like 1 AND (2 OR 3)).
3. For each condition, click **Add Condition** and select a field in the search index, an operator, and a value. The field’s data type, such as text or number, determine which operators are available.
4. Click **Next**.
5. Configure which information to return and how much.
1. Specify the maximum number of results to return.
2. Specify one or more fields that ground the prompt. For each field selected, enter a unique, descriptive label for the retrieved information, and select the field in the search index.
Select only fields that augment the prompt for your use case and help make prompt responses more accurate and relevant.
3. Click **Next**.
6. (Optional) Turn on citations for this retriever.
1. To automatically generate citations that include the source URL, and a heading text, select **Standard Citations**.
2. To customize the citation, select **Custom Citations**. Optionally, enter a base URL, source DMO field that contains the full link or a URL path that can be combined with the base URL, and the source DMO field to use for the citation heading.
For example, if the source DMO contains a citation to a specific help page such as [Retrieve Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever.htm&type=5&language=en_US). Enter a base URL of [https://help.salesforce.com/s/articleView?id=](https://help.salesforce.com/s/articleView?id=&language=en_US) and the URL path would be the source DMO field that contains the document ID “data.c360\_a\_ai\_retriever.htm”. If the source DMO has a field with the entire URL path, then do not enter a base URL path. Set the URL path to the source DMO field that contains the entire URL path.
Citation headings and links may be surfaced to end-users in downstream applications like Agentforce. Make sure that these fields are populated appropriately and end-users have access to the source links.
3. Click **Next**.
7. Review your selections.
1. To change a selection, click the Edit icon.
2. Save your changes, and specify a retriever name and an optional description.
3. Save your changes.
The retriever isn’t available for use in prompt templates until you activate a version
When you create a retriever, AI Models creates the first version. Each time you edit and save a custom retriever, AI Models creates another version. Retrievers adhere to the data governance policies set up for your data. Make sure that users who call the retriever have permissions to access the data and knowledge queried by the retriever.
#### See Also
- [Activate or Deactivate a Retriever Version](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_version_activate.htm&release=264.0.0&type=5 "Activate a retriever version in AI Models (formerly Einstein Studio) and use it in prompt templates. Only one retriever version can be active at a time. Activating a new version deactivates the current one. Deactivate a version only if no prompt templates depend on it.")
- [Retriever Filters Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_retriever_filter_reference.htm&release=264.0.0&type=5 "Configure filter conditions for retrieval accuracy when you create or test retrievers in AI Models (formerly Einstein Studio). Use filter conditions to filter records retrieved for search queries. You can configure up to ten filter conditions for an individual retriever.")
- [Test an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_create.htm&release=264.0.0&type=5 "Test a retriever configuration to ensure accurate responses from your AI agents. Save retriever configurations as new versions of the retriever in AI Models (formerly Einstein Studio). Activate them for use in agents with prompt templates, Flow, and apps.")
# Create an Intelligent Context Configuration
Creating an Intelligent Context configuration includes these key steps: uploading sample documents for evaluation, configuring the Intelligent Context configuration, testing the results, iterating on the configuration, and publishing to a search index.
### Required Editions
User Permissions
Needed
To create an Intelligent Context configuration:
## Enable Agentforce
Intelligent Context requires generative AI features available through Agentforce.
- Enable Agentforce: If you haven't already, [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&type=5&language=en_US) in your org.
- Turn On Einstein Generative AI: Enable Einstein Generative AI in Data 360.
## Create a Configuration
To get started with a new Intelligent Context configuration, upload up to five unstructured files or select a data model object (DMO) with up to 30 records.
1. In Data 360 home, go to the **Process Content** tab.
2. Select **Intelligent Context** in the left-hand navigation and click **New Configuration**.
3. In the New Search Configuration dialog, choose a data space and name for the search configuration, and click **Save**.
4. From the Intelligent Context page, select your new project.
5. Click **Upload Files** or **Choose different source** to select a DMO.
6. Select a file or a DMO to review its content in the Configuration Preview.
## Configure with AI Smart Defaults
Generate a configuration using AI smart defaults.
1. In the agent chat, click **Set up my configuration using smart defaults**.
2. Review the configuration summary, and choose to accept or modify it.
1. If you accept the configuration, continue to [Test and Evaluate a Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_intelligent_context_create_configuration.htm&release=264.0.0&type=5).
2. If you want to modify the configuration, continue to [Modify an Intelligent Context Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_intelligent_context_create_configuration.htm&release=264.0.0&type=5).
## Modify an Intelligent Context Configuration
The configuration preview shows the generated chunks created from your source documents. Modify these configuration settings as necessary.
1. Click the **Edit Configuration** tab.
2. To change the search type, click **Select Search Index Type**, and choose vector or hybrid search.
Vector Index content based on semantic meaning. Hybrid Index content based on semantic meaning and keywords.
3. To change how your content is parsed, click **Set Parsing Options**.
You can't select both LLM-based parsing and LLM-based Visual Data Preprocessing options. Review [LLM-based parsing and preprocessing](https://help.salesforce.com/s/articleView?id=data.c360_a_llm_parsing_preprocessing.htm&release=264.0.0&type=5 "Use LLM-based parsing and preprocessing to extract and prepare text, metadata, tables, and images from unstructured documents for chunking.") for more information about these options.
4. Choose one of these options.
Default Parser Extract text using built-in platform settings. LLM-based Parser Extract all text, images, and other visual elements using a large language model (LLM). Docling Parser Extract text from images, tables, and document layouts using the Docling parser.
5. To change how your content is preprocessed for chunking multimodal elements, such as images and tables, click **Set Preprocessing Options**.
Preprocessing extracts context from images and extracts data from tables while maintaining context and relationships.
6. From the Preprocessing dropdown list, choose one of the following:
No preprocessing Default setting. LLM-based preprocessing Use the default prompt as is, or edit it for your specific use case.
7. To extract text from tables, forms, and image captions, turn on **Image Processing**.
8. Click **Select an Embedding Model**, and choose an embedding model from the list.
9. To change how your content is chunked, click **Set Data Chunking Rules**, and choose a [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&type=5&language=en_US).
10. Adjust the token settings as needed.
Chunking Strategy Description
Section-Aware Chunking
Uses title and heading elements to chunk documents. Additional settings:
Max Tokens: Combine adjacent small sections into larger chunks by
adjusting the token size.
Overlap Tokens: Use only if you create multiple chunks from a single
section. Specify the number of tokens to add from the end of each chunk to
the beginning of the next chunk.
Passage Extraction
Uses the semantic meaning inherent in HTML tags to chunk a document into
passages. Additional settings:
Max Tokens: Combine adjacent small sections into larger chunks by
adjusting the token size.
11. Turn on **Knowledge Harmonization** to render your content in a consistent viewing experience without merging the source content.
12. To add and map metadata fields, such as subject and file type, for local file uploads, select **SI Optimization**. Use these fields to apply prepend values to your generated document chunks, or to set pre-filter conditions that refine your search results.
13. Select the metadata fields to prepend to the generated document chunks.
14. Add pre-filter conditions to refine query results based on your metadata field values.
15. Click **Apply Changes**.
When you click the button, Data 360 automatically generates and displays a new set of content chunks in the Configuration Preview pane.
16. Continue to test and evaluate your configuration.
## Test and Evaluate a Configuration
To verify search quality and chunk accuracy, test your configuration by asking questions in the agent chat pane, or compare the generated chunks with your source documents. Each generated chunk displays a confidence score, a source file reference, and a citation.
1. In the agent chat pane, select a suggested question or enter your own query in the chat box.
2. To open the source file in the preview pane, click a generated chunk. You can also search or filter the list of chunks.
3. To compare the generated chunks directly with the source document, click **Compare with Source**.
4. To make further changes to your configuration, follow the steps in [Modify an Intelligent Context Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_intelligent_context_create_configuration.htm&release=264.0.0&type=5).
5. Continue to publish your search index configuration.
## Publish the Search Index Configuration
Before you can publish your configuration, you need to set up an unstructured data connection to ingest your source files. Set up an unstructured data connector to ingest your source files into an unstructured data lake object (UDLO) in Data 360. See [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&type=5&language=en_US) for a list of connectors.

Note If you've selected a DMO to create the configuration, you don't need to set up an unstructured data connector.
After you test and modify your configuration, the final step is to publish it to make it available for use in your org.
1. From Intelligent Context, click **Publish**.
2. In the Select an Unstructured Data Model Object dialog, select a data model object to apply the configuration to.
3. Click **Next**.
4. In the Create Search Index dialog, confirm or change the index name, and click **Publish**.
5. Navigate to the Content Indexing or Search Index pages to review the results.
6. To manage and review your harmonized objects in Data 360, go to the Knowledge Harmonization page under **Process Content**.
# Create an Object or Field-Level Access Policy in Data 360
In data governance, define who can access specific data objects or fields based on user and data attributes. Create object-level or field-level access policies for users.
### Required Editions
Before completing this task, review these considerations.
- Data 360 enforces service protection limits on Object-Level Security (OLS) and Field-Level Security (FLS) policies to prevent complex policies from affecting system performance. The impact depends on the number of rules and condition complexity. More complex policies have a greater impact.The system checks these limits when you create, edit, or delete a policy. You can't save a policy that exceeds the limit. Simplify the policy or consolidate existing ones.
- When OLS or FLS restrictions are applied to objects within a data graph, the graph is hidden from the list view to prevent unauthorized access. But this filtering doesn’t apply to draft data graphs, since their underlying objects, such as ID or Value DMO, haven’t been created yet. As a result, a draft data graph can still appear in the list view, but opening it displays an error.
- Data 360 architects or users with View All Records (VAR) Modify All Records (MAR) permissions can view the metadata of all objects, even if deny policies are in place. They can add fields, including those restricted by policies, to a report during creation or editing. However, access policies are enforced at runtime. If the Data 360 admin or user doesn’t have access to any of the fields included in the report, the report fails to run and displays an error.
- Index custom user fields before using them in policies for optimal performance.
User Permissions Needed
To create a data access policy:
Permission set:
1. In Data 360, go to the Data Governance tab.
2. In the left pane, click **Policies**.
3. Click **New**, select **Data Access**, and click **Next**.
4. In Policy Builder, enter a unique policy name, and an optional description.
The policy API name is auto-filled based on your policy name, but you can change it.
5. Select the user authorization level. For more information, see [Controlling External User Access in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_control_external_user_access.htm&type=5&language=en_US).
6. Click **Next**.
7. Select **Rules**, and select the resources to protect. In the **Resource** dropdown, select **Object** or **Field**.
By default, the rule applies across all data spaces. As new data spaces are added, these rules apply to their resources.
8. To restrict policies to specific data space scopes, click **Customize Scope**, deselect Apply to the resources in all Data Spaces in Data 360, and select the desired data spaces.
9. Click **Save**.
10. Select the action you want to take on the resource. From the Action dropdown, select **Allow access** or **Deny access**.
Only Deny access is supported in a field-level security (FLS) policy.
11. Define the conditions when this action must take place. For example, set a condition to trigger the rule if the **Financial Data.Account Info** tag is present in the object. Or, if the **Personal Data.Digital Identifier.Browsing History** tag is not present in the object. Trigger the rule when objects meet any or all specified conditions.
12. To add more conditions, click **Add Condition**.
13. Group your conditions into different sets and use the OR operator to take action when any group meets the rule conditions.
14. To add a group, click **Add Group**.
15. To apply the policy to users, select **Users**.
1. Apply the policy to all users or to users who meet specific AND and OR conditions. The conditions are based on custom permissions or standard user attributes assigned to users. Standard user attributes include:
- Call Center ID
- Company Name
- Department
- Division
- Profile ID
- Title
2. Custom user fields are also supported, such as `Department__c` or `Region__c`.
3. Related object fields are supported using relationship notation. For example, `AssignedBrands__r.BrandName__c` or `Departments__r.DepartmentCode__c`.
16. Click **Save and Activate**.
# Create an Omnichannel Audience in Data 360
Let’s review the steps that Cumulus takes to create their Omnichannel audience in Data 360.
# Create an SMS Journey in Journey Builder
With the data extension located and content reviewed, Cumulus can now build the SMS campaign.
You can build this campaign in Journey Builder.
1. In Marketing Cloud Engagement, go to **Journey Builder**.
2. Click **Create New Journey**.
3. Select **Multi-Step Journey** and then click **Create**.
4. For the entry source, drag a **Data Extension** activity to the canvas.
5. Click the **data extension activity** and select **Modified Account**
6. To ensure a contact is opted into SMS, follow these steps.
1. Click **Edit** from **Filter Contacts**
2. From the Attribute list under MobileConnect Data, select **MobileConnect Demographics**, then select **Status**.
3. Drag **Status** to the canvas and click the pencil icon.
4. Set Status so that it equals **Active** and click **Done**
5. Click **Summary** and then click **Done**.
7. Now we can create an SMS message directly in Journey Builder.
1. Drag an **SMS** activity to the interface.
2. Click the **SMS** activity and click **New Message**.
3. Under Message Definition, add your message. For example, for this campaign:
```html
Congrats, %%=v(@First_Name)=%%!! Your %%=v(@program_name)=%% loyalty status level has changed to
%%=v(@loyalty_tier)=%%!
```
4. From the dropdown, select a code type and click **Save**.
8. Under Message Configuration, click **Edit** from the section.
1. Select the **code** the message can be sent from and an optional **From Name**.
2. Click **Delivery Options**.
3. Read and agree to the Opt-Out Availability Policy.
4. Confirm subscriber opt-in from a keyword. If users are already unsubscribed from a keyword, this action doesn’t resubscribe them.
5. Set a blockout window when you don’t want the text message to be sent.
6. Click **Summary**.
7. To check how subscribers see the message, click **Subscriber Preview**.
8. Click **Done**.
9. Click **Set Schedule** and select the start date, time, and time zone. For this campaign, select every **1** day, repeating **Daily**, and **Never** ending.
10. Click **Contact Evaluation** and select **Evaluate new records only**.
1. For the first run, evaluate **All records in the file**.
2. Click **Summary** and then click **Done**.
11. Review the journey, and click **Save**.
12. To ensure that all information has been completed, click **Validate**.
13. Test the journey and then click **Activate** when ready.
The campaign is ready for customers.
# Create an Unstructured Data Lake Object from a Data Kit
After you have deployed your data kit in Data 360, you can create an unstructured data lake object (UDLO). All fields are automatically mapped.
### Required Editions
User Permissions Needed
To create a UDLO from a data kit
Permission set:
1. From App Launcher, select **Data Cloud**.
2. Click **Data Lake Objects** > **New**.
3. From the New Data Lake Object menu, select **Create from a Data Kit**, and click **Next**.
4. From your data kit, select one DLO, and click **Next**.
5. From the Select Connection dropdown list, select a connection. Data 360 auto-populates the source based on the connection that you select.
6. In the Directory field, point to a specific folder or an entire directory in your blob store. All folders and subfolders in a directory are included. Optionally, use wildcard characters to specify a file name pattern for multiple files.
7. To add more directories, click **More Files**. You can include up to 5 directories.
8. Click **Next**.
9. Add an Object Name and an Object API Name for the UDLO. See Data Lake Object Naming Standards.
10. From the Data Space dropdown list, select a data space in which to create the new unstructured data model object (UDMO) or a data space from which to select an existing UDMO.
11. Map the UDLO to a UDMO.
- To create a new UDMO, click **New.**
- To use an existing UDMO, click **Existing**, and select a UDMO from the list.
12. Optionally, leave the checkbox selected to create a search index configuration for the UDMO using system defaults that automatically selects text fields and a chunking strategy for each field.
You can deselect the checkbox and create a search index configuration later if you choose not to do so now.
13. Click **Next**, or if you created a search index configuration, review the details, and save your work.
# Create and Install Your Managed Package for Data 360
Use a managed package to build a Data 360 app and distribute it on AgentExchange. Packaging is the container that you fill with metadata, and it holds the set of related features, customizations, and schema that make up your app. A package can include many different metadata components, and you can package a single component, an app, or library.
### Required Editions
User
Permission Set Needed
To create packages:
Create AgentExchange Packages permission
To upload packages:
Upload AgentExchange Packages permission
To create a data kit:
Data Cloud Architect permission set
Use managed packages to distribute Data 360 solutions on AgentExchange or share configurations across multiple customer orgs. Managed packages provide versioning, upgrade management, and intellectual property protection — making them ideal for ISVs and partners who want to commercialize Data 360 functionality.
You need a Salesforce developer edition org to create the package and a subscriber org to install it. Salesforce offers second-generation managed packaging (managed 2GP) and first-generation managed packaging (managed 1GP). This topic describes how to create a managed 1GP package. For details on packaging Data 360 in managed 2GP packages, see [Workflow for Data Cloud Second-Generation Managed Packages](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/data-cloud-2gp-workflow.html).
1. In Data 360, go to **Setup**, and create a package with the Package Manager. See [Create and Upload a First-Generation Managed Package](https://developer.salesforce.com/docs/atlas.en-us.pkg1_dev.meta/pkg1_dev/uploading_packages.htm).
2. Define a unique namespace for the managed package.
3. To add the necessary components, in Components, click **Add**.
4. For the Component Type, select **Data Package Kit Definition** .
5. Create a standard data kit or select an existing data kit, and click **Add to Package**.
All entities related to data kit metadata are added to the package automatically.
6. Add the package version details.
7. To generate your package installation URL, click **Upload**.
8. Copy the install URL, go to your target org, and use the package install URL to install the package.
Installing a package requires admin user permissions.
After installing the package in the target org, your data kit is now available to deploy data streams and other components in Data 360.
#### See Also
- [_Salesforce Help_: Create and Publish a Standard Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_bundle_package_kits.htm&release=264.0.0&type=5 "Streamline package creation and the installation experience for Data 360 objects by wrapping together the metadata and relationships into a standard data kit. Use a Developer Edition org that supports managed packages to create and publish a standard data kit. Use a DevOps data kit to migrate metadata across orgs.")
# Create and Publish a Standard Data Kit
Streamline package creation and the installation experience for Data 360 objects by wrapping together the metadata and relationships into a standard data kit. Use a Developer Edition org that supports managed packages to create and publish a standard data kit. Use a DevOps data kit to migrate metadata across orgs.
### Required Editions
User Permission Set
Needed
To create a data kit:
Permission set:
## Step 1: Create a Standard Data Kit
Use this process to create a standard data kit for a first-generation managed package. For packaging Data 360 in a second-generation managed package using a data kit, see [Workflow for Data 360 Second-Generation Managed Packages](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/data-cloud-2gp-workflow.html).
1. In your Developer Edition org, go to **Data Cloud Setup**.
2. Under Developer Tools, click **Data Kits**.
3. Click **New**.
4. Name the data kit and add an optional description, such as what it contains.
5. Save your changes.
## Step 2: Add Data 360 Features to a Data Kit
1. Add one or more of the Data 360 features by clicking **Add** in the appropriate section, then configure the data kit details.
To find out which Data 360 features are packageable, see [Data 360 Extensibility Readiness Matrix](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_isv_readiness_data.htm).
2. Save your changes.
## Step 3: Publish a Data Kit
1. To review the auto-publishing sequence of the components, click **Publishing Sequence**.
The system publishes components based on their creation dates. When there are dependencies between components, clearly define the sequence order. For instance, if segments rely on calculated insights, place the calculated insights before the segments. This ensures all necessary data is available and up-to-date when the segments are published.
2. Click **Publish**.
Your data kit is published. You can now upload the data kit in Package Manager and deploy the data kit components in your Salesforce org.
#### See Also
- [_Salesforce Help_: Add a Data Kit to a Package](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_package_kit.htm&release=264.0.0&type=5 "After creating and publishing your data kit in Data 360 source org, add the data kit to a package and upload it using Package Manager in your Salesforce org.")
- [_Salesforce Developers_: Data 360 Extensibility Readiness Matrix](https://developer.salesforce.com/docs/data/data-cloud-ref/guide/c360a-api-isv-readiness-data.html)
- [_Salesforce Developers_: Data 360 Developer Guide](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/data-cloud-2gp-workflow.html)
# Create Communication Capping Rules
Create capping rules to apply to the communication capping activation targets in Data Cloud. You can create a capping rule in the UI or by uploading a JSON file with the rule conditions. You can apply rules individually at each parameter level or cumulatively at the enterprise level.
### Required Editions
Permission Sets Needed
To create a Communication Capping
rule
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. On the Capping Rulesets tab, select **New**.
2. To create a rule using the UI workflow, select **Create from Scratch**.
3. Click **Next**.
4. Configure the rule.
1. For Start Date and End Date, enter the timeframe for which the rule is valid.
2. Select the parameter values from the dropdown list.
The available parameters are based on how Communication Capping was set up.
3. For Frequency, select how often to apply the rule.
4. Select the limit type.
Profile limits cap communications to individuals filtered by the selected parameters. Parameter limits apply to channels and other parameter values.
5. Select the communication channel.
6. For Limits, enter the maximum number of communications that can be sent through the selected channel.
5. Save the rule.
The communication capping rules are created. You can create as many rules as required. You can edit, delete, or copy a rule by using the dropdown menu in the row.

Example For the following rule settings, no more than one SMS per day is sent to any individual who has purchased an insurance policy and falls into the Medium net worth category.
- Lines of Business: Insurance
- Net Worth Category: Medium
- Limit Type: Profile
- Limit: 1
- Channel: SMS
- Frequency: Daily
After creating the capping rules, create a communication capping activation target.
# Create Custom Metadata for Your External Activation Platform
Create custom metadata for your external activation platform before you can package your platform for use by Data 360 admins. This applies only to platforms created using the manual workflow.

Note Activation Schedule supports publishing every 24 hours.
1. Click the gear icon and click **Setup**.
2. In Setup, go to **Custom Metadata Types**.
3. Click **New Custom Metadata Type**.
4. Enter ActivationPlatformCredential for the Label and ActivationPlatformCredentials for the Plural Label.
5. In Visibility, select **Only Apex code in the same managed package can see the type. The name of the type and the record are visible if they're referenced in a formula.**

Note Selecting a different option could expose your Amazon S3 bucket credentials to customers who install your package.
6. Click **Save**.
7. Click ActivationPlatformCredential.
8. In Custom Fields, click **New**.
1. Select Text and click **Next**.
2. Enter AccessKey for the Field Label and Field Name and click **Next**.

Tip We recommend 150 for Length, but you can set any limit.
3. Make sure the ActivationPlatformCredential Page Layout is selected.
4. Click **Save & New**.
5. Select Text and click **Next**.
6. Enter SecretKey for the Field Label and Field Name and click **Next**.

Note We recommend 50 for Length, but you can set any limit.
7. Make sure the ActivationPlatformCredential Page Layout is selected.
8. Click **Save**.
9. Click **Manage ActivationPlatformCredentials**.
1. Click **New**.
2. The label and ActivationPlatformCredential name must match the developer name you chose when creating your external activation platform in Data 360.
3. Enter the value for AccessKey and SecretKey.

Tip Use the credentials for the S3 Bucket Name you entered when you created your External Activation Platform in Data 360.
4. Click **Save**.
The custom metadata for your External Activation Platform is created.
# Create Data 360 Users and Assign Permissions
Create users and provide access to Data Cloud features like identity resolution, transforms, and calculated insights.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud
Architect permission set
1. Go to **Data Cloud Setup**.
2. Under User Management, click **Users**.
3. Add new users or edit an existing user.
4. Select a user and click **Permission Set Assignments**.
5. Click **Edit Assignments**.
6. Select the appropriate Data Cloud permission set and click **Add**.
7. Click **Save**.
Repeat these steps for all users needing access to Data Cloud features.
- **[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5)**
A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.
- **[Custom Permission Sets in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_custom.htm&release=264.0.0&type=5)**
To create a Data Cloud custom permission set, we recommend cloning an existing standard Data Cloud permission set. Some Data Cloud features can’t be accessed with permission sets created from scratch.
- **[Migrate Data Cloud Permission Sets using User Access Policies](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_perm_set_migration.htm&release=264.0.0&type=5)**
Learn how to use user access policies to grant updated Data Cloud permission sets to groups of users based on criteria you set.
- **[Manage Data Cloud Data Access Levels for Salesforce Users](https://help.salesforce.com/s/articleView?id=data.c360_a_data_access_levels_setting.htm&release=264.0.0&type=5)**
You can configure permission sets to grant Salesforce users view access to related list enrichments or other SOQL queries to Data Cloud data without granting access to Data Cloud or permission to view Data Cloud in other contexts.
# Create Data Share Target to Connect with a Data 360 Org
Create a data share target in Data 360 to establish connectivity with another Data 360 org.
### Required Editions
1. In Data Cloud, on the Data Shares Target tab, click **New**.
2. For the connection type, select **Salesforce Data Cloud**, and click **Next**.
3. Enter these details.
- Data Share Target Name - The display name of the data share target. There’s no character limit.
- API Name - This field is auto-populated to match the target name, but you can use a different name.
- Target Org’s My Domain URL - Enter the My Domain URL of the target org. Find the URL in Company Settings -> My Domain in the Setup of target org. For example, https://mycompany.my.salesforce.com or https://mycompany.my.site.com
- Target Org ID - Enter the target organization ID.
4. Copy and share the Org ID, Offcore Tenant ID, and My Domain URL with your target org admin so they allow you to share data with their org.
5. Click **Save**.
A notification is sent to the target Data 360 org to accept the request. If you don’t see a notification, go to the Data Share target in the source org and click **Resend Invite**.
# Create Data Streams from a Marketing Cloud Engagement Starter Bundle
To begin the flow of data from a Marketing Cloud Engagement source to Data 360, create data streams from starter bundles. Data 360 only supports formula fields for the Salesforce Marketing Cloud (SFMC) Enterprise Profile Attribute data stream.
### Required Editions
User Permissions Needed
To create a data stream
Permission set:
1. In Data 360, on the Data Streams tab, click **New**.
2. Select the Marketing Cloud Engagement data source, and click **Next**.
3. From the Connections menu, select the Marketing Cloud Engagement connection you want to configure.
4. Select the data spaces to be mapped to the business units of the chosen connection.
5. Select a starter data bundle.

Note You can configure only one starter bundle at a time. If the starter bundle has previously been ingested into Data 360, it’s unavailable and can’t be selected. If you don’t see the starter bundle that you want, make sure that your Data 360 admin has provisioned the bundle.
6. Review the list of data streams and the fields ingested for each.
7. Click **Next**.
8. Review the list of data streams that Data 360 automatically creates, and then click **Deploy**.
9. Click one of the newly created data streams to review the field list.
10. Click **Review Mappings**.
11. Review how data lake objects (DLOs) are mapped to data model objects (DMOs).
Your Marketing Cloud Engagement data streams are created, and you’re ready to start using your data.
#### See Also
- [_Salesforce Help_: Formula Expression Library](https://help.salesforce.com/s/articleView?id=data.c360_a_formula_expression_library.htm&release=264.0.0&type=5 "When you create a Data 360 data stream, you can choose to generate more fields. These supplemental fields can be hard-coded or derived from other fields in the data stream.")
- [_Salesforce Help_: Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.")
# Create Identity Resolution Rulesets
Get started with identity resolution by setting up a ruleset to unify accounts, individuals, leads, or households. The primary data model object for your ruleset determines which records are unified. Match and reconciliation rules you add to your ruleset after creating it guide how records are matched.
### Required Editions
Permission Sets Needed
To create identity resolution rulesets:
Permission set:
1. On the **Identity Resolutions** tab, click **New**.
2. Select a data space.
3. Select the primary data model object that your ruleset will be based on.
- If you don’t see any objects available, make sure your data is modeled properly and that you haven’t reached the maximum number of rulesets.
- Household unification is available only after you run a ruleset based on Individuals.
4. Add an optional ruleset ID of up to four text characters.
Optionally, add a ruleset ID of up to four text characters. The ruleset ID can’t be changed and becomes part of the data model object names and API names. If you have two rulesets for an object, at least one must have a ruleset ID.

Tip Use test as a ruleset ID. After using the test ruleset to test different combinations of match and reconciliation rules, delete the ruleset. If you delete a ruleset and want to use the same ruleset ID again later, you could encounter an error. Wait for Data 360 to finish deleting the ruleset with your desired ruleset ID and try again.
5. Click **Next**.
6. Name your ruleset and add an optional description.
If your ruleset will unify individuals, you can opt to link all individuals who share the same individual ID and key qualifier.
7. If you’re creating a ruleset to unify households, select the Individual ruleset whose output will be used as the source data for the households.
8. Make a note of the data model object and API names created by the ruleset.
9. Click **Save**.
Add match rules and reconciliation rules to your ruleset.

Note Rulesets are scheduled to run at least one time per day after publication. To prevent unnecessary credit consumption, we recommend disabling Run jobs automatically while you're configuring a ruleset. Use the **Run Now** button to run a ruleset during configuration.
The consolidation rate on the ruleset's identity resolution summary details the results of the last successfully completed run. Compare the consolidation rates of two rulesets to determine which better meets your needs. To reduce usage costs, we recommend keeping only one active ruleset.
- **[Filter Source Records for Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_filter_records.htm&release=264.0.0&type=5)**
Control which source records enter the identity resolution processing pipeline by defining filter conditions on your ruleset's primary data model object. Filters act as a preprocessing gate, so that only records matching your conditions enter the unification pipeline. Using filters helps keep unified profiles clean and reduces credit consumption.
- **[Delete an Identity Resolution Ruleset](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_deletion.htm&release=264.0.0&type=5)**
Deleting a ruleset permanently removes all unified customer data, eliminates dependencies on data model objects, stops all processing of the ruleset, and deletes the history of previous runs. In some cases, it’s better to update the match or reconciliation rules instead of deleting the ruleset.
#### See Also
- [_Salesforce Help_: Configure Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5 "Specify how identity resolution identifies matching records in Data 360.")
# Create Insights from Templates
Create Data 360 Insights efficiently using templates. To simplify insight creation, templates validate the required Data 360 DMOs, ask simple configuration questions, and set up your new insight.
### Required Editions
## Available Templates:
- **[Shopping Cart Insight Template](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_shopping_cart_template.htm&release=264.0.0&type=5)**
The Data 360 shopping cart insight template creates a calculated or real-time insight based on actions in your customer’s shopping cart. Analyze customer interactions with their shopping cart, from items added to purchases completed or abandoned. Shopping cart insights provide a view of the customer's current shopping cart state.
- **[Create a Shopping Cart Insight](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_create_shopping_cart.htm&release=264.0.0&type=5)**
Create a shopping cart insight to understand customer interactions and optimize their journey. This process involves selecting an individual data model, choosing real-time or batch processing, and defining event values. Gain valuable insights into shopping trends and improve conversion rates.
# Create Omnichannel Journeys Using Unified Individual Profiles in Data Cloud
Learn how to set up and use audience activations from Data Cloud to power an omnichannel journey in Marketing Cloud Engagement. This guide walks you through an example of how you can enable an omnichannel experience for your customers. Instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.
Before implementing an omnichannel journey, read this guide on [Omnichannel Considerations and Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_best_practices.htm&release=264.0.0&type=5 "There are important aspects and trade-offs to consider before implementing this solution. This guide is just one example of how to enable an omnichannel experience for your customers. For example, instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.") to understand the required decisions and processes.
This solution kit makes these assumptions. You’re creating an omnichannel journey in Marketing Cloud Engagement that contains email, SMS, and MobilePush channels. Your organization has implemented single-channel contacts for Engagement for all three channels but hasn’t implemented omnichannel contacts.
## Use Case 1
Cumulus Bank and Financial Services want to create a 30-day Credit Limit Alert journey for customers approaching or reaching their credit limit. The journey broadcasts a high-priority message on all possible channels to inform customers that they’ve reached their credit limit. Then, the journey follows up with more targeted communications informing customers on whether they qualify for an additional line of credit.
To complete this use case, review the features used, permissions required, and associated skills.
Products or Features
Data Cloud
Activation
Activation Target
Calculated Insight
Identity Resolution
Marketing Cloud Engagement
Contact Builder
Journey Builder
Roles and Permissions
Data Cloud
Data Cloud Architect, Data Cloud Activation Manager, or Data Cloud Activaiton Specialist
permission set
Marketing Cloud Engagement
Salesforce Marketing Cloud Engagement | General | Access
Salesforce Marketing Cloud Engagement | Campaigns | General | Access
Contacts | Contact Builder | Administer Contact Model
Requirements or Skills Needed
Understanding of activation and activation targets in Data Cloud
Understanding of the Contact Model in Marketing Cloud Engagement
Understanding Identity Resolution in Data Cloud
Understanding of Calculated Insights in Data Cloud
## Related Content
To help guide you through these use cases we suggest the following related content.
 [_Trailhead_: Data and Identity in Data 360](https://trailhead.salesforce.com/content/learn/modules/data-and-identity-in-salesforce-cdp)
 [_Trailhead_: Explore Synchronized Data Sources](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-contact-management/explore-synchronized-data-sources)
 [_Trailhead_: Segmentation in Data 360](https://trailhead.salesforce.com/en/content/learn/modules/customer-360-audiences-segmentation)
 [_Trailhead_: Marketing Cloud Engagement Contact Management](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-contact-management)

1. **[Associated Terms for Omnichannel Journeys Using Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_terms.htm&release=264.0.0&type=5)**
Review terms that you must know when creating your data foundation.
2. **[Model Your Contact Data for Omnichannel Journeys](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_model.htm&release=264.0.0&type=5)**
This solution kit is designed for customers who have implemented single-channel contacts in Marketing Cloud Engagement. Customers who have implemented single-channel contacts in Marketing Cloud Engagement must follow this solution kit to execute omnichannel journeys. Determine whether you’ve implemented omnichannel or single-channel Contacts.
3. **[Omnichannel Journey Solution Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_workflow.htm&release=264.0.0&type=5)**
Review the solution workflow for creating an omnichannel journey in Marketing Cloud Engagement using data from Data 360.
4. **[Stage Your Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_stage.htm&release=264.0.0&type=5)**
Customers commonly implement Marketing Cloud Engagement to create many different SubscriberKeys (Individuals) that represent the same person. Such SubscriberKeys are often channel-specific and, as a result, can’t natively execute omnichannel journeys. To build an omnichannel journey, use Data 360 and build a Unified Individual that represents a single person consisting of separate Marketing Cloud Engagement channel-specific SubscriberKeys (Individuals) and contact points.
5. **[Define Match Rules for Identity Resolution and Relate Separate Individuals](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_match.htm&release=264.0.0&type=5)**
Let’s review the steps for defining match rules for Identity Resolution and relating separate Individuals in Data 360.
6. **[Define Reconciliation Rules to Prioritize Values for the Unified Individual](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_reconciliation.htm&release=264.0.0&type=5)**
Reconciliation rules specify how to select the best value for a Unified field when that field can store only one value, such as a person’s first name.
7. **[Create a Calculated Insight to Select the MobilePush SubscriberKey](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_ci.htm&release=264.0.0&type=5)**
Data 360 has numerous controls to select and activate a channel contact point. However, for some scenarios, you must create a Calculated Insight to filter or select a specific channel contact point. For example, Data 360 doesn’t support activating the Email, SMS, and MobilePush channels together.
8. **[Create an Omnichannel Audience in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_audience.htm&release=264.0.0&type=5)**
Let’s review the steps that Cumulus takes to create their Omnichannel audience in Data 360.
9. **[Create a Segment to Qualify the Correct Unified Individuals](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_segment.htm&release=264.0.0&type=5)**
Cumulus creates a segment that qualifies the Unified Individuals they want to use for their journey.
10. **[Activate an Audience with Contact Points and Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_activate.htm&release=264.0.0&type=5)**
Cumulus activates an audience with contact points and attributes for their journey.
11. **[Configure Omnichannel Journey Settings in Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_journey_settings.htm&release=264.0.0&type=5)**
After the scheduled activation, a data extension is added to the Marketing Cloud Engagement business unit identified in activation. Edit this data extension and update its send relationship to relate the MobilePush Key attribute to SubscriberKey. As a result, Journey Builder defaults all orchestration, personalization, and sending lookups based on the value of the MobilePush Key (representing the MobilePush SubscriberKey selected from the Calculated Insight you created).
12. **[Update the Send Relationship in the Activated Data Extension](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_relationships.htm&release=264.0.0&type=5)**
Cumulus updates the send relationship in the activated data extension.
13. **[Configure the Journey Entry to Use the Activated Data Extension Audience](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_configure.htm&release=264.0.0&type=5)**
Next, Cumulus configures its journey entry source.
14. **[Configure Omnichannel Journey Settings](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_journey.htm&release=264.0.0&type=5)**
Next, Cumulus configures their omnichannel settings. When a journey uses the Omnichannel Credit Limit Alert data extension Entry Source, Journey Builder defaults all orchestration, personalization, and sending lookups based on the value of the MobilePush Key. This Key is represented by the MobilePush SubscriberKey selected from the Calculated Insight. This action enables you to natively send messages using MobilePush activities.
15. **[Add Consent and Preference Filters to Omnichannel Journeys](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_consent.htm&release=264.0.0&type=5)**
For the email channel, Marketing Cloud Engagement stores consent at the SubscriberKey level and not the email address level. By using the MobilePush Key to send an email to the email address stored in the data extension, Cumulus might have violated their own consent strategy.
16. **[Omnichannel Considerations and Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_best_practices.htm&release=264.0.0&type=5)**
There are important aspects and trade-offs to consider before implementing this solution. This guide is just one example of how to enable an omnichannel experience for your customers. For example, instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.
# Create Predictive AI Models From Scratch
Create models to analyze your data and get AI powered predictions based on machine learning. Learn about supported use cases and ethical model building. Then, follow the steps to create a model and evaluate model quality.
### Required Editions
- **[Supported Predictive Model Types](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_use_cases.htm&release=264.0.0&type=5)**
Predictive models address common business use cases.
- **[Algorithms and Loss Functions](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_algorithms_loss_functions.htm&release=264.0.0&type=5)**
Predictive models analyze historical data to discover patterns and relationships that predict future outcomes. Model Builder provides algorithms for binary, multiclass, and regression models with configurable training settings. When you train a predictive model with a numeric outcome, loss functions measure how far predicted values are from actual values. During training, the model minimizes this loss to improve overall prediction accuracy. The selected loss function determines the types of prediction errors that the model prioritizes.These settings enable you to generate predictions that drive business decisions and surface customer insights.
- **[Design Ethical AI Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_ethical_model_building.htm&release=264.0.0&type=5)**
Salesforce offers guidance to help you practice ethical use of artificial intelligence (AI) in your business.
- **[Prepare Your Training Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_prep_data.htm&release=264.0.0&type=5)**
Effective data preparation is the key to getting great results with your predictive model. Harness the power of data integration in Data 360. Load and transform data from one or more data sources into a data model object (DMO) with optimized training data. You can pull data from Salesforce and external sources. You can also use third-party tools and utilities to further expedite data cleansing and wrangling tasks.
- **[Create a Model from Scratch](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_create_model_steps.htm&release=264.0.0&type=5)**
Create a model that uses historical data to predict future outcomes. Select and structure your data source and define the desired outcome. Then train the model to reveal predictive inferences and insights by using AI, machine learning, and statistical analysis.
- **[Improve Predictive Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_quality.htm&release=264.0.0&type=5)**
Model quality is a critical success factor in predictive AI solutions. AI Models (formerly Einstein Studio) supports continuous, iterative improvement for predictive models. Measure model quality in production over time. Use quality alerts to identify and address areas for improvement. Experiment with new model versions. Efforts to improve model quality result in better business outcomes.
- **[Evaluate Model Quality](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_evaluate_model_quality.htm&release=264.0.0&type=5)**
Use training metrics to evaluate the model’s ability to predict an outcome and determine whether it’s ready to activate. Training metrics provide information about how effectively the model understands patterns and relationships within the training data, and indicates its predictive efficacy.
# Create Queries in Query Editor
Build Data 360 SQL queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.
### Required Editions
User Permission Set
Needed
To create queries:
Data Cloud Activation Specialist
To query a Data 360 object, you must have dataspace access to that object. For more information about data space aware objects, see [Data Space Aware Objects and Features](https://help.salesforce.com/s/articleView?id=data.c360_a_data_space_aware_features.htm&release=264.0.0&type=5 "User access to data space-aware objects and features is controlled by setting the object permissions and feature permissions in the user's permission sets. Not all objects and features are data space aware.").
1. In Data Cloud, go to the Query Editor tab.
2. Select a workspace or create a workspace.
A workspace defines which objects and metadata your queries can access.
3. In the left pane, select a Data Cloud object.
4. From the dropdown list, select how you want to create the query.
5. Customize and build a query based on your requirements. The editor suggests the fields as you build the query.
You can also add other Data Cloud objects and query across multiple objects using SQL joins. For help with Data Cloud SQL, see [Get Started With Data Cloud SQL](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/dc-query-section.html).
6. Choose **Run Query** and view the results.
7. To keep the query for future reference, choose **Save**.
# Create Segments in Data 360
Use segmentation in Data 360 to break down your data into useful segments to understand, target, and analyze your customers. After you create a segment, you can publish it to an activation target.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
You can create segments on objects from your data model, and then publish them on a chosen schedule or as needed. Whether basic or complex, segments are crucial in using Data 360. Learn about building segments with the attribute library, extending segments with calculated insights, and filtering your segment data.
Limitations with Composite Keys:
- The Segment Canvas relies on predefined relationships to join data. Because these relationships currently support only a single field, Data 360 can't automatically join data using all fields in a composite key. This can lead to inaccurate population counts or segments that randomly select only one field for the join.
- Composite keys function correctly only when users write manual queries where every field in the composite key is explicitly defined in the join logic.
- To ensure consistent and accurate results in segmentation, use data model objects (DMOs) with a single, unique primary key.
- **[About the Data 360 Marketing Agent](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_agent.htm&release=264.0.0&type=5)**
The Data 360 Marketing Agent helps you with segmentation in Data 360. Describe what you want in natural language, and the agent works in the Agentforce panel to complete the request.
- **[Create a Standard Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&release=264.0.0&type=5)**
Create a standard segment based on a data model object and then publish the segment to activation targets.
- **[Create a Real-Time Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_realtime_segment.htm&release=264.0.0&type=5)**
Create a real-time segment that completes on demand in milliseconds. To make the segment available in your real-time data graph, add the Segment ID and Timestamp fields from the segment membership DMO object to the real-time data graph. You can’t use a real-time segment with exclusion criteria and nested batch segments. You also can't use segment counts and manual publish with a real-time segment.
- **[Create a Waterfall Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_waterfall_segment.htm&release=264.0.0&type=5)**
If you’re running a campaign with multiple offers, use a waterfall segment to process a list of existing segments in a priority order. The primary goal is to ensure that an individual who qualifies for more than one segment is placed only into the highest-priority segment they match. This creates a series of mutually exclusive audiences, which is ideal for campaigns where you want to send customers only one, most-relevant offer.
- **[Create a Dynamic Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_dynamic_segment.htm&release=264.0.0&type=5)**
Create a dynamic segment based on a Data Model Object (DMO) and run segment queries without persisting data in Segment Membership DMOs. Define attribute filters with placeholders that accept dynamic values at execution time.
- **[Create a Segment from a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_from_data_kit.htm&release=264.0.0&type=5)**
Instead of creating a segment from scratch in Data 360, use a predefined segment from a data kit. You can edit and fine-tune the segment.
- **[Segment Canvas](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_canvas_interface.htm&release=264.0.0&type=5)**
Use the segment canvas in Data 360 to select direct and related attributes to narrow down a created segment to your target audience.
- **[Troubleshoot Segment Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_troubleshooting.htm&release=264.0.0&type=5)**
Get tips for solving the most common segment errors in Data 360.
- **[Segmentation Filter Examples](https://help.salesforce.com/s/articleView?id=data.c360_a_examples_of_segmentation_filters.htm&release=264.0.0&type=5)**
Review examples of filters for various types of segmentation use cases. Use these examples as a starting point for your segments, which you can tailor by adding more filters to fit your campaigns.
- **[Einstein Segments in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein.htm&release=264.0.0&type=5)**
Create segments with Einstein Segment Creation generative AI. Enter a high-level description of your segment and receive a suggested segment and all its attributes. Easily draft another segment by changing the description, or edit the segment’s attributes to make adjustments. After you’re satisfied with your segment, publish and activate it.
- **[Billing Considerations for Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_segmentation.htm&release=264.0.0&type=5)**
Segmentation uses Data 360 for processing and publishing segment data. Use of segmentation impacts the consumption of credits in these usage types.
# Create the Audience Segment in Data 360
In Data 360 create an audience segment for a gold status notification campaign.
1. Log in to Data 360.
2. From the **Segments** tab, click **New**.
3. To base the new audience segment, select the Unified Individual DMO.
4. Name the segment Push Loyalty Campaign, add a description, and select a publish schedule of 24 hours.
5. Add a start date and time and an expiration date, and click **Save**.
6. From the related attributes list, select **Loyalty Program Member** and select **Loyalty Program Tier**.
7. Drag the **Loyalty Member Tier Change** attribute to the canvas.
8. Set Aggregation to **Count**, Operator to **At Least**, and Value to **1**.
9. Under Attribute, set the Operator to **Is Equal To** and Value to **T** for true.
10. Drag the **Loyalty Tier** attribute to the canvas.
11. Under Attribute, set the Operator to **Is Equal To** and Value to **Gold**.
12. Drag the **Loyalty Member Tier Benefit** attribute to the canvas.
13. Under Attribute, set the Operator to **Is Equal To** and Value to **Not-Redeemed** for true.
14. Click **Done** and then click **Save**.
# Create the Audience Segment in Data 360
Create and activate an audience segment for a loyalty status SMS campaign.
**Create the Audience Segment**
1. Log in to Data 360.
2. From the **Segments** tab, click **New**.
3. To base the new audience segment, select the Unified Individual DMO.
4. Name the segment SMS Loyalty Campaign, add a description, and select a publish schedule of 24 hours.
5. Add a start date and time and an expiration date, and click **Save**.
6. From the related attributes list, select **Loyalty Program Member** and select **Loyalty Program Tier**.
7. Drag the **Loyalty Member Tier Change** attribute to the canvas.
8. Set Aggregation to **Count**, Operator to **At Least**, and Value to **1**.
9. Under Attribute, set the Operator to **Is Equal To** and Value to **T** for true.
10. Click **Done** and then click **Save**.
# Create the Audience Segment in Data Cloud
The audience segment consists of the decision-makers who have a contract expiring within 4 months. Create a reminder email about the upcoming contract renewal.
1. In Data 360, on the **Segments** tab, click **New**.
1. For Data Space, select **default**.
2. For Segment On, select the **Account** data model object (DMO).
3. Name the segment Upcoming Contract Renewals, and add a description.
4. Click **Next**.
2. For Publish Type, select **Standard Publish** with a publish schedule of **24 hours**.
The type determines how much engagement data to use in the segment. The schedule determines how frequently to refresh the data.
3. For Publish Schedule, enter a start date and time, an expiration date, and click **Save**.
4. In the related attributes list, drag **Contract Expiration Date** to the segment canvas.
1. For measurement, select **Count** with the operator **At Least**, and enter the value 1.
2. For Contract Expiration Date, set the operator to **Next Number of Months** and enter a value of 4.
5. Click **Done**.
6. Click **Save**, and then click **Done**.
# Create the Audience Segment in Data Cloud
The audience segment consists of customers who have a high engagement rate with email campaigns. To create an automated email about new services, follow these steps in Data Cloud to create an audience segment.
1. In Data 360, on the **Segments** tab, click **New**.
1. For Data Space, select **default**.
2. For Segment On, select the **Unified Individual** data model object (DMO).
3. Name the segment New Service Promo, and add a description.
4. Click **Next**.
2. For Publish Type, select **Standard Publish** with a publish schedule of **24 hours**.
The type determines how much engagement data to use in the segment. The schedule determines how frequently to refresh the data.
3. For Publish Schedule, enter a start date and time, an expiration date, and click **Save**.
4. In the related attributes list, drag **Engagement Channel Action** to the segment canvas.
1. For measurement, select **Count** with the operator **At Least**, and enter the value 3.
2. Set the operator to **Is Equal To** and enter a value of Click.
5. In the related attributes list, drag **Engagement Date Time** to the segment canvas.
1. Set the operator to **Last Number of Months** and enter a value of 3.
6. Click **Done**, and then click **Save**.
# Create the Audience Segment in Data Cloud
To create an SMS message to notify California-based customers about their upcoming policy changes, follow these steps in Data Cloud to create an audience segment.
1. In Data 360, on the **Segments** tab, click **New**.
1. For Data Space, select **default**.
2. For Segment On, select the **Unified Individual** data model object (DMO).
3. Name the segment Terms of Service Changes - CA, and add a description.
4. Click **Next**.
2. For Publish Type, select **Standard Publish** with a publish schedule of **24 hours**.
The type determines how much engagement data to use in the segment. The schedule determines how frequently to refresh the data.
3. For Publish Schedule, enter a start date and time, an expiration date, and click **Save**.
4. In the direct attributes list, select **Unified Individual**.
5. Drag **State of Residence** to the segment canvas.
1. Set the operator to **Is Equal To**, and enter the value CA for California.
6. Click **Done**, and then click **Save**.
# Create the Policy Segment in Data 360
Create an audience segment for the auto policy welcome journey.
1. Log in to Data 360.
2. From the **Segments** tab, click **New**.
3. Select the Unified Individual DMO to base the new audience segment on.
4. Name the segment New Auto Policy Holders, add a description, and select a publish schedule of 24 hours.
5. Add a start date and time and an expiration date, and click **Save**.
6. To build the segment, click **Edit Rules**.
7. From the attributes list, select **RA\_PolicyInformation\_02** and select **Starting Date**.
8. Drag the **Starting Date** attribute to the canvas.
9. Set the Operator to **Last Number of Days** and add 30 in the Number of Days field.
10. Click **Done**.
11. From the attributes list, select **Has a Policy** and drag the attribute to the canvas.
12. Select Aggregation to **Count**, Operator to **At Least**, and Value to **1**.
13. Set the Operator to **Is Equal To** and Value to **TRUE**.
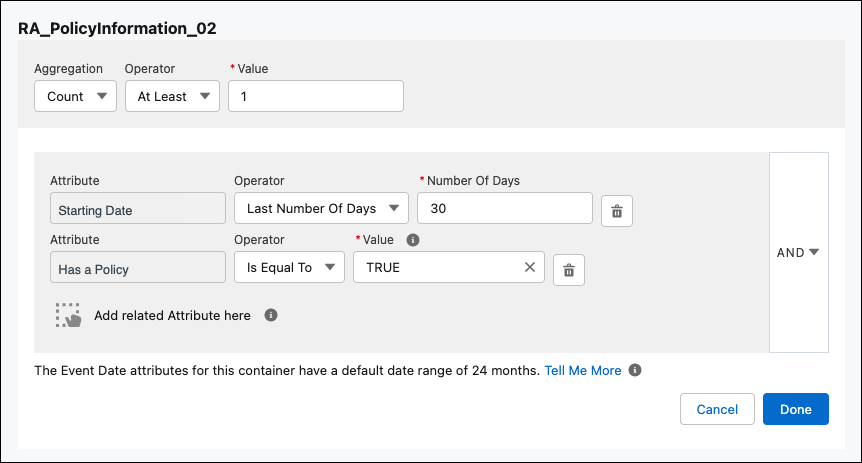
14. Click **Done** and then **Save**.
#### See Also
- [_Salesforce Help_: Segmentation Filters vs. Activation Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_vs_segmentation_filters.htm&release=264.0.0&type=5 "Segmentation and activation use different filters for different purposes. Apply filters to a segment to narrow your audience. Use activation filters to narrow down relevant values with related attributes that personalize messages.")
- [_Salesforce Help_: Create a Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&type=5&language=en_US)
- [_Salesforce Help_: Segment Your Data with Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_interface.htm&type=5&language=en_US)
# Create Your Core Activations in Data 360
Let’s review the steps for creating your core activations in Data 360.
### Required Editions
1. [Create a segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&release=264.0.0&type=5 "Create a standard segment based on a data model object and then publish the segment to activation targets.") at the Individual level that represents your full audience as active segment members. Then create a Unified Individual segment.
Implementation Pattern
Data 360 Segments
Core Audience Model
Full Individual audience
Full Unified Individual audience
Collective Core Audience model
Full Individual audience
Full Unified Individual audience
2. Depending on your data strategy, a marketer [creates one or more Data 360 activations](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation_target.htm&release=264.0.0&type=5 "To publish segments and batch data model objects (DMO) to Marketing Cloud Engagement business units, create an activation target in Data 360.") to Marketing Cloud Engagement based on each full audience segment.
Implementation Pattern
Data 360 SegmentsExample Data 360 Activations
Core Audience Model
Full Individual audience
Full Unified Individual audience
MC Core All Individuals
MC Core All Unified Individuals
Collective Core Audience model
Full Individual audience
Full Unified Individual audience
MC Individuals Identity & Consent
MC Individuals Subscriptions & Preferences
MC Individuals Demographics &
Psychographics
MC Individuals ecommerce Data
MC Unified Individuals Demographics &
Psychographics
MC Unified Individuals ecommerce
3. Select channels and contact points for your activations.
Implementation Pattern
Data 360 SegmentsExample Data 360 Activations
Channels Activated in Data 360
Core Audience Model
Full Individual audience
Full Unified Individual audience
MC Core All Individuals
MC Core All Unified Individuals
Collective Core Audience model
Full Individual audience
Full Unified Individual audience
MC Individuals Identity & Consent
MC Individuals Subscriptions & Preferences
MC Individuals Demographics & Psychographics
MC Individuals ecommerce Data
MC Unified Individuals Demographics & Psychographics
MC Unified Individuals ecommerce
Email & SMS
Email & SMS
Email & SMS
Email & SMS
Email & SMS
Email & SMS
4. For each activation, the marketer organizes and includes the commonly used attributes that the team has chosen.
Implementation Pattern
Data 360 SegmentsExample Data 360 Activations
Channels Activated in Data 360
Example Attributes Activated in Data 360
Core Audience Model
Full Individual audience
Full Unified Individual audience
MC Core All Individuals
MC Core All Unified Individuals
First name, email opt-in, lifetime value
Employment status, lifetime value, date last purchased
Collective Core Audience model
Full Individual audience
Full Unified Individual audience
MC Individuals Identity & Consent
MC Individuals Subscriptions & Preferences
MC Individuals Demographics & Psychographics
MC Individuals ecommerce Data
MC Unified Individuals Demographics & Psychographics
MC Unified Individuals ecommerce
Email & SMS
Email & SMS
Email & SMS
Email & SMS
Email & SMS
Email & SMS
First name, email opt-in, SMS opt-in
Account alerts, promotional messages
Country, gender, lifestyle
Lifetime value, rewards point
Employment status, lifestyle type
Lifetime value, date last purchased
# Create, Connect, and Activate Models
Create your own predictive models with clicks, not code. Establish connections to bring in generative and predictive AI from models outside of Salesforce. Then, activate models to use the inferences and insights revealed in your data.
- **[Access Model Runtime Settings](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_models_access_runtime_settings.htm&release=264.0.0&type=5)**
The new default runtime is the foundation for building all new predictive models in the AI Models tab in Data 360. This enhancement replaces the legacy runtime as the long-term platform for expanded predictive modeling capabilities.
- **[Create Predictive AI Models From Scratch](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_create_model.htm&release=264.0.0&type=5)**
Create models to analyze your data and get AI powered predictions based on machine learning. Learn about supported use cases and ethical model building. Then, follow the steps to create a model and evaluate model quality.
- **[Predictive Model Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_templates.htm&release=264.0.0&type=5)**
Build predictive models quickly by using preconfigured templates in Model Builder. Templates provide a starting point, including model details, variables, and recommended algorithms that you configure before model training.
- **[Clustering](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_clustering.htm&release=264.0.0&type=5)**
Use clustering in Data 360 to uncover hidden patterns and natural groupings in your data.
- **[Forecasting](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_forecast.htm&release=264.0.0&type=5)**
Use forecasting in Data 360 to predict future values from historical data. Forecasting models automatically identify trends and seasonal patterns to generate predictions without requiring data science expertise.
- **[Sentiment Analysis](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_sentiment.htm&release=264.0.0&type=5)**
Use sentiment analysis in Data 360 to evaluate unstructured text and learn how customers feel about your brand, product, or service. For each record, such as a customer review or survey response, the model assigns a positive, negative, or neutral label and a confidence score. To filter audiences, build dashboards, and trigger automations, apply the model outputs.
- **[Topic Classification](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_classify.htm&release=264.0.0&type=5)**
Use topic classification in Data 360 to organize unstructured text such as reviews, case comments, or survey responses, into meaningful categories. To evaluate records for classification, the model applies a trained language model to a selected field. For each record, the model assigns a topic label and a confidence score. Data 360 adds these outputs to your dataset. Apply topic classification in reporting and queries.
- **[Predictive Model Monitoring](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_monitor.htm&release=264.0.0&type=5)**
Maintain the accuracy, stability, and reliability of your deployed predictive models with model monitoring in AI Models (formerly Einstein Studio). This ongoing process provides in-depth insights into model's performance and identifies data quality or connectivity issues. Without consistent monitoring in Data 360, model performance can decline and lead to inaccurate predictions, unexpected outcomes, and reduced confidence in your results.
- **[Connect a Model](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_connect_model.htm&release=264.0.0&type=5)**
Connect predictive and generative AI models hosted outside Salesforce and use them with Salesforce data to predict future outcomes. Select your data source, define your predictive criteria, and train your model to reveal predictive inferences and insights using AI and machine learning.
- **[Activate Your Model](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_mm_activate_models.htm&release=264.0.0&type=5)**
After saving your predictive model settings, the model is ready for activation. To consume predictions, you must first activate the model.
- **[Predictive Models in Companion Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_data_cloud_one.htm&release=264.0.0&type=5)**
Access predictive models trained and activated in a home org from your Data Cloud One companion org. Data Cloud One supports multiorg access, which is ideal when a business is spread across different teams, countries, or brands. Model governance in the home-organization also simplifies model management and enables you to scale predictive AI across your entire ecosystem.
- **[Model Lineage in AI Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_lineage.htm&release=264.0.0&type=5)**
Model lineage provides a traceable history of an AI model's lifecycle, from training data, versioning, deployment, and its use with live data. Data 360 integrates this capability in AI Models (formerly Einstein Studio) and Governance.
- **[Manage Large Language Model (LLM) Access by Hiding Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_mm_show_hide_models.htm&release=264.0.0&type=5)**
Hide an LLM configuration when you want users in Prompt Builder to change to a different model in their prompt templates. They can select a newer LLM version or a different LLM, possibly from a different provider. You can suspend access to a new LLM until you've completed testing. Optionally, you can later show a hidden LLM configuration to make it visible for selection.
# CRM Connections in a Sandbox
Connect your Salesforce org to a sandbox to ensure the safety and integrity of your production environment. When you set up CRM connections from your Salesforce org to a sandbox org, the connections are copied from the production org to the sandbox org.
**Sandbox Connection Activation**
After you create connections to a sandbox, view all CRM connections copied from production on the CRM connection page. The connections are **Inactive**, requiring manual activation. One of these connections has the Production Org Id attached to it: this is your Home Org Connection. When you activate this connection, the Org ID shown changes from the Production Org ID to the current Sandbox Org Id.
To activate the connection, click the dropdown arrow next to the connection and click **Activate**. The connection status updates to **Active**, and the org ID reflects the sandbox org ID. Activating the copied Home Org connection in the sandbox creates a connection to the sandbox itself as the data source.
**External Data Source Selection**
When you connect your Salesforce org to an external data source org, you’re prompted to select the type of external data source to connect to. To connect to an external production org, click **Connect to a Salesforce Org**. To connect to an external sandbox org, click **Connect to a Sandbox Org**.
**Alias**
For connections that are copied over without an [alias](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_alias.htm&release=264.0.0&type=5 "As of July ‘24, an alias is required when setting up a Salesforce CRM connection. Existing connections aren't assigned an alias. The names of the data stream and data lake object are derived from the alias."), the org ID of the data source from the production org is used as the alias when you activate the connection. After you activate the connection, the alias is read-only and you can’t modify it.
**More Connections**
Create new connections to the production org from where the sandbox was cloned, or to a different production or sandbox org as an external data source org. You can also activate copied external CRM connections to the same or different production org or sandbox orgs as the data source.
For example, you can select to activate the connection to either the same (1) data source org as in the production org or a different (2) one.
# CRM Connector Language Behavior
Keep these considerations in mind when using the CRM connector.
The Platform Integration User's language is updated to the new language when the default organization language is changed.
The default language set at the organization level determines the results of a knowledge article query.
Source field names default to the language the object uses. When adding source fields during data stream creation, make sure that the default language matches the object's language. If the languages don't match, the fields won't be available for selection.
# CRM Connector Streaming
Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.
All data streams ingest the initial data in batch mode, and if they're eligible, they move to streaming mode, which continuously processes data with minimal latency.
When you add new source fields to a data stream, or set up a new data stream, exclude batch ingested fields from the stream for faster streaming ingestion. If you prefer periodic batch mode processing, leave them in. See [Create a CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.").
The streaming process checks if a full refresh is required. The first instance of a full refresh always uses batch processing. See [Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.").
**What's the Processing Mode of My Data Stream?**
To see the procesing mode of your data stream, access the data stream's record page. The **Frequency** field indicates the type of processing mode.
**Why Is My Data Stream Not Operating in Streaming Mode?**
For streaming to take place, make sure the required [permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.") are set and validation checks are met. Streaming isn't available under the following conditions, which change the processing mode to batch:
- The object, object type, or derived field don't support streaming. See [Object Support for CRM Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_unsupported_objects_types.htm&release=264.0.0&type=5 "When you create a Salesforce CRM data stream, the CRM connector doesn’t support the ingestion of all objects or object types from the connected CRM orgs. Use only supported objects and object types for your data stream.").
- You include batch ingested standard or custom formula fields in your data stream. [Learn how to create a Salesforce CRM data stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.").
- Your data stream has custom entities where the deployment status is **In Development** instead of **Deployed**. See also [Troubleshooting CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_refresh_history.htm&release=264.0.0&type=5 "If you have trouble with creating, refreshing, or disconnecting a Salesforce CRM data stream, see these common issues.").
- You want to stream a [Deleted Record DLO](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_store_deleted_data_stream_records.htm&release=264.0.0&type=5 "Store soft deleted data stream records that have been in the Salesforce Recycle Bin for up to 15 days. To store deleted data stream records, create a Deleted Record data lake object (DLO). You can use this DLO to view your stored records and use them in Data 360. For example, you can use the Deleted Record DLO to store deleted contacts outside of your Recycle Bin. You can only store deleted records of structured data streams.")
- You participate in the Filtering for Salesforce CRM Connector pilot and have defined a filter on a stream.
- You modified the Data Cloud Salesforce Connector permission set by adding users. When you connect to an org, the Data Cloud Salesforce Connector permission set is created and allows access to Data 360 objects and fields. This permission set is intended for the [Platform Integration User](https://help.salesforce.com/articleView?id=security_platform_integration_user.htm&language=en_US). Adding other users to this permission set prevents Data 360 from assigning the necessary permissions that are needed for streaming.
#### See Also
- [_Salesforce Help_: Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.")
# Cross Join
A cross join combines unrelated records and includes all rows from the left and the right input data source objects. Unlike other joins that use keys to find matches, the cross join pairs every row from one data source with every row of another data source.

Tip When designing a cross join, use the larger object first (left) and then join the smaller one (right). For example, join a:
- 10,000-row input source (left) with a 1,000-row input source (right)
- 20,000-row input source (left) with a 500-row input source (right)
- 40,000-row input source (left) with a 250-row input source (right)
- 100,000-row input source (left) with a 100-row input source (right)

Example
A company sells products at various locations. To assist with stock tracking, use a cross join to combine the product and store data to find all the possible pairs of product and store.
To illustrate how this join combines unrelated records, row number is included for reference but isn’t needed in the data.
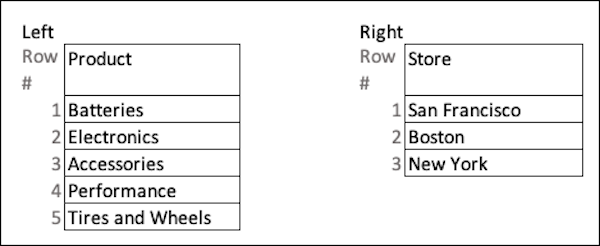
After performing the cross join, the batch data transfrm produces this output.
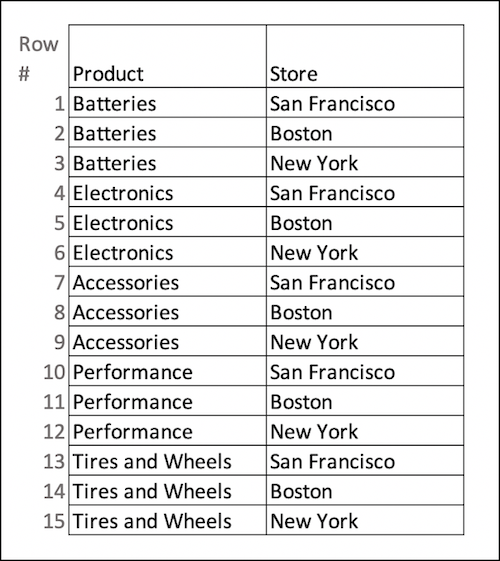
**Limitations for Cross Join**
Because a cross join creates a larger output than either of the input data sources, it has some limitations. Keep these points in mind when designing and testing your cross join.
- Only one cross join per data transform
- Cross join results maximum of 10 million
- Left object field (column) maximum of 8 and row maximum of 100,000
- Right object field (column) maximum of 8 and row maximum of 1,000
- Doesn’t support multivalue fields
# Cross-Validation Failure Alert
Cross-validation evaluates how well a model generalizes to unseen data by splitting the dataset into multiple parts, training the model on some parts, and validating it on others. Failure occurs when training data isn’t large enough, uses too few examples, or has an invalid format, missing values, or outliers.
## Actions to Consider
One of the folds in K-fold cross-validation performed very differently from the other folds. Investigate your training data for outliers or anomalous data and filter accordingly.
## Detection Methodology
Model Builder displays an alerts when it detects a significant performance difference in one of the folds.
## Example
A retail brand wants to predict the weekly demand for products in various stores so it can optimize inventory and improve restocking. To achieve this, the retailer builds and trains a regression model using these input variables.
- store ID
- product ID
- price
- promotion
- stock count
- season
- weekly sales
After model training, an alert displays because cross-validation failed. A lack of product, store, or historical sales data in the dataset or data splits for cross-validation can cause failure. To resolve the issue, here are some actions to consider.
- Retrain the model using attribute-rich input variables, such as “product type” or “store type.” Avoid using “product ID” or “store ID.”
- Remove variables such as “end-of-week stock count” that can leak future information, making the model less reliable.
- Use more data if the dataset is too small (too few rows, columns, or both) for cross-validation.
# Cumulus Activates Segments and Adds Attributes
Because the team has chosen to create a Collective Core Audience Model, the marketer repeats these steps for each activation in their data foundation.
1. After you publish segments, on the Activations tab, click **New**.
2. From the Activation list, select **Full Core Individual Audience**.
3. Select **Marketing Cloud Engagement-Cumulus BU** as the activation target or the destination of the segment data.
4. For the activation membership, select **Individual**, confirm, and click **Next**.
5. For the channels (contact points), select **Email** and **SMS**.
6. Confirm the path and source order for the email address and phone number, and then click **Next**.
7. Find and select this attribute: **Policy Address**
8. Click **Save**, then click **Next**.
9. Name the activation Individual Policy Information.
10. For a description, add Used for Marketing Cloud Engagement data foundation. Contains commonly used attributes for campaigns that reference an insurance policy.
11. Click Save.
12. Create an activation for the Unified Individual Policy Information and include only the recommended Policy Type attribute.
13. Repeat the steps for your Credit Information grouping of attributes.
# Cumulus Creates Core Activations in Data 360
In this use case, to build their data foundation the Cumulus team creates Data 360 activations for their audiences to Marketing Cloud Engagement. These activations comprise their data foundation.
### Required Editions
Review [Create a segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
1. In Data 360, on the Segments tab, click **New**.
2. Name the segment Full Core Individual Audience and add a description.
3. Select a publishing schedule of **12 hours**.
4. Click **Edit Rules**.
5. From the attributes list, find the **DMO for Individual** and Data Source attributes and drag **Data Source** to the interface.
6. Set the operator to **Is Equal To**.
7. To qualify contacts in your Marketing Cloud Engagement account, enter your company’s enterprise ID. For example, SFMC1079707.

Note Your company’s enterprise ID is unique. You can also add other criteria to qualify your full audience.
8. Click **Done** and then click **Save**.
9. If applicable, repeat these steps to create Unified Individual segments.
# Cumulus Establishes Data Foundation Requirements
Cumulus Bank and Financial Services want to integrate Data 360 with Marketing Cloud Engagement. They’re using Data 360 to establish a data foundation in Marketing Cloud Engagement. They then want to use the data foundation as part of their campaigns, including their initial customer campaign: a 30-day journey to welcome new auto policy holders and to introduce them to their policy and benefits.
## Identify Common Content Personalization Attributes for Event-Triggered Journeys
They decide to create event-triggered campaigns for:
- Policy Onboarding—A 30-day journey to welcome new auto policyholders and to introduce them to their benefits.
- Credit Signup—A 14-day journey to deliver progress updates and solicit feedback after a consumer signs up for a new line of credit.
Journey Decisioning for Audience-Based Campaigns
| Campaign | Attribute | Data 360 Data Type | Journey Data Type |
| --- | --- | --- | --- |
| Upcoming Payment Reminder | Customer Credit Balance | Individual | Contact Data |
| Policy Upsell | Policy Type | Unified Individual | Contact Data |
Journey Decisioning for Event-Triggered Campaigns
| Campaign | Attribute | Data 360 Data Type | Journey Data Type |
| --- | --- | --- | --- |
| Policy Onboarding | eBilling Enrollment Status | Individual | Contact Data |
| Credit Signup | Credit Application Status | Individual | Contact Data |
| Credit Signup | Applicant Feedback Status | Individual | Contact Data |
## Determine Which Contact Model Works Best
Cumulus Bank and Financial Services are an international company with a full audience of nearly 10 million contacts shared across 10 countries and five operating units. Although the company is new to Marketing Cloud Engagement, they have a large team that plans to build moderately sophisticated journeys over the next year. They estimate that they’ll need approximately 150 attributes in the data foundation within Engagement to satisfy all potential campaigns over the next year.
Together, the team at Cumulus Bank and Financial Services decides to implement the Collective Core Audience Model pattern in Engagement. Because they’re choosing to implement the Collective Core Audience Model, the team categorizes their chosen required attributes (Contact Data) in preparation for their multiple Data 360 activations.
Group 1: Policy Information
| Attribute Name | Campaigns Used | Data 360 Data Type | Journey Data Type |
| --- | --- | --- | --- |
| Policy Address | Policy Onboarding | Individual | Contact Data |
| Policy Type | Policy Upsell | Unified Individual | Contact Data |
Group 2: Credit Information
| Attribute Name | Campaigns Used | Data 360 Data Type | Journey Data Type |
| --- | --- | --- | --- |
| Credit Application Status | Credit Signup | Individual | Contact Data |
| Available Credit | Credit Signup | Individual | Contact Data |
| Customer Credit Balance | Upcoming Payment Reminder | Individual | Contact Data |
| eBilling Enrollment Status | Policy Onboarding | Individual | Contact Data |
| Applicant Feedback Status | Credit Signup | Individual | Contact Data |
# Cumulus Links Core Activations to the Marketing Cloud Engagement Contact Model
Cumulus follows these steps to link core activations to the Marketing Cloud Engagement Contact Model.
Activate the Data 360 audiences to Engagement. It can take up to an hour before creating the data extension in Engagement and longer to populate it with all audience data.
In the Engagement Contact Builder app, the data specialist [creates attribute groups](https://help.salesforce.com/s/articleView?id=mktg.mc_cab_create_an_attribute_group.htm&type=5&language=en_US) to represent each Data 360 activation grouping identified in their research with the Marketers.
1. In Marketing Cloud Engagement, hover over the Audience Builder icon, and click **Contact Builder**.
2. Click **Create Attribute Group**.
3. For Name, enter Policy Information.
4. Click **Save**.
5. Click **Link Data Extensions**.
6. **Select Shared Items > Shared Data Extensions >**Data 360 and select the Individual Policy Information data extension that you created.

Note Segments are created as a shared data extension with this naming format: {first 52 characters of segment name}\_{16 characters of activation\_name}\_{32 characters of Alphanumeric Random number.
7. Associate the Individual Policy Information data extension.
1. Make sure that data deletion is turned off for commonly shared data extension.
2. Relate the data extension with a 1:1 relationship for ContactKey↔Individual ID.

Note For both performance and functional reasons, we don’t recommend activating [Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_related_attributes.htm&release=264.0.0&type=5 "Personalize Marketing Cloud Engagement communications using direct and related attributes from Data 360. Control the volume and variety of data that can be used in marketing segments.") as attributes in a commonly shared data foundation for journey decisions, waits, or exits. Instead, we recommend converting the related attribute into a Calculated Insight.
8. Read the informational notice and click **Done**.
1. Wait for the system to process, and review the result.
9. To connect the Unified Individual Policy Information data extension to the Individual Policy Information data extension, click the chain icon.
10. Relate the data extensions with a 1:1 relationship for Individual ID↔Individual ID.
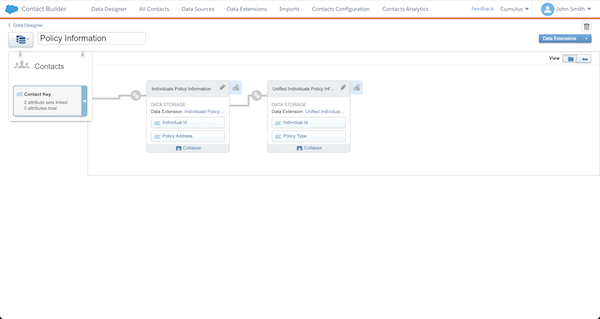
11. Click **Done**.
12. Create an attribute group and repeat these steps for the Individual Credit Information activation in the Credit Information Attribute Group.
# Cumulus Uses Data 360 Data Throughout Marketing Cloud Engagement to Create Event-Triggered Journeys
Now that the team at Cumulus Bank and Financial Services has set up their Marketing Cloud Engagement data foundation, their data from Data 360 can be used throughout Engagement in a scalable, reusable way.
1. In Marketing Cloud Engagement, navigate to **Journey Builder**.
2. Click **Create New Journey**.
3. Select **Multi-Step Journey** and click **Create**.
4. For the Entry Source, drag the **Data Extension** activity to the canvas.
5. Select the **New Auto Policyholders** data extension, and click **Done**.
6. Set the journey schedule to **Recurring** and **Evaluate New Records Only**.
7. To make an outline of the 30-day onboarding journey, drag the required activities to the canvas.
8. Configure the activities in the journey.
9. To personalize the email contents, use the journey personalization tool to select the attributes that come with the New Auto Policyholders data extension.
10. For Decision Splits and Exit Criteria, use the attributes from the Individual and Unified Individual portions of the data foundation to build your expression.
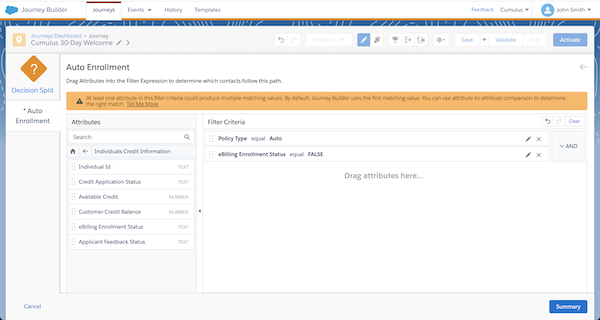
11. In Journey Settings, for Contact Entry mode, select **No re-entry**.
12. Click **Summary** and then click **Done**.
13. Review your journey and click **Save**.
14. To ensure that all the information has been completed, click **Validate**.
15. Click **Activate**.
# Currency Data Type in Segmentation
You can use the currency data type to convert currency when performing aggregations and creating the required groups in segmentation filters.
Make sure that the default currency conversion data model object (DMO) includes all required conversion rates. This ensures accurate results. If the conversion rates are missing from the currency conversion DMO, you could get incorrect results.

Note
The currency data type is not currently supported in segments created using API.
## Currency Attribute in Filters
You can segment your data by using the currency data type attribute. When creating a filter, you select a currency code from the currency dropdown menu. This currency code is used to normalize the data.
## Example
If your filter condition is Order Total = $500 and the Income attribute contains values in multiple currencies, all values are converted to USD (the currency selected in the filter), using the currency conversion DMO. After the conversion, the filter condition is applied to the segment.

Note
There can be some mismatch between the segment count and segment publish results when a filter currency field is used.
## Currency Attribute in Aggregations
When performing aggregation operations such as sum or average with a currency attribute, you select a currency code from the currency dropdown menu. This currency code is used to normalize the data before carrying out the aggregations.
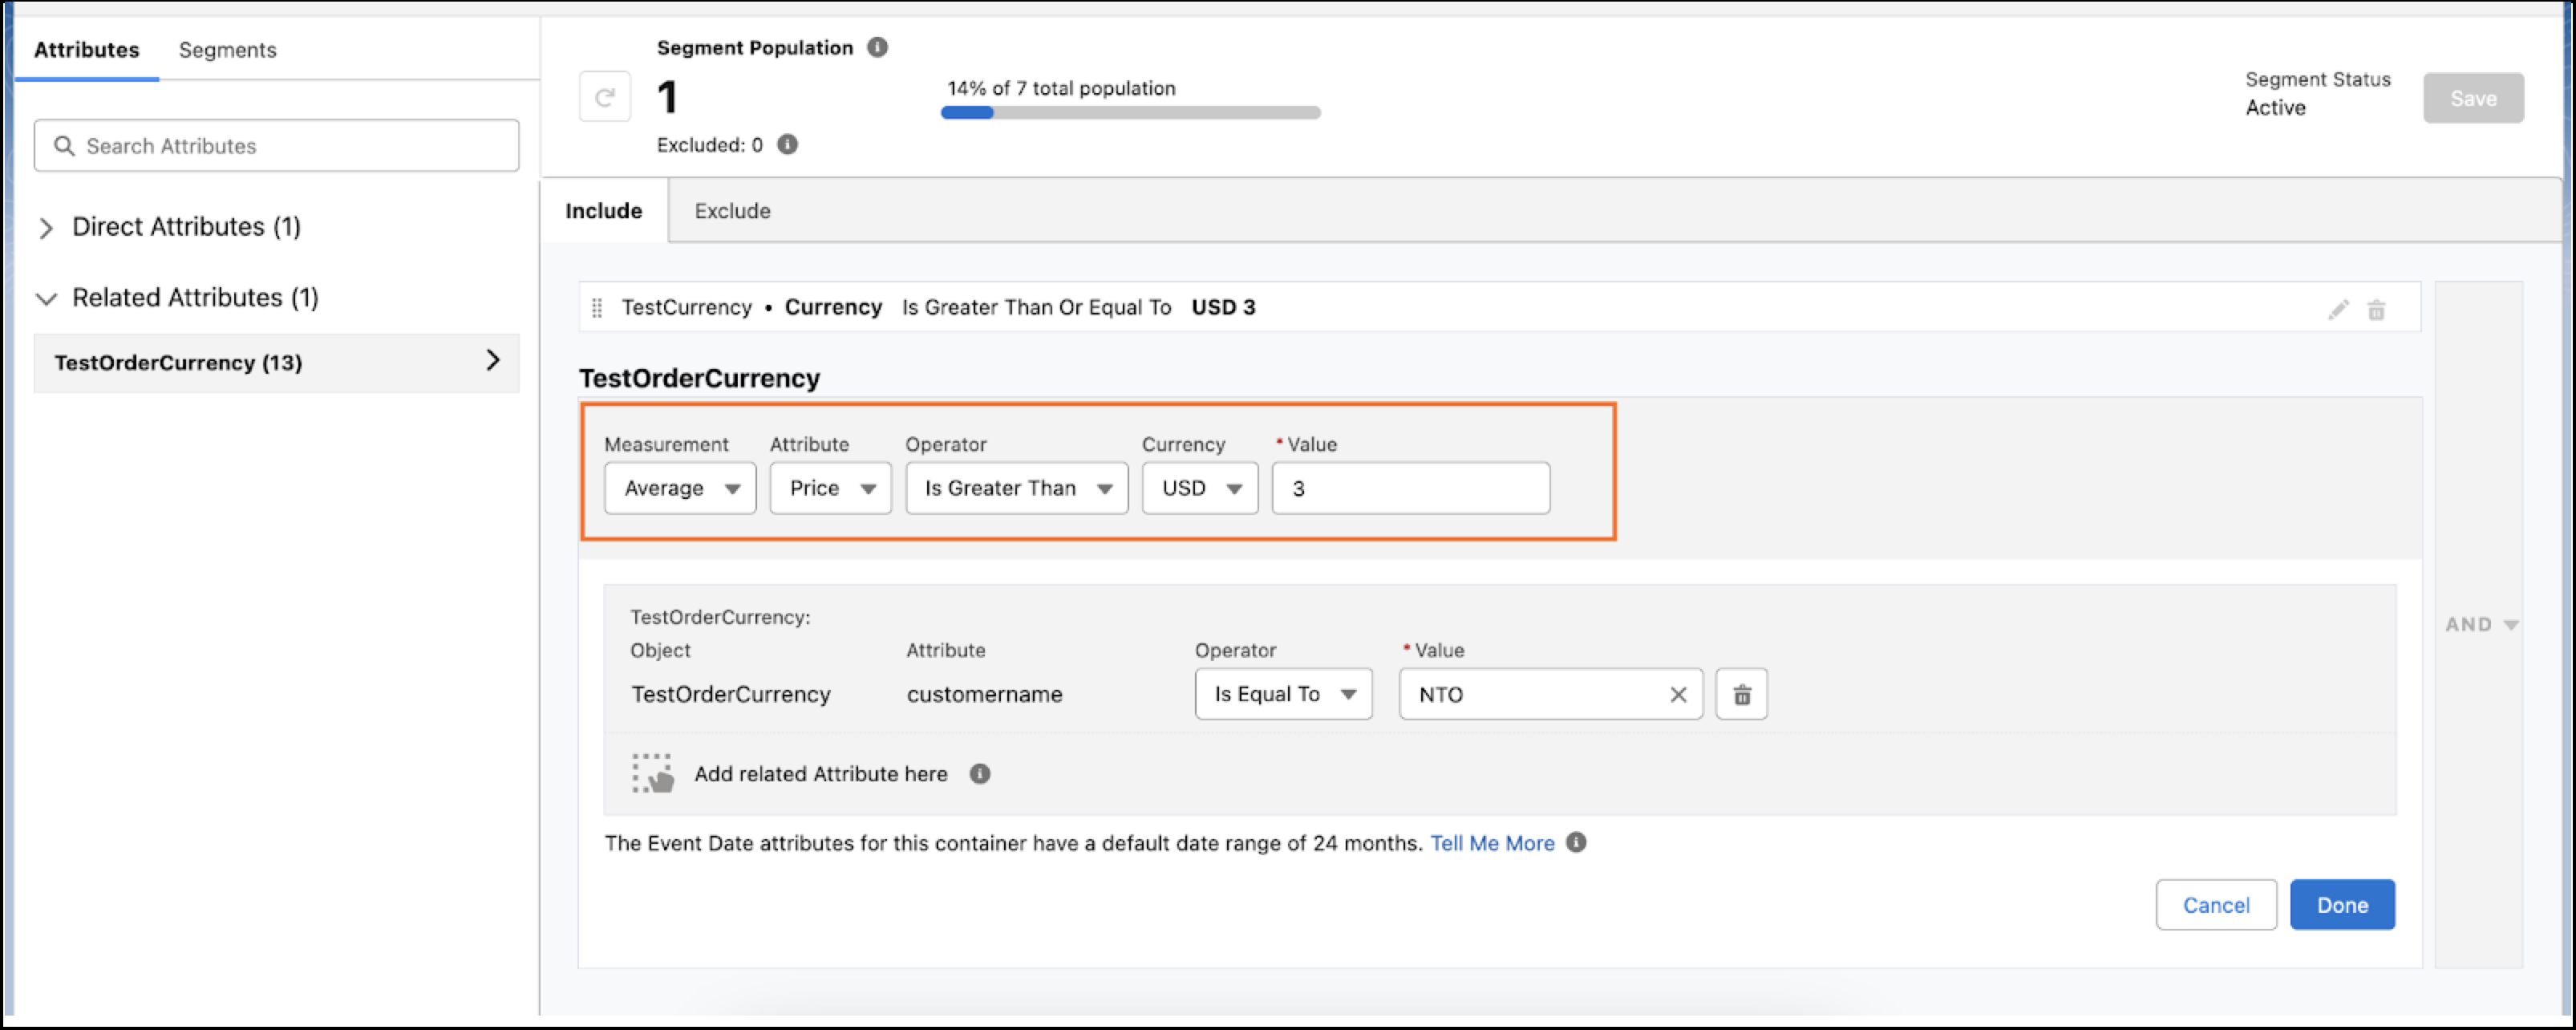

Note
- No implicit currency conversion occurs as part of any other operation.
- Rounding errors during currency conversions can sometimes lead to inaccurate results in segmentation.
# Custom Collaboration Template Sample JSON
Copy the template code below or download it directly in Data 360 to begin creating your custom template. Fill in the required and optional fields with appropriate values.
```
"name": "CustomTemplateExample",
"description": "Example of Clean Room Customized Templates",
"tables": {
"tableConfigs": [
{
"name": "Provider",
"description": "Provider table for overlap use case.",
"role": "Provider",
"columns": [
{
"name": "SegmentName",
"description": "Name of the segment.",
"type": "STRING"
},
{
"name": "Category",
"description": "Category of the segment.",
"type": "STRING"
},
{
"name": "ParentCategory",
"description": "Parent Category of the segment.",
"type": "STRING"
},
{
"name": "SegmentSize",
"description": "Size of the segment.",
"type": "INTEGER"
},
{
"name": "MemberId",
"description": "Member ID, only aggregation or join is allowed.",
"type": "STRING"
},
{
"name": "HashedEmailAddress",
"description": "Contact ID hashed with SHA256.",
"type": "HASHED_EMAIL"
}
]
},
{
"name": "Consumer",
"description": "Consumer table.",
"role": "Consumer",
"columns": [
{
"name": "SegmentId",
"description": "ID of the Segment.",
"type": "STRING"
},
{
"name": "SegmentName",
"description": "Name of the segment.",
"type": "STRING"
},
{
"name": "SegmentSize",
"description": "Size of the segment.",
"type": "NUMBER"
},
{
"name": "HashedEmailAddress",
"description": "Contact ID hashed with SHA256.",
"type": "HASHED_EMAIL"
}
]
}
]
},
"queries": {
"queryConfigs": [
{
"name": "OverlapQuery",
"useCase": "Overlap",
"description": "Query to calculate the overlap between consumers and providers.",
"type": "SQL",
"source": "SELECT Consumer.SegmentId AS Segment_Id__c, Consumer.SegmentName AS Segment_Name__c, Provider.SegmentName AS Provider_Segment_Name__c, Provider.Category AS Provider_Segment_Category__c, Provider.ParentCategory AS Provider_Segment_Parent_Category__c, Provider.SegmentSize AS Provider_Segment_Size__c, Consumer.SegmentSize AS Segment_Size__c, COUNT(DISTINCT Provider.MemberId) AS Matching_Population_Count__c FROM Consumer JOIN Provider ON Consumer.HashedEmailAddress = Provider.HashedEmailAddress GROUP BY Consumer.SegmentId, Consumer.SegmentName, Provider.SegmentName, Provider.Category, Provider.ParentCategory, Provider.SegmentSize, Consumer.SegmentSize HAVING COUNT(DISTINCT Provider.MemberId) >= :threshold_count",
"queryParameters": {
"queryParamConfigs": [
{
"name": "threshold_count",
"type": "INTEGER",
"description": "The threshold count."
}
]
},
"referencedTables": [
"Consumer",
"Provider"
]
}
]
}
}
```
# Custom Collaboration Templates
Custom collaboration templates are JSON files that providers can create to specify the required metadata attributes and the terms of the collaboration. Custom templates can support multiple use cases and multiple queries under each use case. To create a custom template, copy the sample JSON, specify the field values, and upload the template while creating a package. You can also download the sample JSON from Data 360 Setup when you’re creating the clean room package.
## Template Overview
A custom collaboration template includes these fields.
| Field Name | data type | Requirement | Accepted values | Description |
| --- | --- | --- | --- | --- |
| `name` | string | Required | N/A | The name of the collaboration template. |
| `description` | string | Optional | N/A | A short description of the collaboration template. |
| `tables` | object | Required | N/A | The input tables used in a collaboration query. |
| `queries` | object | Required | N/A | The queries to be run in the clean room collaboration to support a use case. |
## Table Configurations
Each input table used by the query must be defined as a `tables` field. Each table definition must include the `tableConfigs` property.
- `tableConfigs` (array, required) – A list of table definitions. Each entry represents one table configuration and must include these fields.
| Field Name | data type | Requirement | Accepted values | Description |
| --- | --- | --- | --- | --- |
| `name` | string | Required | N/A | The name of the table. |
| `description` | string | Optional | N/A | A short description of the table definitions. |
| `role` | string | Required | Provider or Consumer | The role that is sharing the table in the collaboration. |
| `columns` | array | Required | N/A | The schema of the table. Each column object defines a field in the table and must include a `name`, a `type`, an optional `description` and a `defaultvalue`, if any. |
## Query Configurations
The queries section defines all the queries that you want to allow on the combined dataset in a clean room. Each query must include the queryConfigs property.
- `queryConfigs` (array, required) – A list of query configurations. Each entry defines a single query and must include these fields.
Field Name
data type
Requirement
Accepted values
Description
namestring
Required
N/A
The name of the query.
descriptionstring
Optional
N/A
A short description of the query configurations.
useCasestring
Required
Overlap or Custom The use case that this query supports.
typestring
Required
SQL The type of query.
sourcestring
Required
N/A
The actual SQL query text.
Use explicit aliases for SELECT
columns.
referencedTablesarray of strings
Required
N/A
A list of all tables that the query references. This field must contain at
least one table name.
queryParametersobject
Optional
N/A
The dynamic parameters used in the query. Each queryParameter
must contain a queryParamConfigs with a name, a
type and an optional description field.
analysisConfigsobject
Optional
N/A
The output options, such as outputPath.

Note Values for enum fields such as role, useCase, and type are case-sensitive.
- **[Custom Collaboration Template Sample JSON](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_custom_collab_template_json.htm&release=264.0.0&type=5)**
Copy the template code below or download it directly in Data 360 to begin creating your custom template. Fill in the required and optional fields with appropriate values.
- **[Identity Boost Custom Collaboration Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_id_boost_custom_template.htm&release=264.0.0&type=5)**
The identity boost custom collaboration template is a JSON configuration that supports identity enrichment use cases in Data 360 Clean Rooms. Use this template to enrich your first-party individual data with third-party identity attributes, such as real IDs from identity resolution providers, in a privacy-safe environment.
- **[Supported Data Types for Custom Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_custom_templates_datatypes.htm&release=264.0.0&type=5)**
The data types supported in custom templates vary based on the clean rooms platform. Adhere to supported data types for successful query execution.
# Custom Permission Sets in Data Cloud
To create a Data Cloud custom permission set, we recommend cloning an existing standard Data Cloud permission set. Some Data Cloud features can’t be accessed with permission sets created from scratch.
### Required Editions
User Permissions Needed
To clone permission sets:
Manage Profiles and Permission Sets
Custom permission sets aren’t automatically updated when Data Cloud features get new permissions, even if they’re created by cloning a standard Data Cloud permission set.
When you clone a permission set, its data space associations are included in the new permission set. When you create a permission set from scratch, you must manually associate it with a data space.
- **[Add Object Permissions to Custom Permission Sets for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_add_object_permissions.htm&release=264.0.0&type=5)**
Object permissions for new Data Cloud objects are added to all standard Data Cloud permission sets when the new objects is added. However, object permissions for new objects but must be manually added to custom permission sets. Use these object permissions to update any custom Data Cloud permission sets that were created before the new object was added to Data Cloud.
# Customer 360 Data Model
The Customer 360 Data Model reduces the complexities of integrating data across cloud applications by providing standardized data guidelines. Extend the data model to create data lakes, generate analytics, train machine-learning models, build a single view of the customer, and more.
The Customer 360 Data Model is organized into subject areas. Each area represents a major business activity, such as customer information, product, or engagement data. A subject area consists of data model objects (DMO).
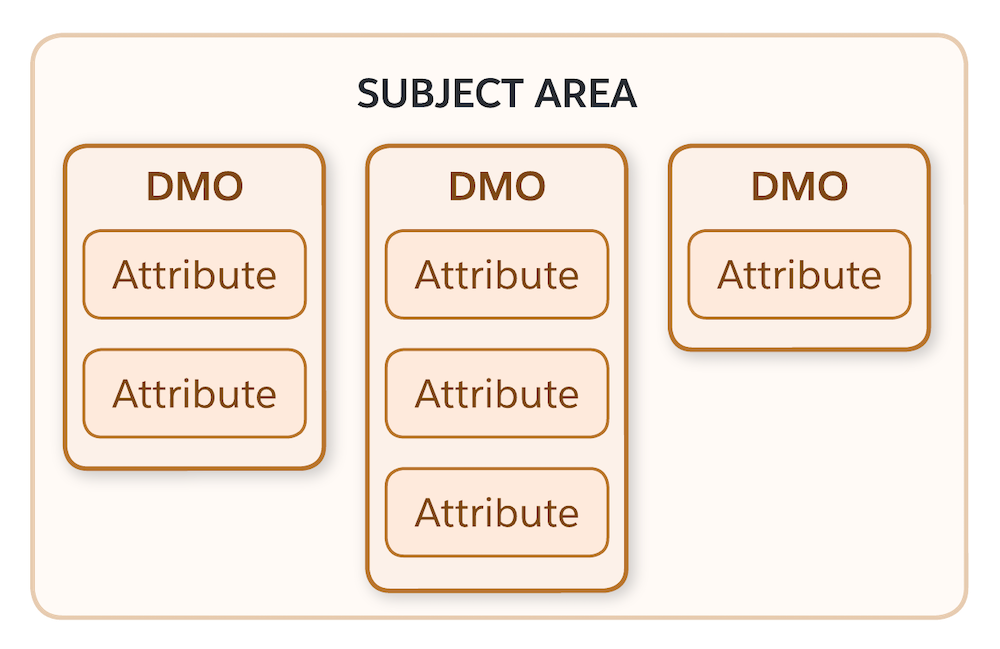
A DMO is a view of your data imported into Data 360 from data streams, insights, and other sources. A DMO uses attributes, or fields, to organize the data in specific and meaningful ways. The term “DMO” can refer to the Salesforce created and managed schema for a DMO or an instance of a DMO in an org based on the schema.
Multiple types of DMOs can be created and used in an org. A standard DMO is created based on the pattern of a schema DMO and inherits the name, shape, and semantics of the referent. You can also create and define custom DMOs directly in an org. Additional subtypes of custom DMOs are created and used for specific features in Data 360.
Data imported into Data 360 must be mapped to a DMO before it can be used for segmentation, activation, analytics, or any other operation. To get started with data mapping, add a connected data source to Data 360. After you connect a source, Data 360 accesses the source so that you can create mapping sets between objects and fields within it and the Customer 360 Data Model.
For more information about DMOs and other object types used in Data 360, see [Data Objects in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lake_objects.htm&release=264.0.0&type=5 "When working with Data 360, it’s helpful to know about Data 360 data objects including data lake objects (DLO) and data model objects (DMO).").
The Customer 360 Data Model connects disparate data together by linking DMOs together through relationships. Here’s the full data relationship diagram for the Customer 360 Data Model.
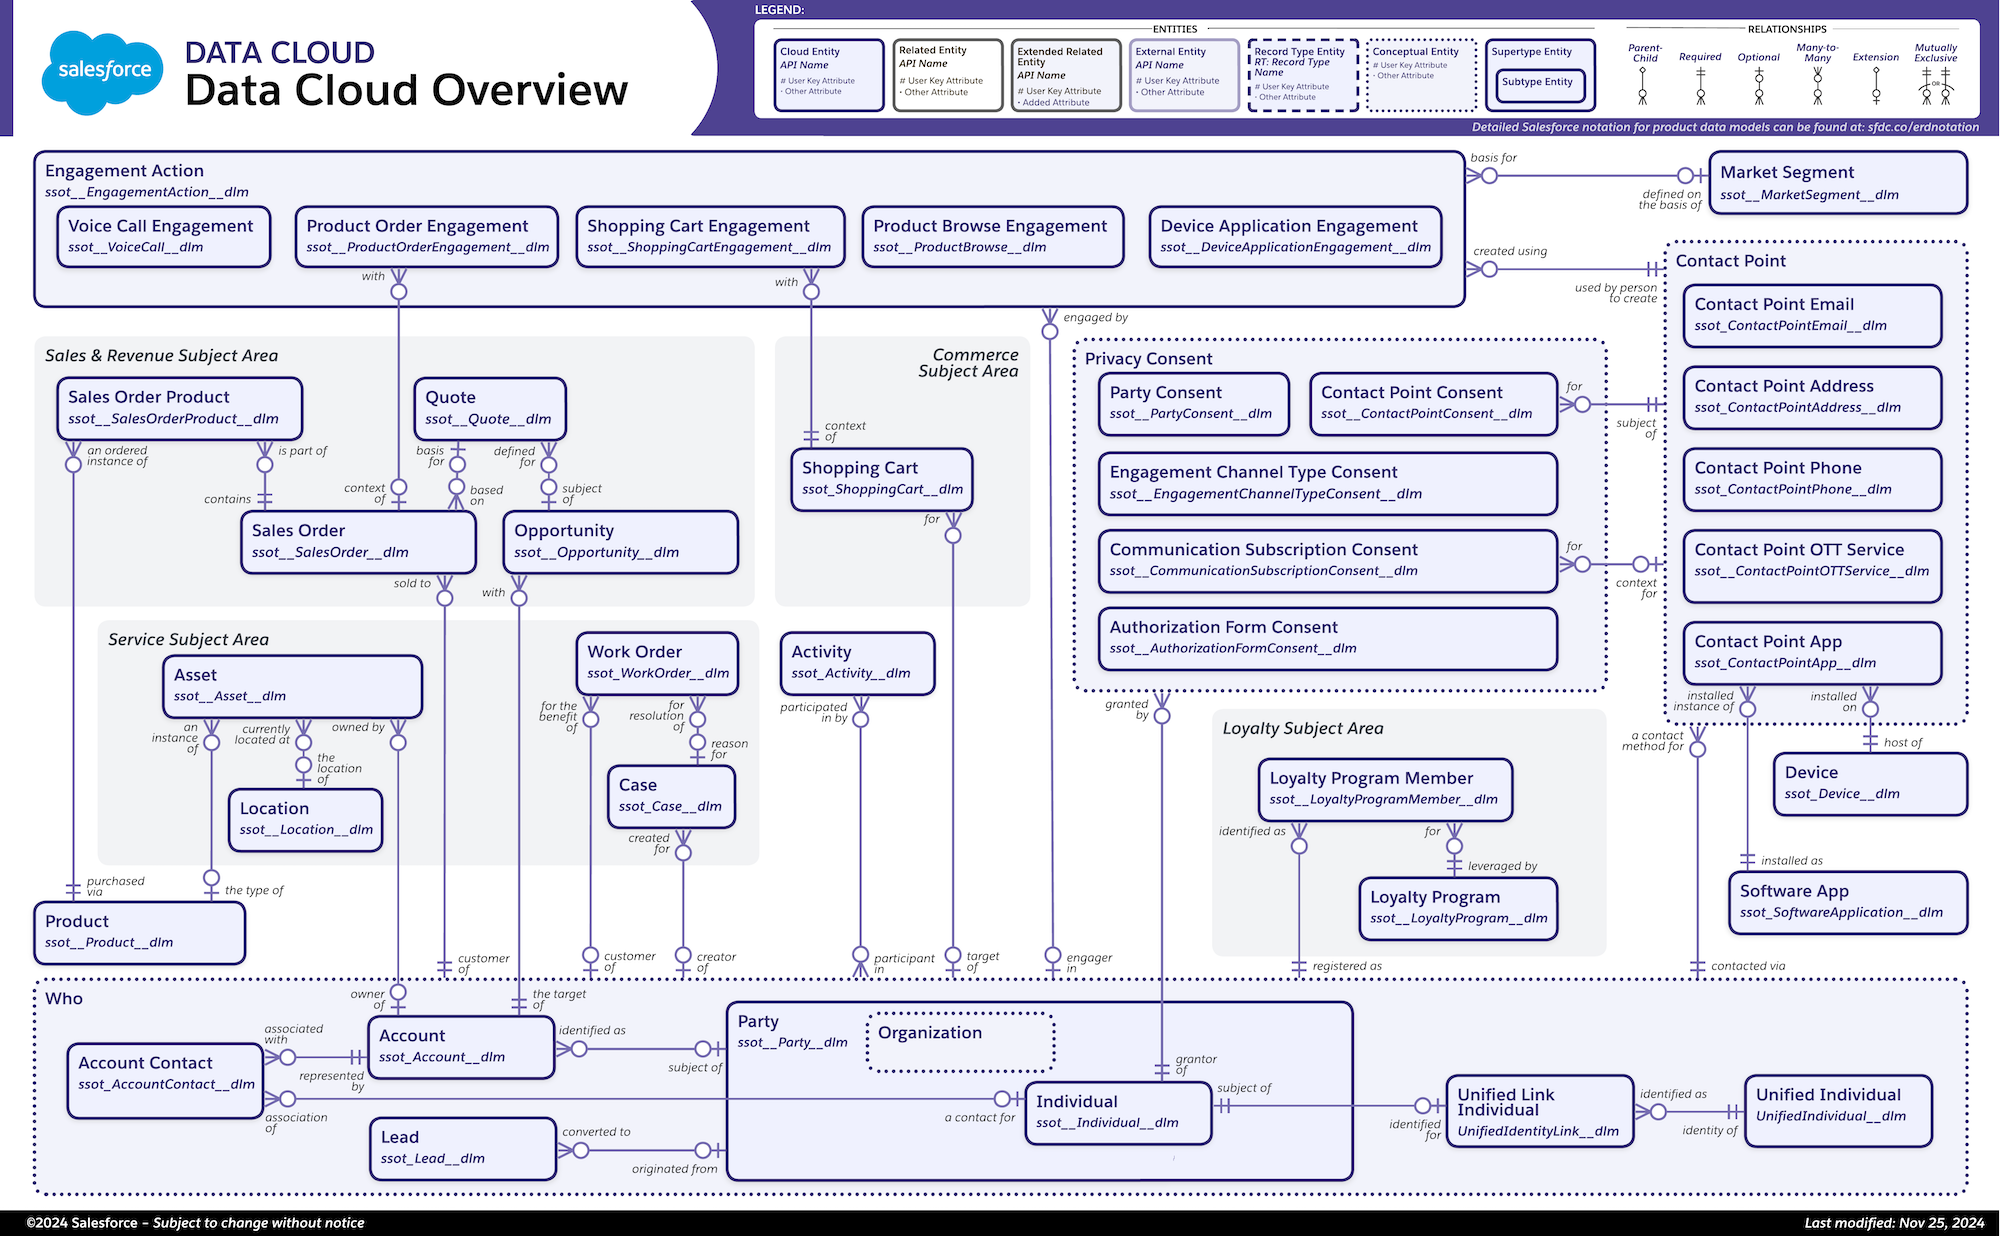
For more details and a larger image, visit the [Data Model Gallery](https://developer.salesforce.com/docs/platform/data-models/guide/data-cloud-overview.html).
To learn more about this topic, review the [Customer 360 Data Model for Data 360](https://trailhead.salesforce.com/content/learn/modules/customer-360-data-model-for-customer-data-platform) Trailhead module.
- **[Case Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_case_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model case subject area groups and defines recorded issues, such as laptop connectivity problems or support tickets.
- **[Engagement Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_engagement_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model engagement subject defines interactions with a party. Example interactions could be speaking to a customer over the phone or receiving a customer email.
- **[Loyalty Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_loyalty_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model loyalty subject area tracks and manages reward and recognition programs.
- **[Party Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_party_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model party subject groups data model objects (DMO) that reflects contact information (personal or business) for a specific customer or account.
- **[Privacy Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_privacy_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model privacy subject tracks and stores certain data privacy preferences. Keep in mind that deciding how to honor customer privacy preferences is up to you.
- **[Product Subject Area](https://help.salesforce.com/s/articleView?id=data.c360_a_product_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model product subject area defines anything you plan to sell or any part of a product to track for service purposes.
- **[Sales Order Data Object](https://help.salesforce.com/s/articleView?id=data.c360_a_sales_order_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model sales order subject defines the future revenue or quantity for an opportunity by product family and rolls it up by territory, management (role), or hierarchy.
- **[Additional Standard Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_software_application_data_model.htm&release=264.0.0&type=5)**
The Customer 360 Data Model includes other standard data model objects that can help organize data in Data 360.
- **[Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5)**
When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.
# Customer 360 Data Model: Individual and Contact Points
When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.
| Object Type | What It Is | Example |
| --- | --- | --- |
| Individual | Represent the person you are, or will be, dealing with using the system | FirstName, LastName, BirthDate, BirthPlace |
| Contact Point Email | Email address for an individual | info@northerntrailoutfitters.com |
| Contact Point Phone | Phone number for an individual | +1555123456 |
| Contact Point Address | Mailing address for an individual | 123 Main St., Big City, CA12345, USA |
| Contact Point App | Software Application for an individual and optionally on a specific device | John Doe has Strava App on device iPhone123 |
| Contact Point OTT Service | The “over-the-top” technology that delivers a messaging/streaming service account of an individual through internet-connected devices | WhatsApp, Line, Netflix |
| Contact Point Social | Social handle for an individual | Twitter: @trustednews |
| Contact Point Digital Id | A digital identifier of an individual such as Google Ad ID (GAID), Mobile Ad ID (MAID), Apple Identifier for Advertisers (IDFA), etc. | |
| Party Identification | Set of ways to identify an individual | Drivers license number, customer ID |
| TelephoneNumber | The display name, as defined by the customer. Include this object in places where customers view the number like Profile API and Profile Views. | |
| FormattedE164PhoneNumber | The E164 formatted phone number. Use in backend systems as the standardized value for processing. | |
| Country | The country code | US, CA, IT, NZ, AU |
| PhoneCountryCode | The country dialing code | +1, +91 |
## Individual ID
Imported data customer identifiers must be mapped to the Individual ID field to drive identity resolution behavior and to receive accurate data when creating data segments.
The Individual ID object is important to ensuring successful data in Data 360. When importing any customer information, it’s mapped to this object and remains consistent throughout the entire product.
# Customer Data Platform Billable Usage Calculations
Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.

Important These billing usage calculations apply only to Data 360 orgs with Customer Data Platform licenses. If your Data 360 org has a Data Cloud license, see [Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.") instead.
You’re billed for usage in the areas of Unified Profiles, Segment Publishes, and Engagement Events. Your maximum usage in these areas is defined in your contract’s entitlement schedule. Overages are billed monthly at contracted rates. Contact your account team if you have questions about your contract.
## Calculating Billable Unified Profiles for Customer Data Platform Orgs
The billable number of profiles is based on whether you have active Identity Resolution rulesets. You’re billed for additional Unified Profiles if the number of billable profiles exceeds your entitlement.
If you’re not using identity resolution, the billable profile count is the sum of all records in all data lake objects (DLOs), regardless of category, mapped to data model objects (DMOs) categorized as Profile type. Both known and unknown profile records are counted. DLOs that are mapped only to the following DMOs are excluded from this count.
- Account Contact
- Contact Point Address
- Contact Point App
- Contact Point Consent
- Contact Point Email
- Contact Point OTT Service
- Contact Point Phone
- Contact Point Social
- Device
- Party Identification
If you’re using Identity Resolution to link source profiles to Unified Profiles, the billable Unified Profile count is the sum of both of these factors.
- The number of known Unified Profile records for all active identity rulesets. To determine how many Unified Profile records you have, view the [Identity Resolution Summary](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_summary.htm&release=264.0.0&type=5 "Summary statistics are available after a ruleset job runs for the first time. Results of the most recent run are shown in the Resolution Summary. Results from previous days are listed in the processing history table. If the ruleset was processed more than one time per day, the results in the processing history table reflect the last run completed during the day.") for each active ruleset. Locate the number of Unified Profiles for the ruleset in the summary. Add the number of known Unified Profiles across all rulesets.
- The number of all records in all DLOs, regardless of category, mapped to DMOs categorized as Profile, excluding DMOs that are part of Identity Resolution. These records are included in the count because you can use them to create segments. DLOs that are mapped to Other type DMOs are counted as Engagement Events and not as Unified Profiles.
Anonymous profile limits are based on your Salesforce edition. When you’re using Identity Resolution, anonymous profiles are excluded from the billable Unified Profile count.
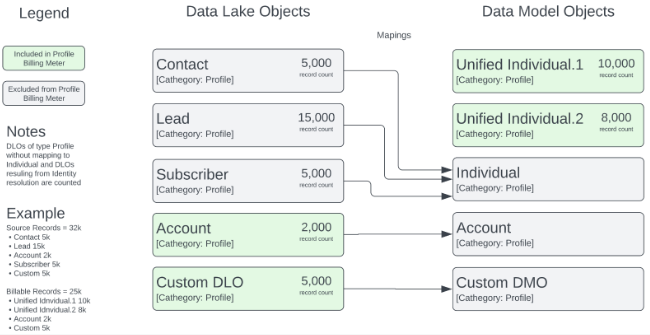

Example
This example has two active identity resolution rulesets: Unified Individual.1 with 10,000 records and Unified Individual.2 with 8,000 records. There are two DLOs that are categorized as Profile but aren’t mapped to Individual: The Account DLO has 2,000 records, and the custom DLO has 5,000 records. For this customer, the total billable Unified Profiles is 10,000 + 8,000 + 2,000 + 5,000 = 25,000.
## Factors That Affect Unified Profile Counts for Customer Data Platform Orgs
Address these factors to ensure that your profile counts accurately reflect your business needs.
**Multiple Identity Resolution Rulesets**
Unified Profile counts from all active identity resolution rulesets are used to calculate total billable profiles. Validate the number of active identity resolution rulesets. If more than one is active, determine if all are needed for an active business purpose.
**Data Stream Growth**
As you connect different source systems to Data 360 and increase the volume of data ingested through new data streams, the number of profiles increases. Review all data streams and sources categorized as Profile. Determine if any duplicate, dev, test, or staging sources exist and whether they’re still needed.
**Anonymous Profiles**
Anonymous profiles don’t count toward billable Unified Profiles, but they must be marked as anonymous when they’re ingested. Validate that the Is Anonymous field on the Individual DMO is correctly mapped for any data stream that includes anonymous records.
**DMO Category**
DLOs mapped to DMOs categorized as Profile are available to segment on and are included in the Unified Profile count. Review all mappings from DLOs to DMOs. Determine if all data streams mapped to DMOs categorized as Profile contain a population that you want to segment by or use as the starting population for a segment. Determine if any DMOs are categorized incorrectly as Profile.
If a DMO is categorized incorrectly as Profile, you can change its category to Other. You can change a DMO’s category only if it isn’t used in segmentation or activation. Delete all segments and activations that use the DMO before changing the category from Profile to Other. See [Change the Category of a Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_change_data_model_object_category.htm&release=264.0.0&type=5 "In most cases, a data model object’s category can’t be changed after the object is created. The category can be changed only if it’s changing from Profile to Other or from Other to Profile on an object that isn’t used in segmentation or activation.").

Note Changing the Individual DMO can impact identity resolution.
**Additional Unified Profile Count Considerations for Customer Data Platform Orgs**
- Data created from a transform that is output as an unmapped DMO isn’t counted toward billable Unified Profiles. If a DLO isn’t mapped, it doesn’t count.
- A DLO that is mapped to the Individual DMO and also to a DMO of type Profile isn’t counted twice.
- All DLOs that are mapped to a DMO with type Profile count toward billable Unified Profiles. This count includes these scenarios.
- Data streams outside of identity resolution counts
- Consent DMOs outside of identity resolution counts
- Data transform or stream transform DLOs mapped to DMOs of type Profile outside of identity resolution counts
## Calculating Segment Publishes for Customer Data Platform Orgs
Your Segment Publish entitlement is the maximum number of billable segment publishes during your contract period.
Each time a segment is published, it counts as one billable segment publish. If a segment has more than one activation or no activation associated with it, a single publication of that segment is counted as one segment publish operation. Segment publishes that are completed during the time period are summed and counted toward your entitlement.
To estimate your billable segment publication counts, review all publish schedules for all segments.
## Calculating Engagement Events for Customer Data Platform Orgs
Your Engagement Events are calculated by summing all records in DLOs categorized as Engagement or Other, so everything that doesn’t count as a Unified Profile record is counted as an Engagement Event. Profile type DLOs that are mapped to Other type DMOs are also counted. You’re billed if your number of records exceeds your entitlement.
To calculate the number of billable records, go to the Data Lake Object home page. Sum the record counts of all DLOs except the ones that are mapped to a Profile type DMO because these DLOs are counted as Unified Profiles. An unmapped DLO counts for Engagement entitlement but not for Unified Profile entitlement.
For example, if a purchase record is copied from a source DLO to a target DLO using data transforms, the record is counted as two Engagement Events because all records in both DLOs are part of the sum.
# Customer Data Platform License Billing and Limits
Customers with this license have access to Data 360 on a Salesforce org. This license is no longer available for purchase and can't be renewed. Orgs with this license are billed based on the numbers of profiles, engagements, and other records in their orgs. Other features have limits. Not all Data 360 features are available on Data 360 orgs with this license.
- **[Migrate Users from a Customer Data Platform License to a Data Cloud License](https://help.salesforce.com/s/articleView?id=data.c360_a_license_update_perm_set_migration.htm&release=264.0.0&type=5)**
When you add a Data Cloud license to an org that was previously operating Data 360 under a Customer Data Platform license, the permission sets granted by the Customer Data Platform license no longer grants access to Data 360. To provide users continued access to Data 360, you must assign the permission sets associated with the Data Cloud license to your users.
- **[Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5)**
Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.
- **[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5)**
Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.
# Customer Data Platform Limits and Guidelines
Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.
Some limits and guidelines vary by edition or org type, such as when using Data 360 in a Developer org.

Note Some limits, guidelines, and usage billing calculations differ depending on your org’s license.
For billing information, refer to this additional document if your Data 360 org is operating under a Customer Data Platform license.
- [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.")
For a list of documents related to other licenses, see this document instead.
- [Data 360 Licenses, Billing, and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_licenses_billing_limits.htm&release=264.0.0&type=5 "How you pay for data services provided by Data 360 depends on how your Data 360 org is licensed. Your licenses determine both billing method and limits for your org. We recommend working with your account exec before buying Data 360 or when your contract renews to ensure your license is the best choice based on your usage and growth potential.")
Contact your account executive if you aren’t sure which documents apply to you.
## General Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Location of data storage
Number of anonymous profiles
Total Number of Known Profiles x 5
For example, if you have 100 known profiles in your account, you can have 500
anonymous profiles.
Number of Data 360 permission set licenses
Learn about Data 360 Standard Permission Sets ,
Permission Set Considerations , and Salesforce Features and Edition
Allocations .
Number of data spaces
Depends on the number of licenses purchased
When using Data 360 in a Developer org: 1
Learn more about licenses in Data 360 Standard Editions
and Licenses
In developer orgs, the default data space is the only
data space.
Data Spaces permission sets
Data spaces permission sets can’t be included in permission set groups.
Data
spaces permissions sets aren’t counted against the Number of Data 360 Permission Set Licenses limit.
Unsupported features
Data Kits: Marketing Cloud Engagement data streams aren’t installable
Unsupported orgs
Professional Edition orgs
Government Cloud
Sandbox orgs
Data Cloud One connections
Not available
## Activation Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Scheduled activation publish frequency
Minimum: 12 hours
Maximum: 24 hours
Learn more in
Review Publish History of Your
Activation .
Total number of attributes
Learn more about attributes in
Create Activation for a Segment .
Number of segments to an activation target
Each segment can be sent to an activation target one time. Learn more in Create Activation for
a Segment .
Number of activation targets total
300
When using Data 360 in a Developer org: 15
An activation target is information stored for a given activation platform,
which is the location that a segment’s data is being sent to during the activation
process.
Total number of activations
Total Number of Contracted Segment Publishes x 4
For example, if you purchased 100 segments, you can create up to 400
activations.
Total number of activations with related attributes
Use up to 100 activations with related attributes. After reaching that limit,
choose to delete related attributes from existing activations or create activations
with only direct attributes.
Total number of related attributes per activation
300 across no more than 4 data model objects in the same path
Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum records in a segment with related attributes
If the segment has more than 10 million records and contains related attributes
when you publish, the segment doesn’t activate. Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum levels away from the Activation Membership DMO with related
attributes
Choose attributes from DMOs 5 levels away from your selected Activation
Membership DMO. Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum number of related attribute records selected
Select the number of records sent for a given attribute in your Activation
payload.
Number of ad audience activations to ad audience partners
3 ad audience activations
Additional add audience activations are available for purchase.
The ad
audience partners are Google Ads, Meta (Facebook), and Amazon Ads.
One ad
audience allows a customer to activate one segment to an ad audience
partner.
For example, sending one segment to a Meta account and one segment
to a Google account equals two ad audiences.
If a customer purchases 10
additional ad audience activations, then the total number will be 13 since it
comes with 3 and 10 were purchased.
Number of activation records processed per org per year for each ad
audience
For example, customers with three ad audiences can consume up to 255 billion
activation records processed in a 12-month period.
Maximum number of characters for file storage activation
## AI Models (formerly Einstein Studio) Guidelines and Limits
## Calculated Insights Guidelines and Limits
## Data Actions Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of data actions per tenant
Total number of data action targets per tenant
This limit is enforced by the UI.
Total number of rules per data action
Refers to the number of filter rules in a data action definition.
## Data Explorer Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of columns queried at a time
Total number of rows displayed per page
## Data Federation Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Number of external data lake objects allowed per org
The profiles in the external tables account towards the billable profile count
limits and any extra profiles beyond the contracted entitlements would incur
overages.
## Data Graph Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of data graphs per org
Maximum number of draft data graphs per org
Scheduled data graph refreshes per day
You can schedule data graphs to refresh every four hours, daily, weekly, or
monthly. You can also refresh them manually.
Maximum number of JSON records that each data graph supports
Including objects with more than 200 million records total in a data graph
impacts data graph refresh times and query response times.
Maximum size of a real-time data graph
Real-time data graphs aren't available
Maximum number of objects per data graph
The data graph’s primary data model object, related data model objects, and
calculated insights count toward this limit.
Maximum number of fields per data model object that can included in a data
graph
Primary key, foreign key, and key qualifier fields aren’t included in this
limit.
Maximum number of engagement events in a real-time data graph
Real-time data graphs aren't available
Maximum age of engagement data included in a real-time data graph
Real-time data graphs aren't available
Maximum number of measures per calculated insight that can be included in a
data graph
Maximum number of total fields and measures that can be included in a data
graph
Primary key, foreign key, and key qualifier fields aren’t included in this
limit.
Maximum number of levels that data model objects (DMO) can be nested below the
primary DMO in a data graph
Levels are represented as a tree structure in the data graphs editor. The
nesting tree including the primary DMO can have a total of 6 levels.
Maximum number of records allowed by the recency filter
Maximum amount of time available for the time filter
## Data Ingestion Guidelines and Limits
**General**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of fields per data stream
Maximum number of single field types in a data stream
Total data size limit
When using Data 360 in a Developer org: 100 GB
Total number of CRM custom objects
This limit applies to the number of custom objects ingested from each connected
CRM org.
Total Number of CRM orgs that can be connected to Data 360
Total number of data models
7,500
When using Data 360 in a Developer org: 300
Total number of data streams
5,000
When using Data 360 in a Developer org: 100
Total number of data lake objects (DLOs)
5,000
When using Data 360 in a Developer org: 100
This limit applies to data lake objects created as part of data streams or in a
standalone manner.
Total Number of Marketing Cloud Personalization (Interaction Studio) datasets
per instance
Maximum number of rows for a Marketing Cloud Engagement Data Extension full
extract
**GCS, Azure, and S3 Bulk Ingestion**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Optimal number of file rows when creating S3 data streams
When creating an S3 data stream, you may need to use a file smaller than the
data you’d like to ingest. The smaller file should contain the same headers and
about 1,000 rows. Once the data stream is created, larger files can be placed within
the file path, maintaining that they fall within set limits.
Optimal size per CSV file
Sometimes, particularly for Day 0 loads, it’s necessary to move
large data volumes. Recommended limits are: 200 GB max per file and 1,000 files max
per scheduled run. These two parameters aren’t intended to be stretched to their
respective maximums concurrently. Rather consider some tradeoff between the two
extremes and refer to the maximum data size guidelines for more context.
Optimal size per parquet file
Maximum number of files per scheduled run
Maximum size per uncompressed CSV file
Maximum size per compressed CSV file
Compressed CSV files aren’t splittable, meaning that they don't allow for
parallel processing and their usage is therefore discouraged. If sending in a
compressed file, it must be a single file per zip.
Maximum size per uncompressed parquet file
We recommend you to use the parquet compression capabilities to reduce file
size.
Maximum size per compressed parquet file
Compressed parquet files are splittable and support parallel processing of
ingestion. There are several native compression options. Learn more about supported
compression formats in Supported File Formats in Data 360 .
Maximum data size for upsert
When a data stream is on upsert, it’s best not to exceed a 50-GB aggregate
across all files in the single run. This number is strongly influenced by the number
of distinct data dates present in the table, the overall size of the table, and
several other factors such as the number of columns. As these variable inputs
increase you may experience performance degradation.
For larger target tables and
larger upsert ingestions, we strongly recommend using engagement tables and
selecting an engagement date field that contains many distinct dates. Not using
engagement nor selecting a high cardinality date field may cause performance
degradation.
Maximum data size for full refresh
Data size is the sum of all file sizes for a single datastream job. When a data
stream is set for full refresh, it’s best not to exceed 1000 GB for all files in a
single run. This number is strongly influenced by the number of distinct data dates
present in the table, the overall size of the table, and several other factors such
as the number of columns. As these input variables increase you may experience
performance degradation.
Maximum number of characters for a single cell
70,000
**Local File Upload**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of characters for a single cell in a local file upload
Supported delimiters
We currently only support the comma (,) delimiter.
Header row requirements
CSV files require a header row name for every field. This requirement is the
same format as what's used for Cloud Drive uploads.
Unsupported refresh of data streams
A data stream created from a local file upload can't be automatically
refreshed. You can upload a new file to refresh your data.
Maximum number of data streams created from a local file upload
Unsupported file or column names
File or column names with multi-byte characters aren't supported.
Primary key uniqueness restrictions
Primary key uniqueness isn’t enforced for local CSV file uploads.
We recommend that your primary key column is unique before uploading a local
file.
**SFTP Ingestion**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum size per file
The SFTP Connector can load up to 1,000 files that are less than 2
GB but total no more than 30 GB per data stream run. If you have more data, you can
use upsert mode for consecutive runs.
Maximum number of files included in a scheduled run
Maximum data per data stream run
Maximum size limit for file allowed during field analysis
Maximum file for PGP-encrypted schema file analysis
Maximum object size for fields
Maximum total size allowed for manual extract
Maximum total number of files allowed for manual extract
## Data Model Object Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Fields per data model object
800 per field type
1,050 total fields
Both custom and system fields are counted toward this limit.
Maximum number of data model objects
7,500
When using Data 360 in a Developer org: 300
Maximum number of custom relationships per data model object
## Data Shares Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of data shares per org
Total number of data share targets per org
This limit isn’t applicable for Salesforce Data 360 data
share targets.
Maximum number of objects included in a data share
## Data Transforms Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of streaming data transforms per org
Maximum number of characters in a streaming data transform SQL statement
Maximum number of batch transforms that can be created in an org
Contact your Account Executive to adjust this limit.
Maximum runtime (duration) of a batch transform job before it’s canceled by the
system
Maximum concurrent batch transforms that can be run at a time
## Document AI Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Document AI
## Identity Resolution Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of identity resolution rulesets
2 per primary data model object per data space
This limit is enforced in the UI.
Consolidating profiles using identity
resolution reduces the number of Individual profiles counted against contracted
entitlements. All unified profiles created from all rulesets are summed, so
deleting unneeded rulesets reduces total unified profiles.
Consolidating
profiles using identity resolution impacts the number of known and anonymous
profiles in your org. To understand how many anonymous profiles are allowed,
review the Number of Anonymous Profiles limit.
Maximum scheduled job frequency per ruleset
Once per day
When using Data 360 in a Developer org: 0
Because the time of day can vary, ruleset jobs can occasionally run more than
once in a 24-hour period. Scheduled ruleset jobs are skipped if there are no changes
to source data, object mappings, or ruleset configurations. This limit is enforced
automatically and isn't configurable.
When using Data 360 in a
Developer org, ruleset runs aren’t scheduled. Use Run
Ruleset to kick off a ruleset job manually.
Maximum number of ruleset jobs in any 24-hour period
4 per ruleset per data space
Ruleset jobs don’t run if there are no changes to source data, object mappings,
or ruleset configurations, or if you’ve already run 4 ruleset jobs in the last 24
hours.
Maximum number of match rules per ruleset
Maximum number of match criteria per match rule
Maximum number of source profiles that can be unified into a single unified
profile
Large profiles usually result from poor data quality or match rules that are
too broad. To reduce the number of matching records, clean your data or refine your
match rules.
Maximum size of source records processed in a ruleset
Records that are larger than 15 KB are skipped when rulesets run.
Maximum number of match rules per ruleset
Maximum number of match criteria per match rule
Maximum combined character count of values reviewed by a match rule
If the sum of characters of values being matched by a single match rule is
greater than 500, some values will be truncated during matching. This can result in
incorrect matches.
Match methods used during real-time matching
Real-time identity resolution isn't available
## Notebook AI Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Notebook AI
## Segmentation Guidelines and Limits
## Streaming Insights Guidelines and Limits
## Unstructured Data and Search Index Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Unstructured data and search indexes
## API Guidelines and Limits
The concurrent request and query limits of Data 360 APIs are independent from the concurrency limits governing the Salesforce platform APIs.
**APIs: Query, Insights, and Profile**
There are three distinct classes of APIs used to extract data: Profile, Query, and Calculated Insights. These API limits for CDP orgs are based on the org’s Data 360 edition, not its Salesforce edition, except when running Data 360 on a Developer org.
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum timeout
The HTTP 408 status code indicates a timeout.
Total number of queries per day for Query API and Insights API
Corporate Edition: 1,000
Enterprise and Enterprise Editions Plus: 1,000
Applies to Query API v1 and v2.
Total number of concurrent inbound requests for Insights API
Corporate Edition: 15
Enterprise and Enterprise Editions Plus: 15
Total number of queries per day for Profile API
Corporate Edition: 10,000
Enterprise Edition: 50,000
Total number of queries per month for Profile API
Corporate Edition: 100,000
Enterprise Edition: 500,000
**Ingest Bulk API**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
API usage limits
After each request, your app must check the response code. The HTTP 429 Too
Many Requests status code indicates that the app must reduce its request
frequency.
Bulk job retention time
Open bulk jobs with the status of Open or Upload Complete that are older than 7
days are deleted from the ingestion queue.
Maximum number of files per job
Maximum payload size
Referring to the CSV files uploaded via Bulk API.
Number of requests or jobs allowed per hour
Number of concurrent requests or jobs Allowed at One Time
**Ingest Streaming API**
These limits and guidelines are for streaming ingestion across Mobile and Web SDK and Ingestion API.
**Profile API**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of records returned per call
Total number of fields per record

Note Unified Profile objects that are filtered on the index column have accelerated response rates. Other Profile category objects can’t guarantee a faster response.
# Customer Data Platform Standard Permission Sets in Data 360
A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.

Tip To determine your org's license, in Setup, go to Permission Sets, and review the license field for your Data Cloud standard permission sets. If the license is Customer Data Platform, this article describes your org's standard permission sets. If the license is Data 360, see [Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.") instead.
## System Administrator
To manage and assign users in Setup and access Data Cloud Setup, you can have a System Administrator user profile or the permissions that grant access to Salesforce Setup.
You don't need a Data Cloud standard permission set to access Data Cloud Setup if you have a system admin profile.
## Standard Permission Sets
You can combine these Customer Data Platform permission sets with other Salesforce permission sets for users who need additional access.
**Data Cloud Admin**—Users with this permission set can access all functionality within Data 360.
**Data Cloud Data Aware Specialist**—Users with this permission set can map data to the data model and create data streams, identity resolution rulesets, and calculated insights.
**Data Cloud Marketing Manager**—Users with this permission set can manage an overall segmentation strategy, including creating activation targets and activations.
**Data Cloud Marketing Specialist**—Users with this permission set can create segments.
Table key:  Full Access  View Only
| Feature | System Admin Profile | Data Cloud Admin | Data Cloud Data Aware Specialist | Data Cloud Marketing Manager | Data Cloud Marketing Specialist |
| --- | --- | --- | --- | --- | --- |
| Data Cloud Setup |  |  | | | |
| Data Space Management |  | | | | |
| Data Additions to a Data Space | |  |  | | |
| Data Streams | |  |  |  |  |
| Data Shares | |  |  |  |  |
| Data Lake Objects | |  |  |  |  |
| Data Transforms | |  |  |  |  |
| Data Model | |  |  |  |  |
| Data Graphs | |  |  |  |  |
| Identity Resolution | |  |  |  |  |
| Data Explorer | |  |  | | |
| Profile Explorer | |  |  | | |
| Calculated Insights | |  |  |  |  |
| AI Models | |  |  |  |  |
| Data Action and Data Action Targets | |  |  |  |  |
| Segments | |  |  |  |  |
| Activation and Activation Targets | |  |  |  |  |
| Communication Capping Setup |  | | | | |
| Communciation Capping Configuration | |  | | | |

Tip Data 360 standard permission sets are automatically updated with each release as new features become available. Using a custom permission set could result in users not having access to new features or functionality.
# Customer Data Subject Rights in Data Transforms
A customer’s Data Subject Rights relate to the storage and use of their personal data. Data 360 offers tools to support Data Subject Rights in alignment with various data protection and privacy regulations.
Submit all Data Subject Rights requests using the Salesforce Consent API.
To ensure that Data Subject Rights are maintained, verify that all personal data is mapped to the Individual DMO.
The Consent API operates on all data stored in DLOs mapped to Individual. For example, in this diagram, DLO2 and DLO4 are mapped to the Individual and Contact Point Address DMOs. Contact Point Address has a relationship with Individual. Because DLO2 and DLO4 are directly or indirectly mapped to Individual DMO, the Consent API operates on these two DLOs.
Data lake objects DLO1, DLO3, DLO5, and DLO6 aren’t mapped to the Individual DMO or any of the Contact Point DMOs, so the Consent API doesn’t operate on these DLOs. You can remove personal data from these DLOs by deleting it from the data stream records.
Data stream-based deletions only apply to source DLOs. Streaming data transforms automatically transfer deletions to relevant target DLOs.
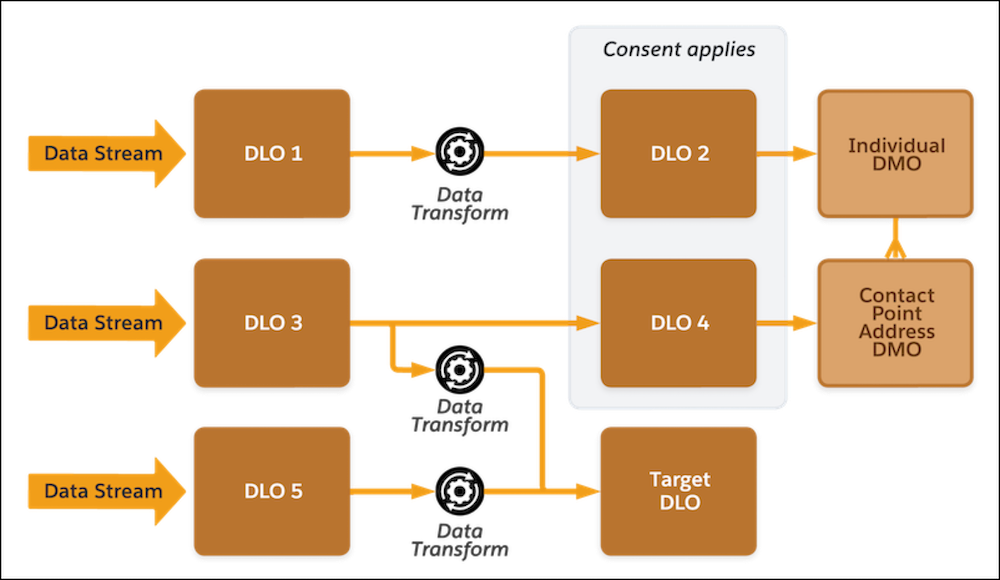
#### See Also
- [_Salesforce Help_: Data Subject Rights](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights.htm&release=264.0.0&type=5 "A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.")
- [_Salesforce Help_: Impact of Data Modeling on Data Subject Rights Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_data_modeling_impact_on_dsr_requests.htm&release=264.0.0&type=5 "Learn more about how Data Modeling impacts your Data Subject Rights Requests in Data 360.")
- [_Salesforce Help_: Delete Data Stream Records](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_stream_records.htm&release=264.0.0&type=5 "You can delete data ingested into Data 360. Your data stream must have an upsert refresh mode. The deletion process depends on the type of connector that you’re using.")
# Customer Data Subject Rights in Insights
A customer’s data subject rights relate to the storage and use of their personal data. When an insight uses the individual data model object (DMO), Data 360 automatically applies your customers’ data subject rights requests to the insight output.
Submit all data subject rights requests using the Salesforce Consent API. You can request restriction of processing for common General Data Protection Regulation (GDPR) scenarios, such as data deletion. For more information, see [Data Subject Rights](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights.htm&release=264.0.0&type=5 "A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.").
To make sure that data subject rights are applied to your insights, map your personal data to the individual DMO. Insights that use DMOs other than the individual DMO don’t have any automatic data subject rights checks. See [Impact of Data Modeling on Data Subject Rights Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_data_modeling_impact_on_dsr_requests.htm&release=264.0.0&type=5 "Learn more about how Data Modeling impacts your Data Subject Rights Requests in Data 360.").
Based on the data sent through the Consent API, each insight type handles data subject rights requests as described in this table.
Data Subject Rights Handling by Insight Type
| Insight Type | Data Subject Rights Handling |
| --- | --- |
| Calculated insight | The calculated insight job automatically removes individuals with a data subject rights request from the output each time it runs. |
| Streaming insight | Because a streaming insight processes data continuously and doesn’t recompute past windows, a data subject rights request is applied only to future window processing. Individuals with a data subject rights request aren’t removed from window data that’s already aggregated. |
| Real-time insight | Data subject rights requests aren’t referenced during per-event processing. A companion batch calculated insight performs the check, and the results are applied on the next scheduled real-time data graph refresh. |
## Calculated Insights
When a calculated insight definition uses the individual DMO, the calculated insight job automatically removes individuals with a data subject rights request from the calculated insight object output each time it runs.
## Streaming Insights
When a streaming insight definition uses the individual DMO, the streaming insight applies data subject rights requests to future window processing only. Because a streaming insight processes data continuously and doesn’t recompute past windows, an individual with a data subject rights request isn’t removed from window data that’s already aggregated.
## Real-Time Insights
Real-time insights don’t reference data subject rights requests during per-event processing. Instead, each real-time insight has a companion batch calculated insight that performs the data subject rights check. On the next scheduled real-time data graph refresh, the real-time insight metrics and dimensions are updated to reflect the check.
Because the check is applied on a scheduled refresh rather than during event processing, an individual with a recent data subject rights request can still appear in real-time insight results until the next real-time data graph refresh.
#### See Also
- [_Salesforce Help_: Data Subject Rights](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights.htm&release=264.0.0&type=5 "A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.")
- [_Salesforce Help_: Impact of Data Modeling on Data Subject Rights Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_data_modeling_impact_on_dsr_requests.htm&release=264.0.0&type=5 "Learn more about how Data Modeling impacts your Data Subject Rights Requests in Data 360.")
# Customize, Test, and Validate Retrievers with Retriever Playground
Fine-tune and validate retrieval logic for retrieval-augmented generation (RAG) systems by using retriever playground, reducing deployment risks, and verifying accurate AI outputs. Use AI Models (formerly Einstein Studio) retriever playground to configure pre-filters, select test data, and adjust result parameters to customize retrieval logic for domain-specific use cases, such as retrieving complaince documents or knowledge articles.
### Required Editions
Review intermediate outputs and key metrics, such as the Source Recall Score or Context Recall Score, to validate that the retriever finds information from expected source documents. Fine-tuning retrieval logic in the retriever playground is a cost-effective way to test and debug retrievers. Retriever playground improves agent performance and search relevance, establishing reliable and meaningful generative AI outcomes.
## Use Case: Agent Answers Field Service Questions on Installing Double Door Refrigerators with Incomplete Results
A business administrator sets up an agent to respond to questions from contractors in the field who install their company refrigerators.
Problem: Although the company knowledge base includes an article with complete step-by-step installation instructions, the field service provides feedback that responses from the agent are incomplete. The business admin tests the retriever set up for the agent in the retriever playground.
The test shows that only five steps are retrieved from the eleven-step article.
In reviewing the retriever results panel, the admin notices that the search index splits the article into two chunks. The top chunk includes the "double-door refrigerator" keyword. Because the second chunk dosen't include the necessary keywords from the question, it's scored lower in the result set and doesn't appear in the response.
Solution: The admin increases the number of test results to include the chunk that contains the rest of the instructions. Then, the admin can test the new configuration with sample questions about installing double-door refrigerators to make sure that the response is complete.
- **[Test an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_create.htm&release=264.0.0&type=5)**
Test a retriever configuration to ensure accurate responses from your AI agents. Save retriever configurations as new versions of the retriever in AI Models (formerly Einstein Studio). Activate them for use in agents with prompt templates, Flow, and apps.
- **[Test an Ensemble Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_ensemble.htm&release=264.0.0&type=5)**
Test an ensemble retriever configuration in the AI Models retriever playground before you use it in prompt templates or AI agents. Add or remove retrievers to an ensemble, configure test data, and result parameters to verify the retrieval logic.
- **[Retriever Metrics and Results](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_metrics.htm&release=264.0.0&type=5)**
Review retriever metrics and the retrieved data chunks to understand the results of your test. Modify the retriever configuration to try different configurations and expected source data to get an optimal response. Save your configuration as a new version of the retriever.
- **[Billing Considerations for Testing Retrievers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_billing.htm&release=264.0.0&type=5)**
When you test retrievers by querying search indexes, your data is processed in Data 360. The primary usage type for retriever testing is Data Queries. Use of retriever playground impacts the consumption of credits used for billing in the following usage types.
#### See Also
- [_Salesforce Help_: Retrieval Augmented Generation (RAG)](https://help.salesforce.com/s/articleView?id=ai.generative_ai_rag.htm&type=5&language=en_US)
- [_Salesforce Help_:Ground with Knowledge Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&language=en_US)
- [_Salesforce Help_: Search for AI, Automation, and Analytics](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&type=5&language=en_US)
# Data 360 and Cross-Cloud Implementation Guides
Use printable PDF guides to set up, administer, and configure Data 360 features and applications. PDF guides are updated regularly, so check the date of any downloaded and saved guides before beginning your implementation.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
## Data 360 Implementation Guides
| Guides | For Admins | For Business Users | For Marketers |
| --- | --- | --- | --- |
| [Worksheet: Data Cloud Checklist and Considerations](https://resources.docs.salesforce.com/rel1/doc/en-us/static/pdf/Data_Cloud_Checklist.pdf) |  |  |  |
| [Data 360 Implementation Overview Guide](https://sfdc.co/cdp_guide) |  |  |  |
| [Data 360 Implementation Guide](https://sfdc.co/cdp_admin_guide) |  | | |
| [Marketer’s Guide to Data 360](https://sfdc.co/cdp_marketer_guide) | | |  |
## Cross-Cloud Implementation Guides
| Guides | For Admins | For Business Users | For Marketers |
| --- | --- | --- | --- |
| [Account Engagement: Data Cloud Integration Implementation Guide](https://resources.docs.salesforce.com/latest/latest/en-us/sfdc/pdf/mcae_data_cloud_implementation_guide.pdf) |  | |  |
| [Data Cloud Quick Start Guide: Get Started with Sales or Service Cloud Use Cases](https://resources.docs.salesforce.com/rel1/doc/en-us/static/pdf/DataCloud_QuickStart_Guide.pdf) |  |  | |
# Data 360 and Tableau Use Cases
Tableau helps you explore, analyze, and find hidden insights in your data. The Tableau to Data Cloud connectors use the Hyper query engine to provide fast processing. You can explore your Data 360data in near real time enabling quick and accurate decision-making. These example use cases illustrate how Data 360and Tableau work together to help you achieve your business goals and deliver a personalized experience for your customers.
## Auto Industry
An automobile company wants to recommend new features and services that are relevant to each customer. The customer data is in the Marketing Cloud Engagement. The company also has other sources for vehicle-related data (mileage, frequent locations) and personal driving data (driving patterns, location).
In Data 360, ingest, prepare, and unify the data to create a customer record that represents a single source of truth for each customer. Build segments to send personalized campaigns.
Create data models that you can then use to explore and analyze in Tableau.
- Understand how your customers are using your products and services to make better and relevant recommendations.
- Decide on which new features would be useful and more likely to be adopted by customers in specific regions.
- Gather key insights that can help you make business decisions, such as problems or alerts from vehicles based on model or driving range for electric vehicles.
## Financial Services
A finance company is looking to simplify its customers’ banking experience and understand user interests based on the various channels that a customer engages with.
To provide a customer journey that is simple and personalized, create a single and consistent view of each customer. In Data 360, ingest data from Engagement, Sales Cloud, and other data sources, such as banking transactions, real estate, or other financial services. Use calculated insights to determine when and how to engage with customers. Create segments based on this information.
Use Tableau to consolidate and analyze data from Salesforce to get a deep understanding of customers and create a data-driven approach.
# Data 360 Architecture Strategy
As you plan your multi-org architecture, consider these data tenancy, residency details, and administrative management details. In some cases, you need more than one Data 360 instance to fulfill legal or business requirements.
You can enable Data 360 on an existing Salesforce org or set up a new one as your Data 360 hub to keep Data 360 functionality separate from your existing Salesforce ecosystem.
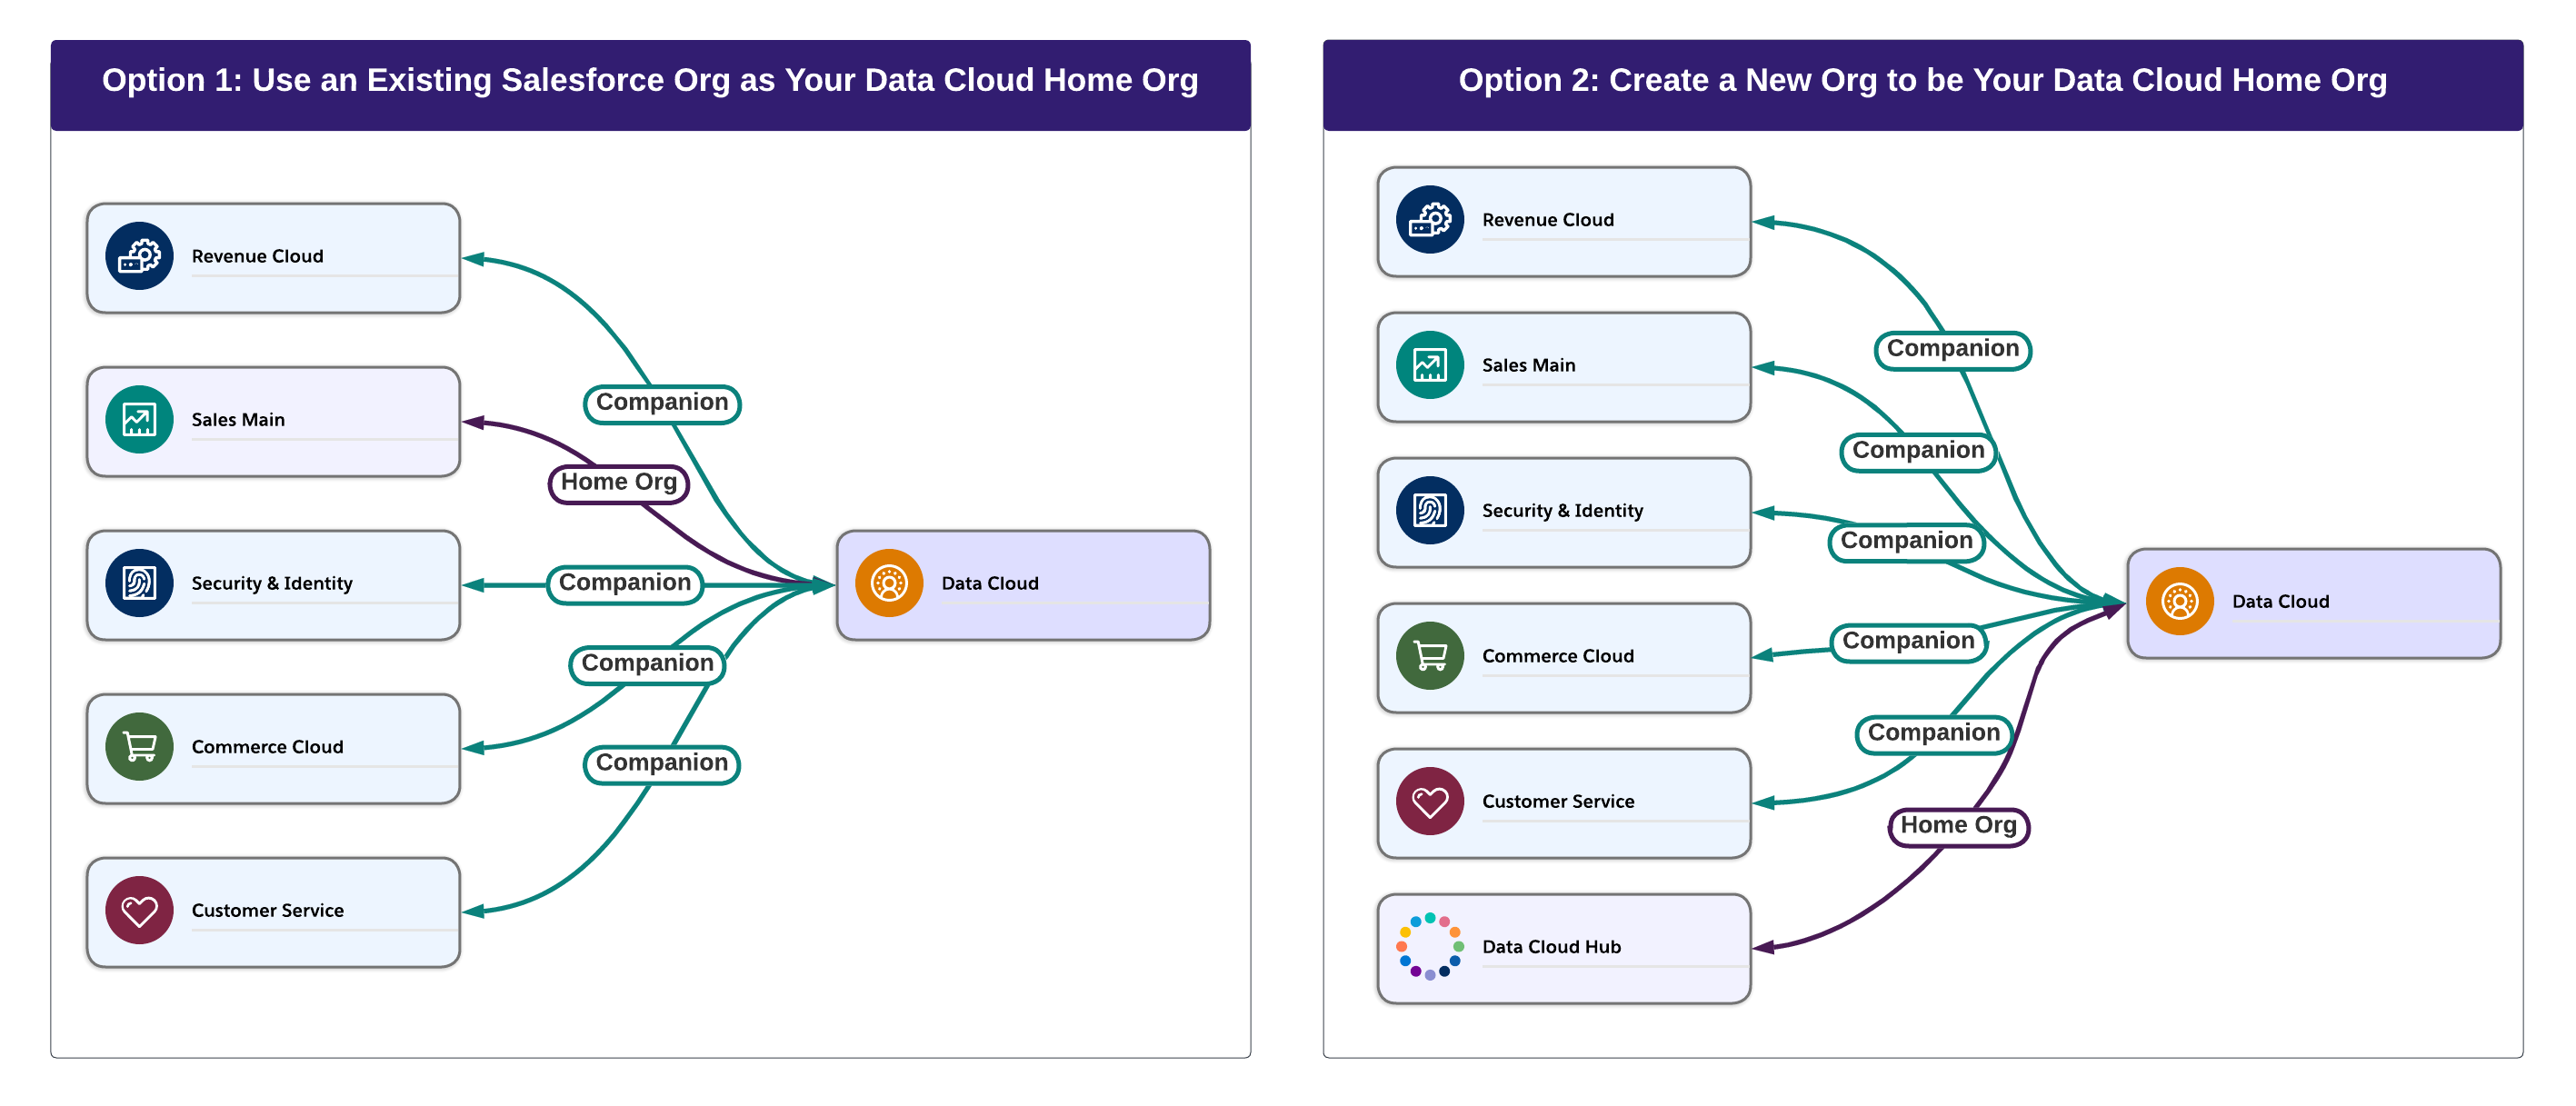
## Data 360 Data Residency Considerations
You can host your Data 360 org in a region that differs from other Salesforce clouds or external source systems. Data 360 can ingest data from multiple regions, but consult with your legal counsel and review your organization’s policies for data residency before doing so. You can also create one Data 360 per region and use Data 360 to unify and enrich data from multiple orgs in that region. For information on Salesforce’s data transfer mechanisms and related topics, see Salesforce’s [privacy resources](https://www.salesforce.com/uk/company/privacy/).
## Data Processing Considerations
Data is processed when users view and update records, create objects that are shared between orgs, or generate reports. Connecting orgs with a standard CRM org or a Data Cloud One companion connection changes where data is processed, which could have legal implications. Review all applicable laws with your legal counsel and consult your business policies for data residency requirements.
Establishing a connection between data spaces in a home org and companion orgs causes data to be processed across all connected orgs. These orgs might be located in different territories. Consult the infrastructure and subprocesses doc to understand the applicable processing locations for your home and companion orgs. Configuring a new companion org doesn’t change the storage location of data in the home org.
## Billing and Credit Consumption Considerations
Ingesting data from Salesforce orgs can have billing implications. Consumption of the credits still occurs on the home org.
## Administration Considerations
When enabled on a Salesforce org, Data 360 can connect to and unify data from multiple sources. Enterprise-level data modelers and data architects can use Data 360 to establish a single source of truth for all business units across one or more Salesforce orgs. Where to set up Data 360 and how many instances of Data 360 to set up depends on your data architecture and data residency requirements.
## Data 360 Architecture Considerations
Data needs—Access your organization’s data requirements, including data modeling, testing, and the need for separate environments.

Tip Get help preparing for and planning your data usage by completing the [Build a Data Strategy for Data 360](https://trailhead.salesforce.com/content/learn/trails/build-a-cdp-data-strategy) Trailhead module.
Future growth—Identify your long-term growth objectives to confirm the decision to implement a single Data 360 instance.
Control vs Centralization—Assess whether all orgs require complete control over their data and Data 360 configurations. If so, creating multiple Data 360 orgs is advisable. However, if you want to centralize control across orgs, connect multiple orgs to a single Data 360.
Separation of functionality—If you enable Data 360 on a new Salesforce org, you can use that org exclusively for Data 360 tasks. For example, to set up separate administrative teams, set up Data 360 on a new org.
Shared functionality—If you enable Data 360 on an existing Salesforce org, all Data 360 features are available to users in the existing org. System admins in the existing org can access Data Cloud Setup.
- **[Multi-Brand Management in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_multi_brand_management.htm&release=264.0.0&type=5)**
To manage multiple brands, set up Data 360 across different location tenants.
- **[Connect Salesforce CRM Orgs to Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_salesforce_orgs.htm&release=264.0.0&type=5)**
Connect your Salesforce orgs to Data 360 to ingest data from Salesforce objects for processing and unification in Data 360. Depending on the type of connection that you select, you can send back only data actions or harmonized Data 360 data. To access Data 360 data and features in your Salesforce CRM orgs, set up a Salesforce companion connection. Platform components, such as Flow, Apex, CRM, and data enrichment, can also access Data 360 data across companion orgs.
#### See Also
- [_Salesforce Help_: Manage Your Salesforce Account](https://help.salesforce.com/s/articleView?id=xcloud.users_checkout.htm&type=5&language=en_US)
# Data 360 Auto Mapping Model Card
The Auto Mapping model automatically maps data lake object (DLO) source fields to data model object (DMO) target fields. The model reduces the amount of manual labor and time required to configure new data streams in Data 360.
- **[Model Details](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
The Auto Mapping model automatically maps data lake object (DLO) source fields to data model object (DMO) target fields. The model reduces the amount of manual labor and time required to configure new data streams in Data 360.
- **[Intended Use](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
The Einstein Content Selection and Testing model in Marketing Cloud Engagement is intended for these use cases.
- **[Relevant Factors](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
These factors are associated with the Data 360 Auto Mapping model.
- **[Metrics](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
Data 360 evaluates and monitors model performance metrics to maintain and improve the quality of the model.
- **[Ethical Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
The model is based on metadata and doesn’t include demographic data. The headers referenced are standardized within the Salesforce Platform or customized per organization. We recommend not using specific values for gender, race, or other demographic data as your field label.
## Model Details
The Auto Mapping model automatically maps data lake object (DLO) source fields to data model object (DMO) target fields. The model reduces the amount of manual labor and time required to configure new data streams in Data 360.
### Person or Organization
Salesforce Data 360
### Model Date and Version
- Pre-trained model, based on MPNet is incorporated into the Auto Mapping mechanism.
- Anonymous metadata collection begins in June 2023 (Summer ’23).
- Separate instances of the pre-trained model will be introduced per org in Winter ’24.
- Minor changes can occur throughout a release.
- Major changes can occur and are communicated via release notes.
### Model Type
The Auto Mapping model is a multi-class semantic textual similarity (STS) model that assigns a score based on the similarity of two texts. The model is pretrained on open datasets and provides a foundation to fine-tune your data to use within your environment. The model provides auto mapping capabilities even if you have little to no data. The downstream models are built to use only your individual data. No global models are trained using customers’ data.
### General Information
The solution is based on the sentence-transformers pretrained model “all-mpnet-base-v2”, which is fine-tuned on over 1 billion sentence pairs. The pretrained model is available on HuggingFace and is incorporated into the Auto Mapping solution to allow for customization for each customer based on their data and needs.
### Licenses
Auto Mapping is available to Salesforce customers that have a Data Cloud license.
### Questions or Comments
Send questions or comments about the model to support@salesforce.com.
## Intended Use
The Einstein Content Selection and Testing model in Marketing Cloud Engagement is intended for these use cases.
### Primary Intended Uses
You can use the Auto Mapping model to map metadata. The primary use cases are platform admins mapping DLOs to the data model and solution architects implementing Data 360 solutions. Anything other than this use case is out of scope and not recommended.
- Platform admins mapping DLOs to the data model
- Solution Architects implementing Data 360 solutions
### Out-of-Scope Use Cases
- Anything other than the primary use case is out of scope and not recommended.
## Relevant Factors
These factors are associated with the Data 360 Auto Mapping model.
### Model Inputs
- DLO field header names and data types (metadata)
- DMO field header names and data types (both standard DMOs and custom DMOs)
### String Similarity and Semantic Similarity
- The Auto Mapping model is based on finding string similarity between fields and semantic similarity. STS assigns a score on the similarity of two texts.
### Previous Mappings
- The model uses usage data, such as previous mappings performed by a specific tenant. The previous mappings are used as possible suggested mappings.
- All the models are single-customer models without any cross-customers or global models. Mappings aren’t shared between customers.
## Metrics
Data 360 evaluates and monitors model performance metrics to maintain and improve the quality of the model.
### Model Performance Measures
Aggregated model performance metrics are gathered to monitor, maintain, and improve the quality of the model. Model performance is based on the number of automapping recommendations that you’ve approved, rejected, or modified.
- Recall = number of mapping recommendations approved by the user / final number of correct mappings
- Precision = number of mapping recommendations approved by the user / total number of mappings recommendations
- Accuracy = 1 – (modified + added) / (total number of mappings recommendations) = Recall\*(2–1/Precision)
All metrics are aggregated and anonymized. The mapping recommendations are only shown above a certain threshold. The exact threshold won’t be determined until Winter ’24.
## Ethical Considerations
The model is based on metadata and doesn’t include demographic data. The headers referenced are standardized within the Salesforce Platform or customized per organization. We recommend not using specific values for gender, race, or other demographic data as your field label.
### Caveats and Recommendations
One of the main challenges is understanding and modeling the elements within a variable context. The semantic similarity of DLO and DMO fields depends on context, resulting in ambiguity.
### Customer Data Privacy
The Data 360 model complies with all relevant regulations and ensures customer privacy by encrypting data using OrgService. The model allows only data scientist access to customer data for debugging, validation, and verification purposes in a secured environment without any data extraction.
# Data 360 Clean Room Collaboration Process Overview
In a clean room collaboration, you and another party can run permitted queries on each other's data while keeping raw records private. The provider specifies which data to share, under what terms, using a collaboration template. Data 360 enforces appropriate privacy and security measures, and gives both parties full visibility into how their metadata is accessed and queried.
### Required Editions
Creating and distributing AppExchange clean room packages: Developer Edition Deploying packages, creating collaborations, accepting invitations, and running queries: Enterprise Edition (home org)
The standard clean room flow applies to use cases such as segment overlap that return query results to a DMO. Some use cases diverge from this flow: clean room activation, identity boost, and collaborations with an AWS Clean Rooms provider. See [Use Case Variations](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_how_clean_room_works.htm&release=264.0.0&type=5).
In a clean room, you collaborate as a provider or as a consumer. To collaborate, both parties map their data to the clean room with the guidance of a collaboration template. The required and optional data fields are predefined in the template, along with the collaboration terms, such as the permitted queries, which party runs the queries, and which party receives the query results.
Data 360 clean rooms use data sharing between Data 360 orgs to securely associate metadata and support federated querying of configured datasets. If you don’t have your data in Data 360, ingest your data or use zero copy to associate your metadata to a clean room. When the collaborator runs a query in a clean room, Data 360 applies the required privacy measures to the data. Data 360 stores the query results—aggregated to preserve privacy—in data model objects (DMOs). Then, you create reports from them.
## Standard Clean Room Use Case
Here’s the sequence of events for a standard clean room collaboration. For example, use this process to identify segment overlap.
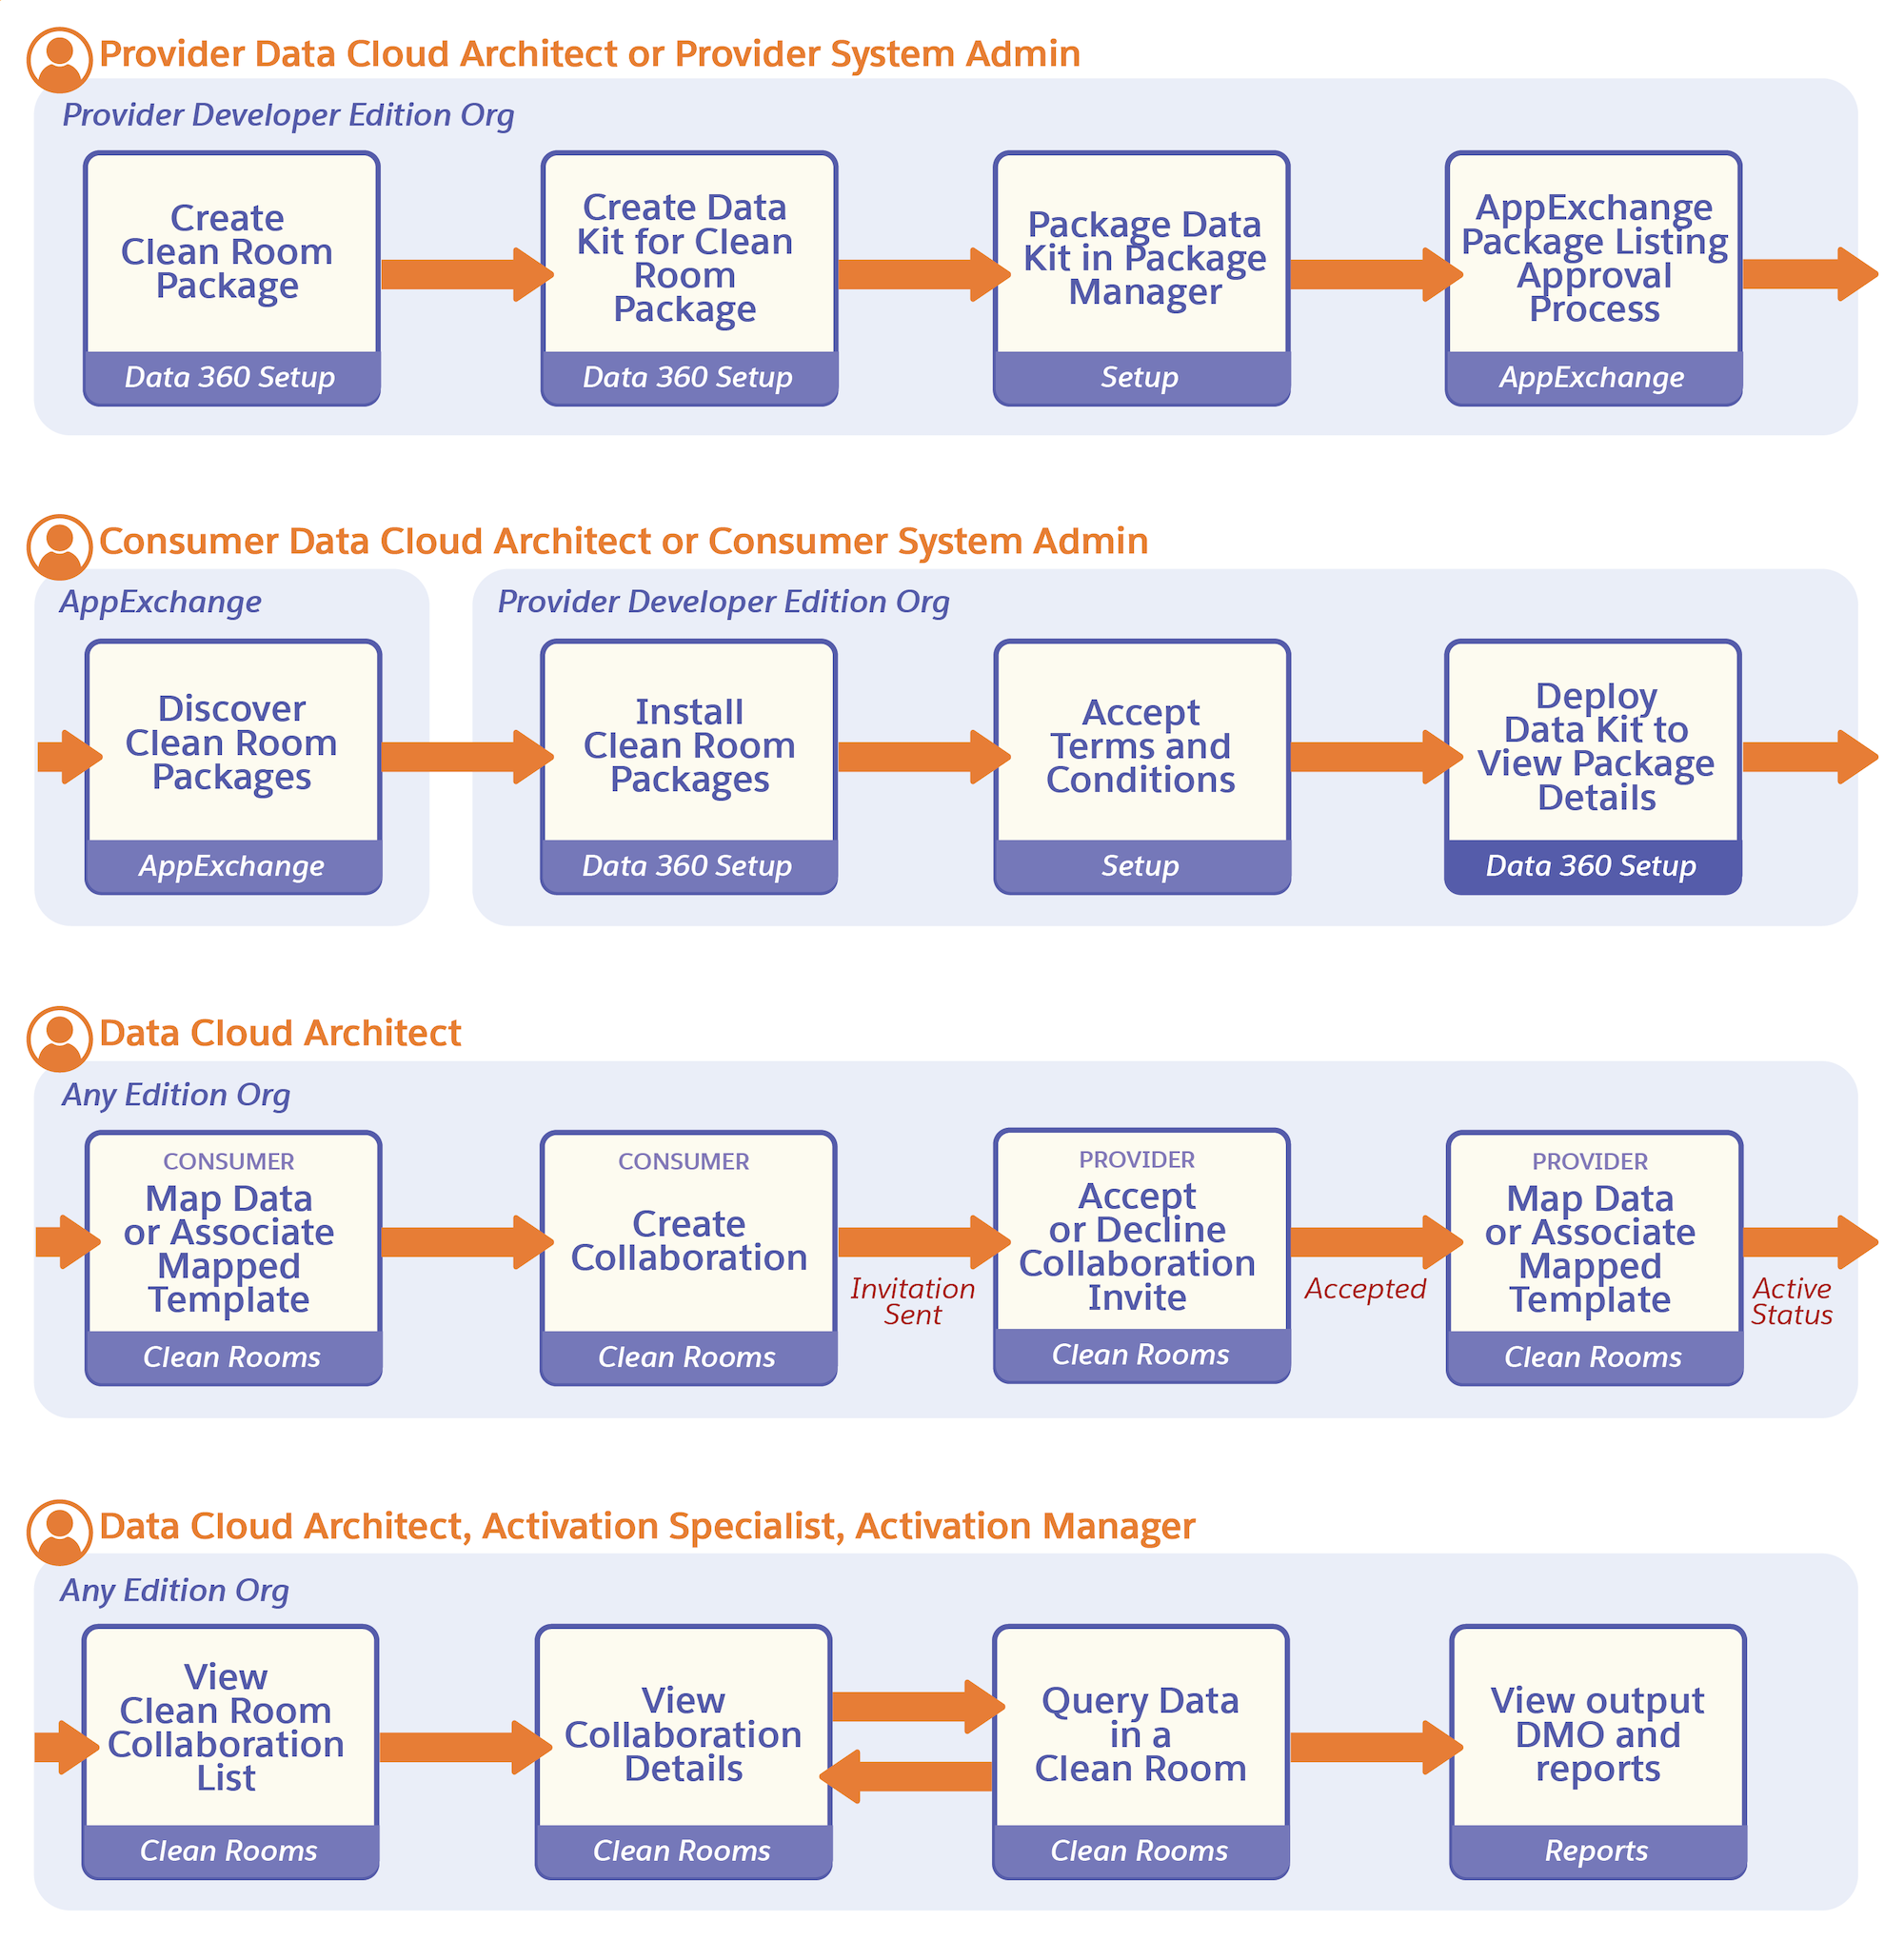

Note Create and publish clean room packages in a Developer Edition packaging org. Deploy packages, create collaborations, accept invitations, and run queries in an Enterprise Edition home org. You can’t receive or accept collaboration invitations in Developer Edition.
- Here's how to configure clean rooms in Data Cloud Setup:
- Provider: In a Developer Edition packaging org, create a clean room package. The package can contain a custom or Salesforce-provided collaboration template. A custom template can support multiple use cases.
- Provider: Publish the clean room package on AppExchange.
- Consumer: In an Enterprise Edition home org, deploy the package from AppExchange. If the provider is a trusted partner, you can also allowlist the provider to access supported use cases without deploying a package.
- Here's how to use clean rooms in the Clean Room tab in Data 360:
- Consumer and provider: In each party’s Enterprise Edition home org, create mappings between the attributes required for the use case and the corresponding attributes in each party’s dataset. Create mapped templates in advance, or map data while creating the collaboration or accepting the invitation. Both parties complete required mappings before the collaboration becomes active.
- Consumer: In an Enterprise Edition home org, create a collaboration for a specific use case, then save it. When you save the collaboration, the provider automatically receives an invitation.
- Provider: In an Enterprise Edition home org, accept the collaboration invitation. After you accept, the collaboration status changes to Active.
- Provider or consumer: Run queries on the combined dataset according to the roles and permissions defined for the use case in the collaboration template. Collaboration results are stored in a DMO or processed as defined in the collaboration template. Permitted parties can view the results and create reports from them.
## Use Case Variations
Three use cases diverge from the standard clean room flow in specific ways.
- **Clean room activation:** When the provider accepts the invitation, they set up an AWS IAM role and trust policy, and configure the S3 bucket path so Data 360 can write results there. Instead of storing query results in a DMO, Data 360 writes the matched audience list directly to the provider's S3 bucket for activation in their demand-side platform. See [Clean Room Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_clean_room_activation.htm&release=264.0.0&type=5 "The clean room activation use case is a privacy-first way to activate first-party data in a provider's advertising platform. Data 360 matches the data in the clean room, then delivers the shared audience list directly to the provider's Amazon S3 bucket. The provider activates it from there, in the demand-side platform (DSP) or media system they already use, without building a new integration.").
- **Identity boost:** Before accepting the invitation, the provider completes required Snowflake setup. On acceptance, Data 360 tests the Snowflake connection automatically. The provider then enriches data in their own Snowflake account, not in a Data 360 org. There's no query step. After the provider runs the enrichment job, the enriched data becomes available to the consumer through the standard Data 360 activation flow, outside the clean room. The consumer shares PII in unhashed form and uses an identity boost package instead of a data collaboration package. See [Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_identity_boost.htm&release=264.0.0&type=5 "Use identity boost to collaborate with identity providers in a clean room and enrich your first-party data with missing contact points. Use the enriched data in your activations to improve match rates.").
- **AWS Clean Rooms provider:** If your provider uses AWS Clean Rooms instead of Data 360, publishing the package is the provider's last action in Data 360. Every subsequent step, including accepting the invitation, happens in AWS Clean Rooms. See [Collaborating with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5 "As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.").
Aside from these differences, all clean room use cases follow the same package-and-collaboration structure: a provider creates and publishes a package, a consumer deploys it and maps data, the provider accepts the invitation, and either party runs queries.
- **[Clean Room Providers](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_providers.htm&release=264.0.0&type=5)**
Providers are publishers or companies that own a platform and can offer access to data or advertising space to other companies. Data 360 Clean Rooms enable providers to collaborate using Salesforce Data 360 clean rooms or AWS Clean Rooms.
- **[Clean Room Consumers](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_consumers.htm&release=264.0.0&type=5)**
Consumers are advertisers seeking insights from providers’ data to find appropriate audiences for their products. To initiate a clean room collaboration, deploy a clean room package from AppExchange, or allowlist a provider. If you allowlist a provider, you don’t need the clean room package to initiate a clean room collaboration. Use the Salesforce-provided collaboration template to initiate the collaboration.
- **[Collaboration with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5)**
As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.
#### See Also
- [_Trailhead_: Data 360 Clean Rooms Quick Look](https://trailhead.salesforce.com/content/learn/modules/data-360-clean-rooms-quick-look)
# Data 360 Connection Details on Companion Orgs
In a companion org, you can identify your home org, check what data spaces are shared with your org, and check the health of your companion org's connection in Setup. Use the Connected Org name and Instance details to identify the Data 360 your org is connected to and the geographical region it's housed at.
### Required Editions
User Permissions Needed
Set up the connection from the home org
Standard System admin profile AND
Data Cloud Architect permission
set
Authorize the connection from the companion org
Standard System admin profile

Note
The connection must be initiated from the home org. When prompted during setup, log in to the companion org by using System Admin credentials.
In Setup, search for Data Cloud Connection and select **Data Cloud Connection**.
The Data Cloud One page in Data Cloud Setup provides information about the status and health of your companion org's connection to Data 360 and your shared data spaces. Use the Connected Org name and Instance details to identify the Data 360 your org is connected to and the geographical region it's housed at.
#### See Also
- [_Salesforce Help_: Data Cloud One Companion Connection Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connection_statuses.htm&type=5&language=en_US)
# Data 360 Cross-Product Solutions
Review various cross-product use cases and solutions for Data 360.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
## Multi-Step Tasks
## Solution Guides
- **[Connect Salesforce Data to Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_data_task_steps.htm&release=264.0.0&type=5)**
Data drives Data 360 functionality. In Data 360, you can connect to many data sources. To get started with standard connections, connect Data 360 to a Salesforce CRM org and install standard data bundles. Then, ingest and further map and refine your data.
- **[Consolidate Customer Service Data for Improved Support](https://help.salesforce.com/s/articleView?id=data.c360_a_service_cloud_guide.htm&release=264.0.0&type=5)**
Data Cloud provides you with a 360 view of your customers by unifying and harmonizing all customer service data in Service Cloud.
- **[Contact Point and Activation Membership Filtering](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_main.htm&release=264.0.0&type=5)**
Personalize marketing communications by having more control on who you’re reaching out to through contact points and the activation membership in Data 360. Use filters to control the volume and variety of data to use in marketing segments.
- **[Create Omnichannel Journeys Using Unified Individual Profiles in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_home.htm&release=264.0.0&type=5)**
Learn how to set up and use audience activations from Data Cloud to power an omnichannel journey in Marketing Cloud Engagement. This guide walks you through an example of how you can enable an omnichannel experience for your customers. Instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.
- **[Implement a Data Foundation in Marketing Cloud Engagement Using Data from Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_guide.htm&release=264.0.0&type=5)**
You can establish a data foundation by activating data from an external system into Marketing Cloud Engagement and linking it to the Engagement Contact Model. You can then refresh and reuse this data across Journey Builder for journey decisioning, wait activities, and exits. You can also use the data for the content personalization of event-triggered campaigns. This solution kit offers a general blueprint on how to set up a data foundation using Data 360.
- **[Ingest Google Analytics into Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_ingest_google_analytics_data_into_datacloud.htm&release=264.0.0&type=5)**
To gain insight into your customer interactions, connect Sales or Service Cloud and Google Analytics data in Salesforce Data Cloud. Enrich your customer information with web engagement data to better segment key audiences and personalize customer interactions.
- **[Ingest Lead Ad Data into Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_sp_leads.htm&release=264.0.0&type=5)**
Set up the Lead Capture app to pull leads from Meta (formerly known as Facebook) into Sales Cloud, connect Sales Cloud to Data Cloud, and receive leads into a data lake object (DLO). Having lead information in Data Cloud can help with event orchestration, activation to ad networks, and lead scoring.
- **[Activate Marketing Cloud Data Extensions to Paid Media Channels](https://help.salesforce.com/s/articleView?id=data.c360_a_mce_migration.htm&release=264.0.0&type=5)**
Use existing data extensions from Marketing Cloud Engagement (MCE) and Journey Builder to create paid media advertising campaigns on Data 360. Migrate your first-party data into Data 360 to enhance your paid media strategy.
- **[Welcome New Loyalty Members to Your Program](https://help.salesforce.com/s/articleView?id=data.c360_a_loy_mgmt_home.htm&release=264.0.0&type=5)**
Send personalized messages to new loyalty members to educate them on program benefits.
- **[Unify Leads for Targeted Selling](https://help.salesforce.com/s/articleView?id=data.c360_a_sales_unify.htm&release=264.0.0&type=5)**
Improve sales experiences by unifying data with Data Cloud. Use that data to unlock insights to enhance Sales Cloud. Combine your Sales Cloud data to identify opportunities with priority customers to sell products and services.
- **[Related Attributes in Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_related_attributes.htm&release=264.0.0&type=5)**
Personalize Marketing Cloud Engagement communications using direct and related attributes from Data 360. Control the volume and variety of data that can be used in marketing segments.
# Data 360 Editions and Licenses
Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.
## Supported Editions
Data 360 is available in these [Salesforce editions](https://help.salesforce.com/s/articleView?id=xcloud.overview_edition.htm&type=5&language=en_US).
- Developer Edition
- Enterprise Edition
- Performance Edition
- Unlimited Edition
Data 360 is also available in Government Cloud. Learn more in [Data 360 in Government Cloud](https://help.salesforce.com/s/articleView?id=ind.government_cloud_data_cloud.htm&type=5&language=en_US).
## User Interface
Data 360 is only available in Lightning Experience.
## Data 360 Licenses
Enable Data 360 on a production Salesforce org with one of these licenses.
Contact your account executive to request information about these licenses or add them using the [Your Account](https://help.salesforce.com/s/articleView?id=xcloud.users_checkout.htm&type=5&language=en_US) app.
| Feature License | Description | Available in Your Account App |
| --- | --- | --- |
| Data Cloud Provisioning | This license turns on Data 360 and includes a base number of credits, storage allocation, and one default data space. Select add-on licenses to turn on additional features, add data spaces, increase your storage allocation, and more. Orgs with this license can be Data 360 Home orgs, but can't be used as Data 360 Companion orgs. | Yes |
| Data Cloud One Companion Org | Designate an org to be used as a companion org and allow it to be connected to a Data 360 Home org via a Data Cloud One Companion Connection. This license can't be added to an org on which Data 360 is provisioned. | Yes |
| Customer Data Platform | This license turns on Data 360, however it is no longer available for purchase and can't be renewed. | No |
## Add-On Licenses for Production Orgs
Some features require these add-on licenses.
Contact your account executive to request information about these licenses or add them using the [Your Account](https://help.salesforce.com/s/articleView?id=xcloud.users_checkout.htm&type=5&language=en_US) app.
Feature License
Description
Available in Your Account App
Ad Audiences
Create segments in Data 360 that you can activate to
advertising platforms like Meta.
Yes
Data 360 Profiles
Change how your Data 360 org is billed. Some features have
limits but don’t consume credits. This license can’t be combined with Data 360
Enterprise Profiles. See Data 360 Profiles License Billing and Limits for details.
No
Data 360 Enterprise Profiles
Change how your Data 360 org is billed. Some features have
limits but don’t consume credits. Includes higher limits than the Data 360 Profiles
license. This license can’t be combined with Data 360 Profiles. See Data 360 Profiles License Billing and Limits for details.
No
Data Cloud One Additional Connection
Increase the maximum allowance of Data Cloud One Companion Connections by one. Add this
license only on Data 360 Home Orgs.
Yes
Data Masking
Protect Data 360 data in real time with dynamic masking and
AI-assisted data tagging for structured data.
No
Data Spaces
Organize your data by adding an additional data space to your account.
No
Platform Encryption for Data Cloud
Encrypt Data 360 with customer-managed root keys.
Yes
Private Connect for Data Cloud
Increase data security with private connectivity between Data 360 and external services.
Yes
Segmentation and Activation
Create segments and batch activations in Data 360 .
As of
September 4, 2025, this license is no longer needed to access segmentation and
activation features. This license is no longer available for purchase.
No
Storage Beyond Allocation
Use additional storage beyond your allocated amount.
Yes
Sub-Second Real-Time Profile & Entities
Create real-time data graphs and use related real-time processes such as
real-time identity resolution, real-time insights, and real-time segments.
No
## Add-On Licenses for Sandbox Orgs (Deprecated)
As of June 17, 2025, these licenses are no longer needed to turn on Data 360 in sandbox orgs.
| Feature License | Description | Available in Your Account App |
| --- | --- | --- |
| Data Cloud Sandbox - Data Services Card | This license is no longer available for purchase. | No |
| Data Cloud Sandbox - Data Storage | This license is no longer available for purchase. | No |
| Data Cloud Sandbox - Real-Time Profile & Entities | This license is no longer available for purchase. | No |
| Data Cloud Sandbox - Segmentation & Activation | This license is no longer available for purchase. | No |
# Data 360 Features and Learning Path
Organize and unify data across Salesforce and other external data sources. After data has been ingested or connected to Data 360, use that data to drive personalization and engagement through the creation of audience segments. Also with identity resolution you can achieve a single, actionable view of your customer built on the world’s #1 customer platform.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
With Data 360 you can:
- Connect any type of data,unstructured or structured, via ingestion or zero copy.
- Create unified profiles across all touchpoints by connecting identities, engagement data, customer orders, loyalty, and marketing journeys.
- Use unified data for improved search capabilities.
- Build smarter audience segments by using insights and filtering.
- Activate data from anywhere across your organization.
- Analyze your data with tools like Tableau, Tableau Next, or Marketing Cloud Intelligence.
## Get Started with Data 360
New to Data 360? Start here.
## Govern and Secure
Ensure consistent, governed data access at scale with tagging, classifications, and policy-based governance. Set up data spaces, configure security features, and understand ethical data best practices.
## Connect and Unify
Once you have the basic implementation, it’s time to start connecting your data to Data 360.
## Process and Enrich
Prepare your data for search and AI use cases with intelligent processing methods.
## Explore and Optimize
Explore your data with clicks, natural language, or SQL. Optimize your data for fast, efficient look ups by creating data graphs and secondary indexes.
## Segment and Act
Segment your data and then act on that data both in and out of Data 360.
## Analyze and Predict
Generate metrics and reports based on your data, ask questions about it, and build AI and semantic models.
## Build and Share
Set up a Data 360 sandbox to test functionality and then extend the use of Data 360 by creating and installing data kits.
# Data 360 Features on Companion Orgs
Use the Data Cloud One app on a companion org to access Data 360 features shared from a Data 360 home org. Full Access means that users with the appropriate permission set can create, update, and delete configurations for the feature on the org they’re logged into.
## Data 360 Features
What you can do depends on which org owns the object/record. An object/record owned by the home org is view-only in a companion org. For how ownership is assigned, see [Metadata Ownership in Connected Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_metadata_ownership.htm&type=5&language=en_US). These Data 360 features are available in Data Cloud One.
| Data 360 Feature | Home Org | Companion Org | Companion Org Notes |
| --- | --- | --- | --- |
| Activations | Full Access | Full Access | |
| Activation Targets | Full Access | View Only | |
| Batch Calculated Insights | Full Access | Full Access | |
| Real-Time Calculated Insights | Full Access | View Only | |
| Data Actions | Full Access | Full Access | |
| Data Action Targets | Full Access | Full Access | |
| Data Explorer | View Only | View Only | |
| Data Graphs | Full Access | View Only | |
| Data Models | Full Access | View Only | |
| Data Streams | Full Access | No Access | |
| Profile Explorer | View Only | View Only | |
| Query Editor | Full Access | Full Access | |
| Retrievers | Full Access | Full Access | When you create a retriever in a Data 360 home org, you can use it in the companion org in Prompt Builder and Flow. See [Retriever Support in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_data_cloud_one.htm&type=5&language=en_US) |
| Search Index | Full Access | Limited Access | Home org search indexes are synced to the companion org but can't be accessed in the Data Cloud One app. |
| Segments | Full Access | Full Access | You can create, update, and delete segments on a companion org. However, segment preview, [approximate count,](https://help.salesforce.com/s/articleView?id=data.c360_a_approximate_segment_population.htm&language=en_US) [vector search](https://help.salesforce.com/s/articleView?id=data.c360_a_add_vector_filters_segmentation.htm&language=en_US), the new attribute library navigation, [Einstein segment creation](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_create.htm&language=en_US), and segment member validation aren’t supported in companion orgs. This applies to all segments, including those created in the companion org and those synced from the home org. |
| Semantic Layer | Full Access | Full Access | If the Sematic model contains data lake objects, Full Access isn't available. |
| Einstein Studio Models | Full Access | View Only | |

Note Data lake objects are accessible via the Data Cloud REST API from a companion org.
## Platform Features
These are some of the Data 360-powered features that are available in home and companion orgs. For questions on other Platform features, contact Salesforce Customer Support.
Platform Feature
Home Org
Companion Org
Activation-Triggered Flows
Full Access
Full Access
Data Cloud-Triggered Flows
Full Access
Full Access
Related Lists Enrichment
Full Access
Full Access
Copy Field Enrichment
Full Access
Full Access
Data 360 Reporting
Full Access
Full Access
Tableau Cloud
Full Access
Full Access
Tableau Next
Full Access
Full Access
For more information,
see Tableau Next Features on Companion Orgs
CRM Analytics
Full Access
Full Access
Custom Lightning / Flexi Pages
Full Access
Full Access
Salesforce Object Query Language (SOQL) / Query / Describe
Full Access
Full Access
Connect APIs
Full Access
Full Access
Prompt Builder
Full Access
Full Access
Static APEX
Full Access
Not Available
Dynamic APEX
Full Access
Full Access
# Data 360 Glossary of Terms
Learn the definition of terms associated with Data 360.
[A](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [B](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [C](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [D](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [E](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [F](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [G](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [H](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [I](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [J](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [K](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [L](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [M](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [N](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [O](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [P](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [Q](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [R](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [S](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [T](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [U](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [W](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) | [Z](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5) |
This glossary defines terms that appear throughout the Data 360 user interface and documentation.
## A
Activation
The process that publishes a segment to activation platforms (targets).
Activation Membership
The grouping of fields from different data model objects (DMOs) to include in an activation.
Activation Target
The location, including authentication and authorization information, where a segment’s data is being sent to during activation, for example, Marketing Cloud Engagement.
Allowlist
A list of email addresses, IP addresses, or domains that are permitted access to a resource. For example, an allowlist controls the IP addresses that can access a Data 360 instance.
Anonymous Data
The data that isn’t associated with a specific person or account, such as mobile ad ID, first-party cookies, and hashed email addresses. Sometimes referred to as unknown data. Profiles in Data 360 can be anonymous or known.
Amazon S3 (Amazon Simple Storage Service)
A service offered by Amazon Web Services (AWS) that provides object storage through a web service interface. Also referred to as Cloud Storage or Cloud File Storage.
API Access
The ability to allow calls to or from your instance of Data 360 outside of the user interface.
API Calls
Specific operations that client applications can invoke at run time to perform certain tasks. For example, query data, obtain metadata, run utilities, trigger events, and pull or push data to a data center.
API Name
The specific, unique name that identifies a Data 360 object, field, segment, or insight within an API call.
Attribute Library Metadata (ALM)
The model of every relationship between objects in your Data 360 data graph. Attribute library metadata determines the paths between objects available for segmentation and activation.
Attributes
The information or data found in data model objects (DMOs). For segmentation, Data 360 offers two types of attributes: Direct (1:1) and Related (1:N). This evaluation originates from the object that was selected for Segment On.
- **Direct attributes (1:1)**: Attributes that have only one value for a record in the Segment On object. For example, if Individual DMO is selected as Segment On, then Individual.First Name or Individual.Gender attributes are listed as direct attributes. Additionally, all attributes from other DMOs that are related to Individual with a relationship cardinality of 1:1 are direct attributes.
- **Related attributes (1:N)**: Attributes that have one or more values for a record in the Segment On object. For example, if Individual DMO is selected as Segment On, then Contact Point Email.Is Active or Sales Order.Grand Total Amount attributes are listed as related attributes.
Audience
A marketing term that refers to the collection of individuals (and their data) that can be used for various purposes within an activation target, like Marketing Cloud Engagement. Similar to a segment.
## B
Base Data Type
The underlying, fundamental data format that represents how data is physically stored and processed. Common base data types include Boolean, Currency, Date, Number, and Text/String.
Business Data Type
A semantic layer that describes how data should be interpreted and processed for a specific business purpose. While the underlying storage format is the same, the business data type enables more specialized handling. For example, Email, Phone, and URL are all stored as Text at the base level.
Business to Business (B2B)
Businesses that market to other businesses.
Business to Consumer (B2C)
Businesses that market to consumers or customers.
Blocklist
A list of email addresses, IP addresses, or domains that are denied access to a resource.
Business Unit
A hierarchical administrative structure within Marketing Cloud Engagement that allows control over the access to, and the sharing of, information by defined user roles. Associated terms:
- **Parent Business Unit (EID)**: A Marketing Cloud Engagement account identified by a unique identifier called an EID.
- **Child Business Unit (MID)**: Business units in the same Marketing Cloud Engagement account. A MID is a unique identifier of a business unit.
## C
Calculated Insight (CI)
A tool in Data 360 that queries, transforms, and creates complex calculations based on stored data.
Calculated Insight Object (CIO)
A data model object created after a calculated insight is processed. CIOs can be viewed in Data Explorer.
Category
A data type grouping that is selected when importing data into Data 360. Categories can’t be edited after ingestion. Available categories include:
- **Profile**: Consumer, business, account, or employee data.
- **Engagement**: Time-based data.
- **Other**: Data that doesn’t fit into either profile or engagement, for example, product data.
Chunk Data Model Object
A data model object that stores chunked fields.
Chunking
The process of breaking unstructured data into manageable, semantically meaningful chunks that can then be turned into vector embeddings. Chunking strategies vary depending on the context of the content being chunked.
Citations
Citations link AI-generated responses to the grounding sources that the LLM used to generate the response. Use citations to verify the validity of the source data and identify potential inaccuracies or hallucinations in the generated responses.
Clean Rooms
Secure, privacy-focused environments designed for data collaboration. They enable multiple legal data owners to securely join and analyze their collective datasets using privacy-enhancing technologies, such as private joins, without sharing the underlying raw data.
Code Extensions
A capability that enables developers to extend Data 360 functionality through custom code development. For example, you can use code extension to create custom batch transforms. This enables organizations to implement tailored data-processing workflows to meet specific business requirements.
Communication Capping
A set of configurable thresholds, frequencies, and rules that limit how often a customer, lead, or prospect can be contacted over a given period, to support compliance and prevent message fatigue.
Composite Key
A primary key made up of multiple fields from your source data. Composite keys are generated by adding a formula during data ingestion.
Connect REST API
A Salesforce REST API that provides programmatic access to Data 360 operations such as querying customer data, activating audiences, and managing data pipelines.
Consent Management
The process of capturing and managing consumer consent, including data accessibility, data usage, and deletion.
Contact Point
A field or set of fields that represent data points that can be used to contact or engage an individual, for example, email or phone.
Conversion API (CAPI)
An integration method that sends online and offline conversion events directly from your business data to advertising platforms in near real time, rather than collecting them from a customer’s web browser.
Cookie
A small amount of data generated by a website and saved by a web browser. Its purpose is to remember information about the website viewer, similar to a preference file created by a software application. While cookies serve many functions, their most common purpose is to store login information for a specific site.
CRM Analytics
A data analysis and visualization service for Salesforce CRM that provides users with actionable insights and AI-driven analytics right in their workflow.
Customer 360 Data Model
The standard, canonical data model used for Data 360 to help with interoperability across systems. The model defines the standard subject areas, objects, fields, metadata, and relationships to ensure consistency across applications and business processes.
Customer Data Platform (CDP)
A platform or software that stores and manages data across systems to create a unified customer database.
Customer Relationship Management (CRM)
A technology for managing all of a company’s relationships and interactions with customers and potential customers.
## D
Data 360
A product used to organize and unify data across Salesforce and other external data sources. After data has been ingested or connected into Data 360, it can be used across Salesforce applications and beyond. Previous product branding includes: Data Cloud, Customer Data Platform, Customer Data Cloud, Salesforce CDP, and Customer 360 Audiences.
Data Cloud Architect
A standard Data 360 permission set that includes permissions to the Data 360 Setup page where administrators configure data sources and create data kits.
Data 360 Enrichment
An enrichment queries or copies the data stored in Data 360 into an org. The two types of enrichments include copy fields and related lists.
Data Action
A process that triggers an action based on data received from a streaming insight. Data actions require data action targets.
Data Action Target
A record that stores authentication and authorization information for a given platform. Supported targets include webhooks and Salesforce CRM.
Data Architecture
A structure for organizing (or the standards that govern) how data is collected, arranged, integrated, and used in data systems.
Data Bundle
A collection of data streams that are automatically mapped to data model objects (DMO), for example, a Salesforce CRM bundle. Also called a starter data bundle in reference to Marketing Cloud Engagement.
Data Capture
The methodology by which an enterprise captures data from various systems, whether that is through pixel-based tagging, manual upload, or API.
Data Collection
The ability to acquire data from many different systems and sources.
Data Connector
A specialized data stream that communicates with external sources to transmit data into Data 360.
Data Explorer
A tool in Data 360 that allows users to view data from a data model object (DMO), data lake object (DLO), or in a calculated insights object (CIO).
Data Extension (DE)
A table in a source system that stores structured data with defined attributes and data types, importable into Data 360 through the Engagement connector. A data extension shared across multiple business units is a Shared Data Extension.
Data Federation
The process of querying data across multiple external sources without physically moving or duplicating the source data. Data 360 supports two data federation methods: Query Federation and File Federation.
Query Federation
A data federation method where Data 360 sends queries to an external source at run time and retrieves results directly, without caching or storing source data locally. Data 360 supports two types of query federation: the default method, also known as live query federation, and accelerated query federation.
Accelerated Query Federation
A data federation method in which Data 360 maintains a periodically refreshed local cache of external data and runs queries against that cache rather than the live source system.
File Federation
A data federation method where Data 360 reads data files in external storage systems through virtual tables, without ingesting and storing the source data in Data 360.
Data Governance
The initiative a company takes to create and enforce a set of rules and policies regarding its data. These policies cover issues such as: Assigning accountability to employees responsible for data assets; granting or restricting access to data, as needed.
Data Graph
A grouping of data created by combining and transforming normalized table data from data model objects (DMOs) into new, materialized views. You can make fewer calls, and queries respond in near real-time, because the data is precalculated.
Data Kit
A portable and customized bundle of packageable metadata, created within Data 360 to streamline the package creation and installation process. Data 360 objects, such as metadata, relationships, and other components, can be wrapped together with a few easy clicks.
Data Lake
A repository of all types of enterprise data, including raw copies of source system data and transformed data used for tasks such as reporting, visualization, analytics, and machine learning.
Data Lake Object (DLO)
Storage containers within the data lake for the data ingested into all data streams within Data 360.
Data Lakehouse
A data architecture that combines the storage scale and schema flexibility of a data lake with the query performance and management capabilities of a data warehouse.
Data Lens
A visual interface embedded in Data 360 features that queries and charts data without creating a static report.
Data Lineage
A traceable record of how data flows between objects across the Salesforce platform, showing each object's upstream sources and downstream dependencies.
Data Mapping
The process of associating (mapping) data lake objects (DLOs) to data model objects (DMOs) after data has been ingested into Data 360. Only mapped fields and objects with relationships can be used for segmentation and activation.
Data Model
A way to organize and standardize data elements, and to add and edit data relationships. Data model is also a tab within Data 360 where a user can create custom data model objects and view existing data model objects.
Data Model Objects (DMOs)
A grouping of data (made up of attributes) created from data streams, insights, and other sources. DMOs can be standard or can be custom, based on business need. Common standard DMOs include sales orders, account, party identification, email engagement, and so on. DMOs can be:
- **Virtual**: A view into a data lake object.
- **Physical**: An actual grouping of data found in Data 360.
Data Share
A collection of data lake objects (DLOs), data model objects (DMOs), and calculated insight objects (CIOs) that lets you make queries without moving any data out of Data 360.
Data Source
Any system with which you can exchange data.
Data Space
A data space is a logical partition to organize your data for profile unification, insights, and marketing in Data 360.
Data Stream
A data source brought into Data 360. For example, a Marketing Cloud Engagement customer data extension. These data streams can be based on batched data or streaming data streams.
Data Transform
A feature that combines, shapes, cleans, and preps your data directly in Data 360.
Data Type
The type and format of source data ingested, specifically text, number, and datetime.
Database
An organized collection of structured information (data) typically stored in a computer system. A persistent database stores data for a long time, for example storing customer purchase data for several years.
Device ID
The unique identifier used for electronic devices. DMPs and customer data platforms can use these identifiers to relate devices (TVs, connected devices, smartwatches, and others) to a "person-based" ID.
Dimension
A qualitative value used to categorize a measure. For example, if you want to see every customer’s total amount spent, the customer ID could be a dimension associated with the measure of the total amount spent.
Document AI
A document-processing service that applies large language models to extract structured field values from unstructured documents such as invoices, resumes, and purchase orders.
Dynamic Filter
With a dynamic filter, the prompt template specifies the filter value at run time. In Prompt Builder, when you configure a retriever in a prompt template, a dynamic filter in the retriever is mapped to a prompt input that gets resolved at run time.
Dynamic Retriever
A dynamic retriever defines a placeholder variable for a value that’s specified in a prompt template at run time.
## E
Endpoint
Any final system where customer data is sent to, which is usually where that data is used for targeting. Common endpoints include Facebook and other social media platforms, Marketing Cloud Engagement, Demand Side Platforms, and so on.
Ensemble Retriever
A collection of individual retrievers. When you run an ensemble retriever, it executes the individual retrievers, combines their results into a single list, reranks the list according to relevance to the search request, and returns the most relevant information to the prompt template or agent.
Entity Relationship Diagram (ERD)
A visual representation of data model objects in Data 360 and their relationships, used to plan data mappings and understand data structure.
Expression
A combination of clauses, operators, variables, and values. You use a SOQL expression to query the Salesforce data model.
Extensibility
An engineering and system design principle that allows for future growth by allowing for the easy development and sharing of key capabilities and functionality.
External Activation Target
An activation target that publishes segments to an external activation platform account, including platforms installed from AppExchange, and Google Ads, Meta, or Amazon Ads platforms.
External Activation Platform
A third-party platform, such as Google Ads, Meta, Amazon Ads, or an AppExchange partner platform, that receives published segments from Data 360. You need an external activation target to connect Data 360 to an external activation platform.
External Data Lake Object (DLO)
A storage container with metadata for the data federated from an external data source. An external DLO acts as a reference, pointing to the data physically stored in an external data source.
External Key Management (EKM)
An encryption option that lets customers manage their root keys externally through an AWS key management service (KMS) account, keeping encryption keys outside the Salesforce platform.
## F
Field
A storage container for data. Used interchangeably with attribute. Associated terms that are used for field metadata include:
- Field API name
- Field description
- Field type
- Field properties
First-Party Data
Data that your company has collected directly from your audience, for example, a customer providing birthday or Social media followers who entered a contest with your company.
Foreign Key
A field in a table that refers to the primary key of another table. The foreign key links these two data tables together based on a data point, for example, a customer ID.
Fully Qualified Key
A fully qualified key (FQK) is a composite key that contains a source key and a key qualifier. Use FQKs to avoid key conflicts when data from different sources is harmonized in the Data 360 data model.
See also the definition for **Key Qualifier Fields**.
## G
Google Cloud Storage
A RESTful online file storage web service for storing and accessing data on the Google Cloud Platform infrastructure.
## H
Harmonization
The process of mapping ingested data into the Customer 360 Data Model.
Hashed Email (HEM)
A type of anonymous email that includes a unique key to anonymize email via a "SHA" or secure hash algorithm. There are various types of SHAs used for this purpose, including SHA-1 and SHA-256.
Hashed Phone
A type of anonymous phone number that includes a unique key to anonymize via an "SHA" or secure hash algorithm.
Hybrid Search
The process in which the results from a keyword search and vector search are merged and ranked to generate the most relevant response. Hybrid search generates two result sets, one based on keyword matching and the other based on semantic similarity. A hybrid search fusion ranker model then reranks these results into a single ranking to be used in Retrieval Augmented Generation (RAG).
Hybrid Search Autodrop
Hybrid search autodrop dynamically filters out results that show a sharp decrease in relevance scores for a search query. This increases the precision of search results for your prompts and RAG use cases.
Hybrid Search Fusion Ranker
A fusion ranking model that reranks the merged results retrieved from Data 360 hybrid search to surface the most relevant results for a search query.
## I
Identity Resolution
The process of identity management by matching and reconciling data about people into a comprehensive view called unified profiles. Identity resolution is powered by rulesets and creates unified and link objects.
Identity Resolution Rulesets
Rulesets are a combination of match and reconciliation rules used to combine source records to resolve identity and create unified profiles.
Ingestion
The process of importing data from multiple sources into Data 360.
Insights Builder
A tool that allows users to create insights with limited knowledge of SQL.
Installed Package
A managed or unmanaged package that has been uploaded into an org from another org or from AppExchange. A package is a collection of components and applications that are made available to other organizations through AppExchange or in another instance of Salesforce.
Instance
The cluster of software and hardware represented as a single logical server that hosts an organization's data and runs its applications.
Intelligent Context
A prompt-driven workspace that processes unstructured data and produces search index configurations tailored to a specific business context.
Interoperability
The ability of systems to easily connect and communicate with one another.
## J
Java Database Connectivity (JDBC)
An application programming interface for the programming language Java, which defines how a client accesses a database.
JavaScript Object Notation (JSON)
JSON is a lightweight format for transferring data.
Journey Builder
A Marketing Cloud Engagement feature that helps marketers create, send, track, and optimize the effectiveness of cross-channel customer journey campaigns.
## K
Key Qualifier Fields
Key qualifier fields are schema fields that are automatically added to DLOs and DMOs by Data 360. Key qualifier fields contain key qualifiers. Key qualifiers are values configured for key qualifier fields to identify the data source. Create and configure key qualifiers for each DLO field that contains either a primary key or a foreign key.
See also the definition for **Fully Qualified Key**.
Known Data
Data that most companies have about their customers such as postal addresses, mobile numbers, or email addresses. Often related to profiles.
## L
Label
A user-created name that identifies an object, field, or attribute.
## M
Managed Package
A collection of application templates that you can bundle and distribute on AppExchange. Salesforce partners use managed packages to sell and deliver Data 360 applications to customers.
Marketing Cloud Intelligence
An AI-powered marketing intelligence engine formerly known as Datorama. Helps customers make smarter decisions by connecting and acting on all of their marketing data, investments, and KPIs. Acquired by Salesforce in 2018, part of the Marketing Cloud.
Marketing Cloud Personalization
A personalization and interaction management tool used to create relevant customer experiences. Formerly known as Interaction Studio and Evergage.
Match Rules
A set of rules used to link multiple records into a unified individual within identity resolution rulesets.
Measure
An aggregated value of attributes, like a customer’s total amount spent or an average order amount.
Metadata
Data that describes other data. Data 360 metadata relates to the fields, configurations, and code that make up your environment. Metadata can be imported into other instances of Salesforce, modified in the product interface, or edited via the Salesforce Metadata API.
Mobile Advertising Identifier (MAID)
A unique ID provisioned by mobile platforms such as Apple and Google's Android to assign a specific device ID to each device. Often used in external activation platforms, referring to a specific data field.
Mobile App
An application on iOS or Android.
MuleSoft
Software for easily connecting disparate software applications within an enterprise so that they can share data and provide a unified view of the customer. Part of the Salesforce organization since 2018.
## N
Next Best Action
A customer-focused marketing paradigm that considers the different actions that can be taken for a specific customer and then decides on the ‘best’ one. This next action could be an offer based on both the customer’s interests and the marketing organization’s business objectives.
Next Best Offer
A customized offer that delivers the merchandise, services, or information the customer wants, at the right time, at the right price, and by their preferred communication channel.
Node
A UI option found in Insights Builder after Selecting Objects.
Notebook AI
A generative AI workspace that combines your business documents with enterprise data to research, summarize, and surface insights.
## O
Objects
A general term that references data found in a database. Within Data 360, used in relation to data model objects.
Object Manager
An admin tool for creating custom objects, using the schema builder, and viewing all objects stored in Data 360.
Org (Organization)
A deployment of Salesforce with a defined set of licensed users including a collection of data and metadata tied to a specific customer. It’s accessible by a defined set of Salesforce users. Each org is considered its own deployment of Salesforce.
## P
Package Manager
A tool in Salesforce Setup that packages components. See also installed package.
Party
A term that can refer to a subject area or a field in Data 360. Party reflects a unique identifier, like a driver’s license number or a contact ID in Salesforce.
Permission
A setting that grants a user access to a specific tool, function, or area in Salesforce.
Permission Set
A collection of permissions and settings that gives users access to specific tools and functions.
Population Count
The number of records or contacts identified in a segment within Data 360.
Point-of-Sale (POS)
A system that manages transaction data at the point of purchase, such as a retail store or grocery.
Primary Key
An object’s unique identifier of a record, such as a customer email address or a product SKU. The relationship is made by matching the values of the foreign key in one table with the values of the primary key in another.
Private Connect
A networking capability that establishes secure, dedicated connectivity between Data 360 and supported external systems for data federation and related data access operations.
Process Definitions
Within data governance, process definitions refer to standardized workflows that manage data operations such as data streams, transformations, insights, segments, and identity resolution.
Profile Explorer
A tool within Data 360 in which a user can view Unified Individual profiles.
Push Notifications, Mobile
Push notifications are alerts that apps render on mobile device home screens when users aren’t using the app. These alerts can consist of text, icons, and sounds, depending on the device type.
## Q
Query
A request for data or information from a database table or combination of tables.
Query Editor
A tool to write and execute SQL queries in Data 360. You can build queries on data lake objects, data model objects, calculated insights objects, and data graphs.
## R
Real Time Interaction Management (RTIM)
Enterprise marketing technology that delivers contextually relevant experiences, value, and utility at the appropriate moment in the customer via preferred customer touchpoints. Salesforce offers this functionality in Marketing Cloud Personalization.
Reconciliation Rules
User-defined rules that determine which source the system uses when creating unified individual profiles. Options include: last updated, most frequent, or source priority.
Record Lineage
Metadata that describes where a record originated and how it is represented within Data 360 using lineage fields such as Data Source, Data Source Object, and Internal Organization.
Relational Data
Data whose organization is based on the relational model of data. This model organizes data into one or more tables (or “relations”) of rows and columns, with a unique key for each row.
Relationships
A connection between two objects or sets of data. Relationships include:
- **One-to-one (1:1)**: A link between the information in two tables, where each record in each table only appears one time. For example, a one-to-one relationship between employees and the cars they drive. See direct attributes.
- **One-to-many (1:N)**: A relationship between records in which one record in a table can be associated with one or more records in another table. For example, each customer can have many sales orders. See related attributes.
Related Object
A related object of a Data Model Object (DMO) shares defined cardinality relationships with the DMO. These relationships connect the DMOs in the Data 360 data model, making it easier to reference and organize data across different DMOs.
Retriever
A logical layer between the search service and knowledge retrieval-powered solutions, such as RAG (Retrieval Augmented Generation) implementations. It defines the runtime search and retrieval configuration for an application, agent, prompt templates, and other solution components. A retriever serves as a reusable, versioned, and packageable artifact that simplifies the setup of knowledge retrieval with search-based grounding for agents, Agentforce data libraries, prompt templates, with Apex, or in Flow.
Ruleset
A user-selected combination of match and reconciliation rules used to combine source records to resolve identity and create unified profiles. See identity resolution rulesets.
## S
Salesforce Advertising Studio
A product that helps you engage with your customers and prospects. It includes three applications: Advertising Audience, Journey Builder Advertising, and Lead Capture. You can use Advertising Studio to coordinate campaigns with social, mobile, sales, and customer service efforts.
Salesforce CRM
Within Data 360, Salesforce CRM refers to Sales Cloud and Service Cloud accounts.
Salesforce Data Pipelines
A product that can clean, transform, and enrich large volumes of data at scale.
Search Index Configuration
A process in Data 360 that generates chunks and vector embeddings from unstructured data.
Second-Party Data
Data provided by a partner or as the result of a relationship.
Secondary Index
A data structure built on top of a DLO to speed up data retrieval by creating shortcuts to specific data. It organizes data based on specified fields and allows the database to find records much faster, similar to how a book's index helps you find a topic quickly.
Segment
A set of objects (for example individuals in B2C) that share some set of characteristics. Similar to an audience, you can learn more about their differences in this internal resource. Related to an audience and population count.
Segments
A tab in Data 360 where marketers can create segments to send to activation targets.
Segment On
Within segmentation, segment on defines the target object used to build your segment.
Segmentation
The ability to query data and split it out into groups based on different attributes or characteristics. For example, customer’s who have bought shoes in the last 30 days.
Streaming Insights
Calculations and queries based on near real-time data. Streaming insights can be used to create data actions.
Structure Query Language (SQL)
Pronounced as either "sequel" or "S-Q-L”, SQL is a query language used for accessing and modifying information in a database. Insights are created using SQL in Data 360.
Structure Object Query Language (SOQL)
Similar to the standard Structured Query Language (SQL), SOQL is used to query the Salesforce data model. Data insights are created using SOQL in Data 360. SOQL is pronounced "so-quel" or "S-O-Q-L."
Structured Data
Information with a specific, consistent format that adheres to a schema. This data is organized into predefined tables, rows, and columns, making it easy to store, query, and analyze in a relational database. Common examples include CRM records (accounts, contacts, leads), e-commerce transactions, and other customer profile data.
Subject Area
A term used to group similar DMOs to aid in data modeling. Data 360 subject areas include party, engagement, loyalty, and so on.
## T
Tableau
Acquired by Salesforce in August 2019, Tableau is a powerful, secure, flexible data analytics platform.
Tenant
An organization in our service. Our multi-tenant architecture means that we have multiple orgs residing on the same app servers.
Tenant-Specific Endpoint (TSE)
A unique system-generated subdomain assigned to your tenant.
Third-Party Data
Any information collected by a group that doesn’t have a direct relationship with a user’s data.
## U
Unified Individual
A unified profile object that consolidates individual data, such as first and last name, from multiple sources, created through identity resolution rulesets.
Unified Profile
A profile that contains customer data reconciled across multiple sources as a single record using identity resolution rulesets.
Unmanaged Package
A collection of application templates that you can bundle and distribute as open-source projects. Use unmanaged packages to move Data 360 metadata between orgs or to provide a starting point for developers.
Unstructured Data
Data that doesn’t have a specific, consistent format and can’t be easily stored in a typical relational database. Common forms of unstructured data include chat transcripts, audio files, websites, legal documents, and other large texts, such as books.
Unstructured Data Lake Object (UDLO)
A data model object that references unstructured data stored in files within an external blob store, such as Amazon S3 or Google Cloud Storage.
Unstructured Data Model Object (UDMO)
A grouping of data (composed of attributes) created from unstructured data lake objects. Workloads in Data 360 consume unstructured data through UDMOs.
## V
Vector Data Model Object (VDMO)
A data model object that stores generated vector embeddings.
Vector Embedding
A numerical representation of unstructured data that machines can read. Vector embeddings measure the semantic similarity of different pieces of text, enabling accurate and relevant results in generative AI prompts and searches.
Vector Search
Also known as Semantic Search, involves retrieving semantically similar documents (or document chunks) given a search query. This is done by searching for vector embeddings that are close to the vector belonging to the query.
## W
Webhook
A type of API that allows web applications to communicate with each other based on events instead of requests. A webhook in web development is a method of augmenting or altering the behavior of a web page or web application with custom callbacks. Webhooks can be used as data action targets.
## Z
Zero Copy
A data access method in which Data 360 queries data directly in an external source system without copying it into Data 360 storage. There are various types of zero copy methods.
# Data 360 Governance Mergeback with DevOps Data Kits
Use sandboxes to develop and validate your data governance strategy, and then deploy it to production through mergeback. Mergeback is the process of moving validated metadata from a sandbox org back to a linked production org or another linked sandbox org. DevOps data kits move governance metadata between environments and maintain a consistent security posture.
## Data Kit Types for Governance
Data 360 provides two data kit types.
- DevOps data kits: Used for sandbox-to-production mergeback between linked environments.
- Standard data kits: Used for packaging and deployment across orgs.
## Governance Metadata in Mergeback
Mergeback moves metadata that controls access to your data.
- Tag assignments identify and classify data model objects (DMOs), data lake objects (DLOs), and calculated insight objects (CIOs).
- Governance policies control access to data and protect it.
- Record-level security (RLS) controls access to records. Use DevOps data kits to deploy governance components to the target org.
- Field-level security (FLS) controls access to fields.
- Object-level security (OLS) controls access to objects.
- Structured masking policies protect sensitive data.
## Data Governance Support for Mergeback
Mergeback supports these data governance features.
- Assigning standard tags to Data 360 objects
- Applying governance policies based on standard tags, including:
- RLS policies
- FLS policies
- Object-level structured masking policies
## DevOps Data Kit Deployment Model for Governance
DevOps data kits group governance components and deploy them to the target org.
- Capture relationships between governance policies and Data 360 objects.
- Use built-in deployment mechanisms, including change sets.
- Add data assets such as DMOs or DLOs to a DevOps data kit. Associated governance policies and tag assignments are included automatically.
You can’t add policies or tag assignments to a data kit on their own.

Note For RLS with joins, make sure all referenced objects exist in the target org or deploy them using DevOps data kits before activating the policy.
## Unsupported Governance Capabilities in Mergeback
Mergeback doesn’t support these capabilities.
| Unsupported capability | What to do instead |
| --- | --- |
| Creating custom tags in a sandbox and deploying them to production | Recreate custom tags manually in the target production org before deployment. |
| Assigning custom tags through mergeback | Assign custom tags manually in the target org after deployment. |
| Applying policies based on custom tags | Use standard tags for mergeback-supported governance policies. |
| Applying policies that combine standard and custom tags | Redesign the policy to use only standard tags before deployment. |
| Using custom tags during mergeback, even if they exist in the target org | Reapply or manage custom tag usage directly in the target org. |
| Unstructured data masking policies | Configure unstructured masking policies separately in the target org. |
| RLS hierarchy operator policies | Use supported RLS policy types for mergeback deployments. |
| Deleting governance metadata during mergeback | Manually remove policies or tag assignments from the target org using the Data Governance UI or supported APIs. |
## Governance Mergeback Deployment Considerations
When planning your migration, consider these specific behaviors.
- Supported deployment paths: Mergeback supports deployments only between related Data 360 environments, such as sandbox-to-production or sandbox-to-sandbox.
- Deletion not supported: Removing a policy or tag assignment in a sandbox doesn’t remove it from the target org.
- CLI not supported: Salesforce CLI doesn’t support governance policy deployment.
- System-defined tags: Salesforce provides and maintains the system-defined tag taxonomy. Don’t rename, delete, or reassign these tags because governance policies depend on them. Any modifications are reverted during platform updates.
- Transaction limits: Large deployments may require batching.
- **[Deploy Data 360 Governance Policies with DevOps Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_deploy_policies_devops_datakit.htm&release=264.0.0&type=5)**
Migrate your data governance policies from sandbox to production orgs using DevOps data kits. This approach maintains consistency and reduces manual errors.
- **[Troubleshoot Data 360 Governance Mergeback Deployments](https://help.salesforce.com/s/articleView?id=data.c360_a_troubleshoot_mergeback_deployments.htm&release=264.0.0&type=5)**
When you migrate your data governance metadata, you can sometimes encounter deployment errors. Review the symptoms and solutions for common mergeback issues so that you can successfully complete your deployment across environments.
# Data 360 Governance Permissions
Review the permissions and permission sets required to effectively use data governance features in Data 360.
## User Permissions
These user permissions are added to the permission sets to support data governance features.
Name
Description
Associated Permission Set
View All Data Governance Tags, Classifications, and Taxonomies
View all tags, classifications, and taxonomies in the Data Governance
tab.
Data Cloud Architect
Data Cloud User
Data Cloud Activation Manager
Data Cloud Activation Specialist
Modify All Data Governance Tags
Create, edit, and delete tags in the Data Governance tab.
Modify All Data Governance Classification Tags
Create, edit, and delete classification tags in the Data Governance
tab.
Modify All Data Governance Tag Taxonomies
Create, edit, and delete tag taxonomies in the Data Governance tab.
Modify All Data Governance Classification Taxonomies
Create, edit, and delete classification taxonomies in the Data Governance
tab.
Modify All Data Governance Tag Assignments
Create, edit, and delete tag assignments in the Data Governance tab.
View the Data Governance Tab
View the Data Governance tab.
Enable Data Governance Suggest Tags
Enable tag suggestion in data governance.
View All Data Governance Policies
View all policies in the Data Governance tab.
Modify All Data Governance Policies
Create, edit, and delete policies in the Data Governance tab.
View Setup and Configuration
View permission set licenses.
# Data 360 in a Sandbox
Use a Data 360 sandbox to test data ingestion, modeling, and identity resolution without affecting live customer profiles. A sandbox provides a secure testing environment by copying metadata from your production Data 360 org. Sandbox usage consumes credits from your production org.
## Benefits of a Sandbox Environment
With sandboxes and deployment tools, you can:
- Test changes against copies of your production data and users.
- Provide a training environment.
- Test AppExchange packages or integrations.
- Isolate customization and development work from your production environment until you’re ready to deploy changes.
## Types of Sandboxes
Data 360 supports all sandbox types: Developer, Developer Pro, Partial Copy, and Full Copy. When you provision Data 360 in a sandbox, it contains only metadata. You can't replicate data even in Partial Copy and Full Copy sandboxes.
## Data 360 Sandbox Storage and Limits
Data 360 sandboxes follow production limits and guidelines. They bypass the storage restrictions of Salesforce sandboxes, such as the 200-MB limit for Developer sandboxes.
## Data 360 License and Setup Requirements
To use Data 360 in a sandbox, provision Data Cloud licenses and maintain an active Data 360 tenant in your production org. The sandbox depends on this production setup. To activate Data 360 in the sandbox, first turn on and configure it in production.
## Supported Features
This table lists the Data 360 features available in a Data 360 sandbox and describes their expected behavior.
Data 360 Feature
The specific Data 360 capability or feature.
Functional in Sandbox
The feature operates in the sandbox environment.
Replicated in Sandbox
The sandbox copies the feature's metadata from your production org during creation.
Deployable from Sandbox
You can deploy the feature's configuration changes from the sandbox to your production org.
When you create a sandbox, it excludes some Data 360 features from production replication. However, you can manually recreate these features in the sandbox. For available features, you can create objects directly in your sandbox. These objects remain local to the sandbox environment and bypass deployment back to production.
Data 360 Feature
Functional in Sandbox
Replicated in Sandbox
Deployable from Sandbox
Activation: Amazon S3
Activation: SFTP, Microsoft Azure, GCS
Activation: Marketing Cloud
Activation: Native - Data Cloud
Activation: Commerce Cloud, Loyalty, Marketing Cloud Personalization
Activation: AgentExchange partners (Liveramp, Criteo, Tradedesk)
Activation: API Activation
Activation: Ad Audiences partners (Google Ads, Amazon Ads, Meta, and
LinkedIn)
Activation: Communication capping enabled (Marketing Cloud, SFTP, and
Microsoft Azure)
Activation: Activation Templates
Activation: Batch DMO
Activation: Streaming (Meta CAPI & Linkedin CAPI)
Activation target: Amazon S3
Activation target: SFTP, Microsoft Azure, GCS
Activation target: Marketing Cloud
Activation target: Native - Data 360
Activation target: Commerce Cloud, Loyalty, Marketing Cloud
Personalization
Activation target: AgentExchange partners (Liveramp, Criteo, Tradedesk)
Activation target: Ad Audiences partners (Google Ads, Amazon Ads, Meta, and
LinkedIn)
Activation target: Communication capping enabled (Marketing Cloud, SFTP, and
Microsoft Azure)
Advertising Audiences: Marketing Cloud Advertising
Zero Copy - Databricks
Zero Copy - Google BigQuery
Zero Copy - Redshift
Zero Copy - Snowflake
Calculated insight - builder
Calculated insight - SQL
Calculated insight - streaming
Clean room - packages
Clean room - mapped templates
Clean room - collaborations
Connector - Amazon S3
Connector - Amazon Kinesis
Connector - Azure
Connector - B2C
Connector - CRM
Connector - Google Cloud Storage
Connector - Ingestion API
Connector - Marketing Cloud Account Engagement
Connector - Marketing Cloud Engagement
Connector - Marketing Cloud Personalization
Connector - Mobile SDK
Connector - Snowflake
Connector - Web SDK
Data action - CRM
Data action - Marketing Cloud Engagement
Data action - Webhook
Data action target - Marketing Cloud Engagement
Data action target - Salesforce Platform
Data action target - Webhook
Data 360 reports
Data graph
Data Governance - Tag
Data lake object (DLO)
Data model object (DMO)
Data share
Data share target - Snowflake
Data space - custom
Data space - default
Data transform - batch and streaming
Einstein Studio
Identity resolution
Private Connect for Data Cloud
Salesforce Platform - Data Cloud enrichments - copy fields
Salesforce Platform - Data Cloud enrichments - related lists
Salesforce Platform - Flow
Salesforce Platform - Lightning Web Components
Salesforce Platform - Data Clean Room
Salesforce Platform - Apex
Search Index Configurations
Service Intelligence
Standard Segment - DBT
Standard Segment - Visual Builder
Segment - Real-Time
Segment - Waterfall
Unstructured Data Lake Object (DLO)
Unstructured Data Model Object (DMO)
## Additional Resources
To learn more about this topic, review the associated Trailhead content.
[Data 360 Sandboxes](https://trailhead.salesforce.com/content/learn/modules/data-360-sandboxes?trail_id=data-360-develop-and-build-solutions)

- **[Considerations for Sandbox in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_consideration.htm&release=264.0.0&type=5)**
Refer to these considerations when creating a sandbox and deploying changes from a sandbox in Data 360.
- **[Billing Considerations for Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_billing_considerations.htm&release=264.0.0&type=5)**
Understand how Data 360 sandbox usage consumes flex credits and learn strategies to reduce sandbox costs.
- **[Create a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_create.htm&release=264.0.0&type=5)**
Develop, test, and train on Data 360 without affecting your production org. Data 360 supports all sandbox types—Developer, Developer Pro, Partial Copy, and Full Copy—but provisions only metadata. Even when you create Partial Copy or Full Copy sandboxes, your production data stays protected. No data is replicated to Data 360 sandboxes.
- **[Remove Legacy Metadata from a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_remove_legacy_metadata_in_data360_sandbox.htm&release=264.0.0&type=5)**
Data 360 sandboxes configured before August 2024 may contain legacy metadata. Use the cleanup process to remove legacy metadata from the sandbox.
- **[Deploy Data 360 Changes Across Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_deploy.htm&release=264.0.0&type=5)**
You can make Data 360 changes in a sandbox and then deploy them to a production org or another sandbox org. Additionally, you can deploy changes from one production org to another production by using a sandbox. Use a DevOps data kit and a change set to deploy the changes to a production org.
- **[Replicate Data 360 Configurations Using Local Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_replicate_data360_configurations_using_local_data_kits.htm&release=264.0.0&type=5)**
Move Data 360 metadata and process definitions between data spaces within the same sandbox using the local data kit deployment method. Create a standard data kit in your default data space, and then use a change set to deploy it to other data spaces.
- **[Replicate Data 360 Sandboxes Using Cloning](https://help.salesforce.com/s/articleView?id=data.c360_a_use_cloning_to_replicate_data360_sandboxes.htm&release=264.0.0&type=5)**
Clone an existing parent sandbox to reuse Data 360 metadata and configurations, create testing environments faster, and streamline complex DevOps workflows. When you clone a sandbox with Data 360 provisioned, you automatically carry over the same Data 360 metadata and configurations to the cloned sandbox. This process saves setup time and avoids manual configuration.
- **[Deploy Direct-DMO Customizations to Production with Sandbox Mergeback](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_mergeback.htm&release=264.0.0&type=5)**
Starting in Winter '26, you can package and deploy customizations containing direct data model object (DMO) relationship metadata from sandbox to production environments.
#### See Also
- [_Salesforce Help_: Considerations for Sandbox in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_consideration.htm&release=264.0.0&type=5 "Refer to these considerations when creating a sandbox and deploying changes from a sandbox in Data 360.")
- [_Trailhead_: Data 360 Sandboxes](https://trailhead.salesforce.com/content/learn/modules/data-360-sandboxes?trail_id=data-360-develop-and-build-solutions)
- [_Salesforce Help_: Create a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_create.htm&type=5&language=en_US)
- [_Salesforce Help_: Deploy Data 360 Changes from a Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_deploy.htm&type=5&language=en_US)
- [_Salesforce Help_: Sandboxes: Staging Environments for Customizing and Testing](https://help.salesforce.com/s/articleView?id=platform.deploy_sandboxes_parent.htm&type=5&language=en_US)
# Data 360 Licenses, Billing, and Limits
How you pay for data services provided by Data 360 depends on how your Data 360 org is licensed. Your licenses determine both billing method and limits for your org. We recommend working with your account exec before buying Data 360 or when your contract renews to ensure your license is the best choice based on your usage and growth potential.
All Data 360 licenses are add-ons to a Salesforce org license. Contact your account executive for a list of Salesforce org licenses that Data 360 can be added onto.
All orgs in a Data 360 cluster, including the primary production Home org, sandbox orgs created from it, its Data Cloud One Companion orgs, and their sandboxes, must all use the same type of Data 360 licenses. Data 360 license are managed by the production Home org, which is billed for data processing workloads generated by its sandboxes and companion orgs.
Features powered by Data 360 including Agentforce and Agentforce Employee Agent, are billed for Data 360 services depending on the org’s Data 360 license type.
## Data Cloud License
- **License**: This license is available for purchase and renewal. A variety of add-ons can be used with this license, including real-time profile processing and data governance features. See [Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.").
- **Billing**: Orgs using the Data Cloud license are billed based on consumption of data storage and data services in a variety of usage types. Depending on which credits your org purchases, credits are decremented from either the Data Services or Flex Credits consumption card. See [Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.").
- **Limits**: Data Cloud orgs must adhere to specific limits for some features. See [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.").
## Data 360 Profiles License
- **License**: This license is an add-on to the Data Cloud license. It changes billing and limits for some data services. See [Data 360 Profiles License Billing and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profiles_overview.htm&release=264.0.0&type=5 "Data 360 Profiles and Data 360 Enterprise Profiles licenses can be added on to Data Cloud licenses to change how a Data 360 org is billed and limited. When a Data 360 org has this license, its unified profiles, segments, data transforms, and insights are limited but don't consume credits.").
- **Billing**: Orgs with this add-on license aren’t billed for batch data transforms, identity resolution rulesets, segments, and batch calculated insights. Credits continue to be decremented from the Data Services or Flex Credits card for all other types of usage. See [Data 360 Profiles License Billing Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profile_billing_considerations.htm&release=264.0.0&type=5 "Adding a Data 360 Profile or Data 360 Enterprise Profile license to a Data 360 org changes its consumption billing and adds limits for certain features.").
- **Limits**: Limits for data transforms, unified profiles, segments, and insights are determined by which Data 360 Profile license you purchase. You can purchase higher limits for data transforms, segments, and insights. However, the number of identity resolution rulesets you can create is determined by the base Data 360 Profile license and can’t be increased. See [Data 360 Profiles License Base License Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_d360_profiles.htm&release=264.0.0&type=5 "Limits in this document represent the base limits of a single Data 360 Profiles or Data 360 Enterprise Profiles license. Some limits can be raised by purchasing multiple copies of the license or buying add-on licenses.").
## Customer Data Platform (CDP) License
- **License**: This license is no longer available for purchase or renewal.
- **Billing**: Orgs using the Customer Data Platform license are billed based on the number of profiles, segment publishes, and engagement events their org completes. To understand billing calculations, see [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.").
- **Limits**: Customer Data Platform orgs must adhere to specific limits for most features. Some Data 360 features aren’t available to orgs with this license type. To review limits, see [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.").
- **[Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5)**
Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.
- **[Data 360 Reportable Resource References](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_resource_references.htm&release=264.0.0&type=5)**
Resource references are standard usage tags that let you view your credit consumption by the feature that generated the usage. You can build custom Data 360 reports on resource types to view, filter, and sort your usage by its source.
- **[Data Space References in Standard Consumption Tags](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_data_space_attribution.htm&release=264.0.0&type=5)**
Filter and group reports about your Data 360 consumption usage by data space.
- **[Attribute Data Query Costs to Agentforce Sessions and API Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_correlation_identifier.htm&release=264.0.0&type=5)**
The CorrelationIdentifier\_\_c field in Digital Wallet billing events connects Data 360 query credit consumption to source processes such as the Agentforce session, AI agent, or API call that triggered the query.
- **[Billing Impact of Data 360–Powered Features](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_billing_impact.htm&release=264.0.0&type=5)**
Some Salesforce CRM features are powered by Data 360 data. These features impact Data Services Credit consumption by increasing usage of associated processes in Data 360 (such as querying, storage, processing, and analytics). Before configuring Data 360\-powered features, review feature and usage documentation. Contact your account executive to understand how features impact Data Services Credit consumption in Data 360.
- **[Data Cloud License Billing and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_license.htm&release=264.0.0&type=5)**
Adding a Data Cloud license enables Data 360 on a Salesforce org. Orgs with this license purchase consumption credits which are consumed by use of Data 360 services.
- **[Data 360 Profiles License Billing and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profiles_overview.htm&release=264.0.0&type=5)**
Data 360 Profiles and Data 360 Enterprise Profiles licenses can be added on to Data Cloud licenses to change how a Data 360 org is billed and limited. When a Data 360 org has this license, its unified profiles, segments, data transforms, and insights are limited but don't consume credits.
- **[Customer Data Platform License Billing and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_cdp_license.htm&release=264.0.0&type=5)**
Customers with this license have access to Data 360 on a Salesforce org. This license is no longer available for purchase and can't be renewed. Orgs with this license are billed based on the numbers of profiles, engagements, and other records in their orgs. Other features have limits. Not all Data 360 features are available on Data 360 orgs with this license.
# Data 360 Lifecycle Management
To manage your Data 360 lifecycle you can renew your license or delete your Data 360 instance to reset the org. To keep your Data 360 instance, renew your license within the 120-day grace period. To set up a new Data 360 instance with an active license, use the Data 360 cleanup process to delete its associated data, metadata, and configurations. You can also use the cleanup process to connect your org as a Data Cloud One companion to an existing Data 360 instance.
After you clean up the org, you can reset it in two ways:
- Set up a new Data 360 instance that requires an active license.
- Connect the org as a Data Cloud One companion to an existing Data 360 instance.
## Renew an Existing Data 360 Instance
When a Data 360 license expires, it enters a 120-day grace period during which the Data 360 service is deactivated but the data remains. Under this scenario, you can renew your license and restore your current org. You also have the option to delete all Data 360 data.
## Data 360 Cleanup and Reset
After the grace period ends and the license expires, the Data 360 tenant is deleted, but its data, metadata, and configurations remain. To create a new Data 360 instance or to use it as a Data Cloud One companion org, remove its data.
These are other scenarios for deleting all associated Data 360 data from an org.
- To create a new Data 360 home org instance in the same or different region.
- To convert an existing home org into a Data Cloud One companion org.
- To connect your org as a Data Cloud One companion org to an existing Data 360 home org.
- To set up an existing sandbox as a companion org for connected sandboxes.
Cleaning up Data 360 data and metadata affects only the orgs directly connected to that Data 360 instance. When you clean up a Data 360home org on a sandbox to convert it into a companion org, this action doesn’t impact any Data 360 features, data, metadata, or packages on the parent production org, as the parent is connected to a different Data 360 instance.
## Data 360 Data Deletion Process
The admin for the org follows the on-screen instructions in Data Cloud Setup to ensure all Data 360 data and metadata are permanently removed from your org. If the org has expired or it contains Data 360 metadata and no Data 360 tenant, the Lifecycle Management screen displays.
**Data Cloud Setup screen with a notification for expired licenses and orgs that have a disconnected Data 360 tenant and leftover metadata.**
**Data Cloud Setup screen with a notification for expired licenses within the 120-day grace period.**
## External Dependency Removal
External dependencies are configurations or features outside of Data 360 that rely on its functionality. These include Data 360\-triggered flows, copy field enrichments, and Agentforce Data Library. To continue the data deletion process, first remove external dependencies. Navigate to each dependency to remove it. After you remove all external dependencies, continue to approve the removal of unmanaged package dependencies and any remaining data.
**Remove External Dependencies screen with a Flow Definition to remove.**
## Unmanaged Package Dependencies Review
Unmanaged packages can contain both Data 360 and non-Data 360 objects. Allowing Salesforce to remove the Data 360 objects doesn't affect unmanaged packages and any non-Data 360 objects they contain. Review how your objects are used to ensure there's no impact on your business needs and processes. Data 360 managed packages are automatically removed as part of Data 360 cleanup.
**Review Packaged Dependencies screen that displays a list of Data 360 objects to review before approving deletion.**
## Data Deletion
After you review the list of unmanaged packages, grant approval for Data 360 to delete the remaining data. Deleting all Data 360 data is a permanent process. After completion, you can no longer access the following.
- Data 360 features, data, metadata, data spaces, and packages
- Data 360 functionality from any connected companion orgs
Salesforce can't provide a backup of customer data or restore your Data 360 instance.
After you approve, data deletion begins. This process can take up 50 minutes. After it’s finished, the Data Cloud Setup screen refreshes.
**Screen that displays the Data 360 cleanup process in progress.**
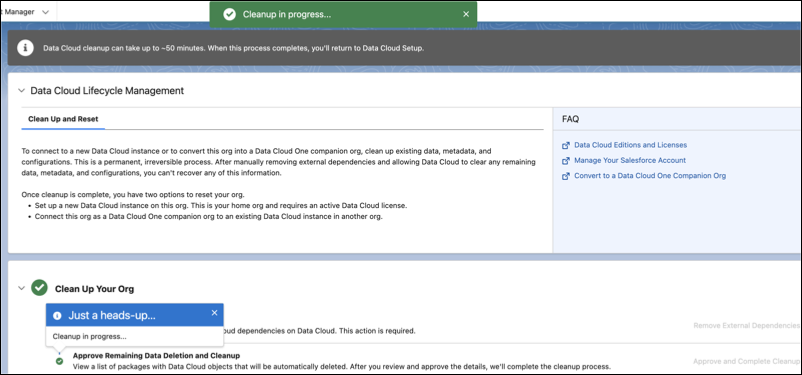
## Org Reset
The Data Cloud Setup screen displays options for how to reset your cleaned up org, based on your license.
- To create a home org, you need a home org license.
- To create a Data Cloud One companion org, you need both home org and companion org licenses. Initiate the companion org connection from a different, existing home org.
**Users with an expired license or who no longer have a Data 360 tenant see this screen with information about connecting to Data 360 upon completion of the cleanup process.**
#### See Also
- [_Salesforce Help_: Data Cloud One Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connections.htm&release=264.0.0&type=5 "With a Data 360 companion connection, you can create a bidirectional connection between a single Data 360 and one or more Salesforce orgs. Companion connections build on the capabilities of standard connections and sync unified data back to the companion Salesforce org. With a companion connection, your Salesforce orgs get a 360 degree view of their customers built with data from all your company's data.")
- [_Salesforce Help_: Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.")
# Data 360 Limits and Guidelines
Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.
Some limits and guidelines vary by edition or org type, such as when using Data 360 in a Developer org. For limits and guidelines related to Data 360 in a Developer org, see [Developer Edition Limits and Guidelines for Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_dev_ed.htm&type=5&language=en_US). Limits that aren't designated as hard limits indicate the point at which exceeding the limit may negatively impact performance, functionality, or usability. Hard limits, on the other hand, can't be exceeded in a regularly provisioned org. Contact your Account Executive to request an increase of the hard limit where indicated.
For limits related to Data 360 Reports, see [Data 360 Reports and Dashboards: Limits and Limitations](https://help.salesforce.com/s/articleView?id=analytics.rd_dc_reports_dashboards_limits.htm&type=5&language=en_US).

Note Some limits, guidelines, and usage billing calculations differ depending on your org’s license.
For billing information, refer to this additional document if your Data 360 org is operating under a Data Cloud license.
- [Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
Refer to these documents instead if your Data 360 org is operating under a Customer Data Platform license.
- [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.")
Contact your account executive if you aren’t sure which documents apply to you.
## General Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Location of data storage
Number of Data Cloud permission set licenses
200,000 Data 360 permission sets
200,000 additional Data Cloud Data Aware Specialist permission sets
Learn about Data 360 Standard Permission Sets ,
Permission Set Considerations , and Salesforce Features and Edition
Allocations .
Contact your Account Executive to adjust this
limit.
Number of data spaces
Depends on the number of licenses purchased
Learn more about licenses in Data 360 Standard Editions
and Licenses
Data Spaces permission sets
Data spaces permission sets can’t be included in permission set groups.
Data
spaces permissions sets aren’t counted against the Number of Data 360 Permission Set Licenses limit.
Unsupported features
Data Kits: Marketing Cloud Engagement data streams aren’t installable
Unsupported orgs
Professional Edition orgs
Government Cloud
Maximum number of Data Cloud One companion connections
Each Data 360 home org includes three Data Cloud One companion org connections.
To raise this limit, use Your Account add a Data Cloud One Additional Connection
license to your home org for each additional connection. Learn more about licenses
in Data Cloud Standard Editions and
Licenses
## Activation Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Scheduled activation publish frequency for standard segments
Minimum: 12 hours
Maximum: 24 hours
Activation frequency is tied to the segment publish frequency for standard
segments.
Learn more in Review Publish History of Your
Activation .
Scheduled activation publish frequency for rapid segments
Minimum: 1 hour
Maximum: 4 hours
Activation frequency is tied to the segment publish frequency for rapid
segments.
Total number of attributes
Learn more about attributes in
Create Activation for a Segment .
Number of segments to an activation target
Each segment can be sent to an activation target one time. Learn more in Create Activation for
a Segment .
Total number of activation targets
An activation target is information stored for a given activation platform,
which is the location that a segment’s data is being sent to during the activation
process.
Total number of activations
There’s no limit on how many of your activations can have.
Total number of activations with related attributes
There’s no limit on how many of your activations can have related attributes.
Although, there's a limit in CDP. Learn more in Customer Data Platform Guidelines and
Limits .
Total number of related attributes per activation
300 across no more than 4 data model objects in the same path
Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum records in a segment with related attributes
If the segment has more than 150 million records and contains related
attributes when you publish, the segment doesn’t activate. Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum levels away from the Activation Membership DMO with related
attributes
Choose attributes from DMOs 5 levels away from your selected Activation
Membership DMO. Learn more in Considerations for Selecting Related Attributes in Data 360 Activations .
Maximum number of related attribute records selected
Select the number of records sent for a given attribute in your activation
payload.
Number of ad audience activations to ad audience partners
Total number of contracted ad audiences
Ad audience activations are available for purchase.
The ad audience partners
are Google Ads, Meta (Facebook), and Amazon Ads.
One ad audience allows a
customer to activate one segment to an ad audience partner.
For example,
sending one segment to a Meta account and one segment to a Google account equals
two ad audiences.
Maximum number of characters for file storage activation
## AI Models (formerly Einstein Studio) Guidelines and Limits
## Calculated Insights Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
How often calculated insights are processed
System managed: Multiple times a day
Scheduled: Users can configure a schedule that best meets their needs
System managed calculated insights are automatically converted to scheduled
calculated insights when the calculated insight is edited.
With schedules, users
can pick a start date, time, and frequency for processing calculated insights. A
calculated insight won't run if there are no changes to source data, object
mappings, or configurations.
Maximum number of times a calculated insight can be manually processed in any
24-hour period
30 per calculated insight
Maximum calculated insight execution time
Insights that run for longer than 2 hours may be terminated by the system.
If
a calculated insight runs for longer than two hours, review your data shape and
optimize it.
Maximum number of nested calculated insights
Refers to how many existing insights you can use within a new insight.
Maximum number of dimensions per calculated insight
A dimension contains a qualitative value, such as a product name, date, or
profile ID.
Maximum number of measures per calculated insight
A measure is a quantitative aggregated value, such as an average or total
amount.
Total number of calculated insights per tenant
This limit includes calculated insights in active, inactive, and draft
statuses.
A tenant is a specific org or instance in Salesforce.
Maximum number of real-time insights
Real-time insights can only be built from real-time data graphs.
Maximum number of real-time insight fields (dimensions and measures)
This limit is for the total number of dimensions and measures in the real-time
insight.
The primary key for the root node of the real-time data graph will
automatically be added to the real-time insight and can’t be removed. This
dimension will count as one of your max fields.
## Code Extension Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum custom code deployment package size (zipped)
Maximum runtime (duration) of a custom function before it’s canceled by the
system
Functions that run longer than 5 minutes are canceled and return a failed
status. This limit applies to the function's active execution time, excluding
standby time.
Maximum runtime (duration) of a custom script before it's canceled by the
system
Retention period of custom code logs stored in a DLO
## Data Actions Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of data actions per tenant
Total number of data action targets per tenant
This limit is enforced by the UI.
Total number of rules per data action
Refers to the number of filter rules in a data action definition.
Maximum number of data graph profile records for enrichment
Refers to the maximum number of data graph records that you can enrich with the
primary object.
Total number of real-time data actions per real-time data graph
## Data Explorer Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of columns queried at a time
Total number of rows displayed per page
## Data Federation Guidelines and Limits
| Feature or Function | Guidelines and Limits | Hard Limit? | Additional Information and Resources |
| --- | --- | --- | --- |
| Maximum number of external data lake objects (DLOs) per org | See [Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.") | | A limit on the number of external DLOs hasn’t been defined. Usage of external DLOs can impact billing. |
## Data Graphs Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of data graphs per org
Standard data graph: 25
Real-time data graph: 25
Maximum number of draft data graphs per org
Standard data graph: 5
Real-time data graph: 5
Scheduled data graph refreshes per day
Standard data graphs can be set to refresh automatically every 30 minutes, four
hours, daily, weekly, or monthly. You can also refresh them manually whenever you
want.
Real-time data graphs refresh instantly for active sessions. The lakehouse
version of the real-time data graph refreshes every 1 hour.
Maximum number of JSON records that each data graph supports
Standard data graph: 200 million
Real-time data graph: 100 million
Including more records in a data graph impacts data graph refresh times and
query response times.
Maximum size of a real-time data graph
Performance may degrade if the size of the data graph exceeds 200 KB. This can
affect refresh times and query response speeds.
Maximum number of objects per data graph
Standard data graph: 25
Real-time data graph: 25
The data graph’s primary data model object, related data model objects, and
calculated insights count toward this limit.
Maximum number of fields per data model object that can be included in a data
graph
Standard data graph: 50
Real-time data graph: 50
Primary key, foreign key, and key qualifier fields aren’t included in this
limit.
Maximum number of measures per calculated insight that can be included in a
data graph
Standard data graph: 5
Real-time data graph: 5
Maximum number of total fields and measures that can be included in a data
graph
Standard data graph: 200
Real-time data graph: 200
Primary key, foreign key, and key qualifier fields aren’t included in this
limit.
Maximum number of engagement events in a data graph
The effective maximum limit on engagement events in a data graph is the lesser
of the number of events or age of the event.
Maximum age of engagement data included in a data graph
Standard data graph: 30 days (720 hours)
Real-time data graph: 30 days (720 hours)
The effective maximum limit on engagement events in a data graph is the lesser
of the number of events or age of the event.
Maximum number of levels that data model objects (DMO) can be nested below the
primary DMO in a data graph
Standard data graph: 5
Real-time data graph: 5
Levels are represented as a tree structure in the data graphs editor. The
nesting tree including the primary DMO can have a total of 6 levels.
Maximum number of records included per DMO
Standard data graph: 1,000
Real-time data graph: 1,000
The default limit is 100 records for sorting records per DMO in a data graph.
You can adjust this limit up to 1,000 records.
## Data Ingestion Guidelines and Limits
**General**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of fields per data stream
Maximum number of fields of a single type in a data stream
Total number of CRM custom objects
See Data Services Billable Usage Types for Data 360
This limit applies to the number of custom objects ingested from each connected
CRM org.
Total number of CRM orgs that can be connected to Data 360
Total number of data models
Total number of data streams
Total number of data lake objects (DLOs)
This limit applies to data lake objects created as part of data streams or in a
standalone manner.
Total Number of Marketing Cloud Personalization (Interaction Studio) datasets
per instance
Maximum number of rows for a Marketing Cloud Engagement Data Extension full
extract
**GCS, Azure, and S3 Bulk Ingestion**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Optimal number of file rows when creating S3 data streams
When creating an S3 data stream, you may need to use a file smaller than the
data you’d like to ingest. The smaller file should contain the same headers and
about 1,000 rows. Once the data stream is created, larger files can be placed within
the file path, maintaining that they fall within set limits.
Optimal size per CSV file
Sometimes, particularly for Day 0 loads, it’s necessary to move
large data volumes. The two parameters maximum file size and maximum files per
scheduled run aren’t intended to be stretched to their respective maximums
concurrently. Rather consider some tradeoffs between the two extremes and refer to
the other limit guidelines for more context.
Optimal size per Parquet file
Maximum number of files per scheduled run
Maximum size per uncompressed CSV file
Maximum size per compressed CSV file
Compressed CSV files aren’t splittable, meaning that they don't allow for
parallel processing and their usage is therefore discouraged. If sending in a
compressed file, it must be a single file per zip.
Maximum size per uncompressed parquet file
We recommend you to use the parquet compression capabilities to reduce file
size.
Maximum size per compressed parquet file
Compressed parquet files are splittable and support parallel processing of
ingestion. There are several native compression options. Learn more about supported
compression formats in Supported File Formats in Data 360 .
Maximum data size for upsert
When a data stream is on upsert, it’s best not to exceed a 50-GB aggregate
across all files in the single run. This number is strongly influenced by the number
of distinct data dates present in the table, the overall size of the table, and
several other factors such as the number of columns. As these variable inputs
increase you may experience performance degradation.
For larger target tables and
larger upsert ingestions, we strongly recommend using engagement tables and
selecting an engagement date field that contains many distinct dates. Not using
engagement nor selecting a high cardinality date field may cause performance
degradation.
Maximum data size for full refresh
Data size is the sum of all file sizes for a single datastream job. When a data
stream is set for full refresh, it’s best not to exceed 1000 GB for all files in a
single run. This number is strongly influenced by the number of distinct data dates
present in the table, the overall size of the table, and several other factors such
as the number of columns. As these input variables increase you may experience
performance degradation.
Maximum number of characters for a single cell
**Local File Upload**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of characters for a single cell in a local file upload
Supported delimiters
We currently only support the comma (,) delimiter.
Header row requirements
CSV files require a header row name for every field. This requirement is the
same format as what's used for Cloud Drive uploads.
Unsupported refresh of data streams
A data stream created from a local file upload can't be automatically
refreshed. You can upload a new file to refresh your data.
Maximum number of data streams created from a local file upload
Unsupported file or column names
File or column names with multi-byte characters aren't supported.
Primary key limitations
The primary key must have a value.
Primary key uniqueness isn’t enforced for local CSV file uploads. For best
results, verify that your primary key column is unique before uploading.
**SFTP Ingestion**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum size per file
The SFTP Connector can load up to 1,000 files that are less than 2
GB but totaling no more than 30 GB per data stream run. If you have more data, you
can use upsert mode for consecutive runs.
Maximum number of files included in a scheduled run
Maximum data per data stream run
Maximum size limit for file allowed during field analysis
Maximum file for PGP-encrypted schema file analysis
Maximum object size for fields
Maximum total size allowed for manual extract
Maximum total number of files allowed for manual extract
## Data Model Object Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Fields per data model object
800 per field type
1,050 total fields
Both custom and system fields are counted toward this limit.
Maximum number of data model objects
Maximum number of custom relationships per data model object
## Data Shares Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of data shares per org
Total number of data share targets per org
This limit isn’t applicable for Salesforce Data 360 data
share targets.
Maximum number of objects included per data share
## Data Transforms Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of streaming data transforms per org
Contact your Account Executive to adjust this limit.
Maximum number of characters in a streaming data transform SQL statement
Maximum number of batch transforms that can be created in an org
Contact your Account Executive to adjust this limit.
Maximum runtime (duration) of a batch transform job before it’s canceled by the
system
Maximum concurrent batch transforms that can be run at a time
## Document AI Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum size of unstructured data files for Document AI processing—DOCX, JPEG,
JPG, PDF, PNG, and PPTX
Real-time: 10 MB
Batch processing: 25 MB
LLM Token consumption varies based on the data density and complexity in input
file and the generated output. These limits apply to the UI and API for extracting
data and schemas.
Maximum number of pages per PDF for Document AI processing
Real-time: 25
Batch processing: 100
Maximum number of slides per Microsoft PowerPoint file for Document AI
processing
Real-time: 25
Batch processing: Not available
Maximum number of pages per Microsoft Word document for Document AI
processing
Real-time: 25
Batch processing: Not available
Maximum number of rows and columns per Microsoft Excel sheet for Document AI
processing
Maximum number of source documents uploaded for a given DLO
Maximum number of requests per minute for all Document AI functions
Maximum number of fields in a schema tree when calling the data extraction API
with an inline schema (no source DMO)
Maximum number of fields in the root object when creating a document schema
config with a source DMO
Maximum number of columns in a table (nested DLO) when creating a document
schema config
Maximum levels of nesting in a document schema config
Maximum number of tables (nested DLOs) in a document schema config
## Identity Resolution Guidelines and Limits
## Intelligent Context Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of files that can be uploaded
Maximum size of files that can be uploaded
Maximum number of DMO records that can be selected
## Private Connect for Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of private network routes
Additional private network routes are available for purchase.
## Real-Time Insights Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of real-time insights
Real-time insights can only be built from real-time data graphs.
Maximum number of real-time insight fields (dimensions and measures)
This limit is for the total number of dimensions and measures in the real-time
insight.
Real-time insights automatically include the primary key from the real-time
data graph they’re built on as a dimension. The primary key can’t be
removed.
All dimensions and measures used in the real-time data graph must be added to
the real-time data graph first.
Maximum number of related-DMOs
Only DMOs that have a many-to-one relationship with an existing real-time Data
Graph Engagement DMO.
The DMO must have a direct relationship to the real-time Data Graph Engagement
DMO.
The maximum is for all active real-time insights across all data spaces.
## Segmentation Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Total number of active segments
An active segment is a created segment with all functionality available. These
limits are enforced by the UI. Learn more in
Create a Segment in Data 360 and
Segment Types and Statuses .
Total number of attributes with value suggestions
Value suggestions can be enabled for up to 500 attributes for your entire org.
Learn more in
Use Value Suggestions in
Segmentation .
Total number of standard concurrent publishes
Total number of filters
You can have up to 50 filters each in the Include and Exclude tabs. Learn more
in
Segment Your Data in Attributes .
Total number of months that events are queried for standard segments
The segmentation event limit is 24 months or less. This limit is enforced by
the UI. For scheduled and manual publishes, segments error if a date range goes past
the 24-month range. To run the segment again, adjust your event dates to fit that
range.
Maximum number of scheduled publishes per standard segment per day
This limit is enforced by the UI. Learn more in
Publish a Segment in Data 360 .
Maximum number of rapid segments
Total number of rapid concurrent publishes
Total number of days that events are queried for rapid segments
The segmentation event limit is 7 days. This limit is enforced by the UI. For
scheduled and manual publishes, segments error if a date range goes past the 7-day
range. To run the segment again, adjust your event dates to fit that range.
Maximum number of scheduled publishes per rapid segment per day
Maximum number of real-time segments
Maximum number of engagement data model objects included in a real-time
segment
Maximum number of streaming events included in a real-time segment
Maximum levels of nested segments in a real-time segment
Exclusion in a real-time segment
Total number of processed records for rapid segments
This limit is for records processed for a rapid segment, which is the sum of
records present in the data streams associated with the segment. This limit isn’t
associated with the segment population.
Maximum number of Einstein segments created per month
The default limit is 20.
Maximum number of waterfall segments
This limit is enforced by the UI. Learn more in Create a Waterfall Segment .
## Streaming Insights Guidelines and Limits
## Unstructured Data and Search Index Guidelines and Limits
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum size of unstructured data files - TXT or HTML formats
Files larger than 4 MB are added to unstructured data lake objects and
unstructured data model objects, but they aren’t chunked or vectorized.
Maximum size of unstructured data files - PDF, Excel, PowerPoint, Word, RTF,
CSV, XML, Email, and Message formats
Files larger than 100 MB are added to unstructured data lake objects and
unstructured data model objects, but they aren’t chunked or vectorized.
Maximum size of unstructured data files - audio and video
File length: 1 hour
File size: 1 GB
Maximum size of unstructured data files - image formats
Maximum number of search indexes per Data 360
instance
Maximum number of fields that can be selected for pre-filtering
With pre-filtering you can enhance a search index configuration by adding
fields from an object or related objects to give users more ways to filter their
searches.
Maximum query filter length in a hybrid search query
Maximum query filter clauses in a hybrid search query
Maximum number of terms in the IN clause in a hybrid search query
Maximum number of results for a hybrid search query
Maximum number of results for a vector search query
Maximum amount of unstructured data that can be added to an enriched
index
Search Index processing time when enriched indexing is enabled
Processing time varies based on LLM processing. Datasets smaller than 200 MB
are processed within 2 hours.
## API Guidelines and Limits
The concurrent request and query limits of Data 360 APIs are independent from the concurrency limits governing the Salesforce platform APIs.
**API Queries**
**Ingest Bulk API Limits**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
API usage limits
After each request, your app must check the response code. The HTTP 429 Too
Many Requests status code indicates that the app must reduce its request
frequency.
Bulk job retention time
Open bulk jobs with the status of Open or Upload Complete that are older than 7
days are deleted from the ingestion queue.
Maximum number of files per job
Maximum payload size
Referring to the CSV files uploaded via Bulk API.
Number of requests or jobs allowed per hour
Number of concurrent jobs per connection per object
A job must be associated with a specific connection, and every connection is
associated with a specific schema that defines object(s). A connector can support
multiple connections.
Maximum number of concurrent jobs per org
**Ingest Streaming API Limits**
These limits and guidelines are for streaming ingestion across Mobile and Web SDK and Ingestion API.
**Profile API Limits**
Feature or Function
Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of records returned per call
Total number of fields per record

Note Unified Profile objects that are filtered on the index column have accelerated response rates. Other Profile category objects can’t guarantee a faster response.
- **[Developer Edition Limits and Guidelines for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_dev_ed.htm&release=264.0.0&type=5)**
Developer Edition orgs with Agentforce and Data 360 have certain limits and guidelines for Data 360 usage.
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
# Data 360 Marketing Agent Considerations and Troubleshooting
Review the limits of the Data 360 Marketing Agent, and fix common problems such as missing criteria, a delayed response, or an attribute the agent can’t reach.
### Required Editions
## Considerations
- Use the agent in one mode at a time. Don’t mix creating a segment from a Data 360 page with adding filters on the canvas by navigating between those pages in the same conversation.
- Prefer the segment canvas when you want to add filters. The canvas gives you better feedback and lets you validate the segment as the agent works. Save the segment yourself; the agent doesn’t save.
- The agent adds and builds filter criteria. It can’t remove or edit existing filters. Delete filters in the segment canvas.
- The agent reads the last saved version of a segment. It can’t see unsaved changes on your canvas, so save before asking it to work with the current criteria.
- The summary the agent gives after creating a segment can omit part of your request. Always check the criteria in the segment canvas.
- If your request names a DMO or calculated insight that isn’t mapped, or that doesn’t appear in the attribute library on the left of the segment canvas, the agent can skip those objects without telling you. It then continues with the filters it can create. Check the canvas to confirm that every condition you asked for is present.
- For highly complex requests, results can be inaccurate. Break the request into smaller parts and build the filters separately.
## Troubleshoot the Data 360 Marketing Agent
Problem
Troubleshooting Suggestions
A condition you asked for is missing from the segment.
Check the criteria in the segment canvas rather than the agent’s summary.
Requests involving a spend or a total can be matched to an existing calculated
insight that satisfies the amount but not the timeframe. Ask the agent to add
the missing condition, or add it yourself in the canvas.
The same thing can happen when the request names a DMO or calculated insight
that isn’t mapped or that doesn’t appear in the attribute library. The agent can
ignore the missing object and proceed with the filters it can create, without
telling you that something was skipped. Compare the canvas to your original
request. If a condition is missing, name the object or attribute more
specifically, or add the filter yourself.
Results are inaccurate.
Check that the Data 360 Data Q&A Agent is enabled. The Data 360 Marketing
Agent relies on it to return accurate results. See Enable Data 360
Data Q&A Agent .
The agent says an attribute can’t be connected to your Segment On
object.
No path exists between the two objects in your data model. Traversable paths
come from the derived relationships that match and reconciliation rules
generate. Choose an attribute the agent offers as an alternative. See Segment
Canvas .
The agent offers an attribute that then fails.
The agent can offer an attribute that identifies a record or links two
objects. Those attributes don’t appear in the segment canvas, so you can’t
filter on them. Choose a different attribute. See Segment Canvas .
The Add filters button doesn’t appear.
The button appears in the Agentforce panel, directly beneath the agent’s
response, not on the segment canvas. If the agent tells you the button is ready
on the canvas, look in the panel.
The button also appears inconsistently, depending on whether the agent treated
your request as editing the segment you have open or as creating a new one. If
the button is missing, stay on the canvas, ask again, and name the segment you
have open. Then save the segment yourself.
The agent asks the same question repeatedly.
When the agent restarts a request, it asks again about the segment type and
publish schedule. Answer it again to continue.
The agent shows Something went wrong. Try again.
The agent backend can take longer than expected to respond. The Agentforce
panel then shows
Something went wrongcontinue . The agent picks up where it left off and can
finish the request.
This can happen after you answer a numbered list of attribute options. For
example, you ask the agent to add a filter, it offers two attributes, you reply
1, and the panel shows the error. Type continue instead
of starting over.
#### See Also
- [_Salesforce Help_: Troubleshoot Segment Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_troubleshooting.htm&release=264.0.0&type=5 "Get tips for solving the most common segment errors in Data 360.")
- [_Salesforce Help_: Segment Canvas](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_canvas_interface.htm&release=264.0.0&type=5 "Use the segment canvas in Data 360 to select direct and related attributes to narrow down a created segment to your target audience.")
- [_Salesforce Help_: Publish a Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_segment.htm&release=264.0.0&type=5 "After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.")
# Data 360 Profiles License Base License Limits
Limits in this document represent the base limits of a single Data 360 Profiles or Data 360 Enterprise Profiles license. Some limits can be raised by purchasing multiple copies of the license or buying add-on licenses.
## Data 360 Profile Limits on Data Cloud One Companion Orgs and Sandbox Orgs
**Data Cloud One Org Companion Orgs:** Batch calculated insights and segments created on companion orgs are counted toward the Data 360 home org’s limit.
For example, if the home org purchases the base Data 360 Profiles license without any add-ons, it’s limited to 25 batch calculated insights. If the home org has 20 batch calculated insights and the companion org has 5 batch calculated insights, the org cluster has hit its limit of 25 batch calculated insights.
**Data 360 Sandboxes:** Each sandbox org created from the production Data 360 home org inherits the limits of its parent org. Identity resolution rulesets, batch data transforms, batch calculated insights, and segments on the Data 360 sandbox org and its connected companion orgs are counted toward the Data 360 sandbox org’s limit.
On sandbox orgs, the number of profiles counted toward the profile limit is calculated by multiplying the number of profiles by the weight. For example, if a production org has 100 unified profiles with a weight of 1, then 100 unified profiles times 1 is counted as 100 unified profiles (100 x 1 = 100 profiles). A sandbox org’s profiles have a weight of 0.8. Therefore, 100 profiles on a sandbox are counted as 80 profiles (100 x 0.8 = 80).
## Base License Limits for Data 360 Profiles and Data 360 Enterprise Profiles Licenses
Feature or Function
Data 360 Profiles Base License Guidelines and Limits
Data 360 Enterprise Profiles Base License Guidelines and Limits
Hard Limit?
Additional Information and Resources
Maximum number of Data Cloud One companion connections
10
10
You can raise this limit by purchasing more Data Cloud One Companion Org
licenses.
Maximum number of unique segments
100
500
Additional segments can be purchased in blocks of 10 segments.
Deactivated segments aren’t counted toward this limit.
Maximum number of unique calculated insights
25
100
Additional insights can be purchased in blocks of 2 insights.
Streaming insights aren’t included with or limited by this license.
Maximum number of batch data transforms
25
100
Additional batch data transforms can be purchased in blocks of 2 transforms.
Total number of records activated per month in batch activations on DMOs
20% of the total number of data lake object (DLO) records
20% of the total number of data lake object (DLO) records
No
For example, suppose you have a total of 1000 DLO records across your home org and one sandbox org.
You can activate up to 200 records per month in batch activations.
# Data 360 Profiles License Billable Profiles Calculations
In orgs with a Data 360 Profiles license, the billable number of profiles is based on whether you have active Identity Resolution rulesets. You’re billed at your overage rates for additional profiles if the number of billable profiles exceeds your entitlement.
## Counting Profiles in Data Spaces with Active Identity Resolution Rulesets
If you’re using identity resolution to link source profiles to Unified Profiles, the billable unified profile count is the sum of your known unified profiles, 4% of your anonymous profiles, and the total number of records in all DLOs mapped to DMOs categorized as Profile that aren’t used by identity resolution.
- **Known Unified Profiles:** The number of known Unified Profile records output by active identity resolution rulesets. To determine how many known Unified Profile records you have, view the Identity Resolution Summary for each active ruleset. Add the number of known Unified Profiles across all active rulesets.
- **Anonymous Unified Profiles:** 4% of the number of anonymous unified profile records output by active identity resolution rulesets. To calculate this number, view the Identity Resolution Summary for each active ruleset. Multiply the number of anonymous profiles by 0.04. Add the number of anonymous unified profiles across all active rulesets.
- **Ununified Source Profiles:** The number of all records in all DLOs, regardless of category, that are mapped to DMOs categorized as Profile, excluding Unified data model objects (Unified DMOs) output by an identity resolution ruleset.
## Counting Profiles in Data Spaces without Active Identity Resolution Rulesets
In a data space that isn’t using identity resolution, the billable profile count is the sum of all records in all data lake objects (DLOs), regardless of category, mapped to data model objects (DMOs) categorized as Profile type. Both known and unknown profile records are counted.
DLOs that are mapped only to the following DMOs are excluded from this count.
- Account Contact
- Contact Point Address
- Contact Point App
- Contact Point Consent
- Contact Point Email
- Contact Point OTT Service
- Contact Point Phone
- Contact Point Social
- Device
- Party Identification

Example
Suppose your org has two identity resolution rulesets: Unified Individual.1 with 10,000 records and Unified Individual.2 with 8,000 records. There are also two DLOs that are categorized as Profile and mapped to other DMOs that are categorized as Profile: the Account DLO has 2,000 records, and the Custom DLO has 5,000 records. For this customer, the total billable Unified Profiles is 10,000 + 8,000 + 2,000 + 5,000 = 25,000.
## Factors That Affect Unified Profile Counts
Address these factors to ensure that your profile counts accurately reflect your business needs.
**Multiple Identity Resolution Rulesets**
Unified profile counts from all active identity resolution rulesets are used to calculate total billable known and anonymous profiles. Validate the number of active identity resolution rulesets. If more than one is active, determine if all are needed for an active business purpose.
**Data Stream Growth**
As you connect different source systems to Data Cloud and increase the volume of data ingested through new data streams, the number of source profiles increases. Review all data streams and sources categorized as Profile. Determine if any duplicate, dev, test, or staging sources are connected and whether they’re still needed.
**Data Model Object Category**
Data lake objects (DLOs) mapped to data model objects (DMOs) that are categorized as Profile are available to segment on and are included in the Unified Profile count. Review all mappings from DLOs to DMOs. Determine if all data streams mapped to DMOs categorized as Profile contain a population that you want to segment by or use as the starting population for a segment. Determine if any DMOs are categorized incorrectly as Profile.
If a DMO is categorized incorrectly as Profile, you can change its category to Other. You can change a DMO’s category only if it isn’t used in segmentation or activation. Delete all segments and activations that use the DMO before changing the category from Profile to Other. See [Change the Category of a Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_change_data_model_object_category.htm&release=264.0.0&type=5 "In most cases, a data model object’s category can’t be changed after the object is created. The category can be changed only if it’s changing from Profile to Other or from Other to Profile on an object that isn’t used in segmentation or activation.").
**Additional Unified Profile Count Considerations**
- Records in a DLO that is included in multiple data spaces are only counted once. The number of records in the source DLO is counted, regardless of how many records are included in data space-specific views of the DLO.
- Data created from a transform that is output as an unmapped DMO isn’t counted toward billable Unified Profiles. If a DLO isn’t mapped, it doesn’t count.
- A DLO that is mapped to the Individual DMO and also to a DMO of type Profile isn’t counted twice.
- All DLOs that are mapped to a DMO with type Profile count toward billable Unified Profiles. This count includes these scenarios.
- Data streams outside of identity resolution counts
- Consent DMOs outside of identity resolution counts
- Data transform or stream transform DLOs mapped to DMOs of type Profile outside of identity resolution counts
#### See Also
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
# Data 360 Profiles License Billing and Limits
Data 360 Profiles and Data 360 Enterprise Profiles licenses can be added on to Data Cloud licenses to change how a Data 360 org is billed and limited. When a Data 360 org has this license, its unified profiles, segments, data transforms, and insights are limited but don't consume credits.
- **[Data 360 Profiles License Billing Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profile_billing_considerations.htm&release=264.0.0&type=5)**
Adding a Data 360 Profile or Data 360 Enterprise Profile license to a Data 360 org changes its consumption billing and adds limits for certain features.
- **[Data 360 Profiles License Base License Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_d360_profiles.htm&release=264.0.0&type=5)**
Limits in this document represent the base limits of a single Data 360 Profiles or Data 360 Enterprise Profiles license. Some limits can be raised by purchasing multiple copies of the license or buying add-on licenses.
#### See Also
- [_Salesforce Help_: Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.")
# Data 360 Profiles License Billing Considerations
Adding a Data 360 Profile or Data 360 Enterprise Profile license to a Data 360 org changes its consumption billing and adds limits for certain features.
All limits associated with Data 360 Profiles licenses apply to the production Data 360 home org and its connectioned Data Cloud One companion orgs collectively. Sandbox orgs created from the Data 360 home org inherit the home org's limits. Limits apply to the sandbox org and its connected companion orgs collectively. To review limits for orgs with Data 360 Profiles licenses, see [Data 360 Profiles License Base License Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_d360_profiles.htm&release=264.0.0&type=5 "Limits in this document represent the base limits of a single Data 360 Profiles or Data 360 Enterprise Profiles license. Some limits can be raised by purchasing multiple copies of the license or buying add-on licenses.").
## Profiles
The number of profiles included in your Data 360 org cluster is based on how many Data 360 Profile licenses you purchase. If you exceed your profile entitlement, you’re charged at your overage rate.
For production orgs, if identity resolution is active in a data space, the count of profiles in each data space is the sum of your known unified profiles, 4% of your anonymous profiles, and the total number of records in all DLOs mapped to DMOs categorized as Profile that aren’t used by identity resolution.
If identity resolution isn’t active, the billable profile count is the sum of all records in all data lake objects (DLOs), regardless of category, mapped to data model objects (DMOs) categorized as Profile type, excluding certain DMOs.
For sandbox orgs, the same counting logic applies, but the total number of profiles counted toward the limit is 80% of the sum of all profiles in all data spaces on the sandbox org.
For a more detailed explanation of how profiles are counted, see [Data 360 Profiles License Billable Profiles Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profiles_billable_profile_calcs.htm&release=264.0.0&type=5 "In orgs with a Data 360 Profiles license, the billable number of profiles is based on whether you have active Identity Resolution rulesets. You’re billed at your overage rates for additional profiles if the number of billable profiles exceeds your entitlement.").
## Identity Resolution Rulesets
Credits aren’t consumed by the Batch Profile Unification or Data 360 Unification usage types when identity resolution runs.
## Data Transforms
Credits aren’t consumed by the Batch Data Transforms or Data 360 Prep usage types, but the total number of active batch data transforms in your Data 360 org cluster is limited.
For production orgs, the number of batch data transforms counted toward the limit is the sum of all data transforms in all data spaces on the home production org.
For sandbox orgs, the number of batch data transforms counted toward the limit is the sum of all data transforms in all data spaces on the sandbox org.
## Calculated Insights
Credits aren’t consumed by the Batch Calculated Insights or Data 360 Prepusage types, but the total number of active batch calculated insights in your Data 360 org cluster is limited.
For production orgs, the number of batch calculated insights counted toward the limit is the sum of all calculated insights in all data spaces on the home production org.
For sandbox orgs, the number of batch calculated insights counted toward the limit is the sum of all calculated insights in all data spaces on the sandbox org.
## Segmentation
Credits aren’t consumed by the Segmentation or Data 360 Segmentation usage types, but the total number of active segments (including standard, waterfall and real-time types) in your Data 360 org cluster is limited.
For production orgs, the number of segments counted toward the limit is the sum of all segments in all data spaces on the home production org and all segments in all data space on all connected Data Cloud One Companion orgs.
For sandbox orgs, the number of segments counted toward the limit is the sum of all segments in all data spaces on the sandbox org.
## All Other Features
**Activations:** Credits aren’t consumed by the Batch Activation Data 360 Activation usage types, but the total number of active batch activations on DMOs in your Data 360 org cluster is limited. Streaming DMO activations consume credits.
**Data Ingestion:** Credits aren’t consumed when data is ingested via an internal data pipeline from a Salesforce org or via a batch data connection from an external source. Streaming data ingestion consumes credits.
**Zero Copy Data Federation:** Data federation via live queries and data federation via file federation don’t consume the Data Federation or Sharing Rows Accessed usage type. This usage type is still consumed by data sharing. Data federation with acceleration doesn’t consume the Batch Data Ingestion usage type.
**AI Inferences:** AI inferences don’t consume the Inferences usage type.
**Data transforms, identity resolution, insights, and segments:** These features continue to consume supplementary usage types listed in their Billing Considerations, such as Data Queries and data storage.
**All Other Features:** All other features continue to consume credits at the regular rates as referenced in the [Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")and the features’ Billing Considerations.
- **[Data 360 Profiles License Billable Profiles Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profiles_billable_profile_calcs.htm&release=264.0.0&type=5)**
In orgs with a Data 360 Profiles license, the billable number of profiles is based on whether you have active Identity Resolution rulesets. You’re billed at your overage rates for additional profiles if the number of billable profiles exceeds your entitlement.
#### See Also
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
# Data 360 Reportable Resource References
Resource references are standard usage tags that let you view your credit consumption by the feature that generated the usage. You can build custom Data 360 reports on resource types to view, filter, and sort your usage by its source.

Note Resource references rolled out incrementally between July 2025 and September 2025. Data isn’t available for a specific resource type prior to its rollout.
Because resource references are organized by feature, usage that is counted against different usage types is sometimes bundled together. For example, batch connectors and streaming connectors consume credits in different usage types, but are both reported by the same resource reference.
After creating a report on a Resource Type, sort by the Resource ID or API Name field to see what within the feature generated usage. For example, if you create a report on the DataStreamDefinition resource type, sorting by connector API names stored in the Resource ID or API Name field lets you see how much each connection contributed to your usage.
## Data 360 Usage Types and Resource Types
Usage Types Reported in Resource Types
| Data 360 Usage type | Usage type api name | Resource usage source | resource type |
| --- | --- | --- | --- |
| Batch Activations | DataCloud\_BatchActivationProcessed | Activations on segments | MarketSegmentActivationDef |
| Batch Calculated Insights | DataCloud\_BatchCI | Calculated Insights | MktCalcInsightObjectDef |
| Batch Data Pipeline | DataCloud\_BatchDataPipeline | Data ingestion via batch connectors | DataStreamDefinition |
| Batch Data Transforms | DataCloud\_BatchDataTransform | Data Transforms | MktDataTransformSetup |
| Batch Profile Unification | DataCloud\_BatchProfileUnification | Identity Resolution | IdentityResolutionDefinition |
| Data Share Rows Shared (Data Out) | DataCloud\_DataShareRowsShared | Data Shares | ExtDataShareDefinition |
| Inferences | DataCloud\_Inference | This category can be used by predictive AI | MktMLAIModel |
| Private Connect Data Processed | DataCloud\_BatchPrivateconnectBytesSent | Private Connect | OutboundNetworkConnection |
| Sub-second Real-Time Events & API | DataCloud\_RealTimeEventsAndAPI | Provided for real-time API calls. Not provided for processing real-time events. | DataGraphDefinition |
| Segmentation | DataCloud\_Segments | Segments | MarketSegmentDefinition |
| Streaming Actions (including lookups) | DataCloud\_StreamingActions | Data Actions | DataActionDefinition |
| Activation DMO - Streaming | DataCloud\_StreamingActivations | Activations on Data Model Objects | MarketSegmentActivationDef |
| Streaming Calculated Insights | DataCloud\_StreamingCI | Calculated Insights | MktCalcInsightObjectDef |
| Streaming Data Pipeline | DataCloud\_StreamingDataPipeline | Data ingestion via streaming connectors | DataStreamDefinition |
| Streaming Data Transforms | DataCloud\_StreamingDataTransform | Data Transforms | MktDataTransformSetup |
| Unstructured Data Processed | DataCloud\_UnstructuredDataProcessed | Search Index | DataSemanticSearchDef |
## Usage Types Not Reported in Resource Types
Usage Types Not Reported in Resource Types
| Data 360 usage type | Usage type api name | Resource usage source |
| --- | --- | --- |
| Data Federation or Data Sharing Rows Accessed | DataCloud\_DataFedOrSharingRowsAccessed | Data Federation |
| Data Queries | DataCloud\_DataQueries | Any feature that queries Data 360 data |
| Storage Beyond Allocation | DataCloud\_Storage | Data 360 storage |
| Sub-second Real-Time Profiles & Entities | DataCloud\_RealTimeProfiles | Data Graphs |
# Data 360 Reports and Dashboards
Easily create standard reports on single or multiple related data model objects (DMOs) or Calculated Insights to determine which areas of your business to focus on. Or, build a custom report type on DMOs to get information on the most pertinent fields and records from Data 360. You can group, filter, and summarize records in the report, run it for near real-time information and share it with others. And, make business decisions faster by visualizing KPIs and trends from Data 360 reports in your dashboards.
By default, users with access to Data 360 can use Data 360 reports.
# Data 360 Resources
In addition to help content, find links to videos, Trailhead, Developer, and other content available to help learn and implement Data 360.
##  Video and Audio Content
Sometimes it’s easier to understand how things work when you see them in action. Check out video content related to Data 360
- [Data 360 Activated](https://www.youtube.com/watch?v=q53cS0mnNNo&list=PLgIMQe2PKPSK3dvC28JnrHwPNg1xqsdvu)
- [Data 360 Video Library](https://sfdc.co/datacloudvideos)
- [Engineering Behind the Salesforce Data Cloud](https://www.youtube.com/watch?v=7NpdmrQQvLo)
- [Explore Document AI in Data 360](https://www.youtube.com/playlist?list=PLgIMQe2PKPSI3azxe6ypZy4e9iXIFHK_u)
- [Extend Data 360 with Code Extension](https://www.youtube.com/playlist?list=PLACV3VmGs318)
- [Get Started with Data 360](https://www.youtube.com/watch?v=vPsKskSZQbs&list=PLgIMQe2PKPSJy-jD9vGKb0oSeBMEEe5Tu&index=3)
- [Salesforce Developers: Data Cloud Decoded](https://www.youtube.com/playlist?list=PLgIMQe2PKPSI5DoY3FTYK7fXKVXNeQ4Xe)
- [Salesforce: Double Click](https://www.youtube.com/playlist?list=PLnobS_RgN7JZwiBQLIWzYR5cl-dTjOkJV)
- [Unlock Your Data with Data Cloud](https://salesforce.vidyard.com/watch/K4yzaAprouprVEhxEPjwgr)
##  Trailhead Content
Trailhead is the fun and free way to learn Salesforce. Get acquainted with Data 360 in trails, modules, quick looks, and trailmixes.
## Data 360 Learning Journey
The Data 360 Learning Journey is a progressive, 3-part trail experience designed to help you build a strong data foundation, apply hands-on skills, and develop solutions that drive business value on Trailhead.
- [Data 360: Unlock the Value of Your Data](https://trailhead.salesforce.com/content/learn/trails/data-cloud-unlock-the-value-of-your-data)
- [Data 360: Explore Setup to Activation](https://trailhead.salesforce.com/content/learn/trails/data-cloud-explore-setup-to-activation)
- [Data 360: Build and Develop Solutions](https://trailhead.salesforce.com/content/learn/trails/data-360-develop-and-build-solutions)
## Trails and Trailmixes
Trails are a collection of modules and projects. Trailmixes are curated resources made up of Trailhead modules, web links, PDFs, and other helpful content to help you learn Data 360.
- [Administer Data 360](https://trailhead.salesforce.com/content/learn/trails/administer-customer-data-platform)
- [Build a Data Strategy for Data 360](https://trailhead.salesforce.com/content/learn/trails/build-a-cdp-data-strategy)
- [Enhance Data in Data 360](https://trailhead.salesforce.com/content/learn/trails/enhance-data-in-customer-data-platform)
- [Explore Data 360](https://trailhead.salesforce.com/content/learn/trails/explore-customer-360-audiences)
- [Model Data in Data 360](https://trailhead.salesforce.com/content/learn/trails/model-data-in-customer-data-platform)
- [Prepare for Your Salesforce Data 360 Consultant Certification](https://trailhead.salesforce.com/content/learn/trails/prepare-for-your-salesforce-data-360-consultant-exam)
- [Use Data Insights Across Salesforce](https://trailhead.salesforce.com/content/learn/trails/use-data-insights-across-cloud)
## Modules, Projects, and Quick Looks
Key Job Area
Title
Description
Get Started
Data 360 Basics for Marketers
Discover the customer data platform for marketers and prepare for
implementation.
Data 360 Credit Consumption: Quick Look
Discover how Data 360 credits are consumed and how to make your credits
count.
Data 360-Powered Experiences
Use Data 360 to create personalized experiences across Salesforce and
beyond.
Data 360 Use Cases
Get the most out of Data 360 for Sales, Service, Marketing, and more.
Data 360 with Zero Copy Establish bidirectional integrations between Data 360 and external
systems.
Explore Data 360 Core Functionality Connect, unify, query, and segment your data in Data 360.
Data Cloud Setup Set up your account and connect data sources to support your company’s business
needs.
Salesforce Data 360: Quick Look
Discover Data 360, the platform for customer magic.
Plan Data
AI + Data: Project Planning
Learn how to create strategy and prepare your data for AI projects.
Customer-Centric Data Strategies
Develop an enterprise data strategy that puts customers front and
center.
Customer Data for Marketers
Use customer data to create personalized, engaging experiences.
Data + AI + CRM: Quick Look Discover how Data + AI + CRM work together to supercharge your
business.
Critical Thinking and Decision-Making with Data and
AI Discover strategies to maximize the impact of data and AI on
decision-making.
Customer Data Platform Strategy
Create a customer data platform strategy that delivers marketing
success.
Ethical Data Use Best Practices: Quick Look
Use ethical best practices to build trust and create personalized customer
experiences.
Real-Time Use Cases in Data 360 Support the customer journey by using real-time features in Data 360.
Govern & Secure
Data 360 Governance: Quick Look Govern data and metadata consistently at scale across every surface area of
Data 360.
Data Governance Strategies Manage your data effectively with tags, classifications, and policies.
Data Spaces in Data 360: Quick Look
Learn the benefits of using data spaces in Data 360.
Agentforce 360 Platform Encryption for Data 360:
Quick Look Add extra security for your sensitive Data 360 data with Platform
Encryption.
Connect & Unify
Batch Data Transforms in Data 360: Quick
Look
Create and schedule complex data transformations using batch data
transforms.
Customer 360 Data Model for Data 360
Explore and use data model objects in Data 360.
Data 360 Connectors and Integrations
Connect your data sources and define their relationship in Data 360.
Data and Identity in Data 360
Learn the fundamentals of data mapping, identity resolution, and unified
records.
Data Cloud One
Expand Data 360's reach across orgs with Data Cloud One connections.
Fully Qualified Keys in Data 360: Quick Look
Use qualified keys to avoid key conflicts in data sources connected to Data
360s.
Streaming Data Transforms in Data 360: Quick
Look
Enable customers to clean and prepare data as it enters the system in real
time.
Unstructured Data in Data 360 Learn how to ground search with unstructured data.
Web Engagement Data in Data 360
Gain customer insights with web engagement data in Data 360.
Process & Enrich
Advanced RAG with Data 360 and
Agentforce Use Data 360 and Agentforce to build grounded agents with advanced RAG.
Hybrid Search for RAG: Quick Look Enhance search accuracy with hybrid search index optimization
strategies.
Retrieval Augmented Generation: Quick Look
Improve LLM responses by augmenting your prompts with contextually relevant
business data.
Search Analytics for AI-Generated Search
Answers Get insights on AI-Generated Search Answers with Einstein Search
Analytics.
Search Index Types in Data 360: Quick Look
Discover how search index types in Data 360 improve search accuracy.
Explore & Optimize
Data 360 Query Editor Fundamentals Create workspaces, write SQL queries, and validate data in Data 360.
Data Graphs in Data 360 Build a data graph to streamline your queries.
Analyze & Predict
Build AI Models
Build, train, and evaluate your own predictive AI models.
Data 360 Insights
Use your data effectively by creating calculated and streaming
insights.
Data 360 Insights Using SQL
Use SQL to create calculated and streaming insights in Data 360.
Insights Builder in Data 360
Use Insights Builder to create insights using a drag-and-drop visual
builder.
Intro to Data 360 Reports Turn unified data into valuable insights with standard and custom
reports.
Machine Learning Predictions: Quick Look
Uncover valuable insights and make informed decisions with machine learning
models.
Predictive Outputs from Model
Builder Build an AI model to predict lead conversion and display results with a screen
flow.
Tableau Semantics Create semantic models and semantic definitions to input your data into Data
360.
Build & Share
Code Extension in Data 360 Build and deploy custom Python scripts to perform advanced batch transforms in
Data 360.
Data 360 Sandboxes Learn to build and deploy Data 360 functionality using a Data 360
sandbox.
Data 360 Solutions on AgentExchange: Quick
Look
Expand the power of Salesforce with Data 360 solutions on AppExchange.
Packaging and Data Kits in Data 360
Learn how to create and package components in Data 360.
Segment & Act
Advanced Segmentation in Data 360 Filter, group, rank, limit, and schedule precise segments in Data 360.
Advertising with Data 360 Discover how Data 360 helps you implement advertising strategies using
first-party data.
Communication Capping in Data 360: Quick
Look Use capping rules to prevent customer communication fatigue and stay on
budget.
Data 360 Clean Rooms: Quick Look Discover a privacy-first approach to data collaboration with Data 360 clean
rooms.
Segmentation in Data 360
Create and filter segments with Data 360.
Beyond Data 360
Agentforce Sales Enhancements with Data 360: Quick
Look
Integrate Data 360 with Sales Cloud for accurate data and better
insights.
Agentic Analytics Administration Build an agentic analytics platform with Data 360, Tableau Semantics, and
Tableau Next.
Connect Data 360 to Agentforce Combine harmonized data and generative AI to create powerful interactions and
automations.
Data 360 Enrichments Add Data 360 related objects to layouts in Sales Cloud.
Data 360 in Flows
Combine the power of Data 360 and Flow Builder to automate processes with
external data.
Data 360 for B2C Commerce: Quick Look
Learn how to personalize the shopper experience with Data 360.
Data 360-Driven Interactions in Marketing
Cloud
Use Data 360 to power journeys and other customer interactions in Marketing
Cloud Engagement.
Data 360-Powered Agentforce Discover how to implement Data 360 for Agentforce.
Data 360 with Sales and Service Integrate CRM data with Data 360 and unlock cross-cloud insights.
Loyalty Management and Data 360 Integration
Use up-to-the-minute customer intelligence to target members with personalized
promotions.
Tableau Next: Quick Look Learn how to analyze and take action on data and insights with Tableau
Next.
Salesforce Data Analysis in Tableau: Quick
Look
Use Tableau to analyze your Salesforce data and make better decisions.
Service and Data 360: Quick Look
Unlock crucial data for your agents and supervisors with Data 360.
Service Intelligence: Quick Look
Discover customer service insights from your data.
## Superbadges
Demonstrate your proficiency with Data 360 in a superbadge.
- [Data Stream Fundamentals Superbadge Unit](https://trailhead.salesforce.com/content/learn/superbadges/superbadge-data-stream-fundamentals-sbu)
##  Developer & Architect Content
Find developer guides and architecture content.
- [Architect Template Gallery](https://architect.salesforce.com/diagrams#template-gallery)
- [Data 360 Developer Center](https://developer.salesforce.com/developer-centers/data-cloud)
- [Data 360 Developer Guide](https://developer.salesforce.com/docs/platform/data-cloud-dev/guide/get-started.html)
- [Data 360 Query and Enhance Data](https://developer.salesforce.com/docs/platform/dc-query-guide/guide/how-to-query-data-cloud.html)
- [Data 360 Reference Guide](https://developer.salesforce.com/docs/data/data-cloud-ref/guide/c360a-api-intro-cdpapis.html)
## AgentExchange
Find ways to extend your data strategy in Data 360.
- [Data Cloud: Data Enrichment Apps](https://appexchange.salesforce.com/mktcollections/cloud-collections/customerdataplatform)
## Known Issues
Found an error in Data 360? Search Known Issues to see if there’s an existing bug identified.
- [About the Salesforce Known Issues Site](https://help.salesforce.com/s/articleView?id=000386216&type=1&language=en_US)
- [Find Known Issues](https://issues.salesforce.com/#q=known%20issues&f[sfcategoryfull]=Marketing%7CData%20Cloud%20\(CDP\))

# Data 360 Search Index
Data 360 uses a search index to manage structured and unstructured content in a search-optimized way. Create a search index configuration to chunk and vectorize your content. Chunking breaks the text into smaller units, reflecting passages of the original content, such as sentences or paragraphs. Vectorization converts chunks into numeric representations of the text that capture semantic similarities.
In Data 360, you can create vector or hybrid search indexes depending on data and query needs.
Use vector search when your data source and search queries benefit more from semantically aware matches within a large dataset. For example, if you send a query such as “What is Acme famous for?”, the LLM retrieves chunks that have the highest vector search score that relates to the closest semantic match with the search query.
When your data source and search queries benefit from both semantically aware vector search and the precision of a keyword search, use hybrid search. For example, in the query “Does Acme motor XYZ123 use hydraulic pumps?” the addition of keyword search promotes higher-ranking positions for more relevant content, thus providing the results with better grounding.
Learn more about the Data Cloud search index.
- [Vector Search](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_index.htm&type=5&language=en_US)
- [Hybrid Search](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index.htm&type=5&language=en_US)
- [Search Index Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&type=5&language=en_US)
- [Manage Search Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_manage.htm&type=5&language=en_US)
# Data 360 Standard Permission Sets
A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.

Note As of Sept. 4, 2025, standard permission sets were updated. Please see the [Data Cloud Standard Permission Set Transition Guide](http://sfdc.co/d360_perm_transition) to learn about the changes.
## About Permissions
In Salesforce, profile, permissions, and permission sets are fundamental aspects of user access. The best practice is to set up a user with the minimum level of permissions that the user needs to do their job.
- **Profiles**: Every Salesforce user is assigned to one profile. In addition to permissions, profiles control tab visibility, page layout assignments, record type access, and IP ranges.
- **Permissions**: Permissions determine whether a user can perform a particular action, such as read, create, or edit for a specific object or feature.
- **Permission Sets**: A permission set is a collection of permissions that grants additional access to users. Users can have multiple permission sets assigned to them.
Admins can create custom permissions. However, Data Cloud standard permission sets are automatically updated with each release as new features become available. By using a custom permission set could result in users not having access to new features or functionality.
## System Administrator Profile
To manage and assign users in Setup and access Data Cloud Setup, you can have a System Administrator user profile or the permissions that grant access to Salesforce Setup, for example, customize applicaton.
You need the Data Cloud Architect standard permission set to access Data Cloud Setup.

Note The Salesforce System Admin profile includes Manage All Data Space definition permission which grants users access to all Data Spaces. If the default Allow All policy is active in the org, users with the System Admin profile can query all Data 360 DMOs. To preserve data security, we recommend deleting the default Allow All policy or editing its scope to apply to specific users. See [Data Governance in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_gov_capabilities.htm&release=264.0.0&type=5 "Data governance provides a robust framework for securing and managing data through the combined use of tags, classifications, user attributes, and policy-based governance. Enabling policies and other governance features improves control and ensures users have access to the right data at scale.") for more information.
## Data Cloud Standard Permission Sets
You can combine these Data 360 permission sets with other Salesforce permission sets for users who need additional access.
**Data Cloud Architect** (formerly known as Data Cloud Admin)—Users with this permission set can access all functionality within Data 360, including Data Cloud Setup, mapping data to the data model, creating data streams, identity resolution rulesets, and insights.
Feature Access:
- **Full Access**: Data Spaces, Data Governance, Data Shares, Data Streams, DLOs, DMOs, Data Transforms, Data Graphs, Query Editor, Identity Resolution, Insights, Data Actions, Data Action Targets, Communication Capping, Segments, Activations, Activation Targets, AI Models, Unstructured Data Hub, Search Index, Semantic Layer
- **View Only Access**: Data Explorer, Profile Explorer

Important Data Cloud Architect grants users the Customize Application permission. To restrict access to Setup functionality, clone this permisison set and remove this permission. See this [article](https://help.salesforce.com/s/articleView?id=000386451&type=1&language=en_US) for more information about this permission.
**Data Cloud Activation Manager** (formerly known as Data Cloud Marketing Manager)—Users with this permission set can manage an overall segmentation strategy, including creating activation targets and activations.
Feature Access:
- **Full Access**: Query Editor, Data Actions, Data Action Targets, Data Transforms, Communication Capping, Segment, Activations, Activation Targets
- **View Only Access**: Data Streams, DLOs, DMOs, Data Graphs, Data Explorer, Identity Resolution, Insights, Profile Explorer, Unstructured Data Hub, Search Index
- **No Access**: Data Cloud Setup, Data Spaces, Data Governance, Data Shares, AI Models, Semantic Layer
**Data Cloud Activation Specialist** (formerly known as Data Cloud Marketing Specialist)—Users with this permission set can create segments.
Feature Access:
- **Full Access**: Query Editor, Data Actions, Data Transforms, Segment, Activations
- **View Only Access**: Data Streams, DLOs, DMOs, Data Graphs, Data Explorer, Identity Resolution, Insights, Profile Explorer, Data Actions Targets, Communication Capping, Activation Targets
- **No Access**: Data Cloud Setup, Data Spaces, Data Governance, Data Shares, AI Models, Unstructured Data Hub, Search Index, Semantic Layer
**Data Cloud User**—Users with this permission set can view Data 360 features.
Feature Access:
- **Full Access**: None
- **View Only Access**: Data Spaces, Data Governance, Data Shares, Data Streams, DLOs, DMOs, Data Transforms, Data Graphs, Query Editor, Identity Resolution, Profile Explorer, Insights, Data Actions, Data Action Targets, Communication Capping, Segment, Activations, Activation Targets, AI Models, Unstructured Data Hub, Search Index, Semantic Layer
- **No Access**: Data Cloud Setup
## Permission Set Table View
View and download a [PDF version](http://sfdc.co/d360_perms) of the permission set table.
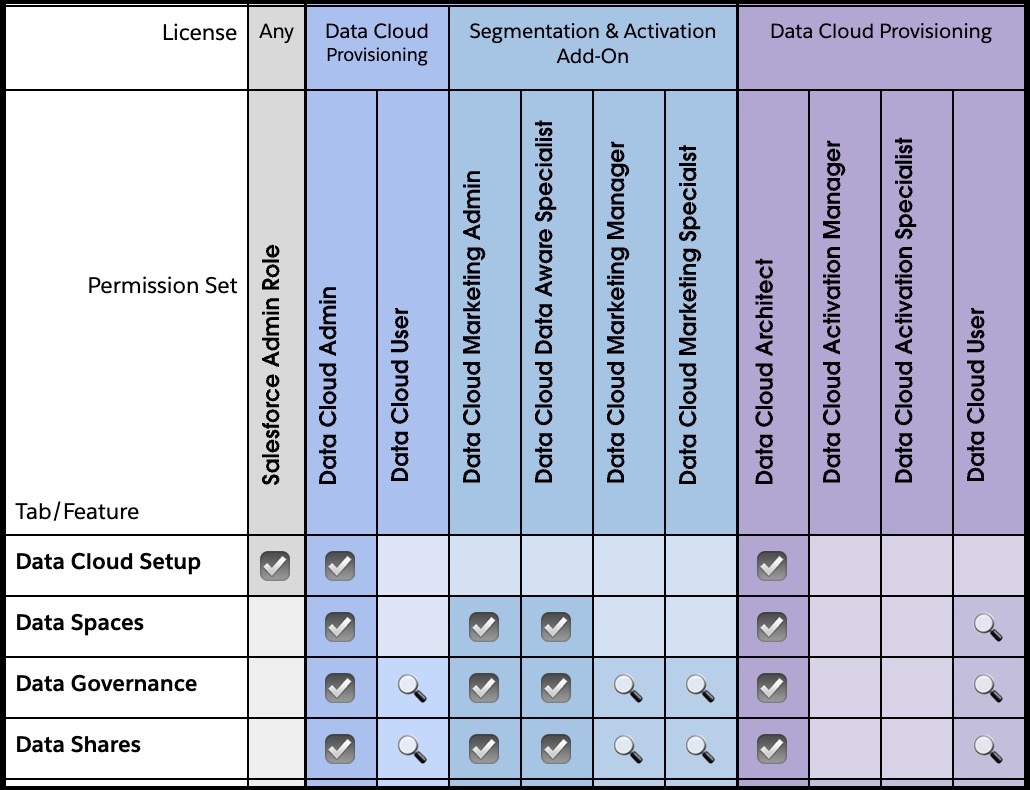
## Legacy Permission Sets
The following permissions are now legacy permissions. While still available, we recommend transitioning to new permissions sets to gain access to new features and enhancements.
- **Legacy Data Cloud Marketing Admin**—Users with this permission set can manage day-to-day configuration needs, support, maintenance, and perform regular internal system audits.
- **Legacy Data Cloud Data Aware Specialist**—Users with this permission set can map data to the data model and create data streams, identity resolution rulesets, and calculated insights.
## Additional Permission Sets
Several features use permission sets to manage access. Review information regarding how permission sets are used across Data 360.
- **Data Cloud Salesforce Connector**—When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. See [Salesforce CRM Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&type=5&language=en_US) and [Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&type=5&language=en_US).
- **Data-Space Aware**—For data-space aware features, access granted by permission sets only applies to associated data spaces. See [Manage Feature Access for Data Space-Aware Data Cloud Features](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_feature_access.htm&release=264.0.0&type=5 "By default, Data Cloud standard permission sets control access to Data Cloud features with preset object permissions. You can further restrict feature access within each data space assigned to a permission set by changing the data space’s feature permissions.") and [Associate a Permission Set with a Data Space](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_associate_perm_sets.htm&release=264.0.0&type=5 "When Data Cloud is enabled, the default data space is associated with standard Data Cloud permission sets, except the Data Cloud Architect. To give access to other data spaces, change the data space permission set that it’s associated with or create a permission set.").
- **Data Cloud One**—Data Cloud One companion orgs don't use standard Data 360 permission sets. To grant access to the Data Cloud One app on companion orgs, assign the **Data Cloud One User** permission set. To refine access to features offered within the app, clone and edit the permission set.
- **[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5)**
A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.
# Data 360 Thought Leadership Content
Find links to blogs, white papers, and community groups related to Data 360.
## Decision Guides and White Papers
Explore Data 360 white papers and decision guides for detailed insights into architecture, common use cases, best practices, and how it can help you unify data for better business results.
| Name | Description | Author |
| --- | --- | --- |
| [Agentforce and RAG](https://www.salesforce.com/content/dam/web/en_us/www/documents/article/agentforce_and_rag_best_practices_for_better_agents.pdf) | Provide best practices for powering Agentforce with unstructured data (files) and long free-text fields on structured objects. | Reinier van Leuken |
| [Data 360 Clean Rooms](https://architect.salesforce.com/docs/architect/fundamentals/guide/data360-cleanrooms) | Architect's guide to clean room functionality. | Yugandhar Bora, Birendra Kumar Singh, and Priyanka Kshirsagar |
| [Data 360 in Sandboxes](https://sfdc.co/d360_sandbox) | Build, test, and deploy Data 360 in a secure environment using sandboxes. Learn about functionality now available with a Data Cloud license. | William Yeh and Susan Oliver |
| [Data 360 Interoperability](https://architect.salesforce.com/decision-guides/data-360-interoperability) | Architect's guide to Salesforce Data 360 interoperability. | Yugandhar Bora and Jan Fernando |
| [Data 360 Provisioning](https://architect.salesforce.com/decision-guides/data-360-provisioning?_ga=2.159949629.1827199884.1762469086-1055302314.1762466692) | Architect's guide to Salesforce Data 360 provisioning. | Kunal Goyal, Erin Wagner Tidwell, Yugandhar Bora, and Samarpan Jain |
| [Exploring Our Monthly Release Process](http://sfdc.co/DCReleases) | Understand the difference between Salesforce core releases and the Data 360 monthly release process. | William Yeh and Susan Oliver |
| [Understanding Consumption Billing: Breaking Down an Enriched Related Lists Use Case](http://sfdc.co/billingwp1) | Discover how consumption-based pricing works within Salesforce, and dive into a real-world use case of "Enriched Related Lists" to understand direct and indirect billing points. Learn how to estimate costs and manage your Digital Wallet effectively. | Erin Wagner Tidwell |
## Articles and Blog Posts
Uncover the latest Data 360 insights and best practices – explore external blog posts published within the last nine months to stay ahead of the curve.
[Datablazer Blog](https://www.salesforce.com/blog/data/)
| Name | Author | Date |
| --- | --- | --- |
| [How Data 360 Builds Trusted Context: The Enduring Layer for Enterprise AI](https://engineering.salesforce.com/how-data-360-builds-trusted-context-the-enduring-layer-for-enterprise-ai/) | Raveendrnathan Loganathan | Sep. 16, 2026 |
| [Improve Enterprise RAG Accuracy in Data 360](https://developer.salesforce.com/blogs/2026/09/improve-enterprise-rag-accuracy-in-data-360) | Barnali Patnaik, Aanchal Varma, & Kartik Muktinutalapati | Sep. 2, 2026 |
| [4 Steps to Eliminate Identity Debt and Build Reliable Agentic AI with Data 360](https://www.salesforce.com/blog/eliminate-identity-debt-data-360/) | Patrice Chalaman | Aug. 6, 2026 |
| [Meet Agentforce Coworker](https://www.salesforce.com/blog/agentforce-coworker-salesforce-ai-teammate/) | Rohit Kapoor | June 2, 2026 |
| [Building an Enterprise Agent Platform: Enforcing Identity, Data, and API Governance](https://engineering.salesforce.com/building-an-enterprise-agent-platform-enforcing-identity-data-and-api-governance/) | Muralidhar Krishnaprasad | May 26, 2026 |
| [Building Data 360 Clean Rooms: Zero-Copy Architecture for Privacy-Safe Data Collaboration](https://engineering.salesforce.com/building-data-360-clean-rooms-zero-copy-architecture-for-privacy-safe-data-collaboration/) | Soumya KV | May 11, 2026 |
| [Filter Level Counts in Segmentation](https://www.salesforceblogger.com/2026/04/06/filter-level-counts-in-segmentation/) | Darshna Sharma | April 6, 2026 |
| [Beyond CRM: How Salesforce Engineered an Enterprise Agent Platform for Any Workload](https://engineering.salesforce.com/beyond-crm-how-salesforce-engineered-an-enterprise-agent-platform-for-any-workload/) | Muralidhar Krishnaprasad | Mar. 11, 2026 |
| [How Data 360 Optimized Kubernetes Scheduling Architecture, Delivering 13% Cost Savings](https://engineering.salesforce.com/how-data-360-optimized-kubernetes-scheduling-architecture-that-delivered-13-cost-savings/) | Padma Aradhyula | Mar. 5, 2026 |
| [The Power of Ingesting Unstructured Data into Data 360](https://www.salesforceblogger.com/2026/03/05/the-power-of-ingesting-unstructured-data-into-data-360/) | Arsheen Chugh | Mar. 5, 2026 |
| [Against the Clock: How Data 360 Launched the Informatica Help Agent in 24 Days](https://engineering.salesforce.com/against-the-clock-how-data-360-launched-the-informatica-help-agent-in-24-days/) | Irina Malkova | Feb. 11, 2026 |
| [Flow-Orchestrated Activations: Build Smarter Customer Journeys in Data 360](https://www.salesforceblogger.com/2026/02/09/flow-orchestrated-activations-build-smarter-customer-journeys-in-data-360/) | Kiranmai Bhamidi | Feb. 9, 2026 |
| [Unlocking Data 360 for Multiple Marketing Cloud Engagement Instances (EIDs)](https://www.salesforceblogger.com/2026/01/15/unlocking-data-360-for-multiple-marketing-cloud-engagement-instances-eids/) | Sankar Muthusamy | Jan. 15, 2026 |
| [The Agentic Bank: How Data 360 and Agentforce 360 Redefine Intelligence in Financial Services](https://www.linkedin.com/pulse/agentic-bank-how-data-360-agentforce-redefine-services-gina-nichols-qtpzc/) | Gina Nichols | Jan. 15, 2026 |
| [GRL: The ‘Precision Filter’ You Didn’t Know Your CDP Was Missing](https://www.salesforce.com/blog/grl-the-precision-filter-you-didnt-know-your-cdp-was-missing/) | Rekha Ayothi | Jan. 6, 2026 |
## Events & Community
Learn about on-demand and upcoming events. The Trailblazer Community of Data 360 users grows daily, and they love to share their knowledge. For community groups, meetups, blogs, and channels, join a group.
Events and Resources
- [Data 360 Events](https://cs.salesforce.com/product/datacloud?filter=false&product=&category=®ion=&language=&type=&search=&startDate=&endDate=&dateSpan=custom)
- [Data 360 Resources](https://www.salesforce.com/data/resources/)
- [Salesforce Data 360: LinkedIn](https://www.linkedin.com/showcase/sfdc-data-cloud)
 Community Groups
- [Datablazer Community Group](https://trailhead.salesforce.com/trailblazer-community/groups/0F94V000000DYhhSAG?tab=discussion&sort=LAST_MODIFIED_DATE_DESC)
- [Data 360 Community Group](https://trailhead.salesforce.com/trailblazer-community/groups/0F94S000000kQixSAE?tab=discussion&sort=LAST_MODIFIED_DATE_DESCo)
- [Data Cloud for Marketing Community Group](https://trailhead.salesforce.com/trailblazer-community/groups/0F93A000000Tz4ISAS?tab=discussion&sort=LAST_MODIFIED_DATE_DESC)
- [Data Matters Community Group](https://trailhead.salesforce.com/trailblazer-community/groups/0F94V000000bvORSAY?tab=discussion&sort=LAST_MODIFIED_DATE_DESC)

# Data 360 Time Zones
Data 360 uses the time zone set in Salesforce when publishing and refreshing segments and activations. The dates and times added to a segment in the segment canvas also use the Salesforce time zone. To change the time zone for Data 360, change the time zone in Salesforce.
#### See Also
- [_Salesforce Help_: Supported Time Zones](https://help.salesforce.com/s/articleView?id=xcloud.admin_supported_timezone.htm&type=5&language=en_US)
- [_Salesforce Help_: Segment Time Zone](https://help.salesforce.com/s/articleView?id=data.c360_a_update_segment_time_zone.htm&release=264.0.0&type=5 "Segment publish schedules are interpreted in the user's time zone. Your Data 360 org sets the publish time zones on the initial segment save and segment canvas. Segment and activation fields display the Publish Schedule Start Date and Time in the user's time zone.")
# Data 360 Unified Profile Lightning Apps
Display data about unified profiles on certain pages using Lightning apps. In the Profile Explorer, the Data 360 Unified Profile Lightning apps are used to display data on the unified individual profile record page.
- **[Configure the Data 360 Profile Related Records Lightning App](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_lightning_apps_configure_profile_related_records.htm&release=264.0.0&type=5)**
Use the Lightning App Builder to set up the Data 360 Profile Related Records app to show records related to a unified profile.
- **[Configure the Data 360 Profile Engagements Lightning App](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_lightning_apps_configure_profile_engagements.htm&release=264.0.0&type=5)**
Use the Lightning App Builder to set up the Data 360 Profile Engagements app to show engagement activity related to a unified profile.
- **[Configure the Data 360 Profile Insights Lightning App](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_lightning_apps_configure_profile_insights.htm&release=264.0.0&type=5)**
Use the Lightning App Builder to set up the Data 360 Profile Insights app to show from a measure from a selected calculated insight.
# Data 360 Usage and Access Changes
Changes to documentation about Data 360 licensing, feature availability, limits, billing, and permission sets are logged in this document.
For other changes to Data 360 features, see [About Data 360 Releases](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_releases.htm&type=5&language=en_US).
## August 25, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Document AI Guidelines and Limits: Updated Maximum number of rows and columns per Microsoft Excel sheet for Document AI processing limit from Columns: 100 to Columns: 200.
## August 21, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Document AI Guidelines and Limits: Updated Maximum size of unstructured data files for Document AI processing—PDF, JPEG, JPG, PDF, and PNG to Maximum size of unstructured data files for Document AI processing—DOCX, JPEG, JPG, PDF, PNG, and PPTX to include DOCX and PPTX file formats.
## August 7, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Document AI Guidelines and Limits: Added these limits:
- Maximum number of slides per Microsoft PowerPoint file for Document AI processing: Real-time: 25, Batch processing: Not available.
- Maximum number of pages per Microsoft Word document for Document AI processing: Real-time: 25, Batch processing: Not available.
- Maximum number of rows and columns per Microsoft Excel sheet for Document AI processing: Rows: 5000 Columns: 100.
- Intelligent Context Guidelines and Limits: Added Maximum number of DMO records that can be selected limit of 30.
## August 4, 2026
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Shares Guidelines and Limits:
- Increased Total number of data shares per org limit from 10 to 20.
- Decreased Total number of data share targets per org limit from 20 to 5.
- Increased Maximum number of objects included in a data share limit from 20 to 250.
## June 23, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Document AI Guidelines and Limits: Updated Maximum number of requests per minute for all Document AI functions limit from 20 to 50.
## June 22, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Ingestion Guidelines and Limits: Local File Upload
- Renamed Primary key uniqueness restrictions limit to Primary key limitations, updated with information on how the primary key must have a value.
- Document AI Guidelines and Limits:
- Updated Maximum size of unstructured data files for Document AI processing—PDF, JPEG, JPG, and PNG limit to Real-time: 10 MB and Batch processing: 25 MB.
- Updated Maximum number of pages per PDF for Document AI processing limit to Real-time: 25 and Batch processing: 100.
- Added Maximum number of source documents uploaded for a given DLO limit of 1.
- Renamed Maximum number of requests per minute for schema extraction limit to Maximum number of requests per minute for all Document AI functions.
- Added Maximum number of fields a nested DLO can have when creating a document schema config limit of 25.
- Added Maximum levels of nesting in a document schema config limit of 1.
- Added Maximum number of nested DLOs in a document schema config limit of 5.
## June 12, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Code Extension Guidelines and Limits: Added Maximum runtime (duration) of a custom function before it’s canceled by the system limit of 5 minutes.
## June 5, 2026
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added section Document AI Guidelines and Limits with limit Document AI: Not available.
- Added section Notebook AI Guidelines and Limits with limit Notebook AI: Not available.
## May 22, 2026
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Update the Batch Calculated Insights and Unstructured Data Processed with additional details.
## May 19, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- AI Models (formerly Einstein Studio) Guidelines and Limits::
- Added limit Clustering Models (Beta): Number of fields allowed for training: Minimum 3, maximum 50.
- Added limit Clustering Models (Beta): Number of text and date fields allowed for training: 10.
- Added limit Clustering Models (Beta): Number of rows required for training: Minimum 400, maximum 20 million.
- Renamed limit Einstein-Created Models (Created From Scratch): Maximum number of input variables for an AI model per tenant to Custom Models (Created From Scratch): Maximum number of input variables for an AI model per tenant.
- Renamed limit Einstein-Created Legacy Models Only (Created From Scratch): Numeric variables automatically categorized into groups to Custom Legacy Models Only (Created From Scratch): Numeric variables are considered continuous fields and removed numeric limit.
- Renamed limit Einstein-Created Models (Created From Scratch): Number of unique categories per model variable to Custom Models (Created From Scratch): Number of unique categories per model variable.
- Renamed limit Einstein-Created Models (Created From Scratch): Minimum number of occurrences required to consider a single text value as unique for model training to Custom Models (Created From Scratch): Minimum number of occurrences required to consider a single text value as unique for model training.
- Renamed limit Einstein-Created Models (Created From Scratch): Minimum number of rows to Custom Models (Created From Scratch): Minimum number of rows.
- Renamed limit Einstein-Created Models (Created From Scratch): Maximum number of rows to Custom Models (Created From Scratch): Maximum number of rows.
- Renamed limit Einstein-Created Models (Created From Scratch): Maximum number of concurrent model training jobs per org to Custom Models (Created From Scratch): Maximum number of concurrent model training jobs per org.
## May 12, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Intelligent Context Guidelines and Limits:
- Renamed Maximum number of PDF files that can be uploaded limit to Maximum number of files that can be uploaded.
- Renamed Maximum size of PDF files that can be uploaded limit to Maximum size of files that can be uploaded.
## May 8, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Unstructured Data and Search Index: Increased Maximum number of search indexes per Data 360 instance limit from 25 to 100.
## Apr 28, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Ingestion: Updated Total number of CRM orgs that can be connected to Data 360 limit to no limit.
## Apr 14, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Graphs: Increased Maximum number of data graphs per org limit for standard and real-time data graphs from 10 to 25.
## Mar 13, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Real-Time Insights: Added Maximum number of real-time insights, Maximum number of real-time insight fields (dimensions and measures), and Maximum number of related-DMOs limits.
## Mar 2, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Activation Guidelines and Limits: Added Maximum number of characters for file storage activation limit.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Activation Guidelines and Limits:
- Added Maximum number of characters for file storage activation limit.
- Increased Total number of activations with related attributes limit to 10,000.
- Increased Total number of related attributes per activation limit to 300.
- Increased Maximum records in a segment with related attributes limit to 150 million.
- Increased Maximum levels away from the Activation Membership DMO with related attributes limit to 5.
- Added Maximum number of related attribute records selected limit.
- Added Maximum number of characters for file storage activation limit.
## Feb 6, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Code Extension (Beta) Guidelines and Limits:
- Added Maximum custom code deployment package size (zipped) limit.
- Added Maximum runtime (duration) of a custom script before it's canceled by the system limit.
- Added Retention period of custom code logs stored in a DLO limit.
## Feb 3, 2026
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- API Guidelines and Limits: Changed Total number of concurrent inbound requests for Query API and Insights API limit to Total number of concurrent inbound requests for Insights API.
## Jan 30, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Document AI Guidelines and Limits:
- Added Maximum number of fields the root object and every table can have when creating a document schema config limit.
- Added Maximum number of fields in a schema tree when calling the data extraction API with an inline schema limit.
## Jan 9, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Streaming Insights Guidelines and Limits:
- Updated Supported primary DMO objects limit.
- Updated Allowed joins limit.
## Jan 5, 2026
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Unstructured Data and Search Index Guidelines and Limits:
- Corrected Maximum number of results for a vector or hybrid search query limit to Maximum number of results for a vector search query.
- Added Maximum number of results for a hybrid search query.
## Dec 12, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Activation:
- Increased Total number of related attributes per activation from 20 to 300 across no more than 4 data model objects in the same path.
- Increased Maximum records in a segment with related attributes from 10 million to 150 million.
- Increased Maximum levels away from the Activation Membership DMO with related attributes from 4 to 5.
- Added Maximum number of related attribute records selected limit.
## Dec 5, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Intelligent Context: Added these limits:
- Maximum number of PDF files that can be uploaded
- Maximum size of PDF files that can be uploaded
- Unstructured Data and Search Index:
- Added Maximum size of unstructured data files - audio and video limit
- Added Maximum size of unstructured data files - image formats limit
- Increased Maximum number of search indexes per Data 360 instance limit from 10 to 25
## Nov 4, 2025
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Ingestion: Added these Local File Upload limits:
- Supported delimiters
- Header row requirements
- Unsupported refresh of data streams
- Maximum number of data streams created from a local file upload
- Unsupported file or column names
- Primary key uniqueness restrictions
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added the Intelligent Processing usage type
## Oct 14, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Ingestion: Added these Local File Upload limits:
- Supported delimiters
- Header row requirements
- Unsupported refresh of data streams
- Maximum number of data streams created from a local file upload
- Unsupported file or column names
- Primary key uniqueness restrictions
## Oct 10, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Shares: Increased Total number of data shares per org limit to 100.
## Sep 26, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- APIs: Added Total number of rows queried at a time in Query Editor limit.
- Unstructured Data and Search Index:
- Removed Maximum length of values for pre-filtering fields of “Text” data type limit.
- Increased Maximum query filter length in a hybrid search query limit to 128,000.
- Increased Maximum query filter clauses in a hybrid search query limit to 3,072.
- Increased Maximum number of terms in the IN clause in a hybrid search query limit to 4,096.
## Sep 19, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- APIs: Removed Data size of query API response limit.
- SFTP Ingestion: Replaced Maximum size per CSV file with Maximum size per file and Maximum number of files per scheduled run with Maximum number of files included in a scheduled run. Increased Maximum data for a data stream run to 30 GB. Added Maximum size limit for file allowed during field analysis, Maximum file for PGP-encrypted schema file analysis, Maximum object size for fields, Maximum total size allowed for manual extract, and Maximum total number of files allowed for manual extract limits.
## Sep 16, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- General Guidelines and Limits: Updated the Number of data spaces limit.
- Document AI: Added Maximum size of unstructured data files for Document AI processing—PDF, JPEG, JPG, and PNG, Maximum number of pages per PDF for Document AI processing, and Maximum number of requests per minute for schema extraction limits.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- General Guidelines and Limits: Updated the Number of data spaces limit.
## Sep 15, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Ingestion: Added the Optimal number of file rows when creating S3 data streams for GCS, Azure, and S3 Bulk Ingestion.
- Unstructured Data and Search Index: Added the Maximum amount of unstructured data that can be added to an enriched index and Search Index processing time when enriched indexing is enabled limits.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Ingestion: Added the Optimal number of file rows when creating S3 data streams for GCS, Azure, and S3 Bulk Ingestion.
## Sep 5, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Ingestion: Added the Maximum number of characters for a single cell for Local File Upload limit and Maximum number of characters for a single cell limit for GCS, Azure, and S3 Bulk Ingestion.
- Data Shares Guidelines and Limits: Increased the Total number of data share targets per org limit to 20.
- Ingest Streaming API: Updated Expected latency for Mobile and Web SDK and server-to-server applications for Engagement data.
## Aug 26, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Ingest Streaming API: Updated limits for Expected latency for Ingestion API and Expected latency for Mobile and Web SDK applications.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Ingest Streaming API: Updated limits for Expected latency for Ingestion API, Expected latency for Mobile and Web SDK and server-to-server applications, Maximum number of records that can be deleted via Ingestion API deletion, and Total number of requests per second across all Ingestion API object endpoints.
## July 22, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Unstructured Data: Updated a limit to add more data files: PDF, Excel, PowerPoint, Word, RTF, CSV, XML, Email, and Message formats.
## June 10, 2025
- Feature Availability: Removed the Feature Availability in Data Cloud and Customer Data Platform topic.
## June 2, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Graph: Added the Maximum number of records included per DMO limit.
- Ingest Bulk API: Added the Maximum number of concurrent jobs per org limit.
## May 6, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Added real-time data graph limits to the Data Graphs section.
## April 15, 2025
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added the Internal Data Pipeline usage type.
- Updated the description of the Batch Data Pipeline usage type.
- Updated the description of the Streaming Data Pipeline usage type.
## March 31, 2025
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- APIs: Added limits to the APIs: Query, Insights, and Profile section.
## March 17, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Einstein Studio: Added limits for Einstein-Created Models (Created from Scratch).
[Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.")
- Added Data Cloud Provisioning and Customer Data Platform licenses.
- Added Your Account availability details.
## March 10, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Shares: Updated the Maximum number of objects included per data share limit from 20 to 250.
- Identity Resolution: Added the limits: Maximum number of individual profile identifiers included in a unified profile and Maximum number of engagement events included in a unified profile.
## March 3, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Developer Edition: Moved Developer org–related limits to [Developer Edition Limits and Guidelines for Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_dev_ed.htm&type=5&language=en_US).
## February 3, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Segmentation: Added the Maximum number of waterfall segments limit.
## January 28, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Data Actions: Added the Total number of real-time data actions per real-time data graph limit.
## January 13, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Data Actions: Removed the Total number of data attributes per payload limit.
- Data Actions: Removed the Maximum size of payload per firing limit.
- Streaming Insights: Updated the section.
## January 6, 2025
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Removed the Total number of Einstein Lookalike seed segments limit.
- Updated the Maximum number of Einstein segments created per month limit to 160.
- Added the Maximum number of draft data graphs per org limit of 5.
- Removed the All Predictive Models: Maximum number of inference calls per month limit (Data Cloud only).
- Removed the Number of anonymous profiles limit (Data Cloud only).
- Added the Maximum number of results for a vector or hybrid search query limit of 16,000 (Data Cloud only).
## December 13, 2024
[Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.")
- Added add-on 4 licenses for Data Cloud in sandbox orgs.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the description of the Inferences usage type.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Increased the Maximum number of batch transforms that can be created in an org limit to 1,000.
- Increased the Total number of data actions per tenant limit to 200.
- Increased the Total number of data action targets per tenant limit to 100.
- The Tableau Query limits section was removed.
## November 11, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added the Private Connect Data Processed usage type.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Maximum number of private network routes limit.
## October 21, 2024
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Updated the Total number of calculated insights per tenant limit.
- Increased the Maximum number of times a calculated insight can be manually processed in any 24 hour period limit.
- Increased the Maximum number of nested calculated insights limit.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Updated the Total number of activations limit.
- Added the Maximum query filter length in a hybrid search query limit.
- Added the Maximum query filter clauses in a hybrid search query limit.
- Added the Maximum number of terms in the IN clause in a hybrid search query limit.
- Increased the Maximum number of times a calculated insight can be manually processed in any 24 hour period limit.
- Increased the Maximum number of nested calculated insights limit.
## October 14, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Maximum number of Data Cloud One companion connections limit.
- Removed the Total number of concurrent queries limit.
Feature Availability in Data Cloud and Customer Data Platform
- Added Data Cloud One.
## October 7, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Unstructured Data billing category description.
- Updated the Sub-second Real-Time Profiles & Entities category name and description.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Raised the Maximum number of objects per data graph limit to 25.
## September 23, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Revised the Scheduled standard data graph refreshes per day limit for clarity.
- Replaced the Maximum number of engagement events in a real-time data graph limit with the Maximum number of engagement events in a data graph limit.
- Replaced the Maximum age of engagement data included in a real-time data graph limit with the Maximum age of engagement data included in a data graph limit.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Batch Data Pipeline billing category description.
- Added the Batch Data Transforms billing category.
- Updated the Streaming Data Pipeline billing category description.
- Added the Streaming Data Transforms billing category.
- Updated the Data Federation or Data Share Rows Accessed billing category description.
## September 9, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Data Queries billing category description.
- As of August 16, 2024, Data Cloud usage will no longer be billed against the Accelerated Data Queries and Real Time Profile API categories.
Feature Availability in Data Cloud and Customer Data Platform
- Added feature availability for Communication Capping (Pilot).
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.") and [Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
- Added permission set information for Communication Capping (Pilot).
## August 22, 2024
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.") and [Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
Removed the requirement that System admins need the Data Cloud admin permission set to see and access Data Cloud Setup.
## August 5, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
Added a note about billing for sandbox orgs.
## July 29, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
Added the Total number of processed records for rapid segments limit.
## July 22, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
Removed these limits:
- Total number of AI models per tenant
- Total number of output fields for an AI model per tenant
- Maximum levels to reach an object in the object hierarchy
Added these limits:
- Maximum number of source profiles that can be unified into a single unified profile
- Maximum size of source records processed in a ruleset
- Maximum combined character count of values reviewed by a match rule
- Maximum number of real-time insights
- Maximum number of real-time insight fields (dimensions and measures)
- Maximum number of real-time segments
- Maximum number of engagement data model objects included in a real-time segment
- Maximum number of streaming events included in a real-time segment
- Maximum levels of nested segments in a real-time segment
- Exclusion in a real-time segment
- Connected Models (Bring Your Own Model): Maximum number of input variables for an AI model per tenant
- Einstein-Created Models (Created From Scratch): Maximum number of input variables for an AI model per tenant
- Einstein-Created Models (Created From Scratch): Minimum number of rows
- Einstein-Created Models (Created From Scratch): Maximum number of rows
- All Predictive Models: Maximum Number of prediction jobs
- All Predictive Models: Maximum number of inference calls per month
- All Predictive Models: Maximum number of active models
- All Predictive Models: Maximum number of rows for each real-time inference request
Updated this limit:
- Maximum size per CSV file
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
Removed these limits:
- Total number of AI models per tenant
- Total number of output fields for an AI model per tenant
- Maximum levels to reach an object in the object hierarchy
Added these limits:
- Maximum number of source profiles that can be unified into a single unified profile
- Maximum size of source records processed in a ruleset
- Maximum number of match rules in a ruleset
- Maximum number of match criteria within a single match rule
- Maximum combined character count of values reviewed by a match rule
- Einstein-Created Models (Created From Scratch): Maximum number of input variables for an AI model per tenant
- Einstein-Created Models (Created From Scratch): Minimum number of rows
- Einstein-Created Models (Created From Scratch): Maximum number of rows
- All Predictive Models: Maximum Number of prediction jobs
- All Predictive Models: Maximum number of inference calls per month
- All Predictive Models: Maximum number of active models
- All Predictive Models: Maximum number of rows for each real-time inference request
Updated this limit:
- Maximum size per CSV file
## July 15, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Added the Maximum length of values for pre-filtering fields of “Text” data type limit.
- Added the Total number of data lake objects (DLOs) limit.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Total number of data lake objects (DLOs) limit.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added the Sub-second Real-Time Events & API usage type.
- Added the Sub-second Real-Time Service Usage section.
- Updated the Data Queries usage type description.
- Updated the Accelerated Data Queries usage type description.
- Updated the Data Federation or Data Share Rows Accessed usage type description.
Feature Availability in Data Cloud and Customer Data Platform
- Added feature availability for Real-Time Data Graphs and related real-time features.
[Billing Considerations for Einstein Generative AI Audit and Feedback](https://help.salesforce.com/s/articleView?id=ai.generative_ai_audit_feedback_usage_types.htm&type=5&language=en_US)
- The article was created.
## July 8, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Updated the Unsupported Orgs limit.
## July 1, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Batch Data Pipeline usage type description.
## June 24, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Updated the Number of external data lake objects allowed per org limit.
- Changed the name of the Rapid Segments limit to Maximum number of rapid segments.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Changed the name of the Rapid Segments limit to Maximum number of rapid segments.
## June 17, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Updated the Number of external data lake objects allowed per org limit.
## June 10, 2024
Feature Availability in Data Cloud and Customer Data Platform
- Added feature availability for Unstructured Data and Search Index Configurations.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Accelerated Data Queries to add vector search queries.
- Added the Unstructured Data Processedusage type.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Added limits for Unstructured Data.
## May 27, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Added the Maximum number of data graph profile records for enrichment limit.
## May 20, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Removed the Maximum scheduled data graph refreshes in 24 hours limit.
- Added the Scheduled standard data graph refreshes per day limit.
- Added the Maximum size of a real-time data graph limit.
- Added the Maximum number of engagement events in a real-time data graph limit.
- Added the Maximum age of engagement data included in a real-time data graph limit.
- Added the Match methods used during real-time matching limit.
- Added the Maximum records in a segment with related attributes limit.
- Added the Maximum levels away from the Activation Membership DMO with related attributes limit.
## May 13, 2024
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Removed the Total number of active calculated insights and Total number of calculated insight batch runs per year, per tenant limits.
## April 22, 2024
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added a note to Data Federation or Sharing Rows Accessed usage type to clarify what it applies to.
## April 1, 2024
Feature Availability in Data Cloud and Customer Data Platform
- Added feature availability for Einstein Segments.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Updated the Data Share Rows Changed (In Region) category name to Data Share Rows Shared (Data Out).
- Updated the Data Share Rows Accessed (In Region) category name to Data Federation or Sharing Rows Accessed.
- As of March 19, 2024, Data Cloud usage will no longer be billed against the Data Share Rows Changed (In Region) and Data Share Rows Accessed (In Region) categories.
## March 25, 2024
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Reduced the Total number of data actions per tenant limit to 10.
- Reduced the Total number of data action targets per tenant limit to 3.
## March 18, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added limits for Data Federation.
- Replaced the Maximum size per standard CSV file limit with the Maximum size per uncompressed CSV file limit.
- Added the Maximum size per uncompressed parquet file limit.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Optimal size per parquet file limit.
- Added the Maximum size per uncompressed parquet file limit.
- Reduced the Total number of data actions per tenant limit to 10.
- Reduced the Total number of data action targets per tenant limit to 3.
## March 11, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Maximum number of match rules per ruleset limit.
- Added the Maximum number of match criteria per match rule limit.
- Added the Maximum number of Einstein segments created per month limit.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Updated the Number of ad audience activations to ad audience partners limit to the total number of contracted ad audiences.
- Replaced Scheduled activation publish frequency limit with separate limits for standard segments and rapid segments.
## February 19, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Removed the Total number of data action events generated per tenant, per minute limit.
## January 29, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Increased the Maximum number of rows for a Marketing Cloud Data Extension full extract limit to 100 million.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Increased the Maximum number of rows for a Marketing Cloud Data Extension full extract limit to 100 million.
- Increased the Maximum number of batch transforms that can be created in an org limit to 100.
## January 18, 2024
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Increased the Maximum number of fields per data stream limit to 1,050.
- Increased the Maximum number of single field types in a data stream limit to 800.
- Increased the Fields per data model object limit to 800 per field type and 1,050 fields total.
## Spring '24 Doc Release (January 11, 2024)
Feature Availability in Data Cloud and Customer Data Platform
- Changed Einstein Studio Bring Your Own Model name to Einstein Studio AI Models.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Changed Einstein Studio Bring Your Own Model name to Einstein Studio AI Models.
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.") and [Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
- Changed Einstein Studio Bring Your Own Model name to Einstein Studio AI Models.
## January 4, 2024
Feature Availability in Data Cloud and Customer Data Platform
- Added feature availability for Data Graphs.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added Data Graphs limits.
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.") and [Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
- Added permissions sets information for Data Graphs.
## December 11, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Increased the Total number of data actions per tenant limit from 20 to 100.
- Increased the Total number of data action targets per tenant limit from 10 to 50.
- Removed the Number of activation records processed per org per year for each ad audience limit.
- Increased the Data size of query API response limit from 8 MB to 32 MB.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Increased the Total number of activations with related attributes limit from 30 to 100.
- Increased the Data size of query API response limit from 8 MB to 32 MB.
## December 4, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Increased the Number of Data Cloud Permission Set Licenses limit from 1,000 to 20,000.
- Removed the Total number of Marketing Cloud data extension tables limit.
- Added the Maximum number of rows for a Marketing Cloud data extension full extract limit.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Removed the Total number of Marketing Cloud data extension tables limit.
- Added the Maximum number of rows for a Marketing Cloud data extension full extract limit.
## October 23, 2023
Feature Availability in Data Cloud and Customer Data Platform
Updated availability for Einstein Studio Bring Your Own Model.
[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
Updated permission sets for Einstein Studio Bring Your Own Model.
## October 16, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Increased the Maximum number of batch transforms that can be created in an org limit to 100.
- Increased the Maximum concurrent batch transforms that can be run at a time limit to 50.
- Added the Maximum size per compressed parquet file limit.
- Increased the Maximum data size for upsert limit to 50 GB.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added 3 Data Share limits.
- Added 4 Einstein Studio Bring Your Own Model limits.
- Added the Maximum size per compressed parquet file limit.
- Increased the Maximum data size for upsert limit to 50 GB.
- Added the Maximum number of records that can be deleted via Streaming API deletion limit.
## October 2, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- The Total number of concurrent queries limits for API Queries generally and for queries to Tableau were increased from 15 to 50.
- Adjusted the name of the Number of ad audiences and activations to Google and Meta external activation platforms limit to Number of ad audience activations to add audience partners and corrected the limit for Data Cloud licenses.
Feature Availability in Data Cloud and Customer Data Platform
Update availability for data shares.
[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
Updated permission sets for Data Shares.
## September 19, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") and [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Adjusted the names of the Total number of data actions generated per tenant, per minute and Total number of standard concurrent publishes per hour limits for clarity.
- The Total number of filters limit on segmentation was increased from 50 to 100.
- The Rapid segments limit was increased from 5 to 20.
## September 6, 2023
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.")
Updated to clarify that Data Cloud for Marketing permission sets are associated with the Segmentation and Activation add-on license.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
Removed an extraneous note from the Total number of Streaming Insights limit.
## August 21, 2023
Feature Availability in Data Cloud and Customer Data Platform
Added Data Shares.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- Added two usage types related to data shares.
- Revised the Batch Data Pipeline and Streaming Data Pipeline usage category descriptions to include data transforms.
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.")
Added Data Shares.
[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
Added Data Shares.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- Added the Data Shares section.
- Added the Einstein Studio Bring Your Own Model section.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- Added the Data Shares section.
- Added the Einstein Studio Bring Your Own Model section.
## August 14, 2023
Feature Availability in Data Cloud and Customer Data Platform
- Added Einstein Studio Bring Your Own Model.
- Added Segmentation: Einstein Lookalike Segments.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
Added the Inferences usage category.
[Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.")
Added Einstein Studio Bring Your Own Model.
[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
Added Einstein Studio Bring Your Own Model.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- In the Segmentation section, noted that Einstein Lookalike Segments isn’t available for orgs with Customer Data Platform licenses.
- In the Streaming Insights section, the Aggregation time window minimum time was changed from 5 minutes to 1 minute.
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- In the Segmentation section, added the Total number of Einstein Lookalike seed segments limit.
- In the Streaming Insights section, the Aggregation time window minimum time was changed from 5 minutes to 1 minute.
## August 7, 2023
[Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.")
Clarified that billable unified profile calculations in orgs that don’t use identity resolution are based on data lake objects mapped to data model objects that are categorized as type Profile type.
## July 31, 2023
[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- In the Data Transforms section, updated the Total number of streaming data transforms per org limit to include information about using Data Cloud in a Developer org.
- In the Identity Resolution section, clarified that the Maximum number of ruleset jobs in any 24-hour period limit is calculated per data space. The Total number of identity resolution rulesets limit is now listed first in this section.
- In the Calculated Insights section, removed from the total limit across all calculated insights limit from the Maximum number of times a calculated insight can be manually processed in any 24-hour period row.
- In the API Usage limits section, changed the Expected latency for Ingestion API limit from 2 minutes to 3 minutes.
[Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
- In the Identity Resolution section, clarified that the Maximum number of ruleset jobs in any 24 hour period limit is calculated per data space. The Total number of identity resolution rulesets limit is now the first limit in this section.
- In the Calculated Insights section, removed the total across all calculated insights from the Maximum number of times a calculated insight can be manually processed in any 24 hour period row.
- In the API Usage limits section, changed the Expected latency for Ingestion API limit from 2 minutes to 3 minutes. The Expected latency for Mobile and Web SDK applications limit replaced the Expected latency for Mobile and Web SDK and Data collection intervals for Mobile and Web SDK applications limits.
Feature Availability in Data Cloud and Customer Data Platform
Descriptions of each feature area were added. Also, the table headers were revised for clarity.
[Customer Data Platform Standard Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_cdp.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Four standard permission sets are provided for orgs contracted under a Customer Data Platform license. The Salesforce admin assigns permission sets to users.")
This article was added.
## July 24, 2023
Feature Availability in Data Cloud and Customer Data Platform
This article was added.
[Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.")
Added a list of data model objects that are excluded when billing based on unified profiles is calculated.
[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
Added the Data Space usage category.
#### See Also
- [_Salesforce Release Notes_: Data 360 Features Released by Month](https://help.salesforce.com/s/articleView?id=release-notes.rn_cdp_data_cloud_features_released_by_month.htm&language=en_US)
# Data 360 Videos
Find short videos about Data 360 fucntionality..
## What is a Data Stream?
Watch this video to learn about data streams.
# Data Action Targets in Data 360
The result of a data action is triggered in a data action target. The target receives the data action in near real time. You can send a data action to a target to drive event-based orchestration.
### Required Editions
Available in: Lightning Experience
The supported targets are:
- Salesforce Platform Event—Send a data action to the core event bus to build a flow application based on near real-time insights generated in Data 360.
- Webhook—Send a data action to a webhook target, and protect the message integrity with a Salesforce-generated secret key. A webhook is a type of API that is event driven rather than request driven.
- Marketing Cloud Engagement—Manage event and insight driven scenarios with Engagement messaging and journey capabilities.
- Amazon Kinesis—Send change data capture events to your Kinesis data stream for downstream processing.
Data action targets created by an integration user, such as a Copy Fields enrichment, Salesforce CRM enrichment, or Data Cloud-triggered flow using Flow Builder, are read only. You can’t delete, disable, or edit these targets.
## Examples
Here are a few examples of near real-time, event-driven use cases enabled by data actions.
- Action-informed engagement
- A customer purchases an item that’s complex to install and searches for “Installation Manual” on your website. You can send the customer an email with a how-to video or installation instructions.
- Service and support
- A customer visits multiple troubleshooting pages in a specific time window. You can automatically log a case for the customer.
- A customer has scheduled a service. You can send automated reminders based on upcoming service appointments.
- Financial services
- A customer purchases a product on your website worth over $1,000. You can trigger a customer journey event.
- You can monitor customer transactions in real-time and send immediate notifications for any fraudulent transaction.
- Account engagement
- A customer selects several items and places them into their cart, but doesn’t purchase them. You can trigger a journey to urge the customer to complete the purchase.
- Automatically enroll customers in promotional journeys based on spending tiers.
- Location-based engagement
- A customer checks into a hotel. You can send the customer a journey with prompts to visit the hotel bar or check out luxury vacations and activities.
- A customer enters a theatre. You can send an SMS with information about movies and their showtime for the day.
- **[Create a Salesforce Platform Event Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_data_actions.htm&release=264.0.0&type=5)**
Send a data action to the core event bus to build a flow application based on a trigger generated in Data 360.
- **[Create a Webhook Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_action_target_of_webhook_type.htm&release=264.0.0&type=5)**
Send a data action event to a webhook target and protect the message integrity with a Salesforce-generated secret key. A webhook is a type of API that’s event driven rather than request driven. The secret key validates the payload requests sent from Salesforce. The webhook transports the HTTP payload with events in the format of `DataObjectDataChgEvent`.
- **[Create an Amazon Kinesis Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_an_amazon_kinesis_data_action_target.htm&release=264.0.0&type=5)**
Send change data capture (CDC) events from Data 360 to an Amazon Kinesis data stream for near-real-time downstream processing.
- **[Marketing Cloud Engagement Data Action Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_cloud_data_action_targets.htm&release=264.0.0&type=5)**
Use data and insights to drive business metrics and reduce delay in interacting with customers with Journey Builder API events and transactional emails sent in Marketing Cloud Engagement. Automate and personalize transactions by combining Data 360 with Engagement. You can automate simple operational tasks with data-triggered email messages and journeys, maximize conversions, and minimize customer drop-off rates.
# Data Actions in Data 360
Monitor data changes in data model objects and calculated insight objects in Data 360, and send the change data events to the Salesforce Platform Event, Marketing Cloud Engagement, Webhook, or Amazon Kinesis targets.
A data action can be triggered based on certain conditions and can enable downstream systems to drive an action or orchestration. Three categories of data that can trigger a data action:
- Change Data Capture events: For example, a profile record is inserted/updated/deleted in a data model object (DMO).
- Streaming events: For example, data comes in from your SDK, ingestion API, or Marketing Cloud Personalization.
- Streaming Calculated Insights: For example, insights that are based off streaming data coming into Data 360.
You can use a data action to focus on near real-time events and insights at different levels, for example, at the channel, product, account, service, sell, fulfillment, engagement, payment, and individual level.
A data action can enable different types of event-driven integrations and orchestrations.
- Orchestrate Salesforce CRM workflows with insights and data events from Data 360.
- Integrate data actions in Mulesoft Anypoint by sharing aggregated event data with external partners based on criteria.
- Integrate with SaaS applications with signals from Data 360.
- Trigger serverless functions that work with a webhook based on insights in Data 360.
- Connect multicloud workflows or services when useful events happen in Data 360.
- Push unfiltered insights and engagements to your data lake for analysis and storage.
When you publish an event to Salesforce Platform using a data action, Salesforce uses the standard event `DataObjectDataChgEvent` for publishing messages.
If the event is published to the home org or a companion org, Data 360 doesn't enforce publishing limits or allocation limits, particularly when the event is consumed on the platform (for example, via Flows). However, Data 360 enforces delivery allocation limits when the event is being delivered outside of the platform to an external subscriber, such as Mulesoft and AWS Lambda.
When you publish an event to Salesforce Platform Event through a Data Cloud-triggered flow, it uses the data action functionality. The data action record home page displays the published record as Flow Integration under the Managed By column.
To use a data action, first create the data action target that receives the results.
- **[Data Action Targets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_action_target_in_customer_data_platform.htm&release=264.0.0&type=5)**
The result of a data action is triggered in a data action target. The target receives the data action in near real time. You can send a data action to a target to drive event-based orchestration.
- **[Enrich Data Actions in Data 360 with Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_actions_data_graph.htm&release=264.0.0&type=5)**
You can enrich a data action in Data 360 with related data graph attributes by including the data graph as a related object.
- **[Create a Data Action in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_action_in_customer_data_platform.htm&release=264.0.0&type=5)**
Use a data action to send an alert or event to targets such as Salesforce Platform, Webhook, or Marketing Cloud Engagement, or Amazon Kinesis. Create the data action to focus on near real-time events and insights at different levels, including the channel, product, account, service, or individual.
- **[Create a Vector Search Data Action in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_vector_search_data_action.htm&release=264.0.0&type=5)**
Create a vector search data action to act on the unstructured data in near real time and send an alert or an event.
- **[Create a Real-Time Data Action in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_real_time_data_action.htm&release=264.0.0&type=5)**
Create a real-time data action to send an alert or an event and get responses in real time. Use a real-time data action to focus on real-time events and insights at different levels, such as the channel, product, account, service, or individual level.
- **[Integrating Data 360 Data Actions with Flow](https://help.salesforce.com/s/articleView?id=data.c360_a_integrate_salesforce_cdp_data_actions_with_salesforce_flow.htm&release=264.0.0&type=5)**
Data 360 data actions can send streaming events and insights to Salesforce Flow to drive an orchestration. An orchestration uses stages, steps, and decisions to organize complex business processes.
- **[Troubleshoot Data Action Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_data_action_troubleshooting.htm&release=264.0.0&type=5)**
Get tips for solving the most common data action and data action target errors.
- **[Billing Considerations for Data Actions](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_actions.htm&release=264.0.0&type=5)**
Use of Data Actions impacts the consumption of credits in these usage types.
#### See Also
- [_Salesforce Help_: Platform Event Allocations](https://developer.salesforce.com/docs/atlas.en-us.248.0.platform_events.meta/platform_events/platform_event_limits.htm)
# Data Builds the Foundation for Marketing
Data 360 works together with Marketing Cloud Next to help marketers build and optimize marketing campaigns with personalization, AI, and data-driven insights.
## About Marketing Cloud Next
Marketing Cloud Next brings the power of the platform to your team’s marketing efforts. You can integrate multiple data sources with Data 360, build content with Experience Cloud, power complex customer journeys with Flow Builder, and optimize with Agentforce along the way.
## Working Together
Marketing Cloud Next relies on Data 360 for certain functionality, such as segmentation. Although a marketer can accomplish their tasks in the Marketing app, some admin and data tasks require visiting the Data 360 app to complete.
By default, the Marketing app includes these Data 360 tabs.
- Identity Resolutions–Admins use identity resolution to build rulesets that dictate how incoming data is unified for marketing use.
- Segments–Marketers use segments to identify target audiences for marketing campaigns.
- Profile Explorer–Marketers use Profile Explorer to review how data relates to unified account and unified individual records.
For other data tasks, visit the Data 360 app or ask an admin to add the tabs to the Marketing app. These Data 360 tabs are useful for a marketing admin.
- Data Streams–During setup, an admin deploys data streams that connect Marketing Cloud Next with Salesforce CRM and other external client apps.
- Data Graphs–An admin can configure data graphs that provides the customer and product data used in basic content personalization.
- Data Lake Objects and Data Model Objects–A data analyst reviews and configures object fields and mappings that store ingested data.
- Data Model–A data analyst creates custom objects and builds or reviews object relationships.
## Considerations
Before you enable or use Marketing Cloud Next, review these considerations.
- Some marketing tasks, such as data ingestion, segmentation, and sending test emails, use consumption-based pricing. Agentforce features also consume credits.
- A default data space is created when you first enable Marketing Cloud Next. Most marketing features are preconfigured to work with this data space. When using a custom data space, marketing users must remember to select the correct data space during certain tasks.
- To ingest and map data for Marketing Cloud Next, use a unique identifier that relates to a primary key in each DMO or source table. For example, to map people data from CRM, map Lead ID to Individual ID.
- If you use Data 360with Marketing Cloud Engagement, we recommend that you select Subscriber ID as the primary key for people data.
## Resources
Learn more about how Data 360 and Marketing Cloud Next work together.
# Data Cleansing and Preparation
Cleaning and preparing your data is crucial for success when using the Data 360 segmentation and activation capabilities.
### Required Editions
Available in: Lightning Experience
After ingesting your data into Data 360, use the library functions, operators, and raw data fields to prepare for data mapping.
- **[Streaming Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_overview.htm&release=264.0.0&type=5)**
A streaming data transform reads one record in a source object, reshapes the record data, and writes one or more records to a target object. The source and target objects must be different objects. A streaming data transform runs continuously as a streaming process, picking up new or changed data.
- **[Batch Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_overview.htm&release=264.0.0&type=5)**
To transform your data for further usage, such as identity resolution, segmentation, or calculated insights, or to derive insights in Salesforce reports, use a batch data transform. A batch transform is a repeatable series of operations that you can run when data updates. The first time you run a batch data transform, it pulls in data and defines it according to your steps. You can then run a transform manually or set it up to run at scheduled intervals.
- **[Billing Considerations for Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_transforms.htm&release=264.0.0&type=5)**
Data Transforms use Data 360 to cleanse, enrich, and reshape data from DLOs and DMOs to prepare it for insights, segmentation, and AI features. Use of Data Transforms impacts the consumption of credits in these usage types.
- **[Create a Data Transform Platform Event Flow](https://help.salesforce.com/s/articleView?id=data.c360_a_transform_platform_event_flow.htm&release=264.0.0&type=5)**
Create a platform-triggered flow for data transform event actions.
- **[Create a Data Transform Record Event Flow](https://help.salesforce.com/s/articleView?id=data.c360_a_transform_record_event_flow.htm&release=264.0.0&type=5)**
Create a record-triggered flow for data transform event actions. With a record-triggered flow, you can update another record, send a notification, or initiate a process.
- **[Normalized and Denormalized Data](https://help.salesforce.com/s/articleView?id=data.c360_a_normalized_and_denormalized_data.htm&release=264.0.0&type=5)**
Data originates from multiple sources and can be normalized or denormalized. The Data 360 standard data model is normalized, so incoming data must be normalized before it can be mapped to the data model. Because not all source systems provide normalized export options or normalize data, assess your field-level data to establish how to transform and map the source data to the standard data model.
- **[Normalize Denormalized Data Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_uc_normalize_denormalized_data_from_marketing_cloud.htm&release=264.0.0&type=5)**
In this use case, the data comes from a single Marketing Cloud Engagement data extension but must be normalized to map to the Data 360 data model objects (DMO).
# Data Cloud Governance Feature Availability by License
Salesforce offers a tiered licensing model for data governance within Data 360, enabling customers to scale from foundational governance to advanced, AI-driven controls. Understand which data governance features are available with which Data Cloud license.
## Features Available to All Data 360 Orgs
The following governance features are included at no extra cost with the standard Data Cloud license.
Feature Area
Description
Access Control
Object-level security (OLS), field-level security (FLS), row-level security
(RLS), and RLS with joins (structured data only)
OLS and FLS support for unstructured data
Tagging
Manual tagging of data for governance
Permission Models
Additive permission sets for role-based and attribute-based governance
## Features Included in Data 360 Dynamic Data Masking
Protect structured data in real time with dynamic masking. These features are only available with an add-on license.
| Feature | Description |
| --- | --- |
| AI-Assisted Tagging | Identifies sensitive fields for masking using AI for structured data |
| Dynamic Masking | Obfuscates sensitive data in real time based on role or context (for example, Personally Identifiable Information (PII) masking) for structured data |
| Automatic Content Tagging (Beta) | Automatically applies tags to unstructured files based on a configurable confidence threshold. Tags that meet or exceed the threshold are auto-approved, while others require manual review. |
## Licensing Requirements
| Governance Capability | Included with Data CLOUD | Included in Dynamic Data Masking |
| --- | --- | --- |
| OLS / FLS / RLS (Structured) | Yes | No |
| RLS with Joins (Structured) | Yes | No |
| OLS / FLS (Unstructured) | Yes | No |
| Manual Tagging | Yes | No |
| AI-Assisted Tagging | No | Yes |
| Dynamic Masking (Structured) | No | Yes |
# Data Cloud License Billing and Limits
Adding a Data Cloud license enables Data 360 on a Salesforce org. Orgs with this license purchase consumption credits which are consumed by use of Data 360 services.
Depending on when you purchased or renewed your Data Cloud license, your org consumes either Data Services credits or Flex Credits for Data 360 services. Review Digital Wallet to determine which type of credits apply to you.
- **[Flex Credits Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_flex_credits_for_data360.htm&release=264.0.0&type=5)**
Usage of certain Data 360 features impacts credit consumption. To monitor your usage in Flex Credits usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.
- **[Data Services Billable Usage Types for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5)**
Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.
- **[Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5)**
Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.
#### See Also
- [_Salesforce Help_: Data 360 Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&release=264.0.0&type=5 "Data 360 is available in several supported Salesforce editions. Some Data 360 features also require additional licenses.")
- [_Salesforce Help_: Data 360 Profiles Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_d360_profiles_overview.htm&release=264.0.0&type=5 "Data 360 Profiles and Data 360 Enterprise Profiles licenses can be added on to Data Cloud licenses to change how a Data 360 org is billed and limited. When a Data 360 org has this license, its unified profiles, segments, data transforms, and insights are limited but don't consume credits.")
# Data Cloud One
Streamline multi-org architecture and simplify Data 360 access with Data Cloud One. Data Cloud One allows users of connected companion orgs to access data and Data 360 features from one unified Data 360 home org.
Get Started with Data Cloud One
| Description | |
| --- | --- |
| Evaluate if Data Cloud One is right for you. | Salesforce Blog: [Redefining Multi-Org Strategy for Salesforce Admins](https://admin.salesforce.com/blog/2024/redefining-multi-org-strategy-with-data-cloud-one) |
| Learn how Data Cloud One helps your company implement Data 360 faster. | Trailhead: [Data Cloud One](https://trailhead.salesforce.com/content/learn/modules/data-cloud-one-quick-look) |
| Learn best practices for multi-org setup. | Salesforce Help: [Data 360 Architecture](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_architecture_strategy.htm&type=5&language=en_US) |
| Connect orgs with Data Cloud One. | Salesforce Help: [Data Cloud One Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connections.htm&language=en_US&type=5) |
- **[Data Cloud One Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connections.htm&release=264.0.0&type=5)**
With a Data 360 companion connection, you can create a bidirectional connection between a single Data 360 and one or more Salesforce orgs. Companion connections build on the capabilities of standard connections and sync unified data back to the companion Salesforce org. With a companion connection, your Salesforce orgs get a 360 degree view of their customers built with data from all your company's data.
# Data Cloud One Companion Connection Statuses
These statuses indicate how companion connections are functioning.
## Connection Status
The connection status indicates the status of the Data 360 home org's connection to a companion org.
- Connecting—The initial connection is in progress. Check back later to get an updated status.
- Incomplete—The connection was set up, but no data space has been shared. The connection isn’t activated until a data space is shared.
- Active—The connection is complete and functioning.
- Inactive—The connection is no longer functioning because the Data 360 license on the home org expired or the companion org is no longer active. For example, if the companion org is a trial org that has expired, the connection is inactive. To resolve this status, renew the home org's Data 360 license, reactivate the companion org, or disconnect the companion org.
## Initialization Status
The initialization status is specific to a data space shared with a companion org. The status indicates whether the Data 360 home org successfully created a data space on the companion org and completed an initial sync.
- Activating—The initial sync between Data 360 and the companion org is in progress. The initial sync can take some time.
- Active—The initial sync completed successfully.
- Error—An error occurred during the initial sync, so the sync isn’t completed. Create a support ticket for help.
- Removing Sharing—The data space is being removed from the companion org. When you unshare a data space, data in that data space is also removed from the companion org. Removing a data space can take up to 30 minutes.
## Metadata Sync Status
Indicates the status of regular metadata syncing between the Data 360 home org and the companion org.
- Error—The last sync failed, and metadata syncing is paused. To resume syncing, download the error log and resolve the errors. In the case of a metadata conflict, resolve the conflict, and try again.
- In Progress—A sync was in progress when the page loaded.
- Pending—The number of changes to be synced in the next round of syncing. This status shows after metadata changes are made and remains until sync completes, and sync timing varies.
- Schema Version Error—The syncing of changed metadata is paused because of a schema version mismatch between the two orgs. Already synced metadata remains fully usable. Syncing resumes automatically after the schema version mismatch is resolved. Download the error log from the companion org for more details. For more information, see [Version Mismatch Errors in Data Cloud One Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_version_mismatch.htm&language=en_US&type=5).
- Succeeded—The last set of syncs completed successfully.
# Data Cloud One Companion Connections
With a Data 360 companion connection, you can create a bidirectional connection between a single Data 360 and one or more Salesforce orgs. Companion connections build on the capabilities of standard connections and sync unified data back to the companion Salesforce org. With a companion connection, your Salesforce orgs get a 360 degree view of their customers built with data from all your company's data.
When you create a Data 360 companion connection, a standard Salesforce CRM org connection is also created. If you already have a standard CRM connection to the org that you're connecting to, the standard connection's name is updated to match the companion connection's name.
- **[Convert a Data Cloud Home Org to a Data Cloud One Companion Org](https://help.salesforce.com/s/articleView?id=data.c360_a_prepare_home_org_for_dcone.htm&release=264.0.0&type=5)**
To convert a home org into a companion org, first remove all Data Cloud data from your org, then connect it as a companion org to a different Data Cloud instance. You can’t convert an org that has Data Cloud enabled.
- **[Set Up a Data Cloud One Companion Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connection_setup.htm&release=264.0.0&type=5)**
Establish a Data Cloud One Companion connection between the Data 360 org and another Salesforce org. You can't create a companion connection to a Salesforce org that's already connected to another Data 360 via a companion connection. You also can't connect a sandbox org to a production org.
- **[Monitor Data 360 Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_monitoring.htm&release=264.0.0&type=5)**
Review the status of Data 360's connections, and check which data spaces are shared with each companion org.
- **[Delete a Companion Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connection_delete.htm&release=264.0.0&type=5)**
To prevent errors in a companion org, address your multi-org data dependencies before deleting a companion connection. If you try to disconnect a companion org that has dependencies, Data 360 shows you the existing dependencies.
- **[Resolve Connection Errors in Data Cloud One Sandbox Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_resolve_connection_errors_in_a_dcone_sandbox.htm&release=264.0.0&type=5)**
Establish a Data Cloud One connection from a home org sandbox to a companion org sandbox using the same steps as with production orgs. The connection succeeds when there’s no metadata drift between the orgs. If metadata drift occurs, delete the specified drifted entities in the error log in the companion sandbox to establish the connection. Manual cleanup of all Data 360 metadata isn’t required.
- **[Considerations for Data Cloud One in a Sandbox Org](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_sandboxes.htm&release=264.0.0&type=5)**
Avoid common mistakes by reviewing these considerations before setting up a Data Cloud One cluster. Create sandbox orgs from your production orgs before establishing Data Cloud One connections, or clean up Data 360 metadata before recreating your Data Cloud One cluster. You can’t use Data Cloud One to connect a sandbox org to a production org.
- **[Access Data Cloud One from a Companion Org](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_app.htm&release=264.0.0&type=5)**
The Data Cloud One app is available in place of the Data 360 app on companion orgs. Use it to access Data 360 features such as profile explorer.
# Data Cloud One Support for Data Graphs
Access data graphs from a companion org through the Data 360 Companion app. From the Data Graphs tab, you can view a list of available data graphs and select any graph to explore its structure, selected fields, JSON preview, and filter settings.
### Required Editions
From the home org, you can continue to create and manage data graphs using the same workflows you're familiar with. From a companion org, you have read-only access to data graphs. Access Data Graphs from other key tabs in a companion org, such as Query Editor. Although you can't edit the data graphs, you can still use them to better understand the data model and ground your prompts with existing data.
# Data Drift in High-Frequency Data Graph Refreshes
When you schedule a data graph to refresh more frequently than once per day, you can experience data drift. Data drift occurs when rapid refresh cycles don’t fully capture or reconcile updates from the source system, causing temporary inconsistencies in the data graph.
### Required Editions
A full refresh automatically runs once every 24 hours and corrects any drift that occurs during more frequent refresh cycles.
## What Causes Data Drift
Data drift can occur when the data graph is refreshed multiple times before a full refresh completes. Common causes include:
- Partial Updates: If records in the source system change several times within a day, not all updates appear in the data graph until the full refresh runs.
- Deleted or Modified Records: Records that are deleted or changed in the source remain in the data graph until the next full refresh reconciles them.
- Complex Relationships:When related data or join keys are updated, mismatched or duplicate nodes can appear in the graph until the full refresh reprocesses all data.
- Hierarchical Dependencies: Drift can also occur when updates arrive for deeper-level nodes before their parent nodes exist in the system. In such cases, child records temporarily appear as unmatched or missing relationships until the parent nodes are processed during the full refresh.
## How Data Drift Is Corrected
A scheduled daily full refresh reprocesses all data from the source and realigns the graph with the most recent state of your data. This process removes any inconsistencies, duplicates, or outdated records that appear during high-frequency refresh cycles. As a best practice, use higher-frequency refreshes only when near-real-time data is required and temporary inconsistencies are acceptable.
# Data Drift in Incremental Runs
When running a batch data transform in incremental mode, data drift can cause output objects to include changed records instead of filtering them out or replacing them. Data drift is corrected in the daily scheduled full run.
Data drift occurs in these situations.
- When filtering on values to remove records from the output, an updated record isn’t filtered out if the value that was changed now meets the removal criteria. The updated record is filtered out in the next full run.
- If a value in a column that’s mapped to a primary key column changes, the updated record is treated like a new record because the updated record’s generated primary key is different from the original key. In this scenario, the output of the incremental run retains one record with the original generated primary key and one record with the updated key until the next full run.
To correct data drift, a full run occurs every 24 hours.
# Data Ethics
Earning and keeping customer trust increasingly means adopting data ethics best practices when using Data 360.
Data ethics are moral guideposts about the gathering, protection, and use of personally identifiable information and how that affects individuals.
## Use and Collect Individual Information Appropriately
Give customers control of their preferences. Customers must have a say in how you use their data. Most importantly, after they provide you with their preferences, be sure to honor them. Data 360 helps you build a unified profile of customers, to better help you track and honor their preferences throughout all your Omni-Channel marketing practices.

Note Learn how to develop a [custom preference center](https://trailhead.salesforce.com/content/learn/modules/custom-preference-center-development).
## Provide Clear Exchange of Value for Data
Provide clear benefits in exchange for data. What do they get in return? Customers provide data in order to improve their customer experience and make them feel like they matter.

Example Add convenience by providing recommendations for frequently purchased items. Thank them for community involvement by sending a special offer. Or drive awareness by offering new products or complementary products of interest.
## Treat Sensitive Data Carefully
Some data types are more sensitive than others. We can’t give you a definitive list of sensitive data points, but we advise you to carefully consider asking for data such as age, gender, or ethnicity. Ultimately it’s up to you and your organization to define sensitive data and determine the reasons you’re asking for it. Other sensitive data to consider excluding: protected status (race, health, veteran, disability, and so on), gender identity, sexual orientation, religion, ethnicity, citizenship, and political affiliation.
## Collect and Use Only What You Need
Limit the use of your data to only what is needed to create more personalized experiences for your customers. Less is more, especially when it comes to demographic, socioeconomic, behavioral, and transactional data.
## Choose Partners Carefully
In addition to being mindful and intentional about selecting and ingesting first- and third-party data, be intentional about activating that data through various ad platforms. When engaging with an activation partner, ensure that you understand the chain of custody for data being provided to the partner. What happens after the activation partner uses the data for your campaign? Is it deleted? Reused? Review each contract with your activation partners to ensure that there are clear obligations with respect to the care, custody, and control of any data sent to the partner.

Note View the [Data 360: Guide to the Value of Ethical Data Partnerships](https://sfdc.co/cdp_ethics) guide.
# Data Explorer
With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.
If you don’t see Data Explorer, contact your admin to enable Data Explorer permissions.
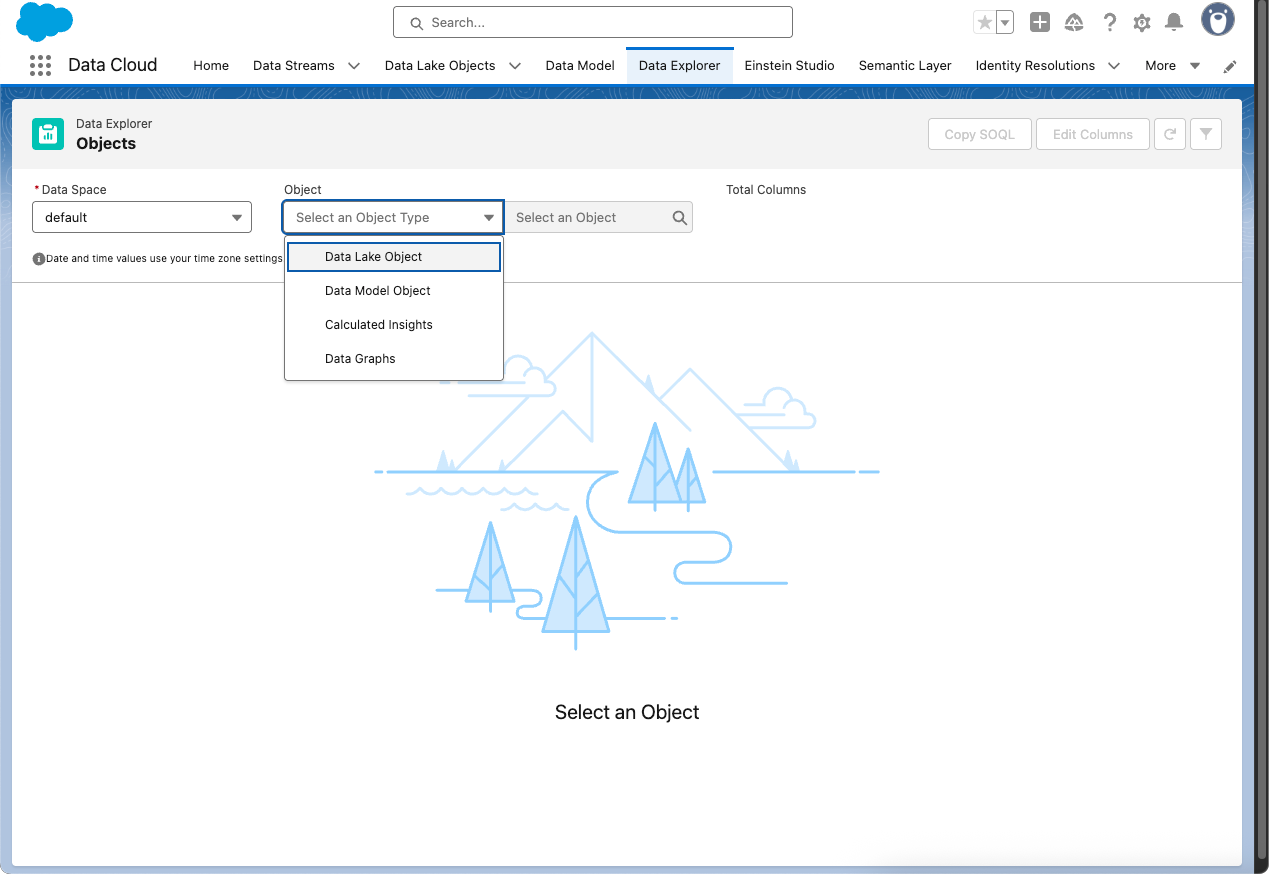
- **[View Your Data in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_your_data.htm&release=264.0.0&type=5)**
In Data Explorer, you can view Data 360 data from your data lake objects (DLOs), data model objects (DMOs), calculated insight objects (CIOs), or data graphs. You can personalize your view by editing the columns and use filters to show only the most relevant data for the selected object.
- **[Data Explorer Columns and Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_data_explorer_columns.htm&release=264.0.0&type=5)**
You can personalize your data view in Data Explorer to show only the most relevant data for your selected object in Data 360. You can show up to 10 columns, which are organized alphabetically by default. You can sort the column data in ascending or descending order.
# Data Explorer Columns and Filters
You can personalize your data view in Data Explorer to show only the most relevant data for your selected object in Data 360. You can show up to 10 columns, which are organized alphabetically by default. You can sort the column data in ascending or descending order.
After selecting your object type and object, your data appears on the Data Explorer dashboard. You can edit columns to change the data that appears for that object. For a calculated insight object, include at least one dimension and one measure for your columns.
You can add a filter to your data to show or exclude values. Select the filter icon to add a filter. You can use these operators when building the filter logic. Don’t use commas with numbers in the Value field. For example, use 1000, not 1,000. Strings in the Value field are case-sensitive.
Operator
Description
equals
Use the 'equals' operator to evaluate if the value of the selected
field equals the specified input value. For example, if you want to select
all the records where Account is 100001, then use 'equals' operator and
supply 100001 as input Value.
not equals
Use the 'not equals' operator to evaluate if the value of the selected
field isn’t equal to the specified input value. For example, if you want to
select all the records where Account isn’t equal to 100001, then use 'not
equals' operator and supply 100001 as input Value.
greater than
Use the 'greater than' operator to evaluate if the value of the
selected field is greater than the specified input value. For example, if
you want to select all the records where Account is greater than 100001,
then use 'greater than' operator and supply 100001 as input Value.
greater than or equal to
Use the 'greater than or equal to' operator to evaluate if the value of
the selected field is greater than or equal to the specified input value.
For example, if you want to select all the records where Account is greater
than or equal to 100001, then use 'greater than or equal to' operator and
supply 100001 as input Value.
less than
Use the 'less than' operator to evaluate if the value of the selected
field is less than the specified input value. For example, if you want to
select all the records where Account is less than 100001, then use 'less
than' operator and supply 100001 as input Value.
less than or equal to
Use the 'less than or equal to' operator to evaluate if the value of
the selected field is less than or equal to the specified input value. For
example, if you want to select all the records where Account is less than or
equal to 100001, then use 'less than or equal to' operator and supply 100001
as input Value.
like
Use the 'like' operator to evaluate if the value of the selected field
matches the characters of the text string in the specified input value. The
'like' operator supports only text data types. The operator provides a
mechanism for matching partial text strings and includes support for '%'
wildcard. For example, 'appl%' matches appleton, apple, and appl, but
not Bappl.
in
Use the 'in' operator to evaluate if the value of the selected field is
in a comma-separated list. The 'in' operator doesn't support date
and datetime data types. For example if you want to select all records from
certain countries in APAC Region you can use 'in' operator and specify the
list of countries like Japan, Taiwan, S Korea.
not in
Use the 'not in' operator to evaluate if the value of the selected
field is not in a multivalue comma-separated list. The 'not in'
operator doesn't support date and datetime data types. For example if you
want to omit all records from certain countries in APAC Region you can use
'not in' operator and specify the list of countries like Japan, Taiwan,
S.Korea.
# Data Extension Considerations for Data 360
If you ingest a data extension into Data 360, you should be aware of some core functionality within Marketing Cloud Engagement and how they operate within Data 360.
## Structure
In Marketing Engagement, orgs are divided into business units, which is the hierarchical structure that controls role-based access to data.
Data extensions can belong to one business unit, multiple business units, or they can be shared across business units.
To view a data extension, select an associated business unit in the context filter dropdown. The business unit dictates the cascaded folder hierarchy.
## More Considerations
- After data extension configuration, don't change the schema. Data 360 doesn't support schema changes.
- You can only request one data extension at a time.
- Date field types in data extensions appear in YYYY-MM-DD format in Data 360.
#### See Also
- [_Salesforce Help_: Data Extensions with Enhanced Subscriber Features in Marketing Cloud](https://help.salesforce.com/s/articleView?id=mktg.mc_es_de_enhanced_subscriber.htm&type=5&language=en_US)
- [_Salesforce Help_: Data Extensions in Contact Builder](https://help.salesforce.com/s/articleView?id=mktg.mc_cab_data_extensions.htm&type=5&language=en_US)
# Data Federation, Ingestion, and Modeling
Data federation and data ingestion bring data from external data sources into Data 360. Data modeling is the next important phase to process data in Data 360.
Data federation in Data 360 allows you to set up connectivity with external data sources and consume data without copying it into Data 360. You create and deploy a data stream that in turn creates an external data lake object (DLO). The DLO acts as a reference, and points to the data physically stored in an external data source.
In data ingestion, data from a data source is brought in as is, meaning that fields and their data types are imported without transformation. You create a data stream to bring in the data into Data 360. Data ingested by all data streams is written to data lake objects (DLOs).
During data modeling, the preserved source schemas are harmonized into standard or customizable data models. The data models are based on [Customer 360 Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_c360datamodel.htm&release=264.0.0&type=5 "The Customer 360 Data Model reduces the complexities of integrating data across cloud applications by providing standardized data guidelines. Extend the data model to create data lakes, generate analytics, train machine-learning models, build a single view of the customer, and more.") that describes the data with well-defined standardized data guidelines. In this phase, connections are created between related data brought from disparate sources by mapping DLOs to data model objects (DMOs). A DMO is a grouping of data created from data streams, insights, and other data sources.
- **[Zero Copy Data Federation Supportability](https://help.salesforce.com/s/articleView?id=data.c360_a_byol_data_federation_supportability.htm&release=264.0.0&type=5)**
Refer to the list of supported and unsupported features of Data 360 when you use zero copy data federation.
# Data Flow
Use the power of Data 360 data in and out of Data 360. Data can be ingested and stored in Data 360 or can be connected via metadata and queried without storage.
## Data Sources
Data sources are ingested into or connected to Data 360 in various ways. Ingested data sources include:
- Salesforce Connectors
- Connector Services
- Connectors and Integrations
Data from those sources is ingested as either streaming or batch data. Near-real time web engagement data is an example of streaming data.
## Data Targets and Data Shares
After data is manipulated, harmonized, or segmented in Data 360, data can be sent to targets (1) such as an SFTP (2) or shared with integrations, such as Snowflake.
Targets are used to:
- Activate segments to Marketing Cloud Engagement, Amazon S3, SFTP, Google Cloud Storage (GCS), and Microsoft Azure Blob Storage.
- Activate segments to advertising platforms, such as Meta
- Perform tasks in Sales or Service Cloud using data actions
- Analyze data within tools like Tableau or CRM Analytics
Specific functions are associated with targets. Activation targets are created to share audience segments and data action targets are created to initiate an action based on data.
Data Shares allows you to share Data 360 data with external platforms outside of Salesforce, for example, with Snowflake.
# Data Foundation Considerations and Best Practices
Generally, we recommend using the Individual portion of your data foundation as much as possible. When executing a journey that uses content personalization or decisioning attributes from the Unified Individual portion of the data foundation, keep these considerations and best practices in mind.
## Using the Wrong Context of a Person
A Unified Individual is created by relating separate Individuals that have been imported from different external data sources. As part of the import process, some imported fields, such as First Name, can have different values from each data source. Customers define reconciliation rules as part of [Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules.htm&release=264.0.0&type=5 "Match rules tell Data 360 which profiles to unify during the identity resolution process. Each match rule contains one or more criteria. Profiles are matched when all criteria within a match rule are satisfied.") and prioritize which data source value to use when activating an audience to Marketing Cloud Engagement.
Your reconciliation rules could result in messaging a person using the wrong context. For example, a person buys themselves a gift for home and receives an email confirmation on their personal email. However, the email content is personalized with the wrong shipping address (uses their work shipping address instead of home address).
Example:
- Each brand within Cumulus has a different external system, each importing data to Data 360. The person John Smith signed up for the Cumulus email newsletter with Brand A of the company. Separately, John Smith later signed up with Brand B. Finally, John Smith eventually signed up on a mobile app with Brand C.
- The Unified Individual for John Smith can have 3 separate Individuals from 3 different systems: “John.Smith.1” (System A from Brand A), “John.Smith.2” (System B from Brand B), and “John.Smith.3” (System C from Brand C). Each system imports a different Full Name, contact point, contact point preference, lifetime value, and loyalty level for John Smith.
- To prioritize the values used as part of activation, Cumulus must create Reconciliation Rules to define how Data 360 selects the value from a shared field. In this example, Cumulus selects to prioritize the Email Address from System A (Brand A), the Full Name value that comes from System C (Brand C), the Contact Point Preference that comes from System A (Brand A), and the most recently updated system value for Lifetime Value and Loyalty Level (System A, B or C).
Records Imported and Prioritized in Data 360
| Source System | Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- | --- |
| System A from Brand A | John.Smith.1 | js@example1.com | John Smith | Promotional | 20 | Bronze |
| System B from Brand B | John.Smith.2 | js@example2.com | John Smith, Jr. | Transactional | 30 | Silver |
| System C from Brand C | John.Smith.3 | js@example3.com | Johnny Smith | Don't Message | 50 | Gold |
| **_Reconciliation Rule_** | **_N/A_** | **_Source Priority Order: System A_** | **_Source Priority Order: System C_** | **_Source Priority Order: System A_** | **_Last Updated_** | **_Last Updated_** |
To create an aggregate representation of the person John Smith in a single data extension for the data foundation, Cumulus segments and activates at the Unified Individual level. The resulting data extension contains one row, with each attribute either selected from one of the three Individual profiles (prioritized based on their Reconciliation Rules) or aggregated among them (from a Calculated Insight).
Activated Individual for Marketing Cloud Engagement Data Foundation
| Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- |
| John.Smith.1 | js@example1.com | John Smith | Promotional | 100 | Bronze |
| **_Source Priority Order: System A_** | **_Source Priority Order: System A_** | **_Selected by Reconciliation Rule: Prioritize System C_** | **_Selected by Reconciliation Rule: Prioritize System C_** | **_Created by Calculated Insight_** | **_Selected by Reconciliation Rule: Last Updated_** |
If Cumulus launched a net-new journey that uses only the Unified Individual portion of the data foundation, then it could lead to a confusing experience for John Smith because of the contextual difference between the contact point selected and the personalization or decisioning attributes assigned to them in the data extension.
In this case, the person John Smith would receive a message to js@example1.com from Brand A using the Full Name Johnny Smith, which John Smith only ever submitted when signing up with Brand C. Or, Cumulus could decision a journey based on the Silver loyalty level, which would be wrong in this context (John.Smith.1 was Bronze) or wrong in aggregate (the highest value in the Unified Individual is Gold).
Alternatively, if Cumulus used the Individual portion of their data foundation (example below) for some elements of their campaign, such as the content personalization for Full Name. In this case, the person John Smith receives a message to js@example1.com from Brand A using the Full Name John Smith, the same value that had submitted when signing up with Brand A.
Activated Individual for Marketing Cloud Engagement Data Foundation
| Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- |
| John.Smith.1 | js@example1.com | John Smith | Promotional | 20 | Bronze |
| John.Smith.2 | js@example2.com | John Smith, Jr. | Transactional | 30 | Silver |
| John.Smith.3 | js@example3.com | Johnny Smith | Don't Message | 50 | Gold |
## Missing Data About a Person
You can activate Data 360 at both the Individual level and Unified Individual level. At the Individual level, each instance of a person is activated from each data source. In comparison, the Unified Individual level uses pieces from multiple data sources. When you’re using a Unified Individual, Data 360 selects a single identifier from one of its related Individuals. However, the identifier used to represent a person in your data foundation can be different than the identifier used for the person in the subsequent journey. As a result, your journey lookups, such as decision splits, might not be able to find data about the person in the Unified Individual portion of the data foundation. This scenario is more common for event-based journeys triggered from third parties, which often lack the context of which identifier is used to represent the Unified Individual in the data foundation. But, this scenario can also occur with audience-based journeys.
Example: Each Cumulus brand has a different back end, each importing data to Data 360. The person John Smith signed up for the Cumulus email newsletter with Brand A. Separately, John Smith later signed up with Brand B. Finally, John Smith signed up on the Cumulus mobile app with Brand C. As a result, the Unified Individual for John Smith has three separate Individuals from three different systems: John.Smith.1 (System A from Brand A), John.Smith.2 (System B from Brand B), and John.Smith.3 (System C from Brand C). Each Individual has a different full name, contact point preference, lifetime value, and loyalty level and a unique send address.
Individual Records Imported to Data 360
| Source System | Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- | --- |
| System A | John.Smith.1 | js@example1.com | John Smith | Promotional | 20 | Bronze |
| System B | John.Smith.2 | js@example2.com | John Smith, Jr. | Transactional | 30 | Silver |
| System C | John.Smith.3 | js@example3.com | Johnny Smith | Don't Message | 50 | Gold |
Then, Cumulus activates its full audience at the Unified Individual level to use for its data foundation. Due to the nature of the Unified Individual, only one record for the person John Smith is activated (John.Smith.1), using attributes sourced from different Individuals or aggregated among them.
Activated Individual for Marketing Cloud Engagement Data Foundation
| Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- |
| John.Smith.1 | js@example1.com | John Smith | Promotional | 100 | Bronze |
| **_Source Priority Order: System A_** | **_Source Priority Order: System A_** | **_Selected by Reconciliation Rule: Prioritize System C_** | **_Selected by Reconciliation Rule: Prioritize System C_** | **_Created by Calculated Insight_** | **_Selected by Reconciliation Rule: Last Updated_** |
**Activated Audience for Journey Builder Entry**
The Cumulus team from Brand B later creates a journey in Marketing Cloud Engagement and configures a decision split to look at the lifetime value of a person at the Unified Individual level. As part of the activation, Cumulus selects a contact point priority order for System B, resulting in an activation of Individual ID John.Smith.2.
In Marketing Cloud Engagement, when John.Smith.2 reaches the decision split, Journey Builder attempts to look up the corresponding lifetime value for that contact. However, Cumulus configured the decision split to look at the Unified Individual portion of the data foundation, which contains only a single row and identifier for John Smith (John.Smith.1). When Journey Builder attempts to make a decision split for John.Smith.2, it can’t resolve the lookup because that identifier isn’t within the Unified Individual portion of the data foundation. As a result, John.Smith.2 is exited from the journey.
Alternatively, Cumulus could use the Individual portion of their data foundation (example below) for their campaign. In this case, the Individual portion of the data foundation would contain all three unique identifiers for John Smith and, as a result, be able to resolve the lookup for John.Smith.2.
Activated Individual for Marketing Cloud Engagement Data Foundation
| Individual ID | Email Address | Full Name | Contact Point Preferences | Lifetime Value | Loyalty Level |
| --- | --- | --- | --- | --- | --- |
| John.Smith.1 | js@example1.com | John Smith | Promotional | 20 | Bronze |
| John.Smith.2 | js@example2.com | John Smith, Jr. | Transactional | 30 | Silver |
| John.Smith.3 | js@example3.com | Johnny Smith | Don't Message | 50 | Gold |
# Data Foundation Solution Workflow
Review the solution workflow for integrating your initial data foundation in Marketing Cloud Engagement.
Establish Data Foundation Requirements for Marketing Cloud
Engagement
Create Core Activations in Data 360
Link Core Activations to the Marketing Cloud Engagement Contact Model
Use Data from Data 360 Throughout Marketing Cloud
Engagement
Identify common content personalization and decisioning attributes used in Journey
Builder
Determine if you’re implementing a Core Audience Model or a Collective Core Audience
Model
Create a segment that represents your full audience in Data 360
Create Data 360 activations of your full audience to Marketing Cloud
Engagement
Activate commonly used personalization and decisioning attributes
Create Contact Model attribute groups in Marketing Cloud Engagement for each Data 360 activation grouping
Link the activated data extensions to the applicable Contact Model attribute group in
Marketing Cloud Engagement
Create one additional Contact Model attribute group in Marketing Cloud Engagement for ad
hoc campaigns
Audience-based journeys (data extensions for journey entry)
Event-triggered journeys (API-triggered journey entry)
# Data Governance Considerations
Before you begin, it’s important to review supported features and considerations for using data governance features in Data 360.
## Supported Features
Data governance tags and policies are supported in these Data 360 features.
- Data Cloud One: Data governance supports consistent tagging and policy management across both home and companion orgs. See [Tagging and Policy Management in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_governance.htm&language=en_US)
- DevOps Data Kits: You can include tags in a DevOps data kit, packaging them along with their associated standard and custom data model objects (DMOs), and merge them from a sandbox into a production org. This ensures consistent tagging across development and production environments. See [Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_data_package_kits.htm&type=5&language=en_US) and [Data 360 in a Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox.htm&type=5&language=en_US).
- Data 360 Sandbox: You can include tags in your sandbox environment and merge them into your production org, ensuring consistent tagging across development and production.
## General Considerations
- Assigning a data space through a permission set doesn’t automatically give users access to the data.
- Data 360 provides an Allow All policy (also known as a day zero policy) out of the box for both existing and new orgs.
- Admins need to delete the default Allow All policy to enable granular access control based on specific access requirements.
- Access to data in the data space is restricted unless a policy explicitly allows it.
- Row-level security policies are applied to queries. After a query passes the security checks for the objects and fields that it accesses, the row-level policy is applied to determine access.
- If row-level allow policies are created for an object, access to the data are limited to only those users who have a row-level allow policy.
## Creating Data Access Policies
These guidelines ensure that you can control data access in Data 360 based on defined policies.
- An Allow Policy:
- Grants the logged-in user read access to data and edit access to metadata for a resource, such as an object or a field.
- Grants access to all fields and records on the objects specified in the grant.
- A Deny Policy:
- Overrides all access, except for users with View All Records (VAR) Modify All Records (MAR) permission, who can bypass these restrictions.
- Denies the logged-in user access to the resource.
- If multiple policies apply to the same user, resource, and action, a deny policy takes precedence and denies access if it conflicts with any allow policy.
- Writing field-level deny policies that affect Primary Key and Fully Qualified Key fields can lead to unexpected results and isn't recommended.
- **[Impact of Custom Permissions on Policies](https://help.salesforce.com/s/articleView?id=data.c360_a_using_custom_permissions.htm&release=264.0.0&type=5)**
Custom permissions in Data 360 play a key role in determining how a policy is applied. You can assign them to users through custom permission sets or profiles to act as user attributes within the policy builder.
# Data Governance in Data 360
Data governance provides a robust framework for securing and managing data through the combined use of tags, classifications, user attributes, and policy-based governance. Enabling policies and other governance features improves control and ensures users have access to the right data at scale.
## About Data 360 Governance
Data governance is a set of rules for keeping your data safe and organized. It uses a combination of tools to make sure the right people can access the right data.
Data tagging is the process of attaching labels or metadata to data to identify and organize so it can be easily searched, filtered, and governed. Tags categorize data based on sensitivity or business relevance, and these tags form the basis for enforcing policies.
Data classification groups tags into categories based on its value, sensitivity, or regulatory requirements. For example, data can be classified as public, internal, confidential, or restricted.
Object-level security (OLS) and field-level security (FLS) policies in Data 360 are driven by tags and classifications, enabling scalable governance across a large number of objects and fields.
Data governance is scalable and automatic. When you ingest new data into Data 360, you just need to give it the correct tag. The existing rules automatically apply to it without any extra work. This makes managing data security more efficient, especially when dealing with large amounts of information.
- **[Get Started with Data Governance](https://help.salesforce.com/s/articleView?id=data.c360_a_getting_started_data_gov.htm&release=264.0.0&type=5)**
Before using Data Governance features, it's important to review the prerequisites and the steps required to enable governance across your organization’s data.
- **[Policy-Based Governance in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_based_governance_dg.htm&release=264.0.0&type=5)**
Data governance policies are rules and guidelines that define how data is accessed, used, protected, and managed. These policies help align data handling with security requirements, compliance standards, and business objectives.
- **[Data Tagging and Classification in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_using_tagging_and_classification_dg.htm&release=264.0.0&type=5)**
Data tagging is the process of attaching labels or metadata to data assets such as objects, fields, or records to describe their content, sensitivity, or purpose. Tags help identify and organize data so it can be easily searched, filtered, and governed.
- **[Viewing Data Relationships with Unified Lineage](https://help.salesforce.com/s/articleView?id=data.c360_a_viewing_data_lineage.htm&release=264.0.0&type=5)**
Unified lineage gives you a complete view of how your data objects are connected. Use it to understand data journeys, dependencies, and the downstream impact of changes such as applying tags or updating objects
- **[Controlling External User Access in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_control_external_user_access.htm&release=264.0.0&type=5)**
Use data governance policies to control what external users can access in your Data 360-powered apps. By defining clear, policy-based access, you make sure that unidentified external users and authenticated external users see only the data intended for them.
- **[Data 360 Governance Mergeback with DevOps Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_mergeback_devops_datakits.htm&release=264.0.0&type=5)**
Use sandboxes to develop and validate your data governance strategy, and then deploy it to production through mergeback. Mergeback is the process of moving validated metadata from a sandbox org back to a linked production org or another linked sandbox org. DevOps data kits move governance metadata between environments and maintain a consistent security posture.
# Data Governance Taxonomy
In Data 360 data governance, a taxonomy is a hierarchical set of categories and subcategories (or tags) that classifies data based on its type, sensitivity, usage, or domain. Using taxonomies ensures consistent tagging, improves data discoverability, and enables accurate application of policies such as masking or access control. They also help align data classification with privacy and compliance requirements.
In data governance, taxonomies can be preconfigured or custom, depending on the level of flexibility and control required.
Here’s an example of a taxonomy for personal data.
- Personal Information (Taxonomy)
- Contact Information (Parent Tag)
- Email Address (Child Tag)
- Phone Number (Child Tag)
- Identity Information (Parent Tag)
- Date of Birth (Child Tag)
- National ID Number (Child Tag)
- Passport Number (Child Tag)
- **[Preconfigured Taxonomies in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_preconfigured_taxonomies.htm&release=264.0.0&type=5)**
Preconfigured taxonimies are built-in, ready-to-use classification structures provided by the system. They cover common data categories such as personal information, financial data, or health records. Preconfigured taxonomies get you started quickly and follow standard best practices without the need to define categories from scratch.
- **[Create a Custom Taxonomy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_taxonomy.htm&release=264.0.0&type=5)**
Custom taxonomies allow you to define your own categories and subcategories based on your specific data, use cases, or business needs. You can create tags, group them into a hierarchy, and align them with internal policies or specialized regulatory requirements.
- **[Edit or Delete a Custom Taxonomy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_custom_taxonomy.htm&release=264.0.0&type=5)**
You can change the taxonomy's name and description. You can’t change the taxonomy type or its API name. You can't delete taxonomies that are used in policies. This includes default taxonomies provided by Data 360.
- **[Best Practices for Designing a Custom Taxonomy](https://help.salesforce.com/s/articleView?id=data.c360_a_best_practices_custom_taxonomy.htm&release=264.0.0&type=5)**
A well-structured taxonomy is essential for effective tagging and policy enforcement in Data 360.
# Data Graph Data Structures
Understand the underlying components of a data graph so that you can create and use data graphs effectively.
In Data 360, a data graph is built within a data space and must have one primary data model object (DMO). You select a DMO in the data space to use as the foundation for the data graph. The foundation DMO is the primary DMO. You can also add data from DMOs that are related to the primary DMO, which are called related objects, and from related calculated insights. You can include calculated insights and streaming insights in a data graph if they’re based on a DMO that’s also included in the data graph.
A primary DMO can belong to any category except Engagement, with the Profile category being the most common. Related object DMOs can belong to the Profile, Other, or Engagement category. You select fields from the primary DMO and its related objects to include in the data graph.
When you create the data graph, the selected objects and fields are transformed from their original hierarchical relationships into a single, flattened, read-only data graph record. The data graph record contains metadata, such as the data space and data graph names. It also includes data from the primary DMO and the related objects as a queryable JSON blob.

Note New real-time data graphs don’t support N:1 relationships between DMOs. If you attempt to add a DMO that creates an N:1 relationship, the system prevents the selection. Existing real-time data graphs that already include N:1 relationships continue to run. However, changes made to the parent DMO in an N:1 relationship aren’t immediately reflected in the real-time data graph.
## Example: How a Data Graph Is Constructed
This data graph has three DMOs. The primary DMO is Unified Individual. The Unified Link Individual DMO is a related object and a child of the Unified Individual DMO. The Individual DMO, which is a child of the Unified Link Individual DMO, is also selected as a related object. Each DMO has one or more fields selected. Taken together, the selected fields from these DMOs define the data graph’s JSON schema.
After the data graph is created, the schema determines which data is available in the JSON blob. The JSON of a typical data graph looks like this example.
```
{
"id__c":"4e5a4e98240a46ec891a6425429318bd",
"name__c":"Evrim",
"age__c":30.000000000000000000,
"ContactPointEmail__dlm":[
{
"id__c":"aaaa4e98240a46ec891a6425429318ba",
"emailid__c":"evrim@example.com"
},{
"id__c":"bbb4e98240a46ec891a6425429318bb",
"emailid__c":"evrim.doctorow@example.com"
}
],
"orders__dlm":[{
"order_id__c":1,
"order_date__c":"01-01-2023",
"order_price__c":1500.000000000000000000,
"items__dlm":[
{
"item_id__c":2.000000000000000000,
"item_name__c":"Mobile S20",
"item_price__c":900.000000000000000000
},{
"item_id__c":3.000000000000000000,
"item_name__c":"Mobile Samsung",
"item_price__c":600.000000000000000000
}
]
}
]}
```
#### See Also
- [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Data Graph Refresh History
Use Refresh History to see a list of recent refresh events associated with a specific data graph. Refresh information varies based on the refresh schedule selected for the data graph. The refresh history tab includes the most recent refresh runs.
### Required Editions
Available in: Lightning Experience
| Field Name | Description |
| --- | --- |
| Start Time | The start time of an hourly time window for aggregating record-level statistics, displayed in the time zone configured for your org. |
| End Time | The end time of an hourly time window for aggregating record-level statistics, displayed in the time zone configured for your org. |
| Run Status | The current status of the refresh activity. |
| Records Processed | The number of records that are refreshed in the data graph during the time window. |
- **[Data Drift in High-Frequency Data Graph Refreshes](https://help.salesforce.com/s/articleView?id=data.c360_a_dg_data_drift.htm&release=264.0.0&type=5)**
When you schedule a data graph to refresh more frequently than once per day, you can experience data drift. Data drift occurs when rapid refresh cycles don’t fully capture or reconcile updates from the source system, causing temporary inconsistencies in the data graph.
# Data Graph Statuses
Each data graph has two separate statuses: a status for metadata and a last run status for materialized data. These statuses work together to provide you with insight into the current configuration and refresh state of a data graph. Use them to monitor the data graph's lifecycle in Data Cloud, identify any issues, and determine if the data graph is ready for querying or further updates.
### Required Editions
When the two-status model is first enabled, some existing data graphs may still use the legacy consolidated status and will subsequently be migrated. If Status is None and Last Run Status contains another value, the data graph follows [Legacy Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graph_status.htm&release=264.0.0&type=5). Use the two status for granular data graph monitoring and perusal. Note that the Connect API will continue to return READY as Status on the connect APIs for the data graphs.
## Status
The current state of the data graph’s metadata.
- Draft: The data graph is a work in progress and not yet published. Editing is allowed.
- Processing: The data graph’s metadata is either syncing or updating.
- Error: The data graph wasn’t created. There can be several reasons for this, such as it failed to sync or encountered a configuration error. You can fix the error by clicking the Retry button.
- Active: The data graph is saved, published, and synced. The Connect API returns this status as Ready.
## Last Run Status
The outcome of the most recent data refresh run.
- None: No refresh is triggered. This can occur if the data graph is still in draft or syncing.
- Processing: A refresh run is currently in progress.
- Success: The most recent refresh completed successfully.
- Failure: The most recent refresh failed and no previous successful runs exist. You can fix the failure by clicking Refresh Now.
## How Statuses Impact Actions
The combination of your data graph's status and last run status determines which actions you can perform, such as editing the data graph or initiating a data refresh.
Status
Last Run Status
Allowed Actions
Draft
None
Processing
None
Clone
Delete
Update Status
Processing
In Progress
Clone
Delete
Update Status
Processing
Success
Clone
Delete
Refresh Now
Refresh History
Update Status
Processing
Failure
Clone
Delete
Refresh Now
Refresh History
Update Status
Active
Success
Edit
Clone
Delete
Refresh Now
Refresh History
Schedule
Update Status
Active
In Progress
Edit
Clone
Delete
Refresh History
Schedule
Update Status
Active
Failure
Edit
Clone
Delete
Refresh Now
Refresh History
Schedule
Update Status
Error
None
Edit
Clone
Delete
Schedule
Update Status
Error
Success
Error
InProgress
Error
Failure
Edit
Clone
Delete
Refresh Now
Refresh History
Schedule
Update Status

Note Editing a data graph updates only its metadata. An edit doesn't automatically trigger a data refresh. To get the updated data, wait for the next incremental refresh cycle (if enabled) or the 24-hour full refresh cycle, or click Refresh Now.
## Troubleshooting Data Graph Status Issues
Use the following guidance to identify and resolve common data graph status issues.
- Status Shows Error: The data graph metadata encountered an issue. For example, it failed to sync or had a configuration error. Click the **Retry** button. This triggers the metadata sync process again and attempts to recover the data graph.
- Last Run Status Shows Failure: The most recent refresh job failed. This can occur for an incremental refresh job (for example, if the data graph is scheduled to refresh every hour) or for a full refresh job. The data graph recovers from a Failure state in the following ways automatically:
- Manual: Click Refresh Now Clicking Refresh Now triggers a full refresh operation, which completely rebuilds the data graph from scratch.
- Automatic: Next incremental refresh cycle (if incremental refresh is enabled) If the data graph has incremental refresh enabled, the transform is automatically triggered at the next scheduled incremental refresh cycle. No manual action is required.
- Automatic: 24 hour full refresh cycle Every data graph has a 24 hour full refresh cycle. If neither a manual refresh nor an incremental refresh resolves the failure, the data graph is automatically refreshed within this cycle.
## Legacy Statuses
Use the Last Run Status column for older data graphs to track progress, identify issues, and take action.
- Draft: The data graph is a work in progress, and you can still edit it.
- Processing: The data graph isn’t yet ready to use.
- Error: The data graph wasn’t created. This could be due to several reasons.
- Active: The update to the data graph data table was successful.
- Active with error: A previous version of the data graph data table is available, but the current data graph operation was unsuccessful.
- Active with processing: A previous version of the data graph data table is available. The current operation is processing.
# Data Graph Tag Propagation
A data graph supports access and security management through tag-based controls, similar to how calculated insight objects (CIOs) are managed. Row-level security (RLS) defined on participating DMOs isn’t automatically enforced in data graphs. Depending on the level of data protection required, administrators can enforce access by using tag propagation.
When you create a data graph, it pulls in fields from various data model objects (DMOs) and CIOs. Only the fields explicitly projected into the data graph are materialized and available at query time. To enforce access controls, the system evaluates user permissions based on tags associated with the projected fields, participating DMOs, and CIOs. Tags from all fields and source DMOs and CIOs are copied to the data graph records. However, if a new tag is added to a DMO after the data graph has already been created, that tag will not automatically propagate to the data graph. In such cases, manual propagation is required so that the data graph reflects the updated tagging.

Important
If a user doesn’t have access to any required tag from a participating DMO or CIO, the entire data graph is inaccessible to that user.
DMO-level RLS policies aren’t applied to data graphs. Data graphs enforce access exclusively through tag-based controls on projected fields.
#### See Also
- [_Salesforce Help_: Tag Propagation in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_tag_propagation.htm&release=264.0.0&type=5 "Tag propagation helps maintain consistent data classification by extending tags from a primary data object to related or downstream objects and fields. This ensures that related objects in your data model carry the same metadata labels and reduces the need for repetitive tagging.")
# Data Graphs
A data graph brings together structured data from your Data Model Objects (DMOs) in Data 360. It combines this data to create easy-to-use views of your information.
Because data in a data graph is preprepared, you can get the information you need in fewer steps. This means your data requests and queries show results almost instantly. Real-time data graphs are crucial for powerful features such as:
- [Real-time identity resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_type_compare.htm&release=264.0.0&type=5 "Identity resolution can perform two types of ruleset runs: scheduled or real-time. They differ in how and when the two types of ruleset runs are performed, and how they interact with other features.")
- [Real-time calculated insights](https://help.salesforce.com/s/articleView?id=data.c360_a_insights.htm&release=264.0.0&type=5 "With insight features, you can define and calculate multidimensional metrics from your entire digital state stored in Data 360.")
- [Real-time segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_realtime_segment.htm&release=264.0.0&type=5 "Create a real-time segment that completes on demand in milliseconds. To make the segment available in your real-time data graph, add the Segment ID and Timestamp fields from the segment membership DMO object to the real-time data graph. You can’t use a real-time segment with exclusion criteria and nested batch segments. You also can't use segment counts and manual publish with a real-time segment.")
To build a data graph, choose the specific fields you want to combine from your existing DMOs. Data 360 then collects and changes these chosen fields into a single, read-only data graph record. This record puts all the combined data into one JSON blob.
You can see your data graphs in Salesforce Lightning Experience using [Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_data_explorer.htm&release=264.0.0&type=5 "With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.") and [Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor.htm&release=264.0.0&type=5 "With the Data 360 Query Editor, you can directly query harmonized customer data using Data 360 SQL (Structured Query Language). You can build queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs."). You can directly query your data graph using the [Data 360 Metadata API](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-metadata-api.html) and [Query API](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-data-graphs-overview.html). You can also use this combined data in other Salesforce applications and operations.
- **[Data Graph Data Structures](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graph_data_structures.htm&release=264.0.0&type=5)**
Understand the underlying components of a data graph so that you can create and use data graphs effectively.
- **[Billing Considerations for Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_graphs.htm&release=264.0.0&type=5)**
Use of data graphs impacts the consumption of credits in these usage types. A data graph creates a transform at the backend and hence reflects under the respective usage type in Digital Wallet.
- **[Data Graph Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graph_status.htm&release=264.0.0&type=5)**
Each data graph has two separate statuses: a status for metadata and a last run status for materialized data. These statuses work together to provide you with insight into the current configuration and refresh state of a data graph. Use them to monitor the data graph's lifecycle in Data Cloud, identify any issues, and determine if the data graph is ready for querying or further updates.
- **[Build and Manage Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_build_and_manage_data_graphs.htm&release=264.0.0&type=5)**
Create and manage data graphs in Data 360. You can view a data graph using the Data 360 user interface or an API.
- **[Advanced Configuration for Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_adv_conf_data_graphs.htm&release=264.0.0&type=5)**
In Data 360, advanced configuration for data graphs allows you to customize the data graph beyond the default settings.
#### See Also
- [_Data 360 Query Guide_: Data Graphs REST API Reference](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-data-graphs-overview.html)
# Data Interpretation with Fully Qualified Keys
Fully qualified keys help to accurately interpret data ingested from different sources. Each data stream is ingested into Data 360 with its specific keys and attributes. When multiple data streams are harmonized into a single data model object (DMO), the various keys can conflict and records can have same key values. Fully qualified keys avoid conflicts by adding key qualifier fields and interpreting the data accurately.
A fully qualified key consists of a source key, such as a contact ID from CRM or a subscriber key from Marketing Cloud Engagement, and a key qualifier.
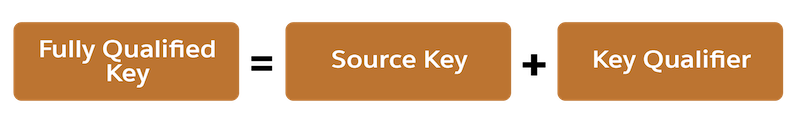
For example, let’s say you have two data streams with related data lake objects (DLO) for profile data: Contacts DLO from Salesforce CRM and Subscribers DLO from Engagement. The records for these DLOs are mapped to the Individual DMO. Now, you want to join the Individual DMO to the Engagement DMO to identify individuals with a minimum of two clicks. Here’s how using fully qualified keys can accurately interpret data ingested from two different sources.
The two data streams are mapped to the Individual DMO in Data 360. The Contacts DLO has three records, and the Subscribers DLO has two records. So the Individual DMO, which contains all the records from all the mapped data streams, has five records.
Engagement is using the Contact ID from the CRM org as the primary key (Subscriber Key). So, there are multiple records in the Individual DMO with the same value for Individual ID which is the primary key field.
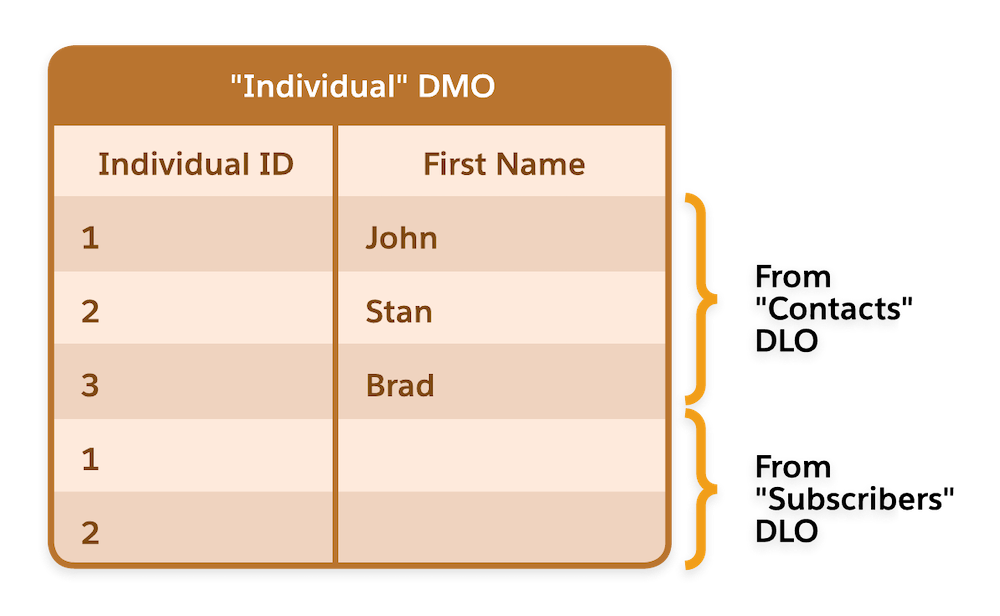
Next, let’s consider the Email Engagement DMO, which contains email engagement data that was ingested from Engagement. The Individual DMO and Email Engagement DMO have a 1:N relationship through the Individual ID.
When you join the Individual DMO and the Email Engagement DMO, Data 360 interprets the combined data set as the first row of Individual 2 having one click and the second row of Individual 2 having one click. In other words, Individual 2 is assumed to have two email clicks. But in actuality, Individual 2 has only one click action, although Data Cloud interprets it as two click actions.
This misinterpretation can create an issue when this data is queried, including segmentation, calculated insights, and query API. If you run a query and ask for individuals who have a minimum of two click actions, Individual 2 is returned in the response. This issue occurs even when profile unification is deployed, because engagement data is always joined to the Individual DMO.
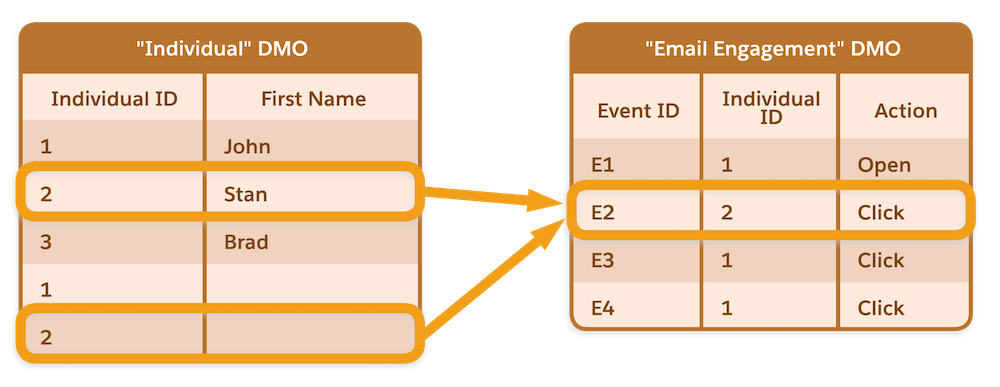
You can avoid this issue by using fully qualified keys. When you add key qualifier fields to all your DLO fields that contain a key value, either a primary key or a foreign key, Data 360 interprets the data ingested from different data sources correctly. In this example, key qualifiers are added to the DLOs from Salesforce CRM and Engagement. The Individual DMO includes the key qualifier field indicating where the record was sourced from.
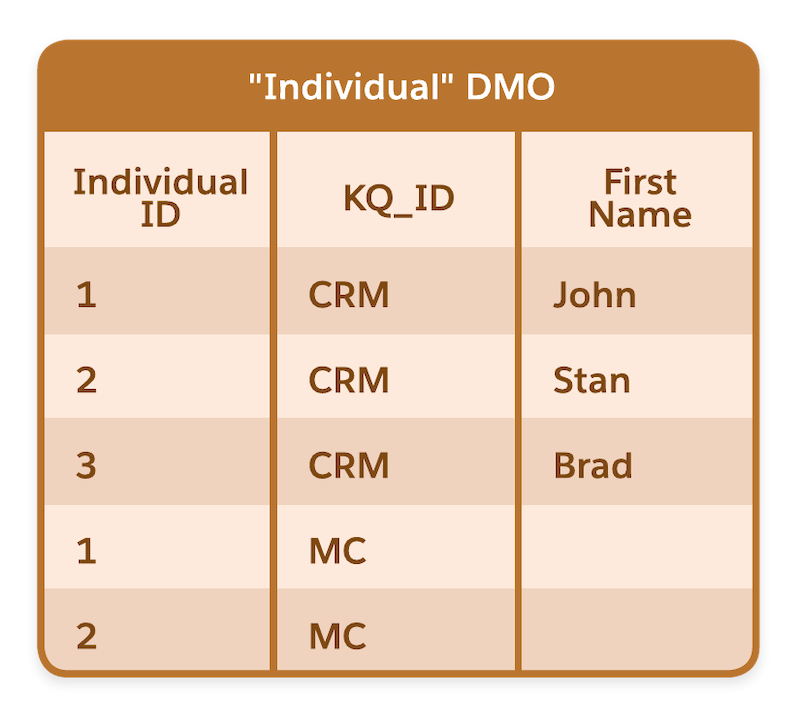
When the Individual DMO and Email Engagement DMO are joined, the table join uses both the foreign key field (Individual ID) and the key qualifier field (KQ\_ID), which enables Data 360 to interpret the data accurately.
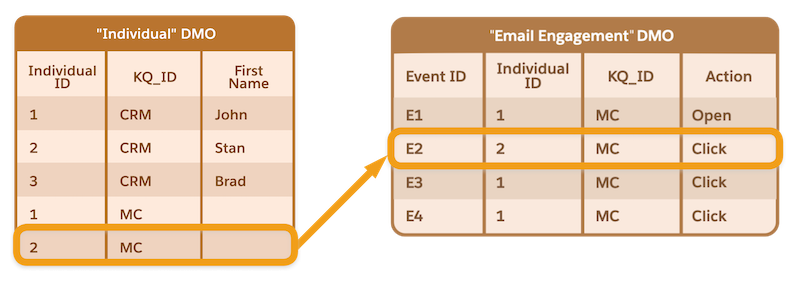
When you run the same query for Individuals who have a minimum of two click actions, data for Individual 2 doesn’t meet the query criteria, and it isn’t returned in the query response.
# Data Kits
Use a data kit in Data 360 to streamline package creation and installation. You can manage all packageable Data 360 features in the data kit. You can create data stream bundles and also include data model customization and relationships.
Watch this video to see how you can create and upload a data kit.
A data kit wraps around all the packageable Data 360 metadata so that you can create and deploy complete solutions on Data 360.
## Types of Data Kits
Data 360 provides two types of data kits to deploy your metadata and process definitions. Choosing the right data kit depends on your use case and deployment environment. Use the guidelines to determine the best option for your needs.
- Standard Data Kit: Create a standard data kit to package and share your Data 360 features and solutions with customers. You can create the data kit from the default data space and deploy it to any data space in the target org. With a standard data kit, you can distribute Data 360 solutions tailored to your customers' needs.
- DevOps Data Kit: Use a DevOps data kit to migrate Data 360 metadata from a sandbox org to a production org, but not to package Data 360 metadata. You can create the DevOps data kit from any data space, but you deploy it to the same data space in the target org. With DevOps data kit, you can maintain consistency in your metadata management processes.
## Workflow for Data Kits in Managed Packages
- Create a data stream to package in the data kit.
- Create a data kit from Data 360.
- Select and add the data streams and data stream definitions in the data kit package.
- Define the deployment sequence for data kit components.
- Upload the data kit package in Data 360.
- Publish the data kit in Package Manager.
- Create a package in Package Manager with the data kit.
- Install the created package in a Salesforce org.
After you deploy the packaged data stream, the relationships included in the package are mapped automatically.
## Additional Resources
To learn more about this topic, review the associated Trailhead content.
[Packaging and Data Kits in Data 360](https://trailhead.salesforce.com/content/learn/modules/packaging-and-data-kits-in-salesforce-cdp)

- **[Considerations for Data Kits in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_datakit_consideration.htm&release=264.0.0&type=5)**
Review these considerations for data kit creation, publishing, and deployment to ensure successful implementation and avoid common issues.
- **[Create and Publish a Standard Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_bundle_package_kits.htm&release=264.0.0&type=5)**
Streamline package creation and the installation experience for Data 360 objects by wrapping together the metadata and relationships into a standard data kit. Use a Developer Edition org that supports managed packages to create and publish a standard data kit. Use a DevOps data kit to migrate metadata across orgs.
- **[Add a Data Kit to a Package](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_package_kit.htm&release=264.0.0&type=5)**
After creating and publishing your data kit in Data 360 source org, add the data kit to a package and upload it using Package Manager in your Salesforce org.
- **[Deploy Data Kit Components in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_deploy_data_kit_components.htm&release=264.0.0&type=5)**
After you create and install a standard data kit in a managed package, you can deploy package components such as data streams, batch data transforms, calculated insights, and data graphs from Data 360 with Package Manager in your target org.
- **[Update a Data Kit in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_update_a_data_kit_in_customer_data_platform.htm&release=264.0.0&type=5)**
You can update an existing data kit when you modify Salesforce CRM and B2C Commerce data streams, data models, mappings, and relationships. You can also retrieve and deploy the updated data kit from Data 360 with Package Manager in your Salesforce org.
- **[Uninstall a Deployed Data Kit in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_uninstall_data_kit.htm&release=264.0.0&type=5)**
Removing unused or outdated data kits keeps your org organized and efficient. To uninstall a data kit deployed from a managed package, first undeploy the deployed data kit components and their dependencies from all data spaces. Then, uninstall the managed package.
# Data Lake Object Naming Standards
Use these naming guidelines for data lake objects.
### Required Editions
Available in: Lightning Edition
Field Label
Description
Field Type
Data Lake Object Label
Display name of the object storing the dataset. The object label must
be unique.
Required
Data Lake Object Label Name
API name of the object storing the data. The name must be unique and
no longer than 40 characters. The naming conventions are:
Only underscores and alphanumeric characters
Begin with a letter and not include spaces
Can’t end with an underscore
Can’t have two consecutive underscores
Required
# Data Leakage Alert
Data leakage occurs when the model's training data contains the information you’re trying to predict. Leakage results in models that score optimistically high in training but perform less accurately on live data. It can mislead the model into learning patterns that are unavailable in practice, thereby compromising predictions.
## Actions to Consider
Investigate the variable for data leakage. If found, exclude the variable from the model.
## Detection Methodology
Model Builder displays an alert when it detects an explanatory variable that always has the same outcome.
## Example
A lender wants to predict if a customer will default on a loan. To achieve this, the lender builds a binary model with these input variables.
- age
- income
- credit score
- loan amount
- loan status
- payment history
- loan final payment date
After training, the model displays an alert because data leakage was detected. The values for the “loan status” and “payment history” variables are determined only after the loan is approved and partially repaid. Including such information leaks future data that wouldn’t realistically be available when the model makes predictions. To resolve the issue, here are some actions to consider.
- Exclude the “loan status", “payment history", and “loan final payment date” input variables from the training set.
- Use variables known at the time of the loan approval instead of “age", “income", “credit score", and “loan amount".
- Retrain the model with an updated dataset.
# Data Lineage Best Practices
Applying these best practices helps maintain consistent data visibility and governance alignment across your organization.
### Required Editions
- Validate lineage accuracy regularly. If the graph doesn’t match expected flows, contact Salesforce Support to rebuild it.
- Use tags consistently. Ensure that key governance tags such as sensitivity or classification are applied at both the object and field level.
- Correlate lineage with policies. Cross check tag-based policies to confirm that access rules align with lineage paths.
- Document critical dependencies. Record major upstream and downstream relationships for high-impact objects to aid troubleshooting.
- Leverage Lineage in reviews. Incorporate lineage insights during data model and policy change reviews to reduce risk.
# Data Lineage Fields
Data 360 adds fields to a data object to capture data source details.
- Data Source—A reference ID for the logical name referring to the source of records, also identified as the external source ID. For example, SFMC\_1487860 indicates records from Salesforce Marketing Cloud Engagement (SFMC) and the internal Org Id.
- Data Source Object—A reference ID for the logical name of the object where the record came from, such as the name of a cloud storage file or another connector’s external object. For example, SFMC\_1487860\_Campaign indicates records from Marketing Cloud Engagement, the internal Org Id, and the object Campaign.
- Internal Organization—A reference ID to the business unit or other internal organization that owns the data record. For example, data records imported from Marketing Cloud Engagement have the business unit Id of where the data record originated from. The Internal Organization ID is not mapped automatically for CRM sources.
# Data Mapper Views
Select table or visual view when mapping your data in Data 360.
### Required Editions
Available in: Lightning Experience in all editions except Starter
To switch between table view and visual view, use the view dropdown menu on the data mapping page. Save your changes before changing views.
## Table View
In table view, you can select data source objects (DSOs) or data model objects (DMOs) in a column format. You can map without using a pointer device or visual feedback. The mapping is managed one data model at a time. You can perform these actions by using your keyboard:
- Search a data model object for a specific field.
- Create a mapping between a data stream source field and a data model object field.
- Remove an existing mapping between a data stream source field and a data model object field.
- Create a custom field in a data model object.
To select a new data model object to add to your field mapping or add a custom model object, use visual view.
## Visual View
In visual view, you can drag to create connections between your DSOs and DMOs.
# Data Mapping
Data ingested by all data streams is written to data lake objects (DLOs). After creating your data streams, you must associate your DLOs to data model objects (DMOs). Only mapped fields and objects with relationships can be used for Segmentation and Activation.
On the Data Stream detail page or after deploying your data streams, click **Start Data Mapping**.
On the Field mapping canvas, you can see both your DLOs and target DMOs. To map one to another, click the name of a DLO and connect it to the desired DMO. For example, you can map the DLO firstname to the target First Name field using this method.
- **[Data Mapping Requirements in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_required_data_mappings.htm&release=264.0.0&type=5)**
Mappings and relationships are set up automatically only for data streams that are deployed through standard data bundles. However, you must ensure that the required mappings and relationships are set up properly for custom data streams.
- **[Data Mapping Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping_best_practices.htm&release=264.0.0&type=5)**
Proper data mapping in Data 360 is a key component for success. Follow some best practices for data mapping to ensure your data can be used throughout Data 360 for segmentation, insights, and identity resolution.
- **[Data Mapper Views](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping_views.htm&release=264.0.0&type=5)**
Select table or visual view when mapping your data in Data 360.
- **[Data Types in Field Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_data_type_field_mappings.htm&release=264.0.0&type=5)**
When mapping a data lake object (DLO) to a data model object (DMO), the data types of the DLO and DMO fields must be compatible.
- **[Map Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&release=264.0.0&type=5)**
Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.
- **[Automapping](https://help.salesforce.com/s/articleView?id=data.c360_a_automapping_dlo_dmo.htm&release=264.0.0&type=5)**
Automapping in Data 360 maps data lake object (DLO) fields to the correct data model object (DMO) fields. When you choose a specific DMO during field mapping, Data 360 calculates and applies the field mappings. You can then make any necessary changes and save the mappings.
- **[Mapping UDLOs to UDMOs](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_map_udlo.htm&release=264.0.0&type=5)**
Workloads in Data 360 that consume unstructured data do so through unstructured data model objects (UDMOs). When you create a UDLO, you map it to a UDMO.
- **[Manage Data 360 Objects and Field Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_model_object.htm&release=264.0.0&type=5)**
Edit or remove objects and field mappings associated with a data model object (DMO) or data lake object (DLO). Manage mappings and objects to ensure data accuracy and maintain the integrity of your data model.
- **[Delete an Unstructured Data Lake Object](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_udlo_delete.htm&release=264.0.0&type=5)**
You can delete unstructured data lake objects (UDLOs) at any time.
- **[Remove a Field from a Data 360 Page](https://help.salesforce.com/s/articleView?id=data.c360_a_remove_a_field_mapping_from_customer_data_platform_flexipage.htm&release=264.0.0&type=5)**
A FlexiPage represents the metadata associated with a Lightning page. A Lightning page is a customizable screen made up of regions containing Lightning components. A Lightning page is created only for derived data model objects (DMO) that have unified objects such as UnifiedIndividual and UnifiedAccount. You can remove a field from the Data 360 page to remove field mappings.
# Data Mapping Best Practices
Proper data mapping in Data 360 is a key component for success. Follow some best practices for data mapping to ensure your data can be used throughout Data 360 for segmentation, insights, and identity resolution.
## Planning Considerations
Plan ahead before you begin mapping your data to DMOs in Data 360.
- Create a report, an offline data dictionary, or source system inventory.
- Identify field-level data and analyze its accuracy.
- Review available standard data model objects (DMOs) and associated fields that your data can map to.
- If gaps are identified, extend standard objects by adding custom fields or create a new custom DMOs on the Data Model tab. See instructions on [creating custom data model objects](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_data_model_object.htm&release=264.0.0&type=5 "If a standard data model object doesn’t meet a business need, you can create a custom data model object (DMO) to store information that is unique to your business. You can create a custom data model object from an existing DMO, from a file, or from scratch.").
- Consider how each data source and corresponding fields relates to the object you want to unify, such as the Individual or Account objects.
- For example, if you’re bringing in web engagement data, ensure that it’s mapped to the Individual DMO or an attribute that is mapped to the Individual DMO to better understand user consumption and behavior on your site.
- Consider the downstream use cases of the mapping. For example, to create a segment on individuals who browsed the blue shirt, map engagement data to the Individual DMO.
- Set the category, or type of data, when you set up the DLO or schema corresponding to the dataset that you’re importing. A DMO inherits its category from the first DLO mapped to it. You can create subsequent mappings between the following categories.
- Profile DLOs can map to Profile DMOs or Other DMOs but not to Engagement DMOs.
- Engagement DLOs can map only to Engagement DMOs.
- Other DLOs can map to Profile DMOs or Other DMOs but not to Engagement DMOs.
## Mapping Person Account Fields
Person accounts use fields from both the Account and Contact objects. Because person accounts represent people, map person account fields to the Individual DMO.
- Map the Contact object to Individual DMO and use Contact Id as Individual Id. This mapping makes the Contact Id your Subscriber Key in Marketing Cloud Engagement during activation. It also limits post-processing SQL and reduces the risk of introducing a new subscriber keys.
- Map the Contact object to the Account Contact DMO.
- Map the Account object to the Account DMO.
## Transformation and Relationships
Once your model is established, review if you need to adjust formula fields, create transforms, or review data relationships.
- Establish how the source data must be transformed and mapped into the standard data model. Not all source systems provide normalized export options or normalize data to the same degree. For more information, see help topic on [normalized and denormalized data](https://help.salesforce.com/s/articleView?id=data.c360_a_normalized_and_denormalized_data.htm&release=264.0.0&type=5 "Data originates from multiple sources and can be normalized or denormalized. The Data 360 standard data model is normalized, so incoming data must be normalized before it can be mapped to the data model. Because not all source systems provide normalized export options or normalize data, assess your field-level data to establish how to transform and map the source data to the standard data model.").
- Visualize objects and relationships holistically with the graph view on the Data Model tab. In many cases, it’s better to inspect the relationships or lack of holistically for all mapped objects in the data model rather than through a single object. For more information see help topic on [viewing data model objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_view.htm&release=264.0.0&type=5 "You can view your Data 360 data model objects in either list or graph view.").
## Troubleshooting
- If you’re attempting to map a DLO but don’t see a specific target DMO in the object selector, check that the category of your DLO matches one of the categories of DMO it can map to. The UI shows a list of DMOs to choose from, filtered by compatible categories and omitting objects with incompatible categories.

Example The Sales Order DMO is first mapped to a DLO called Order-Headers in the Engagement category. Because of this DLO, Sales Order gets assigned to the Engagement category. Subsequently, only Engagement category DLOs can be mapped to the Sales Order DMO.
# Data Mapping Requirements in Data 360
Mappings and relationships are set up automatically only for data streams that are deployed through standard data bundles. However, you must ensure that the required mappings and relationships are set up properly for custom data streams.
- When you’re mapping a data model object (DMO) in the Profile or Other category, you must map the primary key field. You can save the data mapping only after mapping the primary key.
- When you’re mapping a DMO in the Engagement category, you must map the primary key field and the Event dateTime field. You can save the mapping only after mapping both fields.
- To use identity resolution, segmentation, and activation, map the required fields and relationships for the party area data. You can use the Entity Relationships Diagram (ERD) for Party area to plan the mapping. You must also map the Individual object and either a Contact Point or the Party Identification object must be mapped in data streams.
- The reference to the Individual object in other objects within the data model is done through the Party attribute. Think of it as a foreign key relationship that links to an Individual.Id attribute. In the Party entity relationship diagram, you can see that each Contact Point object alongside Party Identification has that reference. While in some cases it can be confusing, when it comes to attributes, Party = Individual.Id.
- Map at least one Contact Point attribute to enable unification and activation processes to work.
A Contact Point object contains details about an individual, such as an email address or phone number. Without the contact point, activation isn’t feasible because there isn’t a contact detail through which to engage with customers.
- The Party Identification object represents sets of third-party identifiers for an individual, such as a loyalty card number or a driver license number that can associate numerous customer records together. For the same Party Identification Type and Identification Name values, Data 360 matches records with the same Identification Number.
- To activate digital identifiers to JSON-based external activation platforms that use the activation toolkit, map the Contact Point Digital Id object. This mapping is mandatory when the activation platform relies on specific digital identifiers such as UID2 or RampID. If your activation only targets email or phone-based destinations (using Contact Point Email or Contact Point Phone), this mapping is optional. For more information, see [Ingest and Model Digital Identifiers for JSON-based External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_map_digital_identifiers_activation_toolkit.htm&release=264.0.0&type=5 "Ingest and model your digital identifier data by using the standard ContactPointDigitalId data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.").
Object
Fields
Relationship
Individual
ID
None
Contact Point Email
ContactPointId
PartyId
EmailAddress
ContactPointEmail (PartyId) (many) to Individual (Id) (one)
Contact Point Phone
ContactPointId (key)
PartyId
TelephoneNumber
Country
FormattedE164PhoneNumber
ContactPointPhone (PartyId) (many) to Individual (Id) (one)
Contact Point Address
ContactPointId (key)
PartyId
StreetID
CityID (City Name)
StateName (State Province Name)
CountryID (Country Name)
ContactPointAddress (PartyId) (many) to Individual (Id) (one)
Contact Point Social
ContactPointId (key)
PartyId
SocialHandleId
ContactPointSocial (PartyId) (many) to Individual (Id) (one)
Contact Point OTT Service
Contact Point OTT Service Id
PartyId
Country
Username
ContactPointOTTService (PartyId) (many) to Individual (Id) (one)
Contact Point Digital Id
ContactPointDigitalId (key)
IndividualId
DigitalIdType
DigitalIdValueText
ContactPointDigitalId (IndividualId) (many) to Individual (Id) (one)
#### See Also
- [_Salesforce Help_: Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.")
- [_External_: Party Overview Entity Relationship Diagram](https://architect.salesforce.com/diagrams/template-gallery/cdp-party-data-model)
# Data Masking
Data masking settings in your Salesforce org and Model Playground determine the privacy of sensitive information and how that data is surfaced in a prompt response. Org-level settings are enabled by default.
When you create or update a model configuration, enable data masking in the Model Playground prompt settings. When enabled, data masking prevents data from leaving the Einstein Trust Layer to third-party large language models during testing and masks all sensitive data in a prompt response. When you disable the setting, sensitive data, such as names, birth dates, and email addresses, are no longer masked during testing.
At the org-level, the Einstein Trust Layer detects and masks selected sensitive data for models deployed in production.
#### See Also
- [_Salesforce Help_: Data Masking](https://help.salesforce.com/s/articleView?id=ai.generative_ai_mask_data.htm&type=5&language=en_US)
- [_Salesforce Help_: Einstein Trust Layer Region Language Support](https://help.salesforce.com/s/articleView?id=ai.generative_ai_trust_lang_region.htm&type=5&language=en_US)
# Data Model Concepts
Improve the interoperability of data across applications, and map data between your connected data sources and the Data 360 Customer 360 Data Model.
- **[Data Flow](https://help.salesforce.com/s/articleView?id=data.c360_a_data_flow.htm&release=264.0.0&type=5)**
Use the power of Data 360 data in and out of Data 360. Data can be ingested and stored in Data 360 or can be connected via metadata and queried without storage.
- **[Data Federation, Ingestion, and Modeling](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion_and_modeling.htm&release=264.0.0&type=5)**
Data federation and data ingestion bring data from external data sources into Data 360. Data modeling is the next important phase to process data in Data 360.
- **[Customer 360 Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_c360datamodel.htm&release=264.0.0&type=5)**
The Customer 360 Data Model reduces the complexities of integrating data across cloud applications by providing standardized data guidelines. Extend the data model to create data lakes, generate analytics, train machine-learning models, build a single view of the customer, and more.
- **[Data Objects in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lake_objects.htm&release=264.0.0&type=5)**
When working with Data 360, it’s helpful to know about Data 360 data objects including data lake objects (DLO) and data model objects (DMO).
- **[Unstructured Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_about.htm&release=264.0.0&type=5)**
By bringing unstructured data in Data 360, you can ground your Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.
- **[Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5)**
Data 360 supports these data types.
# Data Model Object Relationships
A Data 360 data model object (DMO) can have a standard or custom relationship with other DMOs. The relationship can be structured as a one-to-one or many-to-one relationship. You can view the relationships and their statuses on a DMO record’s Relationships tab.
## Cardinality of Relationships
When you create a relationship, choose the cardinality carefully. Cardinality between two DMOs has implications for segmentation and activation. You can’t change the cardinality after the relationship is created.
If you have a relationship between two objects, for example A and B, and object A has multiple records for each record in object B, the relationship chosen is many-to-one.

Example The relationship between the Contact Point Email DMO and the Individual DMO is structured as many-to-one because the Contact Point Email DMO could have one or more records for each Individual DMO record. Similarly, the relationship between a SalesOrder DMO and an Individual DMO is structured as many-to-one because each Individual record could have more than one order record.
## Standard Relationships
The Data 360 data model includes several standard relationships. A standard relationship is inactive until the related object fields are mapped. It’s activated when there’s at least one mapping to both fields in the relationship. The relationship is deactivated when a mapping for at least one field in the relationship is removed. You can disable a standard relationship, but you can’t delete it.
A standard relationship is visible on the Relationships tab only when it’s activated.

Example The Data 360 data model includes a relationship between Sales Order.Bill To Email in the Sales Order DMO and Contact Point Email.Contact Point Email Id in the Contact Point Email DMO. This relationship is activated and is visible on the Relationships tab when field mappings exist for both fields.
## Custom Relationships
Create a custom relationship between DMOs on the Relationships tab.
You can also deactivate a custom relationship or delete it. You can reactivate a deactivated relationship at any time. When you delete a relationship, it’s permanently removed. A custom relationship is automatically deleted if the mappings for at least one field in the relationship is removed.
## DMO Relationship Status
A pair of DMOs can have one or more relationships between them, but only one relationship is allowed between a given pair of DMO fields. The relationship status between DMO fields can be active or inactive.
View the status of a relationship in the Edit Relationships window.
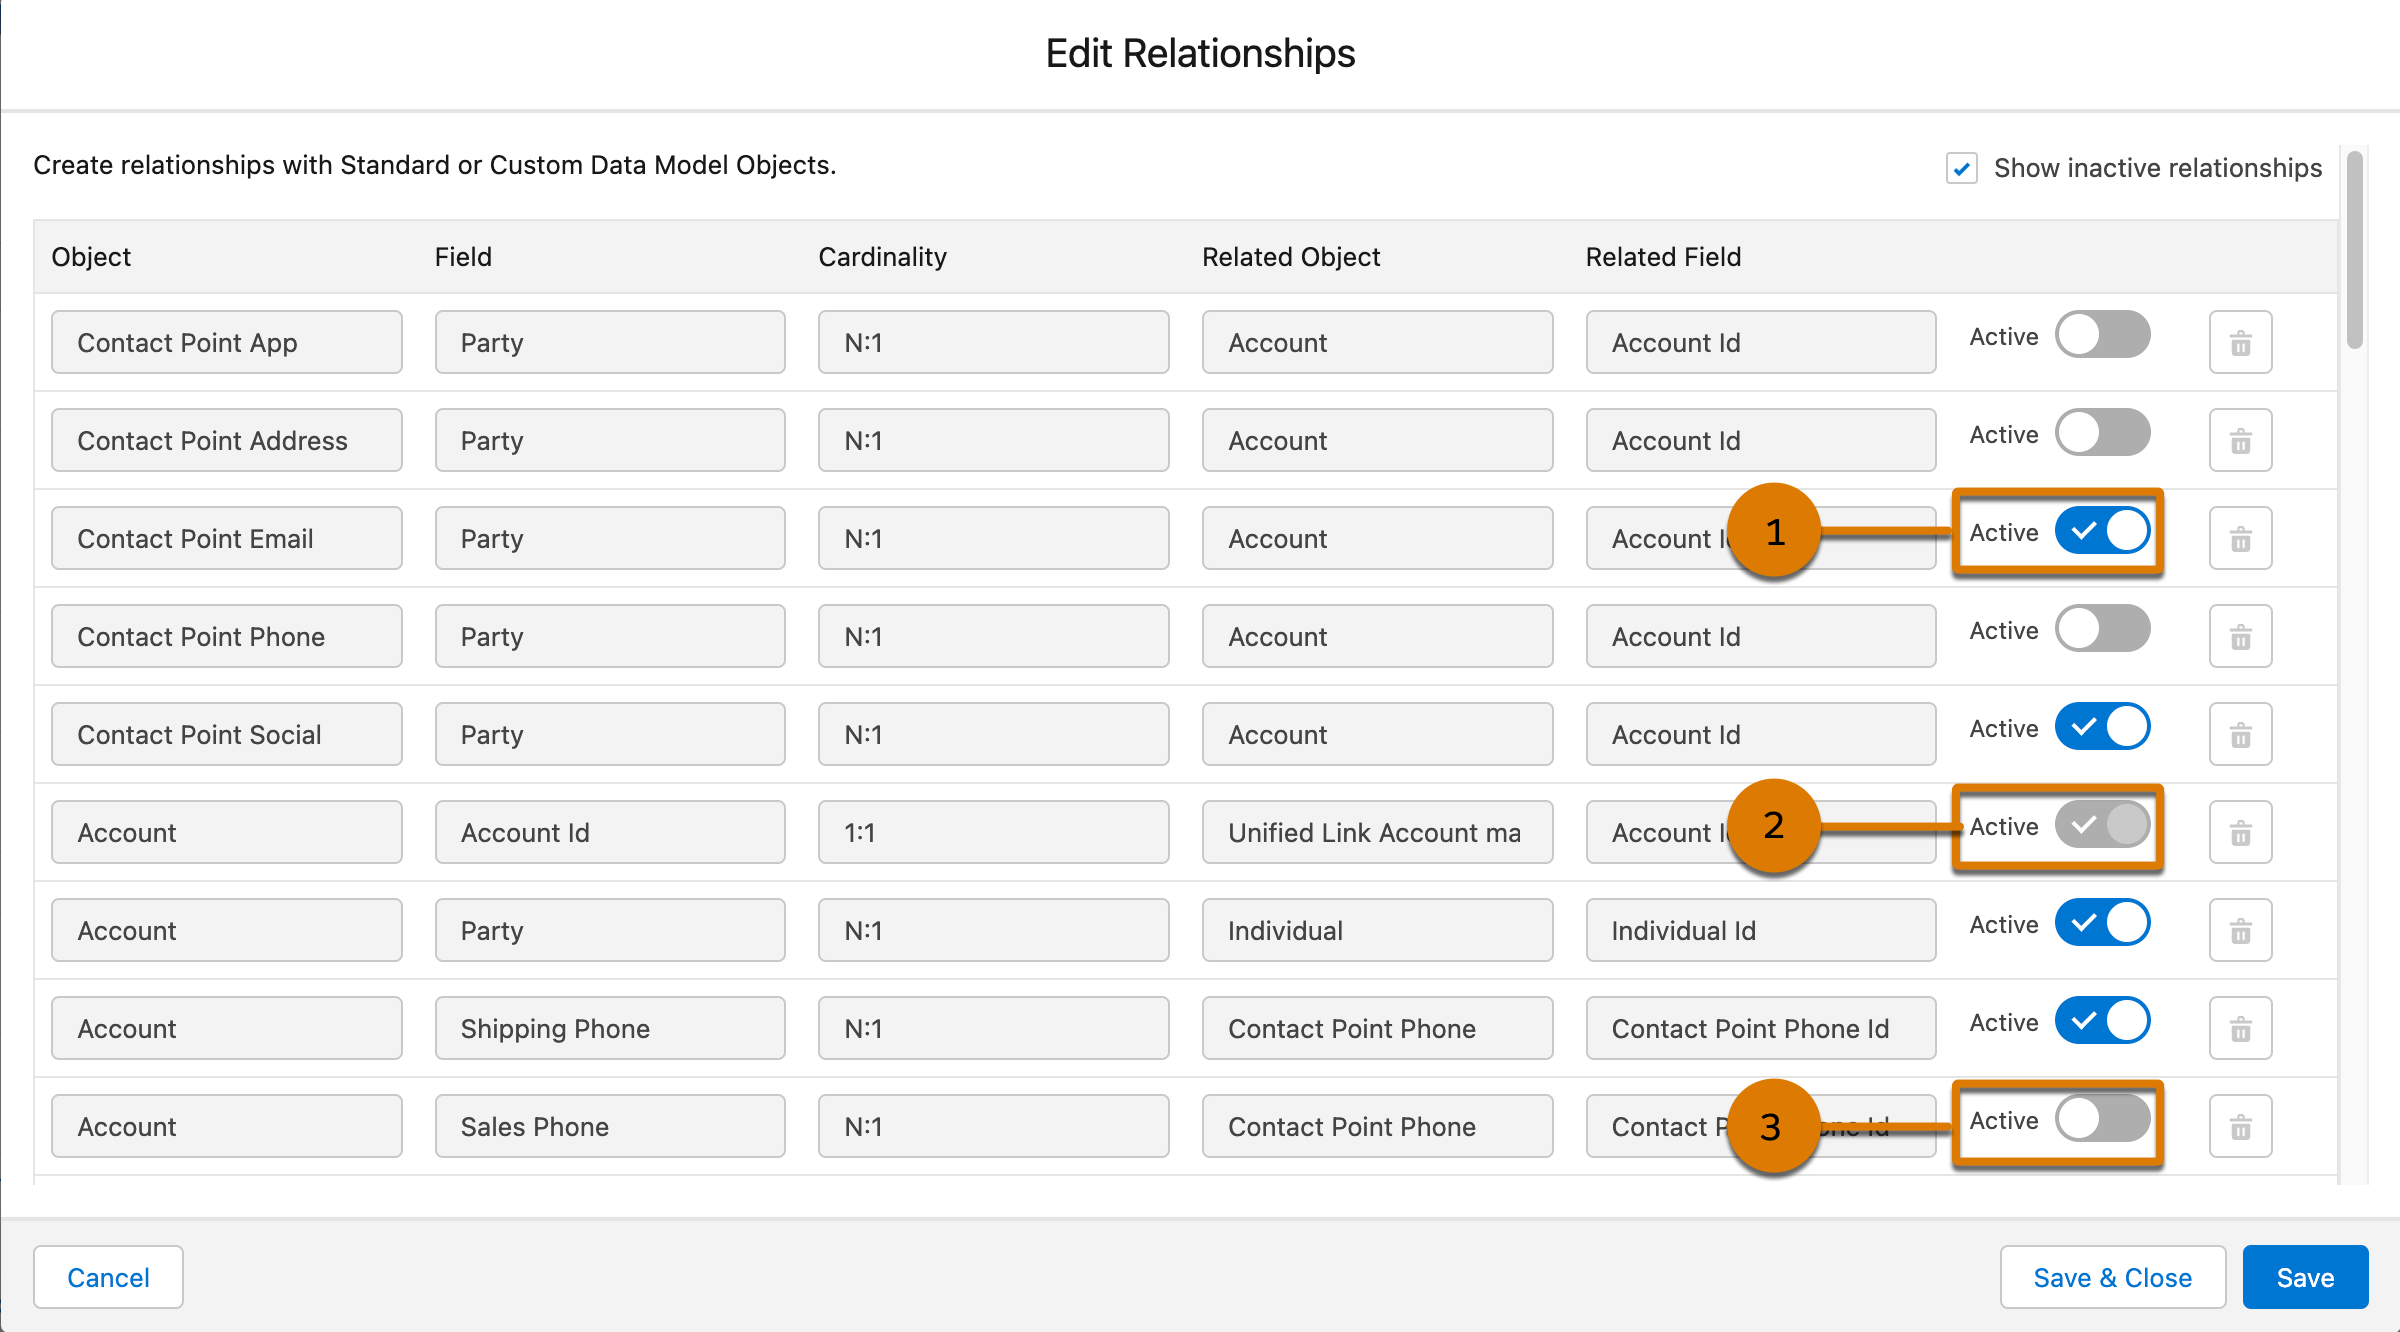
If the relationship status is active and can be deactivated (1), use the toggle switch to modify the state. When the relationship is deactivated, it can’t be used by downstream functional areas, such as segmentation and activation. However, you can’t deactivate relationships that are being used in calculated insights, segmentation, or activation.
Some relationships are active but can’t be deactivated (2). You can’t deactivate relationships that are used by the identity resolution process.
By default, deactivated relationships (3) aren’t visible and can be seen only when you select **Show inactive relationships**. Use the toggle to activate the relationships.
## DMO Relationship Limits
Data 360 limits the number of custom relationships that can be active for each DMO. When the DMO reaches its active relationship limit, you can’t add a custom relationship or activate an inactive relationship. There isn’t a limit on the number of standard and inactive relationships.
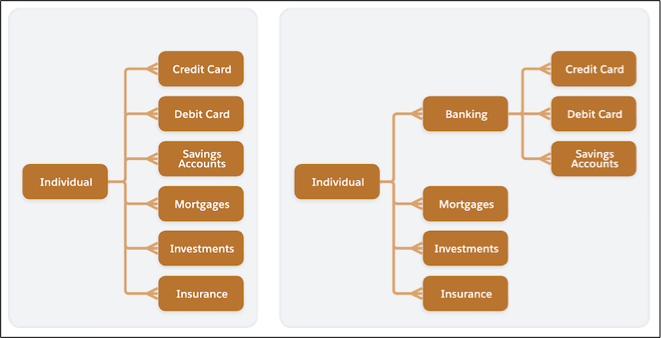
The custom relationship limit applies only to direct relationships associated with a DMO, not indirect relationships. To add more custom relationships, organize DMOs into multiple levels and create a nested structure in the data model. For example, if each DMO is limited to 25 custom relationships but you need 30, decide which 5 DMOs to group together. From the parent DMO, create 25 custom relationships. Designate one of the children as a new parent to the five grouped DMOs.
Data 360 checks for relationship limits when a packaged data bundle is deployed to an org. The package installation fails if the relationship limit is reached.
Salesforce starter data bundles, such as the CRM starter bundles, only include standard relationships. Installation of starter bundles will not fail because standard relationships are not counted towards DMO relationship limits.
#### See Also
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Data Model Objects (DMOs)
Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.
- **[View Your Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_view.htm&release=264.0.0&type=5)**
You can view your Data 360 data model objects in either list or graph view.
- **[Create a Custom Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_data_model_object.htm&release=264.0.0&type=5)**
If a standard data model object doesn’t meet a business need, you can create a custom data model object (DMO) to store information that is unique to your business. You can create a custom data model object from an existing DMO, from a file, or from scratch.
- **[Create a Custom Data Model Object from an Existing Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_dmo_from_existing.htm&release=264.0.0&type=5)**
Use a custom data model object (DMO) to store information that is unique to your business. You can create a DMO by copying an existing standard or custom DMO.
- **[Create a Custom Data Model Object from a CSV File](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_dmo_from_csv.htm&release=264.0.0&type=5)**
Use a custom data model object (DMO) to store information that is unique to your business. You can add a custom DMO by uploading a CSV file.
- **[Edit Data Model Object Properties](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_properties.htm&release=264.0.0&type=5)**
You can edit Data Model Object (DMO) properties either on the Data Model tab or on the data mapping page.
- **[Change the Category of a Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_change_data_model_object_category.htm&release=264.0.0&type=5)**
In most cases, a data model object’s category can’t be changed after the object is created. The category can be changed only if it’s changing from Profile to Other or from Other to Profile on an object that isn’t used in segmentation or activation.
- **[Data Model Object Relationships](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_relationships.htm&release=264.0.0&type=5)**
A Data 360 data model object (DMO) can have a standard or custom relationship with other DMOs. The relationship can be structured as a one-to-one or many-to-one relationship. You can view the relationships and their statuses on a DMO record’s Relationships tab.
# Data Object Concepts and Schema in Data 360
During ingestion, Data 360 retrieves a sample of your data and recommends a source schema. You can then review and modify the recommended schema.
In the schema, the non-editable header label identifies the source of the raw data. You can change the other labels.
- Field Label—A proposed Data 360 display name for each source header column.
- Field API Name—A proposed Data 360 API name for each source header column.
- Data Type—A suggested data type for each source header column. For information on supported data types, see [Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5 "Data 360 supports these data types.").

Warning If you select the wrong data type, you must delete the data stream and re-create it. You can’t change a data type after the data stream is created.
- **[Source, Object Name, and Object API Name](https://help.salesforce.com/s/articleView?id=data.c360_a_source_object_name_and_object_api_name.htm&release=264.0.0&type=5)**
When ingesting a data set into Data 360, name the data set source.
- **[Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5)**
When creating a data stream, select a category or type of data found in that data stream.
- **[Primary Key](https://help.salesforce.com/s/articleView?id=data.c360_a_primary_key.htm&release=264.0.0&type=5)**
To create a data stream in Data Cloud, select a primary key or unique identifier for that source. If a data source doesn't have a field that can be used as a primary key, create a composite key by combining two or more source fields using a formula field.
- **[Categorize Anonymous and Known Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_ingestion_anonymous_vs_known_profiles.htm&release=264.0.0&type=5)**
During ingestion, a source profile is categorized as either anonymous or known based on the value in the Is Anonymous field on the Individual DMO in data streams. A source profile without that field mapped is always considered known. Add the mapping to differentiate between known and anonymous profiles.
- **[Organization Unit Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_organization_unit_identifier.htm&release=264.0.0&type=5)**
The Organization Unit Identifier is an optional field that allows you to specify business units in your Data 360 data.
- **[Data Lineage Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lineage_fields.htm&release=264.0.0&type=5)**
Data 360 adds fields to a data object to capture data source details.
- **[Source Object Schema Modifications](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_source_object_schema.htm&release=264.0.0&type=5)**
You can modify Data 360 source object schema on the Data Stream details page. All changes are applied to future data imports. To apply logic retroactively, pull from the source and ingest into Data 360.
- **[Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_fully_qualified_keys.htm&release=264.0.0&type=5)**
Use Fully Qualified Keys (FQK) to avoid key conflicts when data from different sources are harmonized in the Data 360 data model.
- **[Create a Formula Field](https://help.salesforce.com/s/articleView?id=data.c360_a_formula_expression_library.htm&release=264.0.0&type=5)**
When you create a Data 360 data stream, you can choose to generate more fields. These supplemental fields can be hard-coded or derived from other fields in the data stream.
- **[Formula Expression Use Cases](https://help.salesforce.com/s/articleView?id=data.c360_a_formula_expression_use_cases.htm&release=264.0.0&type=5)**
These examples show use cases of formula expression functionality in Data 360.
# Data Objects in Data 360
When working with Data 360, it’s helpful to know about Data 360 data objects including data lake objects (DLO) and data model objects (DMO).
| Object | Description | NOTES |
| --- | --- | --- |
| Data lake object (DLO) | A container for the data brought into Data 360. | A DLO is automatically created from data brought into Data 360, but can also be created manually. |
| Unstructured data lake object (UDLO) | A container for unstructured data referenced by Data 360. | A UDLO is created manually. |
| Data model object (DMO) | A harmonized grouping of data created from data streams, insights, and other sources. | A DLO is mapped to a DMO. |
| Unstructured data model object (UDMO) | A group of data created from an unstructured data source. | A UDLO is automatically mapped to an existing or new UDMO. |
| External data lake object | A storage container with metadata for the data federated from an external data source. | An external DLO acts as a reference, and points to the data physically stored in an external data source. |
## View Your Objects
Use the Data Model tab to view DMOs. Use the Data Lake Objects tab to view all DLOs and the DMOs that they’re mapped to, create DLOs, or to add fields to your DLOs. To view the recent status of that object, the previously refreshed date, and all associated mappings to DMOs, select the DLO name. You can also view the mapping that’s performed on the object. You can't delete the DLO fields.
If a DLO is associated with a data stream, you can’t add fields to it from the Data Lake Objects tab. Make these updates on the Data Streams tab. For more information, see [Using an Existing Data Lake Object to Create a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_guardrails_existing_data_lake_object.htm&release=264.0.0&type=5 "You can use an existing data lake object (DLO) when creating an S3, Google Cloud Storage, or SFTP data stream. The data stream that initially created the DLO defines the characteristics, such as the primary key, event date time, and record modified field. You can convey how the new data stream’s fields conform to the existing DLO fields.").
# Data Preview Sampling
Use data preview sampling to see a more accurate picture of your data at each node in Preview. By widening the sample size and selecting the mode to arrange your data, data sampling helps prevent working without preview data. Select **Filtered Rows** to isolate specific values.
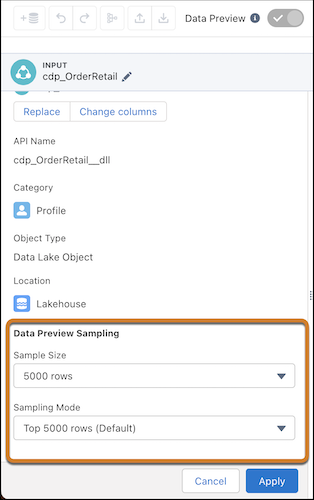
By default, the sample size is set to 2000 and the Sampling Mode is set to the top 2000 rows. This means that Preview shows the first 2000 rows of your data.
1. In an Input node, under Data Preview Sampling, select a **Sample Size**. This is the number of rows to include in preview. By default, the sample size is set to 2000. The Sampling Mode is set to the top 2000 rows.
2. Under Sampling Mode, select the mode that best fits your data. Select A**ll Column Values** to populate a sample when you need to see all column values, such as when creating a bucket. Select **Filtered Rows** to isolate specific values.
3. If you choose the Filtered Rows sampling mode, click the **+** under Filter and choose the column value to filter on. Select the values to include in your filtered results. To include currency fields in a filter, set the currency for the transform. Setting the currency after creating a transform resets the preview.
4. Click **Apply**.
# Data Q&A Agent Considerations and Troubleshooting
Review key considerations for the Data 360 Data Q&A Agent, and troubleshoot common issues such as unexpected results, low confidence scores, or missing data.
### Required Editions
## Considerations
- The agent is read-only. It can't modify data, create or alter objects, or execute DDL statements.
- The agent respects your data access permissions. You can only query data that you have permission to see based on your user permissions and Data 360 data access settings.
- Always validate critical business decisions by reviewing the generated SQL query and the agent's assumptions. The agent's confidence score indicates how certain it is about its interpretation of your question.
- If the agent's interpretation doesn't match your intent, rephrase your question or provide more specific details about fields, time ranges, or filters.
- Responses are influenced by Metadata Knowledge Graph and Semantic Enrichments Indexing status. If metadata changes haven't been indexed yet, the agent may not be aware of new fields or objects.
- Add semantic enrichments to improve the agent's understanding of your business context, terminology, and calculation methods. See [Guide Data Q&A with Semantic Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_semantic_enrichments_overview.htm&release=264.0.0&type=5 "Add semantic statements to help the Data 360 Data Q&A Agent better understand your data's business context, domain-specific terminology, and relationships.").
## Troubleshoot Data Q&A Agent
If the agent provides unexpected results or fails to answer your question, check the following:
Check Data Q&A Indexing status
From Setup, search for Data Q&A Indexing in Feature Manager and verify it's enabled. Indexing runs every 2 hours when metadata changes. If you recently added fields or objects, the agent sometimes isn't aware of them until the next indexing run completes.
Review active semantic enrichments
Conflicting or overly broad semantic enrichments can cause the agent to misinterpret your question. Go to **Semantic Enrichments** and filter by Active status. Check if any enrichments contradict each other or apply too broadly to your data model.
Verify field mappings
If the agent can't find the data you're asking about, verify that your objects are correctly mapped and that the field names match what you're referencing in your question.
Rephrase your question
If the confidence score is low, try rephrasing your question with more specific field names, explicit time ranges, or clearer filter conditions. For example, instead of "show me revenue," try "show me total amount\_usd\_\_c from Opportunity where stage equals Closed Won." Or define a semantic enrichment that outlines API name relationships.
Check the generated SQL query
Click **View More Details** to see the SQL query the agent generated. Look for incorrect table joins, missing filters, or field name mismatches. If the SQL is wrong, the issue may be a semantic enrichment providing incorrect guidance.
# Data Quality Calculated Insight: Contact Points Per Individual
Review the number of contact points for each source record to find outliers. Outliers can help you identify issues with your source data or data mappings. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.

DQ Source - Individual - CP Summary

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__Individual__dlm.ssot__Id__c AS Individual_Id__c,
APPROX_COUNT_DISTINCT( ssot__ContactPointEmail__dlm.ssot__Id__c ) AS unq_Email_CPs__c,
APPROX_COUNT_DISTINCT( ssot__ContactPointPhone__dlm.ssot__Id__c ) AS unq_Phone_CPs__c,
APPROX_COUNT_DISTINCT( ssot__ContactPointAddress__dlm.ssot__Id__c ) AS unq_Address_CPs__c,
APPROX_COUNT_DISTINCT( ssot__PartyIdentification__dlm.ssot__Id__c ) AS unq_Party_Identifiers__c,
APPROX_COUNT_DISTINCT( ssot__Device__dlm.ssot__Id__c ) AS unq_Devices__c
FROM ssot__Individual__dlm
LEFT JOIN ssot__ContactPointEmail__dlm ON ssot__ContactPointEmail__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__ContactPointPhone__dlm ON ssot__ContactPointPhone__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__ContactPointAddress__dlm ON ssot__ContactPointAddress__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__PartyIdentification__dlm ON ssot__PartyIdentification__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__ContactPointApp__dlm ON ssot__ContactPointApp__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__Device__dlm ON ssot__Device__dlm.ssot__Id__c = ssot__ContactPointApp__dlm.ssot__DeviceId__c
GROUP BY
Individual_Id__c
```
# Data Quality Calculated Insight: Summary by Source
Review the number of unique contact points per data source. The number of unique contact points is the number of source records consolidated in identity resolution. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.

Tip
- If you’re matching on the Device DMO and Advertiser Id field add additional JOINS to the Contact Point App object to your calculated insight.
- If any contact point columns return 0, review your mappings to the Individual DMO for the data source in Data Streams.

DQ Source - Summary by Source

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__Individual__dlm.ssot__DataSourceId__c AS DataSourceId__c,
ssot__Individual__dlm.ssot__DataSourceObjectId__c AS DataSourceObjectId__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__Id__c) AS unq_Individuals__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointPhone__dlm.ssot__Id__c) AS unq_PhoneCPs__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointEmail__dlm.ssot__Id__c) AS unq_EmailCPs__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointAddress__dlm.ssot__Id__c) AS unq_AddressCPs__c,
APPROX_COUNT_DISTINCT(ssot__PartyIdentification__dlm.ssot__Id__c) AS unq_PartyIdentifiers__c
FROM ssot__Individual__dlm
LEFT JOIN ssot__ContactPointPhone__dlm
ON ssot__ContactPointPhone__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__ContactPointEmail__dlm
ON ssot__ContactPointEmail__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__ContactPointAddress__dlm
ON ssot__ContactPointAddress__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
LEFT JOIN ssot__PartyIdentification__dlm
ON ssot__PartyIdentification__dlm.ssot__PartyId__c = ssot__Individual__dlm.ssot__Id__c
GROUP BY
DataSourceId__c,
DataSourceObjectId__c
```
# Data Quality Calculated Insights: Contributing Contact Points
Review occurrences of repeat values for Contact Point Address, Contact Point Email, Contact Point Phone, and Party Identification objects. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.

Tip Improving data quality in your source data source improves unified profiles in Data 360. To improve source data:
- Consider removing repeat values from your source data and ingesting data into Data 360 again.
- Consider filtering out repeat values using a formula field in Data Streams.

DQ Source - Address Contact Point

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__ContactPointAddress__dlm.ssot__AddressLine1__c AS AddressLine1__c,
ssot__ContactPointAddress__dlm.ssot__CityId__c AS CityId__c,
ssot__ContactPointAddress__dlm.ssot__CountryId__c AS CountryId__c,
APPROX_COUNT_DISTINCT( ssot__ContactPointAddress__dlm.ssot__PartyId__c ) AS unq_Individuals__c,
APPROX_COUNT_DISTINCT( ssot__ContactPointAddress__dlm.ssot__Id__c ) AS cnt_Occurances__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__FirstName__c) AS unq_FirstNames__c
FROM ssot__ContactPointAddress__dlm
LEFT JOIN ssot__Individual__dlm ON ssot__Individual__dlm.ssot__Id__c = ssot__ContactPointAddress__dlm.ssot__PartyId__c
GROUP BY
AddressLine1__c,
CityId__c,
CountryId__c
```

DQ Source - Email Contact Point

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__ContactPointEmail__dlm.ssot__EmailAddress__c AS EmailAddress__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointEmail__dlm.ssot__PartyId__c) AS unq_Individuals__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointEmail__dlm.ssot__Id__c) AS cnt_Occurances__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__FirstName__c) AS unq_FirstNames__c
FROM ssot__ContactPointEmail__dlm
LEFT JOIN ssot__Individual__dlm ON ssot__Individual__dlm.ssot__Id__c = ssot__ContactPointEmail__dlm.ssot__PartyId__c
GROUP BY
EmailAddress__c
```

DQ Source - Phone Contact Point

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__ContactPointPhone__dlm.ssot__FormattedE164PhoneNumber__c AS FormattedE164PhoneNumber__c,
APPROX_COUNT_DISTINCT(ssot__ContactPointPhone__dlm.ssot__PartyId__c) AS unq_Individuals__c,
COUNT(ssot__ContactPointPhone__dlm.ssot__Id__c) AS cnt_Occurances__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__FirstName__c) AS unq_FirstNames__c
FROM ssot__ContactPointPhone__dlm
LEFT JOIN ssot__Individual__dlm ON ssot__Individual__dlm.ssot__Id__c = ssot__ContactPointPhone__dlm.ssot__PartyId__c
GROUP BY
FormattedE164PhoneNumber__c
```

DQ Source - Party Identifier Contact Point

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
ssot__PartyIdentification__dlm.ssot__PartyIdentificationTypeId__c AS Type__c,
ssot__PartyIdentification__dlm.ssot__Name__c AS Name__c,
ssot__PartyIdentification__dlm.ssot__IdentificationNumber__c AS Number__c,
COUNT(ssot__PartyIdentification__dlm.ssot__Id__c) cnt_Occurances__c,
APPROX_COUNT_DISTINCT(ssot__PartyIdentification__dlm.ssot__PartyId__c) unq_Individuals__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__FirstName__c) AS unq_FirstNames__c
FROM ssot__PartyIdentification__dlm
LEFT JOIN ssot__Individual__dlm ON ssot__Individual__dlm.ssot__Id__c = ssot__PartyIdentification__dlm.ssot__PartyId__c
GROUP BY
Type__c,
Name__c,
Number__c
```
# Data Refresh Process for Extraction
Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge\_kav objects.
### Required Editions
**Data Refresh Phases**
There are two phases for data refresh (or data sync):
- Full refresh: The entire source data replaces the entire destination data.
- Incremental refresh: Updates are made in between full refresh cycles. Each incremental update extracts data from the start time of the prior extraction to the current time.
All data refresh phases have two stages:
- Extraction of data from the source org.
- Ingestion of data to the Data 360 target org.
Extraction has to succeed before ingestion begins. The data stream **History** panel shows extraction and ingestion errors or successful ingestions. Data 360 considers ingestion as successful when the data lake object (DLO) contains the extracted data. The history panel doesn’t show a successful extraction, as the subsequent ingestion flow encapsulates it into the success message.

Note In rare cases where a data stream fails on extraction, you can assume the data stream is in a bad state. For example, if connectivity between the source and target orgs is interrupted, the refresh can surface the interruption as an error. If the issue is transient but there's no new data to extract, no message is sent.
**Full or Incremental Refresh On Demand**
To minimize unnecessary refreshes and data transfers for objects that don’t require regular refresh, you can perform a full or incremental refresh on demand. To refresh a specific data stream on demand, click the **Refresh Now** button for that stream on the **Data Streams** tab. This table describes the refresh process for different on-demand request scenarios.

Note You can't refresh any data stream with a [ContentVersion object](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_contentversion.htm) on demand, even if you click the **Refresh Now** button.
on-demand refresh request scenario / refresh history setting
batch
streaming
none
The data stream is incrementally ingesting since its last periodic full refresh,
see Configure Periodic Full Refresh Schedule .
The user initiates an on-demand incremental refresh.
Data 360 ignores the on-demand request.
Data 360 ignores the on- demand request.
Data 360 initiates a new incremental refresh.
The data stream is incrementally ingesting since its last periodic full refresh,
see Configure Periodic Full Refresh Schedule .
The user initiates an on-demand full refresh.
If there's an existing request, Data 360 cancels it and initiates a new full
refresh.
If there's an existing request, Data 360 ignores the full refresh.
If there's an existing request, Data 360 cancels it and initiates a new full
refresh.
The data stream stopped ingesting in the past due to an error, which is now
resolved.
Ingestion hasn't run for a duration greater than the full refresh interval days,
see Configure Periodic Full Refresh Interval .
The user initiates an on-demand incremental refresh.
Data 360 triggers a full refresh instead of an incremental refresh.
Data 360 triggers a full refresh instead of an incremental refresh.
Data 360 triggers a full refresh instead of an incremental refresh.
The data stream is healthy but hasn't received a request for ingestion for a
duration greater than the full refresh interval days, see Configure Periodic Full Refresh Interval .
The user initiates an on-demand incremental refresh.
Data 360 triggers a full refresh instead of an incremental refresh.
**Knowledge Articles and Content Version Objects Unique Refresh Behavior**
Content version streaming through [ContentVersion objects](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_contentversion.htm) and knowledge article streaming through [Knowledge\_Kav objects](https://developer.salesforce.com/docs/atlas.en-us.knowledge_dev.meta/knowledge_dev/sforce_api_objects_knowledge__kav.htm) follow unique refreshing patterns.
**Content Version Special Day-Zero Behavior:** Unlike the initial data syncing behavior for other objects, Data 360 doesn’t bring all the ContentVersion object data from the CRM org on the initial sync. Instead, it brings the data that gets created or updated after the time the data stream is created, as part of a full refresh.
**Knowledge Article Refreshing Behavior:**
SYNC type
behavior and scope
Day-Zero
On the initial sync when the data stream is created, Data 360 syncs the latest
versions of articles.
Incremental Sync
New articles : Data 360 syncs the latest version (status:
Published ) and all their previous versions (status:
Archived ).
Articles updated during incremental period : Data 360
syncs the latest versions and their older versions—only if the older versions get
updated during the incremental period.
Full Refresh (Subsequent)
Data 360 syncs Published articles only.
Archived articles aren't synced.
- **[Configure Periodic Full Refresh Schedule](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_periodic_full_refresh_schedule.htm&release=264.0.0&type=5)**
The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered.
- **[Configure Periodic Full Refresh Interval](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_full_refresh_interval.htm&release=264.0.0&type=5)**
The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered. By default, the full refresh configurable interval is disabled (set as None). You can configure its value during a bundle or multi-object data stream deployment or for an existing data stream.
#### See Also
- [_Salesforce Help_: Configure Periodic Full Refresh Schedule](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_periodic_full_refresh_schedule.htm&release=264.0.0&type=5 "The periodic full refresh schedule for a Salesforce CRM connector data stream is determined by a number of variables, including a full refresh interval that you can configure to determine when the full refresh is triggered.")
# Data Services Billable Usage Types for Data 360
Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.

Note If your Data 360 orgs operate under a Customer Data Platform license, refer to [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.") instead.
Review your org’s licenses and Digital Wallet to determine how your org is billed.
- If your org operates Data 360 under a Customer Data Platform license, \* refer to [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&language=en_US&type=5) instead.
- If your org operates under a Data Cloud license and has an active Data Services consumption card, refer to Data Services Billable Usage Types for Data 360 instead. If you also have a Data 360 Profiles license, some usage is unmetered. Refer to Data 360 License Billing Considerations for details.
- If your org operates Data 360 under a Data Cloud license but doesn’t have an active Data Services consumption card, this article describes how credits are consumed.
The number of credits consumed is based on the number of units of each usage type used multiplied by the multiplier listed on the rate card for the usage type.
Actual usage is summed for each usage type and credits are decremented at a fractional rate. The minimum number of credits decremented from a usage type is 1, where fractional usage amounts to 1 or more credits over the monthly billing period.
In Digital Wallet, Data 360 consumption for customers with Data Services is tracked on the following consumption cards.
## Data 360 Profiles Licenses
If a Data 360 Profiles or Data 360 Enterprise Profiles license is added to your Data 360 org, some features stop consuming credits. Refer to Data 360 Profiles License Billing and Limits for more details or review the feature’s Billing Considerations article.
## Data Service Usage
Service usage calculations are based on records processed, queried, or analyzed. Service usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
Billing Category
Description
Internal Data Pipeline
Usage is calculated based on the number of
rows of structured data ingested from Salesforce via the Salesforce CRM connector, Marketing
Cloud connector, B2C Commerce CDP connector, Salesforce B2C Commerce Intelligence connector,
and Marketing Cloud Personalization connector.
As of August 7, 2025, usage of this type is
included with Data 360 and doesn't consume credits. For details, see Ingest Salesforce Data into Data 360 for
Free .
Batch Data Pipeline (External Data Pipeline)
Usage is calculated based on the number of rows
batch data processed by Data 360 data streams across all connectors, with the exception of
structured data ingested via the Internal Data Pipeline.
Streaming Data Transforms
Usage is calculated based on the higher of
the number of rows read or the number of rows written.
When performing joins, the number
of rows read is calculated by multiplying the number of records from the streaming input
object by the number of joined objects.
Batch Data Transforms
Usage is calculated based on the higher of the
number of rows read or number of rows written.
For incremental batch data transforms,
after the first time a transform runs, usage is based on the number of rows that have
changed since the previous run.
Streaming Data Pipeline (External Data
Pipeline)
Usage is calculated based on the number of
rows of streaming data processed by Data 360 across all data streams with stream processing,
with the exception of structured data ingested via the Internal Data Pipeline.
Data
streams that report usage with this usage type include streams created by the Website and
Mobile App connector and streaming ingestion API. When you use ingestion API in bulk mode,
it uses the Batch Data Pipeline usage type instead.
Unstructured Data Processed
Usage is calculated based on the amount
of unstructured data that is processed without using AI assisted content processing and
extraction. For example, if the search index processes 100 PDF documents that are 1 MB each,
usage is calculated as 100 MB. If the search index processes five audio/video files that are
on average 100MB each, usage is calculated as 500MB.
In Data 360, unstructured data may
be chunked and vectorized using an embedding model. Usage is computed only once across both
these activities. For example, if one 100 MB PDF document is chunked and vectorized, usage
is computed as 100 MB, not as 200MB.
If you create a search index that uses a data
model object (DMO) as a data source and select Text data type fields from the DMO, all
strings from those fields are indexed and the sum total of all bytes processed is reported
as Unstructured Data Processed.
Intelligent Processing
Usage is calculated based on the amount of
unstructured data that is processed using AI-assisted features such as LLM-based parsing,
LLM-based visual data preprocessing, image processing, Enriched Indexing, and Intelligent
Context.
Data Share Rows Shared (Data Out)
Usage is calculated based on the total number
of records processed when you first create a data share and link to a data share target.
This applies only to the initial full batch of data; subsequent incremental changes don't
count toward this usage type.
For data sharing between Data 360 orgs, this usage type
isn’t applicable to the source org.
Data Federation or Sharing Rows
Accessed
For data federation, usage
is calculated based on the number of records retrieved from the source. For a data share,
usage is calculated based on the number of rows returned to fulfill an external data lake’s
request. The number of rows accessed depends on the structure of the query and isn’t the
same as the number of rows in the source data.
For data sharing between Data 360 orgs,
this usage type applies to the target org for all queries.
For external data shares,
this usage type applies only to cross-cloud and cross-region queries. There’s no credit
consumption if the query originates from the same region and the same cloud.
Private Connect Data Processed
Usage is calculated based on the volume of data in
GBs that are transferred over the private network route. This applies to the transfer of
data into Data 360 and the transfer of data to an external data source.
Batch Profile Unification
Usage is calculated based on the number of
source profiles processed by an identity resolution ruleset. After the first time a ruleset
runs, only new or modified source profiles are counted. A source profile is an individual
and their related records, such as contact points and party identifiers, which are included
in the identity ruleset.
For example, modified means deleted profiles, or profiles marked
as suppressed via Consent API preferences.
Sub-second Real-Time Events
Usage is calculated based on the sum of the number of profile events, engagement events,
and API calls processed in the sub-second real-time layer, including accelerated data
ingest, web and mobile SDKs traffic, server to server API traffic, and real-time ingestion
API. Profile events, engagement events, and API calls are processed in the real-time layer
if they are associated with a real-time data graph.
For example, if 3 profile events, 10 engagement events, and 20 API calls are processed
during a particular billing period, the total processed is 33.
Batch Calculated Insights
Usage is calculated based on the number of
records in all underlying objects used in creating the Calculated Insight each time it
runs.
The number or underlying object records takes into account data space filters. If
there are no changes to the underlying objects, there will be no charge for the Insight job
processing. In the case an object is used multiple times in the Insight definition, the
records processed will only be counted once.
Streaming Calculated Insights
Usage is calculated based on the number
of records processed.
Inferences
Usage is calculated based on the number of unique
inferences produced by a predictive model. A single inference includes one prediction and,
optionally, one or more prescriptions and one or more top predictors. Inferences are
consumed for any predictive AI model used, whether internal (built in Einstein Studio AI) or
external (Bring Your Own Model).
Data Queries
Usage is calculated based on the number of records
processed.
The count of records processed depends on the structure of a query as well as
other related factors such as the total number of records in the objects being
queried.
Streaming Actions (including lookups)
Usage is calculated based on the number of records
processed. A lookup is an enrichment from a related object.
Segmentation
Usage is calculated based on the number of records
processed.
Batch Activations
Usage is calculated based on the number of records
processed.
Activate DMO - Streaming
Usage is calculated based on the number of records
processed in the data model object (DMO). Records processed are based on the number of new
records created or updated in the DMO per Activation.
If a data graph is being used with
the activation, the number of records processed will be doubled in the final calculation.
For example, when a data graph is being used with the activation, if there is 1 new record
change in the DMO, this will count as 2 records processed.
Code Extension
Usage in this type is measured in Compute Units. The
number of Compute Units consumed per hour depends on the compute size selected. The total
number of Compute Units is calculated based on the hourly consumption rate and the total
compute time your code consumes.
Accelerated Data Queries
As of August 16, 2024, usage is no longer
billed to this category.
## Data Storage Allocation
Storage refers to the amount of data stored in Data 360. Storage used outside of Data 360, such as data stored on the Salesforce Lightning Platform, isn't counted toward this limit. Storage usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
| Billing Category | Description |
| --- | --- |
| Storage Beyond Allocation | Usage is calculated based on the amount of storage used above the amount allocated. |
## Data Spaces
Data space usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
| Billing Category | Description |
| --- | --- |
| Data Spaces | Usage is calculated based on the number of data spaces beyond the default data space. |
## Segmentation and Activation
As of September 4, 2025, this consumption card is no longer in use. Usage consumed by the Segmentation, Batch Activations, and Activate DMO - Streaming usage types after September 4, 2025 is recorded against the same usage types on the Data Services card.
Billing Category
Description
Segmentation
Usage is calculated based on the number of records
processed.
Batch Activations
Usage is calculated based on the number of records
processed.
Activate DMO - Streaming
Usage is calculated based on the number of records
processed in the data model object (DMO). Records processed are based on the number of new
records created or updated in the DMO per Activation.
If a data graph is being used with
the activation, the number of records processed will be doubled in the final calculation.
For example, when a data graph is being used with the activation, if there is 1 new record
change in the DMO, this will count as 2 records processed.
## Ad Audiences Service Usage
Service usage calculations for ad audiences are based on the number of audiences.
| Billing Category | Description |
| --- | --- |
| Ad Audiences | Usage is calculated based on the number of ad audience targets. |
## Data 360 Real-Time Profiles
Service usage calculations for real-time service is based on the number of records associated with real-time data graphs.
Billing Category
Description
Sub-second Real-Time Profiles &
Entities
Usage is calculated based on the total
number of unique and active visitors during the billing month. Each unique visitor is
counted only once per month, regardless of how many times they appear or engage.
For
example, if 1 million unique visitors become active each day for 30 days, the total count
is 1 million unique active visitors for that month.
#### See Also
- [_Salesforce.com_: Data Cloud Data Services Rate Card](https://www.salesforce.com/products/platform/customer-data-cloud/services/)
# Data Shares
Data Shares provide easy access for external systems to use data in Data 360. With access to data lake objects (DLOs), data model objects (DMOs), and calculated insight objects (CIOs), you can build powerful analytical insights and machine learning models. Zero copy data sharing with data shares lets you share Data 360 objects without loading the data into an external system and gives you near real-time access to data.
Combine Data 360 objects in a data share and then connect to an external system through a data share target. A data share target sets up connectivity with an external system.

Important
- Data shares don't honor the data governance policies enforced by Data 360. Apply those policies at the data share target.
- Admins or privileged users in the receiving organization other than Salesforce Data 360 can view and query all records of the data lake objects (DLOs) mapped to data model objects (DMOs) in the data share. This depends on the security construct defined at the external system.
- **[Manage Data Shares](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_data_shares.htm&release=264.0.0&type=5)**
Create, edit, clone, or delete data shares in Data 360. You can also link or unlink a data share to a data share target.
- **[Share Data with Snowflake V2](https://help.salesforce.com/s/articleView?id=data.c360_a_access_data_from_snowflakev2.htm&release=264.0.0&type=5)**
Share Data 360 data with Snowflake using the Snowflake V2 connector. Create a data share target, link data shares, and migrate legacy targets.
- **[Share Data with Snowflake (Legacy)](https://help.salesforce.com/s/articleView?id=data.c360_a_access_data_from_snowflake.htm&release=264.0.0&type=5)**
To access Data 360 data, create a data share that contains Data 360 objects. You can access Data 360 objects as views in a Snowflake account. When data is available in Snowflake, you can work on harmonized and unified data.
- **[Share Data with Google BigQuery](https://help.salesforce.com/s/articleView?id=data.c360_a_access_data_from_google_bigquery.htm&release=264.0.0&type=5)**
You can access Data 360 objects as datasets in Google BigQuery by creating a data share. Zero copy integration allows data to be directly shared and queried without copying it into Google BigQuery. When data is accessible in Google BigQuery, you can work with harmonized and unified data from Data 360. Sharing data involves these high-level steps.
- **[Share Data with Amazon SageMaker](https://help.salesforce.com/s/articleView?id=data.c360_a_access_data_from_redshift.htm&release=264.0.0&type=5)**
Amazon SageMaker includes AWS Glue Data Catalog Views, AWS Lake Formation, and AWS engines to run queries using Amazon Redshift, Athena, or Elastic MapReduce (EMR). Share Data 360 objects, such as data lake objects, data model objects, and calculated insights objects, with an Amazon Redshift account using a data share.
- **[Share Data with Databricks](https://help.salesforce.com/s/articleView?id=data.c360_a_share_data_with_databricks.htm&release=264.0.0&type=5)**
Share Data 360 objects with a Databricks account using a data share. Link the data share to a Databricks data share target to make the Data 360 objects available to the Databricks account.
- **[Share Data with Databricks Using Query Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_access_data_from_databricks.htm&release=264.0.0&type=5)**
Securely share Data 360 data with Databricks without migrating your data from Data 360 to Databricks by running federated queries using Zero Copy Data Federation. You can access your data lake, data model, and calculated insight objects in your workspace using the Unity Catalog in Databricks.
- **[Share Data Between Data 360 Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_share_data_between_dc_orgs.htm&release=264.0.0&type=5)**
Share Data 360 objects, such as data lake objects (DLOs), data model objects (DMOs), and calculated insights objects (CIOs), between Data 360 instances in different regions or with other Data 360 orgs using a data share.
- **[Troubleshoot Data Share Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_troubleshooting.htm&release=264.0.0&type=5)**
Get tips for solving the most common data share and data share target errors.
# Data Source Configuration in Data 360
To connect data sources, review the admin tasks that must be completed first. After they’re configured in Data Cloud Setup, data streams can be created for each data source. Find information about all the varieties of data source connectors, their configuration, and data stream setup under Connect Data.
- **[Configure User Permissions for an External Salesforce Org Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setting_user_permissions_to_connect_external_org.htm&release=264.0.0&type=5)**
For non-admin users to connect an external Salesforce org to Data 360, they must have the required user permissions assigned by the main Data 360 account.
- **[Set Up Connectors with Google OAuth](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_oauth_google.htm&release=264.0.0&type=5)**
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
- **[Set Up Connectors with LinkedIn OAuth](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_oauth_linkedin.htm&release=264.0.0&type=5)**
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using LinkedIn OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
- **[Set Up Connectors with Microsoft OAuth](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_oauth_microsoft.htm&release=264.0.0&type=5)**
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
- **[Set Up Connectors with OpenId Connect OAuth](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_oauth_openid.htm&release=264.0.0&type=5)**
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
- **[Disconnect a Data Source](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_data_source.htm&release=264.0.0&type=5)**
If needed, a data source can be disconnected and removed from Data 360. This disconnect removes all provided data.
# Data Sources in Data 360
Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.
A data source can be a Salesforce connector, such as the Marketing Cloud Engagement connector or CRM connector. Salesforce connectors offer starter data bundles that pre-define objects and mappings to help you quickly set up a data stream.
Other services are available to connect data sources using SDKs and through the Ingestion API. You can also expand your data source possibilities using the MuleSoft Anypoint Connector or one of our third-party integrations. New connectors are added regularly to expand what data can be ingested into Data 360, providing more value when unifying your data.
- **[Salesforce Connectors for Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_connectors.htm&release=264.0.0&type=5)**
In Data Cloud, you can connect to other Salesforce data sources. Many of the connectors for these data sources have a starter data bundle to help you quickly set up a data stream. A starter data bundle is a Salesforce-defined data stream definition that includes mapping to the Data Cloud DMO structure. You can also customize a bundle. Some connectors offer multiple data bundle options.
- **[Web and Mobile App Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_web_mobile_app_connector.htm&release=264.0.0&type=5)**
Connect your web and mobile apps to Data Cloud to collect customer engagement data. This data helps you customize messages, create automations, or support AI projects. After it’s connected, set up data streams to ingest your data into Data Cloud, allowing you to access and query this data for various uses.
- **[Zero Copy Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_byol_data_federation.htm&release=264.0.0&type=5)**
The Data 360 zero copy data federation is the process of querying data from multiple, physically distinct data sources. This approch allows users to treat disparate systems as a single logical system, called a federation, while maintaining the autonomy of each system. Importantly, data federation avoids duplicating data across system boundaries. Data 360.
# Data Space Aware Objects and Features
User access to data space-aware objects and features is controlled by setting the object permissions and feature permissions in the user's permission sets. Not all objects and features are data space aware.
These objects are data space aware.
- Data lake objects (DLOs)
- Data model objects (DMOs)
- Calculated insight objects (CIOs)
- Data graphs
These Data Cloud features are data space aware.
- Data shares
- Data graphs
- Identity resolution
- Calculated insights
- Einstein Studio AI models
- Data actions
- Segmentation
- Activation
- Data semantic search
- Search Index
If you have View All Records and Modify All Records permissions on the primary object for a feature, you can view the object metadata regardless of the data space scope access.
## System-Level Permissions and Data Space Access
System-level permissions such as View All Records (VAR) and Modify All Records (MAR) don't automatically associate a user with a Data Space. However, users who have these permissions can query data-space-aware objects according to the permissions granted by those system-level permissions. Data Space assignments continue to control access to Data Space-scoped features and administrative operations.
To access Data Space-scoped features and resources, users must be explicitly assigned through Data Cloud Data Space Management. Users with system-level permissions such as VAR or MAR may still be able to query data-space-aware objects based on their granted permissions.
This behavior ensures that Data Space access control remains enforced in compliance-sensitive and multi-tenant environments.
## Billing Considerations for Data Space-Aware Features
For billing purposes, all records in a source object are counted even if a downstream process uses a filtered version of the object associated with a specific data space. This is because the data space-specific version of the object is a virtual view of its source object. Queries to a data space-specific object return a filtered view of the source object’s data that is created from all records stored in the object.

Example
Suppose a data lake object (DLO) with 100 records is associated with two different data spaces. In one data space, the filtered view of the DLO contains 75 records. In the second data space, the filtered view of the DLO contains 50 records. However, the number of records counted for billing purposes is 100 records.

Example
Suppose a data lake object (DLO) that contains 50 records is created within a specific data space. It isn’t associated with any other data spaces. The number of records counted for billing purposes is 50.
# Data Space Filters in Data Transforms
Data space filter behavior in data transforms differs based on whether the transform uses DLO or DMO inputs. This distinction helps you anticipate which records appear in preview and which records the transform processes when it runs.
In features that view DLO data, such as Query Editor or Data Explorer, you select a data space before viewing the data. Any data space filters defined on the DLO are active when viewing the data. In data transforms, this behavior differs based on the input types of the transform.
## DLO Transforms
In data transforms that use DLOs as input sources, the data preview behaves similarly to Query Editor or Data Explorer. Before viewing preview data, you select a data space for each input node. Filters from the selected data spaces are applied to the input DLOs and used to generate the data preview.
For data preview, all input nodes in the transform must use the same data space.
When a DLO transform runs, it processes all records in the input DLOs—data space filters don't apply at run time. To control which records downstream users see, either add the output DLO to a data space, or add a filter node to the transform before the output.
## DMO Transforms
In DMO transforms, the data space is set at transform creation—no separate selection is needed on each input node to generate a preview. Filters from this data space are applied to DLOs mapped to the transform's input DMOs and are used to generate the data preview.
When a DMO transform runs, the transform's data space filters apply to DLOs mapped to the input DMOs. The transform processes these filtered records and writes the results into a new DMO.
# Data Space Mapping Filter Operators
Use these operators to define filters when mapping Data Lake Objects (DLOs) to a data space. These filters make sure that only the relevant subset of your data is accessible within a specific data space.
### Required Editions
| Operator | Description | Supported Data Types |
| --- | --- | --- |
| Is Equal To | Matches values that are the same as the specified value. | Text, Number, Boolean |
| Is not Equal To | Matches values that aren’t the same as the specified value. | Text, Number, Boolean |
| Is In | Matches if the value is found within a provided list. | Text, Number |
| Is Not In | Matches if the value isn’t found within a provided list. | Text, Number |
| Contains Any | Matches if the field contains any of the specified values. | Text, List |
| Is Greater Than | Matches values that are higher than the specified value. | Number, Date, DateTime |
| Is Less Than | Matches values that are lower than the specified value. | Number, Date, DateTime |
| Last Number of Days | Matches values that fall within the specified number of past days. | Date, DateTime |
# Data Space References in Standard Consumption Tags
Filter and group reports about your Data 360 consumption usage by data space.
The data space name is captured in the Data Space API field in the TenantUsageAttrDetail data lake object (DLO). To use it, build a Data 360 report that breaks down consumption by data space by joining the TenantEnrichedUsageEvent and TenantUsageAttrDetail DLOs on Tenant Billing Usage Event Id.
You don’t consume credits when querying or reporting on these DLOs. You can build reports in other ways, such as by reporting on the Consumption Insights Extended data model object (DMO) or creating a Tableau Next Viz. Some reporting methods can consume credits.
Data space attribution is only available for usage types related to data space aware features. on the Data 360 Data Services consumption card, these usage types can be grouped and filtered by data space.
- Data Queries
- Unstructured Data Processed
- Data Transforms on data model objects
- Batch Profile Unification
- Segments Processed
- Calculated Insights
- Batch Activations
- Activate DMO - Streaming
- Streaming Actions
- Sub-second Real-Time Events
#### See Also
- [_Salesforce Help_: Example: Create a Report on Usage by Data Space Using Our DLOs](https://help.salesforce.com/s/articleView?id=xcloud.wallet_custom_report_dcr_dataspace_join.htm&language=en_US)
# Data Stream and Data Lake Object Refresh History
Data 360 provides record-level statistics of the data ingested by data streams and records processed into a data lake object (DLO).
## Data Stream Refresh History
View the Refresh History tab on the data stream record home for the record statistics. After the initial ingestion of data into Data 360, a data stream pulls new data based on specific schedules and refreshes the data. The data refresh information can vary based on the connector that the data stream ingests the data from.
| Field Name | Description |
| --- | --- |
| Refresh Date | The date and time of the last data refresh, displayed in your org’s time zone. |
| Refresh Mode | The way data is refreshed during each cycle, such as a full or incremental refresh. |
| Duration | Time taken for the data refresh. |
| Status | The status of the last refresh. |
| Records Processed | The number of records processed during the refresh cycle. |
| Records Added | The number of records ingested or added during the refresh cycle. |
| Records Removed | The number of records deleted from Data Cloud during a refresh cycle. |
| Problem Records | The number of problem records not ingested due to data quality issues. If a row encounters partial failures, the system counts the row as one problem record. Similarly, if a row encounters a total failure, the system counts the row as one problem record. The system focuses on the number of rows affected, not the individual failures within a row. |
## Data Lake Object Refresh History
View the Refresh History tab on the DLO record home for the record-level statistics. The statistics are aggregated in hourly time windows, and the refresh history is kept for up to 20 days. The information is available for DLOs that are used by data streams and data transforms. If there are no changes to data records in a DLO during the time window, no details are listed on the Refresh History tab.
| Field Name | Description |
| --- | --- |
| Start Time | The beginning time of an hourly time window for aggregating the record-level statistics. It’s displayed in your org time zone. |
| End Time | The end time of an hourly time window for aggregating the record-level statistics. It’s displayed in your org time zone. |
| Total Records | The total number of records in the DLO at the end of the time window. |
| Records Added | The number of records that are added to the DLO during the time window. |
| Records Updated | The number of records that are updated in the DLO during the time window. |
| Records Removed | The number of records that are deleted from the DLO during the time window. |

Note The field mapping counts displayed on the DLO record home don't match the fields that show as mapped on the data stream field mapping page. This is because mappings for certain system fields are system managed and don't appear on the field mapping page.
## Understanding the Difference Between Data Stream and DLO Metrics
Data Stream Refresh History and DLO Refresh History provide different views of your data.
| Feature | Data Stream History | DLO Refresh History |
| --- | --- | --- |
| Perspective | Business Logic View | Storage View |
| Focus | Records processed from the source (for example, Snowflake) | File-level operations in the Data Lake storage |
| Records Added | New records from the source | Records written to new storage files |
| Records Removed | Records deleted from the source | Records from storage files being rewritten or replaced |

Note Data 360 uses Apache Iceberg to manage data storage in Parquet files. Apache Iceberg is a table format that tracks which files contain your data. When data changes, Apache Iceberg often rewrites entire files. To update even one record, Data 360 marks the old file as deleted (removing all its records) and creates a new file with both the old records and the changes.
**Example**
You process 13,169 new rows into a table that already has 7,083,765 rows.
- Data Stream shows: 13,169 Records Added
- DLO Refresh shows: 7,083,765 Records Removed and 7,096,934 Records Added
Data 360 rewrote the entire 7M+ row table to safely commit the 13K changes. Total Table Count = Records Added - Records Removed.
For billing and credit consumption, always refer to Data Stream Refresh History metrics, which reflect the actual business data processed.
# Data Stream Schedule in Data 360
Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.
To see the refresh history of a data stream, access the data stream’s record page and click **Refresh History**.
Initiate a manual refresh of the data stream by clicking **Refresh Now** in the data stream’s record page.
## B2C Commerce
When you create a B2C Commerce data stream using the Order Bundle, Data 360 loads 30 days of historical data. After you deploy the data stream, Data 360 pulls new data based on this schedule.
Data Stream Name
Data Type
REFRESH MODE
REFRESH SCHEDULE
BundleProduct
Other
Full Refresh
Daily
GoodsProduct
Other
Full Refresh
Daily
MasterProduct
Other
Full Refresh
Daily
ProductCatalog
Other
Full Refresh
Daily
ProductCategory
Other
Full Refresh
Daily
ProductCategoryProduct
Other
Full Refresh
Daily
ProductOption
Other
Full Refresh
Daily
ProductOptionValue
Other
Full Refresh
Daily
ProductProductOption
Other
Full Refresh
Daily
SalesOrder
Engagement
Upsert
Hourly
SalesOrderCustomer
Profile
Full Refresh
Hourly
## Cloud Storage
Data streams that use cloud storage sources such as AWS S3 or Google Cloud Storage (GCS) are refreshed on a pre-defined schedule, or manually through the data stream record home. For more information, see [Amazon S3 Storage Connector](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-connector.html) and [Google Cloud Storage Connector](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-gcs-connector.html).
## Ingestion API
The Ingestion API provides a RESTful interface that supports both streaming and bulk interaction patterns for programmatically loading data into Data 360. With Bulk Ingest API you can move large amounts of data on a daily, weekly, or monthly schedule. Streaming Ingest API processes small micro-batches of records in near-real time. For information on expected latency, review [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") or [Customer Data Platform Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.").
## Marketing Cloud Personalization (formerly Interaction Studio)
The Marketing Cloud Personalization connector ingests user and event data into Data 360.
- Users—This data is ingested incrementally in upsert mode. Only users who engage after the bundle is deployed are synced to Data 360.
- Standard engagement events—Data for Catalog events, Cart & CartLineItem events, and Order & OrderLineItem Events. This data is ingested incrementally in insert mode.
- Custom engagement events—This data is ingested incrementally in insert mode.
The connector is set up with a predefined bundle requiring little configuration. New Marketing Cloud Personalization data is refreshed in Data 360 hourly. Data 360 performs an incremental update of engagement data streams within 2 minutes and a full refresh of user data streams within 15 minutes.
## Marketing Cloud Engagement
Data streams that use the Marketing Cloud Engagement connector are automatically scheduled to pull data either daily or hourly, depending on the type of data. No user input is required. Automation Studio handles this process. Supporting automations are scheduled dynamically, depending on when the connection was established or when the data stream was created. Don’t change the schedule after creation because it can create problems for data in transit.

Note There’s a timing difference between adding records in Engagement and exporting data to S3 for ingestion in Data 360 via a data stream. Extracting historical data from Engagement takes up to 24 hours, and ingestion processes one time daily. The application reflects the status of the Refresh Mode, which runs hourly, and allows you to see only extracted data. Incremental updates occur for data with a current or future date. Historical data for past dates aren’t included in the incremental update.
| Data Type | Refresh Schedule |
| --- | --- |
| Standard | Daily |
| Standard Data Engagements | Hourly |
| Data Extension Full Extract | Daily |
| Data Extension Delta Extract | Hourly |
## Salesforce CRM
The Salesforce CRM connector conducts full and incremental refreshes on a set schedule, requiring no action from you.
Type
Schedule
Details
Full
Configurable
Periodic full refresh is disabled in new data streams, and in existing data
streams within developer edition orgs, to save costs where refresh is not
required.
To enable periodic full refresh, you can configure its schedule by
setting the full refresh interval.
Incremental
Every 10 minutes
Incremental refreshes start after a full refresh and fetch changes that have
been made since the last full refresh.
When a field is deleted, it’s processed in the next incremental refresh.
Refresh times vary.
Formulas are refreshed during a full or incremental refresh and are recalculated if a record has changed.
To minimize unnecessary refreshes and data transfers for objects where regular refreshes are not required, perform a full or incremental refresh on demand in alignment with your business requirements. To refresh on demand, click the **Refresh Now** button for a specific data stream on the **Data Stream** tab.
You can view the refresh history on the Data Stream record home page. The refresh history includes details such as whether a full or incremental refresh occurred. If no changes have been made since the last update, the refresh history shows 0 for events.
Data streams are processed as batch or streaming. For more information, see [Salesforce CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.").
## Mobile and Website Connectors
Mobile and Website connectors provide streaming ingestion through Engagement SDK and Salesforce Interactions SDK respectively to send data from customer-owned mobile apps and websites into Data 360. For efficiency, mobile events are queued on the device to save processing power and bandwidth.
#### See Also
- [_Salesforce Help_: Configure Anonymous Data Export](https://help.salesforce.com/s/articleView?id=mktg.mc_pers_salesforce_cdp_anonymous_data_export.htm&type=5&language=en_US)
- [_Salesforce Help_: Connect Data](https://help.salesforce.com/s/articleView?id=data.c360_a_connectors.htm&release=264.0.0&type=5 "Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Data Stream Settings and Refresh Modes
With data streams, you can schedule or run jobs to ingest data from a source system. These jobs pull data from the source system into the connected data stream. The method and frequency options for data ingestion depends on the type of connector. Use the data stream settings to create or change the execution parameters of a data stream.
### Required Editions
Available in: Lightning Edition
## Refresh Modes
The Refresh Mode settings determine how data is ingested into a data lake object (DLO). Efficient use of these modes ensures data freshness and cost reduction by improving data processing efficiency.
Setting
Description
Incremental
This mode is available for most non-file-based data streams that have a
Datetime field. Select the field that indicates when the incoming record was last
modified. For each refresh, the data stream is updated with data added or changed
since the last refresh.
To make sure that there’s no data loss, the last few
records from the previous run are reprocessed during each job run.
To remove
records from an incrementally updated DLO, mark deleted records in your source
system with a Delete Record Flag. For example, record_delete_flag =
true. The DLO will then remove these records during the next update.
You can permanently delete them from your source system after a successful update
run.
Incremental refresh is also supported in Zero Copy Data Federation, but
deletion of records during incremental refresh operations isn't supported. For
more information, refer Caching or Acceleration in Data Federation .
Upsert
This mode is available for data streams created from file-based connectors. For
each refresh, the data stream is updated with data added or changed since the last
refresh.
When the refresh mode is set to upsert, you can efficiently delete
records from a DLO using a file. See Delete Records by Using a Delete File .
Full Refresh
During each refresh cycle, all existing data is deleted and replaced with the
newly imported dataset. If no other refresh setting is available, full refresh is
the default refresh mode.
## Conditional Settings
Setting
Description
Filter
Use a filter to extract only the records that fulfill the specified condition.
The syntax of the condition depends on the source system. For example, on a source
that relies on SQL92 syntax, the filter could be, s_nationkey = 10 and
s_acctbal > 2000.
When filtering on a DateTime field, the filter
value must include the time zone. Use either UTC format (for example,
2026-03-30 08:00:00Z) or local time with a time zone offset
(for example, 2026-03-30 15:00:00+07:00). This requirement
applies to all Data 360 connectors.
Data Explorer displays timestamps
in your user profile's time zone, or your org's default time zone (from
Company Information in Setup), without the time zone offset.
To get
the correct format for filters, use the Query Editor , which displays
timestamps in UTC.
Supported Operators
For database sources, see the list in the section entitled "Supported Operators" below for more details.
## File Settings
These settings are specific to data streams that use file-based connectors.
Setting
Description
Log an error if no file is found
When enabled and a file isn’t found during the data stream run, the line item
in the refresh history for that run shows a failure status. A notification is
triggered if you subscribe to data stream failure notifications. For more
information, see Data Cloud: Control Event Notifications Using
Flows .
When this setting isn’t enabled and a file isn’t found during the
data stream run, the refresh history shows 0 records but with a success status.
Is headerless file retrieval enabled
When set, Data 360 accepts the data records without headers.
Don’t turn on this setting while you’re creating the data stream because the header
information is necessary for the initial run when the schema is being generated. You
can enable the setting after the initial run.
To avoid data corruption, maintain
the order of fields in the incoming data records.
Refresh only new files
When set, all files are retrieved when the data stream is first run. For
subsequent runs, only new files are retrieved.
Refresh initial file immediately
When set, Data 360 doesn't wait until the scheduled run
and retrieves the initial file immediately.
## Supported Operators, Functions, and Keywords
For database sources,the `WHERE` clause supports the following:
Supported Operators
- Comparison: <, >, <=, >=, =, <>
- Pattern matching: LIKE, RLIKE
- Null checks: IS NULL, IS NOT NULL
- Set membership: IN, NOT IN
- Range evaluation: BETWEEN
- Uniqueness: DISTINCT
Supported Functions and Keywords
The following SQL functions and expressions are allowed within the `WHERE` clause:
- `CEIL`
- `CFLOOR`
- `CAST`
- `TRIM`
- `TIMESTAMP`
- `DATE`
Not Supported in the `WHERE` Clause
The following constructs are not supported and will result in an error if used:
- Data Manipulation Language (DML) operations: `INSERT`, `UPDATE`, `DELETE`
- Complex query structures: `JOIN,` `UNION`, `INTERSECT`, and subqueries
- Control characters: semicolons (;)
- Any other SQL functions or keywords not explicitly listed in the supported sections above
## Schedule
The frequency setting describes the time interval between executions of your data stream job. Based on connector capabilities, supported schedule intervals can vary.
Setting
Description
Frequency
Set the frequency of data refresh by choosing the relevant frequency. The
available refresh frequencies are:
Hourly
Daily at a specified hour
Weekly on a specified day and time
Monthly on a specified day and time
All frequency times are in UTC and are applicable for both full and
incremental refreshes.
Amazon Simple Storage Service (Amazon S3), Azure Blob Storage, and Google Cloud Storage data streams have 5-, 15-,
or 30-minute intervals. These connectors can synchronize data and deduplicate jobs
to provide these narrow intervals.
# Data Stream Updates Using File Upload
Update the data of an existing data stream created using File Upload. Quickly update your data by re-uploading the revised CSV file with added or removed records. Updating data replaces the data that was previously stored in the associated Data Lake Object (DLO). It also ensures that the data stream is always current with the latest information.
Before you upload data, verify that your file is less than 2 GB and has a maximum of 1,050 columns. Use the four-digit ("yyyy") format for date and time records that include a year. When data from an ingested file uses the two-digit ("yy") format, additional date and time pattern rules for the ["year"](https://docs.oracle.com/javase/8/docs/api/java/text/SimpleDateFormat.html) are applied. This can result in an unexpected date value.

Important File updates aren't supported while the last run status is **Pending**, **Extracting**, or **In Progress**. Wait until the data stream status is **Active** and the last run status shows **Success** or **Error** before uploading a new file.

Important To update an existing data stream, upload a revised file with columns that exactly match the original file. If the columns don't match, your data won't upload correctly.
You can update a data stream created with File Upload from the data streams list view or the overview page.
## Data Streams List View
You can view data streams created from an uploaded file on the list view page. To update a file for a specific data stream, go to your data stream and use the dropdown option on the right side of the page to select this option.
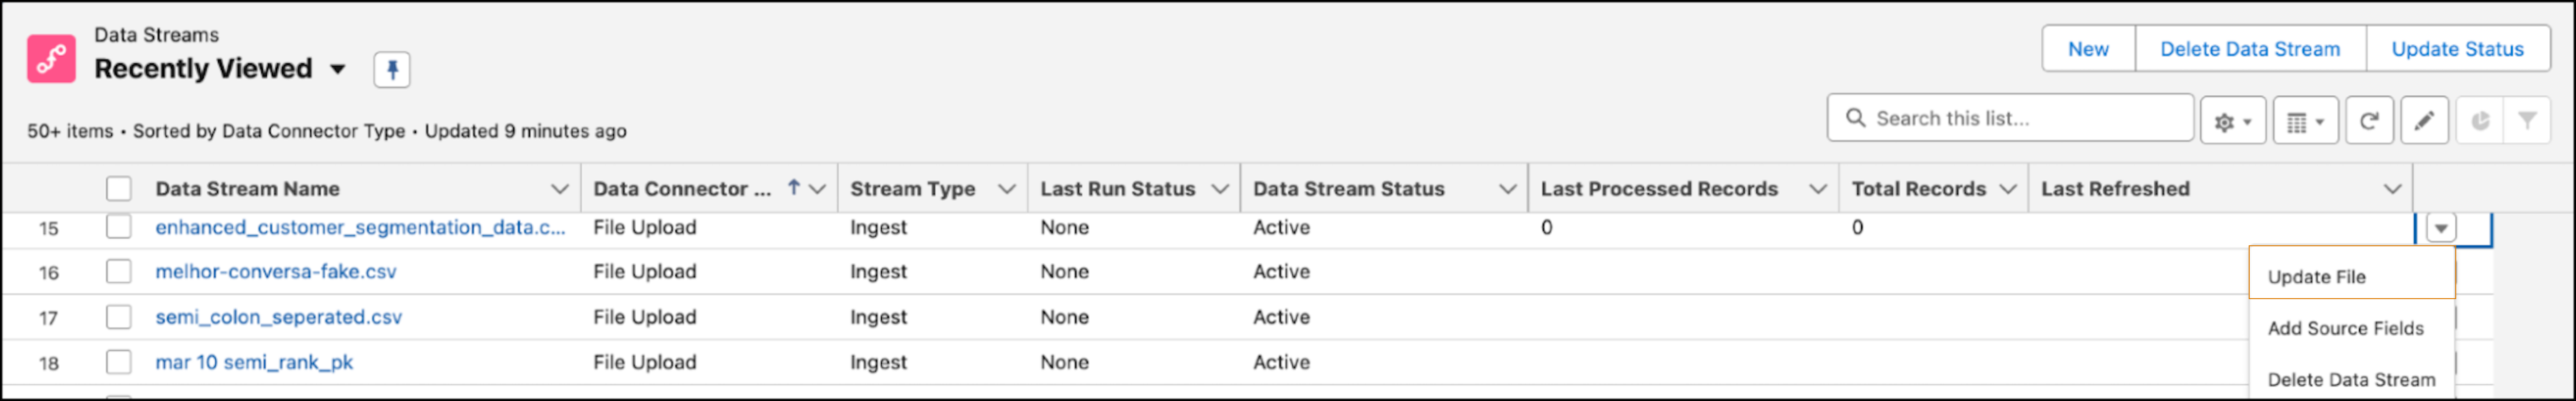
## Data Stream Overview
After you create a new data stream using an uploaded file, you can see its details on its overview page. Additionally, you can find the option to update your file.
# Data Streams in Data 360
Data streams are the connections and associated data ingested into Data 360.
Navigate, edit, and review data stream schedules in this help section. Review the [Data Sources in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_connectors.htm&release=264.0.0&type=5 "Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.") section to know about data streams supported in Data 360 and the steps to create the data streams.
- **[Billing Considerations for Data Ingestion](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_ingestion.htm&release=264.0.0&type=5)**
Data Ingestion uses Data 360 to ingest data from external sources. Use of Data Ingestion impacts the consumption of credits in these usage types.
- **[Data Streams Tab Navigation](https://help.salesforce.com/s/articleView?id=data.c360_a_data_streams_tab.htm&release=264.0.0&type=5)**
On the Data 360 Data Streams tab, you can view all existing data streams, including the data streams you own. You can also create a data stream.
- **[Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5)**
Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.
- **[Data Stream Settings and Refresh Modes](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_edit_settings.htm&release=264.0.0&type=5)**
With data streams, you can schedule or run jobs to ingest data from a source system. These jobs pull data from the source system into the connected data stream. The method and frequency options for data ingestion depends on the type of connector. Use the data stream settings to create or change the execution parameters of a data stream.
- **[Data Lake Object Naming Standards](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lake_object_naming.htm&release=264.0.0&type=5)**
Use these naming guidelines for data lake objects.
- **[Record Modified Field](https://help.salesforce.com/s/articleView?id=data.c360_a_record_modified_field.htm&release=264.0.0&type=5)**
The record modified field is set when defining the source object during setup in Data 360.
- **[Create a Data Stream from a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_install_package_kit.htm&release=264.0.0&type=5)**
When you create a data stream from a data kit in your target org, the data model objects are available automatically. When adding a data model to a data kit, a custom data model is added as is. If you’re adding a standard data model, only the custom mappings and custom fields are packaged.
- **[Update Database Configuration for Zero Copy Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_update_db_schema_after_deployment.htm&release=264.0.0&type=5)**
When deploying a data kit that contains zero copy data streams, you can update the target database, schema, or table after deployment to match your target environment.
- **[Create an Unstructured Data Lake Object from a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_create_udlo_from_data_kit.htm&release=264.0.0&type=5)**
After you have deployed your data kit in Data 360, you can create an unstructured data lake object (UDLO). All fields are automatically mapped.
- **[Disable a Data Stream Field](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_data_stream_fields.htm&release=264.0.0&type=5)**
If a field is no longer required in a data stream, you can disable it. Disabling a field removes it from the data stream, and no new data is ingested. You can’t assign the name of a disabled field to a new field.
- **[Delete a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_data_stream.htm&release=264.0.0&type=5)**
You can delete a data stream in Data 360 if the connection is no longer needed.
- **[Edit a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_data_stream.htm&release=264.0.0&type=5)**
Edit a data stream in Data 360 for the Amazon Simple Storage Service (Amazon S3), Google Cloud Storage (GCS), Azure, Marketing Cloud Engagement, and Secure File Transfer Protocol (SFTP) connectors. Changing the name of a data stream doesn’t change the name of the data lake object (DLO) that the data stream uses.
- **[Delete Ingested Records in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_stream_records.htm&release=264.0.0&type=5)**
You can delete data ingested into Data 360. Your data stream must have an upsert refresh mode. The deletion process depends on the type of connector that you’re using.
- **[Supported File Formats in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_file_formats.htm&release=264.0.0&type=5)**
Data 360 supports various files and compression formats for your data stream sources.
- **[Data Stream and Data Lake Object Refresh History](https://help.salesforce.com/s/articleView?id=data.c360_a_datastream_dlo_refresh_history.htm&release=264.0.0&type=5)**
Data 360 provides record-level statistics of the data ingested by data streams and records processed into a data lake object (DLO).
- **[Monitoring Data Stream Problem Records](https://help.salesforce.com/s/articleView?id=data.c360_a_datastream_dlo_problem_record.htm&release=264.0.0&type=5)**
Records that can’t be ingested into Data 360 due to data quality issues are logged as problem records and stored in a problem record data lake object (DLO). Problem records are created when data is ingested through: all structured ingest connectors, Web and Mobile App connectors, and Ingestion APIs.
- **[Using an Existing Data Lake Object to Create a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_guardrails_existing_data_lake_object.htm&release=264.0.0&type=5)**
You can use an existing data lake object (DLO) when creating an S3, Google Cloud Storage, or SFTP data stream. The data stream that initially created the DLO defines the characteristics, such as the primary key, event date time, and record modified field. You can convey how the new data stream’s fields conform to the existing DLO fields.
- **[Ingest Data by Uploading a File](https://help.salesforce.com/s/articleView?id=data.c360_a_upload_a_csv_file.htm&release=264.0.0&type=5)**
Create a data stream by bringing in data from a local CSV file into Data 360.
- **[Troubleshoot Data Stream Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_troubleshoot_data_stream_errors.htm&release=264.0.0&type=5)**
Data streams can encounter various issues when importing data into Data 360. Use this troubleshooting section to identify and resolve common data streaming errors.
# Data Streams Tab Navigation
On the Data 360 Data Streams tab, you can view all existing data streams, including the data streams you own. You can also create a data stream.
When you visit the Data Streams tab for the first time, you may not see any data streams. Change the list view to see all existing data streams. To create a data stream, use the New button. Additionally after data streams are ingested into Data 360, they can be modified or deleted.

Note If you modify or delete fields for Marketing Cloud Engagement data streams, an error can occur. If you recreate the data streams later, the previously modified or deleted fields could cause the fields to populate incorrectly.
#### See Also
- [_Salesforce Help_: Edit a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_data_stream.htm&release=264.0.0&type=5 "Edit a data stream in Data 360 for the Amazon Simple Storage Service (Amazon S3), Google Cloud Storage (GCS), Azure, Marketing Cloud Engagement, and Secure File Transfer Protocol (SFTP) connectors. Changing the name of a data stream doesn’t change the name of the data lake object (DLO) that the data stream uses.")
- [_Salesforce Help_: Delete a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_data_stream.htm&release=264.0.0&type=5 "You can delete a data stream in Data 360 if the connection is no longer needed.")
# Data Subject Rights
A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.
In Data 360, these regulations include: Submit all data subject rights requests using the Salesforce Consent API.
- Data Deletion or Right To Be Forgotten (RTBF)
- Restrict Processing or Restriction of Processing (RofP)
- Data Access and Export

Note Learn more on how to [Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm).
You can submit data subject rights requests for individual profiles in Data 360. If you’re using Identity Resolution, submit requests for source individual profiles.
- **[Data Subject Rights Request](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights_request.htm&release=264.0.0&type=5)**
Learn more about how to submit Data Subject Rights requests in Data 360.
- **[Requesting Data Deletion or Right to Be Forgotten](https://help.salesforce.com/s/articleView?id=data.c360_a_data_deletion_request.htm&release=264.0.0&type=5)**
Learn more about how to submit Data Deletion requests in Data 360.
- **[Requesting Restriction of Processing](https://help.salesforce.com/s/articleView?id=data.c360_a_restrict_processing_request.htm&release=264.0.0&type=5)**
Learn more about how to submit Restriction of Processing requests in Data 360.
- **[Requesting Data Access and Export](https://help.salesforce.com/s/articleView?id=data.c360_a_data_access_request.htm&release=264.0.0&type=5)**
Learn more about how to submit Data Access and Export requests in Data 360.
- **[Checking Status of Data Subject Rights Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_checking_status_dsr_requests.htm&release=264.0.0&type=5)**
Learn how to check the status of your Data Subject Rights Requests in Data 360.
- **[Impact of Data Modeling on Data Subject Rights Requests](https://help.salesforce.com/s/articleView?id=data.c360_a_data_modeling_impact_on_dsr_requests.htm&release=264.0.0&type=5)**
Learn more about how Data Modeling impacts your Data Subject Rights Requests in Data 360.
# Data Subject Rights Request
Learn more about how to submit Data Subject Rights requests in Data 360.
Submit Data Subject Rights requests using Individual ID as the identifying parameter. Requests must be submitted and processed separately in all connected Salesforce clouds, including Commerce Cloud.
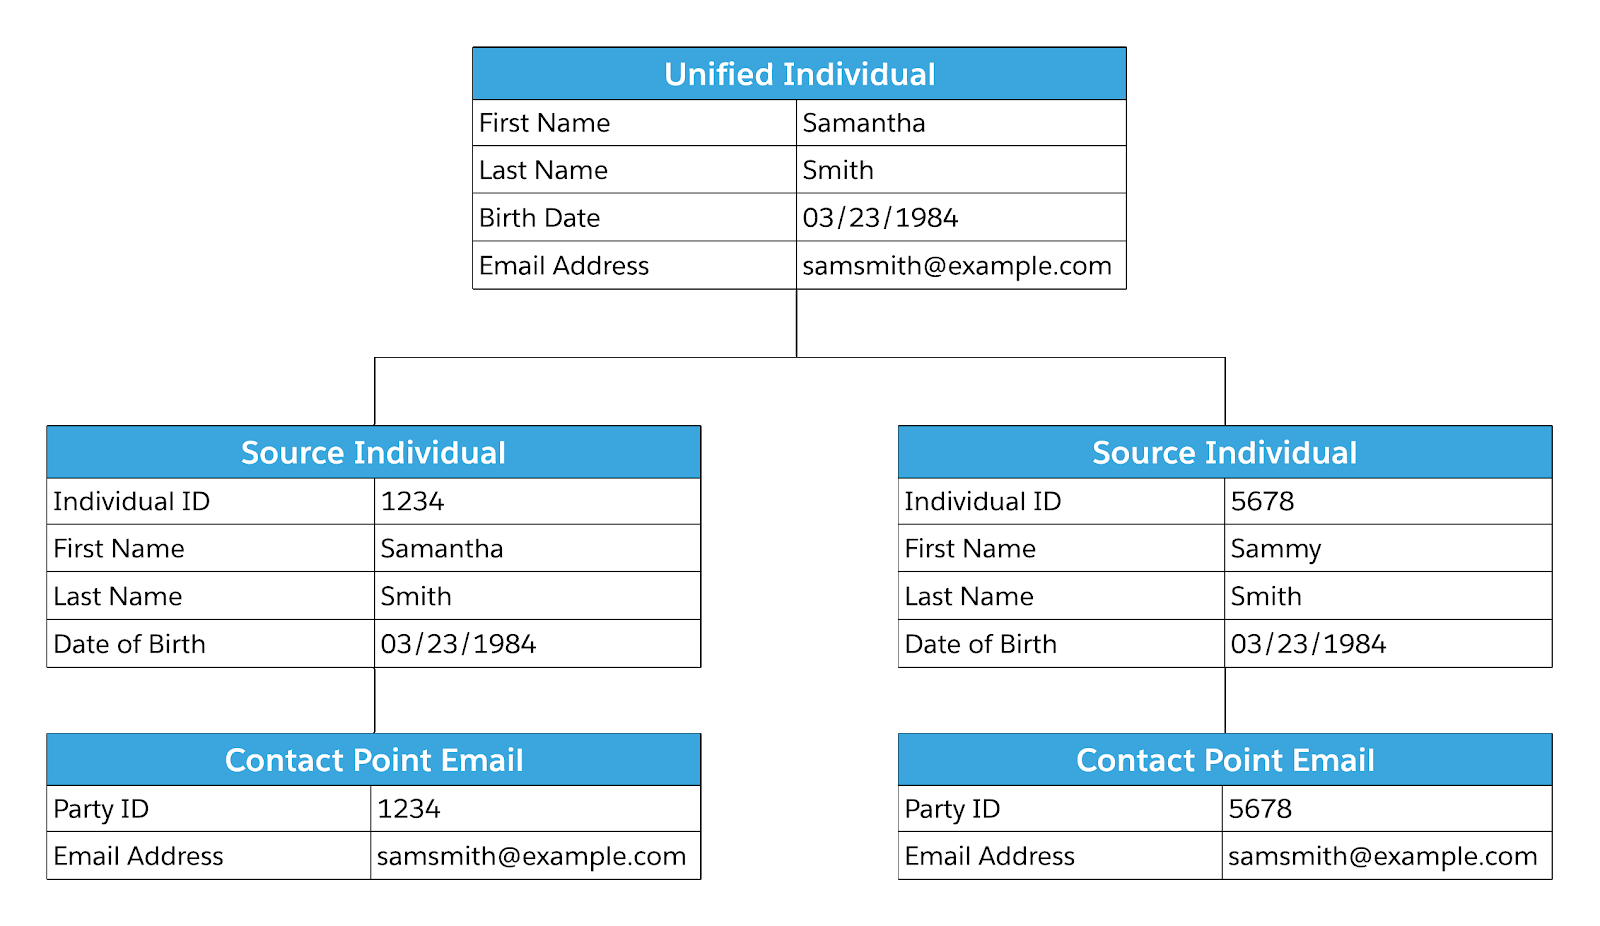

Example Northern Trail Outfitters (NTO) has a Unified Individual profile for Samantha Smith that consists of two Source Individual profiles. These Source Individual profiles are identified as Individual ID 1234 and 5678. Samantha requests that Northern Trail Outfitters delete her personal data. When processing Samantha’s request, NTO submits a data deletion request to the Consent API using Individual ID 1234 and 5678 in the relevant API parameters.
- **[Obtain an Individual ID](https://help.salesforce.com/s/articleView?id=data.c360_a_consent_obtaining_individual_id.htm&release=264.0.0&type=5)**
Learn how to obtain an Individual ID in Data 360.
#### See Also
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
- [_Salesforce Help_: Unify Source Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_source_profiles.htm&release=264.0.0&type=5 "Use identity resolution in Data 360 to consolidate data from different sources into comprehensive views of your customers and accounts. Identity resolution uses matching and reconciliation rules to link data about people or accounts into unified profiles. Identity resolution creates complete, actionable views of your customers but doesn’t create golden records and isn’t a master data management (MDM) system. Each unified profile contains all the unique contact point values from all sources. You choose which view of your customers to use based on each business use case you want to solve.")
# Data Tagging and Classification in Data 360
Data tagging is the process of attaching labels or metadata to data assets such as objects, fields, or records to describe their content, sensitivity, or purpose. Tags help identify and organize data so it can be easily searched, filtered, and governed.
Tagging transforms data governance from a manual task into a scalable, policy-driven approach. By linking policies to tags, enforcement becomes dynamic and adapts as data grows. Classification builds on this by grouping tags based on data value, sensitivity, or regulations, such as public, internal, or confidential. Together, tagging and classification help organizations understand their data and apply security, access, and compliance controls more effectively.
## Benefits
Instead of applying governance controls manually to each object or field, you can use standardized tags and classification levels to automate and streamline policy enforcement.
Tagging and classification enables scalability in various ways.
- Policy automation: Tags and classifications serve as triggers for governance policies. Once tagged, objects automatically inherit relevant access and masking policies, eliminating repetitive, manual configuration.
- Consistency across data: Applying a defined taxonomy ensures data is classified uniformly across teams, sources, and data types. This reduces ambiguity and minimizes policy gaps.
- Bulk enforcement through tag propagation: Object-level tags propagate to related downstream objects, and field-level tags propagate to the corresponding fields within those objects.
- Simplified governance for new data: The Suggest Tags feature uses LLM-based tagging to recommend appropriate tags and classifications based on metadata, making it easier to govern newly ingested or created data with minimal manual effort.
- Attribute-based access control (ABAC): Tags and classifications can be used as attributes in access policies, supporting fine-grained control based on data context rather than hardcoded roles or objects.
Tagging and classification decouple governance from individual data objects, allowing you to apply policies at scale with speed, accuracy, and reduced manual effort.
- **[Object-Level and Field-Level Tags in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_object_level_field_level_tags.htm&release=264.0.0&type=5)**
In data governance, you can use object-level tags and field-level tags to label and manage data at different levels of granularity.
- **[Manual and Automatic Tagging in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_manual_automatic_tagging.htm&release=264.0.0&type=5)**
There are two ways to apply tags to data: manual tagging and automatic tagging.
- **[Tag Propagation in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_tag_propagation.htm&release=264.0.0&type=5)**
Tag propagation helps maintain consistent data classification by extending tags from a primary data object to related or downstream objects and fields. This ensures that related objects in your data model carry the same metadata labels and reduces the need for repetitive tagging.
- **[Parent-Child Hierarchy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_parent_child_hierarchy.htm&release=264.0.0&type=5)**
A parent-child tag hierarchy organizes tags in a logical, multi-level structure, where broader, general tags (parents) are linked to more specific, detailed tags (children).
- **[Data Governance Taxonomy](https://help.salesforce.com/s/articleView?id=data.c360_a_taxonomies_in_data_gov.htm&release=264.0.0&type=5)**
In Data 360 data governance, a taxonomy is a hierarchical set of categories and subcategories (or tags) that classifies data based on its type, sensitivity, usage, or domain. Using taxonomies ensures consistent tagging, improves data discoverability, and enables accurate application of policies such as masking or access control. They also help align data classification with privacy and compliance requirements.
- **[Sensitive Data Classification in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_classify_data_sensitivity_usage.htm&release=264.0.0&type=5)**
Classifying data helps ensure it’s handled appropriately, securely, and in line with regulatory or internal standards. You can classify data by considering both its sensitivity (how confidential it is) and its usage (how and by whom it’s accessed or used).
# Data Target Configuration in Data 360
To configure data targets, review the admin tasks that must be completed first.
- **[Set Up an External Activation Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_external_activation_platform.htm&release=264.0.0&type=5)**
Reach more customers by connecting an external activation platform to Data 360. Install an external activation platform from AppExchange or a packaged URL.
- **[Set Up an Amazon S3 Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_an_amazon_s3_target_connection.htm&release=264.0.0&type=5)**
After you create your Data 360 instance, you can set up an Amazon S3 target connection.
- **[Set Up an Amazon Kinesis Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_an_amazon_kinesis_target_connection.htm&release=264.0.0&type=5)**
Send data action events from Data 360 to an Amazon Kinesis data stream. Use an access key or Salesforce as an OpenID Connect identity provider.
- **[Set Up an SFTP Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_an_sftp_target_connection.htm&release=264.0.0&type=5)**
Create an SFTP connection in Data 360 using your own SFTP server that’s not provided or used by Marketing Cloud Engagement.
- **[Set Up a Microsoft Azure Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_a_microsoft_azure_target_connection.htm&release=264.0.0&type=5)**
After you create your Data 360 instance, you can set up a Microsoft Azure Blob Storage Connection.
- **[Set Up a Google Cloud Storage Target Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_a_google_cloud_storage_target_connection.htm&release=264.0.0&type=5)**
After you create your Data 360 instance, you can set up a Google Cloud Storage (GCS) connection.
# Data to Decisions: Data 360 and Tableau Next
Tableau Next, Tableau Semantics, and Data 360 work together as a connected ecosystem to unlock the value of your data. With all three natively built into Salesforce and integrated with Agentforce, any team can discover analytical insights to make strategic decisions quickly.
## Analysis and insights on a unified data layer
Tableau Next uses Data 360 to create a unified and secure data layer. Data 360 ingests, unifies, and harmonizes both structured and unstructured data from different sources into a single source of truth. Its federated, zero-copy architecture allows for real-time queries of massive datasets without moving anything. Plus, Salesforce’s continued commitment to trust and privacy provides a trusted and secure and compliant foundation.
## Add business context with Tableau Semantics
Tableau Semantics is the AI-infused semantic layer that runs on top of Data 360's data sources and serves as a single source of truth for Tableau Next, AI, and other data consumption layers across Salesforce. With Tableau Semantics, you can add business context and metrics in semantic models, which provide a consistent way to interpret data across Salesforce with familiar business terms and consistent definitions. Built-in AI assistance and agent enrichment capabilities drive more accurate responses and relevant insights.
For information about creating and managing semantic models, including the C360 Semantic Model, see [Tableau Semantics](https://help.salesforce.com/s/articleView?id=analytics.semantics.htm&language=en_US).
## Analyze and consume with Tableau Next
Tableau Next is a composable, AI-analytics experience that uses the well-structured, contextualized data created in Data 360 and Tableau Semantics. Grounded in those trusted data layers and semantic models, Tableau Next lets you build powerful visualizations and ask questions about your data with conversational AI agents for analytics. These natural language prompts are translated into semantic queries, which result in accurate answers, actionable insights, and rich visualizations. With Tableau Next, you can bring those insights into the flow of work to take direct action within Salesforce or an integrated application like Slack.
## Resources
Learn more about using data in Tableau Semantics and Tableau Next.
# Data Type Compatibility in Data Federation
When federating data from external sources, the source data is converted to the corresponding Data 360 data types. If the source data contains a data type that's not supported in Data 360, the column is ignored. During data stream creation, fields whose data types aren’t supported in Data 360 are listed under the Unsupported Fields tab. Array, struct, and other nested datatypes are not supported in data federation.

Note Data federation doesn't support timestamp values from before January 1, 1990.
## Mapping Snowflake Data Types with Data 360 Data Types
| Snowflake Data type | Data 360 Data Type |
| --- | --- |
| NUMBER, DECIMAL, NUMERIC | Number |
| INT, INTEGER, SMALLINT, TINYINT, BYTEINT | Number |
| BIGINT | Number |
| FLOAT, FLOAT4, FLOAT8, DOUBLE, DOUBLE PRECISION, REAL | Number |
| VARCHAR, CHAR, CHARACTER, STRING, TEXT | Text |
| DATETIME, TIMESTAMP, TIMESTAMP\_LTZ, TIMESTAMP\_NTZ, TIMESTAMP\_TZ | DateTime |
| DATE | Date |
| BOOLEAN | Boolean |
| TIME | Not supported |
| VARIANT, OBJECT, ARRAY, GEOGRAPHY, GEOMETRY | Not supported |
| BINARY, VARBINARY | Not supported |
## Mapping Google BigQuery Data Types with Data 360 Data Types
| Google BigQuery Data type | Data 360 Data Type |
| --- | --- |
| BIGNUMERIC | Number |
| FLOAT64 | Number |
| INT64 | Number |
| NUMERIC | Number |
| STRING | Text |
| DATE | Date |
| DATETIME | DateTime |
| TIMESTAMP | DateTime |
| BOOL | Boolean |
| BYTES | Not Supported |
| TIME | Not Supported |
## Mapping Redshift Data Types with Data 360 Data Types
| Redshift Data type | Data 360 Data Type |
| --- | --- |
| SMALLINT | Number |
| INTEGER | Number |
| BIGINT | Number |
| DECIMAL | Number |
| REAL | Number |
| DOUBLE PRECISION | Number |
| CHAR | Text |
| VARCHAR | Text |
| DATE | Date |
| TIMESTAMP | DateTime |
| TIMESTAMPZ | DateTime |
| BOOL | Boolean |
| GEOMETRY | Not Supported |
| GEOGRAPHY | Not Supported |
| HLLSKETCH | Not Supported |
| TIME | Not Supported |
| TIMETZ | Not Supported |
| VARBYTE | Not Supported |
## Mapping Databricks Data Types with Data 360 Data Types
| Databricks Data type | Data 360 Data Type |
| --- | --- |
| BIGINT | Number |
| SMALLINT | Number |
| INT | Number |
| TINYINT | Number |
| DECIMAL(p,s) | Number |
| DOUBLE | Number |
| FLOAT | Number |
| STRING | Text |
| DATE | Date |
| DATETIME | DateTime |
| TIMESTAMP | DateTime |
| INTERVAL | Not Supported |
| ARRAY | Not Supported |
| BOOL | Boolean |
| STRUCT | Not Supported |
| MAP | Not Supported |
#### See Also
- [_Salesforce Help_: Zero Copy Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_byol_data_federation.htm&release=264.0.0&type=5 "The Data 360 zero copy data federation is the process of querying data from multiple, physically distinct data sources. This approch allows users to treat disparate systems as a single logical system, called a federation, while maintaining the autonomy of each system. Importantly, data federation avoids duplicating data across system boundaries. Data 360.")
# Data Type Conversion Transformations: Convert Column Types
The data type of a column determines how you can query that column’s data. For example, you can filter and group by a text or date column, or perform math calculations on a number column. Sometimes, fields are tagged incorrectly. If needed, use the column-type conversion transformations to convert columns to the correct types.
- **[Text to Date Transformation: Convert the Column Type](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_transformation_dimensiontodate.htm&release=264.0.0&type=5)**
A date column is sometimes tagged as text if it contains unexpected string values or dates in different formats. To use date functionality, such as grouping by month, use the Text To Date transformation to change the Text column type to Date.
- **[Text to Number Transformation: Convert the Column Type](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_transformation_dimensiontomeasure.htm&release=264.0.0&type=5)**
To perform a mathematical calculation on the column, such as calculating the average, use the Text To Number transformation to change the Text column type to Number. You can perform mathematical calculations on numeric columns only. Numeric types include the percent data type.
- **[Number to Text Transformation: Convert the Column Type](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_transformation_measuretodimension.htm&release=264.0.0&type=5)**
To group and filter by a numeric column, use the Number To Text transformation. You can group and filter by text columns only.
# Data Type Mappings Between Data 360 and Data Extensions
Map the Data 360 data types to their corresponding data extension data types in Marketing Cloud Engagement.
| Data 360 BUSINESS Data Type | Data 360 Base Data Type | Data Extension Data Type |
| --- | --- | --- |
| Boolean | Boolean | Boolean |
| Currency | Currency | Text |
| Date\_Only | Date | Date |
| Date | Datetime/Timestamp | Date |
| Email | Text | Email |
| Number | Number | Decimal/Number |
| Percent | Percent | Text |
| Phone | Text | Phone |
| Text | Text/String | Text |
| URL | Text | Text |
If a field with "Text" data type in Data 360 contains an email address, it is mapped to "Email" data type in data extension.
#### See Also
- [_Salesforce Help_: Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&type=5&language=en_US)
# Data Types for Insights SQL
When you define a calculated or streaming insight with SQL in Data 360, use the supported data types for your measures and dimensions. Measures are the numerical values you aggregate; dimensions are the qualitative fields you group by.
### Required Editions
## Measure Data Types
A measure is a numerical value enhanced by an aggregation function in an insight. Use one of these data types when you add a measure to an insight.
| Data Type | Notes |
| --- | --- |
| Currency | When you use aggregate currency values as a measure, you must convert them to a single currency using `TRY_CONVERT_CURRENCY`. |
| Integer | Whole number values with no decimal places. Use for counts or quantities that don't require fractional precision. |
| ListOfFloats | An ordered list of floating-point numbers. Use for vector or multi-value measures. |
| Number | Decimal (floating-point) values. Use for measures that require fractional precision. |
| Percent | Returns a number. For example, 50% + 1 = 51. |
## Dimension Data Types
A dimension is a qualitative field you use to categorize and group your measures. Use one of these data types when you add a dimension to an insight.
| Data Type | Notes |
| --- | --- |
| Boolean | True or false values. |
| Date | Includes timestamp. |
| DateOnly | Excludes timestamp. |
| Email | Returns data in text format when the insight uses a transform node. |
| Phone | Returns data in text format when the insight uses a transform node. |
| Text | String (character) values. |
| URL | Returns data in text format when the insight uses a transform node. |
# Data Types in Data 360
Data 360 supports these data types.
Data 360 BUSINESS Data Type
Data 360 Base Data Type
Description
Boolean
Boolean
Possible values are ‘true’, ‘false’, and blank.
Fields with boolean data type can’t be used as primary keys, record
modified fields, and internal organization fields.
Currency
Currency
Stores a currency value with a fixed scale of 38 and a precision of 18.
You can use multiple currencies and change the default currency at any time.
Each record is associated with a single currency type. In data lake
objects (DLO) and data model objects (DMO) a system field captures the currency
code associated with the currency values within a given record. The currency code
is a three-character ISO code, such as USD, EUR, INR.
You can’t use a currency field as a primary key or record modifier
field for engagement data.
Date_Only
Date
Holds the calendar date without a time part or time zone.
Example: yyyy-MM-dd, where yyyy is the year, MM is the month ranging
between 1–12, dd is the day ranging between 1–31.
If the incoming data record includes a time part for a field configured
as type date, the time part is ignored. For example, the value 01-01-2023 22:00:00
UTC is ingested and stored as 01-01-2023.
A value that can’t be parsed into a date is stored as a null value.
Date
Datetime/Timestamp
Stores an instant in time expressed as a calendar date and time of
day.
A valid datetime must include the time part and time zone. If they’re
not included, it’s inferred as 00:00:00 UTC. If the value can’t be parsed into a
datetime, it’s stored as a null value.
Abbreviated time zones like CST are considered ambiguous and aren’t
part of the ISO8601 standard.
Email
Text
Stores email addresses. The email data type is modeled on the text
data type. You can use any valid text value for ingestion into an email data type
field. Data 360 doesn’t validate the format.
You can explicitly
choose the email data type for a source field if you want it to be treated as an
email ID. You can use an email ID field as a primary key but not as an engagement
date field.
Formula functions that work with text values accept email data type
input. You can convert the text output from these formula functions into an email
data type.
Number
Number
Stores numbers with a fixed scale of 18 and a precision of 38.
Scale is the count of digits to the right of the decimal point in a number.
Precision is the total count of digits, regardless of the location of the decimal
point. For example, the number 123.45 has a precision of 5 and a scale of 2.
If an ingested number is out of the supported range or is a
non-numerical value, a null value is stored.
Percent
Percent
Holds percentage values. The percent data type is modeled on the number
data type. Only valid numeric values are accepted for ingestion into a percent
data type field.
You can explicitly choose the percent data type for a source field if
you want it to be treated as a percentage.
You can use a percent data type field as a primary key but not as an
engagement date field or internal organization field.
Formula functions that work with number values accept the percent data
type.
Examples of valid values: 34, 87.232, -0.76523
Examples of invalid values: 255%, 83.21 %, 25 Percent
Phone
Text
Stores phone numbers. Data 360 doesn’t validate the format of the
phone number. The phone data type is modeled on the text data type. Any valid text
value is accepted for ingestion into a phone data type field.
You
can explicitly choose the phone data type for a source field if you want it to be
treated as a phone number. You can use a phone number field as a primary key but
not as an engagement date field.
Formula functions that work with text values
accept phone data type input. You can convert the text output from these formula
functions into a phone data type.
Text
Text/String
Stores any kind of text data. It can contain both single-byte and multibyte
characters that the locale supports.
Zero length strings (“”) and no
value are treated as empty strings.
You must make sure that text fields such as
file name, wildcard, directory name, or formula syntax editor use ASCII characters.
UTF-8 sometimes contains non-ASCII characters that aren’t guaranteed to work
properly. Also, don't use : (colon) and ' (single
quote) in file names and formulas. The maximum supported limit for Text field values
is 31,072 characters. While this is the maximum limit that Data 360 is certified to
support, it isn't a hard limit.
URL
Text
Stores URL values. Data 360 doesn’t parse or interpret the
ingested URL value. It also doesn’t validate the value for correctness. Data 360
doesn’t store any metadata related to the URL.
You can explicitly
choose the URL data type for a source field if you want it to be treated as a URL.
You can use a URL field as a primary key but not as an engagement date
field.
The URL data type is modeled on the text data type. Any
valid text value is accepted for ingestion into a URL data type field.
Formula
functions that work with text values accept URL data type input. You can convert the
text output from these formula functions into a URL data type.
For more information about formula functions, see [Supported Library Functions](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_library_functions.htm&language=en_US&type=5).
When you create a data stream, Data 360 attempts to detect the data type of each field. When mapping a data lake object (DLO) to a data model object (DMO), the data type of the DLO field must match the data type of the DMO field. The only exception is that DLO fields with the Number data type can be mapped to DMO fields with the Text data type.

Tip To review and confirm or change the auto-suggested data types, scroll to the far right of your window.
Fields detected as date or datetime also include a recommended date and time format based on the raw data. Review the types and formats carefully and modify if necessary. For more information, see [Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.").

Important After creating a DLO, you can’t change the data types of its fields.
- **[Data Type Mappings Between Data 360 and Data Extensions](https://help.salesforce.com/s/articleView?id=data.c360_mapping_data_type_dc_mc.htm&release=264.0.0&type=5)**
Map the Data 360 data types to their corresponding data extension data types in Marketing Cloud Engagement.
- **[Data Type Compatibility in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_byol_data_federation_data_type_compatability.htm&release=264.0.0&type=5)**
When federating data from external sources, the source data is converted to the corresponding Data 360 data types. If the source data contains a data type that's not supported in Data 360, the column is ignored. During data stream creation, fields whose data types aren’t supported in Data 360 are listed under the Unsupported Fields tab. Array, struct, and other nested datatypes are not supported in data federation.
- **[Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5)**
Data 360 supports date and datetime data types.
# Data Types in Field Mappings
When mapping a data lake object (DLO) to a data model object (DMO), the data types of the DLO and DMO fields must be compatible.

Note After a DLO or DMO is created, you can’t change the data type of any fields. For more information, see [Data Type of Data Lake Object and Data Model Object Fields Cannot be Changed](https://help.salesforce.com/s/articleView?id=001233477&type=1&language=en_US).
| DLO Field Data Type | Compatible DMO Field Data Types |
| --- | --- |
| Boolean | Boolean |
| Currency | Currency |
| Date | Date |
| DateTime | DateTime |
| Email | Email, Phone, Text, URL |
| Percent | Percent, Number |
| Phone | Phone, Email, Text, URL |
| Number | Number, Text |
| Text | Text, Email, Phone, URL |
| URL | URL, Email, Phone, Text |
A system field cdp\_sys\_record\_currency\_\_c holds the currency ISO code for the currency value and it's auto-mapped. See [Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5 "Data 360 supports these data types.")
# Date and Datetime Formats
Data 360 supports date and datetime data types.

Important Refer to [DateTime offsets in CDP](https://help.salesforce.com/s/articleView?id=000394441&type=1&language=en_US) if you’re adjusting for a data stream created before Winter ’23.
A field with a date or datetime data type must be accompanied by a date and time format. Data 360 references this format while parsing the data and writing it into a data lake object (DLO).

Warning
The system suggests a date or datetime format based on a small sample of your source data, and it is your responsibility to verify the suggestion. If you accept an incorrect suggested format without reviewing it, your data can be corrupted without failures.
For example, if your source data uses MM/DD/YYYY but the system suggests DD/MM/YYYY, a date like 03/07/2024 will be interpreted as July 3, 2024, instead of March 7, 2024.
To avoid data corruption, manually verify that the suggested format matches your source data exactly before proceeding. Review multiple rows of your source file or data stream to confirm the correct format. If the system's suggestion doesn’t match your data, edit the format manually.
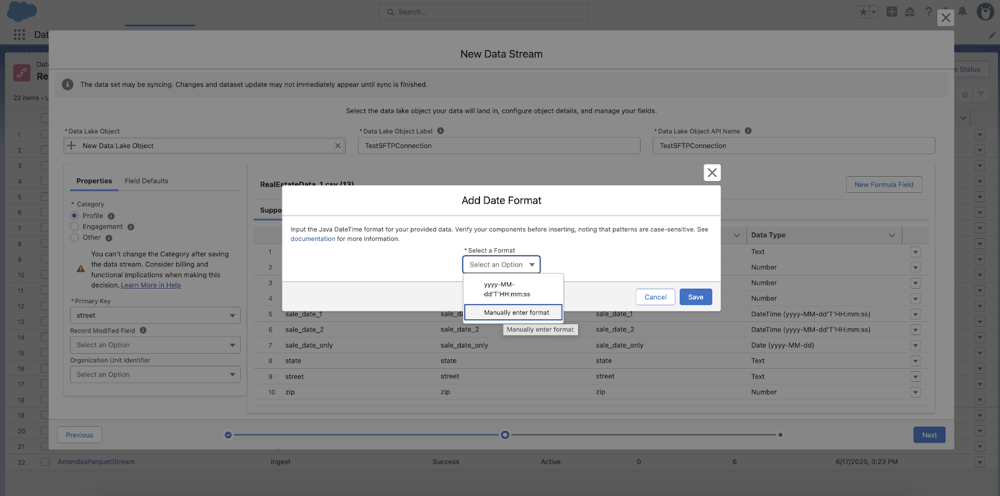
Data 360 recommends the applicable data type by reviewing the incoming raw data. It also suggests the format. If you choose to override a date type to a datetime or a datetime to a date type, make sure that the format stays the same so that it still reflects the format in the raw data.
Overrides are only available for file-based connectors (Amazon S3 Storage, Google Cloud Storage, Azure Storage, and SFTP).
The table samples the overriding behavior between date and datetime data types for these scenarios.
- **Raw Data:** Incoming data from the data source.
- **Recommended Data Type:** Data type auto-detected by Data 360.
- **Recommended Date and Time Format:** Date format suggested by Data 360 based on the raw data.
- **Overridden Data Type:** User specified data type.
- **Overridden Date and Time Format:** The date and time format that applies when overriding the data type.
- **Stored Format:** Format of the data stored in the DLO.
| Raw Data | Recommended Data Type | Recommended Date and Time Format | Overridden Data Type | Overridden Date and Time Format | Stored Format |
| --- | --- | --- | --- | --- | --- |
| 06/14/2022 | Date | MM/dd/yyyy | DateTime | MM/dd/yyyy | 06/14/2022 00:00:00 UTC |
| 06/14/2022 22:00:00 PST | DateTime | MM/dd/yyyy HH:mm:ss ZZZ | Date | MM/dd/yyyy HH:mm:ss ZZZ | 06/14/2022 |
| 06/14/2022 02:00:00 | DateTime | MM/dd/yyyy HH:mm:ss | Date | MM/dd/yyyy HH:mm:ss | 06/14/2022 |
The table shows the date and time pattern strings and their definitions. Use this table when validating the date and time format suggested for each field. The patterns are case-sensitive and failure to differentiate between cases can produce vastly different results. For example, “MM” is used to represent the month while “mm” represents the minute.
Letter
Date or Time Component
Examples
G
Era designator
AD
y
Year
1996, 96
Y
Week-based year
December 31, 2019
Output is 2020, as December 31 falls in the first week of
2020.
M
Month in year
July, Jul, 07
w
Week in year
27
W
Week in month
2
D
Day in year
189
d
Day in month
10
F
Day of week in month
2
E
Day name in week
Tuesday, Tue
U
Day number of week (1 equals Monday, 7 equals Sunday)
1
a
AM or PM marker
PM
H
Hour in day (0-23)
0
k
Hour in day (1-24)
24
K
Hour in AM or PM (0-11)
0
h
Hour in AM or PM (1-12)
12
m
Minute in hour
30
s
Second in minute
55
S
Millisecond
978
z
Time zone
Pacific Standard Time, PST, GMT-08:00
Z
Time zone
-0800
X
Time zone
-08, -0800, -08:00

Example If your dataset has a value like 2001-07-04T12:08:56.235-0700, the datetime format is mapped to this pattern according to the format yyyy-MM-dd ‘T’ HH:mm:ss.SSSZ.
- 2001 is the year 2001, represented as yyyy
- 07 is the month July, represented as MM
- 04 is the day in month, represented as dd
- T is a literal to separate the date from the time
- 12 is the hour in the day on a (0–23 hour clock), represented as HH
- 08 is the minute in the hour, represented as mm
- 56 is the seconds in the minute, represented as ss
- 235 is the milliseconds, represented as SSS
- \-700 is the time zone, represented as Z
## Ambiguous Date Formats
You might need to override a date format if the incoming values are ambiguous. For example, if all the sampled values have month and day parts like 01-02, Data 360 arbitrarily interprets it as either January 2 or February 1. However, if you apply the necessary context with the date and time pattern, the ambiguity is rectified.
If the month and day positions are reversed, the system may interpret the date as being years ahead, resulting in unexpected or future-dated records.
We don’t recommend using time zones represented by alphabetic abbreviations, such as EST, WST, or CST, because they can result in ambiguous interpretation. For example, CST can mean China Standard Time (UTC+8), Cuba Standard Time (UTC-5), and North American Central Standard Time (UTC-6).
Time zone abbreviations aren’t supported.
# Date and Time Transformations: Calculate on Date Fields
Date fields are key to understanding trends over time or keeping teams aware of upcoming milestones and deadlines. To calculate based on dates or make them more helpful to your analysis, use date and time transformations. Insert a column with the current date and time in a specified format with the Now option. Calculate the duration between two selected date columns as days, months, or years using Date Difference. And add or subtract days or months from a date column with the Add or Subtract Days or Months function.
- **[Add or Subtract Days or Months](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_add_subtract_time.htm&release=264.0.0&type=5)**
Return the column date with the specified days or months added or removed.
- **[Date Difference](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_duration_between_dates.htm&release=264.0.0&type=5)**
Calculate the duration between two selected date columns as days, months, or years.
- **[Now](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_now.htm&release=264.0.0&type=5)**
Create a column that displays the current date and time in a specified format. This transformation works without interacting with any other columns.
# Date Difference
Calculate the duration between two selected date columns as days, months, or years.
1. In a Transform node, select one date column in the Preview tab.
2. Select the **Formula** button () in the Transform toolbar.
3. Select **Date Difference**.
4. Configure the transformation.
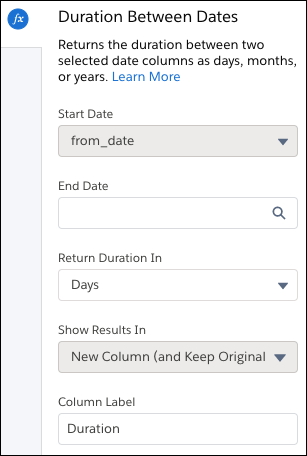
1. The start date is automatically filled with the date column you previously chose. To choose a different start date, cancel and restart.
2. The end date is the value used to calculate the duration from the start date. Choose a date column from your data or the **Now** option to use the current date and time.
3. Select whether to return duration as days, months, or years. Days are rounded up to the nearest value, while months and years include the selected number of decimal places.
5. Optionally, change the label of the column that stores the result in the Column Label field.
6. To add the transformation to the Transform node, click **Apply**. The Preview tab shows the new Now column.
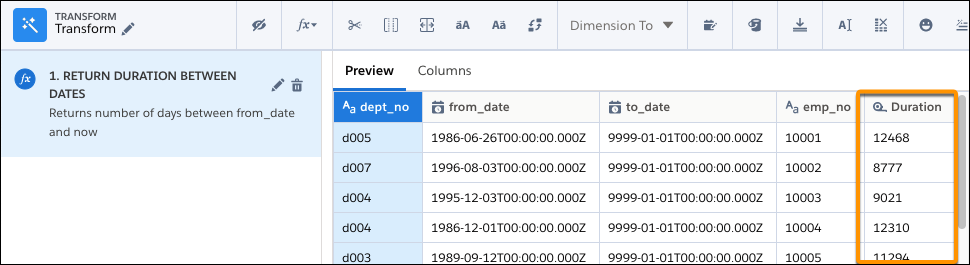
7. To view the canvas area, click the Collapse button .
After you run the batch data transform, you can view the calculated duration. The Now option uses the date and time when the batch data transform last ran, based on the UTC timezone.
# Date Functions for Formulas
Use date functions to adjust or calculate values from dates. For example, you can add time, find time until, and extract a day of the week from date fields. The arguments for date functions are date fields.
When entering a formula, use the API name of the field in the expression, not the label. The parameters section is surrounded by parentheses. For example, you can enter the following expression.
```
datediff(ClosedDate, CreatedDate)
```
Date Function
Description
Syntax
add_months
Returns the date with the specified number of months after the start date.
add_months(startDate ,num_months )
startDate
is the date field calculated on.
num_months is the number of months
added to the startDate .
current_date
Returns the current date.
current_date()
current_timestamp
Returns the current date and time.
current_timestamp()
datediff
Returns the number of days between start date and end date.
datediff(endDate ,startDate )
endDate
is the later of the two dates you are finding the difference
between.
startDate is the earlier of the two dates you are finding
the difference between.
date_add
Returns the date with the specified number of days after the start date.
date_add(startDate ,num_days )
startDate is the date field calculated on.
num_days is the number of days added to the startDate. Only
static integer values are accepted.
date_format
Converts the timestamp to a specified date format.
date_format(field ,'format ')
field
is a date field/timestamp or string to be converted to the given
format.
'format' is the date and time format pattern to
follow.
Example:
date_format('2016-04-08', 'y') returns
2016
date_sub
Removes the specified number of days from the start date.
date_sub(startDate ,num_days )
startDate is the date field calculated on.
num_days is the number of days subtracted from the startDate.
Only static integer values are accepted.
date_trunc
Resets the specified part of the timestamp, and all portions after it, to zero (or 01
for date and year). Specify the portion of the timestamp, fmt, with ‘year’, ‘quarter’,
‘month’, ‘week’, ‘day’, ‘hour’, ‘minute’, or ‘second’. For example, dateTrunc for ‘year’ of
2019-05-01 12:31:32 returns 2019-01-01 00:00:00. If your data is date and not datetime, use
the trunc function instead.
date_trunc('format' ,timestamp )
'format'
is the date and time format pattern to follow.
timestamp is a
date/timestamp or string which is returned as a UNIX timestamp.
Example:
date_trunc('week',CloseDate) returns the Monday
of the week of the Close Date.
day
Returns the day of the month component of the date/timestamp.
day(date )
date is the date field to
extract the day of the month from.
dayofmonth
Returns the day of the month component of the date/timestamp.
dayofmonth(date )
date is the date field
to extract the day of the month from.
dayofweek
Returns the day of the week component of the date/timestamp. 1 = Sunday, 2 = Monday,
..., 7 = Saturday.
dayofweek(date )
date is the date field to
extract the day of the week from.
dayofyear
Returns the day of year component of the date/timestamp.
dayofyear(date )
date is the date field to
extract the day of the year from.
months_between
Returns the number of months between two timestamps. Calculates the difference based on
31 days per month rounded to 8 digits unless roundOff=false. If timestamp1 is later than
timestamp2, the result is positive. If timestamp1 and timestamp2 are on the same day of the
month, or both are the last day of the month, the result is an integer and the time of day is
ignored.
months_between(timestamp2 ,timestamp1 ,roundOff(optional) )
timestamp2
is one of the timestamps to compare.
timestamp1 is the other
timestamp to compare.
roundOff(optional) is a boolean that
determines whether to round the result. This parameter is optional.
now
Returns the current date and time in the specified format.
now()
to_date
Converts the date string to the specified date format. Returns null with invalid
input.
to_date(field ,'format(optional)' )
field
is a date string field that you want to convert.
'format(optional)'
is the date and time format pattern to follow. This parameter is optional. The function
follows casting rules to a date if format isn’t included.
to_timestamp
Converts the timestamp string to the specified timestamp format.
to_timestamp(field ,'format(optional)' )
field is a timestamp string field that you want to convert.
'format(optional)' is the timestamp format pattern to follow.
This parameter is optional. The function follows casting rules to a timestamp if
format isn’t included.
For example, 'M' or
'L' is the month number in a year starting from 1.
to_timestamp('2020-01-01', 'M')
returns
1 The value YYYY/MM/DD is
a 4-digit year, 2 digit month, and day of the month.
TO_TIMESTAMP('2024/12/10 11:10:15', 'YYYY/MM/DD HH:MI:SS')returns
10-DEC-24 11.10.15.000000000 AM
to_unix_timestamp
Returns the UNIX timestamp of the specified time.
to_unix_timestamp(timestamp ,format(optional )
timestamp is a date/timestamp or string which is returned as a
UNIX timestamp.
format(optional) is the date/time format pattern to follow.
format(optional) is ignored if timestamp is
not a string. Default value is "yyyy-MM-dd HH:mm:ss". This
parameter is optional.
Example:
to_unix_timestamp('2016-04-08', 'yyyy-MM-dd')
returns
1460098800
trunc
Replaces the specified portion of the timestamp, and all portions after, with
zeroes.
trunc(field ,'format(optional)' )
field
is a timestamp field.
'format(optional)' specifies the part of the
timestamp to truncate. Accepted values are "YEAR",
"YYYY", "YY",
"MON", "MONTH",
"MM", "DAY",
"DD", "HOUR",
"MINUTE", "SECOND", "WEEK", and "QUARTER".
Example:
trunc('2015-03-05T09:32:05.359', 'MM') returns
2015-03-01T00:00:00
## Date and Time Function Considerations
Keep these behaviors in mind when working with date and time functions.
- These functions are relative to when the batch data transform runs.
- `now`
- `current_date`
- `current_timestamp`
- `to_unix_timestamp`
- All date and datetime functions are based on the UTC time zone.
- When Custom Time Zone Support is enabled, date functions and DateTime functions are separated. When it’s disabled, the functions are grouped together.
# Deactivate or Delete Data Q&A Agent
Control whether the Data 360 Data Q&A Agent is active and accessible in your org, or remove it entirely.
You can control the agent's availability in two ways:
- **Deactivate:** Temporarily stop your users from accessing the agent. Salesforce preserves the agent's configuration, prompt templates, and settings so you can reactivate them later. Deactivation is immediate.
- **Delete:** Permanently delete the agent from your org. You can't undo this action. Deleting the agent also deletes its configuration and any customizations made in Agentforce Builder. Salesforce doesn't delete semantic enrichments; it stores them separately so they remain available if you re-enable the feature.
## Deactivate the Agent
Deactivating the agent prevents users from accessing it while preserving all configuration.
1. From Setup, in the Quick Find box, enter Agentforce Agents, and select **Agentforce Agents**.
2. Find **Data 360 Data Q&A Agent** in the list and click its name to open it.
3. Click **Deactivate** in the top toolbar.
4. Confirm the deactivation when prompted.
The agent is no longer accessible to users, but its configuration is preserved. You can reactivate it at any time by opening the agent and clicking **Activate**.
## Delete the Agent
Deleting the agent permanently removes it from your org. This action cannot be undone.
1. From Setup, in the Quick Find box, enter Feature Manager, and disable Data 360 Data Q&A Agent. **Agentforce Agents**.
The agent is permanently removed from your org.

Warning Deleting the agent removes its configuration, including any custom modifications you made in Agentforce Builder. Semantic enrichments aren't deleted. There's no rollback or restore option after deletion. If you're unsure, deactivate the agent instead of deleting it.
## Metadata Knowledge Graph and Semantic Enrichments
Even if you deactivate or delete the agent, Metadata Knowledge Graph and Semantic Enrichments continues to run every 2 hours (when metadata changes are detected) and consumes Flex Credits. To disable indexing, navigate to **Feature Manager** and disable Metadata Knowledge Graph and Semantic Enrichments.
# Deactivated Segment
If a segment is no longer needed, it can be deactivated through Data 360 and applies to all chosen targets. A deactivated segment no longer publishes, can’t be chosen for an activation, and can’t be re-enabled. If you plan to use the segment again, stop the publish schedule instead.
Deactivate a segment using the dropdown menu next to the segment name and click **Inactivate**.

Note If you deactivate a segment, there's no functionality to re-enable it. If deactivated in error, you must recreate the segment.
# Default and Custom Match Rules
Identity resolution provides out-of-the-box, default match rules for different types of matching. Use custom match rules to resolve use cases that aren’t covered by default rules. Developing balanced, effective sets of match rules across different types of criteria improves consolidation rates for individuals and accounts.
- **[Match Rules for Accounts](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_accounts.htm&release=264.0.0&type=5)**
Identity resolution provides two preconfigured default match rules based on Account Name combined with other common data. Default match rules allow you to quickly select one of the four common match rule configurations. You can combine default and custom rules in a ruleset to create multiple ways for records to match. To get the best results from account matching, we recommend using match rules that match by account name and geographical location. The specific address data you select impacts the quality and precision of your matches.
- **[Match Rules for Individuals](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_individuals.htm&release=264.0.0&type=5)**
Identity resolution provides four preconfigured default match rules based on Individual First Name and Individual Last Name combined with other common data. You can combine default and custom rules in a ruleset to create multiple ways for records to match.
- **[Match Rules for Households](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_households.htm&release=264.0.0&type=5)**
You can add only one match rule to a ruleset when configuring household matching in Data 360 identity resolution. Each unified household contains one or more individuals. We recommend matching individuals into households based on either last name and address or on party identifier.
# Define Match Rules for Identity Resolution and Relate Separate Individuals
Let’s review the steps for defining match rules for Identity Resolution and relating separate Individuals in Data 360.
Relate your separate Individuals to a Unified Individual using [Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution.htm&release=264.0.0&type=5 "Identity resolution is the processing engine that generates unified profiles from source profile data stored in Data 360. Unified profiles act as a system of reference to unlock our source data. Understand how and when source profiles are processed and what you can do with unified profile output."). This example assumes that you can externally collect FirstName, LastName, EmailAddress, and/or PhoneNumber for each channel SubscriberKey. You then import the external data from three different systems, one for each channel, and map it accordingly. The imported SubscriberKey is linked to the Individual ID in Data 360. Using these match rules, Identity Resolution relates the separate Individuals, representing a person’s various Marketing Cloud Engagement SubscriberKeys, to a single Unified Individual.

Note Your company’s data mapping, identity resolution strategy, and rules can differ. Learn more about [match rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_criteria.htm&release=264.0.0&type=5 "Identity resolution provides out-of-the-box, default match rules for different types of matching. Use custom match rules to resolve use cases that aren’t covered by default rules. Developing balanced, effective sets of match rules across different types of criteria improves consolidation rates for individuals and accounts.") and Unified Individual [Considerations and Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_omni_best_practices.htm&release=264.0.0&type=5 "There are important aspects and trade-offs to consider before implementing this solution. This guide is just one example of how to enable an omnichannel experience for your customers. For example, instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.").
1. In Data 360, go to the Identity Resolution app.
2. Click **New**.
3. Set the Primary Data Model Object to Individual and enter a Ruleset ID.
4. Click **Next**.
5. Enter a ruleset name and the description.
6. Click **Save**.
7. In the Match Rules section, click **Configure**.
8. For Match Rule 1, click **Configure**.
9. Select **Fuzzy Name and Normalized Phone** and click **Next**.
10. Review the default rules.
11. Click **Add Match Rule**.
12. Select **Fuzzy Name and Normalized Email** and click **Next**.
13. Select **Custom Rule** and click **Next**.
14. [Match on Mobile SDK Shared Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_partyidentifier.htm&release=264.0.0&type=5 "Party identifier refers to the exact match of the Identification Number, Identification Name, and Party Identification Type fields in the Party Identification object. This type of match is useful for matching unique identifiers, such as government ID, first-party cookies, external MDM systems, and vendor-specific IDs.").

Note Customers must implement Mobile SDK to include both Data 360 and MobilePush modules.
15. Enter a name for the Match Rule and click **Next**.
16. Read the overview and click **Save**.
# Define Reconciliation Rules to Prioritize Values for the Unified Individual
Reconciliation rules specify how to select the best value for a Unified field when that field can store only one value, such as a person’s first name.
In our example, Cumulus imported data from three different systems. Some fields, such as FirstName, can have different values within each system. For Data 360 to prioritize a value when activating an audience to Marketing Cloud Engagement, Cumulus must define reconciliation rules.
Cumulus chooses the Source Priority rule for most of their fields. Because their primary external database (System A) is its most trusted and up-to-date system, they intend to prioritize the values that come from this database.
1. In the Identity Resolution ruleset that you created, scroll to the Reconciliation Rules section.
2. To expand the fields, click **Individual**.
3. Select the fields to update.
4. Click the edit icon.
5. Select **Source Priority**.
6. Choose whether to **Ignore Empty Fields**.
7. Click **Save**.
8. [Match on Mobile SDK Shared Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_partyidentifier.htm&release=264.0.0&type=5 "Party identifier refers to the exact match of the Identification Number, Identification Name, and Party Identification Type fields in the Party Identification object. This type of match is useful for matching unique identifiers, such as government ID, first-party cookies, external MDM systems, and vendor-specific IDs.").

Note Customers must implement Mobile SDK to include both Data 360 and MobilePush modules.
9. Enter a name for the Match Rule and click **Next**.
10. Read the overview and click **Save**.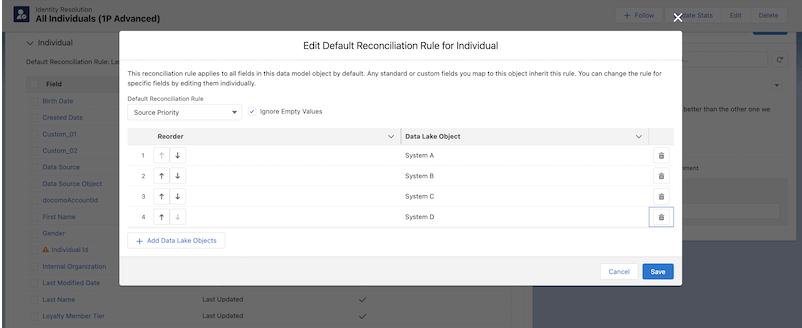
# Define Relative Time-Window Metrics
Get real-time Data Cloud insights with metrics based on rolling time windows. Determine metrics using relative timeframes, such as a specified number of past seconds, minutes, or days.
## Calculated Insights Time-Window Metrics
For calculated insights, use the `NOW` function to establish dynamic or relative time windows. The `SECOND_ADD` and `SECOND_SUB` functions provide more precise control to define the exact time window for your metrics.
- **Availability:**
- The `NOW`, `SECOND_ADD`, and `SECOND_SUB` functions are available in the transform node for [Visual Insight Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_working_with_nodes_in_builder.htm&release=264.0.0&type=5 "Visual Insight Builder uses a low-code, drag-and-drop interface to simplify the creation of streaming, calculated, and real-time insights. Visual components replace complex code, allowing you to develop metrics and expressions, regardless of technical expertise.").
- These functions are included in the [SQL Functions for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_aggregates.htm&release=264.0.0&type=5 "Use these aggregate, datetime, analytical, formatting, math and statistical, and boolean functions when you author calculated insights in Data 360. The Aggregatable column indicates whether a function's output can be rolled up across fewer dimensions when queried in segments or activations.").
- **Filtering:** You can define a relative time filter with the Visual Builder filter node "Relative DateTime operator" option.
- **Flexibility:** You can define and calculate dynamic metrics over configurable time intervals, from seconds to years (365+ days).
## Real-Time Time-Window Metrics
Use dynamic time-window metrics for real-time calculation of metrics over specific time frames. Use these metrics for personalized product recommendations informed by recent activity. For instance, you can:
- Count website interactions for the last 10 minutes to recommend products similar to recent views.
- Remove products that weren’t viewed in the last 10 minutes.
## How Real-Time Insights Update Metrics
Real-time insights update metrics when a data event is processed.
- Calculation at query time: The value for this metric is calculated at graph query time.
- Handling no events: When no events are processed, the metric value is calculated based on the defined relative time window. For example, if your metric is "count of product clicks for the last ten minutes," and no clicks occur during this time, the metric is 0.
- Client-side processing: Real-time graph clients must process the real-time insight data from the client side to get the true metric at graph query time.
## Streamlining Data Aggregation with Submetrics and Time Buckets
To streamline data aggregation and minimize storage within the real-time graph, the time-window process employs submetrics and time buckets within the user-defined time interval. This process eliminates the need to store every event in the real-time graph.
- **How it works:** When processing a real-time event, the `NOW` function compares the event time of each event within a 5-minute sub-time window to determine the appropriate window size. The function applies five different window types in a hierarchical order, with each type covering a specific time range relative to the compute time.
- **Automatic dimension creation:** When a dynamic time window is defined, the function creates the dimensions `window_start__c` and `window_end__c` as real-time insight dimensions.
- **Improved storage cost:** The time window process can result in an approximate metric rather than an exact count of events. The process is optimized to store the most recent data in smaller, precise buckets, grouping older data into larger buckets, to balance accuracy with storage cost.
**Window Types and Logic:**
- Five-Minute Windows (Most Recent Data)
- Covers: Last 1 hour from compute time
- Maximum Buckets: 12 (ensures at least 1 hour of coverage)
- One-Hour Windows (Recent Data)
- Covers: From 1 hour ago to 1 day ago
- Maximum Buckets: 23
- Daily Windows (Medium-Term Historical Data)
- Covers: From 1 day ago to 1 month ago
- Bucket Examples: \[2025-03-19 00:00 - 23:59\], \[2025-03-20 00:00 - 23:59\]
- Maximum Buckets: ~30 (varies by length of month)
- Monthly Windows (Long-Term Historical Data)
- Covers: From 1 month ago to 1 year ago
- Bucket Examples: \[2025-02-01 00:00 - 2025-02-28 23:59\], \[2025-03-01 00:00 - 2025-03-31 23:59\]
- Maximum Buckets: 11
- Yearly Windows (Oldest Data)
- Covers: All data older than 1 year from compute time
- Bucket Examples: \[2024-01-01 00:00 - 2024-12-31 23:59\], \[2023-01-01 00:00 - 2023-12-31 23:59\]
- Maximum Buckets: Unlimited (depends on data age)
**Example: Processing 25 Months of Minute-Level Data**
- Dataset: Records every minute from April 1, 2023, to May 1, 2025
- Compute Time: May 1, 2025, 10:30 AM
- Total Records: ~1,081,440 records
| Window Type | Time Range | DMO Event Count | Real Time Graph Aggregate Count |
| --- | --- | --- | --- |
| 5-minute | May 1, 2025 09:30-10:30 | 60 records | 12 records |
| 1-hour | April 30, 2025 10:30 to May 1, 2025 09:30 | 1380 records | 23 records |
| Daily | March 31 to April 30, 2025 | 44,640 records | 31 records |
| Monthly | May 1, 2024 to March 31, 2025 | 525,600 records | 11 records |
| Yearly | April 1, 2023 May 1, 2024 | 525,600 records | 2 records |
#### See Also
- [_Salesforce Help_: Supported SQL Statements for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_aggregates.htm&release=264.0.0&type=5 "Use these aggregate, datetime, analytical, formatting, math and statistical, and boolean functions when you author calculated insights in Data 360. The Aggregatable column indicates whether a function's output can be rolled up across fewer dimensions when queried in segments or activations.")
- [_Salesforce Help_: Create a Calculated Insight Using SQL](https://help.salesforce.com/s/articleView?id=data.c360_a_get_started_with_calculated_insights.htm&release=264.0.0&type=5 "Write SQL expressions to create your metrics and dimensions from mapped objects and fields. You can create a calculated insight in Data 360 using SQL.")
- [_Salesforce Help_: Create a Calculated Insight Using Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_calculated_insight_using_builder.htm&release=264.0.0&type=5 "Create a calculated insight without using SQL by using the builder tool in Data 360.")
- [_Salesforce Help_: Create a Real-Time Insight Using Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_create_real_time_insight.htm&release=264.0.0&type=5 "You can create real-time insights with a real-time data graph and related data model objects (DMOs). A related DMO is a DMO not defined in the real-time data graph but can be used as a real-time dimension.")
# Delete a Batch Data Transform
Delete any batch data transforms that you no longer need. Deleting a batch data transform doesn’t delete its target data.
Click the actions button to the right of the batch data transform that you want to delete, and then click **Delete**.
# Delete a Companion Connection
To prevent errors in a companion org, address your multi-org data dependencies before deleting a companion connection. If you try to disconnect a companion org that has dependencies, Data 360 shows you the existing dependencies.
### Required Editions
User Permissions Needed
To delete a companion connection
Permission set:
1. In **Data Cloud Setup**, select **Data Cloud One**.
2. Select the companion connection that you want to remove.
3. For each shared data space, click **Unshare**.
4. For the companion connection that you want to remove, click **Disconnect**.
If the companion org doesn’t have dependent features or processes, the org is disconnected. Otherwise, you're provided a list of dependencies to resolve.
Each Data 360 instance can have multiple companion orgs but only one home org. You can disconnect companion orgs from Data 360, but you can't disconnect your home org from its Data 360.
# Delete a Copy Field Enrichment
Delete a copy field enrichment to stop updating your data from Data Cloud.
### Required Editions
Available in: Enterprise and Unlimited Editions
You must have access as a Data Cloud user to use enrichments.
User Permissions Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To create or update a specific enrichment:
For standard data spaces: you must have access to the data space used in the enrichment.
For enhanced security data spaces: for Data Cloud Data Space Management permissions, each data space
assigned to you must have the Data Actions feature Customize permissions enabled.
To delete a specific enrichment:
You must have access to the data space used in the enrichment.
To delete enrichments:
Customize Application
Object Permissions Needed
To view enrichments in Object Manager:
Data Action Definition object Read permissions.
To delete enrichments in Object Manager:
Data Action Definition object Create, Update, and Delete permissions.
Deleting a copy field enrichment stops updating the field with data from Data Cloud, but it doesn’t remove the field or data from your org.
1. From Setup, select **Integrations**, **Enrichments**, and then **Copy Fields**.
2. Click the name of the enrichment that you want to delete.
3. Click **Delete**.
4. To confirm that you want to delete the enrichment, click **Delete** again.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
# Delete a Data Graph
In Data 360, when you delete a data graph, the record’s DMO schema structure and the queryable JSON blob are also deleted. Deleting a data graph removes it and all related data. You can’t undo this action or retrieve a deleted data graph.
### Required Editions
User Permission Set
Needed
To delete a data graph:
Permission set:
1. In Data Cloud, go to the Data Graphs.
2. Click **Delete** for the data graph you want to delete.
3. In the confirmation window, click **Delete**.

Note A data graph depends on data sourced from the data model objects and calculated insight objects. To ensure that data remains consistent, you can’t delete the objects, fields, or relationships that are included in a data graph. You also can’t delete calculated insights objects and calculated insight measures referenced in a data graph.
# Delete a Data Share
In Data Cloud you can delete an unlinked data share that's no longer needed.
### Required Editions
User
Permissions Needed
To delete data shares:
Permission set:
1. In Data 360, go to the Data Shares tab.
Before you delete the data share, make sure that it’s not linked to a target. You can’t delete a linked data share.
2. Click the data share that you want to delete.
3. On the data share record home page, click **Delete**.
4. In the confirmation window, click **Delete**.
#### See Also
- [_Salesforce Help_: Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.")
# Delete a Data Share Target
You can delete unlinked data share targets that you no longer need.
### Required Editions
User
Permissions Needed
To delete data share targets:
Permission set:
1. In Data 360, go to the Data Share Targets tab.
Before you delete the target, make sure that it’s not linked to a data share. You can’t delete a linked target.
2. Click the data share target that you want to delete.
3. On the data share target record home page, click **Delete**.
4. Click **Continue Delete** and confirm the deletion.
#### See Also
- [_Salesforce Help_: Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.")
# Delete a Data Stream
You can delete a data stream in Data 360 if the connection is no longer needed.
When you delete a data stream, the underlying data lake object (DLO) containing all the data records provided by that data stream is also deleted. Before you delete the data stream you must free the underlying data lake object of all of its dependencies. Consider the following factors before deleting a data stream:
- The underlying DLO can’t be mapped to a data model object.
- The underlying DLO can't be used in a data transform.
- The data stream can’t be associated with a data kit.
Some connectors support conditional deletion, which means that you can delete the data stream without implicitly deleting the underlying DLO. If you choose a conditional delete for data streams, meaning you plan to retain the DLO, then you aren't bound by the first three factors listed previously. Conditional deletes are supported as long as the following conditions are met:
- The data stream uses S3, Google Cloud Storage, Microsoft Azure Storage, or SFTP connectors.
- A single data stream is being deleted, meaning it’s not a bulk delete operation.
- The data stream wasn't created from a managed package.
1. Go to the Data Streams tab.
2. Select the check box next to the data streams that you want to select for deletion.
3. Click **Delete Data Stream**.
If you choose to delete the underlying DLO, select **Delete the associated data lake object**. This option is supported only for data streams that use S3, Google Cloud Storage, Microsoft Azure Storage, or SFTP connectors.
4. Click **Delete**.
# Delete a Direct-DMO Related List Enrichment
Delete a related list enrichment that's based on a direct relationship between a DMO and a Salesforce object.
### Required Editions
Available in: Enterprise and Unlimited Editions
User Permissions
Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To delete enrichments:
Customize Application
Object Permissions
Needed
To delete enrichments:
Data Action Definition object Create, Update, and Delete permissions.
To view enrichments in Object Manager:
Data Action Definition object Read permission.
Before you delete the DMO relationship, remove all the dynamic related lists that reference the DMO relationship.
To delete a related list enrichment:
1. From Setup, in the Quick Find box, enter App Builder, and then select **Lightning App Builder**.
2. Edit the record page for the object that has the direct-DMO related list.
3. In the record page, delete the dynamic related list that references the DMO relationship.
4. Repeat steps 1 to 3 for every object that has the same direct-DMO related list.
5. To delete the DMO relationship, in the Data Cloud app, click **Data Model**.
6. In the Relationships tab, click **Edit**.
7. Delete the DMO relationship to the Salesforce object.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
# Delete a History Tracking Calculated Insight
If it’s no longer needed, you can delete a history tracking insight.
### Required Editions
1. Go to the Calculated Insights list view and find the source insight for the tracking history calculated insight.
2. From the drop-down arrow, select **Track History** and deselect the checkbox for **Track history**.
3. Click **Save**.
4. From the list view, delete the calculated history insight.
# Delete a Private Connect Network Route
You can delete a private network route that isn’t used in a data stream.
### Required Editions
User Permissions
Needed
To delete a network route
Data Cloud Architect permission set OR
Manage External Connections or
Customize Application permissions
Make sure that the network route isn’t used by any data streams. If a data stream is using the route, you can update the data stream to use a different route.
1. In Data Cloud Setup, under External Integrations, click **Private Connect**.
2. For the network route that you want to delete, click the down arrow and select **Delete**.
3. Confirm that you want to delete the network route.
After you delete the network route in Data Cloud, the endpoint connections entry from your VPC endpoint service is also deleted.
# Delete a Related List Enrichment
Delete a related list enrichment so that data from Data 360 can’t be queried.
### Required Editions
Available in: Enterprise and Unlimited Editions
You must have access as a Data Cloud user to use enrichments.
User Permissions Needed
To view enrichments in Object Manager:
View Setup
To view a specific enrichment:
You must have access to the data space used in the enrichment.
To delete enrichments:
Customize Application
Object Permissions Needed
To delete enrichments:
Data Action Definition object Create, Update, and Delete permissions.
To view enrichments in Object Manager:
Data Action Definition object Read permissions.
Before you delete the enrichment, remove the enrichment from the Contact or Lead record page using Page Layout Editor.
Deleting a related list enrichment means that the related list component for the enrichment can’t retrieve data from Data 360.
1. From the Contact or Lead object management settings, select **Data Cloud Related Lists**.
2. Click the name of the enrichment that you want to delete.
3. Click **Delete**.
4. To confirm that you want to delete the enrichment, click **Delete** again.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
# Delete a Segment
Delete a segment if it’s no longer needed. If the segment is attached to an activation, delete the activation first.
If you’re planning to use the segment again, stop the publish schedule instead. To delete a segment, use the dropdown menu next to the segment name to select delete.
If you delete a segment, you can’t re-enable it. If you restore the deleted segment from the recycle bin, you can't edit or delete it again. You must re-create the segment.
# Delete an Identity Resolution Ruleset
Deleting a ruleset permanently removes all unified customer data, eliminates dependencies on data model objects, stops all processing of the ruleset, and deletes the history of previous runs. In some cases, it’s better to update the match or reconciliation rules instead of deleting the ruleset.
Delete a ruleset from the Identity Resolution tab or the ruleset’s record home. Deletion takes up to 24 hours to complete.

Warning You can’t recover previous unification data after deleting a ruleset.
To keep the same ruleset name and ruleset ID and override existing data, update the ruleset instead of deleting it.
# Delete an Unstructured Data Lake Object
You can delete unstructured data lake objects (UDLOs) at any time.
### Required Editions
User Permissions
Needed
To delete a UDLO
Permission set:
If a UDMO mapped to the UDLO has a search index configuration, you must first delete the search index before you can delete the UDMO and any mappings to it.
## Delete a UDLO Without a Search Index
Use these steps to delete a UDLO for which you haven’t created a search index.
1. From App Launcher, select **Data Cloud**.
2. Click **Data Lake Objects**, select the UDLO that you want to delete, and click **Delete**.
3. When prompted, review any dependencies, and click **Delete**.
## Delete a UDLO With a Search Index
Use these steps to delete a UDLO if you have created a search index from it.
1. [Delete the retrievers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_version_edit.htm&release=264.0.0&type=5 "Edit retriever versions in AI Models (formerly Einstein Studio) to create versions for testing different configurations and responses within a prompt. You can edit only custom individual retrievers. If no prompt templates depend on a retriever, you can delete it.") associated with the search index.
2. [Delete the search index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_delete_index_config.htm&release=264.0.0&type=5 "You can delete Data 360 search index configurations from the list view and the object record view.").
3. Delete the data model object (DMO).
4. Click **Data Lake Objects**, select the UDLO that you want to delete, and click **Delete**.
# Delete Clean Room Mapped Templates
You can delete a mapped template if it’s not associated with an active clean room collaboration.
### Required Editions
Available in: Enterprise Edition (home org)
User Permissions Needed
To map data for a use case:
Permission set:
1. In Data Cloud, on the Clean Rooms tab, go to **Mapped templates**.
2. Find the mapped template that you want to delete.
- In the dropdown next to the mapped template name, select **Delete**.
- Click the mapped template you want to delete and select **Delete**.
3. To confirm, click **Delete**.
# Delete Ingested Records in Data 360
You can delete data ingested into Data 360. Your data stream must have an upsert refresh mode. The deletion process depends on the type of connector that you’re using.
Amazon S3, Google Cloud Storage, and Microsoft Azure Storage connectors—The records that you’re deleting must be read from the same source directory that the corresponding data stream is ingesting from. When a data stream has multiple upsert and deletion files, the files are processed in the order of their last modified time. Row versioning isn’t supported for deletes.
Ingestion API connector—The API provides a delete operation for both streaming and bulk interaction patterns. To delete up to 200 records, refer to [Delete Records](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_delete_records.htm). To delete more than 200 records in a request, use bulk ingestion operations. For more information, see [Upload Job Data](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_upload_job_data.htm) and [Delete a Job](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_delete_a_job.htm). After the delete requests are received programmatically, they're processed asynchronously.
SFTP connector—The records that you’re deleting must be read from the same source parent directory that the corresponding data stream is ingesting from. When a data stream has multiple upsert and deletion files, the order of processing isn't guaranteed. Row versioning isn’t supported for deletes.
Salesforce CRM connector—The connector manages the deletion requests. After data is deleted on the source org, it’s removed from Data 360 with the next incremental refresh. You can store deleted records that have been in the Salesforce Recycle Bin for up to 15 days by creating a Deleted Record Data Lake Object, see [https://developer.salesforce.com/docs/atlas.en-us.c360a\_api.meta/c360a\_api/c360a\_api\_upload\_job\_data.htm](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_upload_job_data.htm).
Data 360 doesn’t support cascading deletes. If you delete a profile record, its related engagement or other profile records aren’t deleted. Delete these records manually from each table.
- **[Delete Records by Using a Delete File](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_stream_records_deletion_file.htm&release=264.0.0&type=5)**
To delete data records ingested by using the Amazon Simple Storage Service (Amazon S3), Google Cloud Storage (GCS), Microsoft Azure, Ingestion API, or Secure File Transfer Protocol (SFTP) connector, create a delete file. Create the file in CSV or Parquet file format. S3, GCS, and Azure data streams support Parquet file ingestion.
#### See Also
- [_Salesforce Developer_: Data 360 Reference- Delete Records](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_delete_records.htm)
- [_Salesforce Developer_: Data 360 Reference- Delete a Job](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_delete_a_job.htm)
# Delete Records by Using a Delete File
To delete data records ingested by using the Amazon Simple Storage Service (Amazon S3), Google Cloud Storage (GCS), Microsoft Azure, Ingestion API, or Secure File Transfer Protocol (SFTP) connector, create a delete file. Create the file in CSV or Parquet file format. S3, GCS, and Azure data streams support Parquet file ingestion.
For considerations regarding various file formats, review [Supported File Formats in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_file_formats.htm&release=264.0.0&type=5 "Data 360 supports various files and compression formats for your data stream sources.").
When you delete more than 600,000 records between refreshes, the data stream performs a full refresh.
## Delete Records
To delete records:
1. Create a delete file with the list of primary keys of the records to delete.
The primaryKey field in the delete file must match the primary key data type of the data lake object (DLO). For example, if the DLO primary key field is a number, the primary key data type in the delete file must be a number.
- For CSV delete files, wrap the primary key values in double quotes for correct file delimiter detection. Don't use quotes in Parquet delete files.
- For records ingested from a CSV file, create a headerless delete file in CSV format. Wrap primary key values in double quotes. Edit the file in a plain-text editor, not a spreadsheet application such as Excel, which can reformat the quotes.
- For records ingested from a Parquet file, create a Parquet delete file with a single column named primaryKey. Don't use quotes around primary key values.

Important
The Parquet delete file column name must be exactly `primaryKey`. Don't replace it with your own primary key field name or API name, such as `CustomerId` or `ContactId`. A different column name causes the delete operation to fail or produce unexpected results.
2. Name the delete file by using the prefix Deletion\_ followed by the matching CSV the source file name.
The file name is case-sensitive so make sure that the prefix is exactly "Deletion\_" and the source file name remains unchanged. For example, if a file is named Customer\*, which contains a wildcard, you can name your deletion file Deletion\_Customer.csv or Deletion\_Customer.parquet.

Important
To prevent processing errors or unintended data loss, don't overwrite existing deletion files via the SFTP Connector. Instead, create a new, uniquely named file for every deletion request. Make sure that file names are unique and append a timestamp by using this format:
**Format:** `Deletion_{FileNameWildcard}_YYYYMMDDHHMMSS`
**Example:** If your file name wildcard is `UserData`, name your uploaded deletion file similarly to: Deletion\_UserData\_20240514103000.csv
This timestamp format guarantees that the SFTP Connector processes each deletion file independently.
3. In the directory containing the source files, create a subfolder named delete.
4. Upload the delete file to the delete folder.
## Delete Encrypted Records
To delete encrypted records ingested by using an SFTP connector:
1. Locate the schema file created during the [SFTP connection setup](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-set-up-sftp-connection.html).
2. Verify that the schema file is in the correct format, and that it's not corrupted. For the file format requirements, see the steps for deleting records.
3. Verify the delete folder and its parent and root folders have Read, Write, and Delete permissions.
4. To delete the schema file, add it to the delete folder.

Example
Your data stream ingests a file named accounts-file by using the accounts-\* wildcard. The file comes from a bucket named accounts-bucket and a folder named accounts-folder.
- To delete records, create a delete folder under the -folder.
- Depending on the file format, create a file named the accounts Deletion\_-.csv or Deletion\_-.parquet.
- Your folder structure can be accounts-folder/delete/Deletion\_accounts-.csv or accounts-folder/delete/Deletion\_accounts-.parquet.
Sample CSV delete file
```csv
"0000-0000-0000"
"0000-0000-0001"
"0000-0000-0002"
```
Sample Parquet delete file
```csv
primaryKey
0000-0000-0000
0000-0000-0001
0000-0000-0002
```
# Delete Search Index Configurations
You can delete Data 360 search index configurations from the list view and the object record view.
### Required Editions
User Permissions Needed
To delete a search index configuration:
Permission set:
If you delete a search index configuration, you can no longer use the associated index DMO for vector search.
You can’t delete a search index configuration if any retrievers reference it. You must first delete all dependent retrievers in AI Models (formerly Einstein Studio), and then delete the search index configuration.
## Delete from List View
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index**, click the drop-down arrow for the configuration that you want to delete, and select **Delete**.
3. Review any dependencies for the configuration, and click **Delete.**
## Delete from Object View
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index**, and from the list view, select the configuration that you want to delete.
3. From the object view, click **Delete**.
4. Review any dependencies for the configuration, and click **Delete**.
# Delta Extract
Marketing Cloud Engagement supports two types of incremental extracts: delta extract by date and by number.
## Delta Extract by Number
When Delta Extract by Number is selected, there is a cascading list of fields in the numeric Data Extension data type. Choose a numeric field as the basis for the high-water mark between consecutive extracts.
With this extract method, the Data Extension data is sorted in ascending order according to the Numeric field selected. For the first extract, a high-water mark is tagged next to the ordered highest number (maximum) and data below that mark is sent. By the time of the second extract, more data can accumulate, resulting in a new maximum value. The second extract reflects all rows of data between the initial max value and the updated max value. With each new extract, all new rows of data between the penultimate max value (second-to-last-identified max value) and the last-identified max value get sent.
## Delta Extract by Date
When Delta Extract by Date is selected, there is a cascading list of fields in the Data Extension whose data type is date time. You are prompted to choose a date time field as the basis for the high-water mark between consecutive extracts.
With this extract method, the Data Extension data is sorted in ascending order according to the Date Time field selected. For the first extract, a high-water mark is tagged next to the ordered most recent date time, and data below that mark is sent. By the time of the second extract, more data can accumulate, resulting in a new most recent date time or maximum value. The second extract reflects all rows of data between the initial max value and the updated max value. With each new extract, all new rows of data between the penultimate max value, or second-to-last-identified max value, and the last-identified max value get sent.
# Deploy a Clean Room from an AppExchange Package
To initiate a collaboration with a provider, install a clean room package from AppExchange and deploy it in Data 360 .
### Required Editions
Available in: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
User Permissions Needed
To install a clean room package:
System admin profile OR
Data Cloud Architect permission set
1. In AppExchange, locate the package.
2. Install the package for all users.
3. In Data Cloud Setup, [deploy the data kit components](https://help.salesforce.com/s/articleView?id=data.c360_deploy_data_kit_components.htm&release=264.0.0&type=5 "After you create and install a standard data kit in a managed package, you can deploy package components such as data streams, batch data transforms, calculated insights, and data graphs from Data 360 with Package Manager in your target org.").
# Deploy a Marketing Cloud Engagement Bundle to a Data Space
Add Marketing Cloud Engagement data to a Data 360 data space based on the mapping.
### Required Editions
User Permissions Needed
To deploy a Marketing Cloud Engagement bundle:
Permission set:
1. In Data 360, go to the Data Streams tab, and click **New**.
2. Select **Marketing Cloud**, and click **Next**.
3. Select a data space for each business unit. Business unit to data space mapping is applicable only for bundles.
Each business unit must be mapped to at least one data space, and you can map a business unit to multiple data spaces. You can also map a data space to many business units.
If Allow Profile Business Unit Mapping Data is enabled in Engagement setup, make sure that the Engagement subscribers are mapped to the same business unit ingested into Data Cloud. If the SFMC Subscribers BU mapping data stream is empty, applications like Data Explorer, Segmentation, and Activation don’t get data for Individual and contact point DMOs.
4. Click **Next**.
5. Select a standard Engagement data bundle, and click **Next**.
6. Optionally edit labels or add formula fields.
7. Click **Deploy**.
If you’re ingesting a new business unit, you must deploy the data streams again.
#### See Also
- [_Salesforce Help_: Set Up Marketing Cloud Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_marketing_cloud_connection.htm&release=264.0.0&type=5 "After you create your Data 360 instance, control the scope of data ingestion and activation from Marketing Cloud Engagement and other sources. Before integrating with Data 360, make sure that your Engagement user’s default business unit (BU) is set to the Enterprise ID (EID). Set up your data sources to tell Data 360 where to pull data from, also known as ingest, for data mapping and segments. You can connect multiple EIDs to a single Data 360 org, where each EID has its own connection to Data 360. For each of these connections, you can set up multiple data streams using data bundles or data extensions. Each connection also has its own business unit-to-data space mapping configuration. Data 360 supports only Engagement Enterprise 2.0 account connections.")
# Deploy a Salesforce CRM Bundle to a Data Space
Add Salesforce CRM data to a Data 360 data space based on the mapping. You can deploy only a standard data bundle to a data space.
### Required Editions
User Permissions Needed
To deploy a CRM bundle:
Permission set:
1. In Data 360, go to the Data Streams tab, and click **New**.
2. Select **Salesforce CRM**, and click **Next**.
3. Select a Salesforce org. If you have only one Salesforce org connected to Data 360, it’s selected by default.
4. Select a data bundle, and click **Next**.
5. Select a data space. You can select only one data space.
6. Optionally select the data fields to deploy, and click **Next**. By default, all data fields are deployed.
7. Optionally set filters.
8. Click **Deploy**.
#### See Also
- [_Salesforce Help_: Connect Data](https://help.salesforce.com/s/articleView?id=data.c360_a_connectors.htm&release=264.0.0&type=5 "Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.")
- [_Salesforce Help_: Ingest Data](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion.htm&release=264.0.0&type=5 "To get started with Data 360, you connect a data source, through either data federation or data ingestion. Data federation sets up direct connectivity with data sources. It uses a zero copy integration that eliminates the need to ingest data into Data 360. During data ingestion, data is brought into Data 360 in its original form and stored in a data lake object (DLO).")
- [_Salesforce Help_: Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.")
# Deploy Data 360 Changes Across Orgs
You can make Data 360 changes in a sandbox and then deploy them to a production org or another sandbox org. Additionally, you can deploy changes from one production org to another production by using a sandbox. Use a DevOps data kit and a change set to deploy the changes to a production org.
### Required Editions
User Permission Set
Needed
To deploy Data 360 changes:
Permission set:
This process details how to deploy changes from a sandbox to a production org. Use the same steps to deploy changes from your production org back to a sandbox. The process involves multiple steps within both Data 360 and the Salesforce Platform. Bookmark () this page or keep it open in a separate window to refer to this topic. For more information, see [Change Sets](https://help.salesforce.com/s/articleView?id=platform.changesets.htm&type=5&language=en_US).
To deploy Data 360 changes from a sandbox org to another org by using the Salesforce command-line interface, see [Use CLI to Deploy Changes from a Sandbox to Data Cloud](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/dc-deploy_data_kit_using_cli.html).

Note When you deploy changes from a sandbox, you can deploy them back to the production org or to another sandbox. For simplicity, this topic uses the term "production," which can be the production org from which the sandbox was created or another sandbox org. To move metadata across production orgs, deploy the data from production org one to sandbox org one. Then, deploy those changes from sandbox one to the sandbox linked to production org two before the final push into production org two.
## Step 1: Create a Deployment Connection
If you haven’t already done so, in your production org, create a deployment connection between your production (target) org and the sandbox (source) org. See [Authorize a Deployment Connection](https://help.salesforce.com/s/articleView?id=platform.t_changesets_deployment_connection.htm&type=5&language=en_US) and [Change Set Setup and Configuration](https://help.salesforce.com/s/articleView?id=000385608&type=1&language=en_US).
Because you’re deploying from sandbox to production, you create the deployment connection in the production org. This deployment connection allows inbound change sets to be installed in the production org.
## Step 2: Create a DevOps Data Kit
1. In the sandbox org, from Data Cloud Setup, create a DevOps data kit. See [Create a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_bundle_package_kits.htm&type=5&language=en_US).
2. For Data Kit Type, select **DevOps**.
3. Select a data space.
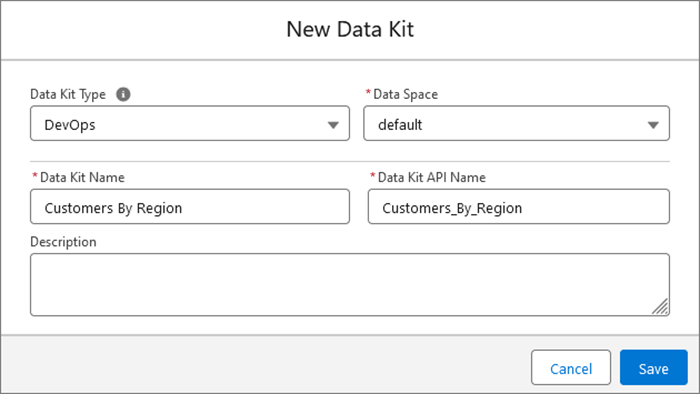
Make sure that the data space with the same prefix name exists in both the sandbox org and the production org.
4. Add the Data 360 components that you want to deploy to the DevOps data kit.
When you add a source DMO to a DevOps data kit, the kit automatically detects and packages the associated DMO-to-sObject relationships.
5. To review the auto-publishing sequence of the data kit components in target org, click **Publishing Sequence**.
If you edit the publishing sequence, Data 360 doesn't auto-update the sequence when you add or modify data kit components. After editing, update the publishing sequence manually for each data kit change.
The system publishes components based on their creation dates. Review the publishing sequence for these components.
6. Click **Save**.
If you create a data space in a sandbox that doesn’t exist in the production org, and you want to deploy components from that data space, you must first manually create the data space in production. The data space isn’t created when you deploy the data kit.
## Step 3: Create and Upload an Outbound Change Set
1. In the sandbox org, from Setup, create an outbound change set. See [Create an Outbound Change Set](https://help.salesforce.com/s/articleView?id=platform.t_changesets_outbound.htm&type=5&language=en_US).
2. Add the DevOps data kit to the outbound change set.
3. In the Component Type field, select **Data Package Kit Definition** and select the DevOps data kit that you want to add. See [Select Components for an Outbound Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_outbound_components_select.htm&type=5&language=en_US).
4. In the outbound change set, add the data kit dependencies. See [View and Add Dependent Components to a Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_outbound_dependencies.htm&type=5&language=en_US).
When you add dependencies, there can be multiple pages of components, so be sure to scroll through all the pages.
If your data kit includes any key qualifier files related to DMOs or relationships, make sure to delete them.
5. If you add a data kit that contains a custom DMO to the outbound change set, you must add the DMO relationships to the change set. However, don't add relationships for derived objects, like unified individuals, to the change set. These relationships are automatically handled through their source objects. In the Change Set Components section, click **Add**. Then from the Component Type field, select **Field Source Target Relationship**, and add the relevant relationships to the change set.
If a field source-target relationship exists between a DMO and a custom field on a standard Salesforce object, create the same custom field in the target org before deploying the change set. If the custom field doesn't exist in the target org, the deployment fails.
6. Upload the outbound change set. See [Upload an Outbound Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_outbound_init_deploy.htm&type=5&language=en_US).
## Step 4: Deploy the Inbound Change Set and the Data Kit
1. In the production org, from Setup, deploy the inbound change set. See [Deploy a Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_inbound_deploy.htm&type=5&language=en_US).
This step deploys the data kit and all the features in the data kit.
2. Verify the deployment status of the data kit components.
1. From Data Cloud Setup, in the Quick Find box, enter Data Kits.
2. Select **Data Kits** and select the DevOps data kit.
3. On the Deployment History tab, verify the progress of the deployment.
If a component in the deployment fails, the components after it in the sequence aren’t deployed.
When you deploy a data kit using a change set, the system automatically deploys the data kit and its components. If you deploy the same data kit by using another change set, the data kit installs but doesn't deploy the components. To complete the deployment, open your data kit, and click **Deploy Data Kit**.
#### See Also
- [_Salesforce Developers_: Use CLI to Deploy Changes from a Sandbox to Data 360](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/dc-deploy_data_kit_using_cli.html)
- [_Salesforce Help_: Data 360 Governance Mergeback with DevOps Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_mergeback_devops_datakits.htm&language=en_US)
# Deploy Data 360 Governance Policies with DevOps Data Kits
Migrate your data governance policies from sandbox to production orgs using DevOps data kits. This approach maintains consistency and reduces manual errors.
### Required Editions
| User permission needed | |
| --- | --- |
| To deploy Data 360 changes: | Data Cloud Architect |
Verify that your deployment meets these prerequisites before starting a mergeback.
- Create and test governance policies in a sandbox org. See:
- [Create an Object or Field-Level Access Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_ols_fls_policy.htm&type=5&language=en_US)
- [Create a Record-Level Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_rls_policy.htm&type=5&language=en_US)
- [Dynamic Data Masking Policies in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_dynamic_data_masking_policies.htm&type=5&language=en_US)
- The target organization contains the necessary data model objects (DMOs) and data lake objects (DLOs).
- Bundle all policies and their associated protected objects in a single data kit to prevent policy leaks and unintended data exposure.
- Make sure dependencies for record-level security (RLS) policies, including objects referenced in joins, exist in the target environment.

Important Deploy governance policies only using Salesforce change sets. The Salesforce CLI doesn’t support governance policy deployment.
To move governance policies:
1. Create a DevOps data kit in your sandbox org. See [Create a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_create.htm&type=5&language=en_US).
1. Select the data assets such as data stream bundles or DLOs that you want to migrate.
2. In the data kit wizard, select the associated RLS, OLS, and FLS policies and tag assignments.
3. If your implementation includes RLS policies with joins, create a second DevOps data kit. Add the data stream bundle that contains the RLS policies with joins and related tag assignments.
2. Add the data kit and its tag assignments to an outbound change set.
1. From Setup, in the Quick Find box, enter Outbound Change Sets, and then select **Outbound Change Sets**.
2. Create a new outbound change set.
3. Add the data kit with all its dependencies to the change set. See [View and Add Dependent Components to a Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_outbound_dependencies.htm&type=5&language=en_US).
4. Review the publishing sequence. Make sure that the dependent DLOs or DMOs are deployed before or are higher up in the deployment sequence.
3. Upload the change set to the production org. See [Upload an Outbound Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_outbound_init_deploy.htm&type=5&language=en_US).
4. In the production org, deploy the change set.
Deploying the change set installs the DevOps data kit and applies the associated governance policies in the target org. See [Deploy a Change Set](https://help.salesforce.com/s/articleView?id=platform.changesets_inbound_deploy.htm&type=5&language=en_US).
5. Verify the deployment status.
1. In the target org, go to **Data Kits**, click **Deployment History** and verify that the deployment is successful.
2. In the target org, go to **Data Governance**, click **Policies** and verify that the merged RLS, FLS, and OLS policies appear in the dashboard and are active.
#### See Also
- [_Salesforce Help_: Deploy Data 360 Changes Across Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_deploy.htm&type=5&language=en_US)
# Deploy Data Kit Components in Data 360
After you create and install a standard data kit in a managed package, you can deploy package components such as data streams, batch data transforms, calculated insights, and data graphs from Data 360 with Package Manager in your target org.
### Required Editions
User Permission Set
Needed
To deploy data kit components:
Permission set:
Before you begin, understand the deployment guidelines and limitations.
- Before you deploy a data kit, verify that every corresponding project, database, dataset, schema, and table has the same name in the source and target environments. A data kit captures these names from the source connection and doesn’t remap them during deployment. If any name differs, deployment fails. For example, deployment fails if a schema is named `Sales` in the source environment but `DevSales` in the target environment.
1. In your org, create and install a managed package with a data kit.
See [Create and Install Your Package](https://help.salesforce.com/s/articleView?id=data.c360_a_create_install_package.htm&release=264.0.0&type=5 "Use a managed package to build a Data 360 app and distribute it on AgentExchange. Packaging is the container that you fill with metadata, and it holds the set of related features, customizations, and schema that make up your app. A package can include many different metadata components, and you can package a single component, an app, or library.").
2. Go to your target org, and use the package URL to install the managed package.
3. In your target org, under Developer Tools, click **Data Kits**.
4. Open your data kit, and click **Data Kit Deploy**.
5. To deploy the data kit components, select a data space, and add the connection org details of the data bundle.
6. Click **Deploy**.
The deployments follow the order defined in the publisher org.
When you package and deploy DMOs in a data kit, their relationships and tags are automatically included if they are defined during the packaging process.
7. To check the deployment status, click **Deployment History**.
If a component fails during deployment, the process stops, and any subsequent components in the sequence aren’t deployed.
To programmatically deploy all the data kit components in the target org, use the [Deploy Data Kit Components](https://developer.salesforce.com/docs/data/connectapi/references/spec#tag/Data-Kits/paths/~1ssot~1data-kits~1%7BdataKitDevName%7D/patch) Connect REST API endpoint.
After you deploy the packaged data stream, your data stream is created and is identical to the one in your package instance. If the data stream in your package was mapped to data models, they’re mapped automatically.
#### See Also
- [_Salesforce Developers_: Data 360 Developer Guide](https://developer.salesforce.com/docs/data/data-cloud-dev/guide/get-started.html)
# Deploy Direct-DMO Customizations to Production with Sandbox Mergeback
Starting in Winter '26, you can package and deploy customizations containing direct data model object (DMO) relationship metadata from sandbox to production environments.
### Required Editions
User Permission Set
Needed
To deploy Data 360 changes:
Permission set:
This process is specifically for deploying direct-DMO custom lookup fields from sandbox to production orgs.

Important If your Lightning Page contains a dynamic related list, do not change the activation status of the page. Activating a page during this process prevents you from installing this new change set.
1. In your sandbox org, open Setup and navigate to Outbound Change Sets.
2. Create a new change set.
3. Add foundational CRM metadata, such as custom objects and custom fields, as well as Data 360 metadata in the form of a data kit. In this change set, you must manually configure the metadata type [`FieldSrcTrgtRelationship`](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/meta_fieldsrctrgtrelationship.htm) for your desired direct-DMO relationship.
4. In the Change Set Components section, click **View | Add Dependencies**. Then, add your direct-DMO custom lookup field to the changeset.
5. Navigate to the target org and open the Inbound Change Sets list.
6. In the Change Sets Awaiting Deployment section, deploy your change set. If the deployment is successful, you can mergeback CRM customizations that reference the relationships you added.
7. If needed, [deploy the installed data kit in your target org](https://help.salesforce.com/s/articleView?id=data.c360_deploy_data_kit_components.htm&type=5&language=en_US).
8. Create a new outbound change set and add your customizations. .
9. Upload the changeset to the target org.
10. Install the changeset in the target org.
# Design Considerations
Keep these design considerations in mind when you welcome new loyalty members to your program.
## Configuring Marketing Cloud Connect
- Marketing Cloud Connect requires using the Contact Record ID from Sales Cloud or Service Cloud as the [subscriber key](https://help.salesforce.com/s/articleView?id=mktg.mc_co_subscriber_key.htm&type=5&language=en_US) in Marketing Cloud Engagement to return email tracking data to Salesforce CRM.
## Supporting Multiple Brands
- If you have one Loyalty Management org and multiple Marketing Cloud Engagement business units, query the synchronized data extensions and save your results to shared Salesforce data extensions so that the child business units can access them. In this case, Loyalty Management Content blocks don’t work because they rely on standard synchronized data extension naming (for example, Contact\_Salesforce).
- If you have multiple Salesforce orgs that use multi-org Marketing Cloud Connect, synchronized data extensions at the child business unit level are named differently (for example, Contact\_Salesforce1). In this situation, Loyalty Management content blocks don’t work because they rely on standard synchronized data extension naming (for example, Contact\_Salesforce).
## Displaying Loyalty Management Information in Emails
Set up one or more saved content blocks for reuse in emails to display personalized loyalty program information.
The Loyalty Management Content Blocks managed package addresses these use cases for displaying loyalty program information.
- Loyalty Campaign Promotion—You choose a specific campaign and promotion to inform members about the promotion details. This content block uses the Campaign ID to associate the specific promotion.
- Loyalty Tier Upgrade—You choose a specific loyalty program, tier group, and tier. This content block uses the Contact ID to look up tier information.
- Loyalty Accrual Transaction—Use this content block to inform members about the points they’ve earned for an activity. It uses the Transaction Journal ID to associate the specific transaction.
- Loyalty Redemption Transaction—Use this content block to inform members about the points they’ve redeemed for an activity. It uses the Transaction Journal ID to associate the specific transaction.
## Custom Content Blocks Example
You can also create custom content blocks to look up information from synchronized data extensions. For example, Sunnie Foods uses a custom content block to display a customer’s loyalty tier, membership number, and points balance in the email banner.
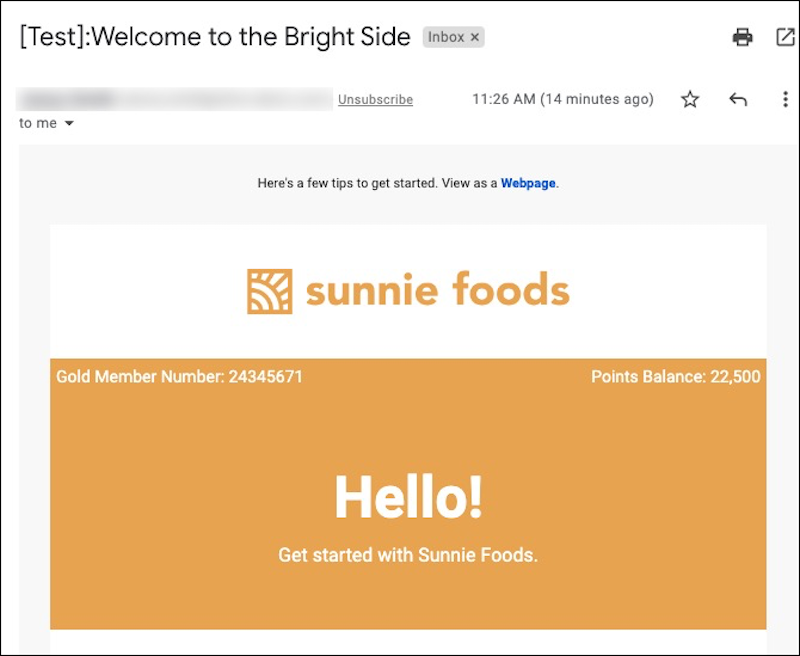
Sunnie Foods uses this code to create the custom content block.
```html
%%[ set @ContactId = ContactID set @LoyaltyProgramMemberId = Lookup("LoyaltyProgramMember_Salesforce", "Id", "ContactId", @ContactId) set @LoyaltyMemberTier_Name = Lookup("LoyaltyMemberTier_Salesforce","Name","LoyaltyMemberId",@LoyaltyProgramMemberId) set @LoyaltyProgramMember_MembershipNumber = Lookup("LoyaltyProgramMember_Salesforce","MembershipNumber","ContactId",@ContactId) set @LoyaltyMemberCurrency_PointsBalance = Lookup("LoyaltyMemberCurrency_Salesforce","PointsBalance","LoyaltyMemberId",@LoyaltyProgramMemberId) ]%%
%%=v(@LoyaltyMemberTier_Name)=%% Member Number: %%=v(@LoyaltyProgramMember_MembershipNumber)=%%
Points Balance: %%=FormatNumber(@LoyaltyMemberCurrency_PointsBalance,"N0","en-US")=%%
```
#### See Also
- [_Salesforce Help_: Use Loyalty Management Content Blocks in Email](https://help.salesforce.com/s/articleView?id=xcloud.content_block.htm&type=5&language=en_US)
- [_Salesforce Help_: Create Content Blocks](https://help.salesforce.com/s/articleView?id=mktg.mc_ceb_create_content_blocks.htm&type=5&language=en_US)
- [_Salesforce Help_: Share Content](https://help.salesforce.com/s/articleView?id=mktg.mc_ceb_share_content.htm&type=5&language=en_US)
# Design Ethical AI Models
Salesforce offers guidance to help you practice ethical use of artificial intelligence (AI) in your business.
## Ethical AI at Salesforce
Ethical AI is an essential part of Salesforce's commitment to the ethical and humane use of technology. For an overview, check out these resources.
- [Ethical and Humane Use](https://www.salesforce.com/company/ethical-and-humane-use/) at Salesforce
- [Responsible Creation of Artificial Intelligence](https://trailhead.salesforce.com/en/content/learn/modules/responsible-creation-of-artificial-intelligence) Trailhead module
## Bias in Modeling Data
Bias in data can lead to unfair or inaccurate predictions that can unintentionally disadvantage certain groups or skew business outcomes. In AI Models (formerly Einstein Studio), building ethical models starts with understanding where bias exists in your data and taking proactive actions to minimize its impact throughout the model lifecycle.
Binary or Multiclass Models
BIAS TYPE SCENARIO Recommended Action
Historical
Past data reflects existing inequalities or human decisions that weren't
objective.
For example, a model that predicts customer prioritization can perpetuate
service quality imbalances by continually favoring existing customer profiles.
Historical support data indicates that certain customers received faster
resolutions due to perceived importance or spending power.
Before deployment, audit or test models that use diverse datasets and fairness
metrics to check for bias.
To detect and address misclassifications, implement a human-in-the-loop review
process for critical decisions.
Variable (Feature)
Input variables that are used to train a model unfairly influence predictions or
reveal hidden bias. They’re introduced by choice or are a representation of
variables in your data. Bias occurs when certain attributes, such as location,
age, or gender, disproportionately influence predictions.
For example, a model that predicts customer satisfaction uses the “preferred
communication channel” variable. Some customer segments prefer specific channels
(chat, phone, or email) because of age, accessibility, or cultural factors. The
model misjudges satisfaction for groups that engage through less-dominant
channels.
Before deployment, audit or test models that use diverse datasets and fairness
metrics to check for bias.
Remove or modify variables that directly reference sensitive attributes, or
replace them with less biased proxies.
Change decision thresholds for underrepresented groups to mitigate unfair
outcomes.
To detect and address misclassifications, implement a human-in-the-loop review
process for critical decisions.
Labeling
Outcomes in data are inconsistently or unfairly labeled due to inconsistent,
inaccurate, or subjective judgment.
For example, a model that predicts churn uses the churn label “no purchase in 90
days”. However, some customers can have long buying cycles, such as seasonal
shoppers. The model predicts that these customers “churned” even though their
consumer behavior is normal for their segment.
Audit labels to ensure that they accurately reflect the real-world outcome.
Exclude data points where labels are clearly inconsistent or subjective. Ensure
that segments that were misrepresented have sufficient examples with correct
labels.
Sampling
Training data isn’t diverse enough to represent customers or use cases.
For example, a model that predicts the likelihood to purchase overestimates
engagement or satisfaction scores. Because inactive or churned customers are
underrepresented, the model hasn’t learned from less active customer segments.
Audit training data to identify which segments of your customer base or use
cases are underrepresented. Also, compare model performance across different
segments to identify disparities.
# Developer Edition Limits and Guidelines for Data 360
Developer Edition orgs with Agentforce and Data 360 have certain limits and guidelines for Data 360 usage.
### Required Editions
Available in: Developer Edition
This table is a partial list of limits. For other feature limits and guidelines related to Agentforce in Developer Edition orgs, see [Developer Edition with Agentforce and Data 360](https://help.salesforce.com/s/articleView?id=xcloud.overview_developer_edition_agentforce_datacloud.htm&type=5&language=en_US). For Developer Edition org allocations, see [Salesforce Developer Edition Allocations](https://help.salesforce.com/s/articleView?id=xcloud.overview_limits_developer.htm&type=5&language=en_US).
| Feature | Limits and Guidelines | Notes |
| --- | --- | --- |
| Number of data spaces | 1 | The default data space is the only data space available. |
| Total data size limit | 10 GB | |
| Total number of data models | 300 | |
| Total number of data streams | 100 | |
| Total number of data lake objects (DLOs) | 100 | This limit applies to data lake objects created as part of data streams or in a standalone manner. |
| Total number of streaming data transforms per org | 3 | |
| Maximum number of batch transforms that can be created in an org | 5 | |
| Maximum number of data model objects | 300 | |
| Maximum scheduled job frequency per ruleset | 0 | When using Data 360 in a Developer Edition org, ruleset runs aren’t scheduled. Use Run Ruleset to kick off a ruleset job manually. |
| Total number of calculated insights per org | 10 | This limit includes calculated insights in active, inactive, and draft statuses. |
| How often calculated insights are processed | 0 | When using Data 360 in a Developer Edition org, schedules are ignored. Use Publish Now to kick off a refresh manually. |
| Total number of active segments | 25 | An active segment is a created segment with all functionality available. These limits are enforced by the UI. Learn more in [Create a Standard Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&type=5&language=en_US) and [Segment Types and Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_types_statuses.htm&type=5&language=en_US). |
| Maximum number of scheduled publishes per standard segment per day | 0 | When using Data 360 in a Developer Edition org, segment publishes aren’t scheduled. Use Publish Now to kick off publication manually. |
| Total number of activation targets | 15 | An activation target is information stored for a given activation platform, which is where a segment’s data is sent during the activation process. |
| Total number of identity resolution rulesets per org | 2 | |
| Total number of data actions per org | 5 | |
| Total number of queries per day | 1,000, with 2 concurrent queries allowed | |
| Maximum number of scheduled refreshes per data stream per day | 0 | When using Data 360 in a Developer Edition org, data stream refreshes aren’t scheduled. Use Refresh Now to kick off data ingestion manually. |
# Disable a Currency Connection in Data Cloud
While we recommend keeping the currency connection in Data Cloud enabled, if you plan to disconnect a standard Salesforce CRM connection from Data Cloud, disable the currency connection to Data Cloud first.
### Required Editions
User Permissions Needed
To disable a connection:
Permission set:
1. Go to **Data Cloud Setup**.
2. Under Admin Tools, click **Currency Connections**.
3. From the connection’s dropdown menu, click **Disable**.
Then disable the related currency connection. For more information, see [Disable a Salesforce CRM connector](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_salesforce_crm_connection.htm&language=en_US).

Note You can’t disable the connector to the Data Cloud home org.
In a multicurrency configuration, you must also [delete the associated CurrencyType data stream](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_data_stream.htm&language=en_US).
# Disable a Data Stream Field
If a field is no longer required in a data stream, you can disable it. Disabling a field removes it from the data stream, and no new data is ingested. You can’t assign the name of a disabled field to a new field.
### Required Editions
User Permissions
Needed
To disable a data stream field
Permission set:
Before disabling a data stream, review [Considerations for Data Stream Field Disablement](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_field_deletion_settings.htm&release=264.0.0&type=5 "There are few restrictions to consider when planning to disable a data stream field.").
After you disable a field you can’t enable it again, but existing data remains in Data 360. However, you can enable a disabled field in Salesforce CRM connector data stream. See [Disable or Re-enable Salesforce CRM Connector Data Stream Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_disable_or_reenable_data_stream_field.htm&release=264.0.0&type=5 "Disable fields in a Salesforce CRM connector data stream to stop new data ingestion, clear existing data for that field, and remove it. If you need a field again later for a standard or custom data lake object (DLO), re-enable it. Give a new field a different name than any disabled field.").
1. Go to the Data Streams tab.
2. On the Fields tab on the record page, view the fields associated with the data stream.
3. In the Search field, enter the field name or scroll the page to locate it.
4. At the end of the row for the field, click the down arrow and select **Disable Field**.
5. Click **Disable**.
The disabled field remains in the data lake object (DLO), and the data ingested before the field was disabled is still available in the DLO. You can't delete a DLO field.
- **[Considerations for Data Stream Field Disablement](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_field_deletion_settings.htm&release=264.0.0&type=5)**
There are few restrictions to consider when planning to disable a data stream field.
#### See Also
- [_Salesforce Help_: Delete Fields](https://help.salesforce.com/s/articleView?id=platform.deleting_fields.htm&type=5&language=en_US)
# Disable or Re-enable Salesforce CRM Connector Data Stream Fields
Disable fields in a Salesforce CRM connector data stream to stop new data ingestion, clear existing data for that field, and remove it. If you need a field again later for a standard or custom data lake object (DLO), re-enable it. Give a new field a different name than any disabled field.
### Required Editions
User Permissions Needed
To disable or re-enable Salesforce CRM connector data stream fields
System admin profile OR
Data 360 Architect permission
set
#### See Also
- [_Salesforce Help_: Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.")
- [_Salesforce Developers_: updateDataStream](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=updateDataStream)
## Disable a Single Salesforce CRM Connector Data Stream Field
If you no longer need a field in a Salesforce CRM connector data stream, disable it.
To disable a single field, follow the instructions in [Disable a Data Stream Field](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_data_stream_fields.htm&release=264.0.0&type=5 "If a field is no longer required in a data stream, you can disable it. Disabling a field removes it from the data stream, and no new data is ingested. You can’t assign the name of a disabled field to a new field.").
## Review and Disable Multiple Salesforce CRM Connector Data Stream Fields
If Data 360 can't extract data stream fields from the source because of permission changes, field deletions, or other issues, the data stream stops working. To fix the data stream, review its fields, identify the fields with errors, and disable them in bulk. Alternatively, enable the required permissions. You can’t disable source fields used in formulas. To disable such fields, first remove the related formula from the data stream, and then disable the fields. To remove the formula, in Data 360, go to the Data streams tab, find the formula field and click Edit.
1. In Data 360, go to the **Data Streams** tab.
2. Click **Review Fields**.
3. Under **Fields to Disable**, select the fields to disable.
4. Review which segments, activations, and other features depend on them to prevent disruptions. See Example.
5. Click **Disable Selected**.

Example Check whether the data model objects (DMOs) or calculated insights use the fields that you want to disable.
**DMO FIeld Mapping**
- In Data 360, go to the **Data Model** tab.
- Enter a potentially affected DMO.
- Check whether the DMO maps any of the fields.
**Calculated Insights**
- In Data 360, go to the **Data Model** tab.
- Check whether any calculated insights references fields you want to disable.
## Re-enable a Salesforce CRM Connector Data Stream Field
If a data stream field becomes relevant again, re-enable it by adding a source field to the data stream.
1. In Data 360, go to the **Data Streams** tab.
2. Select the data stream for which you want to re-enable the field.
3. On the **Fields** tab, click **Add Source Field** on the top right.
4. Select your disabled field to re-enable it.
You re-enabled the disabled field, and its data is now ingested again to the original DLO field that it was paired with.
Alternatively, you can re-enable a disabled field by re-deploying a data stream, including the disabled field, see [Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification."). You can also use the [UpdateDataStream](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=updateDataStream) endpoint of the Data 360 Connect REST API.
# Disable Source Fields
After your schema is created you can disable source fields as needed.
### Required Editions
User Permissions Needed
To disable source fields
Permission set:

Note
- Disabled fields can’t be re-enabled.
- Fields used as part of the Primary Key, Event Date Time, or Record Modified fields can’t be disabled. Additionally, system-generated fields like Data Source, Data Source Object, and Internal Organization can’t be disabled.
To disable a field:
1. Go to the Data Streams tab and select a data stream.
2. View or search the fields associated with the data stream in the table.
3. Click the dropdown arrow for the field.
4. Click **Disable Field**.
5. When prompted, click **Disable**.
The field is disabled. Data that was previously ingested for this field remains, however, no new data is populated.
# Disconnect a B2C Commerce Instance Connection
You can delete a connection to your B2C Commerce instance. Removing the connection stops data ingestion from your B2C Commerce instance to Data 360.
### Required Editions
User Permissions
Needed
To disconnect a connection
System admin profile OR
Data Cloud Architect permission set
1. From **Setup** click **Data Cloud Setup**.
2. Under Salesforce Integrations, select **B2C Commerce**.
3. Find the connector that you want to disconnect.
4. Click ▼ next to the connection name, and select **Disconnect**.

Note If the connection that you’re disconnecting has data streams or activations, you’re notified that Data 360 can’t disconnect it. Delete the data streams or activations, and try again.
The instance and all its data is removed from Data 360.
#### See Also
- [_Salesforce Help_: Delete a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_data_stream.htm&release=264.0.0&type=5 "You can delete a data stream in Data 360 if the connection is no longer needed.")
# Disconnect a Data Source
If needed, a data source can be disconnected and removed from Data 360. This disconnect removes all provided data.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
1. From Setup, select **Data Cloud Setup**.
2. Go to the data source page found in Salesforce Integrations or External Integrations.
3. To disconnect an org from Data 360, click the dropdown menu on the right side of the source's setup page.
4. Click **Disconnect**.

Note If the org has data streams or segmentations associated with it, these streams must be removed before disconnecting the org.
# Disconnect a Salesforce CRM Connection
When you no longer need a connection, you can delete it. After you remove a standard Salesforce CRM connection, Data 360 stops ingesting data from the connected org and deletes all the data it ingested from that org, except trust files. Data ingested from the org is removed from unified profiles the next time that identity resolution runs.
### Required Editions
User Permissions Needed
To disconnect a connection
System admin profile OR
Data 360 Architect permission
set
1. From Setup, select **Data 360 Setup**.
2. In Salesforce Integrations, select **Salesforce CRM**.
3. Next to the connection that you want to remove, click ▼ and select **Disconnect**.

Note If the connection you’re disconnecting has data streams and associated data action targets or is tied to a Data 360 One companion connection, you can’t remove the connection. To remove the connection, first delete the data streams or remove the companion connection.
You can't edit or delete Salesforce system data streams that other applications use, such as these Digital Wallet system data streams: PF (ProvisionedFeature), TET (TenantEntitlementTransaction), or TUTM (TenantUsageTypeMultiplier). You also can't remove a connection that includes them. To remove the connection, contact Salesforce Customer Support.
4. Click **Disconnect** to get redirected to the login screen.
5. Log in to the org using your Salesforce credentials.
6. Confirm disconnection by entering the Data 360 org identifier. You can find this ID on the modal under **Data 360 Org Details**. This ID specifies which Data 360 org stops retrieving data from your source org.
7. Check the checkbox to agree to disconnect the connection and click **Disconnect**.
The connection no longer appears in the list of standard Salesforce CRM connections.
After you remove the connection, you can't undo it.
The connection and all of its data is removed from Data 360, but the trust files aren't removed.
# Disconnect an Omnichannel Inventory Connection
You can delete a connection to Omnichannel Inventory if you don't need it. Removing the connection stops Data 360 from using your inventory as a data source and data action target.
### Required Editions
User Permissions
Needed
To disconnect Omnichannel Inventory:
One of these permisison sets:
Data Cloud Architect
Commerce Intelligence Admin

Note Disconnecting deletes the data streams and associated data action targets for this connection. This action can’t be undone.
1. From Data Cloud Setup, in the Quick Find box, enter Omnichannel Inventory Connector, and then select **Omnichannel Inventory Connector**.
2. Find the connector that you want to disconnect.
3. From the dropdown menu next to the connection name, select **Disconnect**.
4. Click **Disconnect**.
The connector is removed from the list of connected Omnichannel Inventory instances.
#### See Also
- [Set Up an Omnichannel Inventory Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_oci_connection.htm&release=264.0.0&type=5 "Ingest your Omnichannel Inventory data into Data 360 using the Omnichannel Inventory connector.")
- _Salesforce Help_: Set Up an Omnichannel Inventory Connection
# Docling Parser
The Docling parser is a third-party intelligent document parsing framework that brings together multiple open-source models for layout understanding and table extraction. To enhance responses from information available in images and complex tables, combine the Docling parser with image processing by using Large Language Models (LLMs).

Note Using LLMs to parse images impacts credit consumption and is billed against the Intelligent Processing usage type. For more information, see [Billing Considerations for Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&type=5&language=en_US).
With LLM-based image processing, Data 360 filters out unnecessary images such as logos and routes only complex infographics. Data 360 captures and sends pages containing more than a specific threshold of images as a single whole-page image for captioning. This captures any relationships between multiple images, maintains quality, and reduces latency.
With LLM-based image processing, Data 360 evaluates and routes only complex tables to the LLMs. These include tables with nested headers or long-form merged columns that span multiple pages.
For more information, see [Docling parser](https://github.com/docling-project/docling-parse).
Use the Docling parser to parse content that contains information in these formats.
Parser Option
Format
Description
Extension
Docling
Document
Structured content such as text and tables in documents.
.pdf, .docx, .doc
Spreadsheet
Spreadsheet data in cells, rows, and columns.
.xlsx, .xls
Slide Deck
Content in presentations such as PowerPoint.
.pptx, .ppt
Web Page
Content in websites.
.html, .xml, .xhtml, .htm
Docling + LLM-Based Image Processing
Image File
Content in images, diagrams, and flowcharts. Parse images using LLMs by
turning-on the image-processing toggle when you define chunking strategies.
.png, .jpg, .jpeg, .bmp, .tiff, .tif, .gif, .pdf
Complex Tables
Content in tables with merged cells or columns and nested multi-level headers.
Parse complex tables using LLMs by turning on the image-processing toggle when you
define chunking strategies.
.pdf
You can’t select both the Docling parser and LLM-based Visual Data Pre-processing options for a search index.
To parse images using an LLM, turn on image processing when you select chunking strategies. For more information on configuring content parsing with Data 360 search indexes, see [Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&type=5&language=en_US) and [Create a Hybrid Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&type=5&language=en_US).

Example Use Case: Select Docling parser with image processing in scenarios where business-critical information is embedded within visual elements of enterprise documents.
Consider an airline maintenance division that manages operational processes through structured RACI-style flowcharts within its governance manuals. These process maps define critical handoffs and validations across functions such as operators, reps, modules, planning, and operations. Each diagram includes directional arrows, decision nodes, and annotated swim lanes, reflecting step-by-step responsibilities from irregularity detection through to work plan reprioritization and resource redistribution.
With this enhancement, the LLM can interpret the flowchart as a structured process, recognizing nodes, connectors, arrows, and step order. Instead of a flat list of labels, the LLM reconstructs the sequential flow of actions across roles and departments. As a result, answers to questions from the field related to responsibilities or the sequence of steps are more accurate.

Example Use Case 2: If business-related critical information is embedded in complex tables, select the Docling parser with image processing. This Accounts Management table contains nested headers and rows of dense text.
Data 360 chunks the information in the table and preserves the header information before sending the chunks to the LLM. This process improves response accuracy and reduces hallucinations.
# Document AI
Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.
Document AI supports two processing modes.
- Real-time (Transactional) Mode: Invoke Document AI APIs directly for documents stored in Salesforce or the documents sent at run time. You don't need to create unstructured data model objects (UDMOs).
- Batch Mode: To process large volumes of documents from external sources, create unstructured data model objects (UDMO) that reference the files. Data 360 has several connectors built to ingest unstructured data from third-party sources. Document AI extracts data from documents into Data Lake Objects (DLO), which represent schemas for the extracted data. Then, your data is available for search index processing and retrieval from automation flows or AI agent actions.
## Document AI Requirements
- [Turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) and [enable Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5) to use Document AI in Data 360.
- You need Data 360 licenses to use Document AI in Data 360. Document AI isn't available with Customer Data Platform licenses.
## Example Use Cases for Document AI
Explore how teams working in various clouds can use Document AI to create draft configurations, refine document schemas, and publish them for production use.
| Cloud | Use Case |
| --- | --- |
| Sales Cloud | Ingest contract documents and proposals in Microsoft Word files and link them to customer profiles to centralize all contract data. |
| Sales Cloud | Ingest invoices, workbook quote templates, or pricing sheets to compare them against data extracted from related loan applications. |
| Service Cloud | Ingest guest survey data and business review presentations delivered as Microsoft PowerPoint files. Create customer records and follow-up for future opportunities. |
| Employee Service | Ingest tax return documents and HR forms in spreadsheet-format, such as timesheet reports and benefit enrollment sheets. Link them to employee records without rigid cell-mapping configuration. |
| Health Cloud | Extract data from patient lab reports in a range of formats, including PDFs, system-generated images, or images of hand-written notes. |
## Supported Large Language Models (LLMs)
Document AI supports these LLMs.
Supported LLMs
| Model Provider | Model Family |
| --- | --- |
| OpenAI | GPT 5.4 (OpenAI GPT-4o\*) |
| Vertex AI (Google) | Gemini 2.5 Flash, Gemini 3 Flash |
| Anthropic | Claude Sonnet 4.6 |
\*Document AI in Government Cloud supports only the OpenAI GPT-4o model hosted in Microsoft Azure. For more information, review [Agentforce in Government Cloud](https://help.salesforce.com/s/articleView?id=ind.government_cloud_agentforce.htm&type=5&language=en_US).
## Supported File Types
Document AI supports these file formats.
- PDF files (.pdf)
- Images (.png, .jpeg)
- Microsoft Word documents (.docx)
- Microsoft PowerPoint presentations (.pptx)
- Microsoft Excel single-sheet workbooks (.xlsx)
See the Document AI table on [Data Cloud Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") for specific limits.
## Document AI in Connect API
You can use the Data Cloud Connect API to create Document AI configurations. See the [Connect API reference](https://developer.salesforce.com/docs/data/connectapi/references/spec?meta=getConfigurations) for more.
## Billing Considerations for Document AI
Use of Document AI has billing implications. For more information, see [Billing Considerations for Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_billing_considerations.htm&release=264.0.0&type=5 "Document AI uses Data 360 to extract structured data from unstructured documents and Flex Credits to call generative AI. Use of Document AI impacts the consumption of credits in these usage types.").
- **[Create a Document Schema Config (Auto-extraction)](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config.htm&release=264.0.0&type=5)**
Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the auto-extraction option in the document schema builder to have an LLM define the structure of the document schema. The builder auto-populates all fields, tables, and columns.
- **[Create a Document Schema Config (Manually)](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_manual.htm&release=264.0.0&type=5)**
Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the document schema builder to manually define the structure of the document schema by adding fields and tables.
- **[Create a Document Schema Config (Without Source)](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_no_source.htm&release=264.0.0&type=5)**
Configure a document schema to use in programmatic API workflows. Use the document schema builder to define a new document schema.
- **[Manage Document AI Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_manage_configs.htm&release=264.0.0&type=5)**
View, edit, publish, export, and rebuild Document AI configurations. Package Document AI configurations in data kits. Save Document AI configurations as drafts, and refine your extraction schemas over multiple sessions.
- **[Document AI Example Schemas](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_schema_ref.htm&release=264.0.0&type=5)**
The following prompts are JSON-formatted schemas that you can use when creating an Document AI configuration in Data 360. Use these examples as starting points, or modify them for your specific use cases.
- **[Billing Considerations for Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_billing_considerations.htm&release=264.0.0&type=5)**
Document AI uses Data 360 to extract structured data from unstructured documents and Flex Credits to call generative AI. Use of Document AI impacts the consumption of credits in these usage types.
#### See Also
- [Create a Document Schema Configuration Using Auto-Extraction](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config.htm&release=264.0.0&type=5 "Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the auto-extraction option in the document schema builder to have an LLM define the structure of the document schema. The builder auto-populates all fields, tables, and columns.")
- [Create a Document Schema Configuration Manually](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_manual.htm&release=264.0.0&type=5 "Configure a document schema to represent data extracted from your source files into a Data Lake Object (DLO). Use the document schema builder to manually define the structure of the document schema by adding fields and tables.")
- [Create a Document Schema Configuration Without a Source Object](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_no_source.htm&release=264.0.0&type=5 "Configure a document schema to use in programmatic API workflows. Use the document schema builder to define a new document schema.")
- [Manage Document AI Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_manage_configs.htm&release=264.0.0&type=5 "View, edit, publish, export, and rebuild Document AI configurations. Package Document AI configurations in data kits. Save Document AI configurations as drafts, and refine your extraction schemas over multiple sessions.")
- [Document AI Example Schemas](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_schema_ref.htm&release=264.0.0&type=5 "The following prompts are JSON-formatted schemas that you can use when creating an Document AI configuration in Data 360. Use these examples as starting points, or modify them for your specific use cases.")
- [Unstructured Data Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_workflow.htm&release=264.0.0&type=5 "Regardless of your use case for unstructured data, there's a general workflow to ingest and process it in Data 360.")
- [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- [Billing Considerations for Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_billing_considerations.htm&release=264.0.0&type=5 "Document AI uses Data 360 to extract structured data from unstructured documents and Flex Credits to call generative AI. Use of Document AI impacts the consumption of credits in these usage types.")
# Document AI Example Schemas
The following prompts are JSON-formatted schemas that you can use when creating an Document AI configuration in Data 360. Use these examples as starting points, or modify them for your specific use cases.
## Lab Report
Create an output DLO from a pathology lab report.
```json
{
"$schema": "http://json-schema.org/draft-07/schema#",
"type": "object",
"title": "Pathology Report Schema",
"properties": {
"lab_name": {
"type": "string",
"description": "Name of the pathology lab"
},
"lab_contact": {
"type": "string",
"description": "Contact number of the lab"
},
"lab_email": {
"type": "string",
"description": "Email address of the lab"
},
"lab_address": {
"type": "string",
"description": "Full address of the lab"
},
"lab_website": {
"type": "string",
"description": "Website URL of the lab"
},
"patient_name": {
"type": "string",
"description": "Name of the patient"
},
"patient_age": {
"type": "string",
"description": "Age of the patient"
},
"patient_sex": {
"type": "string",
"description": "Sex of the patient"
},
"patient_id": {
"type": "string",
"description": "Patient identification number"
},
"sample_collection_address": {
"type": "string",
"description": "Address where the sample was collected"
},
"referred_by": {
"type": "string",
"description": "Name of the referring doctor"
},
"registration_date": {
"type": "string",
"description": "Date and time of registration"
},
"collection_date": {
"type": "string",
"description": "Date and time of sample collection"
},
"report_date": {
"type": "string",
"description": "Date and time of report generation"
},
"test_name": {
"type": "string",
"description": "Name of the test conducted"
},
"test_result": {
"type": "number",
"description": "Result value of the test"
},
"result_remarks": {
"type": "string",
"description": "Remarks based on the test result"
},
"reference_value": {
"type": "string",
"description": "Reference value for the test"
},
"unit": {
"type": "string",
"description": "Unit of measurement for the result"
},
"interpretation_table": {
"type": "array",
"items": {
"type": "object",
"description": "Table for interpretation of results",
"properties": {
"result_index": {
"type": "string",
"description": "Range of result index"
},
"remarks": {
"type": "string",
"description": "Remarks corresponding to the index range"
}
}
},
"description": "Table for interpretation of results"
},
"comments": {
"type": "string",
"description": "Additional comments about the test"
},
"report_signatories": {
"type": "array",
"items": {
"type": "object",
"properties": {
"signatory_name_role": {
"type": "string",
"description": "This is name of the signature along with any salutation"
},
"signatory_qualification": {
"type": "string",
"description": "These are any of the qualifications or title associated with the signatory"
}
}
}
}
}
}
```
## Invoice
Create an output DLO from an invoice.
```json
{
"$schema": "http://json-schema.org/draft-07/schema#",
"type": "object",
"title": "Invoice Schema",
"properties": {
"VendorName": {
"type": "string",
"description": "Name of the vendor issuing the invoice"
},
"Vendor Address": {
"type": "string",
"description": "Full address of the vendor"
},
"Vendor Phone number": {
"type": "string",
"description": "Phone number"
},
"Billing Address": {
"type": "string",
"description": "Full name and address of the billing entity"
},
"Product Item List": {
"type": "array",
"items": {
"type": "object",
"description": "Table containing the list of products",
"properties": {
"Item ID": {
"type": "string",
"description": "Item id"
},
"Item Description": {
"type": "string",
"description": "Full description for the item"
},
"Quantity": {
"type": "number",
"description": "Number of items"
},
"Unit Price": {
"type": "number"
},
"Line total": {
"type": "number",
"description": "Line total for the product line item"
}
}
},
"description": "Table containing the list of products"
},
"Total amount": {
"type": "number"
}
}
}
```
## Resume
Create an output DLO from a resume.
```json
{
"$schema": "http://json-schema.org/draft-07/schema#",
"type": "object",
"title": "Resume Schema",
"properties": {
"Candidate First Name": {
"type": "string",
"description": "Candidate's first name"
},
"Candidate Surname": {
"type": "string",
"description": "Candidate's surname. Include the rest of the name apart from the title and first name. Include any initials."
},
"Candidate Title": {
"type": "string",
"description": "Title of the candidate. Generally comes before their name"
},
"Candidate Address line 1": {
"type": "string",
"description": "Address line 1 of the candidate"
},
"Candidate Address line 2": {
"type": "string",
"description": "Address line 2 of the candidate"
},
"Candidate City": {
"type": "string",
"description": "City name of the candidate (Use current residential address)"
},
"Candidate State": {
"type": "string",
"description": "State name of the candidate (Use current residential address)"
},
"Candidate's country": {
"type": "string",
"description": "Country name of the candidate (Use current residential address)"
},
"Candidate's pincode": {
"type": "string",
"description": "Pincode of the candidate (Use current residential address)"
},
"Candidate Phone number": {
"type": "string"
},
"Candidate's academic record": {
"type": "array",
"items": {
"type": "object",
"properties": {
"Name of institution": {
"type": "string"
},
"Name of the program or degree": {
"type": "string",
"description": "Full details of the academic program including degree name and specialization"
},
"Description of the program": {
"type": "string"
},
"Duration of program": {
"type": "string",
"description": "Contains start and end year/month"
}
}
}
},
"Candidate's work experience": {
"type": "array",
"items": {
"type": "object",
"properties": {
"Organization name": {
"type": "string"
},
"Duration of tenure": {
"type": "string",
"description": "Contains start and end year/month"
},
"Role": {
"type": "string"
}
}
}
}
}
}
```
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
- [Auto-extract the Document Schema](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config.htm&release=264.0.0&type=5 "Use the document schema builder to auto-extract the document schema, including fields, tables, and columns.")
- [Add Tables to Extract](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_manual.htm&release=264.0.0&type=5 "Configure the tables to extract.")
# Drift Monitoring (Beta)
Use Drift Monitoring in Data 360 to track predictive model degradation, which occurs when the distribution of model predictions changes significantly over time. Drift indicates shifts in customer behavior, business conditions, or underlying data patterns.

Note Predictive Drift Monitoring is a beta service that is subject to the Beta Services Terms at Agreements — Salesforce.com or a written Unified Beta Agreement if executed by Customer, and applicable terms in the Product Terms Directory. Use of this beta service is at the Customer's sole discretion.
Use drift monitoring in Data 360 to track these two types of drift across active binary and regression models.

Note To turn on predictive model drift monitoring, use Feature Management in your org settings.
## Variable Drift
Variable drift occurs when the distribution of live input data shifts away from training data. For example, a lead scoring model trained on email and organic search leads drifts when a new campaign suddenly drives most leads from social media.
The Variable Drift Over Time chart visualizes how the distribution of input variables changes over time. Lower scores indicate stable input data, while higher scores indicate greater drift that can affect model performance.
The Drift by Variable chart visualizes drift scores across input variables to help identify which variables contribute most to overall drift. Lower scores indicate stable input data, while higher scores indicate greater drift that can affect model performance.
To investigate a specific variable, view the variable-level breakdown and open the variable-specific drift chart.
## Prediction Drift
Prediction drift occurs when the distribution of predictions changes significantly over time, which can indicate shifts in customer behavior, business conditions, or underlying data patterns.
The Prediction Drift Over Time chart shows how model prediction distributions change over time. Lower scores indicate stable predictions, while higher scores indicate greater drift and potential shifts in underlying data patterns.
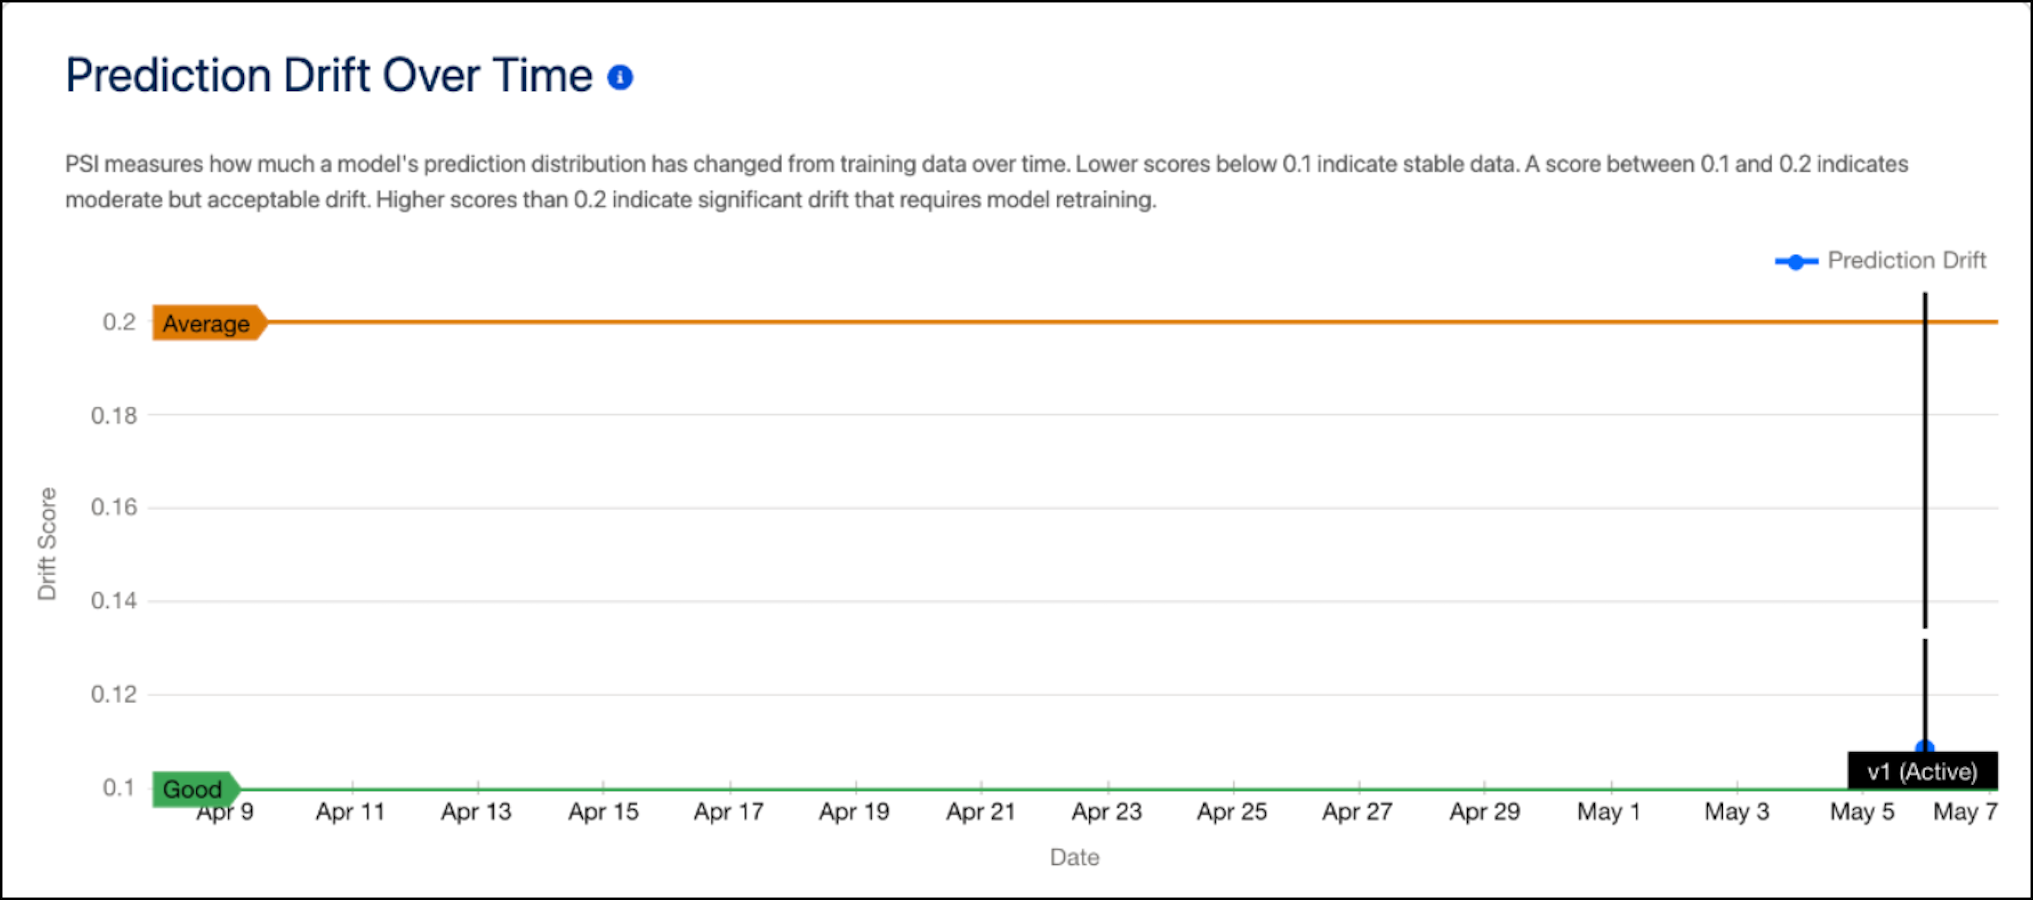
The Drift Score Distribution chart shows the distribution and frequency of prediction drift scores across inference runs. Rising drift scores indicate reduced model reliability and signal the need for retraining. To identify whether drift occurs only during specific periods or consistently increases over time, use this chart.
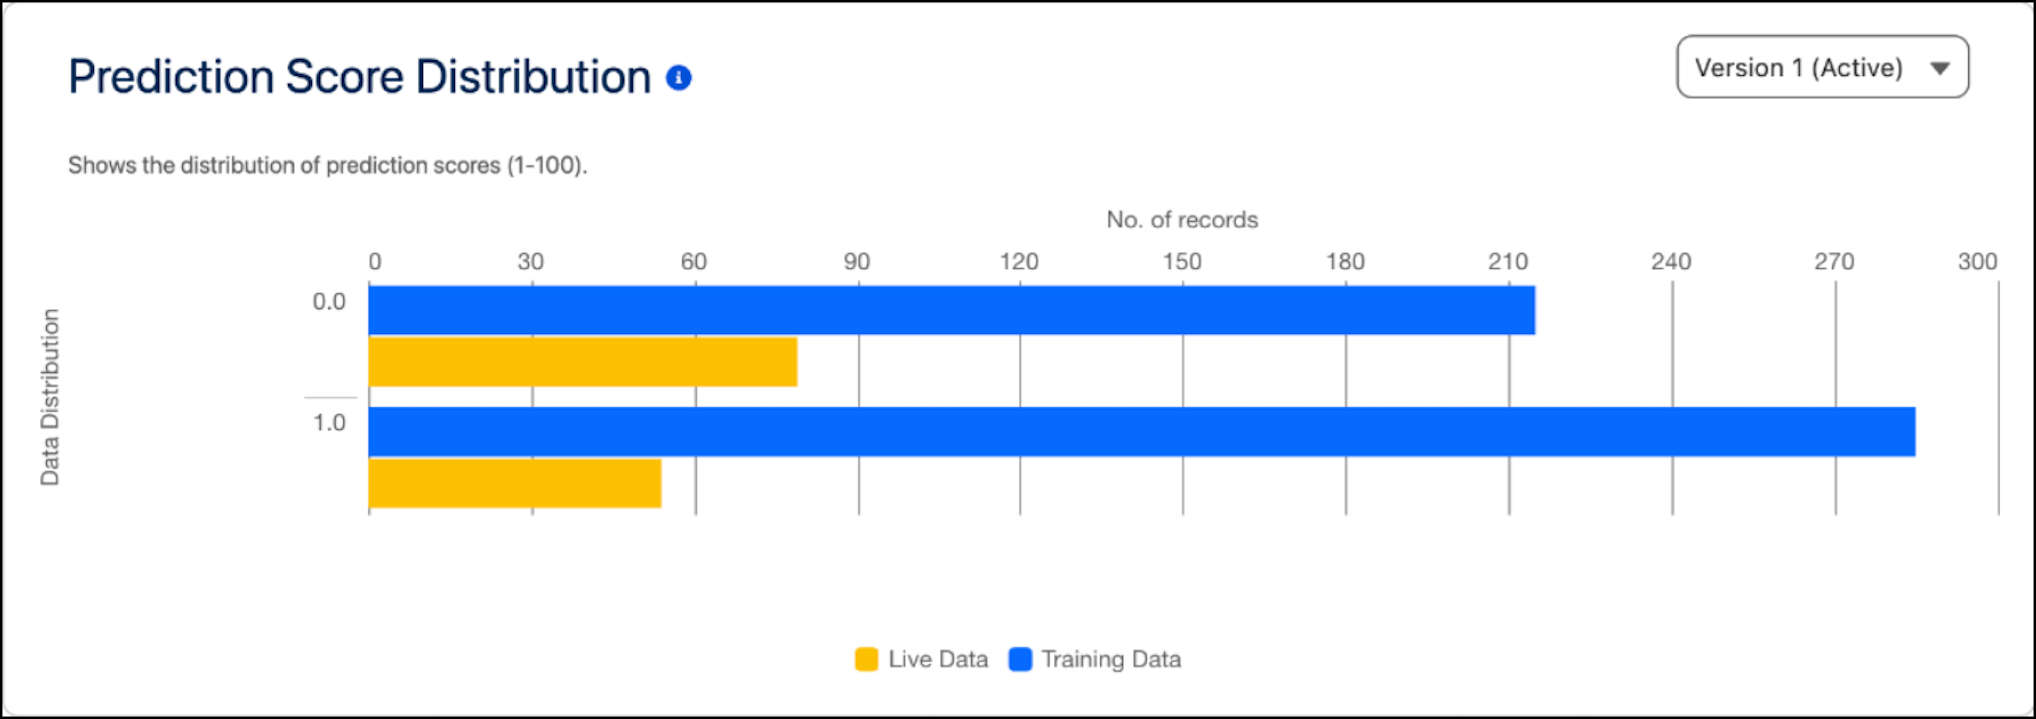
Thresholds for Prediction and Variable Drift
| STATUS | SCORE RANGE |
| --- | --- |
| Stable Drift | 0.0–0.1 |
| Moderate Drift | 0.1–0.2 |
| Significant | \>= 0.2 |
## Model Drift for an Activated Model
To monitor changes in an activated model, review its drift metrics in the AI Models tab in Data 360. The drift dashboard shows cards for variable drift and prediction drift. To track model changes over time, assess these metrics by day, week, or month.
Each drift card shows these details:
- Current drift score and status — stable, moderate, or significant drift
- Trend indicator that shows whether drift is increasing or decreasing
- Version markers on the trend chart that indicate when a new model version was activated
## Model Retraining
When drift scores reach the moderate or significant range, retrain the model to align it with current data patterns. To address the drift, train the model by using an updated dataset, and then activate the new version. Activation updates the drift baseline to reflect the new training data and adds version markers to the drift trend charts.
## Model Considerations
- Drift monitoring is available for binary and regression models and for Flow or API-based inferences only.
- Make sure that at least one inference job is running.
- An org can compute drift across all active inference jobs for a model. If a model has multiple inference jobs, drift scores reflect aggregated data across all jobs.
- Basic drift charts are available at no additional cost. Deeper analysis by inference job or inference channel is a paid feature that consumes Data 360 credits.
# Drive Better Decisions with Predictive and Generative AI
The Predictive Model reference action in Agentforce enables an AI agent to invoke a predictive model created in AI Models (formerly Einstein Studio). Use the action to generate on-demand, data-driven predictions, interpret the results, and provide recommendations for how to improve an outcome. The integration of predictive and generative AI improves the interpretability of results for taking the best actions.
Here’s how the reference action works.
- Model Connection, Creation, and Training: First, you connect an existing model or create and train predictive models in AI Models using historical data. These models predict outcomes based on specific input variables, such as customer behavior, sales trends, or service requests.
- Integration with Agentforce: For a predictive model to become available in Agentforce, you need to create a predictive action. Users can then select the right model for their use case and set the necessary parameters for the action.
- On-Demand Predictions: During a user interaction, the agent triggers the Predictive Model reference action. This action sends the relevant data (such as the customer information and interaction context) to the predictive model.
- Prediction Generation: The model processes the input data and generates an output—the prediction. For example, the likelihood of a customer making a purchase to the probability of a service issue occurring.
- Actionable Insights: The prediction is displayed to the agent in a clear and understandable format. In addition to the prediction, the model can provide top predictors that influenced a prediction and actionable recommendations, such as follow-up actions or personalized offers for a customer.
- Enhanced Decision-Making: Predictions and recommendations from models enable users to make better decisions. This can lead to improved customer satisfaction and business outcomes.
Some best practices for setting up the agent action include:
- Identify use cases where predictive AI can be useful by analyzing what questions your users would ask an agent. For example, when predicting churn, users may want to know things such as: "what's the risk of churn for my customer?"
- Build and train models that provide the predictions as answers for these questions.
- Get data from a flow, Apex, a Salesforce record, or directly from the context of the interaction.
- Because actions can be reused, we recommend creating one action per model. In the action setting, you can edit the agent instructions to describe the general purpose of the model. You can also customize the number of top factors and recommendations to display.
- Select the Show in Conversation checkbox for all outputs that you want the agent to display to the user.
- Create recommendation variables to provide dynamic recommendations, such as to suggest a particular upsell offer to maximize long term value. Or, use instructions to trigger an action based on a prediction result, such as a proactive service intervention if the likelihood of an escalation is high.
- Model input values are case-sensitive. If you know that your data can look different from what the model requires, add instructions on how to format the inputs in the way that the model inspects it, such as convert month to a number.
- Customize a topic by adding instructions to guide Agentforce for when to invoke a predictive model and connect it to your topic actions. You can create a new topic or use an existing one. Add instructions to help the agent understand how to answer questions about results provided by the model.

Example
An topic instuction can look like this:
_“If the user has questions about customer churn, first make sure to get inputs for the model and pass them into the Predict Churn Account action.”_
The model returns an output in JSON. Because you don’t want to display the results in the raw JSON format and want to show the conversational insights instead, you can add this instruction to your topic.
_“Don't show the raw output of the Predict Churn Account action to the user. Summarize the_ _results to the end user in simple English. Use the top predictive factors to explain_ _why the customer has a high or low churn score.”_
- **[Use the Predictive Model Agent Reference Action to Enhance Predictions](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_reference_action.htm&release=264.0.0&type=5)**
For an AI agent to provide and interpret outputs from a predictive model, you must create a custom agent action in your org. Let's look at how Agentforce can enhance predictions from a Predicted Attrition model that was created in Model Builder.
# Drop Columns Transformation
Drop unwanted columns from a batch data transform. For example, you can add a Drop Columns transformation after a Formula transformation to drop input columns used for a calculated column.
1. In the Transform node, select the column in the Preview tab.
2. In the Transform toolbar, click the **Drop Columns** button ().
The dropped column appears in the Drop Columns step.
3. Alternatively, to keep the columns selected instead of removing them click **Keep**.
4. To include additional columns, enter their label in the Select Columns to Drop/Keep Column.
5. Click **Apply** to add the transformation to the Transform node.
6. To view the canvas, click the **Collapse** button ().
7. Click **Save**.
From this point forward, dropped columns can’t be used in transformations and nodes. They also no longer appear in Preview.
# Dynamic Data Masking Best Practices
Here are some best practices for implementing dynamic data masking in Data Cloud.
- Identify sensitive data: Before you apply masking, identify which data fields are considered sensitive and need protection. For example, protect PII, financial records, and medical data.
- Role-based masking: Use role-based access controls to determine who sees what data. For example, senior managers can have access to full data, while other users see redacted or partially masked fields.
- Balance usability and security: Ensure that masking protects sensitive data while still allowing users to perform their tasks effectively. Aim for a balance between data protection and usability.
- Avoid masking key fields used in joins and queries: Masking fields that are used as join keys or in query filters can result in incorrect or incomplete result sets. To maintain query accuracy, avoid applying masking to fields that are critical for data relationships or filtering. A row-level security (RLS) with joins policy on masked key values doesn't return any results. Similarly, related lists based on masked fields don't show any data.
# Dynamic Data Masking Policies in Data 360
Dynamic data masking conceals sensitive data without altering its usability, accuracy, or relationships. It applies to all Data 360 objects and fields, regardless of the access method.
Data 360 protects sensitive data by encrypting it at rest, which prevents unauthorized access even if the database is compromised. With dynamic data masking, authorized users can view the data, but sensitive data is masked to prevent them from seeing it in plaintext.
Masking works together with other security features. First, access policies determine if users can see data. Then, masking policies determine if the user sees the data masked or unmasked. This is also known as dynamic or query-time masking.
Supported masking methods include redaction (with selective redaction), nullification, and rounding of datetime or numeric values for structured data.
- **[Dynamic Masking Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_types_of_dynamic_data_masking.htm&release=264.0.0&type=5)**
Dynamic data masking policies protect sensitive data by changing or hiding values when you query them. This is done based on user information, roles, or policy rules, but it doesn't change the data itself.
- **[Create a Dynamic Data Masking Policy for Structured Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_dynamic_data_masking_policy.htm&release=264.0.0&type=5)**
Protect sensitive information by restricting data visibility based on user roles and permissions.
- **[Masking Unstructured Data in Data 360 (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_unstr_data_masking.htm&release=264.0.0&type=5)**
Mask sensitive information in unstructured files, such as PDFs and text documents, so that only authorized users can view it. Masking policies work on sensitive data that’s automatically tagged or identified.
- **[Create a Dynamic Data Masking Policy for Unstructured Data (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_create_unstruc_dynamic_data_masking_policy.htm&release=264.0.0&type=5)**
Define a masking policy to protect sensitive information in unstructured files such as PDFs and text documents.
- **[Dynamic Data Masking Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_dynamic_masking_best_practices.htm&release=264.0.0&type=5)**
Here are some best practices for implementing dynamic data masking in Data Cloud.
# Dynamic Masking Types in Data 360
Dynamic data masking policies protect sensitive data by changing or hiding values when you query them. This is done based on user information, roles, or policy rules, but it doesn't change the data itself.
Here are some examples of masking types.
## Redaction
Replaces the data with X to completely hide the original content. Example: Redact the first three characters of email addresses.
## Nullification
Replaces the actual value with null, making it invisible to the user. Example: Mask a customer’s email address so it appears as null for unauthorized users.

Note Applying nullification to a boolean field sets its value to false by default.
## Datetime and Numeric Rounding
Reduces the precision of numeric or date values while keeping the data generally useful. Example: Display only the year in a date field: 1/1/2022 instead of 11/15/2022.
# Edit a Batch Data Transform
Make changes to your batch data transforms and save the results.
1. In Data Cloud, go to the Data Transforms tab.
2. From Recently Viewed, click  next to the data transform name, and select **Edit**.
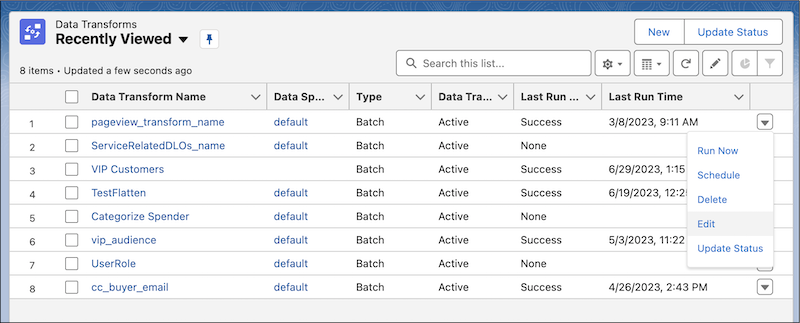
The canvas editor opens and displays the selected batch data transform.
3. Edit the batch data transform.
4. Click **Save**.
# Edit a Calculated Insight Schedule
In Data 360, you can change the schedule of calculated insights that are created with a SQL and the builder.
### Required Editions
1. In Data Cloud, go to the Calculated Insights tab.
2. Open the calculated insight that you want to change.
3. On the top right, click the dropdown, and select **Schedule**.
4. Make your changes, and click **Save**.
# Edit a Data Graph
You can change a data graph’s name and description, associate new data model objects (DMO), and make additive changes to the existing primary and associated DMOs.
### Required Editions
User Permission Set
Needed
To edit a data graph:
Permission set:
1. In Data Graphs, next to the data graph you want to change, select Edit.
You can edit data graphs that aren’t in a processing state.
2. To add associated objects, click **+** or search for a DMO.
If there's more than one path to a DMO, choose a path from the list of results. Longer paths add more levels to your data graph.
In real-time data graphs, the relationship join must use the primary key of the parent data model object (DMO). If a relationship requires a non–primary key field from the parent DMO, it isn’t supported for real-time data graph.
3. To add fields, select them in the data graph’s DMOs.
If the data graph is in draft status, you can add and remove objects and fields. If the data graph has any other status, you can add objects and fields but not remove existing ones.
When you edit a real-time data graph, you can’t add DMOs that create an N:1 relationship. Real-time data graphs support only 1:1 and 1:N relationships for new associations. Existing real-time data graphs that already include N:1 relationships continue to run. However, changes to the parent DMO in an N:1 relationship aren’t immediately reflected in the data graph.
4. To change a DMO’s filters, select the DMO and go to the Filters tab.
The available filter settings depend on the DMO category.
5. To edit the data graph’s properties, click **Edit Properties**.
You can’t edit some properties, such as the API name and data space.
6. Save your work.
- To save your changes without making the data graph active, click **Save Draft**. You can continue editing the data graph, but if you save a new draft, it overwrites the previous draft.
- To save the data graph and process the changes, click **Save and Build**.
During processing, the existing data graph remains active and shows a processing icon in its status. When processing is complete, the icon is removed, and the new data graph version is active.
If the build fails, select **Refresh Now**. In the meantime, the existing data graph remains active.
# Edit a Data Share
You can add or remove the data lake objects, data model objects, and calculated insights objects in a data share. When you add a Data 360 object to a data share, it’s accessible through the linked data share target. Similarly, when you remove a Data 360object, it’s inaccessible through the linked data share target.
### Required Editions
User Permissions
Needed
To edit data shares:
Permission set:
1. In Data 360, go to the Data Shares tab.
2. Click the data share that you want to edit.
3. On the data share’s object home page, click **Edit**.
4. Enter the Label, Name, Description for the edited data share.
5. Select the Data Space, click **Next**.
6. Select or deselect the Data 360 objects.

Note You can’t edit a data share if it’s linked to both a legacy Snowflake data share target and a Snowflake V2 data share target. To add or remove objects, unlink the data share from one of the Snowflake targets.
7. Click **Save**.
# Edit a Data Stream
Edit a data stream in Data 360 for the Amazon Simple Storage Service (Amazon S3), Google Cloud Storage (GCS), Azure, Marketing Cloud Engagement, and Secure File Transfer Protocol (SFTP) connectors. Changing the name of a data stream doesn’t change the name of the data lake object (DLO) that the data stream uses.
### Required Editions
User Permissions
Needed
To edit a data stream
Permission set:
1. Go to the Data Streams tab.
2. Next to the data stream that you want to edit, from the dropdown, select **Edit Data Stream**.
3. Make your changes and click **Save**.
#### See Also
- [_Salesforce Help_: Data Stream Settings](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_edit_settings.htm&release=264.0.0&type=5 "With data streams, you can schedule or run jobs to ingest data from a source system. These jobs pull data from the source system into the connected data stream. The method and frequency options for data ingestion depends on the type of connector. Use the data stream settings to create or change the execution parameters of a data stream.")
- [_Salesforce Help_: Using an Existing Data Lake Object to Create a Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_guardrails_existing_data_lake_object.htm&release=264.0.0&type=5 "You can use an existing data lake object (DLO) when creating an S3, Google Cloud Storage, or SFTP data stream. The data stream that initially created the DLO defines the characteristics, such as the primary key, event date time, and record modified field. You can convey how the new data stream’s fields conform to the existing DLO fields.")
# Edit a History Tracking Calculated Insight
You can modify the frequency, duration, and activation status of history tracking insights.
### Required Editions
1. Go to the **Calculated Insights** list view and select the source calculated insight or calculated history insight you want to edit.
1. Enable or disable **Track history**.
2. Change the **Schedule** and **Time** for the calculated insight.
2. Click **Save**.
# Edit a Model Configuration
Try different prompts and adjust your hyperparameters to evaluate how well the model responds to your prompts. However, if your model is already associated with prompts, create a new model instead. Updating model settings can affect the performance of associated prompts.
1. In AI Models (formerly Einstein Studio), on the Generative tab, click the model to edit your settings.
2. In Model Playground, click **Edit Model**.
3. Change your prompt, prompt settings, and hyperparameters. Then click **Update**.
# Edit a Segment
After you create a segment in Data 360, you can edit its rules or properties to provide updates or change the purpose. Changing the segment name doesn’t change the segment API name.
### Required Editions
Permission Sets Needed
To edit a segment:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, go to the **Segments** tab.
2. Select your segment.
3. To edit attribute rules or segment properties, click **Edit Rules** or **Edit Properties**.
If you don’t see these options, the segment was created via an API and only supports a limited set of actions.
- **[Copy a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_copy_segment.htm&release=264.0.0&type=5)**
In Data 360, you can copy an existing segment to populate it with the same filters and customizations as an existing segment.
- **[Delete a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_segment.htm&release=264.0.0&type=5)**
Delete a segment if it’s no longer needed. If the segment is attached to an activation, delete the activation first.
- **[Deactivated Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_segment.htm&release=264.0.0&type=5)**
If a segment is no longer needed, it can be deactivated through Data 360 and applies to all chosen targets. A deactivated segment no longer publishes, can’t be chosen for an activation, and can’t be re-enabled. If you plan to use the segment again, stop the publish schedule instead.
# Edit an Insight
If you created an insight using SQL or Insight Builder, you can change its attributes or logic and reuse it.
Insight Editing Guidelines
Item
Guidelines and Limitations
Measures
You can’t change the API name, data type, or rollup behavior.
You can add only aggregatable measures to an aggregatable insight.
You can add any measure to a non-aggregatable insight.
You can’t remove existing measures.
Dimensions
You can’t change the name or data type.
You can only add dimensions to an insight if it’s a key qualifier dimension.
See Key
Qualifiers .
You can’t update a non-transformed dimension. In this select statement, you
can’t update the soldToCustomer__c dimension, SELECT
SalesOrder.soldToCustomer__c AS soldToCustomer__c.
You can’t remove existing dimensions.
1. In Data 360, go to the Calculated Insights tab.
2. Open the calculated insight, and click **Edit**.
3. Make your changes, and click **Update**.
4. Click **Save**.
# Edit Attributes Transformation: Change the Column Names and Value Formats
Use the Edit Attributes transformation to make column names more descriptive and apply consistent formats to column values. You can set the labels and API names of all columns. You can also set the precision and scale for numeric columns, character length for text columns, and date formats for date columns.
1. In the Transform node, select the column in the Preview tab.
2. In the Transform toolbar, click the **Edit Attributes** button ().
3. Change the column attributes. Based on the column datatype, you can set these attributes.
Attribute
Description
Label
API Name
Precision
Scale
Length
Date Format
For more guidelines, see the “Field Name Restrictions” section in [this help topic](https://developer.salesforce.com/docs/atlas.en-us.bi_dev_guide_ext_data_format.meta/bi_dev_guide_ext_data_format/bi_ext_data_schema_reference.htm).
4. Click **Apply** to add the transformation to the Transform node. If applicable, Preview shows the new column label.
5. To view the canvas, click the **Collapse** button ().
6. Click **Save**.
# Edit Data Model Object Properties
You can edit Data Model Object (DMO) properties either on the Data Model tab or on the data mapping page.
### Required Editions
1. In Data 360, go to the Data Model tab.
2. Open your DMO, and click **Edit**.
3. Modify any of these properties: Object Label, Object Description, Field Label, or Enable Value Suggestion.
The Enable Value Suggestion option is available only for Text data type fields. If you enable this option, as you enter text in the Value field in the segment builder, you can select from the suggested values in the dropdown list.

Note When you edit field labels within DMOs, these changes are not automatically reflected in Related Lists. Related Lists display data based on the initial configuration at the the time of their creation. To ensure updated DMO field labels appear correctly, re-create or reconfigure the Related List on the record detail page after you change the DMO field lables.
4. To modify a DMO category, see [Change the Category of a Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_change_data_model_object_category.htm&release=264.0.0&type=5 "In most cases, a data model object’s category can’t be changed after the object is created. The category can be changed only if it’s changing from Profile to Other or from Other to Profile on an object that isn’t used in segmentation or activation.").
5. To delete a field, click the Delete icon.
You can’t delete a standard field of a standard DMO.
6. Save your changes.
You can also edit the DMO properties directly from the data mapping page by clicking the Edit Properties icon.
#### See Also
- [_Salesforce Help_: Use Value Suggestions in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_suggested_values_in_segments.htm&release=264.0.0&type=5 "You can enable value suggestions for data model object (DMO) fields if the data type is Text. Enable or deactivate the feature in the DMO record home. You can enable value suggestions for up to 500 attributes for your entire org. It can take up to 24 hours for suggested values to appear.")
# Edit or Delete a Classification in Data 360
Edit the name and description of a classification, manage its associated tags, or delete it if no longer needed. You can't delete classifications that are used in policies. This includes default classifications provided by Data 360.
### Required Editions
| User permission needed | |
| --- | --- |
| To edit or delete a classification: | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Classifications**.
3. Search for the classification.
4. Click its dropdown and select **Edit** or **Delete**.
5. Make your changes and click **Save**.
# Edit or Delete a Custom Taxonomy in Data 360
You can change the taxonomy's name and description. You can’t change the taxonomy type or its API name. You can't delete taxonomies that are used in policies. This includes default taxonomies provided by Data 360.
### Required Editions
| User permission needed | |
| --- | --- |
| To modify or delete a custom taxonomy: | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. In the left pane, click **Taxonomies**.
3. Search for the taxonomy.
4. Click its dropdown and select **Edit** or **Delete**.
5. Make your changes and click **Save**.
# Edit or Delete a Data Space in Data Cloud
You can change a data space’s name and description, but you can’t modify its prefix. You can delete a data space that you no longer need. However, you can’t delete the default data space.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
Before you delete a data space, remove all its data model objects, data lake objects, calculated insights, identity resolution, segments, and activations. If the data space is associated with a data governance policy, remove it from the policy before deleting.
1. Go to **Data Cloud Setup**.
2. Under Data Management, click **Data Spaces**.
3. Open the data space, and click **Edit** or **Delete**
4. Make your changes, and click **Save**.
# Edit or Delete a Foundation Model
You can edit most of your foundation model settings as long as the model isn’t a source for other models. If it’s used as a source, you must first delete all associated model configurations. You can delete a foundation model if it’s no longer needed.
1. On the AI Models (formerly Einstein Studio) Generative tab, select the foundation model.
2. Click **Edit Settings**.
- Edit the model settings, and then click **Update**.
- To delete the model, click **Delete Model**. You can’t recover a model after it’s deleted.
# Edit or Delete a Retriever Version
Edit retriever versions in AI Models (formerly Einstein Studio) to create versions for testing different configurations and responses within a prompt. You can edit only custom individual retrievers. If no prompt templates depend on a retriever, you can delete it.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, and
delete)
Allow users to manage models in AI Models
OR
Permission set:
1. In AI Models, go to the retriever’s details page.
Alternatively, you can edit an active retriever version from the Retrievers list page. If no version is active, the most recently modified version is selected.
2. Select the version that you want to edit or delete.
3. To edit a retriever version, click **Edit Version**.
4. To change filter or results settings, click the associated Edit icon and make changes.
5. Save your changes.
6. (Optional) Update the retriever name and description. Save the changes as a new version of the retriever.
7. To delete a retriever version, click **Delete Version**.
Alternatively, you can delete a retriever and all its versions from the Retrievers list page if it has no dependencies from prompt templates. You can’t recover a deleted retriever.
# Edit or Delete a Tag in Data 360
You can delete a tag or edit the tag name, API name, and classifications. You can't delete tags that are used in policies. This includes default tags provided by Data Cloud.
### Required Editions
| User permission needed | |
| --- | --- |
| To edit or delete tags: | Data Cloud Architect permission set |
1. Search for the tag in the Data Governance tab in Data Cloud.
2. Click the tag’s dropdown, and select **Delete** or **Edit**.
3. If editing, make your changes and click **Save**.
# Edit Search Index Configurations
If needed, you can edit Data 360 search index configurations to add fields or file extensions for chunking. You can view but not modify other existing settings.
### Required Editions
User Permissions Needed
To edit a search index configuration:
Permission set:
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index** > **Edit**.
3. From the Guided Setup navigation, click **Chunking**.
- To add a file extension to a search index created from an unstructured data model object, click **Add File Extension**.
- To add fields to a search index created from a data model object, click **Manage Fields** and then select one or more fields as needed.
4. From the Guided Setup navigation, click **Review and Build**, and then click **Save**.
# Einstein Engagement Score Filters in Data 360 Segments
Here are some examples of common Einstein Engagement Score use cases.
## Find Most Engaged Individuals Who Made a Previous Purchase
Filter for individuals who made a purchase greater than $500 this year and who are most likely to click an email.

Example
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 500
- AND
- Order Start Date | This Year
AND
- Einstein Email Engagement Score | Count | At Least | 1
- Email Click Likelihood | Is Equal To | Most Likely
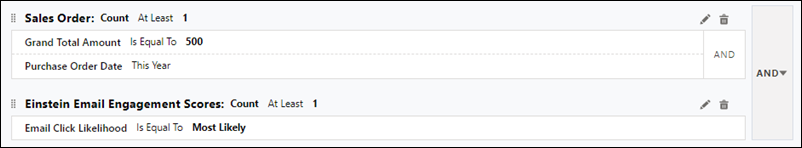
## Find Individuals with High Engagement and Low Conversion for a Specific Brand
Filter for individuals who have a high engagement rate but low conversion rate from brand BU 829302. High engagement means an email click predictive score of 0.2 or more.
Low conversion means a conversion likelihood of least likely and no purchases from the brand.

Example
- Einstein Email Engagement Score | Count | At Least | 1
- Email Click Score | Is Greater Than | 0.2
- AND
- Conversion Likelihood | Is Equal To | Least Likely
- AND
- Internal Organization | Is Equal To | 829302
## Find Highly Engaged Individuals with Large Purchase Sums
Filter for individuals with a high engagement rate who have made at least 5 purchases each over $500. High engagement means a mobile open predictive score of 0.8 or more and conversion likelihood of most likely for BU 20392.

Example
- Einstein Push Engagement Score | Count | At Least | 1
- Direct Open Score | Is Greater Than | 0.8
- AND
- Conversion Likelihood | Is Equal To | Most Likely
- AND Internal Organization | Is Equal To | 20392
AND
- Sales Order | Count | At Least | 5
- Grand Total Amount | Is Greater Than | 500
[1](#fntarg_1)
[1](#fnsrc_1) Rights of ALBERT EINSTEIN are used with permission of The Hebrew University of Jerusalem. Represented exclusively by Greenlight.
# Einstein Segments in Data 360
Create segments with Einstein Segment Creation generative AI. Enter a high-level description of your segment and receive a suggested segment and all its attributes. Easily draft another segment by changing the description, or edit the segment’s attributes to make adjustments. After you’re satisfied with your segment, publish and activate it.
## Einstein Segments and Your Data
When you generate a segment, Salesforce doesn’t send Personally Identifiable Information (PII) data, including data from the Unified Individual DMO, to third-party sources. Your customer data isn’t shared with others or used to enrich other customer data. For more information, see [Data Masking](https://help.salesforce.com/s/articleView?id=ai.generative_ai_mask_data.htm&type=5&language=en_US).
Salesforce sends sample data for each field so that generative AI can understand the context and create a grounded model. For example, if a Hobby field exists in your data, the grounded model can recognize that hiking, canoeing, and running are related to hobbies. Generative AI can then suggest meaningful segment definitions that relate to your actual audience data when you enter a description, such as customers who enjoy outdoor sports.
## Trust and Einstein Segments
Unethical or biased language isn’t allowed when creating an Einstein segment. If a description includes unethical or biased language, an error message appears telling you to change your description.
To help reduce the possibility of creating bias in segments created by generative AI, all demographic attributes that can create bias are deselected by default. If you encounter something unethical, contact your Salesforce representative.
- **[Set Up Your Data for Einstein Segments in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_setup.htm&release=264.0.0&type=5)**
To get proper results when creating an Einstein segment, make sure that your data is prepared correctly.
- **[Enable Einstein Segments in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_enable.htm&release=264.0.0&type=5)**
Before you can create Einstein segments, enable generative AI and then turn on Einstein segments.
- **[Create an Einstein Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_create.htm&release=264.0.0&type=5)**
Describe your segment to get suggested related attributes that are based on the data found in your org. To avoid bias and inaccuracies, all demographic attributes are removed. Attributes that produce fewer than 10 results for the segment population are also removed to improve the segment's accuracy.
- **[How to Write a Good Prompt for Einstein Segments in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_prompts.htm&release=264.0.0&type=5)**
When creating a segment, use certain formats and language to get the best results possible. Provide descriptive names for data model objects (DMOs) and attributes to ensure that generative AI can understand them. OpenAI was trained on data that leans toward the United States, which influences Einstein’s responses. If you require a specific country, enter the name of the country in the prompt.
- **[Improve Your Einstein Segment Creation Results in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segment_einstein_improve.htm&release=264.0.0&type=5)**
What happens if you receive unclear results, or if the results aren’t necessarily what you’re hoping for? Use these suggestions to gain more accurate results.
#### See Also
- [_Salesforce Help_: Einstein Generative AI and Trust](https://help.salesforce.com/s/articleView?id=ai.generative_ai_trust_overview.htm&type=5&language=en_US)
- [_Salesforce Help_: Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_about.htm&type=5&language=en_US)
# Email a Contract Renewal Notification (B2B) Use Case
Cumulus Bank wants to email decision-makers at a specific business about an expiring contract. Before sending the email, the bank ensures that it has consent for each email address to receive emails about contract renewals.
## Identify Requirements
- **Goals**
- When a contract is within 4 months of expiring, an email is sent to all decision-makers at the business to remind them about the upcoming renewal.
- **Personalization components**
- The email includes the customer’s first name, last name, and contract expiration date.
- **Audience and data sources**
- Account contacts who are decision-makers and have a contract expiring within 4 months.
- DMOs involved: Account, Account Contact, Contact Point Email, Contact Point Subscription Consent, Communications Subscription Consent
- **[Create the Audience Segment in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc1_contract_create_segment.htm&release=264.0.0&type=5)**
The audience segment consists of the decision-makers who have a contract expiring within 4 months. Create a reminder email about the upcoming contract renewal.
- **[Filter the Segment and Publish to Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc1_contract_filter_segment.htm&release=264.0.0&type=5)**
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by job title and whether the person has opted in to receive emails.
# Email a New Service Promo Notification (B2C) Use Case
Cumulus Bank wants to send an email message to customers about new services. They want to ensure that only customers who have provided consent and opted in to receive advertisements are the ones receiving the emails.
## Identify Requirements
- **Goals**
- Send email advertisements about new services only when a customer opts in and provides consent.
- The campaign is ongoing, regularly adding customers who meet the criteria.
- **Personalization components**
- The email includes the customer’s first name, last name, and their current services.
- **Audience and data sources**
- Active customers who have opened more than 3 emails in the last 3 months and have provided consent to receive advertisements.
- DMOs involved: Unified Individual, Email Engagement, Contact Point Email, Contact Point Subscription Consent
- **[Create the Audience Segment in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc2_service_create_segment.htm&release=264.0.0&type=5)**
The audience segment consists of customers who have a high engagement rate with email campaigns. To create an automated email about new services, follow these steps in Data Cloud to create an audience segment.
- **[Filter the Segment and Publish to Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc2_service_filter_segment.htm&release=264.0.0&type=5)**
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by consent status and whether the person has opted in to receive emails.
# Email Engagement Filters
Here are some examples of common email engagement use cases.
## Subject Line Engagement
This filter finds individuals who opened an email with the subject line of Holiday Special.

Example
- Email Engagement | Count | At Least | 1
- Engagement Channel Action | Is Equal To | Open
- AND
- Subject Line Text | Is Equal To | Holiday Special
## Opens by Subject Line and Purchases
This filter finds individuals who made a purchase and opened an email with the subject line of Holiday Flash Sale.

Example
- Email Engagement | Count | At Least | 1
- Subject Line Text | Is Equal To | Holiday Flash Sale
- AND
- Engagement Channel Action | Is Equal To | Open
AND
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 0
## Opens by Subject Line and Total Purchase by Month
This filter looks for seasonal spenders who opened an email with the subject line of Holiday Flash Sale and made purchases greater than $1,000 in December.

Example
- Email Engagement | Count | At Least | 1
- Subject Line Text | Is Equal To | Holiday Flash Sale
- AND
- Engagement Channel Action | Is Equal To | Open
AND
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 1000
- AND
- Order Start Date | Month Of Year | December
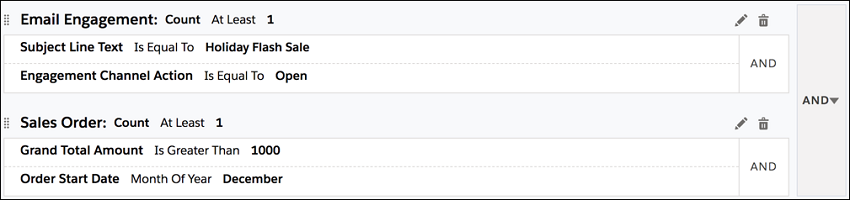
## Subject Line Engagement by Multiple Locations in the Last 7 Days
This filter finds individuals who had some engagement based in New York or San Francisco and opened an email with the subject line of Pop Up Store Surprise in the last 7 days.

Example
- Email Engagement | Count | At Least | 1
- Subject Line Text | Is Equal To | Pop Up Store Surprise
- AND
- Engagement Channel Action | Is Equal To | Open
- AND
- Engagement Date Time | Last Number Of Days | 6
- AND
- City Name | Is In | New York, San Francisco
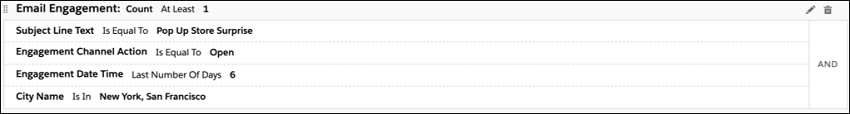

Alternative Example
- Email Engagement | Count | At Least | 1
- Subject Line Text | Is Equal To | Pop Up Store Surprise
- AND
- Engagement Channel Action | Is Equal To | Open
- AND
- Engagement Date Time | Last Number Of Days | 6
- AND
- City Name | Is In | New York
OR
- Email Engagement | Count | At Least | 1
- Subject Line Text | Is Equal To | Pop Up Store Surprise
- AND
- Engagement Channel Action | Is Equal To | Open
- AND
- Engagement Date Time | Last Number Of Days | 6
- AND
- City Name | Is In | San Francisco
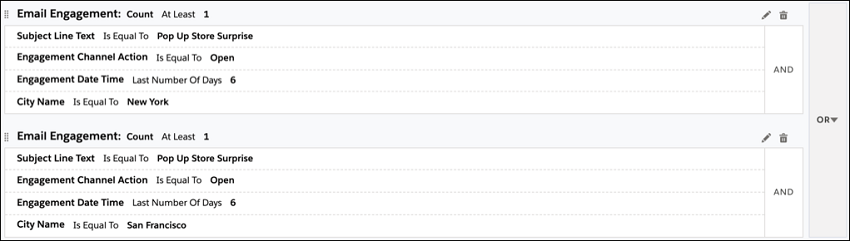
## Not Opened by Location in the Last 3 Months
This filter finds individuals who have not opened email in the last 3 months, and with an IP address identified as New York City.

Example
- Email Engagement | Count | Exactly | 0
- Engagement Channel Action | Is Not Equal To | Open
AND
- City Name | Is Equal To | New York
- AND
- Engagement Date Time | Last Number Of Months | 2
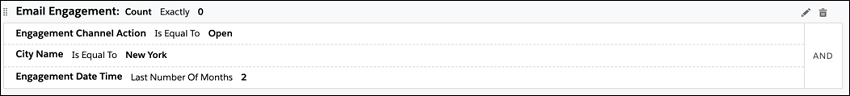
## Subject Line Engagement by Country
This filter finds individuals who engaged with the subject line of Early Black Friday Sale, have an engagement channel action of Open, and Country as the United States.

Example
- Email Engagement | Count | At Least | 1
- Engagement Channel Action | Is Equal To | Open
- AND
- Subject Line Text | Is Equal To | Early Black Friday Sale
- AND
- Country | Is Equal To | United States
## No Email Engagement
This filter looks for customers who have no email engagement.

Example
- Email Engagement | Count | Exactly | 0
- Subject Line Text | Is Equal To | Holiday Sales
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Enable Data 360 Data Q&A Agent
Turn on the Data 360 Data Q&A Agent and Metadata Knowledge Graph and Semantic Enrichments features to start asking natural language questions about your data.
### Required Editions
Before you enable the Data 360 Data Q&A Agent:
- Turn on Einstein in the Generative AI Einstein Setup.
- Enable Agentforce in Agent Studio.
- Understand that enabling this feature in production environments affects all users with appropriate permissions. Consider testing in a sandbox environment first if your org has Data 360 sandbox capabilities.
The Data 360 Data Q&A Agent has two required features that work together:
- **Data 360 Data Q&A Agent:** Automatically provisions an agent in the Legacy Agentforce Builder that answers natural language questions about your Data 360 data.
- **Metadata Knowledge Graph and Semantic Enrichments:** Indexes your data's schema, relationships, sample values, and descriptions when metadata changes are detected every 2 hours. This index helps the agent understand your data structure.

Important Both features consume Flex Credits when invoked. Monitor your credit consumption in Setup under Flex Credits Usage. Credit consumption varies based on query complexity, data volume, and indexing frequency.
## Enable the Feature
You must have the Manage Data 360 Features permission to enable this feature.
1. From Setup, in the Quick Find box, enter Feature Manager, and select **Feature Manager**.
2. Find **Metadata Knowledge Graph and Semantic Enrichments** and click **Enable**.
3. Find **Data 360 Data Q&A Agent** and click **Enable**.
Verify that both **Data 360 Data Q&A Agent** and **Metadata Knowledge Graph and Semantic Enrichments** appear as enabled in the feature list. Initial indexing begins automatically after enablement. Subsequent re-indexing occurs every 2 hours only if the schema has changed since the last indexing.
## Next Steps
- Open the Data 360 Data Q&A Agent chat panel to start asking questions.
- Add semantic enrichments to help the agent better understand your data. See [Guide Data Q&A with Semantic Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_semantic_enrichments_overview.htm&release=264.0.0&type=5 "Add semantic statements to help the Data 360 Data Q&A Agent better understand your data's business context, domain-specific terminology, and relationships.").
- Review agent configuration in Legacy Agentforce Builder to customize behavior.
#### See Also
- [_Agentforce Workshop_: Exercise 1: Get Started with Agentforce](https://developer.salesforce.com/workshops/agentforce-workshop/employee-agents/1-get-started)
# Enable Data 360 Features
You can enable Data 360 features using the Feature Manager. This screen is visible only when there are one or more features to enable or disable.
### Required Editions
User Permissions Needed To access Data Cloud Setup System Administrator
1. Go to **Data Cloud Setup**.
2. Under Feature Management, click **Feature Manager**.
3. To enable a feature, click **Enable** next to the Data Cloud feature name.
4. Agree to the terms and service, and then confirm that you want to enable it.

Note Certain beta features can’t be disabled.
- **[Grant or Remove Access to Data Explorer or Profile Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_data_explorer_permissions.htm&release=264.0.0&type=5)**
Data Explorer and Profile Explorer are enabled by default for Data 360 admins and data aware specialists. To make them available to users in other roles, or to remove access from roles that have it by default, create custom permission sets.
# Enable Data 360 in Tableau
Using the Data 360 connector, you can discover and analyze unified profiles and other customer insights.
Accelerated Queries for Tableau is a Data 360 capability that supports interactive analytics with fast data query processing. It simplifies the connect-to-data experience for faster data exploration. The engine speeds up query time using a live connection and extracts when querying Data 360 data from Tableau.

Note With the Salesforce Data Cloud connector, you can connect to Tableau Cloud, Tableau Prep, and Tableau Desktop (version 2023.2 or later) and use Accelerated Queries for Tableau.
# Enable Einstein Segments in Data 360
Before you can create Einstein segments, enable generative AI and then turn on Einstein segments.
### Required Editions
User Permissions
Needed
To enable Einstein segments:
Permission set:
For more information about how to enable generative AI, see [Enable Generative AI.](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&type=5&language=en_US)
To create Einstein segments, you must enable Einstein Segment Creation in your org. This is done in the Feature Manager.
1. In Data Cloud Setup, select **Feature Manager**.
2. Enable Einstein Segment Creation.
3. To confirm, click **Enable** again.
You can now start creating Einstein segments.
Einstein Segment Creation results are optimized with Einstein Data Prism. To get the best results with Einstein Data Prism, use Metadata Studio to review the generated descriptions for objects and fields, enter missing information, and remove obsolete objects from the data source. See [Metadata Studio](https://help.salesforce.com/s/articleView?id=ai.generative_ai_prism_metadata_studio.htm&type=5&language=en_US).
# Enable Notebook AI For Data Spaces and Users
Grant Data 360 Notebook AI access to data in data spaces and give enterprise users access to Notebook AI with custom permission sets. In a multi-org architecture, enable Notebook AI in both the home org and companion org.
### Required Editions
User Permissions Needed
To access Setup
System admin profile
In **Setup**, select and turn on Einstein Setup. For more information, see [Set Up Einstein Generative AI.](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&type=5&language=en_US)
In **Setup**, select **Agentforce Agents**, and turn on Agentforce. For more information, see [Enable Agentforce.](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&type=5&language=en_US)
## Grant Notebook AI Data Space Access
Give Notebook AI access to data by selecting data spaces. To use Notebook AI, users must also have access to those data spaces.
1. From Data Cloud **Setup**, enable Notebook AI in **Feature Manager.**
Notebook AI gets access to the default data space.
2. In Feature Settings, select Notebook AI and select the data spaces where you want to give Notebook AI access to data.
If you don't see the custom data spaces, update Data Cloud Data Space Management. For more information see, [Troubleshoot Notebook AI Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_troubleshooting.htm&type=5&language=en_US).
Next, go to **Manage Users** to give enterprise users access to Notebook AI.
## Enable Notebook AI User Access
To give users access to Notebook AI, create and assign them to a custom permission set. You can also clone an existing Data Cloud permission set and add the necessary permissions.
1. From **Setup**, in the **Quick Find** box, enter Permission Sets, and then select **Permission Sets**.
2. In the Permission Sets page, create a permission set and add the necessary permissions to ensure that user gets access only to Notebook AI.
Select Data Cloud as the license for the permission set. You can also clone the Data Cloud permission set and modify the permissions.
3. Update permission set information and click **Save**.
4. Select the new permission set and ensure that only the following permissions are enabled.
System Permissions
| Permission Name | Access |
| --- | --- |
| Grant users permission to sfDrive | Enabled |
| Create, edit, and delete knowledge spaces | Enabled |
Object Settings
Permission Name
Access
Data Knowledge Dataspace Scopes
Read, Create, Edit, Delete, View All Records, Modify All Records
Data Knowledge Libraries
Read, Create, Edit, Delete
Data Knowledge Library Source Relationships
Read, Create, Edit, Delete, View All Records, Modify All Records
Data Knowledge Sources
Read, Create, Edit, Delete, View All Records, Modify All Records
Data Knowledge Space Definitions
Read, Create, Edit, Delete
Data Knowledge Space Library Relationships
Read, Create, Edit, Delete, View All Records, Modify All Records
Data Model Domain Capability Usage
Read, View All Records
Data Model Fields
Read, View All Records
Data Model Objects
Read, View All Records
Data Model Taxonomies
Read, View All Records
Data Object Categories
Read, View All Records
Data Semantic Search Definitions
Read, View All Records
Data Space Definitions
Read
Data Spaces
Read
5. To manage user access to data spaces, assign Dataspaces to the permission set from Data Cloud Data Space Management.
6. In Agent Access, add Notebook AI Agent to the permission set.
7. Assign users to the Notebook AI custom permission set from **Manage Assignments**. For more information see, [Manage Permission Set Assignments.](https://help.salesforce.com/s/articleView?id=platform.perm_sets_manage_assignments.htm&type=5&language=en_US)
8. Optionally, to ensure that the Notebook AI tab is visible in your org, from **Setup**, navigate to the user's profile and Tab Settings, and enable Notebook AI.
# Enable Notebook AI Web Access
Give enterprise users access to Data 360 Notebook AI web application. Authorize the Notebook AI web application to connect to your Salesforce org and allow users to log in to the application from the web.
### Required Editions
User Permissions Needed
To enable access to Notebook AI Web application for users
System admin profile
Enable users access to Notebook AI in Data 360. For more information see, [Enable Notebook AI User Access](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_custom_user_perm.htm&type=5&language=en_US)
## Set User Profile Permissions
1. From **Setup**, in the **Quick Find** box, enter Profiles.
2. Select the profile your users are assigned to.
3. Under Administrative Permissions, select API Enabled.
## Enable Notebook AI to Securely Connect with your Salesforce Org
1. From **Setup**, in the **Quick Find** box, enter CORS.
2. Select CORS.
This page lists URL patterns allowed for cross-origin resource sharing (CORS).
3. Click **New** to add a new URL pattern in the Allowed Origins List.
4. Enter https://notebookai.salesforce.com in the **Origin URL Pattern** box and save your settings.
5. Approve the Notebook AI connected app.
1. Go to the applications's login page, [notebookai.salesforce.com.](https://notebookai.salesforce.com).
2. Log in using your system administrator credentials.
3. To give access to the application, Click **Allow** .
This initial login makes the application visible in your org's setup menu so you can install it.
## Install the Notebook AI Application in Your Salesforce Org
1. From **Setup**, in the **Quick Find** box, enter Connected Apps Oauth Usage and select it.
2. Find NotebookAIConnectedApp in the list and install it.
3. Review policies and continue to install the application.
# Enable Object and Field Permissions for CRM Connections
You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.
### Required Editions
User Permissions Needed
To update object settings
System admin profile OR
Data Cloud Architect permission set
Watch this video or follow the steps to enable permissions.
1. Log in to the Salesforce org containing the objects and fields that you want to ingest into Data 360.
2. From Setup, in the Quick Find box, enter Permission, and then select **Permission Sets**.
3. Select the **Data Cloud Salesforce Connector** permission set.
The permission set is available after you connect your CRM org to Data 360.
4. From Apps, select **Object Settings**.
5. Select the object that you want to ingest into Data 360.
6. Click **Edit** to change the permissions.
7. Enable permissions.
- For objects, enable: Read, View All Records.
- Optionally, you can enable permissions on specific fields.
By default, all fields associated with the objects that the user has object permissions for in the Data Cloud Salesforce Connector permission set have read access.
8. 
9. Click **Save**.
Repeat these steps for all objects that you want to ingest into Data 360.
# Enable Permissions for CRM Streaming
For CRM streaming, set these system and user permissions.
### Required Editions
User Permissions Needed
To ingest objects and fields:
Permission set:
The Streaming processing mode can change to batch for certain scenarios. See [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.").
1. From Setup, in the Quick Find box, enter Permission, and then select **Permission Sets**.
2. Select the **Data Cloud Salesforce Connector** permission set.
3. Click **System Permissions**.
4. Enable **View Setup and Configuration**, **Customize Application** and **Modify Metadata Through Metadata API Functions**.
5. Enable the **View All Users** permission located under **Users** for user data streams
6. Save your changes.
# Enable Permissions to Ingest Salesforce Classic Encrypted Salesforce CRM Objects and Fields
Values in Salesforce Classic custom encrypted fields ingested from connected Salesforce CRM org are masked in Data 360 by default. You can opt to ingest them as unmasked values instead.
### Required Editions
User Permissions
Needed
To ingest objects and fields:
Data Cloud Architect permission set
AND
View All Records and Read
permission on the object being ingested
To ingest Classic encrypted fields with unmasked values:
Data Cloud Salesforce Connector permission set in the connected
org
AND
View Encrypted Data permission

Warning If you choose to ingest Classic encrypted fields and wish to unmask values, remember values are stored unmasked everywhere in Data 360.
To ingest Classic encrypted fields with unmasked values, update your permissions in each Salesforce org from which you will ingest encrypted fields.
1. From Setup in the Quick Find box, enter Permission, and select **Permission Sets**.
2. Select the **Data Cloud Salesforce Connector** permission set.
The permission set is available after you connect your CRM org to Data 360. For deployed orgs that haven’t been updated recently, the Data Cloud Salesforce Connector permission set is listed as Salesforce CDP Salesforce Connector Integration, Customer Data Platform Salesforce Connector Integration, or Customer 360 Audiences Salesforce Connector Integration.
3. Select **System Permissions**.
4. Click **Edit**, then add **View Encypted Data**.
5. Click **Save**.
6. Assign the **Data Cloud Salesforce Connector** permission set to the users who need it.
Repeat these steps for any Salesforce CRM orgs where you want to ingest Classic encrypted fields as unmasked values.

Tip Each Salesforce CRM org connected to Data 360 can have its own permission settings for Classic encrypted fields.
Changes made toData Cloud Salesforce Connector permission set are honored at the next full refresh of the data stream. Full refresh happens:
- The first time the data stream is deployed.
- When a data stream is edited, such as when a source or formula field is added.
- If you contact Salesforce Customer Support and log a case.
#### See Also
- [_Salesforce Help_: Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.")
- [_Salesforce Help_: Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.")
- [_Salesforce Help_: Classic Encryption for Custom Fields](https://help.salesforce.com/s/articleView?id=platform.fields_about_encrypted_fields.htm&type=5&language=en_US)
# End a Clean Room Collaboration
When you end a clean room collaboration, you can’t restart it. If you have permissions to run queries and receive results in the collaboration, you can still access query results and query logs from past query runs.
### Required Editions
Available in: Enterprise Edition (home org)
User Permissions Needed
To end a clean room collaboration:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, go to the Clean Rooms tab.
2. Under Collaboration, open the collaboration record that you want to end.
3. Click **End Collaboration**.
4. To confirm, click **End Collaboration**. The collaboration becomes inactive.
# Engagement Data Model
The Customer 360 Data Model engagement subject defines interactions with a party. Example interactions could be speaking to a customer over the phone or receiving a customer email.
The engagement data model includes the individual, contact point, device, and email engagement data model objects.
These DMOs are represented in the engagement subject area.
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Device | A Data 360 DMO for a specific electronic unit that you want to track signals from, for example, a refrigerator, watch, or car. | [Device DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_device_dmo.htm) |
| Device Application Engagement | A Data 360 DMO for data about device engagement, for example mobile app usage. | [Device Application Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_device_application_engagement_dmo.htm) |
| Device Application Template | A Data 360 DMO for a reusable standard format for messages for applications on devices. | [Device Application Template DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_device_application_template_dmo.htm) |
| Email Engagement | A Data 360 DMO for data captured from various data sources about an engagement. | [Email Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_email_engagement_dmo.htm) |
| Email Template | A Data 360 DMO for the standard form of an email message that can be personalized and customized with data specific to an individual recipient, market segment, or other customization factor. | [Email Template DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_email_template_dmo.htm) |
| Engagement Topic | A Data 360 DMO for engagement topics such as multiple campaigns or promotions. | [Engagement Topic DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_engagement_topic_dmo.htm) |
| Product Browse Engagement | A Data 360 DMO for data captured from a user action, such as searching for products or viewing a list of products. | [Product Browse Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_browse_engagement_dmo.htm) |
| Product Order Engagement | A Data 360 DMO for a user’s online shopping order data. | [Product Order Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_order_engagement_dmo.htm) |
| Shopping Cart Engagement | A Data 360 DMO for data captured from user actions, such as adding and removing items from a shopping cart. | [Shopping Cart Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_shopping_cart_engagement_dmo.htm) |
| SMS Engagement | A Data 360 DMO for data captured from various data sources about a message engagement. | |
| SMS Template | A Data 360 DMO for a reusable, standard format for text (SMS) messages. | [SMS Template DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_sms_template_dmo.htm) |
| Web Search Engagement | A Data 360 DMO for web search engagement data. | [Web Search Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_web_search_engagement_dmo.htm) |
| Website Engagement | A Data 360 DMO for any data associated with website engagement, like views or clicks. | [Website Engagement DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_website_engagement_dmo.htm) |
#### See Also
- [_Salesforce Help_: Marketing Cloud Engagement Data Bundle Information](https://help.salesforce.com/s/articleView?id=data.c360_a_mc_bundle_data_categories.htm&release=264.0.0&type=5 "When ingesting data from Marketing Cloud Engagement, Data 360 creates data streams and data lake objects (DLOs) for each starter bundle, along with schema and mappings to data model objects (DMOs).")
# Enhance Data with Insights
With insight features, you can define and calculate multidimensional metrics from your entire digital state stored in Data 360.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
Your metrics can include customer lifetime value (LTV), most viewed categories, and customer satisfaction score (CSAT), or any other metrics.
After creating your insights, put them into effect for your streaming insights with data actions.
## Calculated Insights
Use a calculated insight to define and calculate multidimensional metrics on your entire digital state in Data 360. You can create metrics at the profile, segment, and population levels. For example, you can evaluate performance at the channel level or use product metrics to understand purchasing and browsing behavior.
Marketers can use metrics, dimensions, and filters to define segment criteria and personalization attributes for activation. Data analysts can also visualize the insights in CRM Analytics to understand data patterns.
Calculated insights can help you understand each stage of the customer journey by analyzing various metrics. Here are some benefits.
- Build metrics on large-scale data in Data 360 by using analytical functions for in-depth analysis. For example, rank customers by spend or engagement scores.
- Calculate custom metrics with logic, mathematics, statistics, time series functions, and complex workflows.
- Automatically recompute calculated insights when the base data changes. The calculated insight automatically adds the incremental data changes.
- Access the Visual Insights Builder for point and click insight creation. The SQL-based insights authoring experience provides data engineers with appropriate tools for their role and experience.
- Turn insights into actions as they’re integrated into segmentation and activation.
## Streaming Insights
Get insights more quickly by creating metrics on streaming data. Streaming insights are aggregation queries based on real-time engagement data for a rolling time window. Insights process the data from streaming data sources, such as Web SDK and Mobile SDK. Use a streaming insight to build time series aggregation, in near real time, that you can use to drive orchestration or data actions in Data 360.
Note: Segment and activation don't support streaming insights.
You can use streaming insights and data actions to support different use cases. Review these examples to discover ways to apply the functionality.
- Service and support: A customer visited a troubleshooting page before calling support. Having this information helps support skip unnecessary troubleshooting steps that the customer has attempted.
- Intelligent routing: When used with Service Cloud, send a notification to PagerDuty if a customer escalates a case.
- Customer feedback: Intercept near real time customer reviews and drive satisfaction improvement actions, such as creating a case.
- Account engagement: Intercept inactive accounts for customer engagement signals in near real time to drive re-engagement.
- Points balances: Update the point balance in Salesforce CRM based on order transaction and social share.
- Log scanning: Filter streaming device log data based on error codes to find the most frequent errors and determine if the device needs servicing.
- Lead scoring: Perform lead scoring based on near real-time user actions, such as a customer requesting a product feature in a forum.
## Real-Time Insights
Use real-time insights to build more complex personalization logic for your website. With real-time insights, you can track cumulative website activity to see if the user’s activity meets defined thresholds.
For example, use a customer’s active browsing behavior to:
- Calculate which products the customer is most interested in and deliver personalized recommendations.
- Calculate the value of items in a customer’s cart to see if they qualify for a discount.
- Get a count of the number of times the customer has clicked a product to track product category preferences.
You can create real-time insights with a real-time data graph and related data model objects (DMOs). Data 360 calculates and stores insights in the data graph. You can use real-time insights with segmentation and activation as part of a real-time data graph.
## How Are Calculated, Streaming, and Real-Time Insights Different?
| | Calculated Insights | Streaming Insights | Real-Time Insights |
| --- | --- | --- | --- |
| How is data processed? | High volume data processing and metrics generation. | Continuous stream processing as Data 360 receives data. Time windows as little as 1 minute. | In real-time, with results in milliseconds. |
| How is data collected? | Collected in batches as sets of records and processed as unit. | Work on events as they’re updated via streaming data from Web SDK and Mobile SDK. | Data 360 processes insights for every event that updates in the real-time data graph. |
| How can you use this data in Data 360? | Perform complex calculations usually needing large historic data. | Handle micro batches of a few records. | Calculates an insight from a single record to drive personalization logic using aggregate metrics. |
| Example Use Case | Customer rank by spending. | Click stream analysis, ecommerce, transactions. | Personalized ecommerce experience with recommendations based on which products the user is viewing. |
- **[Billing Considerations for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_insights.htm&release=264.0.0&type=5)**
Insights uses Data 360 to define and calculate multi-dimensional metrics across unified customer data to power real-time personalization and analytics. Use of insights impacts the consumption of credits used for billing in these usage types.
- **[Authoring Methods for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_authoring_methods_for_insights.htm&release=264.0.0&type=5)**
Design and implement insights using visual building tools or direct SQL syntax to meet specific analytical requirements. Authors can transform raw data by joining, aggregating, or filtering datasets through node-based workflows and streaming functions. With these methods you can clone existing logic, save drafts, and apply complex SQL operators to generate real-time or calculated metrics. You gain the flexibility to build sophisticated data models from scratch or use pre-configured packages for faster deployment.
- **[Authoring Considerations for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_insights_considerations.htm&release=264.0.0&type=5)**
With strategic planning your Data 360 insights deliver accurate, high-performance data visualizations for your business users. You can optimize your data processing with complex joins, relative time-windows, and advanced metric layering.
- **[Managing Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_managing_insights.htm&release=264.0.0&type=5)**
Manage calculated insights to drive data-informed decisions with precision. Configure history tracking to monitor long-term metric trends and maintain data integrity. You can schedule automated processing, manually trigger updates, and validate results to ensure your team accesses accurate analytics. Efficiently organize your insight using the list view to edit or delete records as your business needs evolve.
# Enhancing Data Analysis with Vector Search in Tableau
Find and analyze data based on meanings, not just keywords, by using vector search in a Tableau query. Vector search broadens the scope of data exploration as well as enhances the accuracy and relevance of the insights by identifying semantic similarities rather than relying solely on exact keyword matches.
For example, a business analyst creates a Voice of the Customer analysis dashboard. The analyst sourced the data from a file in an Amazon S3 bucket, created a Data 360 data stream from that content, and mapped the custom fields to a custom DMO they named `dc_voc`. The analyst then created a search index configuration from the `dc_voc` object and chunked and vectorized the Description field from the object. The analyst can now use a search filter in Tableau specifically tailored for Voice of the Customer descriptions.
The Tableau dashboard displays both structured and unstructured data analytics. The left side uses a category filter, and the right side uses semantic search to enhance data exploration.
For instance, when you enter the term “real time” into the semantic search on the right side, the records show entries that include related terms, such as real-time activation, near-time data ingestion, and real-time data stream.
The matching score ranks results based on the similarity of their descriptions to the search term. This scoring system highlights the advantage of semantic search, because it captures varied expressions of similar concepts, providing richer insights than a simple keyword search.
To implement this functionality, the analyst created a custom SQL query in Tableau that uses the `vector_search( )` function. (Note that the query contains non-standard or custom objects that are examples and may not correspond to objects in customer orgs.)
```
SELECT distinct "dc_voc__dlm"."Accounts_Impacted__c" AS "# Accounts Impacted",
"dc_voc__dlm"."Opportunities_Impacted__c" AS "# Opportunities Impacted",
"dc_voc__dlm"."Created_By_Role_Name__c" AS "Created By: Role: Name",
"dc_voc__dlm"."Created_Date__c" AS "Created Date",
"dc_voc__dlm"."Description__c" AS "Description",
"dc_voc__dlm"."Input_Name__c" AS "Input Name",
"dc_voc__dlm"."Product_Area__c" AS "Product Area",
"dc_voc__dlm"."Total_ACV_Impacted_converted__c" AS "Total ACV Impacted (converted)",
"dc_voc__dlm"."Total_AOV_Impacted__c" AS "Total AOV Impacted",
"Chunk__c", "score__c" FROM vector_search(table("dc_voc_str_id_vector__dlm"), , '', 500) vs
INNER JOIN "dc_voc_str_id_chunk__dlm" USING ("RecordId__c")
INNER JOIN "dc_voc__dlm" USING("Str_id__c")
ORDER BY "score__c" DESC
LIMIT
```
Notice two specific parameters:
- `Query String` for entering search terms.
- `Limit VOC Matches` controls the number of VOC records displayed.
This integration of vector search within Tableau not only broadens the scope of data exploration but also enhances the accuracy and relevance of the insights derived from customer feedback by identifying semantic similarities rather than relying solely on exact keyword matches.
#### See Also
- [_Salesforce Help_: Query Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_query.htm&release=264.0.0&type=5 "Use the Query API to run vector searches in Data 360. Use these examples as starting points.")
- [_Salesforce Help_: Create Vector Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
- [_Salesforce Help_: Data 360 for Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_for_tableau.htm&release=264.0.0&type=5 "After you've combined, unified, and harmonized your data in Data 360, it's now ready for you to analyze. Use Tableau to find useful and actionable insights that can drive business success and create a personalized experience for your customers. Data 360, Tableau, and Salesforce 360 apps work together to consolidate your data and create a single customer record. Unlock hidden insights, and make decisions based on all your customer data.")
# Enhancing Personalization User Mappings for Identity Resolution
To successfully use your Marketing Cloud Personalization data in segmentation and activations, map the user fields for Identity Resolution.
The users data stream is mapped to Contact Point Email and Party Identification Customer 360 Data Model objects in the data model. With these mappings, you can match Marketing Cloud Personalization user profiles using email or party identification match rules.
| Data Lake Objects (DLOs) | Customer 360 Data Model Objects |
| --- | --- |
| Base Events | WebsiteEngagement |
| Cart | ShoppingCartEngagement |
| Cart Events | |
| CartItem | ShoppingCartProductEngagement |
| Cart Events Items | ShoppingCartEngagement |
| Catalog | ProductBrowseEngagement |
| Catalog Events | ProductBrowseEngagement |
| Consent | PrivacyConsentLog |
| Users | Individual, EmailContactPoint, PartyIdentification |
| Order | ProductOrderEngagement |
| Order Events | ProductOrderEngagement |
| OrderItems | SalesOrderProductEngagement |
| Order Line Items | |
#### See Also
- [_Salesforce Help_: Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules.htm&release=264.0.0&type=5 "Match rules tell Data 360 which profiles to unify during the identity resolution process. Each match rule contains one or more criteria. Profiles are matched when all criteria within a match rule are satisfied.")
# Enrich Data Actions in Data 360 with Data Graphs
You can enrich a data action in Data 360 with related data graph attributes by including the data graph as a related object.
For example, enrich a data action with related data graph attributes such as the service status, customer ID, customer name, and email address data graph attributes. Then, use the enriched data action to send emails to your customers to remind them of their upcoming vehicle service appointments.
When a change event is triggered to a data action target, such as Marketing Cloud Engagement, Webhook, or Salesforce Platform Event, the resulting JSON structure contains the complete payload.
- **[Configure a Data Extension to Store a Data Action Payload](https://help.salesforce.com/s/articleView?id=data.c360_a_data_extension_data_action_payload.htm&release=264.0.0&type=5)**
If you’re using a Marketing Cloud Engagement data action target to enrich a data action, configure a data extension to store the data action payload.
#### See Also
- [_Salesforce Help_: Create a Data Action in Data 360](https://help.salesforce.com/s/articleView?language=en_US&id=sf.c360_a_create_a_data_action_in_customer_data_platform.htm)
# Enrich Your Org with 360 Data and Insights
Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.
### Required Editions
You can add information from Data 360 to your Salesforce CRM record pages using enrichments. There are three types of enrichments.
- Related Lists—Related lists show information for DMO objects. DMO objects have a 1-to-many relationship to a Data 360 Individual or Unified Individual object. For example, a contact can have many email engagements. With a related list, you can see all of the email engagements across your enterprise for your contact.
- Direct-DMO Related Lists—Direct-DMO related lists show information from any DMO that's connected to the Salesforce object through a direct relationship. The direct relationship doesn't require identity resolution to be completed for the DMO. For example, a Vehicle object in Automotive Cloud can have a related list of Vehicle Telematics Event DMO records from Data 360.
- Copy Fields—Copy Fields show field data copied from objects with a 1-to-1 relationship to a Data 360 Individual, Unified Individual, Data 360 Account, or Unified Account DMO. CIO objects must have a single Individual ID as the dimension or be a multi-dimensional aggregatable CIO.
Watch this video to learn more about enrichments.

Note This topic includes steps found in multiple products and requires different roles to complete. Look for the Enrichments link at the end of each task to return to this page.
- **[Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5)**
Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.
- **[Billing Considerations for Data 360 Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations_cost.htm&release=264.0.0&type=5)**
Usage of enriched related lists and copy field enrichments impacts credit consumption.
- **[Create a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_enrichment.htm&release=264.0.0&type=5)**
Add information from Data Cloud DMOs to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.
- **[Create a Permission Set for a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_permset.htm&release=264.0.0&type=5)**
Control which users can see a related list enrichment by assigning them to a permission set that has access to the Data Cloud data space.
- **[Delete a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_related_list_enrichment.htm&release=264.0.0&type=5)**
Delete a related list enrichment so that data from Data 360 can’t be queried.
- **[Create a Direct-DMO Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_direct_dmo_enrichment.htm&release=264.0.0&type=5)**
Add information to a Salesforce object related list from a Data Cloud DMO by using a direct relationship between the DMO and the Salesforce object. The direct relationship doesn't require that you complete identity resolution for the DMO. For example, a Vehicle object in Automotive Cloud can have a related list of Vehicle Telematics Event DMO records from Data Cloud.
- **[Delete a Direct-DMO Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_related_list_direct_dmo_enrichment.htm&release=264.0.0&type=5)**
Delete a related list enrichment that's based on a direct relationship between a DMO and a Salesforce object.
- **[Build and Deploy Related List Enrichments from a Data Cloud Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_rl_enrich_deploy_sandbox.htm&release=264.0.0&type=5)**
In a Data Cloud sandbox, build new related list enrichments or modify the existing ones that are automatically generated. After you finish testing your enrichments, package them in a data kit and deploy it to production using change sets.
- **[Create a Copy Field Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_copy_field_enrichment.htm&release=264.0.0&type=5)**
Add information from Data 360 data model objects (DMO) to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.
- **[Delete a Copy Field Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_a_copy_field_enrichment.htm&release=264.0.0&type=5)**
Delete a copy field enrichment to stop updating your data from Data Cloud.
- **[Copy Field Enrichment Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_copy_field_enrichment_matching.htm&release=264.0.0&type=5)**
Copy Field enrichments enhance the records in your org by adding data from other data sources. To avoid returning data that isn’t relevant to the records in your org, the enrichment matches data from your org to data in Data Cloud. How the data is matched determines what data is returned.
- **[Syncing Copy Field Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_syncing_copy_field_enrichments.htm&release=264.0.0&type=5)**
Learn how data is copied and synced between Data 360 and your org for copy field enrichments. Get tips for troubleshooting data syncing and changing enrichments.
- **[Build and Deploy Copy Field Enrichments from a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_copy_field_enrichment_deploy_sandbox.htm&release=264.0.0&type=5)**
Use Data Kits and Change Sets to package and deploy tested copy field enrichments from your Data 360 sandbox to a production environment.
- **[Enrichment Troubleshooting](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_troubleshooting.htm&release=264.0.0&type=5)**
Diagnose issues with enrichments and fix them.
- **[Configure the Data 360 Engagement Timeline Widget](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_engagement_timeline_widget.htm&release=264.0.0&type=5)**
The Data 360 engagement timeline widget shows engagement data in a chronological format on Account, Contact, Lead, and Person Account records. Configure up to 10 types of engagements at once, and your users can sort them newest or oldest first.
#### See Also
- [_Trailhead_: Data 36 Enrichments](https://trailhead.salesforce.com/content/learn/modules/data-cloud-enrichments)
## Step 1: Create a Data Space
You need access to a data space to create enrichments. If you need access to a data space or need one to be created, your Data 360 admin can help. If you have multiple data spaces, it's important to understand which data space includes the information that you want to share for your contact and lead records. For example, if each data space is assigned to a different business unit, you want to select the data space that aligns with your business unit.
1. Data Cloud architect—[Create a Data Space](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_create.htm&release=264.0.0&type=5 "Every Data Cloud org is created with a default data space. Until you create other data spaces, all Data Cloud objects are mapped to the default data space. To segregate your brand, region, or department data and services, create more data spaces.") in Data 360 (10 minutes)
2. Data Cloud architect—Identify the version of data spaces that you’re using, and assign permissions.
You can check that you have the right permissions by opening Setup and looking for Data 360 Related Lists and Data 360 Copy Fields in the menu. If you can see these items, you can create enrichments.
## Step 2: Create a Unified Individual or Unified Account and Calculated Insights
You must have a Unified Individual or Individual DMO to create a related list. You must have a Unified Individual DMO or a calculated insight object to create a copy field enrichment. Any data that you want to use in your org must be associated with a Unified Individual.
1. Data Cloud architect—[Unify Source Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution.htm&release=264.0.0&type=5 "Identity resolution is the processing engine that generates unified profiles from source profile data stored in Data 360. Unified profiles act as a system of reference to unlock our source data. Understand how and when source profiles are processed and what you can do with unified profile output.") (Time to complete depends on the number of records to be processed)
2. Data Cloud architect—Create Calculated Insights (5 minutes per insight)
## Step 3: Configure Integration User Field Permissions for Copy Fields
You must have fields in your org to copy data into. If you don’t want to overwrite existing data or you don’t have an existing field, you must create a field. Before starting this task, make sure that you created all the fields that you want to copy into. A Salesforce admin for your org must set integration permissions for all fields. This task takes about 5 minutes, unless you have a large number of fields that you want to copy.
1. From Setup, in the Quick Find box, enter Permission Sets, and then open **Customer 360 Data Platform Integration**.

Note At least one data action and data action target must exist for this permission set to be visible. If you can't find the permission set, create an enrichment and return to this task.
2. In the Find Settings box, enter the name of the object that you want, and select it from the list. Click **Edit**, and scroll to the Object Permissions section.

Note For more information about the supported objects for copy fields, see [Enrichment Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5 "Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.").
3. Set the object permissions.
- For all objects except products, in the Object Permissions section, click **Edit**, and then select **Read**, **Edit**, **Delete**, **View All Records**, and **Modify All Records**.
- If you added object permissions for orders, also add these permissions for contracts: **Read** and **View All Records**.
- For products, the object permissions don't include **Modify All Records** and **View All Records**. In the Object Permissions section, click **Edit**, and then select **Read**, **Edit**, and **Delete**.
4. For all objects, set the field permissions. In the Field Permissions section, select **Edit Access** for the fields that you want to copy in Field Permissions.
5. Save your changes.
6. For ideas, price books, article types, and products, update the sharing rule settings to public read/write. For more information about sharing rule settings, see [Organization-Wide Sharing Defaults](https://help.salesforce.com/s/articleView?id=platform.security_sharing_owd_about.htm&type=5&language=en_US) in Salesforce Help.
1. In the Quick Find box, enter Sharing Settings, and then click **Sharing Settings**.
2. In Organization-Wide Sharing Defaults, click **Edit**.
3. For your object, select **Public Read/Write** in the Default Internal Access column.
4. Save your changes.
## Step 4: Configure Enrichments
Configure enrichments in Setup and automatically add them to your page layout.
1. Org admin—[Create a Related List Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_related_list_enrichment.htm&release=264.0.0&type=5 "Add information from Data Cloud DMOs to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.") (15 minutes)
2. Org admin—[Create a Copy Field Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_copy_field_enrichment.htm&release=264.0.0&type=5 "Add information from Data 360 data model objects (DMO) to record pages in your org, so you can show information and interactions from multiple systems, orgs, or business units in a related list.") (15 minutes)
If you’re overwriting data in existing fields, create a record triggered workflow to make sure that data entered into the field is ingested before it’s overwritten.
## Step 5: Customize Your Page Layout
To make sure that you successfully added the related list to your Lead or Contact record page, check your page layout
Org admin—[Customize Related Lists](https://help.salesforce.com/s/articleView?id=platform.customizing_related_lists.htm&type=5&language=en_US) (5 minutes)
# Enriched Indexing of Content Chunks
When you create a vector or hybrid search index from unstructured data in Data 360, you can enrich the generated content chunks by extracting metadata from the content. Extracted metadata includes keywords, entities, topic overviews, questions answered by the content, and content summaries.
Chunk enrichment greatly improves retrieval accuracy, especially in cases in which you can’t use prepend fields (for example, in a UDMO path) and in question and answer agent actions. Enriched content chunks provide an alternative to intensive content curation because LLM-generated content helps improve the identification of the right chunks.
To use enriched content chunks, first create a search index and enable enriched content chunks. In AI Models, create a new custom retriever. When prompted for the search index, select a search index that was created using the enrich chunks option.
To get the most value from an enriched index, access it through a retriever. To use the metadata chunks, a retriever applies extra logic, such as reranking and intent alignment. Calling the index directly through search APIs bypasses the retriever and results in retrieval behavior closer to standard vector or hybrid search. Although introducing a retriever sometimes adds latency, it enables higher retrieval accuracy by improving how queries map to relevant, answer-ready content.

Note
Use of this feature in Data Cloud consumes Data 360Credits. For more information see, [Billing Considerations for Unstructured Data and Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&release=264.0.0&type=5 "When you use unstructured data and search index configurations, your data is stored and processed in Data 360. Use of unstructured data and search index in Data 360 impacts the consumption of credits in the following usage types."). Contact your account executive for more information.
## Contents of Enriched Chunks
When you enable enriched content on a vector or hybrid search index, Data 360 generates three chunks: one chunk that contains the original chunk text, one chunk that contains metadata text, and one chunk that contains questions that the chunk can answer. Retrievers access these chunks to use in RAG and AI agent workflows.

Note Generated metadata doesn’t include personal identifying information (PII).
Chunk Type
Metadata Type
Description
METADATA
Keywords
Extracts keywords that uniquely identify the content.
Entities
Identifies and lists verbatim any of the following:
Locations
Organizations
Dates
Time
Currencies
Amounts
Percent
Products
Platforms mentioned
Topics
Extracts main topics discussed in the chunk. Includes important entities and
keywords in the topic names.
Title
Generates a concise and informative title summarizing the content.
Summary
Provides a summary of the content, highlighting key topics and entities. If
possible, aim to encompass a minimum of 100 words and a maximum of 250
words.
QUESTION
Questions
If applicable, compiles a comprehensive set of detailed questions that the
content in the text chunk can answer.
## Data Processing for Enriched Indexing
Enriched indexes are supported in all regions where Data 360 is available. Data for enriched indexes is processed through Amazon Bedrock managed services in these regions.
- us-west-2: US West (Oregon)
- us-east-1: US East (Virginia)
- eu-central-1: Europe (Frankfurt)
- eu-central-2 Europe (Zurich)
- eu-west-3: Europe (Paris)
Enable Amazon Bedrock Models (Amazon and Anthropic) in Einstein Setup to use enriched indexing. For more information, see [Amazon Bedrock documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/batch-inference-supported.html).
- **[Retrieval Response with Enriched Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_retrieval_response_enriched_index.htm&release=264.0.0&type=5)**
Enriched indexing enhances retrieval response by matching a question to a passage with the best possible answer in your knowledge base. While Data 360 hybrid search combines the strengths of sematically aware vector search with the precision and speed of keyword search, enriched indexing closes the gap further by finding the chunks closest to the users' question.
#### See Also
- [Create a Hybrid Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&release=264.0.0&type=5 "Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.")
- [Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
- [Billing Considerations for Unstructured Data and Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&release=264.0.0&type=5 "When you use unstructured data and search index configurations, your data is stored and processed in Data 360. Use of unstructured data and search index in Data 360 impacts the consumption of credits in the following usage types.")
- [Agentforce Data Library](https://help.salesforce.com/s/articleView?id=ai.data_library_parent.htm&language=en_US)
- [Data Cloud Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&language=en_US)
# Enrichment Considerations
Learn vital information about security, data storage, cost, deletion, and other considerations before you create enrichments to use Data 360 data in your org.
## Supported Source and Target Objects for Related Lists
You can create a related list enrichment on these target objects.
- Account
- Contact
- Lead
- Transform
Your related list enrichment queries records from these source objects.
- A DMO with the category Engagement, Profile, or Other that has a relationship to the Unified Individual DMO, Unified Account DMO, Individual DMO, or Account DMO. The DMO’s source data can be from other Salesforce orgs or from external data streams.
- A Unified contact point DMO, such as contact point email.

Note The unified contact point DMO is the only derived DMO that you can use in your related list enrichments.
- On Vehicle objects in Automotive Cloud, you can use any source DMO with an ID that uniquely identifies the vehicle. For example, you can use a vehicle identification number as a unique identifier to display vehicle telemetry data from a DMO as a related list on vehicles.
## Supported Source and Target Objects for Direct-DMO Related Lists
You can create a direct-DMO related list enrichment by using direct relationships between DMOs and Salesforce objects without the need for identity resolution. You can create a direct-DMO related list enrichment on these target objects.
- Account
- Asset
- AssetAccountParticipant
- AssetContactParticipant
- AssetMilestone
- Case
- Contact
- Contract
- FinancialAccount
- Fleet
- Lead
- LeadLineItem
- LeadPreferredSeller
- Opportunity
- OpportunityPreferredSeller
- Order
- Product2
- Transform
- Vehicle
- Work Order
- Work Order Line Item
Your direct relationship enrichment can query records from the source DMO that’s connected to the Salesforce object through the direct relationship. The direct relationship matches the DMO records with the Salesforce object records by using an ID or string field.
For considerations, see [Direct-DMO Related List Enrichment and Merged Salesforce Records Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations.htm&release=264.0.0&type=5).
## Supported Source and Target Objects for Copy Fields
You can create a copy field enrichment on these target objects.
- Account
- Asset
- Case

Note If you add a copy field enrichment to the Case object, auto-assignment isn’t supported for cases. Also, feed tracking isn’t supported for enriched objects. See [Feed Tracking](https://help.salesforce.com/s/articleView?id=experience.collab_feed_tracking_overview.htm&type=5&language=en_US) and [Assign Cases](https://help.salesforce.com/s/articleView?id=service.cases_assign.htm&type=5&language=en_US).
- ClinicalServiceRequest
- Collection Plan
- Contact
- Contract
- Custom Object
- Invoice
- Lead
- Opportunity
- Order
- Product
- Quote
Your copy field enrichment copies data from either a DMO or from a calculated insight object (CIO). You can use any one-dimensional or multi-dimensional aggregatable CIO as a source object. You can use these DMOs as a source object.
- Mapped DMOs—If the DMO’s source data is an external data stream, select **accelerate** when creating the data stream so that the external data is cached in Data Cloud.
- Unified Individual
- Unified Account
With copy field enrichments, data for the correct person or account is copied from Data Cloud to your org. If the source DMO in Data Cloud doesn’t have a 1:1 relationship with a unified object, then copy field enrichments return records that match the primary key of your org’s target object.
## Supported Data Types for Copy Field Enrichments
When creating a copy field enrichment, you can copy data from these DMO/CIO source fields.
- Number
- Text
- Date
- DateTime
- Email
- Phone
- Url
- Percent
- Boolean
- Currency
You can copy values into these target fields on your CRM object.
- Double
- Text
- DateOnly
- DateTime
- Email
- Phone
- Url
- Percent
- Boolean
- Currency
## Currency Fields for Copy Field Enrichments
You can copy financial data from data model objects (DMOs) into Salesforce objects using currency fields in copy field enrichments.
Consider these guidelines and limitations.
- Multi-currency orgs aren’t supported.
- If there’s a mismatch between the org currency and the currency coming from Data 360, those records aren’t copied.
- Changing the org currency with an active currency copy field enrichment doesn’t trigger incremental Change Data Feed job execution.
- You must redo the currency copy field enrichment setup if the org currency changes while there is an active currency copy field enrichment to avoid data corruption issues.
## Security
Permissions that are set on the parent object (Contact, Lead, or Person Account) in your org restrict access to the related list or copy field in your record home page.
You can restrict who can view a related list so that:
- Everyone who can access the object record home page can see the related list.
- No one who can access the object record home page can see the related list.
- Only users who have permissions to view that parent object in your org can see the related list.
- Only users who have specific permissions for each data space scope can see the related list.
If you restrict access so that a user who has access to the object record home page doesn’t have access to the related list data, the related list appears blank.
For data spaces, the standard Salesforce security policy of “most restricted access wins” doesn’t apply to the data shown in related list enrichments. All information within a selected data space is accessible, regardless of additional data restrictions placed within Data Cloud. To restrict the data that can be viewed, create a dynamic related list and filter on the data space.
You can control user access to data space aware objects and features by setting the object permissions and feature permissions in the user’s permission sets. For more information, see [Data Space Aware Objects and Features](https://help.salesforce.com/s/articleView?id=data.c360_a_data_space_aware_features.htm&release=264.0.0&type=5 "User access to data space-aware objects and features is controlled by setting the object permissions and feature permissions in the user's permission sets. Not all objects and features are data space aware.").
## Data Loss
If you map a copy field enrichment to an existing field in an org, the data in the field is overwritten with data from Data Cloud. Depending on the ingestion and sync options configured for Data Cloud, it’s possible for data changed in an org field to be overwritten before the data is ingested into Data Cloud, causing data loss.
To avoid possible data loss, consider these options.
- Map the copy field to a new field that only contains Data Cloud data, instead of an existing field on a Salesforce object where data is entered. For example, if Contact has a Nickname field where service reps can enter a nickname, create a new Preferred Nickname field for data from Data Cloud. Data Cloud data is harmonized and more likely to show clean and accurate data. You can control whether the last entered nickname or the most frequently used nickname is used in resolving different values in Data Cloud.
- Don’t use scheduled ingestion for data streams from your org. Instead, create a workflow to allow ingestion triggered by data changes for fields that you’re copying data into.
For example, if a customer calls into any service center to change their last name, you want the latest data to be available to all of your service reps, no matter what business unit they work for.
You set up a data stream from your org to Data Cloud, scheduled every 15 minutes. You create an enrichment that copies data from Data Cloud into the Last Name field in your org. The service rep changes the customer’s last name from Alders to Mayfair in the Last Name field, which is a copy field. Salesforce syncs the field data for the copy field before scheduled data ingestion, overwriting Mayfair with the original value of Alders. The new value of Mayfair is unrecoverable.
To keep data from being overwritten, you create a flow to allow ingestion to be triggered when changes are detected for the Last Name field.
## Data Actions and Data Targets
Copy field enrichments impact the total number of data actions and data targets available. Each copy field enrichment uses one data action and one data target available with your Data Cloud license. The number of available data actions and data targets can be found on the list of enrichments for the object.
## Data Latency
When you click to see more information in a related list, the list queries Data Cloud for more information. Data in the component is displayed in near real-time. However, if you specified more than the default date range of 7 days of data, the related list can experience significant latency, depending on the amount of data retrieved. You can reduce the date range or add filters as part of your related list enrichment to improve latency.
Copy field enrichments use a batch job to sync information between Data Cloud and your org records. Depending on the number of records being processed, there’s some data latency. The initial load of data takes hours or days, depending on the number of records, but subsequent syncs only update changed records and are quicker.
## Dynamic Related Lists
You can create a dynamic related list from the related list created by the related list enrichment. With a dynamic related list, you can override the default 7-day limit of data returned for a related list enrichment and restrict the data shown in the list.
To override the 7-day default, your dynamic related list filter must cover all Event-Time-mapped fields for that engagement DMO. If you filter on only one, it silently falls back to the 7-day windown instead of erroring.
## Lightning and Lightning App Builder
Related list components in the Lightning App Builder and on Lightning record pages have some limitations for related list enrichments.
- The Related List - Single component and the Related Lists component don’t show previews of Data Cloud related lists in the Lightning App Builder.
- In the Lightning App Builder, the Related List Quick Links component doesn’t show the record count for Data Cloud related lists. On the record page, when users hover over a Data Cloud related list in the component, the list overlay doesn’t show any related records.
## Limits for Related List Enrichment
- For related list enrichments, the maximum number of related lists depends on the maximum number of lookup relationships you can create in your Data Cloud org. The upper limit for an org is 10,000.
- You can create related lists for all data types, except for the Array of Floats data type.
## Related List Date Range for Engagement Data
By default, related list enrichments that contain engagement data return data from the last 7 days. You can modify the default date range by using a date filter when you create or edit an enrichment, or by creating a dynamic list. Keep in mind that a longer date range can make the related list significantly slower because the amount of data to display can be large.
## Person Accounts
When creating a related list enrichment for the Contact object, if you have person accounts enabled in Setup, you see an option to add them to the Person Account record home page. The Person Account related list is based on the Contact or Account object. For tips on which ID field to use for mapping, see [Data Cloud: Person Account Related List Mapping Requirement](https://help.salesforce.com/s/articleView?id=004269106&type=1&language=en_US).
Person account fields that are contact fields, not business account fields, can’t be used in copy field enrichments. These fields are identifiable by a prefix `Person` or suffix `_pc` on the field name.
**Use Person Accounts as a Target for Direct-DMO Related List Enrichments**
Starting in Winter ’26, you can select Person Account Fields when configuring a Direct-DMO Related List Enrichment in a Person Account enabled org. You can use fields from either the underlying Account or Contact objects as the matching fields, providing greater flexibility to link data between Data Cloud and your CRM.
## Direct-DMO Related List Enrichment and Merged Salesforce Records Considerations
Merged Salesforce records can cause issues with direct-DMO related list enrichments if they reference the Salesforce record ID. When duplicate accounts, contacts, or lead records are merged by using [duplicate rules](https://help.salesforce.com/s/articleView?id=sales.duplicate_rules_map_of_reference.htm&type=5&language=en_US), one of the records is deleted and its ID is no longer valid because the record no longer exists. If a related list enrichment uses a DMO relationship that matches records based on IDs, and it references the deleted Salesforce record ID, the related list enrichment doesn’t display all the related data.
The solution depends on the type of connector used.
- If a [Salesforce CRM Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector.htm&release=264.0.0&type=5 "A standard Salesforce CRM connection establishes a connection between Data 360 and a Salesforce org, allowing Data 360 to ingest data from the connected org. Data 360 ingests data and sends back only data actions. This type of connection doesn’t share any data back to the connected org.") is set up, refresh the data stream. This refresh updates the record ID on the Data Cloud DMO records.
- If a connector is used to an external data source, such as S3, update the IDs in the external data source. The external connection uses one of these [Data Cloud connectors](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-thirdparty-connectors.html).
Here’s an example of a record merge scenario. Say the Salesforce admin sets up a relationship between the Contact Salesforce object and the Email Engagement DMO and relates the records based on the Contact.Id and the EmailEngagement.ssot\_\_IndividualId\_\_c fields. When a contact record with an Id of 2 is merged with a contact with an Id of 1, the system deletes the contact with Id of 2. As a result, the Email Engagement records that reference the IndividualId\_\_c field of 2 aren’t displayed on the enriched contact with Id of 1 after the merge. To fix this issue, update the DMO data so that the Email Engagements that are associated with IndividualId\_\_c of 2 are associated with IndividualId\_\_c of 1.
This consideration affects only direct-DMO related list enrichments that use an ID field on the Salesforce object. It doesn’t affect other types of enrichments or direct-DMO enrichments that aren’t based on a CRM object ID field.
## Limits for Copy Field Enrichment
The maximum number of copy field enrichments is limited by the maximum number of data actions and data action targets for your org.
The maximum number of fields you can copy for a single enrichment without experiencing performance impacts is the maximum number of custom fields on an entity. However, you can create multiple enrichments for the same objects if you want.
## Excluded Fields for Copy Field Enrichment
Salesforce excludes fields that aren’t supported for copy field enrichment. The excluded fields aren’t available as target fields for copy field enrichment. They’re separate from incompatible fields.
## Technical Considerations for Copy Field Enrichment
These technical considerations are crucial for a successful Copy Field Enrichment implementation.
- Data kit compatibility: Data kits are a critical functionality for many users. However, the current compatibility between enrichments and data kits is unclear. Further investigation is recommended to ensure seamless integration.
- Impact on Existing Workflows: Implementing an enrichment can impact existing data processing workflows. Thoroughly evaluate potential disruptions and develop mitigation strategies if necessary.
## Full Sync Limits
A full sync job can run for a maximum of 24 hours. The number of records that can be processed is 60–100 million, depending on the environment in. Production environments can generally process more records.
## Troubleshooting Enrichments
Data in the org depends on data space, object, mapping, and data ingestion in Data Cloud.
If your enrichment doesn’t behave as expected, make sure that:
- The object and the data space configured for it haven’t changed.
- The data stream for the objects is connected successfully and ingesting data.
- You specified the correct key qualifier. You don’t usually require a key qualifier. However, if you specified the wrong key qualifier, it can cause the wrong data to be copied over. You need a key qualifier only in the rare case that data from your org isn’t ingested directly by using the CRM connector but via another system or service.
- If a user notices that a related list is blank, make sure that they have data space access control for any permission sets assigned to them.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
# Enrichment Troubleshooting
Diagnose issues with enrichments and fix them.
Data in the org depends on data space, object, mapping, and data ingestion in Data Cloud.
## Blank Related List
If a user complains that a related list is blank, but you can see the data, make sure that they have data space access control for any permission set assigned to them.
If you see that the related list is blank, make sure that you don’t need a key qualifier for your data stream. You only need a key qualifier in the rare case that data from your org is ingested via another system or service and not directly by using the CRM connector.
Data Cloud supports specific [date formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&type=5&language=en_US). Make sure that you’re using a supported date format.
## Blank Copy Field
If no data is available for the field you’re copying, make sure that:
- You selected a valid ID matching method. If the criteria you’re using doesn’t matchthe underlying data, then no data is returned.
- The object and data space configured for it hasn’t changed.
- The data stream for the objects is connected successfully and ingesting data.
- You specified the correct key qualifier. You don’t usually require a key qualifier. However, if you specified the wrong key qualifier, it can cause the wrong data to be copied over for a copy field enrichment.
## Copy Field Is Copying the Wrong Data
If the copy field isn’t showing data from the correct field, make sure that you specified the correct key qualifier. You only require a key qualifier if you aren’t using the CRM connector to ingest data from your org into Data Cloud. If you specified the wrong key qualifier, it can cause the wrong data to be copied over for a copy field enrichment.
If the copy field isn’t showing the data you expect, for example, it shows cases related to personal purchases, rather than business purchases, make sure you’re using an ID matching method that matches against the correct object.
## Copy Field Full Sync is Failing
Make sure that you set the permissions on the Contact or Lead object for the integration user. See [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.") for instructions on setting the permissions. After you set the permissions, stop the sync, and then start it again.
## Data Space Not Found
If you see the **"You don't have access to the required data space. To create a Copy Field Enrichment, the Data 360 Architect permission set must be assigned to your user and have access to the data space you're working in."** error, your user may be missing data space access. To fix the problem, ask your admin to do the following:
1\. Go to **Permission Sets —> Data 360 Architect**
2\. Under **Data Space Management**, add access to the relevant data space(s)
## Unexpected Behavior
If your enrichment doesn’t behave as expected and you tried the other troubleshooting steps, make sure that:
- The object and data space configured for it hasn’t changed.
- The data stream for the objects is connected successfully and ingesting data.
 [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&release=264.0.0&type=5 "Add cleaned and harmonized data from across your organization to your org through Data 360 enrichments. Create related list and copy field enrichments for your record pages with data from Data 360.")
#### See Also
- [_Salesforce Help_: Copy Field Enrichment Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_copy_field_enrichment_matching.htm&release=264.0.0&type=5 "Copy Field enrichments enhance the records in your org by adding data from other data sources. To avoid returning data that isn’t relevant to the records in your org, the enrichment matches data from your org to data in Data Cloud. How the data is matched determines what data is returned.")
# Ensuring Integrity in Marketing Cloud Engagement Activation
When multiple Marketing Cloud Engagement (MCE) orgs (EIDs) are involved in an Activation, unintended data mixing can occur. This happens when subscriber keys from different EIDs are brought into the same data space and are later activated to a specific EID, which can cause data integrity issues.
## Why is data mixing a concern?
- A subscriber key isn’t necessarily unique across different EIDs. This means the same key (for example, SK1) could belong to completely different individuals in separate EIDs.
- Activating subscriber keys from multiple EIDs together risks sending messages to the wrong individuals. For example, consider a company that runs two brands under separate EIDs, Tech Gadgets (EID 1) and Home Essentials (EID 2). If subscriber data from both EIDs is included in an Activation by mistake, a Tech Gadgets customer might receive a Home Essentials promotion, even if they never interacted with that brand. Worse, if they had opted out of Home Essentials, this could lead to compliance violations.
- Organizations must ensure that user consent is honored and data remains separate to maintain compliance. The same individual can give consent for different communication channels across EIDs. For example, they could have given consent for email in EID3 but for WhatsApp in EID4. Keeping data siloed prevents unintended cross-use of consent preferences across different EIDs.

Example
Imagine an organization using three Marketing Cloud connections (EID) and different business units (BU) to manage subscriber data. Each EID has a unique set of subscriber keys (SK).
- EID1 covers BU1, BU2, BU3 (with SK1 to SK15)
- BU1 covers SK1 to SK5
- BU2 covers SK6 to SK10
- BU3 covers SK11 to SK15
- EID2 covers BU4, BU5, BU6 (with SK16 to SK30)
- BU4 covers SK16 to SK20
- BU5 covers SK21 to SK25
- BU6 covers SK26 to SK30
- EID3 covers BU7, BU8, BU9 (with SK31 to SK45)
- BU7 covers SK31 to SK35
- BU8 covers SK36 to SK40
- BU9 covers SK41 to SK45
To keep things organized, subscriber data is grouped into data spaces (DS):
- DS1 contains only data from EID1 (BU1, BU2, BU3).
- DS2 contains only data from EID2 (BU4, BU5, BU6).
- DS3 contains only data from EID3 (BU7, BU8, BU9).
- DS-Global includes all EIDs (BU1–BU9).
- DS5 contains data from EID1 (BU2, BU3) and EID2 (BU4, BU5).
**Activation Scenarios**
**Scenario 1**: Activation using DS1
If you create an activation target with DS1, you’re working only with data from EID1 (BU1, BU2, and BU3).
- This means only subscriber keys from SK1 to SK15 are activated in the Marketing Cloud Engagement target (MC1).
- Data mixing is prevented. Since DS1 contains only EID1 data, there’s no chance of mixing data from EID2 or EID3.
**Scenario 2**: Activation using DS-Global
DS-Global contains data from all EIDs, but if you’re activating only BU1 (which belongs to EID1):
- The system ensures that only SK1 to SK15 (EID1) are activated, even though DS-Global contains data from EID2 and EID3. If **Allow Profile Business Unit Mapping Data** (BU-aware) is turned on, only the SKs for BU1 are activated.
- Data mixing is prevented because SK16 to SK45 from EID2 and EID3 are automatically blocked from activation.
**Scenario 3**: Activation using DS5
DS5 is a mix of EID1 (BU2, BU3) and EID2 (BU4, BU5), and you want to activate data for BU4.
- Since BU4 belongs to EID2, only SK16 to SK30 (EID2) are activated in MC2. If **Allow Profile Business Unit Mapping Data** (BU-aware) is turned on, only SK16 to SK20 are activated.
- Data mixing is prevented because SK1 to SK15 (from EID1) are blocked, ensuring data integrity.
#### See Also
- [_Salesforce Help_: Set Up a Marketing Cloud Engagement Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_marketing_cloud_connection.htm&language=en_US)
- [_Salesforce Help_: Create a Marketing Cloud Engagement Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
# Establish Data Foundation Requirements for Marketing Cloud Engagement
When integrating Data 360 and Marketing Cloud Engagement, clearly delineate the roles and responsibilities between each product. Data 360 is designed to ingest, resolve, transform, segment, and enrich data. Marketing Cloud Engagement is an engagement product that orchestrates personalized messaging campaigns.
We recommend taking time to examine the data foundation that you create in the Engagement Contact Model. To balance and increase marketer efficiency while preventing data sprawl in Engagement, we recommend an initial data foundation that selectively integrates a commonly shared dataset. You can use this foundation for content personalization and decisioning across many different Journey Builder use cases.
Which Data is Needed for Your Marketing Cloud Engagement Data Foundation?
The data foundation in Engagement stores refreshed data to use throughout your journeys. An audience-based journey uses the data foundation for rapid decisioning but typically doesn’t use it for content personalization. However, an event-triggered journey can use the data foundation for both rapid decisioning and content personalization.

Note By default, an event-triggered journey uses [journey data](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_journey_contact_data.htm&type=5&language=en_US) for content personalization, which likely suffices for transactional or short-duration journey use cases. When using an event-triggered journey for more complex or multi-day campaigns, use refreshed data for content personalization. For these journeys, we recommend using the data foundation’s contact data.
Determining the personalization attributes that your organization needs in their Marketing Cloud data foundation involves data specialists and marketers reviewing the campaigns and journeys that they want to execute. Start with an initial set of attributes commonly used for content personalization only for your event-triggered journeys. We then recommend an initial set of commonly used attributes for the decisioning of all of your journeys. You don’t need a comprehensive list of attributes to begin. You can adjust your data foundation and add more attributes as you launch more campaigns and grow into your implementation.

Note For both performance and functional reasons, we don’t recommend activating Related Attributes to store in your data foundation for journey decisions, waits, or exits. Instead, we recommend converting the Related Attribute into a Calculated Insight.
Individual Attributes Versus Unified Individual Attributes
For sensitive information, such as personal identifiable information for personalizing messages or consent attributes used for journey decisioning, we recommend activating attributes at the Individual level. This action ensures that the data foundation contains the correct context of data for the given Individual’s activated contact points.
Example: John Smith has three Individual profiles: John.Smith.1, John.Smith.2, and John.Smith.3. Each profile is imported to Data 360 with a slightly different full name—John Smith, John Smith Jr., and Johnny Smith—and each has a unique email address: js@example1.com, js@example2.com, and js@example3.com. The lifetime values are $20, $30, and $50, respectively, and the loyalty levels are Bronze, Silver, and Gold.
To add all three representations of John Smith into a single data extension, use Data 360 to segment and activate at the Individual level. The resulting data extension contains three rows, with each attribute selected directly from their respective Individual profile.
For aggregate information used for journey decisioning, activate attributes at the Unified Individual level. This activation enables you to retarget the person based on data collected throughout their larger Unified Individual profile.
Example: John Smith has 3 separate Individual profiles: John.Smith.1, John.Smith.2, and John.Smith.3. Each profile is imported to Data 360 with a slightly different full name —John Smith, John Smith Jr., and Johnny Smith—and each has a unique email address: js@example1.com, js@example2.com, and js@example3.com. The lifetime values are $20, $30, and $50, respectively, and the loyalty levels are Bronze, Silver, and Gold.
To add pieces from the three representations of John Smith into a single data extension, use Data 360 to segment and activate at the Unified Individual level. The resulting data extension contains one row, with each attribute either selected from one of the three Individual profiles or aggregated among them. For example, Individual ID: John.Smith.1; Full Name: John Smith Jr.; EmailAddress: js@example1.com; Lifetime Value: $100; Loyalty Level: Gold.
How to Model Your Data Foundation in Marketing Cloud Engagement
First, determine the best model for your data foundation. Then initialize your data foundation by using Data 360 to activate core audiences to Engagement. Finally, establish your data foundation by connecting the resulting data extensions to the Engagement Contact Model.
Deciding the Right Contact Model for Your Organization
| Organizational Factors | Core Audience Model | Collective Core Audience Model |
| --- | --- | --- |
| Total Audience Size | 0–8 million | 8 million or more |
| Number of Shared Personalization and Decisioning Attributes | 1–100 | 100+ |
| Team Experience with Marketing Cloud Engagement | None–Low | Moderate–Advanced |
| Desired Journey Length and Sophistication | None–Low | Moderate–Advanced |

Note For best performance, keep the count of shared attributes to a minimum and only activate attributes that are commonly used across multiple journeys.
Core Audience Model
- The marketer creates two activations in Data 360: one activation at the Individual level, and one at the Unified Individual level. Each activation contains your organization’s full active audience and all your required content personalization and decisioning attributes chosen by your organization.
- The data specialist creates a Marketing Cloud Engagement attribute group named “SF CDP” and attaches the Individual activated data extension audience to the root of the Engagement Contact Model in a 1:1 relationship. The data specialist then connects the Unified Individual data extension directly to the Individual data extension in a 1:1 relationship.

Note Some datasets can benefit from mapping in a 1:N relationship. In that case, we recommend creating a separate activation and connecting it within the attribute group.
- The data specialist creates a Marketing Cloud Engagement attribute group named “SF CDP Ad Hoc” for future one-off campaigns. This group requires unique data that isn’t commonly shared across multiple journeys and can be deleted after the journey is complete.
Collective Core Audience Model
- As a team, think of 2–15 groupings to organize the commonly shared attributes that you’ve chosen with your team. For example, Identity & Consent or Demographics & Psychographics.
- The marketer creates a separate activation in Data 360 for each grouping. Determine which groupings to activate at the Individual level, Unified Individual level, or both. Each activation contains your full active audience. Between the collection of activations, include all your required content personalization and decisioning attributes you’ve chosen with your team.
- The data specialist creates an attribute group in Marketing Cloud Engagement for each grouping and attaches the resulting data extension activations to the Engagement Contact Model in a 1:1 relationship. Link the Individual data extensions for each grouping to the root of the Engagement Contact Model in a 1:1 relationship. The data specialist then links the Unified Individual data extension for that grouping directly to the Individual data extension in a 1:1 relationship.

Note Some datasets can benefit from mapping in a 1:N relationship. In that case, we recommend creating a separate activation and connecting it within the attribute group.
- The data specialist creates a Marketing Cloud attribute group named “SF CDP Ad Hoc” for future one-off campaigns This group requires unique data that isn’t commonly shared across multiple journeys and can be deleted after the journey is complete.
# Ethics, Privacy, and Consent
Understand the concept of ethical data use and learn how to incorporate data ethics into your Data 360 implementation. Learn about how to protect your consumer’s privacy, data rights, and manage consent.
- **[Data Ethics](https://help.salesforce.com/s/articleView?id=data.c360_a_ethics.htm&release=264.0.0&type=5)**
Earning and keeping customer trust increasingly means adopting data ethics best practices when using Data 360.
- **[Data Subject Rights](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights.htm&release=264.0.0&type=5)**
A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.
- **[Consent Management](https://help.salesforce.com/s/articleView?id=data.c360_a_consent_management.htm&release=264.0.0&type=5)**
Learn more about Consent Management in Data 360.
- **[Honor “Do Not Share” and "Do Not Sell" Requests in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_do_not_share_requests.htm&release=264.0.0&type=5)**
Understand how to comply with the California Privacy Rights Act (CPRA) and other laws that give consumers the right to restrict sharing their data with or selling it to third parties.
- **[Data 360 Auto Mapping Model Card](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_mapping_model_card.htm&release=264.0.0&type=5)**
The Auto Mapping model automatically maps data lake object (DLO) source fields to data model object (DMO) target fields. The model reduces the amount of manual labor and time required to configure new data streams in Data 360.
#### See Also
- [_Salesforce Help_: Data Protection and Privacy](https://help.salesforce.com/s/articleView?id=data_protection_and_privacy.htm&language=en_US&type=5)
- [_Salesforce Developer_: Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm)
# Evaluate Account Matching in Query Editor
Check the effectiveness of your account unification match rules by reviewing Unified Account profiles with Query Editor.
The following query compares the output from a ruleset with the ruleset ID `001` with the output from a ruleset with ruleset ID `002`. The query compares how profiles linked to the phone number 555-234-5678 were unified by each ruleset.
To run this query in Query Editor in your org, customize the query for your org’s data.
1. Replace the account IDs in the specified UnifiedLinkssotAccount objects with ruleset IDs that are valid for your org. For example, to compare rulesets with IDs `ABC` and `XYZ`, replace `UnifiedLinkssotAccount001__dlm` and `UnifiedLinkssotAccount002__dlm` with `UnifiedLinkssotAccountABC__dlm` and `UnifiedLinkssotAccountXYZ__dlm.`
2. Replace the sample phone number, `(555) 234-5678`, with the phone number of specific record you want to review. Or, update the `WHERE` clause with different criteria.

Important Don’t remove the LIMIT clause from your query. An unlimited query response can return too many records to be useful.
After running the query, review the output to determine if the matches created by your match rules fulfill your business requirements. If not, tweak your match criteria and match methods to optimize your matching.
```
SELECT
"ssot__Account__dlm"."ssot__Id__c",
"UnifiedLinkssotAccount001__dlm"."UnifiedRecordId__c" as Med_UUID,
"UnifiedLinkssotAccount002__dlm"."UnifiedRecordId__c" as LOW_UUID,
"ssot__Account__dlm"."ssot__Name__c",
"ssot__ContactPointAddress__dlm"."ssot__AddressLine1__c",
"ssot__ContactPointAddress__dlm"."ssot__AddressLine2__c",
"ssot__ContactPointAddress__dlm"."ssot__CityId__c",
"ssot__ContactPointAddress__dlm"."ssot__CountryId__c",
"ssot__PartyIdentification__dlm"."ssot__PartyIdentificationTypeId__c",
"ssot__PartyIdentification__dlm"."ssot__Name__c" AS "Party_Name",
"ssot__PartyIdentification__dlm"."ssot__IdentificationNumber__c",
"ssot__ContactPointPhone__dlm"."ssot__FormattedE164PhoneNumber__c"
FROM "ssot__Account__dlm"
LEFT JOIN "UnifiedLinkssotAccount001__dlm" ON "UnifiedLinkssotAccount001__dlm"."SourceRecordId__c" = "ssot__Account__dlm"."ssot__Id__c"
LEFT JOIN "UnifiedLinkssotAccount002__dlm" ON "UnifiedLinkssotAccount002__dlm"."SourceRecordId__c" = "ssot__Account__dlm"."ssot__Id__c"
LEFT JOIN "ssot__ContactPointAddress__dlm" ON "ssot__ContactPointAddress__dlm"."ssot__PartyId__c" = "ssot__Account__dlm"."ssot__Id__c"
LEFT JOIN "ssot__PartyIdentification__dlm" ON "ssot__PartyIdentification__dlm"."ssot__PartyId__c" = "ssot__Account__dlm"."ssot__Id__c"
LEFT JOIN "ssot__ContactPointPhone__dlm" ON "ssot__ContactPointPhone__dlm"."ssot__PartyId__c" = "ssot__Account__dlm"."ssot__Id__c"
WHERE "ssot__ContactPointPhone__dlm"."ssot__FormattedE164PhoneNumber__c" = '(555) 234-5678'
ORDER BY
"ssot__ContactPointPhone__dlm"."ssot__FormattedE164PhoneNumber__c",
"ssot__Account__dlm"."ssot__Id__c"
LIMIT 100
```
# Evaluate Model Quality
Use training metrics to evaluate the model’s ability to predict an outcome and determine whether it’s ready to activate. Training metrics provide information about how effectively the model understands patterns and relationships within the training data, and indicates its predictive efficacy.
To evaluate model quality, it’s helpful to review key concepts.
- The outcome variable is the goal of the model. It’s the desired prediction or outcome.
- Variables are the input data that the model analyzes to make its predictions.
- Training is the process the model takes to learn patterns and relationships that can be used to make predictions on new, unseen data.

Tip No model is perfect, and there may be limitations and uncertainties in the predictions made. Always use caution and common sense when interpreting the results of a machine learning model.
## Accuracy
To measure accuracy, Einstein uses r-squared for regressions and area under the curve (AUC) for binary classifications. Based on standard thresholds for performance, Einstein tells you whether the overall accuracy of your model is performant, too low, or too high.
- Performant means the model is generally accurate.
- Too low means the model isn’t much better than random guessing.
- Too high means the model is perfect or nearly perfect, which indicates potential data leakage or overfitting.
## Top Predictors
The top predictors are the inputs, or variables that have the greatest impact on predicting the outcome.
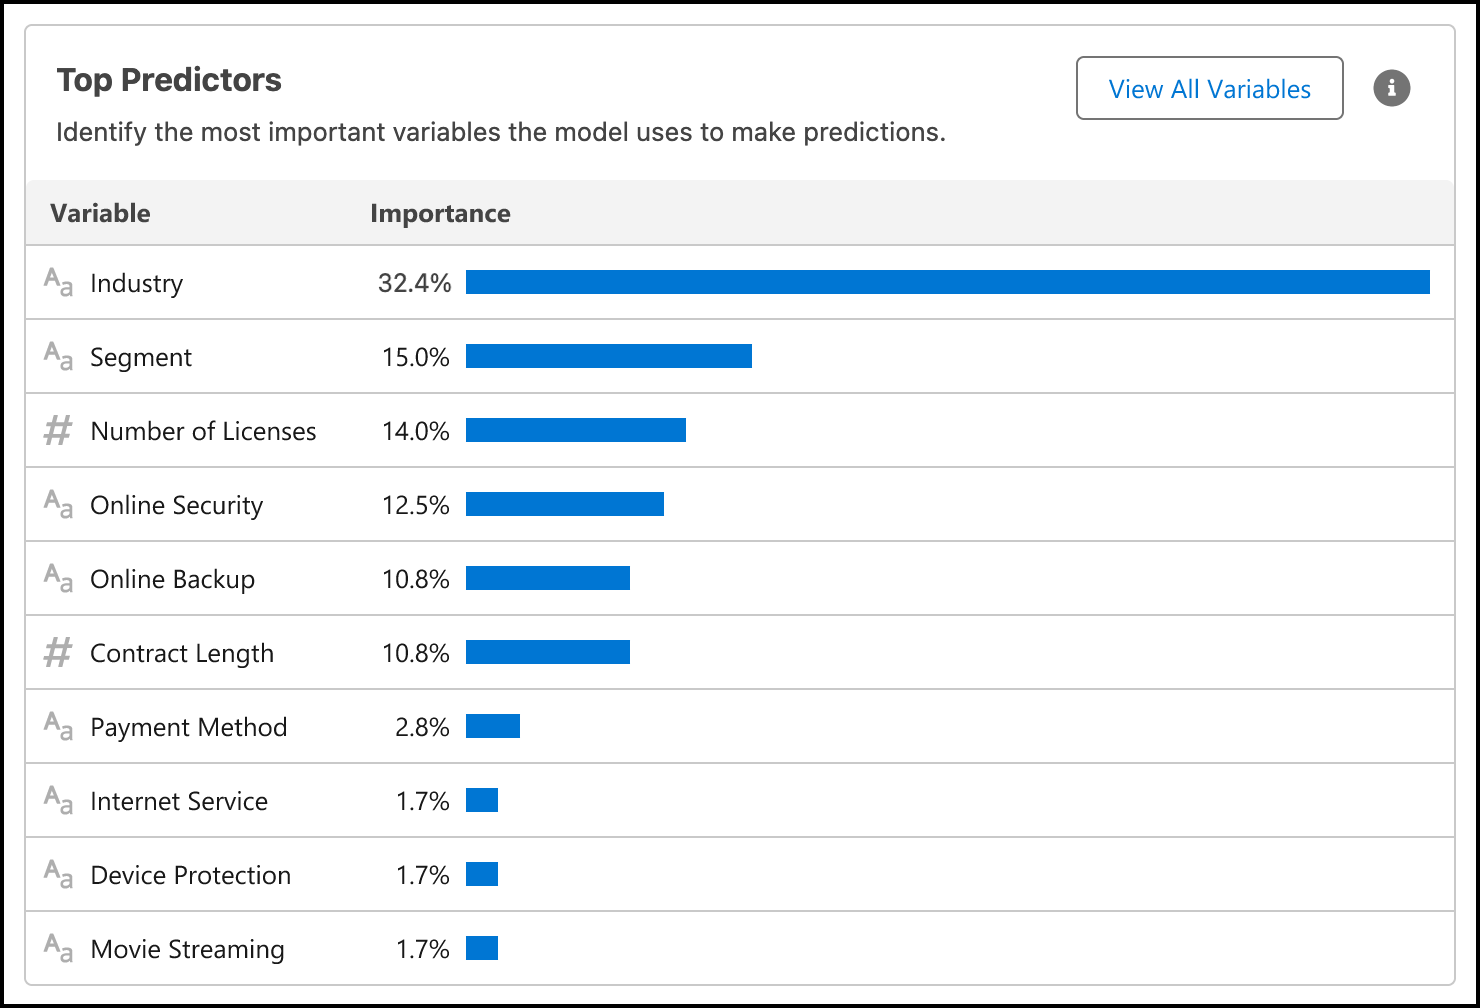
## Variable Distribution
The distribution of actual, or observed, values in the data for the outcome variable.
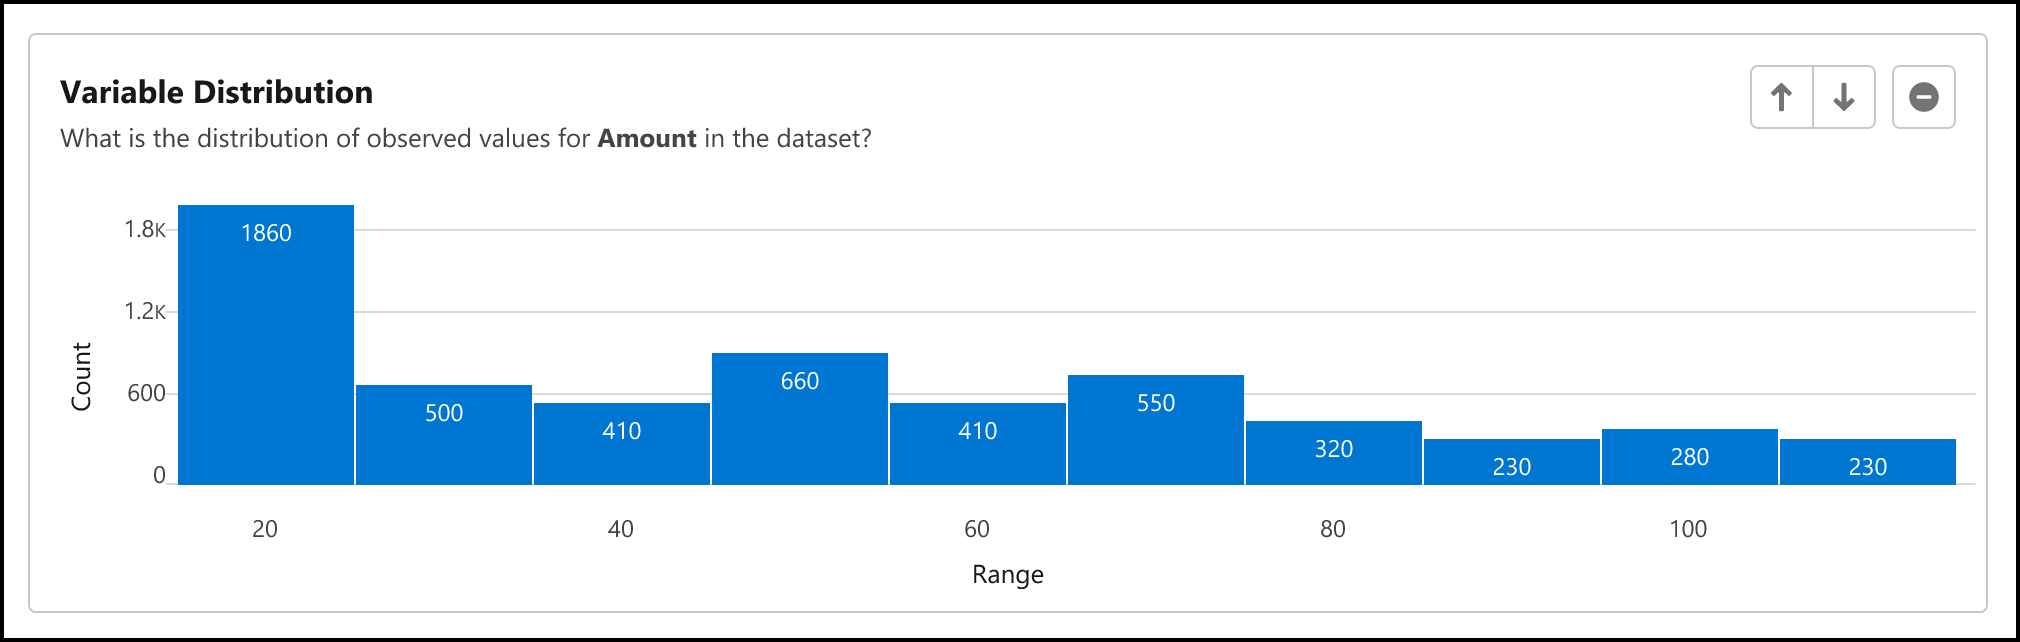
- **[Regression Metrics](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_regression_metrics.htm&release=264.0.0&type=5)**
Metrics for regressions help evaluate the performance of a model that predicts numerical values for continuous data.
- **[Binary Classification Metrics](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_binary_metrics.htm&release=264.0.0&type=5)**
Metrics for binary classification help evaluate the performance of a model that categorizes data into two classes.
# Event Time in Data 360
An event date is a time-based attribute in a DMO that is defined at the data stream level during ingestion. A DMO can have multiple event dates. The Event Time Field applies only to DMOs designated with the Engagement category.
When a segment is processed, only records that have a value for all system date attribute fields are returned. When an Engagement DMO is included in a segment, the segment can process the data records up to 24 months of the event date field. A segment fails if the date range exceeds 24 months. To run the segment again, adjust the event dates to fit this range.

Example The Sales Order DMO designates the Purchase Date attribute as the event date field. When you use the Sales Order DMO to create a segment of individuals who made at least $500 of purchases within the past X days, the value of X can’t exceed 24 months.
#### See Also
- [_Salesforce Help_: Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.")
- [_Salesforce Help_: Ingest Data](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion.htm&release=264.0.0&type=5 "To get started with Data 360, you connect a data source, through either data federation or data ingestion. Data federation sets up direct connectivity with data sources. It uses a zero copy integration that eliminates the need to ingest data into Data 360. During data ingestion, data is brought into Data 360 in its original form and stored in a data lake object (DLO).")
# Explore and Optimize
Optimize and explore your unified Data 360 data. Use Data Explorer and the Query Editor to inspect and interrogate your data. Build Data Graphs to precompute the fields your real-time apps need most. Add Secondary Indexes to speed up high-volume queries. Use Profile Explorer to validate that identity resolution produced the unified customer views your business expects.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
## Why Explore and Optimize?
After you connect, transform, and unify your data use these tools to make sure it is accurate, optimized, and dependable. The tools in this section give you direct visibility into your data and control over how it's structured and served. Whether you're troubleshooting an unexpected record count, tuning query performance for a high-traffic activation, or confirming that a unified profile looks right before a campaign goes live, Explore and Optimize is where that work happens.
- **[Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_data_explorer.htm&release=264.0.0&type=5)**
With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.
- **[Profile Explorer in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer.htm&release=264.0.0&type=5)**
Get a complete view of a unified profile for an account or individual for purposes such as validating unified profile data and checking for discrepancies. Customers can deploy a set of Lightning apps to customize and expand the experience.
- **[Query Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_query_data_in_dc.htm&release=264.0.0&type=5)**
A query is a structured request for specific information from Data 360. It's similar to asking a precise question of your data. Data 360 offers multiple ways to query your data.
- **[Get Instant Answers from Your Data with Data Q&A](https://help.salesforce.com/s/articleView?id=data.c360_a_data_qna_agent_overview.htm&release=264.0.0&type=5)**
Ask questions in natural language about your Data 360 data and get AI-powered answers, SQL queries, and visualizations instantly.
# Explore and Research Content with Notebook AI
Data 360 Notebook AI is a generative AI notebook for uploading personal, enterprise, and public content, conducting research, and generating insights.
Notebook AI is for individual business users and teams such as sales, support, and marketing. Use it to create a personal purpose-built workspaces for exploring content by asking questions or select source content to generate summaries.
Users create private resource libraries in the notebook, combine them with enterprise-wide content, and produce authoritative content all in one space.
Notebook AI is for short-term, time-bound projects or long-term research and content creation, bringing flexibility, control, and collaboration to AI-powered research.
You can use Notebook AI in Data 360 or as a web application.
## Use Case: Notebook AI for Researching Repetitive Customer Support Issues
Customer support representatives often deal with repetitive customer issues that stem from underlying product issues or configuration gaps.
Multiple systems and sources record customer issues, such as support cases, JIRA tickets, Slack threads, and error logs related to the product. There are multiple ways to find and document solutions to the issues, such as personal notes, product manuals, or community articles.
If there's no clear knowledge in one place that support representatives can use, reuse, or share, it can lead to different responses and escalations. As a support engineer, use this general flow to work with Notebook AI:
- Create a research notebook
- Upload all the sources into a resource library
- Explore your sources by asking questions, reviewing responses, and validating source citations
Validate the resolution and create an authoritative article by copying or downloading your analysis. Share and add the new content to your enterprise resource as a knowledge base article for others to benefit from your research.
## Use Case: Notebook AI for Researching a Request for Proposal (RFP) Business Opportunity
Sales representatives can use Notebook AI to research a sales proposal for a new business opportunity.
Sales representatives can utilize an AI-Generated notebook to upload various documents into resource libraries. These documents can include meeting notes with the customer, web pages detailing market trends, competitor analysis reports, and the RFP.
Explore your sources by asking questions, reviewing responses, and validating source citations. Use your research to generate a report and share it with your team for review.
- **[Enable Notebook AI For Data Spaces and Users](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_custom_user_perm.htm&release=264.0.0&type=5)**
Grant Data 360 Notebook AI access to data in data spaces and give enterprise users access to Notebook AI with custom permission sets. In a multi-org architecture, enable Notebook AI in both the home org and companion org.
- **[Enable Notebook AI Web Access](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_web_access.htm&release=264.0.0&type=5)**
Give enterprise users access to Data 360 Notebook AI web application. Authorize the Notebook AI web application to connect to your Salesforce org and allow users to log in to the application from the web.
- **[Generate Research Reports with Deep Research](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_deep_research.htm&release=264.0.0&type=5)**
Use Deep Research to generate comprehensive research reports directly in your Notebook AI workspace. Instead of querying multiple sources separately, submit a single research query. Notebook AI analyzes CRM records, uploaded documents, enterprise search results, and web sources, then delivers a report complete with findings, recommendations, and inline citations.
- **[Manage AI Notebooks](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_manage_notebooks.htm&release=264.0.0&type=5)**
Manage your generative AI notebooks in Data 360 Notebook AI. By default, a notebook is private to the user who creates it.
- **[Billing Considerations for Notebook AI](https://help.salesforce.com/s/articleView?id=data.c360_a_notebookai_billing_considerations.htm&release=264.0.0&type=5)**
Notebook AI uses Data 360 to upload content, ask questions, and save insights. Your data is processed through Data 360 and Agentforce. Use of Notebook AI impacts the consumption of credits in these usage types.
- **[Troubleshoot Notebook AI Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_troubleshooting.htm&release=264.0.0&type=5)**
Diagnose and fix the most common issues when setting up Notebook AI.
#### See Also
- [_Salesforce Help_: Billing Considerations for Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&release=264.0.0&type=5 "When you use unstructured data and search index configurations, your data is stored and processed in Data 360. Use of unstructured data and search index in Data 360 impacts the consumption of credits in the following usage types.")
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
- [Troubleshoot Notebook AI Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_notebook_ai_troubleshooting.htm&release=264.0.0&type=5 "Diagnose and fix the most common issues when setting up Notebook AI.")
# Explore Individual Profile Unification in Tableau
Dig into your unification data visually with the Identity Resolution Tableau accelerator. Pre-configured charts provide at-a-glance information such as how many profiles were ingested from each source and how they contributed to your unified individual profiles.
The Identity Resolution Tableau accelerator also lets you explore the composition of unified individuals and learn how matching rules and data quality affect your identity resolution results.
To learn more about the Identity Resolution Tableau dashboard and to download it, visit Data 360 Identity Resolution on [Tableau Exchange](https://exchange.tableau.com/products/624) or on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=998f2129-6168-4193-8cac-248a49ece04a).

Note To use this app, you must have a Tableau license. If you experience an issue when using an accelerator, share the details with your Tableau Account Team and ask them to contact the Tableau Accelerator Team to review the issue. Salesforce Support doesn’t support the Tableau accelerators for Data 360 available on [Tableau Exchange](https://exchange.tableau.com/accelerators) and [Salesforce AppExchange](https://appexchange.salesforce.com/mktcollections/curated/tableau-accelerators?_ga=2.121680143.505645265.1694449023-1607241779.1694449023).
# External Activation Platform Files in Cloud File Storage
Learn more about the files delivered to Amazon S3 for your external activation platform.
## File Paths
All your success, metadata, and activation output files arrive to S3. Use this information to interpret the file path variables and locate your files.
| File Path Variable | Description |
| --- | --- |
| Bucket-Name | The S3 Bucket Name that you provided when configuring your External Activation Platform in Data 360 Setup. You can write directly into the bucket without root folders or write to a specific folder within the bucket. |
| Date | The date (in UTC) the files were published. Date is expressed as YYYY-MM-DD. Success files are located here. |
| Account-ID | This value represents your Data 360 customer’s account in your external activation platform. The value is required when creating an activation target for an external activation platform. |
| Activation-Run-ID | A 36-character string to differentiate between multiple customers publishing to the same activation target. Multiple folders represent different Data 360 orgs sending data to the same Account ID in your external activation platform. Metadata files are located here. |
| ID-Type | Data 360 generates activation output files for each identifier type. This applies only when the output is grouped by user identifier (PER\_USER). Supported types are hashed email, hashed phone, mobile advertising Ids, and OTT advertising Ids. |
## Identifier Types (ID-Type)
This table shows the identifier type (ID-Type) values for the files. This applies only to external activation platforms created using the manual workflow.
| Type | Value | Description |
| --- | --- | --- |
| Email Address | HEM\_SHA25 | SHA256 hashed email address |
| Phone Number | PHONE\_SHA256 | SHA256 hashed E164 formatted phone number |
| Mobile Advertiser ID (MAID) | MAID | Advertising ID for a mobile device |
| Over-the-top (OTT) ID | OTT | Advertising ID for an OTT or CTV device |

Example This is an example of an activation output, grouped by user identifer. It creates a CSV file of SHA256 hashed email addresses sent to the account number 123-456-789 in the external activation platform. The file is written to subfolders of the S3 bucket, not directly into the bucket.
The file path is s3://mydatacdp/Salesforce-CDP/ActivatedSegments/2021-11-29/123-456-789/63a37da2-7474-428b-bdca-54cc0d970de5/type=HEM\_SHA25/part-0000-ca80176d-e93b-46d5-a17f-c448a078d34b.c000.csv.gz.
| Value | File Path Variable |
| --- | --- |
| mydatacdp/Salesforce-CDP/ActivatedSegments | Bucket-Name |
| 2021-11-29 | Date |
| 123-456-789 | Account-ID |
| 63a37da2-7474-428b-bdca-54cc0d970de5 | Activation-Run-ID |
| Type=SHA256 | ID-Type |
## Metadata File
The daily metadata file contains details about required and hidden fields, optional fields, segment Ids, and segment names. Data 360 admins can exclude segment names when installing your external activation platform by disabling **Include segment name in activations to this platform**. The metadata file includes only the segments present at the time of publishing. Segments deactivated, deleted, or expired in Data 360 don’t appear in the metadata file.
The file is stored at s3://{Bucket-Name}/{Date}/{Client-Account-ID}/{Activation-Run-ID}/metadata.json.
To identify segments deleted from Data 360, compare metadata file contents daily for differences.

Example This metadata file includes details about three segments for account 123456 in the external activation platform.
```json
{
"metadata": {
"AccountId": "123456",
"OptionalField1": "default",
"HiddenField1": "Salesforce-CDP"
},
"segments": [
{
"segmentId": "1sgRN00000002tI",
"segmentName": "Shoe Lovers"
},
{
"segmentId": "1sgRN00000001tC",
"segmentName": "High-Value Customers"
},
{
"segmentId": "1sgRN00000001rV",
"segmentName": "Email Engagement in Last 30 Days"
}
]
}
```
## Activation Output Files
Multiple activation output files arrive each day for each identifier type with information about segments published that day. Files include the value for an ID type and a list of segments in which that ID is a member. Each partial file is an individually compressed CSV, NDJSON, or Parquet GZIP file.
## CSV Format
CSV files include a header and record details for each segment.
| id | adds | removes |
| --- | --- | --- |
| IFA-Value | Segment-IDs | |

Example This CSV file is an example of an activation output grouped by user identifer that includes one segment with Id 1sgRN00000001rV and IFA value 30f39b57-7a31-439b-beeb-c3aa22593b27.
```
id,adds,removes
30f39b57-7a31-439b-beeb-c3aa22593b27,1sgRN00000001rV,""
```
## NDJSON Format
NDJSON is newline delimited with format `{"id":"[IFA-Value]","adds":"[Segment-IDs]","removes":""}`.

Example
This JSON file includes one segment with Id 1sgB000000000gq and IFA value 43950934.
```json
{"id":"43950934","adds":"1sgB000000000gq","removes":""}
```
# External Activation Platforms
Create and package an External Activation Platform to determine file formatting, required data details, or where to publish the files during activation. Share your package on AppExchange or provide the package URL generated in Package Manager for Data 360 admins to install.
- **[ISV Ecosystem Activation Using the Activation Toolkit](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_toolkit.htm&release=264.0.0&type=5)**
The Data 360 Activation Toolkit allows Independent Software Vendors (ISV) to build activation platforms on AppExchange. These platforms let subscriber organizations install and use ISV activation services. It lets them to match Data 360 data with destination data payloads and use advanced features like multi-key matching, contact point filtering, and supporting additional DMOs in Activation Membership.
- **[Create an External Activation Platform Using the Manual Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_external_activation_platform_schedule.htm&release=264.0.0&type=5)**
Create an external activation platform in a Data 360 Developer Edition org to help you reach your customers on your platform.
- **[Create Custom Metadata for Your External Activation Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_external_activation_platform_custom_metadata.htm&release=264.0.0&type=5)**
Create custom metadata for your external activation platform before you can package your platform for use by Data 360 admins. This applies only to platforms created using the manual workflow.
- **[Package Your External Activation Platform for Distribution with Package Manager](https://help.salesforce.com/s/articleView?id=data.c360_a_package_external_activation_platform_distribution.htm&release=264.0.0&type=5)**
After you created your External Activation Platform and custom metadata, use Package Manager to package and distribute your External Activation Platform to Data 360 Admins. A managed package is recommended because you can provide updates to admins when anything changes with the package. Only managed packages can be distributed through AppExchange.
- **[Find External Activation Platform Segments in Cloud File Storage](https://help.salesforce.com/s/articleView?id=data.c360_a_package_external_activation_platform_find_metadata.htm&release=264.0.0&type=5)**
After admins install your external activation platform, you can receive segments to Cloud File Storage (Amazon S3). For each activation target, you receive a success file, metadata file, and activation output files once a day for each identifier type when the output is grouped by user identifiers (PER\_USER). Because files arrive only once a day, there’s a delay between Data 360 customers updating segments and those changes arriving to S3.
# Extract Mode for a Marketing Cloud Engagement Data Extension in Data 360
Marketing Cloud Engagement Connector Extract mode dictates how Data 360 exports and imports data from Marketing Cloud Engagement.
Data 360 Engagement connector communicates with the source system on your behalf, but sometimes needs your help on source-specific concepts like extract settings. Engagement generates datasets based on the extract setting that you choose. If you choose data that reflects only new or updated records, there’s increased efficiency because there are fewer extracted records for the run.
Refresh Mode in Data 360 dictates how incoming data interacts with the data lake object (DLO). Use Refresh Mode to indicate if incoming data adds or updates previously sent data or replaces it with a new snapshot.
Extract settings correspond to how Engagement exports data. Refresh settings represent how that data is imported. If the Full Refresh extract is configured for Engagement, choose a Full Refresh import in Data 360. And a delta extract, reflecting new or updated records, is associated with an Upsert import in Data 360.

Note If you can’t use Upsert, you can’t change the Refresh settings. When the data stream was provisioned, the Refresh mode was set. Even deleting the data stream and recreating it, still uses that Refresh mode.
To extract data from Engagement, use a Full Refresh for all data to be available all the time. To extract data incrementally, use Numeric CDC or Date Time CDC. You can anchor each extract to the high-water mark for a column in the raw data.
- **[Full Refresh](https://help.salesforce.com/s/articleView?id=data.c360_a_full_replace.htm&release=264.0.0&type=5)**
Learn more about the Full Refresh extract method in Data 360 and when to use it.
- **[Delta Extract](https://help.salesforce.com/s/articleView?id=data.c360_a_incremental_replace.htm&release=264.0.0&type=5)**
Marketing Cloud Engagement supports two types of incremental extracts: delta extract by date and by number.
- **[Extract Mode Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_extract_mode_use_case.htm&release=264.0.0&type=5)**
Learn more about extract modes in Data 360 with a specific scenario.
# Extract Mode Use Case
Learn more about extract modes in Data 360 with a specific scenario.
The following example uses a data extension with the following column headers: Claim Number (Data Type: Number); Claim Status (Data Type: Text); Claim Created Date (Data Type: DateTime); Claim Updated Date (Data Type: DateTime).
## Raw Data in Marketing Cloud Engagement
Day 1 Snapshot in Marketing Cloud Engagement
Claim Number
Claim Status
Claim Created Data
Claim Updated Date
1
New
12/1/2019
12/1/2019
2
New
12/1/2019
12/1/2019
3
New
12/1/2019
12/1/2019
Day 2 Snapshot in Marketing Cloud Engagement
Claim Number
Claim Status
Claim Created Date
Claim Updated Date
1
New
12/1/2019
12/1/2019
2
In Review
12/1/2019
12/2/2019
3
New
12/1/2019
12/1/2019
4
New
12/2/2019
12/2/2019
5
New
12/2/2019
12/2/2019
## Goal
Make sure that Data 360 has the most recent data.
## Option 1: Set Extract Method to Full Refresh
1. On day 1, data for all time is sent, in this case three rows of data. Rows corresponding to Claims #1, 2, 3 are sent.
2. On day 2, data for all time is sent again, in this case now five rows of data. Rows corresponding to Claims #1, 2, 3, 4, 5 including updated Status for Claim #2 are sent.
**Outcome**: Goal achieved. Data 360 has all up-to-date data.
## Option 2: Set Extract Method to Numeric Change Date Capture (CDC) based on the Claim Number column
1. On day 1, all initial data is sent in this case three rows of data. Rows corresponding to Claims #1, 2, 3 are sent.
2. On day 2, the claims that accumulated between the penultimate claim number maximum of 3 and the newest claim number maximum of 5 are sent. Rows corresponding to Claims #4 and 5 are sent.
**Outcome**: Goal not achieved. Data 360 has data for all 5 claims, but it doesn't have the most recent status for Claim #2.
## Option 3: Set Extract Method to Date Time CDC based on Claim Updated Date column
1. On day 1, all initial data is sent, in this case three rows of data. Rows corresponding to Claims #1, 2, 3 are sent.
2. On day 2, the claims that accumulated between the penultimate claim updated date maximum of 12/1/2019 and the newest claim updated date maximum of 12/2/2019 are sent. Rows corresponding to Claims #2, 4, and 5 are sent.
**Outcome**: Goal achieved. Data 360 has data for all 5 claims and it has the most recent status for Claim #2.
## Option 4: Set Extract Method to Date Time CDC based on Claim Created Date column
1. On day 1, all initial data is sent, in this case three rows of data. Rows corresponding to Claims #1, 2, 3 are sent. On day 2, the claims that accumulated between the penultimate claim created date maximum of 12/1/2019 and the newest claim created date maximum of 12/2/2019 are sent. Rows corresponding to Claims #4 and 5 are sent.
**Outcome**: Goal not achieved. Data 360 has data for all 5 claims, but it doesn't have the most recent status for Claim #2.
## Conclusion
The Full Refresh option and the Date Time CDC with Claim Updated Date high-water mark result in the most up-to-date data for Data 360. But the Full Refresh option means that Data 360 processed 8 total rows of data: 3 rows on day 1 and 5 rows on day 2. The Date Time CDC option means that Data 360 processed 6 total rows of data: 3 rows on day 1 and 3 rows on day 2. Date Time CDC extract based on updated date column is the most efficient option when scaling your use case.
## Caveats
If the data extension is extracted from Engagement for an existing automation, the UI reflects the previously configured Extract Mode and high-water mark field.
# Extract Transformation: Get a Date Component
Use the Extract transformation to pull a selected component from a date field into a new field. For example, extract the hour component from the Case Created Date field to analyze case creation by hour of the day.
1. In the Transform node, select the date field that you want to extract a component from.
2. In the Transform toolbar, click the **Extract** button () to set the extract settings.
3. Select which date component to extract.
4. Under Show Results In, select whether the new values appear in a new field and whether to keep the original field.
5. If you elect to create a field, set the label under Field Label.
6. Click **Apply** to add the transformation to the Transform node. The Preview tab shows the new date component field.
7. To view the canvas, click the **Collapse** button ().
8. Save the data transform.
After you run the data transform, the selected date component is extracted in the specified dimension field.
# File Name Examples for File Storage Activation
Based on the values configured for the fields of your file storage activation target, here are some examples of file names for Data 360 external activations.
## File Naming for Segment Activations
File Name
Description
TeenagersInNewyork_EmailCampaign_2023-07-30-17-55-45-216_00000.csv
Non-compressed / Non-encrypted CSV file with date/time suffix. This file name
is predetermined based on the segment name and activation name.
TeenagersInNewyork - Segment name
EmailCampaign - Activation name
2023-07-30-17-55-45-216 - Date/time suffix referring to the segment
publish/refresh time with milliseconds in yyyy-MM-dd-HH-mm-ss-SSS format.
00000 - Part number. The number of files generated depends on the volume of
activated data. Each file has a part number (00000, 00001, 00002, and so on)
even if the activation produces only a single file.
.csv - File extension
TeenagersInNewyork_EmailCampaign_2023-07-30_00000.csv
Non-compressed / non-encrypted CSV file with date/time suffix referring to the
segment publish/refresh time in yyyy-MM-dd format.
TeenagersInNewyork_EmailCampaign_2023-07-30-17-55-45-216_00000.parquet.gz
Compressed / non-encrypted parquet file with date/time suffix. The gz refers
to the compressed file
TeenagersInNewyork_EmailCampaign_2023-07-30-17-55-45-216_00000.json.bz2.pgp
Compressed / PGP encrypted JSON file with date/time suffix in milliseconds. The
bz2 refers to the compressed file, and the pgp refers to the encrypted file. PGP
encryption is applicable only for SFTP activation target.
WinterOffersForMobileAudience_2023-07-30-17-55-45_00000.json
A custom file name. All activations to the activation target contain the same
custom file name with a different date/time suffix based on the segment publish time
## File Naming for Non-Segment Activations
For non-segment activations, such as batch DMO and API activations, the output file name always uses `` irrespective of the predetermined file name you select for the activation target.
Example: EmailCampaign\_2023-07-30-17-55-45-216\_00000.csv
## Segment Metadata JSON File
For S3 (Legacy) targets, the filename is segment\_metadata.json.
For other file storage activation targets, the segment metadata JSON file uses the naming convention {File Name Type}\_{Date/Time Suffix}\_segment\_metadata.json, where the File Name Type and Date/Time Suffix are defined during the activation target setup. Example: TeenagersInNewYork\_EmailCampaign\_2023-07-30-17-55-45-216\_segment\_metadata.json
# Filter Node
Use a Filter node to remove rows that you don’t need in your target. For example, you can filter case records to focus on escalated cases only. Filter values are case-sensitive.
1. In a batch data transform that already has at least one Input node, select the **Add Node** button between two nodes or at the end of the batch data transform. To show the Add Node button between two nodes, hover the cursor on the connecting line.
2. 
Note When adding a filter node, the picklist displays only the values present in the preview dataset. Values that exist in your full dataset but weren't included in the preview won't appear as filter options.
In the Add Node dialog box, select **Filter**.
3. Click the + to add a standard filter. A standard filter uses conventional filter operators—equals, does not equal, less than, and so on. For more granularity in your filter options, such as access to string and math functions, select **Add Custom Filter Expression** from the dropdown next to Filters. Filter values for both options are case-sensitive.
1. To apply an aggregate function to currency values, set a currency. If you don't specify a currency, the node uses the currency from the first row of data.
4. 
Note Column search results display up to 2,000 values.
If you define a filter condition on a dimension column, you can select a filter value from a list of values in your data. Then, click **Add new value** and enter the value.
5. Click **Apply**.
6. To display the current standard filter logic click  and **Add Standard Filter Logic**.
The default `AND` logic is shown, and each filter component is assigned a number.
7. To edit the logic, click the pencil icon ().
8. Build the filter logic with parenthesis and the `AND`, `OR`, and `NOT` Boolean operators.
9. Click **Apply**.
10. Save the data transform.
# Filter Source Records for Identity Resolution
Control which source records enter the identity resolution processing pipeline by defining filter conditions on your ruleset's primary data model object. Filters act as a preprocessing gate, so that only records matching your conditions enter the unification pipeline. Using filters helps keep unified profiles clean and reduces credit consumption.
Filters are intended for broad, partition-level segregation. They apply to the primary data model object of a ruleset and aren’t designed for record-level control on high-cardinality fields such as IDs.
## Use Cases
- **Separate B2B and B2C accounts—**If your data space includes both business and consumer accounts in the same Account DMO, add a filter such as RecordType = "B2B" to your B2B ruleset. Accounts that don't match the B2B record type aren't sent to identity resolution for processing by the ruleset.
- **Run a sample dataset to test match rules—**Before running identity resolution on your full dataset, filter by data source to process only a representative sample. Evaluate your match and reconciliation rule results, refine the configuration, and then remove the filter to process the full dataset.
- **Isolate verified data sources—**If you have a high-velocity or lower-quality data source alongside highly verified CRM data, use a filter to include only the verified source in a given ruleset.
## Limits and Considerations
Each ruleset supports up to 3 filter groups with up to 3 field conditions per group. Each filter group applies to the primary data model object of the ruleset.
Use AND/OR logic to combine conditions within and across groups. Standard operators are available for building conditions.
Adding or changing a filter condition on an active ruleset triggers a full reprocessing of the ruleset. To minimize the number of full reruns, pause the ruleset's automated schedule, make all configuration changes, including filter changes, at once, and then resume the schedule.
#### See Also
- [_Salesforce Help_: Create Identity Resolution Rulesets](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5 "Specify how identity resolution identifies matching records in Data 360.")
# Filter Streaming Data Transform Records
Use the `WHERE` clause in the streaming data transform SQL statement to limit which source object records the streaming data transform reads and processes.
For example, suppose you want to create a streaming data transform that reads and processes from the CRMContacts object only when the WorkPhone field has a non- `NULL` value.
In this SQL statement, the `WHERE ISNOTNULL(object.field)` clause filters out records that don’t contain a work phone number.
```
SELECT CONCAT(CRMContacts.CustomerId, "_1") as PhoneId,
CRMContacts.CustomerId as CustomerId,
CRMContacts.MobilePhone as PhoneNumber,
"Mobile" as PhoneType
FROM CRMContacts
WHERE ISNOTNULL(CRMContacts.WorkPhone) AND CRMContacts.WorkPhone <> ""
```
If a record in the source object is updated so that it no longer matches the `WHERE` filter, the record is deleted from the target object.

Note
Don’t compare a field to null using `=,!=, or <>`. These comparisons don’t match null values, so rows with a null in that field will be silently excluded or included when you don’t expect it. Always use field `ISNULL(field)` or `field ISNOTNULL(field)` instead.
# Filter the Segment and Publish to Marketing Cloud Engagement
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by job title and whether the person has opted in to receive emails.
1. In Data 360, on the **Segments** tab, select the **Upcoming Contract Renewals** segment.
2. In the Activations section of the segment record, click **New**.
3. Select a Marketing Cloud Engagement activation target, the destination of the segment data.
1. For the activation membership, select **Account Contact**.
2. Click **Continue**.
4. Click **\+ Select** for Email as the contact point (channel).
1. Confirm the email address path and source priority order, and then click **Next**.
5. Curate the activated members by selecting attributes to filter the activation membership DMO. Under Activation Membership, click **Add Filters**.
1. Drag the **Title** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Decision Maker.
2. Click **Done**, and then click **Save**.
6. To determine which contact points are chosen for a member, under Contact Points, click **Add Filters**, and select the attributes.
7. To manage consent, go to the Contact Point Consent DMO (L3).
1. Drag the **Data Use Purpose** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Contract.
2. Drag the **Consent Status** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Opt In.
3. Click **Done**.
8. Filter for Communication Subscription Consent. Go to the Communication Subscription Consent DMO (L4).
1. Drag the **Communication Subscription** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Contract Renewal.
2. Drag the **Consent Status** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Opt In.
3. Click **Done**.
4. Make sure the AND operator is selected between the two DMOs.
5. Click **Save**.
9. Under Contact Point, the value is 1 for Max. # of Attribute Values because only one value is sent for each contact point channel. For Sort By, select **Last Modified Date** and the **Most Recent** operator to organize your data.
10. Add attributes for personalization.
The email template has placeholders for the customer’s name and contract expiration date.
1. At the top of the screen, click **Add Attributes**.
2. From the direct attribute list, select **First Name** and **Last Name**.
3. From the related attribute list, click **Account DMO**, select **Contract Name** and **Contract Renewal Expiration Date**.
4. Click **Save**.
11. Under Attributes, the value is 5 for Max # of Attribute Values since you may have multiple contracts renewing for each customer. For Sort By, select the **Last Modified Date** attribute and the **Most Recent** operator to organize your data.
12. Click **Next**.
13. Name the activation Upcoming Contract Renewals and add a description.
1. Select **Incremental Refresh**.
2. Click **Save**.
The activation is sent to Marketing Cloud Engagement.
# Filter the Segment and Publish to Marketing Cloud Engagement
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by consent status and whether the person has opted in to receive emails.
1. In Data 360, on the **Segments** tab, select the **New Service Promo** segment.
2. In the Activations section of the segment record, click **New**.
3. Select a Marketing Cloud Engagement activation target, which is the destination of the segment data.
1. For the activation membership, select **Unified Individual**.
2. Click **Continue**.
4. Click **\+ Select** for Email as the contact point (channel).
1. Confirm the email address path and source priority order, and then click **Next**.
5. Under Contact Points, click **Add Filters**.
6. To manage consent, go to the Contact Point Consent DMO (L3).
1. Drag the **Data Use Purpose** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Marketing.
2. Click **Done**.
3. Drag the **Consent Status** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Opt In.
4. Make sure the attributes have an AND operator, and click **Done**.
7. Click the Communication Subscription Consent DMO (L4).
1. Drag the **Communication Subscription** attribute, select the **Is Equal To** operator, and enter the value Service Newsletters.
2. Click **Done**.
3. Drag the **Consent Status** attribute, select the **Is Equal To** operator, and enter the value Opt In.
4. Make sure the attributes have an AND operator, and click **Done**.
8. Select the AND operator for the two DMOs.
9. Click **Save**.
10. Under Contact Point, the value is 1 for Max. # of Attribute Values because only one value is sent for each contact point channel. For Sort By, select the **Last Modified Date** attribute and the **Most Recent** operator to organize your data.
1. Click **Continue**.
11. The campaign has placeholders for personalization to include the customer’s first name, last name, and the customer’s current services. To make sure this information gets sent to Marketing Cloud Engagement, add attributes to the activation. Click **Add Attributes**.
1. In addition to Unified Individual, in the direct attribute list select **First Name** and **Last Name** and drag it to the segment canvas.
2. In the related attribute list, navigate to **Services**, select **Purchased Service**, and select a path.
3. Click **Save**.
12. Under Attributes, the value is 5 for Max # of Attribute Values since you may have multiple services for each customer. For the Sort By field, select **Last Modified Date**, and then **Most Recent** to define how to sort the date.
13. Name the activation New Service Promo, and click **Done**.
The activation is sent to Marketing Cloud Engagement.
# Filter the Segment and Publish to Marketing Cloud Engagement
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by consent status and whether the person has provided their phone number.
1. In Data 360, on the **Segments** tab, select the **Terms of Service Changes - CA** segment.
2. In the Activations section of the segment record, click **New**.
3. Select a Marketing Cloud Engagement activation target, which is the destination of the segment data.
1. For the activation membership, select **Individual**.
2. Click **Continue**.
4. Click **\+ Select** for Phone (SMS) as the contact point (channel).
1. Confirm the phone path and source priority order, and then click **Next**.
5. To determine which contact points are chosen for a member, under Contact Points, click **Add Filters**.
6. To manage consent, go to the Contact Point Consent DMO (L3).
1. Drag the **Data Use Purpose** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Services.
2. Drag the **Consent Status** attribute to the segment canvas, select the **Is Equal To** operator, and enter the value Opt In.
3. Click **Done**.
7. Go to the Communication Subscription Consent DMO (L4).
1. Drag the **Communication Subscription** attribute, select the **Is Equal To** operator, and enter the value Terms of Service.
2. Drag the **Consent Status** attribute, select the **Is Equal To** operator, and enter the value Opt In.
3. Confirm the attributes have an AND operator, and click **Done**.
8. Confirm the AND operator for the two DMOs.
9. Click **Save**.
10. Under Contact Point, the value is 1 for Max. # of Attribute Values because only one value is sent for each contact point channel. For Sort By, select the **Last Modified Date** attribute and the **Descending** operator to organize your data.
11. The campaign has placeholders for personalization to include the customer’s first name and last name. To make sure this information gets sent to Marketing Cloud Engagement, add attributes to the activation.
1. At the top of the screen, click **Add Attributes**.
2. In addition to Individual Id, from the direct attribute list, select **First Name** and **Last Name** and drag it to the canvas.
3. Confirm the path is correct, and then click **Save**.
4. Click **Next**.
12. Name the activation Terms of Service Changes - CA, and add a description.
1. Select **Incremental Refresh**.
2. Click **Save**.
The activation is sent to Marketing Cloud Engagement.
# Filtering Using Containers and Attributes
On the segmentation canvas, you can define rules to filter your population to a targeted group. You can create and combine filters in different ways for different results. When you define a filter using a related attribute, a container is added to the canvas with applicable rule options. The related attribute’s data model object (DMO) becomes the container object.
If you add other related attributes to the container, they act on the same data row as the container object. The attribute library displays objects up to five relationships away from the container. You can include the related attributes of any of these objects in the container.
However, attributes in separate containers have no relationship to each other and filter your segment separately.
For each container on the canvas, you can calculate the segment population attributed to that container (container population). This helps you see how much each container narrows your segment. The count is shown in a ribbon below the container and is calculated only when you trigger it, and not shown automatically when you add the container.

Example Scenario 1: If you place the attributes “yellow” and “scarf” in the Order Product container, the query engine uses AND logic and looks for a customer who purchased a yellow scarf as a single order product” on the purchase.

Example
Scenario 2: If you place the attribute “yellow” in one container, and the attribute “scarf” in another container, the query engine looks for customers who purchased any yellow product and purchased a scarf of any color.
If your attributes are unrelated in your data model, you can’t combine them in a container. Review your data model to understand which attributes are ingested.
- **[Aggregation](https://help.salesforce.com/s/articleView?id=data.c360_a_aggregation.htm&release=264.0.0&type=5)**
The first step in defining your filter criteria is to decide how you want to quantify the results, such as an average or sum, also known as aggregation. For example, you use different criteria to find five sales order products as compared to five sales orders. Use the container object to aggregate your data. The Data Model Object (DMO) of a related attribute in a container becomes the container object.
- **[Simplify Segment Filters with Shortcuts](https://help.salesforce.com/s/articleView?id=data.c360_a_attribute_shortcuts.htm&release=264.0.0&type=5)**
Save commonly used segment filter attributes with their data model paths as shortcuts to reuse them across segments and activations. Instead of navigating the attribute library to find the right data model object (DMO), path, and attribute each time, you can select a saved shortcut that has the required configuration.
- **[Group, Rank, and Limit Segment Audience](https://help.salesforce.com/s/articleView?id=data.c360_a_rank_and_limit_segment.htm&release=264.0.0&type=5)**
The grouping, ranking, and limiting rules in Data 360 Segmentation adds advanced, multi-level filtering to the segment builder. After your standard filters are applied, you can use sequential logic to group, rank, and limit your segment population, creating more structured and balanced audiences.
- **[Hierarchical Aggregation in Segment Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_b2b_hierarchical_aggregation.htm&release=264.0.0&type=5)**
Hierarchical aggregation provides a comprehensive view of your data by rolling up revenues for accounts and their subsidiaries. You can then define more precise segment filters based on an aggregate value across multiple levels.
- **[Container Paths](https://help.salesforce.com/s/articleView?id=data.c360_a_container_path.htm&release=264.0.0&type=5)**
Some containers have multiple paths back to the segmentation entity. When a container has multiple access paths, you can select a path to help Data 360 understand how to build your segment. The paths available when you first create a filter may differ from those available when you edit it later. This is expected behavior driven by relationship-cardinality rules.
- **[Issues with Using Cyclic Paths in Segment Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_issues_with_cyclic_paths_in_segment_attributes.htm&release=264.0.0&type=5)**
When you choose a DMO more than one time while selecting a related attribute, you create a cyclic path. Cyclic paths are relationships that use cyclic behavior (a→b→a). Cyclic paths degrade segment performance and can lead to count or publish failures. To avoid these issues, Data 360 prevents you from creating cyclic paths through Segment Builder by default.
- **[Event Time in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_container_basics_attributes.htm&release=264.0.0&type=5)**
An event date is a time-based attribute in a DMO that is defined at the data stream level during ingestion. A DMO can have multiple event dates. The Event Time Field applies only to DMOs designated with the Engagement category.
- **[Create a Container for Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_use_a_container.htm&release=264.0.0&type=5)**
When a filter is defined using a related attribute, a container is created on the canvas with options to define the rules that you need. You can include up to 20 filters within a container.
- **[Use Vector Filters in Data 360 Segments (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_add_vector_filters_segmentation.htm&release=264.0.0&type=5)**
Vector filters reduce reliance on exact keyword matches and manual data organization, allowing you to create accurate segments efficiently. This feature uses NLP algorithms to sort through unstructured data in segment creation. It supports filtering both structured and unstructured data within a single interface and a segment.
- **[Currency Data Type in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_currency_datatype_segment.htm&release=264.0.0&type=5)**
You can use the currency data type to convert currency when performing aggregations and creating the required groups in segmentation filters.
# Financial Services Cloud Bundle Data Mappings
The Financial Services Cloud data bundle for Data Cloud helps financial services firms increase employee productivity, accelerate time to value, and deepen customer trust with every interaction. These data mappings relate to Financial Services Cloud bundle available for the Salesforce CRM connector. You can add to or customize the data mappings.
| Source Object | Mapping Reference |
| --- | --- |
| Account | [Account Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_account.htm) |
| Alert | [Alert Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_alert.htm) |
| Card | [Card Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_card.htm) |
| Contact | [Contact Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_contact.htm) |
| Financial Account | [Financial Account Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_finacct.htm) |
| Financial Account Role | [Financial Account Role Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_finacct_role.htm) |
| Financial Goal | [Financial Goal Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_fin_goal.htm) |
| Financial Goal Party | [Financial Goal Party Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_fin_goal_party.htm) |
| Financial Holding | [Financial Holding Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_fin_holding.htm) |
| Party Expense | [Party Expense Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_party_expense.htm) |
| Party Income | [Party Income Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_party_income.htm) |
| Personal Life Event | [Personal Life Event Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_perlife_event.htm) |
| Topic | [Topic Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_fsc_topic.htm) |
# Find Activated Data in File Storage Platforms
After you create and activate segments/DMOs to file storage platforms, view them in their respective storage locations.
### Required Editions

Important For non-segment activations, such as batch DMO and API activations, the output file name always uses ``, irrespective of the activation target’s predetermined file name selection.
## Find Activated Files in Amazon S3
After you create and activate segments to Amazon S3, a subfolder called Salesforce-c360-Segments is automatically created when the first segment is activated to Amazon S3.
Access Amazon S3.
- For activations with S3 (Legacy) as the target, a subfolder called Salesforce-c360-Segments is automatically created when the first segment/DMO is activated. Go to the path /{bucket}/{parentFolder}/Salesforce\_c360\_Segments.
- For segment activations, activated files are created in the format {yyyy}/{MM}/{dd}/{HH}/{segmentName}\_{activationName}\_{yyyyMMddHHmmssSS}/
- For batch DMO activations, activated files are created in the format {yyyy}/{MM}/{dd}/{HH}/{activationName}\_{yyyyMMddHHmmssSS}/
- For activations with Amazon S3 as the target, activated files are placed in the parent or child directory based on your configuration. Go to the path /{bucket}/{parentFolder}/{childFolder}/{automaticFolder} based on your configuration.
- For segment activations, activated files are created in the format {segmentName}\_{activationName}\_DateTimeSuffix\_Part#.FileFormat.CompressionFormat.PGPEncryption
- For batch DMO activations, activated files are created in the format {activationName}\_DateTimeSuffix\_Part#.FileFormat.CompressionFormat.PGPEncryption.
## Find Activated Files in SFTP Server
After you create and activate segments/DMOs to the SFTP server, activated files are placed accordingly in the parent or child directory based on your configuration.
1. Access the SFTP server.
2. Go to the server you configured in SFTP target.
3. Go to the path /Parent directory/Child directory/Automatic folder based on your configuration.
Activated files are created in the format: /FileName\_DateTimeSuffix\_Part#.FileFormat.CompressionFormat.PGPEncryption.

Note The datetime suffix in the file name is provided in UTC time.
Example file name: /TeenagersInNewyork\_EmailCampaign\_2023-07-30-17-55-45-216\_00000.csv.gz.pgp
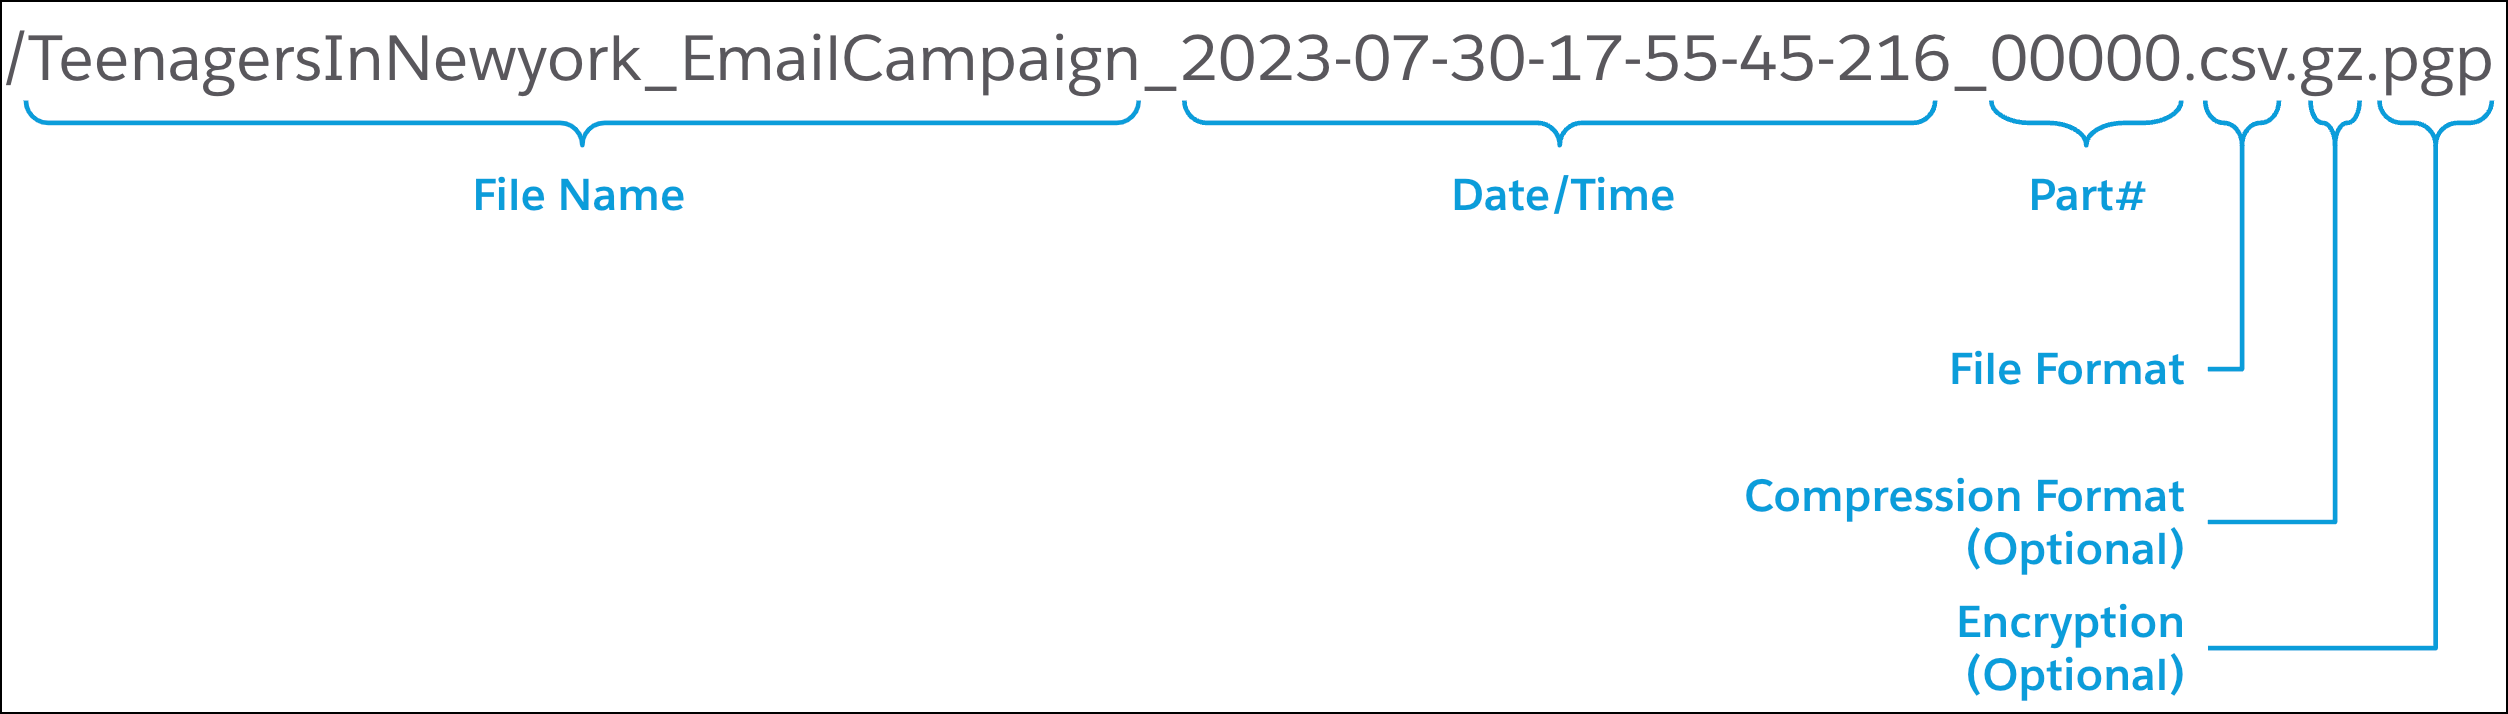
## Find Activated Files in Google Cloud Storage
After you create and activate segments/DMOs to Google Cloud Storage bucket, activated files are placed accordingly in the parent or child directory based on your configuration.
1. Access the Google Cloud Storage bucket.
2. Go to the bucket you configured in Google Cloud Storage.
3. Go to the path /Parent directory/Child directory/Automatic folder based on your configuration.
Activated files are created in the format: /FileName\_DateTimeSuffix\_Part#.FileFormat.CompressionFormat
CompressionFormat is optional.

Note The datetime suffix in the file name is provided in UTC time.
Example file name: /TeenagersInNewyork\_EmailCampaign\_2023-07-30-17-55-45-216\_00000.csv.gz

Important A system-generated folder named aws-datasync is created in the folder where the files are activated. Do not take any action on this folder as it will be removed automatically when there are no activations running.
## Find Activated Files in Microsoft Azure Blob Storage
After you create and activate segments/DMOs to the Microsoft Azure Blob Storage container, activated files are placed accordingly in the parent or child directory based on your configuration.
1. Access the Microsoft Azure Blob Storage container.
2. Go to the container you configured in Microsoft Azure Blob Storage.
3. Go to the path /Container path/Child directory/Automatic folder based on your configuration.
Activated files are created in the format: /FileName\_DateTimeSuffix\_Part#.FileFormat.CompressionFormat
CompressionFormat is optional.

Note The datetime suffix in the file name is provided in UTC time.
Example file name: /TeenagersInNewyork\_EmailCampaign\_2023-07-30-17-55-45-216\_00000.csv.gz

Important A system-generated folder named aws-datasync is created in the folder where the files are activated. Do not take any action on this folder as it will be removed automatically when there are no activations running.
#### See Also
- [_Salesforce Help_: File Name Examples (SFTP, GCS, Azure)](https://help.salesforce.com/s/articleView?id=data.c360_a_file_name_examples.htm&release=264.0.0&type=5 "Based on the values configured for the fields of your file storage activation target, here are some examples of file names for Data 360 external activations.")
# Find Data Cloud Segments in Marketing Cloud Engagement
After you create and activate segments to Marketing Cloud Engagement, view them in Contact Builder. A Data 360 segments subfolder is created when you publish your first activation.
### Required Editions
You can access the Engagement folders only in the Business Unit (BU) that your Engagement user is associated with. In Engagement, you can see the Data 360 segments for that BU in Contact Builder.
1. In **Marketing Cloud**, click **Contact Builder**.
2. Click **Data Extensions**.
1. Click **Shared Items**.
2. Click **Shared Data Extensions**.
3. Click **Customer 360 Segments**.
If a segment is activated to more than one BU, the activated segments are created as a shared data extension in the Data 360 subfolder. Shared data extension has the naming format segmentName\_activationName\_segmentID\_activationID. For the activation target, the shared data extension folder is based on the selected BUs. Child business units (MID) provide permission to the parent business unit (EID) by default. Any shared data extensions created on the MID can be accessed by the EID. If there are multiple MIDs, shared data extensions created on a specific MID can’t be accessed by users of other MIDs.
If the number of individuals in your Engagement segment is lower than the segment population in Data 360, try troubleshooting with tips from this knowledge article: [Data 360 segment counts do not match activation counts for a Marketing Cloud activation target](https://help.salesforce.com/s/articleView?id=000362648&type=1&language=en_US).
#### See Also
- [_Salesforce Help_: Create Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_add_activation_target.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
- [_Salesforce Help_: Marketing Cloud Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_cloud_data_sources.htm&release=264.0.0&type=5 "Connect Marketing Cloud Engagement to Data 360 using a starter data bundle or data extension.")
- [_Salesforce Help_: Data Extensions for Data 360](https://help.salesforce.com/s/articleView?id=mktg.mc_cab_c360a_data_extensions.htm&type=5&language=en_US)
# Find External Activation Platform Segments in Cloud File Storage
After admins install your external activation platform, you can receive segments to Cloud File Storage (Amazon S3). For each activation target, you receive a success file, metadata file, and activation output files once a day for each identifier type when the output is grouped by user identifiers (PER\_USER). Because files arrive only once a day, there’s a delay between Data 360 customers updating segments and those changes arriving to S3.
1. Log in to Cloud File Storage.
2. Go to the bucket that you provided in the Bucket Name field when you created your external activation platform.
3. Go to s3://{Bucket-Name}/{Date}/{Account-ID}/{Activation-Run-ID}/type={ID-Type}/.
Segments publish every 24 hours as multiple CSV, NDJSON, or Parquet files. Multiple partial files are delivered for each identifier type when the output is grouped by user identifiers (PER\_USER), and each partial file is an individually compressed GZIP file. When the activation output is grouped by segments (PER\_SEGMENT), the refresh schedule is tied to the segment publish schedule.
- **[External Activation Platform Files in Cloud File Storage](https://help.salesforce.com/s/articleView?id=data.c360_a_package_external_activation_platform_find_metadata_reference.htm&release=264.0.0&type=5)**
Learn more about the files delivered to Amazon S3 for your external activation platform.
# Find How Many Records of a Specific Type Synced Successfully
Determine how many records of a specific file type (for example, HTML, PDF, and images) from the Web Content (Crawler or Sitemap) connector were ingested.
Use this procedure to count the number of files that were ingested based on the file type. This is helpful to use when youget reports that images are not ingesting and you want to track the number of image files that are ingested.
1. From App Launcher, select **Data Cloud**.
2. Open the **Data Streams** tab, open the relevant data stream, and copy the data stream Object API Name, for example: `SffWeb-Crawler__dll`.
3. Open the **Query Editor** tab, and create a new query. Get familiar with the [Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_create_queries_a_query_editor.htm&language=en_US) to understand how to create queries.
4. For your new query, use the following format examples.
1. **HTML Pages**: `SELECT COUNT(*) FROM "" WHERE "ContentType__c" = 'html'`
2. **PDF Files**: `SELECT COUNT(*) FROM "" WHERE "ContentType__c" = application/'pdf'`
3. **Image Files**: `SELECT COUNT(*) FROM "" WHERE "ContentType__c" = 'image/png'`
#### See Also
- [_Salesforce Help_: Monitor the Status of Data Ingestion for Unstructured Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_the_status_of_unstructured_connectors_data_ingestion.htm&release=264.0.0&type=5 "You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.")
# Find Segments in Data Model Objects (DMOs)
After you create and activate segments to Data 360, you can find segments via the Query API or in Data 360.
### Required Editions
User Permissions
Needed
To view Data Explorer
One of these permission sets:
Data Cloud Architect
Data Cloud User
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. Navigate to the activation.
2. Click **Edit** and **Continue** to find the API Name of the Data 360 Object.
Save the API Name somewhere you can find it again.
3. Go to **Data Explorer**.
4. Select **Data Model Object** as the object type.
5. Select the object that matches the API Name of the Data 360 Object you saved from your activation.
Segment columns are based on the attributes selected when creating your activation.
#### See Also
- [_Salesforce Developer_: Retrieve Data with Query V1](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/data-cloud-query-api-reference/c360a-api-query.html)
# Find Your Instance and Endpoint Information
Data 360 runs on both Salesforce's first-party infrastructure and public cloud infrastructure, referred to as a functional domain (FD). Use these steps to find your Data 360 instance so that you can understand the impact when there’s an unforeseen incident or if you have a support case where additional information is required.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
To add or edit users
Manage Internal Users
Find your Data 360 Id, instance, and endpoint on the home page of Data Cloud Setup.
1. Go to **Data Cloud Setup**.
2. From the Setup Home and Set Up Your Data Cloud Instance, learn about your Home Org Id, Home Org Instance, and Tenant Endpoint.
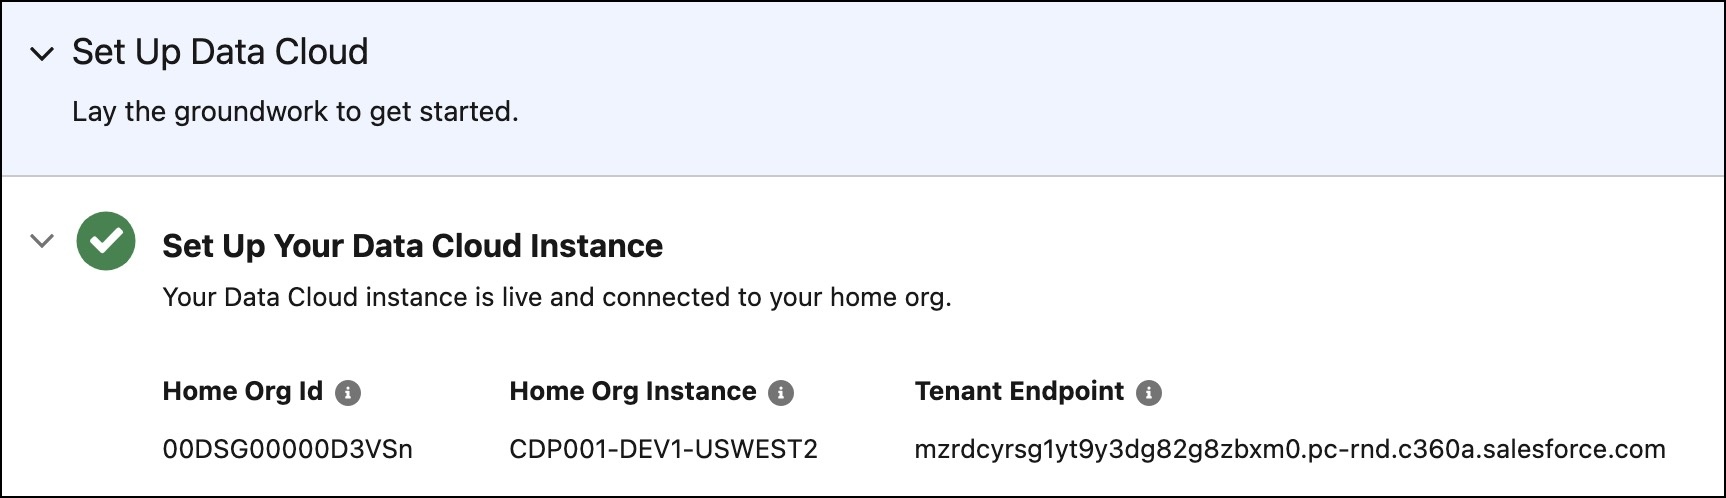
# Fiscal Calendar Options for Data 360 Queries
Use standard or custom fiscal calendar options to configure how Data 360 queries handle fiscal years. With these settings, you can align query results with your organization’s fiscal periods rather than calendar years.
Data 360 queries can group, sort, and filter data by using fiscal weeks, months, quarters, and years that match your business needs. Fiscal calendar options work with the `EXTRACT`, `DATE_PART`, `DATE_TRUNC`, `DATEDIFF`, and `DATE_ADD` functions when you use fiscal date units.
For examples using the fiscal calendar options, see Data 360 Query Guide: [Fiscal Calendar Options](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/dc-sql-reference/datetime-func.html#fiscal-calendar-options).
## Standard Fiscal Calendar Options
Use these options to configure a standard fiscal calendar with consistent rules:
- **fiscal\_year\_start\_month**: The first month of your fiscal year. Accepts values 1-12 (1=January, 2=February, and so on). The default is 1 (January). For example, if your fiscal year starts in April, set the value to 4.
- **first\_day\_of\_fiscal\_week**: The first day of your fiscal week. Accepts values 1-7 (1=Monday, 2=Tuesday, and so on). The default is 1 (Monday). The default is 1 (Monday).
- **use\_start\_date\_as\_fiscal\_year\_name**: This option controls fiscal year naming. Default is true. When true, a fiscal year starting April 1, 2020 is named "FY 2020." When false, the same period is named "FY 2021." The default is true.
## Custom Fiscal Calendar Option
For more complex fiscal calendars, use the **fiscal\_period\_table** option. This option uses a lookup table that maps each day to specific fiscal periods, enabling highly customized fiscal calendars that don’t follow standard patterns. The table must contain date-to-period mappings for each day in your fiscal calendar.
**Important**: Choose either the standard options or the custom table approach. You can’t combine both methods, as this causes configuration errors.
## Default Behavior
If you don't configure a fiscal calendar, queries default to the Gregorian calendar (January 1 to December 31). Updates to fiscal calendar settings can take up to 24 hours to appear in Data 360 queries.
#### See Also
- [_Salesforce Help_: Set the Fiscal Year](https://help.salesforce.com/s/articleView?id=xcloud.setting_the_fiscal_year.htm&language=en_US)
- [Data 360 Query Guide: Date/Time Functions and Operators](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/dc-sql-reference/datetime-func.html#fiscal-calendar-options)
# Flatten Hierarchical Data
Use the flatten transformation to simplify nested, hierarchical data by converting it to a list. The list tracks where each node and the ones preceding it (referred to as its ancestors) appear within the hierarchy. To flatten data, specify the field that contains every node in the hierarchy and the field that contains their corresponding parent. After you run the transform, each record contains the list of ancestors.
The number of hierarchical levels that you can flatten in a data source depends on the number of rows that it contains.
- 300 levels for over 1 million rows
- 100 levels for 15 million rows
- 50 levels for 20 million rows (the maximum)
1. In a transform node, click the Flatten button ().
2. For Record ID Column, select the column that contains all the nodes in the hierarchy.
3. For Parent ID Column, select the column that contains the parent of each node in the hierarchy.
To include the record ID in the generated column that contains the hierarchy nodes, select **Include Record ID Column Value**.
4. For Hierarchy Column Label, enter a name for the generated column of hierarchy nodes.
5. Preview the transformation results.
Preview shows only the record ID and its parent in the hierarchy column. You see all ancestors when you run the data transform.
6. Click **Apply**.
To collapse the view and see the canvas, click the Collapse button ().
7. To generate the hierarchy column, run the data transform.
# Flatten JSON Data
Turn data ingested as a JSON string into tabular data in a batch transform. To use data in downstream features, such as identity resolution and segmentation, the data must be stored as rows and columns in a data lake object or data model object. You can flatten JSON data that’s stored as a single object, an array of objects, or an array of literals (scalar values).
A schema file describing the structure and content of the JSON data is required to flatten nested JSON. This file can be created manually or generated from a sample of your JSON data using a web utility.

Note :
Only the 'type', 'properties', and 'items' keywords are recognized from the schema file; all others are ignored.
The row will not be processed and included in the results if the JSON data is malformed.
The maximum JSON level limit is 6. The 'properties' keyword has a maximum limit of 50.
1. In a transform node, select the input field containing the JSON data you want to flatten, and then select the Flatten JSON transformation.
2. Select **Upload File**, and select your JSON schema file.
3. Enter a transformation name.
4. Add at least one output table.
1. Select **Add New Table**.
2. Enter a name for the table.
3. Select one or more fields to extract from the JSON data.
5. To save the configuration, click **Apply**.
6. To preview table data, add a node to the output branch for that table.

Example Your data table includes the fields `order_id` and `json_data`. `Order_id` contains an integer that identifies the order. `Json_data` contains JSON data strings with important information about each order. You want to extract data about orders into tables so that you can calculate insights, such as customer lifetime value.
| order\_id | json\_data |
| --- | --- |
| 1 | {"customer": "John", "items": \[{"id": 101, "name": "Laptop", "price": 1500}, {"id": 102, "name": "Mouse", "price": 20}\]} |
| 2 | {"customer": "Alice", "items": \[{"id": 103, "name": "Keyboard", "price": 50}, {"id": 104, "name": "Monitor", "price": 300}\]} |
To ensure that Data 360 can properly interpret your JSON data, upload a schema file that conforms to the JSON schema specifications. This sample schema file describes the data in the data table.
```
{
"type": "object",
"properties": {
"customer": {
"type": "string"
},
"items": {
"type": "array",
"items": {
"type": "object",
"properties": {
"id": {
"type": "number"
},
"name": {
"type": "string"
},
"price": {
"type": "number"
}
},
"required": ["id", "name", "price"]
}
}
},
"required": ["customer", "items"]
}
```
# Flex Credits Billable Usage Types for Data 360
Usage of certain Data 360 features impacts credit consumption. To monitor your usage in Flex Credits usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.
Review your org’s licenses and Digital Wallet to determine how your org is billed.
- If your org operates Data 360 under a Customer Data Platform license, refer to [Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&language=en_US&type=5) instead.
- If your org operates under a Data Cloud license and has an active Data Services consumption card, refer to Data Services Billable Usage Types for Data 360 instead. If you also have a Data 360 Profiles license, some usage is unmetered. Refer to Data 360 License Billing Considerations for details.
- If your org operates Data 360 under a Data Cloud license but doesn’t have an active Data Services consumption card, this article describes how credits are consumed.
The number of credits consumed is based on the number of units of each usage type used multiplied by the multiplier listed on the rate card for the usage type.
Actual usage is summed for each usage type and credits are decremented at a fractional rate. The minimum number of credits decremented from a usage type is 1, where fractional usage amounts to 1 or more credits over the monthly billing period.
## Data 360 Profiles Licenses
If a Data 360 Profiles or Data 360 Enterprise Profiles license is added to your Data 360 org, some features stop consuming credits. Refer to Data 360 Profiles License Billing and Limits for more details or review the feature’s Billing Considerations article.
## Flex Credits Usage Types for Data 360
Service usage calculations are based on records processed, queried, or analyzed. Service usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
In Digital Wallet, Data 360 consumption for customers with Flex Credits is tracked on the Flex Credits consumption card in the following usage types.
Billing Category
Description
Data 360 Prep
Usage is calculated based on the data object type.
For local data lake objects and data model objects, the number of rows used for billing
calculations is limited to the number of rows in the object.
For external data lake objects, the actual count of rows read or written is used. This
number can exceed the number of rows in the object if an object’s rows are read multiple
times in a single transform run.
For incremental batch transforms, after the first time a transform runs, usage is
calculated based on the number of rows that changed since the previous run.
For batch calculated insights, usage is calculated based on the number of records in all
underlying objects used in creating the Calculated Insight each time it runs.
Data 360 Unification
Usage is calculated based on the number of source profiles processed by an identity
resolution ruleset. After the first time a ruleset runs, only new or modified source
profiles are counted. A source profile is an individual and their related records, such as
contact points and party identifiers, which are included in the identity ruleset.
For example, modified means deleted profiles, or profiles marked as suppressed via
Consent API preferences.
Data 360 Segmentation
Usage is calculated based on the number of records processed by a Data 360
segment.
Data 360 Activation
Usage is calculated based on the number of records processed for a Data 360
activation.
Data 360 Zero Copy Sharing-Out
Usage is calculated based on the number of rows returned to fulfill an external
data lake’s data share request. The number of rows accessed depends on the structure of the
query and isn’t the same as the number of rows in the source data.
For data sharing
between Data Cloud orgs, this usage type applies to the target org for all
queries.
Data 360 is hosted only on Amazon Web Services (AWS) across multiple AWS
regions. Same region is when Data Cloud and the data share target are hosted in the same
AWS region. Same cloud is when Data Cloud and the data share target are hosted on the same
cloud.
Data 360 Queries
Usage is calculated based on the number of records processed.
The count of records processed depends on the structure of a query as well as other
related factors such as the total number of records in the objects being queried.
When an object is queried in the context of a data space, the number of rows processed is
based on the total number of processed rows in the source object, not the number of rows
pertaining to the particular data space
Data 360 Unstructured Processing
Usage is calculated based on the amount of unstructured data that is processed
without using AI assisted content processing and extraction. For example, if the search
index processes 100 PDF documents that are 1 MB each, usage is calculated as 100 MB. If the
search index processes five audio/video files that are on average 100MB each, usage is
calculated as 500MB.
In Data Cloud, unstructured data may be chunked and vectorized
using an embedding model. Usage is computed only once across both these activities. For
example, if one 100 MB PDF document is chunked and vectorized, usage is computed as 100 MB,
not as 200MB.If you create a search index that uses a data model object (DMO) as a data
source and select Text data type fields from the DMO, all strings from those fields are
indexed and the sum total of all bytes processed is reported as Unstructured Data
Processed.
Data 360 Intelligent Processing
Usage is calculated based on the
amount of unstructured data that is processed using AI-assisted features such as LLM-based
parsing, LLM-based visual data preprocessing, image processing, Enriched Indexing, and
Intelligent Context.
Data 360 Streaming Pipeline
Usage is calculated based on the data object type.
For streaming data ingestion, usage is calculated based on the number of rows of
streaming data processed by Data 360 across all data streams with stream processing, with
the exception of structured data that is ingested via the Internal Data Pipeline.
Data streams that report usage with this usage type are streams created by Website and
Mobile App Connector, and the ingestion API when used in streaming mode. Bulk mode of
ingestion API is not included.
For streaming data transforms, usage is calculated based on the higher of the number of
rows read or the number of rows written.
When performing joins, the number of rows read is calculated by multiplying the number of
records from the streaming input object by the number of joined objects.
For streaming calculated insights, usage is calculated based on the number of records
processed.
For streaming data actions, usage is calculated based on the number of records processed
in the DMO. Records processed are based on the number of new records created or updated in
the DMO per activation.
If a data graph is being used with the activation, the number of records processed will
be doubled in the final calculation. For example, when a data graph is being used with the
activation, if there is 1 new record change in the DMO, this will count as 2 records
processed.
Data 360 Real-Time Pipeline
Usage is calculated based on the sum of the number of profile events, engagement events,
and API calls processed in the sub-second real-time layer, including accelerated data
ingest, web and mobile SDKs traffic, server to server API traffic, and real-time ingestion
API. Profile events, engagement events, and API calls are processed in the real-time layer
if they are associated with a real-time data graph.
For example, if 3 profile events, 10 engagement events, and 20 API calls are processed
during a particular billing period, the total processed is 33.
Data 360 Code Extension
Usage in this type is measured in Compute Units. The number of Compute Units consumed
per hour depends on the compute size selected. The total number of Compute Units is
calculated based on the hourly consumption rate and the total compute time your code
consumes.
For information about Flex Credits usage types for Agentforce and Speech Foundations, see [Flex Credits Billable Usage Types for AI](https://help.salesforce.com/s/articleView?id=ai.usage_flex_credits.htm&type=5&language=en_US).
To review current and historical standard rates and multipliers, see [Data 360 Multipliers](https://www.salesforce.com/data/rates/multipliers/). Review your contract to determine your contracted rates.
## Data Storage Allocation
Storage refers to the amount of data stored in Data 360. Storage used outside of Data 360, such as data stored on the Salesforce Lightning Platform, isn't counted toward this limit. Storage usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
| Billing Category | Description |
| --- | --- |
| Storage Beyond Allocation | Usage is calculated based on the amount of storage used above the amount allocated. |
## Data Spaces
Data space usage applies to Data 360, Data 360 for Marketing, and Data 360 for Tableau customers.
| Billing Category | Description |
| --- | --- |
| Data Spaces | Usage is calculated based on the number of data spaces beyond the default data space. |
## Ad Audiences Service Usage
Service usage calculations for ad audiences are based on the number of audiences.
| Billing Category | Description |
| --- | --- |
| Ad Audiences | Usage is calculated based on the number of ad audience targets. |
# Follow Steps to Ingest Google Analytics into Data 360
Connect your CRM and Google Analytics data in Data 360 using the following configurations. This multi-step solution includes multiple roles and permission sets to complete steps in Data 360, Sales Cloud or Service Cloud, CRM Analytics, and Google Analytics.
### Required Editions
 Bookmark this page or keep it open in a separate window to refer to this topic.

Note Steps and links outside of Salesforce content may not be updated or accurate.
## Step 1: Connect Google Analytics Data to Google BigQuery
Start by connecting the Google Analytics Connector to Google BigQuery.
1. Set up BigQuery Export in Google APIs Console (Google Analytics Administrator—5 minutes).
2. [Link BigQuery to Google Analytics](https://support.google.com/analytics/answer/3416092?hl=en#step3) in Google Analytics (Google Analytics Administrator—5 minutes).
## Step 2: Link Salesforce Data with Google Analytics
Linking Salesforce data with Google Analytics data ensures that you have access to the most up-to-date information. To link this data, create a connection to link Google Analytics data to the CRM Analytics Data Manager.
1. To sync Google Analytics data to CRM Analytics in CRM Analytics Data Manager, create a [Google Analytics 4 Connection](https://help.salesforce.com/s/articleView?id=analytics.bi_integrate_connectors_ga4_settings.htm&type=5&language=en_US) in CRM Analytics (System Admin or Data Cloud Architect-5 minutes).
2. Filter out data activity for authenticated users that is ingested into Data 360 with the Measurement Protocol User-ID (UID) integration method. From the Google page, [Measurement Protocol](https://developers.google.com/analytics/devguides/collection/protocol/ga4) (Google Analytics 4) learn how to use measurement protocols to record events to Google Analytics for use in reports.
3. [Set up User-ID](https://support.google.com/analytics/answer/3123666?hl=en&ref_topic=3123660#zippy=%2Cin-this-article) and then implement it in your tracking code in Google Analytics (Google Analytics Editor—5 minutes).
## Step 3: Set Up the Google Cloud Storage Connection
Now connect Google Cloud Storage to Data 360.
[Set Up a Google Cloud Storage Connection](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-set-up-gcs-connection.html) in Data 360 (Data Cloud Architect—5 minutes).
## Step 4: Import Data from Google Cloud Storage
Ingest and map data into Data 360.
1. [Create a Google Cloud Storage Data Stream](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-gcs-data-streams.html) in Data 360 (Data Cloud Architect—5 minutes).
2. [Map the fields to a data model object (DMO)](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&type=5&language=en_US) in Data 360 (Data Cloud Architect—5 minutes).

Note If you’re bringing custom attributes into Data 360 from Google Analytics, create custom DMOs to support those attributes. See [Create a Custom Data Model Object from an Existing Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_dmo_from_existing.htm&type=5&language=en_US) in Salesforce Help.
## Step 5: Schedule Recurring Queries in Google BigQuery
After you bring data from Google Analytics to Salesforce Data 360, we recommend scheduling queries in BigQuery to bring only incremental data into Data 360.
[Link BigQuery to Google Analytics](https://support.google.com/analytics/answer/3416092?hl=en#step3) in Google Analytics (Google Analytics Administrator—5 minutes).
Considerations
- When you create or update a query schedule, the scheduled time for the query is converted from your local time to UTC. Your query’s schedule is still shown in your local time zone.
- The Google Cloud console doesn’t support changing the credentials used in a scheduled query to a service account.
- Cross-region queries aren’t supported.
# Forecasting
Use forecasting in Data 360 to predict future values from historical data. Forecasting models automatically identify trends and seasonal patterns to generate predictions without requiring data science expertise.
The default algorithm is Holt-Winters and it’s best suited for structured time-series data with clear trends and recurring seasonal patterns. For example, retail sales that peak each quarter or monthly revenue that grows steadily over time.

Note
All forecasting models and algorithms use the new runtime.
Forecasting supports various use cases.
- **Revenue forecasting**: predict future revenue trends with historical performance data
- **Demand planning**: estimate product or service demand across time periods
- **Sales trend analysis**: identify growth or decline patterns in pipeline or bookings
- **Capacity planning**: forecast resource needs based on historical usage trends
- **Seasonal pattern analysis**: analyze recurring peaks and dips in business activity
Single-variate forecasting enables these use cases by using one historical variable. For example, forecast next month's revenue by using only past revenue data when a clearly defined metric exists.
## How Forecasting Works
Forecasting models learn from historical time-series data—a sequence of values recorded at regular intervals, such as daily sales or monthly revenue. The model identifies patterns, such as trend direction and seasonality, and projects those patterns into the future to generate predictions.
Forecast outputs include prediction intervals that represent uncertainty in the forecast. The upper and lower bounds define the range of expected values, where narrower ranges indicate higher confidence.
Each forecasted record includes these outputs:
- Forecasted value—the predicted value for each future time period
- Forecast upper bound—the high end of the predicted range
- Forecast lower bound—the low end of the predicted range
Review these forecasting concepts.
**Partition columns** define how Data 360 groups data for forecasting. For example, when forecasting revenue by account, the account field is the partition column. Each model supports up to five partition columns, enabling segmented forecasting across multiple dimensions.
**Time-series grouping** defines the aggregation interval for the data, such as minute, day, month, or year. The model automatically infers forecasting frequency from this grouping, and you don't configure it separately.
**Seasonality** captures recurring patterns that repeat over a fixed interval, such as weekly traffic spikes or quarterly sales increases. Define seasonality manually for up to 24 periods.
**Null handling** imputes missing values in training data automatically with the built-in imputation method. The model uses imputed values only during training and doesn't write them to forecast outputs.
## Considerations
Review these considerations.
- Forecasting inference consumes the inference billing meter.
- Batch transform forecasting also consumes the Data Transform—Batch meter based on rows processed.
- If missing values aren't reliably imputed, forecasting inference stops.
- **[Use Single Variate Forecasting](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_forecast_holt.htm&release=264.0.0&type=5)**
Predict future values based on historical patterns in a single variable by using the Holt-Winters algorithm. For example, use a data transform to forecast sales by account based on opportunity data.
# Format Dates Transformation: Standardize the Date Format in a Column
Standardize the format for all dates in a text column with the Format Dates transformation. With a consistent format, you can correctly filter and group records by date, including filtering by date component, such as month. A consistent format also ensures that you can successfully convert the column type from Text to Date.
1. In a Transform node, select the text column that contains dates in the Preview tab.
2. In the Transform toolbar, click the **Format Dates** button ().
3. Enter the original date formats in the selected column. The Date Format transformation assumes the first matching format shown in the Original Formats search box is the correct one. For example, if a date is 01/06/2023, the date format could be `dd/MM/yyyy` or `MM/dd/yyyy`.
4. Select the desired date format in the **Change To** field.
5. To convert a text column with dates to a Date column type, select **Convert column type to Date**.
6. Under **Show Results In**, select whether the new values appear in a new column and whether to keep the original column.
7. If you elect to create a column, set the label under **Column Label**.
8. To add the transformation to the Transform node, click **Apply**.
9. To view the canvas area, click the **Collapse** button ().
When you run the batch data transform, the transformation replaces the dates in the existing column with dates in the specified format. If the transformation can't determine the date's original format or the date doesn’t have a value for a date component, then it replaces the date with null. For example, if you standardize on the `MM/dd/yyyy:hh:mm:sssz` format and a date value doesn’t have the seconds date component (`sssz`), then the transformation replaces the date with null.
# Formula Expression Use Cases
These examples show use cases of formula expression functionality in Data 360.
- **[Use Case 1: Create a State-Specific Primary Address Flag](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_1.htm&release=264.0.0&type=5)**
This use case creates a flag for customers who live in a specific state.
- **[Use Case 2: Create a Primary Key Using a Composite Key](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_2.htm&release=264.0.0&type=5)**
This use case creates a composite key and sets a formula field as the primary object.
- **[Use Case 3: Set a Hard-Coded Value for the Organization Unit Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_3.htm&release=264.0.0&type=5)**
This use case sets a hard-coded value for the Organization Unit Identifier in Object Details and allows you to specify a business unit in your Data 360 data.
- **[Use Case 4: Convert Hours in the Day to Day Parts](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_4.htm&release=264.0.0&type=5)**
This use case converts hours in the day into day parts; for example, morning or afternoon.
- **[Use Case 5: Calculate Revenue](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_5.htm&release=264.0.0&type=5)**
This use case calculates revenue by a defined margin.
- **[Use Case 6: Add the Date and Time Field to Engagement Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_6.htm&release=264.0.0&type=5)**
This use case locates engagement streams that have no set date and updates them since a date is required.
- **[Use Case 7: Create Required Party Identifier Formula Fields for Mobile](https://help.salesforce.com/s/articleView?id=data.c360_a_use_case_7_create_party_identifier_formula_fields_for_mobile.htm&release=264.0.0&type=5)**
This use case creates required party identifier formula fields to match on the Identity data stream.
# Formula Transformation: Create a Calculated Column Based on an Expression
Create a column that displays values based on a formula calculation. The calculation can include input from other columns in the same row or across rows. For example, you can create a Profit column based on input from Revenue and Cost columns. Enter formulas in SQL. SQL in Data 360 is a collection of standard and custom functions for numeric, string, and date data.
1. In the Transform node, select the column in the Preview tab.
2. To create the formula for the calculated column, select the **Formula** button () in the Transform toolbar and select **Custom Formula**.
3. In the formula editor, enter the formula and add parameters using the correct syntax.
As you type in the formula editor, functions and columns matching the name appear for you to select to add to the formula.
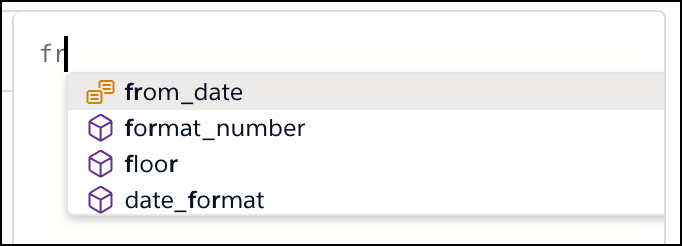

Note The best practice is to use double quotes around all column names. For a value that is a string literal, use single quotes.
Double quotes are required when referencing dataset columns that share a name with reserved keywords.
To get help, check out all functions and columns in the Functions and Columns tabs. To add one to the formula, select it and click **+**.
Functions are listed in the Functions tab by category: Window Functions, String Functions, Numeric Functions, Date/Time Functions, and Additional Functions. To view the window functions, enable **Multiple row formula**.
4. For formulas with window functions, specify the column used to partition the rows in **Partition By**, column used to sort the data in **Order By**, and sort direction in **Sort Direction**.
For example, set Partition By to Opportunity Name, Order By to Last Modified Date, and Sort Direction to Ascending. Based on these settings, the transformation combines all records into partitions (think buckets) based on the same opportunity name. It then sorts the records in each partition in ascending order based on the last modified date.
5. Identify each column in the formula by its API name. Type in the API name or select the column from the **Columns** tab.
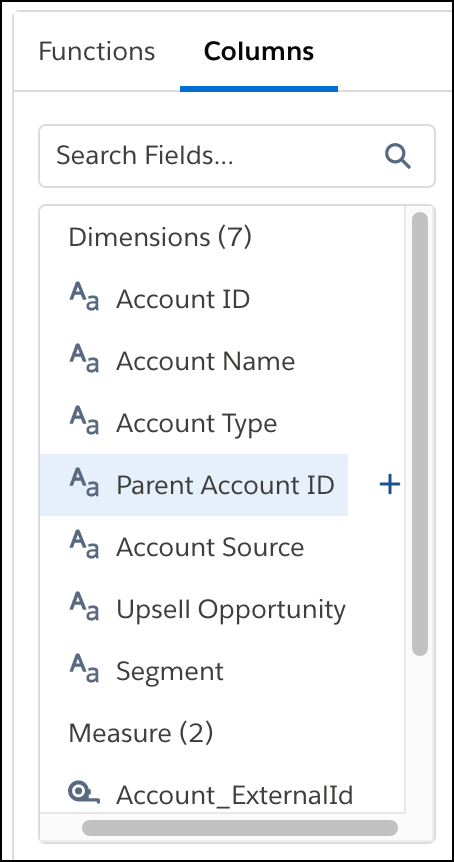
6. In **Output Type**, select whether the calculated column’s data is text, numeric, date, or datetime.
7. Based on the output type, you can set these attributes.
| Attribute | Description |
| --- | --- |
| Precision | The maximum number of digits in a numeric column. Includes all numbers to the left and to the right of the decimal point (but excludes the decimal point character). Enter an integer from 1 through 18, inclusive. |
| Scale | The number of digits to the right of the decimal point in a numeric column. Enter an integer from 0 through 17, inclusive. The scale must be less than the precision. For example, if the numeric value is 123456.789 and you set the scale to 2, the number appears as 123456.78. |
| Length | The maximum number of characters in a text column. Enter an integer from 1 through 32000, inclusive. The default length is 255 characters. |
| Date Format | The date format of a date column. |
8. In **Default Value**, choose the value to show if your expression returns no results.
9. If needed, you can change the label of the calculated column.
10. To add the formula as a step in the Transform node, click **Apply**. The calculated column appears in Preview.
11. To view the canvas, click the **Collapse** button ().
12. Save the data transform.
You can bucket a formula column or reference it in later formulas defined in the data transform.

Tip Common functions have their own buttons in the Transform toolbar that automatically fill in the formula with the column and predefined syntax. The toolbar shows appropriate functions based on the type and number of selected columns. To use one, click the function button in the Transform toolbar (1). The formula is started for you (2), using the column and function that you selected.
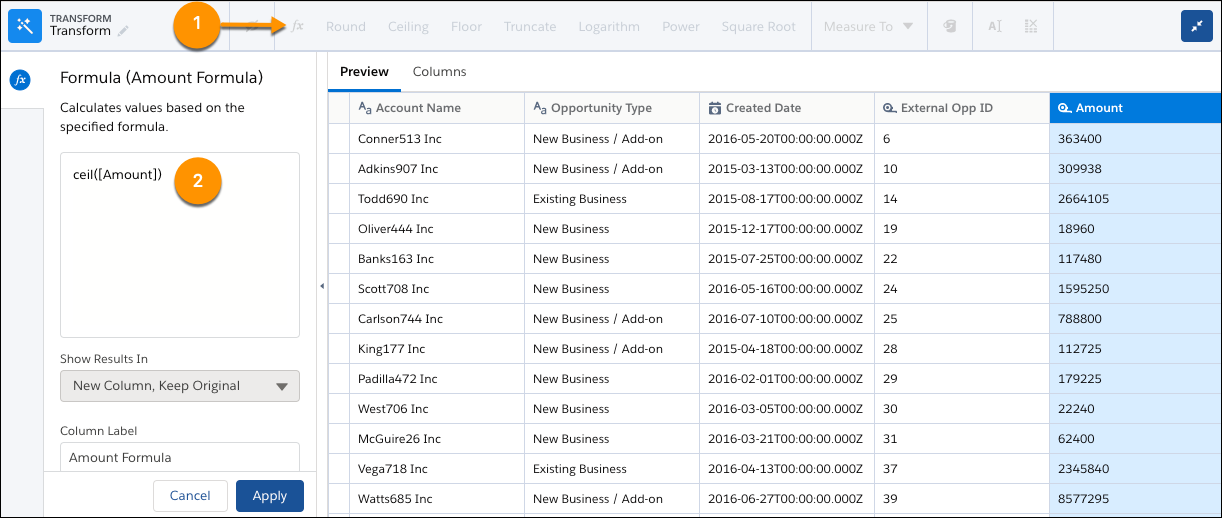
- **[Date Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_date_functions.htm&release=264.0.0&type=5)**
Use date functions to adjust or calculate values from dates. For example, you can add time, find time until, and extract a day of the week from date fields. The arguments for date functions are date fields.
- **[Numeric Operators and Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_numeric.htm&release=264.0.0&type=5)**
Use numeric functions to calculate values from measures. For example, you can round, truncate, and determine the absolute value of a number. The arguments for numeric functions can be numbers or measure fields.
- **[String Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_string.htm&release=264.0.0&type=5)**
Use a string function to manipulate the text data type, including email, phone, time, and date values. For example, change text from uppercase to lowercase, concatenate values from multiple fields, and replace values.
- **[Window Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_window.htm&release=264.0.0&type=5)**
Use window functions to perform calculations across rows. For each row of input data, perform a calculation on a selection—or window—of related rows. Unlike aggregation functions that group rows, window functions return a result for each row. For example, you can calculate the changes to the opportunity amount throughout the stages of each opportunity to see if you can hit your sales target.
- **[Multivalue Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_multivalue_functions.htm&release=264.0.0&type=5)**
Multivalue data is limited to use in formulas. To work with multivalue data in downstream processes from batch data transforms in Data 360, such as reporting in CRM Analytics, convert it into a string.
- **[Additional Functions for Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_additionalfunctions.htm&release=264.0.0&type=5)**
To build logic into formulas, use these functions with the text, number, and datetime data types.
# Formulas, Operators, and Calculated Insights
Create audiences in different ways and at different stages of your workflow using formulas, operators, and calculated insights in Data 360. During ingestion, you can use formulas to perform operations on row-based data used downstream. For segmentation, audiences are created with segment operators.
With calculated insights, you can use views to understand large-scale behavioral data and reuse views to enhance segmentation. You can also find insights in business intelligence tools. Which option you use to perform a data transformation depends on your use case and the type of data.
## Formulas
A formula is good for calculating different data types but requires advanced knowledge. A formula is derived from other source fields, but you can use hardcoded values.
It’s recommended to use a formula when a simple row-based operation is used to abstract logic that the user can consume and use at segmentation time. A row-based calculation applies logic to self-contained rows as opposed to aggregating across rows. For example, an IF formula that changes “Shoe” to “Shoes” works because the result is static. But finding the number of days since January 1 doesn’t work because the number of days changes over time. The calculation occurs only at ingestion time and is a stored calculation, not a run-time calculation. Formulas don’t automatically update.
This table summarizes when to use a formula.
| Use Case | Formula |
| --- | --- |
| Simple logic on a row-based operation |  |
| Ease of use and self-service |  |
| Highly reusable content |  |
| Attribute updated regularly |  |
## Segmentation Operators
Use an operator to complete self-service filtering use cases without the help of a data analyst. Segmentation operators are a good choice for:
- Simple aggregations, like count, on one object
- Max, min, avg, and sum aggregations on numbers when the conditions are simple and unlikely to be reused often
- Filtering on 2 years or less of aggregation data
If segmentation operators don’t fully support your use case, use a calculated insight instead. For example, the max operator on dates is available only with a calculated insight, for example, finding the last purchase date of shoes. Use a calculated insight for max, min, avg, and sum aggregations on numbers that are reused among segments or if they have a long list of other attributes as part of the filter container.
This table summarizes when to use a segmentation operator.
| Use Case | Segmentation Operator |
| --- | --- |
| Ease of use and self-service |  |
| Highly reusable content |  |
| Attribute updated regularly |  |
## Calculated Insights Functions
To understand customer behavior, use a calculated insight at the customer or entire population level with multiple dimensions, such as customer, channel, and product attributes. You define and calculate multidimensional metrics, such as recency, frequency, monetary value (RFM), and customer lifetime value (CLV). After the metrics are calculated, they can be automatically refreshed daily so that you’re operating on the most recent information for your channel, customers, or products.
Calculated insights make it easy for users to define segment criteria and personalization attributes for activation using metrics, dimensions, and filters. Calculated insights are best used for:
- Nontrivial calculations, such as calculating a net promoter score as a percentage
- Complex queries across multiple objects
- Reusability, such as when you expect a view to be used multiple times across different values or when combining related attributes in the same view
For example, you want to find web page views and page clicks that belong to the same view and a product category that changes as a dimension. If implemented using segmentation, you must redefine the conditions every time there’s a change. With a calculated insight, after the dimensions are set on the view, you can reuse the dimensions as needed. Because you can only have a maximum of 50 measures and 10 dimensions, you can organize the view to have different views and group metrics together on the relevant object. If possible, avoid having a view include different channels in which all the engagement is in one cross-channel view.
This table summarizes when to use a calculated insight.
| Use Case | Calculated Insight |
| --- | --- |
| Simple logic on a row-based operation |  |
| Ease of use, self-service |  |
| Highly reusable content |  |
| Attribute updated regularly |  |
# Full Outer Join
A full outer join includes all rows from the left and right input data source objects, regardless of whether they have matches. The join includes all matched rows in the output data when multiple rows match.

Example
Our company's marketing team captures demographic data in Redshift for opportunities stored in Salesforce. To help create more targeted campaigns, the team is segmenting our current opportunities by the Education Level demographic. Let’s use a full outer join to combine the opportunity and demographic data.
Consider the following two input data sources that feed the batch data transform's output data. To illustrate how the full outer join handles unmatched rows and duplicate keys, we included them in both input data source objects.
After performing the full outer join based on the matching the keys, the data transform produces the following output.
All rows—matched or not—are included in the output. Because of multiple matches, you see two records with `Opp_ID` 2 (Amy and Bob) and two more records with `Opp_id 1` (High School and Secondary School). `Opp_ID` 4 and `Opp_id` 5 are also included despite not having a match.
By including unmatched left records, we now know that we have to find out David’s education level to complete the output data. By including unmatched right records, we see that no customers have a PhD.
# Full Refresh
Learn more about the Full Refresh extract method in Data 360 and when to use it.
The full snapshot option called Full Refresh, guarantees that all data for all time is sent continuously.

Note The Full Refresh extract method can be used on data of 100 million rows or smaller. For larger data groups, use either Delta Extract by Date or by Number.
Use Full Refresh when you expect data to change frequently but the magnitude of data is reasonably static, for example, with audience membership.
# Fully Qualified Keys
Use Fully Qualified Keys (FQK) to avoid key conflicts when data from different sources are harmonized in the Data 360 data model.
Configure key qualifier fields for all data lake object (DLO) fields that contain a key value to use FQKs. The field can be a primary key or a foreign key field.
- **[Data Interpretation with Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_data_inter_fqk.htm&release=264.0.0&type=5)**
Fully qualified keys help to accurately interpret data ingested from different sources. Each data stream is ingested into Data 360 with its specific keys and attributes. When multiple data streams are harmonized into a single data model object (DMO), the various keys can conflict and records can have same key values. Fully qualified keys avoid conflicts by adding key qualifier fields and interpreting the data accurately.
- **[Best Practices for Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_key_qualifier_best_practices.htm&release=264.0.0&type=5)**
Use fully qualified keys (FQKs) to help Data 360 accurately interpret data ingested from different data sources.
- **[Fully Qualified Keys in Data Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_dlo_dmo_key_qualifiers.htm&release=264.0.0&type=5)**
Data 360 adds key qualifier fields to data lake objects (DLOs) and data model objects (DMOs). Key qualifier fields can also be added when you create object relationships and object mappings between DLOs and DMOs.
- **[Fully Qualified Keys for Query API](https://help.salesforce.com/s/articleView?id=data.c360_a_query_api_key_qualifiers.htm&release=264.0.0&type=5)**
Use Query API to query data in Data 360. Identify key qualifier fields in a data lake object with the Data 360 Metadata API, and include key qualifier fields in all table joins to get accurate results.
- **[Configure a Key Qualifier Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_or_view_key_qualifier.htm&release=264.0.0&type=5)**
After creating a data stream, add key qualifiers to your data lake object (DLO) fields to create fully qualified keys (FQK). Configure key qualifiers for all DLO fields that contain either a primary or foreign key. You can add up to 20 active key qualifiers. A key qualifier is active when it's used for a DLO field. Data 360 automatically adds and removes key qualifiers to and from data model object (DMO) fields. You can't edit these system fields.
- **[Remove or Delete a Key Qualifier](https://help.salesforce.com/s/articleView?id=data.c360_a_remove_and_delete_key_qualifier.htm&release=264.0.0&type=5)**
To reduce clutter and avoid reaching your org's limit for key qualifiers, remove and delete unnecessary key qualifiers from the system. To delete a key qualifier, first remove it from all the data lake object (DLO) fields that it’s associated with and then delete it. You can also just remove a key qualifier from a DLO field but not delete it from the system. Removing a key qualifier from a DLO field can potentially affect the accuracy of calculated insights, segments, activations, and API queries.
# Fully Qualified Keys for Query API
Use Query API to query data in Data 360. Identify key qualifier fields in a data lake object with the Data 360 Metadata API, and include key qualifier fields in all table joins to get accurate results.
Query API supports SQL queries in ANSI standard. Use supported query API versions to set up table joins that include key qualifier fields to query data accurately.
#### See Also
- [_Salesforce Developer_: Query Data Using Query API V1](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_query_call_overview.htm)
- [_Salesforce Developer_: Query Data Using Query API V2](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_query_v2_call_overview.htm)
# Fully Qualified Keys in Data Objects
Data 360 adds key qualifier fields to data lake objects (DLOs) and data model objects (DMOs). Key qualifier fields can also be added when you create object relationships and object mappings between DLOs and DMOs.
## Key Qualifier Fields in DLOs
Data 360 adds key qualifier fields to DLO fields that contain either a primary key or a foreign key. The default value stored in a key qualifier field is null. You must create and configure key qualifiers for each DLO field that contains either a primary or foreign key.
A DLO’s primary key field is determined when the DLO is created. Data 360 determines that a DLO field is a foreign key field when the field is mapped to a DMO field and the DMO field is included in an object relationship.
Data 360 also adds field mappings between DLO and DMO key qualifier fields. These mappings are internally managed and aren’t listed on the field-mapping page.
## Key Qualifier Fields in DMOs
Data 360 adds a key qualifier field for each primary key field in a DMO and for each DMO field that’s participating in an object relationship. However, regardless of how many relationships a specific DMO field is part of, the field has only one key qualifier field.
When a new DMO is created, a key qualifier field is automatically added to the DMO’s primary key field. When a new object relationship is activated, key qualifier fields can be added to the DMOs that are linked in the object relationship if those DMO fields don’t have corresponding key qualifier fields. Key qualifier fields and their associated DMO fields are listed in the Key Qualifier column on the DMO record home page.
Because a fully qualified key is composed of a source provided key and a key qualifier, a DMO relationship also uses a composite key consisting of a key field and a key qualifier field. On the DMO record home page, the object relationship summary view shows the key qualifier fields that are part of each object relationship.
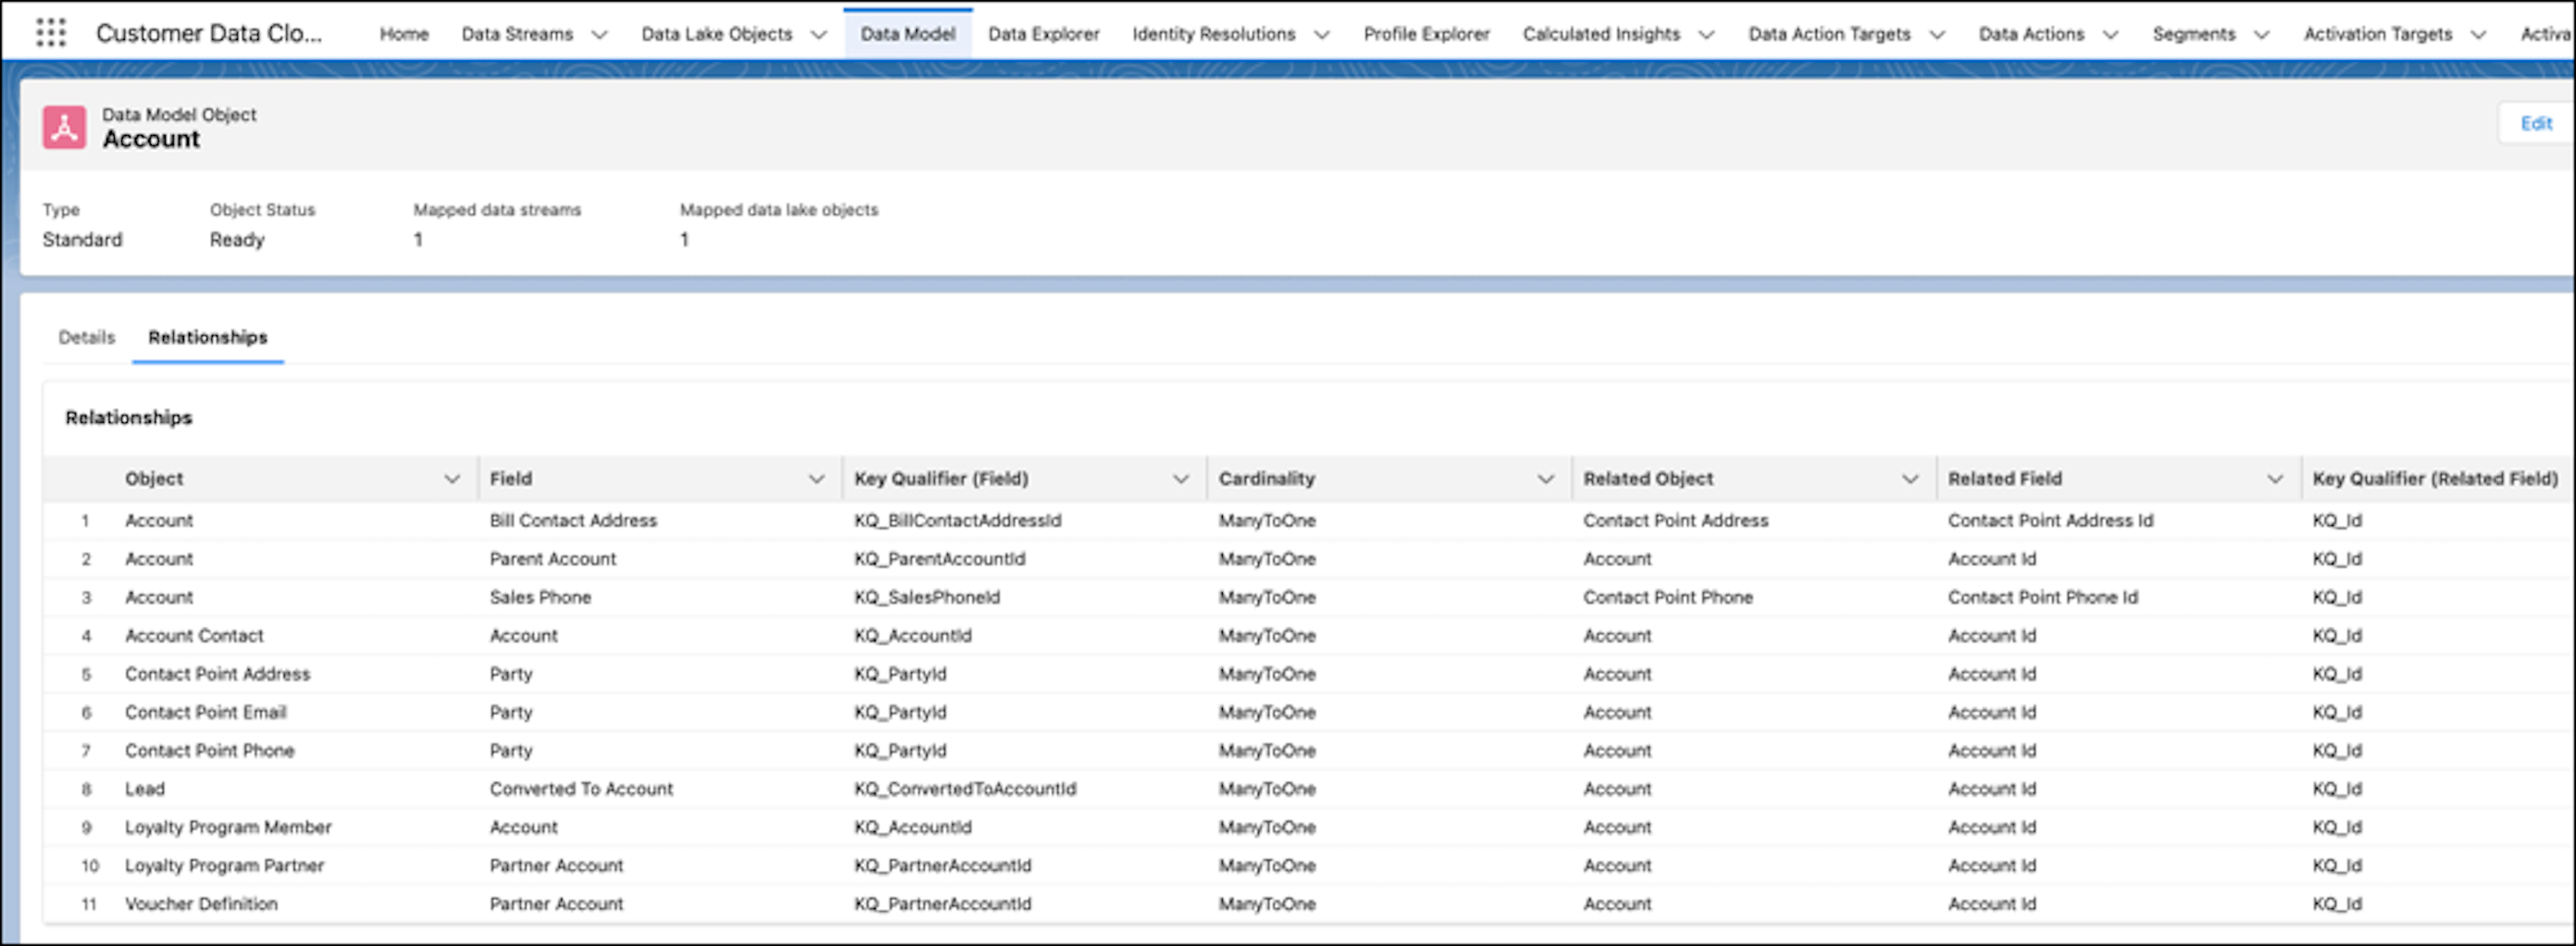
#### See Also
- [_Salesforce Help_: Configure a Key Qualifier Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_or_view_key_qualifier.htm&release=264.0.0&type=5 "After creating a data stream, add key qualifiers to your data lake object (DLO) fields to create fully qualified keys (FQK). Configure key qualifiers for all DLO fields that contain either a primary or foreign key. You can add up to 20 active key qualifiers. A key qualifier is active when it's used for a DLO field. Data 360 automatically adds and removes key qualifiers to and from data model object (DMO) fields. You can't edit these system fields.")
# Gain Insights on Data with CRM Analytics
Data 360 allows you to perform exploratory analysis on your data at different stages of its lifecycle using CRM Analytics. You can build contextual insights and create interactive views on a data lake object (DLO), data model object (DMO), or calculated insights object (CIO) without loading the data into CRM Analytics. You can filter the Data 360 data, drill deeper, and act on the data directly from the dashboards.
### Required Editions
CRM Analytics is available in Developer Edition and for an extra cost in Enterprise, Performance, and Unlimited editions.
- **[Access CRM Analytics from a Calculated Insights Object](https://help.salesforce.com/s/articleView?id=data.c360_a_access_crma_from_a_calculated_insights_object.htm&release=264.0.0&type=5)**
You can access CRM Analytics from the Calculated Insights tab in Data 360.
- **[Access CRM Analytics from a Data Lake Object](https://help.salesforce.com/s/articleView?id=data.c360_a_access_crma_from_a_data_lake_object.htm&release=264.0.0&type=5)**
You can access CRM Analytics from the Data Lake Objects tab in your Data 360 instance.
- **[Access CRM Analytics from a Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_access_crma_from_a_data_model_object.htm&release=264.0.0&type=5)**
You can access CRM Analytics from the Data Model tab in your Data 360 instance.
#### See Also
- [_Salesforce Help_: Unlock CRM Analytics Insights on Data 360](https://help.salesforce.com/s/articleView?id=analytics.bi_direct_data_for_cdp.htm&type=5&language=en_US)
# General Set Up Tasks in Data 360
In addition to provisioning and connecting data sources, learn about additional tasks completed in Data Cloud Setup.
- **[Fiscal Calendar Options for Data 360 Queries](https://help.salesforce.com/s/articleView?id=data.c360_a_standard_fiscal_calendar_setup.htm&release=264.0.0&type=5)**
Use standard or custom fiscal calendar options to configure how Data 360 queries handle fiscal years. With these settings, you can align query results with your organization’s fiscal periods rather than calendar years.
- **[Using Currencies in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_multi_currency_how_it_works.htm&release=264.0.0&type=5)**
Data Cloud uses the currencies and static exchange rates configured in your Salesforce CRM org and applies them to data transforms, calculated insights, segmentations, reports, and other processes.
- **[Data 360 Time Zones](https://help.salesforce.com/s/articleView?id=data.c360_a_time_zones.htm&release=264.0.0&type=5)**
Data 360 uses the time zone set in Salesforce when publishing and refreshing segments and activations. The dates and times added to a segment in the segment canvas also use the Salesforce time zone. To change the time zone for Data 360, change the time zone in Salesforce.
- **[Control and Metadata Change Events](https://help.salesforce.com/s/articleView?id=data.c360_a_control_events_supported_objects.htm&release=264.0.0&type=5)**
Set up notifications for your Data 360 data in Flow Builder and create reports to see your Data 360 statuses.
- **[Allowlisting](https://help.salesforce.com/s/articleView?id=data.c360_a_allowlist.htm&release=264.0.0&type=5)**
An allowlist defines things that a system trusts. It’s used to control allowed traffic and rejects undefined traffic and can be applied at different layers of the OSI Model. Here’s how the allowlist works at the application and network layers for Data 360.
- **[Find Your Instance and Endpoint Information](https://help.salesforce.com/s/articleView?id=data.c360_a_find_your_functional_domain.htm&release=264.0.0&type=5)**
Data 360 runs on both Salesforce's first-party infrastructure and public cloud infrastructure, referred to as a functional domain (FD). Use these steps to find your Data 360 instance so that you can understand the impact when there’s an unforeseen incident or if you have a support case where additional information is required.
# Generate a Filter Population Breakdown for Your Segment
See the individual and cumulative impact of each Include and Exclude filter before you activate the segment.
### Required Editions
Permission Sets Needed
To generate a population breakdown:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
A filter population breakdown report analyzes how attributes and filters change the segment across Include and Exclude logic.
1. Go to the **Segments** tab, select the segment, and click **Edit Rules**.
2. Click **Generate Population Breakdown**.
3. To check the report status, click **View Population Breakdown**.
The population breakdown report shows the filter-level and cumulative impact of the Include and Exclude filters.
- **[View Filter Population Breakdown](https://help.salesforce.com/s/articleView?id=data.c360_a_filter_population_breakdown_report.htm&release=264.0.0&type=5)**
After you start a report, open it to see how each Include and Exclude filter changes the audience, from the first filter through the final count.
# Generate Research Reports with Deep Research
Use Deep Research to generate comprehensive research reports directly in your Notebook AI workspace. Instead of querying multiple sources separately, submit a single research query. Notebook AI analyzes CRM records, uploaded documents, enterprise search results, and web sources, then delivers a report complete with findings, recommendations, and inline citations.
### Required Editions
User Permissions Needed
To use Deep Research in Notebook AI
Enable Notebook AI Custom Permission Set
Deep Research runs in the background while you continue working. When your report is ready, Notebook AI adds it to the Resources panel, where it becomes a searchable source for future queries in your Notebook.
## Run Deep Research
1. In your Notebook AI workspace, make sure that you added relevant resources.
2. In the chat section, enter your research query in detail. For example: What are the top three priorities based on our CRM data and their recent earnings report?
3. Turn on **Deep Research** and **Submit**. Notebook AI generates a Research Plan listing the specific tasks and data sources to be analyzed.
4. Optionally, customize the Research Plan before running it.
1. To edit the plan, click **Edit Plan**. Deselect data sources that you want to exclude from the research, or enter a natural language prompt to change the direction of any of the research tasks and save progress.
2. To choose a report template from the library or your own template in Markdown (.md) format, click **Select Template**.
5. To start the analysis, click **Run Research**.
6. Optionally, click **Show Thinking** to see what Notebook AI is retrieving and processing in real time.
7. When the report is ready, click **View** to open it. The report includes a **Table of Contents** and inline citations linked to source documents.
8. Download the report as a PDF, or ask follow-up questions to continue exploring the findings.
## Considerations
- Write detailed research queries. Include context, goals, and the specific insights that you need. For example, whether you’re preparing for a customer meeting, evaluating competitors, or analyzing deal risk.
- Upload 5–15 documents that directly relate to your research topic. Include diverse sources such as internal documents or external research sources.
- Use **Show Thinking** view to understand what Deep Research is retrieving and how it’s analyzing your sources to catch gaps early and refine your query if needed.
# Get Instant Answers from Your Data with Data Q&A
Ask questions in natural language about your Data 360 data and get AI-powered answers, SQL queries, and visualizations instantly.
### Required Editions
Data 360 Data Q&A is an AI-powered agent that enables business users to ask natural language questions and get answers grounded in your Data 360 data. The agent generates SQL queries, executes them against your data, and returns responses with tables, charts, and explanations—all without requiring SQL knowledge.
The agent reduces time-to-insight from hours or days to seconds. Instead of waiting on data teams or learning SQL, you can explore your data conversationally through the chat interface.
## Key Capabilities
- **Natural language queries:** Ask questions in plain English about your data.
- **Automatic SQL generation:** The agent writes, executes, and explains SQL queries for you.
- **Visual insights:** Get charts and data tables alongside prose explanations.
- **Semantic enrichments:** Add business context to help the agent understand your data better.
- **Query refinement:** Ask follow-up questions to modify, fix, or explain generated queries.
## What Influences Agent Behavior
Multiple factors shape how the agent interprets your questions and generates responses:
- Data schemas such as object and field names and descriptions
- Semantic enrichment statements you've added
- Data governance policies and user access permissions
- Sample values and relationships between objects

Important Before making decisions based on the agent's answers, validate the response by clicking **View More Details** to review the generated SQL query, assumptions, and confidence score.
## Sample Questions and Requests
- What are the top 10 best performing products in Q3 in terms of revenue?
- Show the product usage levels over the last year, broken down by regions.
- Show me the top 3 opportunities by deal size.
- Generate a chart comparing customer engagement by segment.
## Topics
- **[Enable Data 360 Data Q&A Agent](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_data_qna_agent.htm&release=264.0.0&type=5)**
Turn on the Data 360 Data Q&A Agent and Metadata Knowledge Graph and Semantic Enrichments features to start asking natural language questions about your data.
- **[Use the Data Q&A Agent](https://help.salesforce.com/s/articleView?id=data.c360_a_data_qna_use.htm&release=264.0.0&type=5)**
Ask the Data 360 Data Q&A Agent questions in natural language to explore your data, review the responses and generated queries, and refine your analysis with follow-up questions.
- **[Data Q&A Agent Considerations and Troubleshooting](https://help.salesforce.com/s/articleView?id=data.c360_a_data_qna_considerations_troubleshooting.htm&release=264.0.0&type=5)**
Review key considerations for the Data 360 Data Q&A Agent, and troubleshoot common issues such as unexpected results, low confidence scores, or missing data.
- **[Deactivate or Delete Data Q&A Agent](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_data_qna_agent.htm&release=264.0.0&type=5)**
Control whether the Data 360 Data Q&A Agent is active and accessible in your org, or remove it entirely.
- **[Guide Data Q&A with Semantic Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_semantic_enrichments_overview.htm&release=264.0.0&type=5)**
Add semantic statements to help the Data 360 Data Q&A Agent better understand your data's business context, domain-specific terminology, and relationships.
# Get Predictions in Apex
Use Apex code to get predictions, top factors, and prescriptions from a no-code model in Model Builder.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
## Invocable Action
To use a predictive model with Apex, create an invocable action with this method. The method creates an invocable action that provides input data to a predictive model. It triggers the model request and processes the returned output, including predictions, top factors, and prescriptions (recommended actions).
`Invocable.Action.createCustomAction`
## REST Request
As a model is activated, an invocable action is automatically created and it can be used in Flow or Apex. When using this invocable action in Apex, you may need to get the input parameters using this REST Endpoint.
`GET /services/data/v63.0/actions/custom/cdpMlPrediction/{ModelIdOrName}`

Note You can use the predictive model name (this example) or model id (API Name). Some APIs also require the model API name “{ModelIdOrName}”. You can find a model's API name in Model Builder, on the model details page.
Let's look at how to use a REST request for a 'Predicted Purchased' model.
`GET /services/data/v63.0/actions/custom/cdpMlPrediction/Predicted_Purchased_CM_12l_YSs01128465`
The request retrieves metadata about the invocable action such as the model input parameters.
`{ "inputs" : [ { "label" : "Top Predictors", "name" : "maxTopFactors", "type" : "INTEGER" }, { "label" : "Top Prescriptions", "name" : "maxPrescriptions", "type" : "INTEGER" }, { "label" : "Lead Source", "name" : "param_Lead_Source_c__c", "type" : "STRING" }, { "label" : "Industry", "name" : "param_Industry_c__c", "type" : "STRING" }, { "label" : "Title", "name" : "param_Title_c__c", "type" : "STRING" }, { "label" : "Response Time From Assignment", "name" : "param_Response_Time_From_Assignment_c__c", "type" : "DOUBLE" }, { "label" : "No. of Employees", "name" : "param_No_of_Employees_c__c", "type" : "DOUBLE" }, { "label" : "Response Time from Creation", "name" : "param_Response_Time_from_Creation_c__c", "type" : "DOUBLE" } ] }`
## Apex for Predictions
You can then use Apex code to invoke the 'Predicted Purchased' model to provide predictions, top factors, and prescriptions.
`Invocable.Action action = Invocable.Action.createCustomAction('cdpMlPrediction', 'Predicted_Purchased_CM_12l_YSs01128465'); action.setInvocationParameter('param_Industry_c__c', 'High Tech'); action.setInvocationParameter('param_No_of_Employees_c__c', 100); action.setInvocationParameter('param_Lead_Source_c__c', 'Chat'); action.setInvocationParameter('param_Response_Time_from_Creation_c__c', 100); action.setInvocationParameter('param_Response_Time_From_Assignment_c__c', 300); action.setInvocationParameter('maxTopFactors', 3); action.setInvocationParameter('maxPrescriptions', 3); List results = action.invoke(); if (results.size() > 0 && results[0].isSuccess()) { System.debug('Prediction =' + results[0].getOutputParameters().get('prediction')); //output will be in the same data type as the model output System.debug('Top Factors =' + results[0].getOutputParameters().get('factors')); //output is a custom Apex Type ConnectAPI.CdpMlPredictionContribution System.debug('Prescriptions =' + results[0].getOutputParameters().get('prescriptions')); //output is a custom Apex Type ConnectAPI.CdpMlPredictionContribution }`
#### See Also
- [_Salesforce Developer:_ Apex Developer Guide](https://developer.salesforce.com/docs/atlas.en-us.apexcode.meta/apexcode/apex_dev_guide.htm)
# Get Predictions in REST APIs
Use the Salesforce Data 360 Connect REST API to programmatically interact with predictive models. Get predictions, top factors, and prescriptions using the predict endpoint.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
## Prediction Request
Syntax for the predict endpoint.
```markup
POST /services/data/v63.0/ssot/machine-learning/predict
```
## POST Request Body
When you run a prediction, Salesforce applies the model to the set of model inputs and returns a prediction score for each set of input values specified. For example, if you specify three sets of values, you get three predictions in the order that the records were specified in the request.
```markup
GET /services/data/v61.0/ssot/machine-learning/configured-models/{ModelIdOrName}
```

Note You can use the predictive model name (this example) or model id (API Name). Some APIs also require the model API name “{ModelIdOrName}”. You can find a model's API name in Model Builder, on the model details page.

Let's look at the REST request using the Predicted Purchased model.
```markup
{
"model":
{
"name": "Predicted_Purchased_CM_12l_YSs01128465"
},
"type": "RawData",
"fieldNames": ["Industry_c__c", "Response_Time_From_Assignment_c__c" , "Company_c__c", "Title_c__c"],
"rows":
[
["High Tech", 56, "Condax","Student"],
["Professional Services",70,"Rantouch","Developer"]
],
"settings" : {
"maxPrescriptions" : 3,
"maxTopFactors" : 2,
"prescriptionImpactPercentage" : 50
}
}
```
- `maxPrescriptions` specifies the maximum number of improvements (1-3) to return in the response
- `maxTopFactors` specifies the number of top predictors (1-3) to return in the response
- `prescriptionImpactPercentage` specifies the threshold filter (minimum % improvement for the outcome, which in this example is 50%) needed for the improvement to be returned in the response
## POST Response
Example POST response.
```markup
{
"aggregatePredictions": [],
"model": {
"id": "12l1Q000000blV0QAI"//Id
},
"predictionType": "BinaryClassification",
"predictions": [
{
"factors": [
{
"fields": [
{
"customText": null,
"inputValue": "Student",
"label": null,
"name": "Title_c__c",
"prescribedValue": "Title"
}
],
"value": -40.58208510642879
},
{
"fields": [
{
"customText": null,
"inputValue": "56",
"label": null,
"name": "Response_Time_From_Assignment_c__c",
"prescribedValue": "Response Time From Assignment"
}
],
"value": 10.187649697792125
}
],
"partition": {
"id": "12l1Q000000blV0QAI" //Id"
},
"predictedValue": 0.5997765233332488,
"prescriptions": [],
"status": "Success",
"type": "BinaryClassification",
"warnings": {
"missingFieldNames": [],
"outOfBoundsFields": []
}
},
{
"factors": [
{
"fields": [
{
"customText": null,
"inputValue": "Developer",
"label": null,
"name": "Title_c__c",
"prescribedValue": "Title"
}
],
"value": -28.000138322513255
},
{
"fields": [
{
"customText": null,
"inputValue": "70",
"label": null,
"name": "Response_Time_From_Assignment_c__c",
"prescribedValue": "Response Time From Assignment"
}
],
"value": 6.156639498073147
}
],
"partition": {
"id": "12l1Q000000blV0QAI" //Id"
},
"predictedValue": 5.278021902657085,
"prescriptions": [],
"status": "Success",
"type": "BinaryClassification",
"warnings": {
"missingFieldNames": [],
"outOfBoundsFields": []
}
}
],
"settings": {
"aggregateFunctions": [],
"maxPrescriptions": 3,
"maxTopFactors": 2,
"prescriptionImpactPercentage": 50
}
}
```
#### See Also
- [_Salesforce Developer:_ Salesforce Data 360 Connect REST API](https://developer.salesforce.com/docs/platform/connectapi/references/spec?meta=Get%2Bprediction.htm)
- [_Salesforce Developer:_ Data 360 Connect REST API Developer Guide](https://developer.salesforce.com/docs/atlas.en-us.chatterapi.meta/chatterapi/intro_what_is_chatter_connect.htm)
# Get Predictions, Prescriptions, and Top Predictors
Put your predictive AI models into action. After a model is activated, use it to get inferences—predictions, prescriptions, and top predictors—from your Salesforce workflows. Get inferences on demand, in batches, and in streams. Use them in flows, prediction jobs, batch data transforms, agents, and prompt templates. Get them programmatically in Apex and REST applications.
- **[Actionable Variables and Prescriptions](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_actionable_variables_prescriptions.htm&release=264.0.0&type=5)**
In AI Models (formerly Einstein Studio) Model Builder, which uses data from Data 360, actionable variables are fields in a model created from scratch (AI-created) that you can change to influence a predictive outcome. In constrast to other fields that you can't change, such as a customer's location, gender, and age, actionable variables can be changed. These variables are important because they provide suggested actions (prescriptions) that users can take for more succesful outcomes.
- **[Use Outputs from Predictive Models](https://help.salesforce.com/s/articleView?id=data.c360_a_get_predictions_from_your_model.htm&release=264.0.0&type=5)**
There are many ways in which you can consume predictions, prescriptions, and top factors returned from predictive models.
- **[Transform Data with Predictions and Prescriptions](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_batch_transform_append_predictions.htm&release=264.0.0&type=5)**
Enrich a data model object (DMO) with outputs. Use a data transform to add predictive and prescriptive intelligence to your data. Run data transformations and save the outputs, such as prediction scores, on a DMO. Use each row of the output to create derived columns and run calculations. You can also build data visualizations using output data saved on the DMO in other Salesforce applications, such as in Tableau, CRM Analytics, and app templates.
- **[Use Predictions in Flow Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_flow_builder_predictions.htm&release=264.0.0&type=5)**
Create automation using outputs from an activated model for decision-making. Predictive models that are activated in AI Models (formerly Einstein Studio) are surfaced in Flow as actions. You can use all flow types and choose a flow based on your goal. For example, if a business process requires user input or you want to display specific data to users, use a screen flow. If you want to automate possible actions to take after a record is created, updated, or deleted, use a record-triggered flow.
- **[Use Predict Jobs](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_prediction_job_get_predictions.htm&release=264.0.0&type=5)**
A predict job enables an active model to write predictive outputs to a data model object (DMO). Create a streaming or batch job in Model Builder and use the model's outputs in Salesforce workflows.
- **[Get Predictions in REST APIs](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_rest.htm&release=264.0.0&type=5)**
Use the Salesforce Data 360 Connect REST API to programmatically interact with predictive models. Get predictions, top factors, and prescriptions using the predict endpoint.
- **[Get Predictions in Apex](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_apex.htm&release=264.0.0&type=5)**
Use Apex code to get predictions, top factors, and prescriptions from a no-code model in Model Builder.
- **[Use Predictive AI with Agents and Prompt Templates](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_generative.htm&release=264.0.0&type=5)**
Use predictive intelligence to power agents and prompt templates in Agentforce solutions.
- **[Use Real-Time Predictions to Drive Personalized Recommendations](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_personalized_recommendations.htm&release=264.0.0&type=5)**
Predictive models in AI Models (formerly Einstein Studio) can generate real-time predictions to inform personalized recommendations in Salesforce Personalization. The integration enables the delivery of customized experiences, which can boost engagement. Predict the customer lifetime value annual spend, or likeliood to purchase and use your model's predictions in a Personalization Decision targeting rule to serve up different content recommendation strategies.
# Get Started with Data 360
Before you begin with Data 360, review the checklist, considerations, and product navigation.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
To get ready for Data 360, teams should:
- Understand the guidelines and limitations that impact billing.
- Review brand management and organization structure used in Data 360.
- Decide on a data strategy by reviewing data model concepts.
- Analyze existing data and data sources.
- Discuss using unified profiles.
- Identify users and their needed permissions.
- Create goals and determine data usage.
## Checklist and Considerations
Download the interactive PDF worksheet: [Data 360 Checklist and Considerations](https://resources.docs.salesforce.com/rel1/doc/en-us/static/pdf/Data360_Checklist.pdf).
[](https://resources.docs.salesforce.com/rel1/doc/en-us/static/pdf/Data_Cloud_Checklist.pdf)
## Navigation Options
Find Data Cloud in the App Launcher after provisioning.
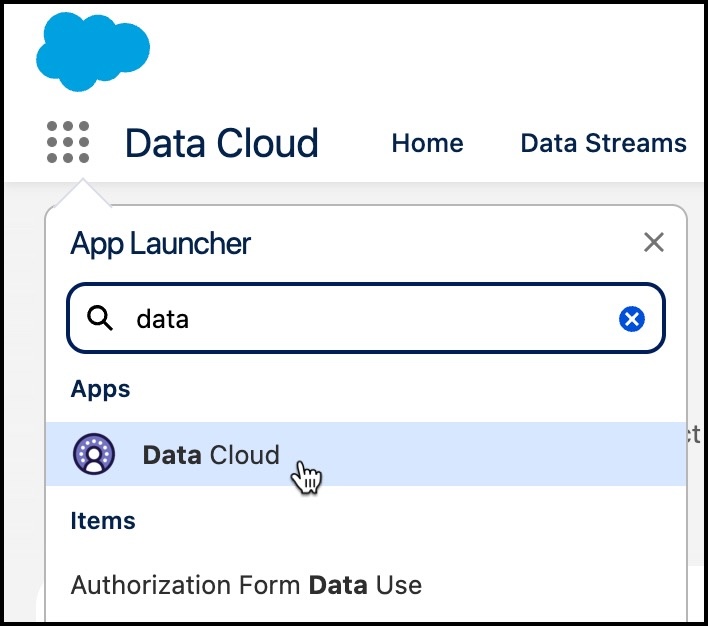
## Tab Navigation
On the Data Cloud home page, find features through tabs.
Ingest, connect and model data with the Data Streams, Data Lake Objects, and Data Model (1) tabs. View connected data and unified profiles with Data Explorer and Profile Explorer (2). Create match and reconciliation rules to unify individual records with the Identity Resolutions (3) tab. Calculate metrics and build streaming insights from the Calculated Insights (4) tab. The Data Cloud Setup gear (5) is where system admin and users with the Data 360 Architect permission set configure Data 360 features.
## Left Side Navigation
Users can now enable a new navigation pattern in Feature Manager. Instead of using tabs, job-based categories organize features based on related tasks and implementation order.
Find features grouped into categories.
- **Connect & Unify:** Connect Salesforce or external data into Data 360, standardize and harmonize the data, and create unified profiles.
- **Govern & Secure:** Provide users access to the right data at scale with data spaces, and add governance through tagging, classification, and policy-based controls.
- **Process & Enrich:** Prepare your data for search and AI with intelligent processing methods.
- **Explore & Optimize:** Explore your data with clicks, natural language, or SQL. Optimize your data for fast, efficient lookups by creating a data graph and a secondary index.
- **Analyze & Predict:**Use your data to generate metrics and reports, ask questions, and build AI and semantic models.
- **Segment & Act:** Build and activate segments, manage communications channels, and take external action.

- **[Set Up and Turn On Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_provision.htm&release=264.0.0&type=5)**
Capture, unify, segment, and activate your customer data with Data 360. Automatic provisioning occurs for most orgs that have a Data Cloud license. However, if auto provisioning isn't available or if you’re working in a Developer Edition or sandbox org, you must manually enable it.
- **[Create Data 360 Users and Assign Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_walkthrough.htm&release=264.0.0&type=5)**
Create users and provide access to Data Cloud features like identity resolution, transforms, and calculated insights.
- **[Data 360 Licenses, Billing, and Limits](https://help.salesforce.com/s/articleView?id=data.c360_a_licenses_billing_limits.htm&release=264.0.0&type=5)**
How you pay for data services provided by Data 360 depends on how your Data 360 org is licensed. Your licenses determine both billing method and limits for your org. We recommend working with your account exec before buying Data 360 or when your contract renews to ensure your license is the best choice based on your usage and growth potential.
- **[Enable Data 360 Features](https://help.salesforce.com/s/articleView?id=data.c360_a_feature_manager.htm&release=264.0.0&type=5)**
You can enable Data 360 features using the Feature Manager. This screen is visible only when there are one or more features to enable or disable.
- **[Data 360 Lifecycle Management](https://help.salesforce.com/s/articleView?id=data.c360_a_lifecycle_management_cleanup.htm&release=264.0.0&type=5)**
To manage your Data 360 lifecycle you can renew your license or delete your Data 360 instance to reset the org. To keep your Data 360 instance, renew your license within the 120-day grace period. To set up a new Data 360 instance with an active license, use the Data 360 cleanup process to delete its associated data, metadata, and configurations. You can also use the cleanup process to connect your org as a Data Cloud One companion to an existing Data 360 instance.
- **[Data Source Configuration in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_connection_tasks.htm&release=264.0.0&type=5)**
To connect data sources, review the admin tasks that must be completed first. After they’re configured in Data Cloud Setup, data streams can be created for each data source. Find information about all the varieties of data source connectors, their configuration, and data stream setup under Connect Data.
- **[Data Target Configuration in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_target_configuration_in_data_cloud.htm&release=264.0.0&type=5)**
To configure data targets, review the admin tasks that must be completed first.
- **[AI and Data Usage in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_einstein_data_usage_in_data_cloud.htm&release=264.0.0&type=5)**
AI is built on data. Review this table to find out which AI models Data 360 features support and the implications of turning off access to a model.
- **[General Set Up Tasks in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_admin_maintenance_tasks.htm&release=264.0.0&type=5)**
In addition to provisioning and connecting data sources, learn about additional tasks completed in Data Cloud Setup.
- **[Data 360 Usage and Access Changes](https://help.salesforce.com/s/articleView?id=data.c360_a_changelog_usage_and_access.htm&release=264.0.0&type=5)**
Changes to documentation about Data 360 licensing, feature availability, limits, billing, and permission sets are logged in this document.
#### See Also
- [_Salesforce Help_: Find Your Functional Domain](https://help.salesforce.com/s/articleView?id=data.c360_a_find_your_functional_domain.htm&release=264.0.0&type=5 "Data 360 runs on both Salesforce's first-party infrastructure and public cloud infrastructure, referred to as a functional domain (FD). Use these steps to find your Data 360 instance so that you can understand the impact when there’s an unforeseen incident or if you have a support case where additional information is required.")
# Get Started with Data Governance
Before using Data Governance features, it's important to review the prerequisites and the steps required to enable governance across your organization’s data.
## Prerequisties
Review the following steps before getting started.
- Familiarize yourself with [data spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces.htm&type=5&language=en_US), which define the boundaries for data visibility.
- To create specific, attribute-based policies, evaluate Data 360 standard [permission sets](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_permission_sets.htm&type=5&language=en_US) and associated [data governance permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_tags_classifications_taxonomies_policies.htm&release=264.0.0&type=5 "Review the permissions and permission sets required to effectively use data governance features in Data 360.").
- (Optional) Enable Einstein to trigger automatic tagging. See [Set Up Einstein Generative AI](https://help.salesforce.com/s/articleView?language=en_US&id=sf.generative_ai_enable.htm&type=5).
## Overview of Steps
To grant granular access using access policies, assign data spaces through permission sets and create an access policy.

Note Assigning a data space through a permission set doesn’t automatically give users access to the data.
To create and assign access policies, you must:
- Create tags and assign to objects and fields.
- Create custom permissions and add them to a custom permission set. You can’t add custom permissions to standard permission sets or their clones.
- Assign the permissions to the intended users.
- Create access policies to grant data access.
## Control Models
Data 360 uses a combination of access control models to deliver granular, scalable, and policy-driven governance. Each mechanism serves a distinct purpose, and together they create a comprehensive security and governance framework.
| LAYER | function | what it controls |
| --- | --- | --- |
| Data Spaces | Data visibility scope | Controls which data objects or records a user can interact with. It can be used to grant access to a set of objects but doesn’t support fine-grained or row-level control. |
| Role-based Access Control (RBAC) | Base access to features and setup | Navigation, admin tasks, configuration rights, and access assignment to specific objects within the dataspace. |
| Attribute-based Access Control (ABAC) | Policy-driven access based on context | Object-level, field-level, row-level, and masking rules |
- **[Data Cloud Governance Feature Availability by License](https://help.salesforce.com/s/articleView?id=data.c360_a_data_gov_feature_availability.htm&release=264.0.0&type=5)**
Salesforce offers a tiered licensing model for data governance within Data 360, enabling customers to scale from foundational governance to advanced, AI-driven controls. Understand which data governance features are available with which Data Cloud license.
- **[Data 360 Governance Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_tags_classifications_taxonomies_policies.htm&release=264.0.0&type=5)**
Review the permissions and permission sets required to effectively use data governance features in Data 360.
- **[Assign Data Access](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_access.htm&release=264.0.0&type=5)**
For data governance, assign access to Data 360 objects using either role or attribute-based policies, or maintain an Allow All policy.
- **[Data Governance Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_before_you_begin_data_gov.htm&release=264.0.0&type=5)**
Before you begin, it’s important to review supported features and considerations for using data governance features in Data 360.
# Get Trusted AI Responses with Retriever Citations
Citations link AI-generated responses to the source content relevant to each response. Citations allow users to compare the LLM response with the source data to verify the validity of the response and identify any potential inaccuracies or hallucinations. Enable citations in AI Models (formerly Einstein Studio) at the individual retriever level to give access to citations to solution components that call the retriever, such as a prompt template.
Standard citations automatically generate citations that include a source URL and a header text. Custom citations allow you to define a base URL, a URL path, and a label from the source data model object (DMO) fields. Citation headings and links may be surfaced to end-users in downstream applications like Agentforce agents and prompt templates. Make sure that these fields are populated appropriately and that end-users have access to the source links.
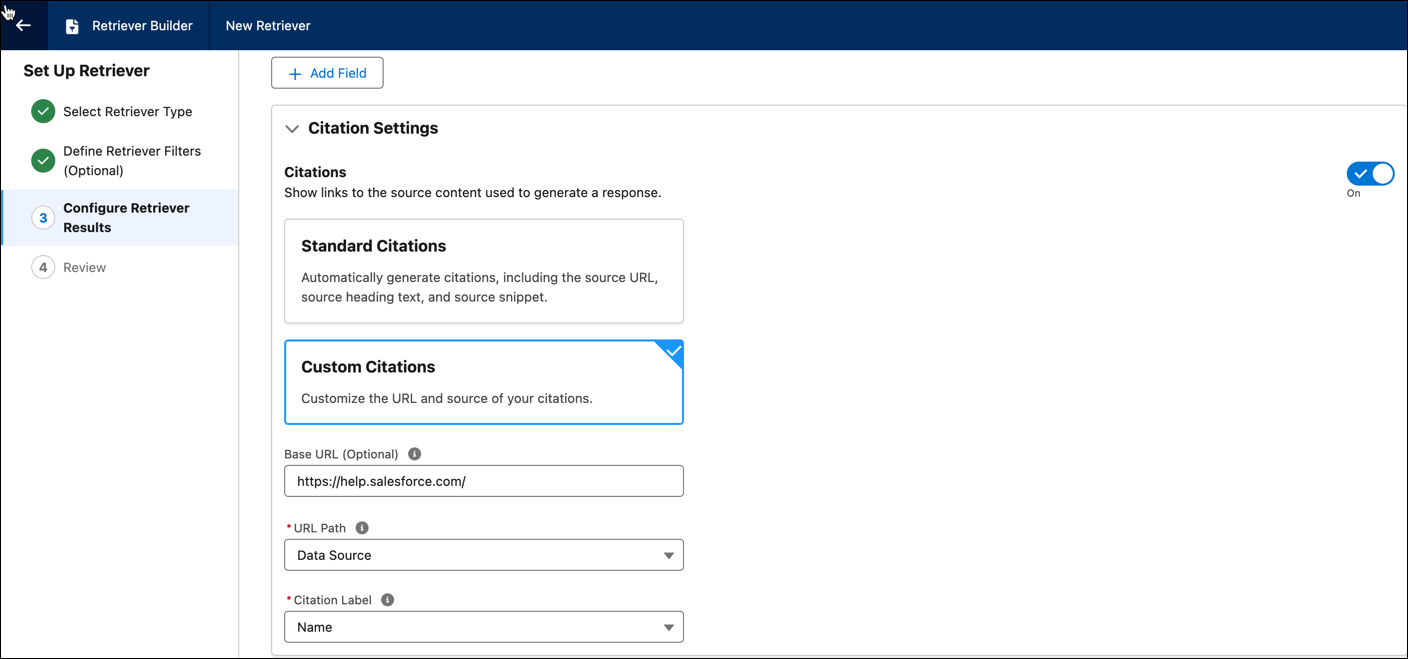
You can also configure citations in Einstein Platform with custom actions and Answer Questions with Knowledge standard action. For more information see, [Build Trust in AI Responses with Citations](https://help.salesforce.com/s/articleView?id=ai.generative_ai_trust_citations.htm&type=5&language=en_US).
## Use Case: Ground Agent Responses with Citations to Image Sources
Consider a scenario where a financial planner is preparing for meeting with a client and would like to provide investment recommendations. The financial plan document for the client includes various charts and graphs such as a graph for the total portfolio value.
With advanced search index setup, you can process both text and images in the plan document and ask questions about the client’s portfolio. Graphs and charts are processed by generating structured descriptions of the image using LLMs and providing a URL link to the image. Use this general flow to process your document.
- Connect and ingest documents that include images, and other visuals such as graphs or charts.
- Transform and index the documents using Data 360 search advanced setup. Enable image processing and select the appropriate embedding model to process images as part of your chunking strategy.

Note Enriched indexing is not supported for image files.
- Create an individual retriever for the search index.
- To test the retriever, embed it in a prompt template.
- Use the retriever in a custom agent or other client applications.
So when a financial planner asks the agent a question about the portfolio allocation, the LLM retrieves the text description of the graph with a link to the image. The agent response includes the answer with a source citation. Image citations appear as external links.
#### See Also
- [Create an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_create.htm&release=264.0.0&type=5 "To improve the relevancy of the content returned to a prompt for a particular use case, create a custom individual retriever in AI Models (formerly Einstein Studio). To customize the retriever, select its search index, define filters, and specify what information it returns.")
- [Create a Hybrid Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&release=264.0.0&type=5 "Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.")
- [Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
- [_Salesforce Help_: Add Citations to Prompt Template Responses](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_retriever_citations.htm&language=en_US)
# Get User Credentials from Snowflake
Gather the user information and authentication details in Snowflake to create a data share target.

Important You can’t create legacy Snowflake data share targets. [Create a Snowflake V2 data share target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflakev2.htm&type=5&language=en_US) instead, and link your existing and new data shares to it. Migrate existing data shares that are linked to a legacy Snowflake data share target to a Snowflake V2 data share target. See [Migrate Data Shares with Legacy Snowflake Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_migrate_data_shares_legacy_snowflake.htm&type=5&language=en_US). Don’t unlink an existing data share from its legacy target until you verify that the Snowflake V2 connection works. Downstream processes in Snowflake can refer to the database that was created using the legacy target.
These steps involve running commands in Snowflake. We recommend contacting your Snowflake admin for any troubleshooting assistance.
1. In Snowflake, create a user for Data 360 admin or Data Aware Specialist.
```
CREATE OR REPLACE USER
PASSWORD = ''
LOGIN_NAME =
DISPLAY_NAME =
FIRST_NAME =
MIDDLE_NAME =
LAST_NAME =
EMAIL =
DEFAULT_ROLE = ;
```
If you want to use an existing user, you can skip creating a user. Make sure that the default role isn’t ACCOUNTADMIN, SECURITYADMIN, or ORGADMIN. The user must have USAGE privileges (Read & Query) for the relevant warehouse.
2. In Snowflake, create a security integration.
```
CREATE OR REPLACE SECURITY INTEGRATION [IF NOT EXISTS]
TYPE = OAUTH
OAUTH_CLIENT = CUSTOM
OAUTH_CLIENT_TYPE = 'CONFIDENTIAL'
OAUTH_REDIRECT_URI = 'https://login.salesforce.com/services/cdpSnowflakeOAuthCallback'
ENABLED = TRUE
OAUTH_ISSUE_REFRESH_TOKENS = TRUE;
```
For a Data Cloud sandbox org, the `OAUTH_REDIRECT_URI` is `https://test.salesforce.com/services/cdpSnowflakeOAuthCallback`
3. In Snowflake, run the DESCRIBE statement to get the OAUTH\_AUTHORIZATION\_ENDPOINT details.
```
DESC SECURITY INTEGRATION ;
```
When you [create a data share target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflake.htm&release=264.0.0&type=5 "Create a data share target in Data 360 to establish connectivity with a Snowflake account.") in Data 360, for Account URL, enter the value of OAUTH\_AUTHORIZATION\_ENDPOINT and convert any underscores to hyphens and ignore the subdirectory and subsequent parts.
For example, if your OAuth Authorization Endpoint URL is `https://nto_america_dev_instance.example.computing.com/oauth/authorize`, enter `https://nto-america-dev-instance.example.computing.com` for the Account Url.
4. In Snowflake, get the client credentials.
```
SELECT SYSTEM$SHOW_OAUTH_CLIENT_SECRETS( '');
```
Use the Client ID and Client Secret to [create a data share target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflake.htm&release=264.0.0&type=5 "Create a data share target in Data 360 to establish connectivity with a Snowflake account."). Share the credentials with your Data 360 admin.
# Glossary for Predictive AI
Familiarize yourself with terminology that is commonly associated with predictive AI in AI Models (formerly Einstein Studio).
Actionable Variable
An actionable variable is an explanatory variable that people can control or influence, such as deciding which marketing campaign to use for a particular customer. Contrast these variables with explanatory variables that can’t be controlled, such as a customer’s street address or a person’s age. If a variable is designated as actionable, the model uses prescriptive analytics to suggest actions the user can take to improve the predicted outcome.
Actual Outcome
An _actual outcome_ is the real-world value of an observation's outcome variable after the outcome has occurred. Model performance is calculated by comparing how closely predicted outcomes come to actual outcomes. An actual outcome is sometimes called an _observed outcome_.
Algorithm
An _algorithm_ is what predictive modeling uses to create a model. Models created in AI Models use one of several algorithms: generalized linear model (GLM) is a regression-based algorithm, while gradient boosting machine (GBM) and XGBoost are decision tree-based machine learning algorithms.
Attribute
See _variable_.
Auth Header
An _authentication header_ is part of the HTTP request sent by a client to the server when making API requests. It provides information that the server uses to verify the client identity and permissions to access the requested resource.
Binary Classification
The _binary classification_ use case applies to business outcomes that are binary: categorical (text) fields with only two possible values, such as win-lose, pass-fail, public-private, retain-churn, and so on. These outcomes separate data into two distinct groups. For analysis purposes, Einstein converts the two values into Boolean true and false. Logistic regression is used to analyze binary outcomes. Binary classification is one of the main use cases that created models in AI Models support. Compare with _Regression_.
Cardinality
_Cardinality_ is the number of distinct values in a category. Variables with high cardinality (too many distinct values) can result in complexity that’s difficult to interpret. Created models in AI Models support up to 100 categories per variable. You can optionally consolidate the remaining categories (categories with fewer than 25 observations) into a category called **Other**. Null values are put into a category called **Unspecified**.
Categorical Variable
A _categorical variable_ is a type of variable that represents qualitative values (categories). A model that represents a binary classification use case has a categorical variable as its outcome. See _category_.
Category
A _category_ is a qualitative value that usually contains categorical (text) data, such as Product Category, Lead Status, and Case Subject. Categories are handy for grouping and filtering your data. Unlike numeric variables, you can’t perform math on categories.
Causation
_Causation_ describes a cause-and-effect relationship between things. In predictive modeling, causality refers to the degree to which variables influence each other (or not), such as between variables and an outcome variable. Some variables can have an obvious, direct effect on each other (for example, how price and discount affect the sales margin). Other variables can have a weaker, less obvious effect (for example, how weather can affect on-time delivery). Many variables have no effect on each other: they are independent and mutually exclusive (for example, win-loss records of soccer teams and currency exchange rates). It's important to remember that you can’t presume a causal relationship between variables based simply on a statistical correlation between them. In fact, correlation provides you with a _hint_ that indicates further investigation into the association between those variables. Only with more exploration can you determine whether a causal link between them really exists and, if so, how significant that effect is.
Coefficient
A _coefficient_ is a numeric value that represents the impact that a variable (or a pair of variables) has on the outcome variable. The coefficient quantifies the change in the mean of the outcome variable when there’s a one-unit shift in the variable, assuming all other variables in the model remain constant.
Correlation
A _correlation_ is simply the _association_—or “co-relationship”—between two or more things. In predictive modeling, correlation describes the statistical association between variables, typically between variables and an outcome variable. The strength of the correlation is quantified as a percentage. The higher the percentage, the stronger the correlation. However, keep in mind that correlation is _not_ causation. Correlation merely describes the strength of association between variables, not whether they causally affect each other.
Count
A _count_ is the number of observations (records) associated with model training. The count can represent all observations in the data, or the subset of observations that meet associated filter criteria.
Date Variable
A _date variable_ is a type of variable that contains date/time (temporal) data.
Dependent Variable
See _outcome variable_.
Drift
Over time, a deployed model's performance can _drift_, becoming less accurate in predicting outcomes. Drift can occur due to changing factors in the data or in your business environment. Drift also results from now-obsolete assumptions built into the data on which the model is based. To remedy a model that has drifted, you can refresh it by adjusting settings or retrain it on newer data.
Endpoint URL
The URL that represents the location where a particular API or service can be accessed. It’s where you can make requests to interact with the endpoint of an API.
Ethical Use
Ethical use reflects the application of AI and machine learning for fair and unbiased purposes. With AI Models, it's the practice of producing ethical and accountable models, insights, and predictions. For an overview, take the [Responsible Creation of Artificial Intelligence](https://trailhead.salesforce.com/en/content/learn/modules/responsible-creation-of-artificial-intelligence) Trailhead module.
Feature
See _predictor variable_.
Feature Selection
_Feature selection_ involves choosing the optimum set of features (predictor variables) in a model. Ideally, a model contains the number of variables that best explain variations in the outcome variable. A model with too few variables can be too vague to detect underlying patterns in the data, resulting in an underfitting model. A model with too many variables can be overly specific and too complex to filter out noise in the data, resulting in an overfitting model. Successful feature selection includes the most influential variables with no significant lurking variables (important variables that are missing from the model).
Generalized Linear Model (GLM)
_General Linear Model_ is an equation-based modeling algorithm used to build a model.
Goal
A _goal_ specifies the desired outcome for your model. A model’s goal includes its outcome variable plus your preferred direction (minimize or maximize) for the outcome. For example, your goal could be to maximize margin or to minimize costs. Predictive modeling uses the model goal to orient its analysis and training. See _outcome variable_.
Gradient Boosting
_Gradient Boosting_ is a decision tree-based ensemble machine learning algorithm used to build a model. Also called _Gradient Boosting Machine_ (or _GBM_).
Importance
_Importance_ is the relative influence of a variable on the model's predicted outcome. For models created in AI Models, importance indicates how much the model chooses to use a variable when predicting the outcome. The level of importance is quantified as a percentage. The higher the percentage, the greater the impact. Importance is an advanced metric that considers interactions between variables. If two variables are highly correlated and contain similar information, the model chooses the better variable to use. For example, when predicting energy usage the variables of temperature and number of air conditioner hours are both highly correlated, but only one of the variables receives a high importance score.
Independent Variable
See _predictor variable_.
Inference
An _inference_ is any type of data output produced by an AI model in AI Models.
k-fold Cross-Validation
Model validation process that randomly divides all the observations in the data into four separate partitions of equal size. Next, it completes four test passes (folds) in which three of the partitions serve as the training set and one partition serves as the test set. Metrics are averaged across all four folds.
Key Based Authentication
Authentication that uses an API key to authorize access to an API endpoint. API keys are a common method of securing APIs and controlling access to specific resources.
Leakage
_Leakage_ occurs when the data used to train your model includes one or more variables that contain the information that you’re trying to predict. This can result in models that are extremely accurate when, in actuality, they are problematic. To remedy data leakage, remove any variables from your model that are causing the leakage.
Linear Regression
_Linear regression_ is an analytical technique used for numeric use cases.
Logistic Regression
_Logistic regression_ is an analytical technique used for the binary classification use case.
Lurking Variable
A _lurking variable_ is a variable that is missing from your model but that significantly explains variations in the outcome variable.
Mean
A _mean_ is the statistical average: the sum of all items divided by the number of items.
Model
A _model_ is the sophisticated, custom representation based on a comprehensive, statistical understanding of past outcomes used to predict future outcomes. A model accepts the values of one or more predictor variables as input and produces a predicted outcome as output, along with top factors and improvements (if requested).
Model Builder
The _model builder_ is the tool in AI Models used to create, connect, and edit models.
Modeling Algorithm
A modeling algorithm is what AI Models uses to create a model. Einstein uses one of several algorithms: generalized linear model (GLM) is a linear algorithm, while gradient boosting machine (GBM) and XGBoost are decision tree-based machine learning algorithms.
Model Performance
Model performance are the metrics used to describe the performance of the predictive model. These metrics (quality indicators, which are sometimes called fit statistics) show how well the model's predictions fit the training data in the dataset. For definitions of quality indicators shown in Model Performance, see [Evaluate Model Quality](https://help.salesforce.com/s/articleView?id=analytics.bi_edd_model_metrics.htm&type=5&language=en_US).
Noise
_Noise_ is any data that doesn’t meaningfully explain variations in your outcome variable. See _signal_.
Numeric Variable
A _numeric variable_ is a type of variable that represents quantitative values (numbers), such as revenue or price. You can do math on numeric variables, such as calculating the total revenue or the average price. A numeric value always has an associated unit of measure, such as currency, volume, or weight. A model that represents a numeric use case has a numeric outcome variable.
Observation
An _observation_ represents an instance of the data. An observation is analogous to a row of data in a table, or a record in Salesforce. For example, if your model’s goal is to maximize opportunity wins, then each observation represents an opportunity.
Outcome
An _outcome_ is the business result. An outcome is typically a key performance indicator (KPI), such as sales margin or opportunity wins.
Outcome Variable
In predictive modeling, the _outcome variable_ is the field used as the single, primary focus for analysis and predictions. The goal of a model is to maximize or minimize its outcome variable. An outcome variable is sometimes referred to as the _response_, the _target variable_, or the _dependent variable_. See _goal_.
Outlier
If Einstein detects outliers in your data, it means that a variable contains data points that are unusually distant from the average value (more than five times the standard deviation from the mean for that variable). Uncommonly large or small numbers, potentially from data entry errors or rare events, affect averages (means) and standard deviations, which can reduce the accuracy of insights or predictions. Outliers can be selectively excluded from a model.
Overfitting
In predictive modeling, _overfitting_ occurs when a model performs well in predicting outcomes on the training data in the data, but less well when predicting outcomes for novel, or unseen data, such as production data. Using too many variables can result in an overly complex predictive model that captures the noise in your data. To mitigate overfitting, created models in AI Models use ridge regression and regularization. See also _underfitting_.
Performance
For predictive models, performance is a qualitative measure of how accurately a model predicts outcomes. For created models in AI Models, use the model’s training metrics to evaluate performance.
Predicted Outcome
A _predicted outcome_ is the result that a predictive model estimates or forecasts based on input data and learned patterns. It represents the model’s best guess for the target variable.
Prediction
In AI Models, a prediction is a derived value (produced by a model) that represents a predicted outcome. You can think of a prediction as the output of a predictive model.
Predictive Model
See _model_.
Predictive Modeling
_Predictive modeling_ is the practice of analyzing historical and current data, based on AI, machine learning, predictive modeling, and statistical techniques to identify patterns and predict probabilistic future outcomes. Predictive modeling is sometimes called _predictive analytics_ or _predictive AI_.
Predictor or Predictor Variable
A variable that a model expects as input. A prediction request passes values for each predictor variable that the model requires. Based on the provided input values, the model's equation produces a prediction as an output. Predictors are also known as _features_ and _independent variables_.
Prescription
A _prescription_ is a suggested action that can improve the likelihood of a desired outcome. Prescriptions are associated with _actionable variables_, which are explanatory variables that people can control. Taking a suggested action can improve the _predicted_ outcome.
R2
_R2_ measures a regression's model's ability to explain variation in the outcome. It represents the proportion of the variance in the outcome variable that is predictable from one or more variables. In general, the higher the R2, the better the model predicts outcomes. R2 is a commonly used metric for regression use cases that predict numeric values.
Ranked Data
_Ranked data_ is used to distribute data by probability. Also known as cumulative fraction, ranked data is often presented as deciles or quantiles. In training metrics for created models in AI Models, gain and lift charts are plotted on an x-axis of percentage of ranked data. For example, a ranked data of 0.1 equates to the top decile, or the 10% of records with the highest scores.
Regression
A _regression_ applies to model outcome variables that are numeric. Predicting a number field is a regression problem with its own set of metrics to measure model quality. In predictive modeling, linear regression is used for numeric outcomes. The numeric use case is one of the main use cases that created models in AI Models support.
Request
An endpoint request is a client's request to a specific URL or endpoint on a server. This request includes the HTTP method, headers, parameters, and, if applicable, a request body.
Residual
A _residual_ is the mathematical difference between the observed (or actual) value and the predicted value. It's calculated as `residual=observed value-predicted value`. Residuals are also known as errors, and are used to assess model quality and accuracy. A positive residual means the prediction was too low, while a negative residual means the prediction was too high.
Response
An endpoint response is a server's reply to a client’s request. The request includes an HTTP status code indicating the success or failure of the request, headers providing metadata about the response, and, if applicable, a response body containing the requested data or additional information.
Retriever
A retriever returns relevant facts from textual data, which is indexed in the vector database, to augment a Large Language Model (LLM) prompt. By augmenting prompts with accurate, current, and pertinent information, retrievers improve the value and relevance of LLM responses for the user.
Ridge Regression
_Ridge regression_ is a regularization approach that created models in AI Models use to mitigate model overfitting by preventing coefficients from getting too large.
Sampling
Technique of randomly selecting a subset of observations to analyze for the purpose of reducing the time needed to analyze the data. The sample should be large enough to be sufficiently representative of the variability in the data.
Score
(noun) A prediction associated with an observation. (verb) The process of predicting outcomes for a set of observations.
Secret Key
A secret cryptographic key that’s associated with an API endpoint. The key authenticates and authorizes endpoint requests.
Segment
A _segment_ is a subset of observations (rows) that meet the criteria specified in the segment filter. See _segmentation_.
Segmentation
Segmentation involves filtering data to focus predictions on a particular group, such as a customer type or region.
Sensitive Variable
A sensitive variable contains data that could potentially be associated with unfair treatment. Some examples are variables associated with race, gender, religion, national origin, sexual orientation, disability, or age. Less obvious examples include proxy variables, such as street address or ZIP code, which can reflect discriminatory practices.
Signal
Signal is an indication of a statistically significant and potentially meaningful pattern in your data. For example, an insight can describe a high correlation between a variable and the outcome variable. By investigating the relationship further, you can learn whether the correlation helps explain variations in the outcome (possible signal) or not (possible noise). Sometimes referred to as a _hint_.
Sync Type
The method used to synchronize data between different systems, devices, or applications. Synchronization is the process of maintaining consistency between two or more datasets.
Terminal State
Data that is finalized and not expected to change. An example of finalized data is the date on which an order shipped. A record that has reached its terminal state represents an _actual_ outcome (also called _observed outcome_). Define the conditions under which your model’s outcome variable has attained its terminal state.
Text Variable
See _categorical variable_, _binary outcome_.
Threshold
In a binary classification model, the _threshold_ value tells your model how to classify a binary outcome. For created models in AI Models, if the calculated probability is above the threshold value, Einstein classifies the outcome one way (such as True or Positive). If the calculated probability is below the threshold value, Einstein classifies the outcome the other way (such as False or Negative). The default threshold is 0.5, but you can tune this value up or down to accommodate your use case. The threshold is sometimes called the _Classification Threshold_ or _Decision Threshold_.
Tokens
The units of text that the large language models (LLMs) process and generate. Tokens act as a bridge between the raw text data and numerical representations that LLMs can work with. Examples of units include individual characters, words, subwords, or larger linguistic units.
Top Predictors
_Top predictors_ are the conditions that most significantly drive the predicted outcome, in decreasing order of magnitude. A condition is a data value associated with a column. In created models in AI Models, a predictor consists of one or two conditions. See _predictor variables_.
Training Set
In predictive modeling, the _training set_ is the portion of the data that is used to train the model to make predictions. See also: _validation set_.
Underfitting
In predictive modeling, _underfitting_ occurs when a model performs poorly in predicting outcomes on the training data in the dataset. Underfitting is often a result of an excessively simple model in which there aren't enough variables for a statistical algorithm to capture the underlying patterns in the data. See also _overfitting_.
Unstructured Text
Free-form text that varies in content and length. Examples include customer comments, survey feedback, social media postings, text messages, and emails. Contrast with _categorical variable_.
Validation Set
In predictive modeling, the _validation set_ is the portion of the data used to validate the predictions generated by the trained model. See also: _training set_.
Variable
A _variable_ represents a characteristic of the data you’re analyzing. A variable is analogous to a column in a table or a field in a Salesforce object. For example, an opportunity has variables—such as the opportunity type, lead source, fiscal year, lead source, expected amount—that describe properties associated with each opportunity. Each variable has one data type (number, text, or date). In predictive modeling, relationships among two types of variables are analyzed: outcome variables and variables. Data scientists sometimes refer to variables as _attributes_ or _features_.
XGBoost
_XGBoost_, or extreme gradient boosting, is an extension of GBM that’s optimized for efficiency. XGBoost is a decision tree-based, ensemble machine learning algorithm where groups of decision trees are built sequentially to better fit the data, while avoiding overfitting.
#### See Also
- [_Salesforce Help:_ About Predictive AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_about.htm&release=264.0.0&type=5 "Learn key concepts for working with predictive models in AI solutions.")
# Google Audience Insights in Activation
Delve into your customers’ unique characteristics, interests, and behaviors with insights from a Google audience report within Data Cloud. After you activate a segment to Google, an audience report is generated in 5–7 days. The report provides insights in terms of demographics and customers who are actively researching products and their affinity groups based on their lifestyle, long-term buying habits, and interests.
## Report Scores
The report generates scores by comparing the activated segment membership population, known as the Customer Match audience, with the average Google user population in a particular country. The scores represent the likelihood of members within the Customer Match audience being part of a specific demographic or behavioral category.
Demographics categorize the members based on age and gender. The In-Market category shows customers who are actively researching products, so potentially in the market for specific services or products. Affinity categorizes customers who exhibit specific characteristics.
For the In-Market and Affinity categories, the report includes up to 20 scores. The insights selected are based on the top 20 highest scores.
## Considerations and Privacy
To qualify for audience insights reporting, the activated segment population must be more than 1,000 users. The report is updated when there’s a major change to the segment membership.
To ensure that insights remain anonymous and can’t be linked back to individuals, Google implements privacy safeguards. Some of the privacy measures include:
- Category redaction—In certain cases, high-indexing categories are excluded from a report if the user population is considered too small. This exclusion preserves user privacy.
- Differential privacy—To protect individual membership records without significantly impacting reporting results, Google employs algorithms that add randomized noise to the reports. As a result, insights scores are considered approximations and can exhibit slight fluctuations over time.
#### See Also
- [_Salesforce Help_: Create an External Activation Target in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&type=5&language=en_US)
- [_Salesforce Help_: Create an Activation for an External Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activations.htm&type=5&language=en_US)
# Govern and Secure
Establish and control access, visibility, and data security with key features including data spaces, data governance, and encryption in Data 360.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
Here are some benefits of planning and developing a governance and security strategy.
- Earn and keep customer trust. Adopting data ethics and privacy best practices makes sure that your customers feel confident sharing their information with you.
- Follow regulatory compliance. Built-in tools help you meet strict privacy laws and industry regulations by managing consent and honoring data rights.
- Safely power AI. Strong data governance ensures that AI agents provide accurate, context-aware answers without exposing underlying personally identifiable information (PII) to unauthorized users.
- Scale securely. By implementing automated, policy-driven governance, you guarantee that the right users have access to the exact right data at scale, reducing the risk of unauthorized access or data leaks.
- **[About Data Spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces.htm&release=264.0.0&type=5)**
A data space is a logical partition to organize your data for profile unification, insights, and marketing in Data 360. You can segregate your data, metadata, and processes into categories, such as brand, region, or department, and then enable users to see and work on data only in the context of their category. You can also merge and analyze data in data spaces.
- **[Data Governance in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_gov_capabilities.htm&release=264.0.0&type=5)**
Data governance provides a robust framework for securing and managing data through the combined use of tags, classifications, user attributes, and policy-based governance. Enabling policies and other governance features improves control and ensures users have access to the right data at scale.
- **[Platform Encryption for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_platform_encryption_for_data_cloud.htm&release=264.0.0&type=5)**
Some customers require tenant-specific encryption keys, control over key material, or improved key visibility for auditing and compliance reporting. Platform Encryption for Data 360 extends Data 360’s robust security services by adding options for encryption key control and visibility.
- **[Ethics, Privacy, and Consent](https://help.salesforce.com/s/articleView?id=data.c360_a_consumer_rights.htm&release=264.0.0&type=5)**
Understand the concept of ethical data use and learn how to incorporate data ethics into your Data 360 implementation. Learn about how to protect your consumer’s privacy, data rights, and manage consent.
# Grant Data Cloud One Access to Users
Users in companion orgs must be assigned the Data Cloud One User permission set to access Data Cloud One in their org. To view data in shared data spaces, users must be assigned permission sets that have the data spaces they need associated with them.
1. In the companion org, in the Data Cloud connections section, click on **Assign Users**.
2. Assign Data Cloud One permission sets to the intended users who need to access Data Cloud One app.
#### See Also
- [_Salesforce Help_: Partition Your Data with Enhanced Security Data Spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_secure_data.htm&type=5&language=en_US)
- [_Salesforce Help_: Associate Permission Sets with Data Spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_associate_perm_sets.htm&type=5&language=en_US)
- [_Salesforce Help_: Grant or Remove Access to Data Explorer or Profile Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_data_explorer_permissions.htm&type=5&language=en_US)
# Grant or Remove Access to Data Explorer or Profile Explorer
Data Explorer and Profile Explorer are enabled by default for Data 360 admins and data aware specialists. To make them available to users in other roles, or to remove access from roles that have it by default, create custom permission sets.
### Required Editions
User Permissions Needed
To create permission sets:
Manage Profiles and Permission Sets
To assign permission sets:
Assign Permission Sets
AND
View Setup and Configuration
1. Clone an existing Data 360 permission set.
1. From Setup, in the Quick Find box, enter Permission Sets, and then select **Permission Sets**.
2. Clone one of the existing Data 360 permission sets and give it a unique name. For example, Data Cloud Marketing Manager Data Explorer Users.
Cloned permission sets grant the same permissions as the set they were cloned from. Clone different permission sets to match each role your users have in Data 360.
3. Click **Save**.
2. Edit the permissions in your new permission set.
1. Find the new permission set on the list of permission sets. Click its name.
2. Click **System Permissions**, then click **Edit**.
3. To enable access to Data Explorer, select **Access Data Cloud Data Explorer**. To enable access to Profile Explorer, select **Access Data Cloud Profile Explorer**. If you're removing access, deselect the permission.
4. Click **Save**, then confirm your changes.
3. Assign the new Data 360 permission set to users.
1. Click **Manage Assignments**, then click **Add Assignment**. Select the users you want to add this permission to.

Note You can only add users who have a Data Cloud or Data Cloud for Marketing license.
2. Click **Save**.
# Group Individuals into Households
Household matching lets you consolidate unified individuals into groups of individuals called households. Households use the Unified Individual object as the primary data model object for the ruleset and output to the Unified Household object.
Before you can create households, you must first set up a ruleset based on the Individual object and run it to produce Unified Individual profiles. Then set up a ruleset based on the output of an Individual ruleset.
Each household group is designated with a separate UUID. Output from the ruleset is stored in the Unified Household object.
#### See Also
- [_Salesforce Help_: Match Rules for Households](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_households.htm&release=264.0.0&type=5 "You can add only one match rule to a ruleset when configuring household matching in Data 360 identity resolution. Each unified household contains one or more individuals. We recommend matching individuals into households based on either last name and address or on party identifier.")
# Group, Rank, and Limit Segment Audience
The grouping, ranking, and limiting rules in Data 360 Segmentation adds advanced, multi-level filtering to the segment builder. After your standard filters are applied, you can use sequential logic to group, rank, and limit your segment population, creating more structured and balanced audiences.
### Required Editions
The grouping, ranking, and limiting rules provide these advanced filtering options:
- Group Data: Bundles records together based on a shared attribute (for example, grouping all contacts that belong to the same Account ID).
- Sort Data (Rank): Orders the records within each group based on a specific attribute, such as sorting accounts by a Fit Score in descending order.
- Limit Data: Restricts the number of records selected from each ranked group (for example, keeping only the top 10 accounts).
For example, you can:
- Rank accounts within a region and target the top three accounts per region.
- Within each shortlisted account, rank contacts by authority level and target the top three contacts per account.

Note Ranking and limiting rules apply only within the qualified profiles that pass the include and exclude conditions. They don’t perform global ranking across the entire dataset.
## Considerations
- Grouping, ranking, and limiting is available for segments based on Profile DMOs and Engagement DMOs. When building rules, you can only use direct attributes and aggregatable calculated insights. Ranking and Limiting aren’t supported for related attributes.
- A segment that uses grouping, ranking, and limiting rules can be nested inside another segment only in Last Membership mode. The Segment Criteria option isn’t available for these segments. Grouping, ranking, and limiting is not supported for DBT, realtime, or dynamic segments; for waterfall segments, these rules can only be applied to child segments; and segments using these rules don’t qualify for approximate count.
- Include a limit rule in each ruleset (or container). You can create a ruleset with a limit rule by itself, or combine it with one or more sort and group rules.
- A maximum of three group rules and three sort rules are allowed within a single ruleset.
- To preserve the filtering logic, you can delete only the last ruleset in a sequence. You can add a new ruleset only if the preceding container includes a Group By rule.
- Records filtered out by these rules are added to the 'Excluded Population' count for your segment
- When you add an attribute to a ruleset, Data 360 determines the relationship path back to your main segment-on entity (for example, Individual or Account Contact). Sometimes, there can be multiple relationship paths to the same data. For consistency, you only select a container path once per object within a ruleset. This path is then automatically reused for any other attributes you add from that same object.
- **[Refine Segments with Grouping, Ranking, and Limiting](https://help.salesforce.com/s/articleView?id=data.c360_a_apply_grl_rules_segment.htm&release=264.0.0&type=5)**
In Data 360 Segmentation, after setting your initial criteria in the Include and Exclude tabs, go to the Rank and Limit tab to further refine your segment. The first container is automatically created and locked to your segment's primary entity. This container defines your innermost filtering rule.
# Guide Data Q&A with Semantic Enrichments
Add semantic statements to help the Data 360 Data Q&A Agent better understand your data's business context, domain-specific terminology, and relationships.
### Required Editions
Semantic enrichments are statements you create to provide business and data context to the Data 360 Data Q&A Agent. These statements help the agent interpret your questions more accurately and generate better SQL queries by explaining domain-specific terminology, business rules, data relationships, and calculation methods.
## Why Use Semantic Enrichments
While the agent can analyze your data's schema and relationships automatically, it doesn't inherently understand your business context. Semantic enrichments bridge this gap by teaching the agent:
- **Business terminology:** What "active customer" or "qualified lead" means in your organization
- **Calculation methods:** How to compute metrics like "customer lifetime value" or "conversion rate"
- **Data quality rules:** Which fields to use, which to avoid, and why
- **Relationships:** How objects connect beyond foreign key relationships
- **Filtering conventions:** Default filters or conditions that should apply to certain queries
## How Semantic Enrichments Work
When you ask the agent a question, it considers the applicable semantic enrichments along with the data schema to generate its response. The agent finds the enrichments most relevant to your question based on:
- Object scope (specific object or all objects)
- Field scope (specific field within an object)
- The natural language content of your question
- Lookup summaries that map expected question phrases to the enrichment
Enrichments marked as Critical are always considered. To keep responses accurate, focus each enrichment on a distinct aspect of your data model and avoid contradictory guidance for the same data.
## Scope Levels
Semantic enrichments can be scoped at different levels:
Object
Applies to a specific Data Lake Object (DLO) or Data Model Object (DMO). Use for object-specific terminology or calculation methods.
Field
Applies to a specific field within an object. Use for field-level data quality guidance or interpretation rules.
## Examples of Effective Semantic Enrichments
| **Use Case** | **Semantic Statement Example** |
| --- | --- |
| Define business term | "Active customers are those with status = 'Active' and at least one order in the last 90 days." |
| Explain calculation | "Customer lifetime value is calculated as total\_revenue divided by months\_active, multiplied by average\_customer\_lifespan\_months." |
| Data quality guidance | "When filtering string columns, always use lowercase comparisons because some legacy data has mixed case values." |
| Field interpretation | "The amount\_usd\_\_c field represents deal size in US dollars. Use this field for revenue calculations." |
| Default filter | "For opportunity queries, exclude stage = 'Closed Lost' unless explicitly requested." |
## Best Practices
- Write statements in clear, plain language that explains context, not just definitions.
- Be specific about when and how rules should apply.
- Mark critical enrichments with the critical flag to ensure the agent prioritizes them.
- Test enrichments by asking the agent questions and reviewing the generated SQL.
- Keep enrichments up to date as your data model and business rules evolve.
## Topics
- **[Create a Semantic Enrichment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_semantic_enrichment.htm&release=264.0.0&type=5)**
Add business context to improve how the Data 360 Data Q&A Agent interprets and responds to questions about your data.
- **[Manage Semantic Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_manage_semantic_enrichments.htm&release=264.0.0&type=5)**
Edit, deactivate, or delete semantic enrichments as your data model and business rules evolve.
# Guidelines and Limits for Automations
You can configure automations based on your requirements using the Data 360 actions. When planning an automation, make sure to review the guidelines and limits. Throttling limits the maximum number of API requests triggered within a specified time period.
### Required Editions
Available in: Lightning Experience
| Item | Throttling Limit |
| --- | --- |
| Data ingestion (Salesforce CRM and Amazon S3 data streams) | 4 times in a 24-hour period per data stream |
| Calculated insights | 3 times in a 24-hour period per calculated insight |
| Identity resolution | 4 times in a 24-hour period per ruleset job |
| Segmentation and activation | 6 times in a 24-hour period per segment |
The API requests are triggered from a flow, a schedule, and manually from the UI by clicking **Run**. You can disable schedule (if available) for an action to avoid triggering API requests multiple times.
| Item | Trigger from Flow | Manually Trigger from UI | Trigger from Schedule |
| --- | --- | --- | --- |
| Amazon S3 data streams | Yes | Yes | Yes |
| Salesforce CRM data streams | Yes | Yes | No |
| Marketing Cloud Engagement connector | No | No | No |
| B2C commerce connector | No | No | No |
| Google Cloud storage connector | No | No | No |
| Calculated insights | Yes | Yes | No |
| Identity resolution | Yes | Yes | No |
| Segmentation and activation | Yes | Yes | Yes |
# Hierarchical Aggregation in Segment Filters
Hierarchical aggregation provides a comprehensive view of your data by rolling up revenues for accounts and their subsidiaries. You can then define more precise segment filters based on an aggregate value across multiple levels.
Hierarchical aggregation offers several advantages:
- Accurately reflect your hierarchical account structures when performing data aggregations.
- Gain a more comprehensive view of your data by rolling up revenues for accounts and their subsidiaries. Use the aggregated values to create more precise and meaningful segment filters.
## Example
Global Corp, which oversees several regional branches and local offices, has a total opportunity value (potential sales or deals) of $300,000. The US Branch contributes $100,000 to this total, and the two EU Branch local offices each contribute $100,000.
The total opportunity value for Global Corp is:
- $100,000 from the US Branch
- $200,000 from the EU Branch (sum of Local Office 1 and Local Office 2)
This hierarchical aggregation shows how the opportunities are structured from the top-level company down to its regional branches and local offices.
To use hierarchical aggregation, you enable it when [creating a container for segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_use_a_container.htm&language=en_US).
# High Frequency Values Alert
High frequency values indicate that most values in a variable are in the same category. It indicates that the variable provides little predictive value and can limit its contribution to the model.
## Actions to Consider
Update the variable with a more even distribution of data values. Alternatively, consider removing the variable from the model.
## Detection Methodology
Model Builder displays an alert for a variable when a single value in the dataset occurs at least 90% of the time (relative frequency of 0.9 or higher).
## Example
An e-commerce retailer wants to predict its customers' propensity to buy a brand across different regions. To achieve this, the retailer builds a regression model with these input variables.
- product ID
- customer ID
- sales channel
- frequency of purchase
- region
After model training, an alert displays because the data indicates that 95% of customers who are likely to purchase the brand are in the USA, and only 5% are in Canada. The model assumes that the USA is the best region for the brand's customers. However, because the "region" variable has low variability, this variable isn't meaningful for predictions. To resolve the issue, here are some actions to consider.
- Use one value and remove the less dominant one. For example, consider customer data for the USA and not Canada. Or, else remove the "region" variable from the dataset.
- Retrain the model with an updated dataset that has a better representation of data values for other regions in addition to the USA.
# History Tracking Considerations
Keep these considerations in mind when using history tracking.
- History tracking is only available for calculated insights. History tracking isn't available for streaming or real time insighst.
- Changes that affect the schema of a source calculated insight object (CIO), such as adding a new measure, truncate the history CIO data and remove existing history. History tracking resumes with the new schema on the next history job run.
To retain history data, create a new source calculated insight and turn on history tracking for it.
- History tracking doesn’t impact billing for the source calculated insight. History tracking CIO billing is under the Data Queries usage type. See [Billing Considerations for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_insights.htm&release=264.0.0&type=5 "Insights uses Data 360 to define and calculate multi-dimensional metrics across unified customer data to power real-time personalization and analytics. Use of insights impacts the consumption of credits used for billing in these usage types.").
# Honor “Do Not Share” and "Do Not Sell" Requests in Data 360
Understand how to comply with the California Privacy Rights Act (CPRA) and other laws that give consumers the right to restrict sharing their data with or selling it to third parties.
## Ingest “Do Not Share” and "Do Not Sell" Data
Ingest individuals’ data about Do Not Share and Do Not Sell as part of the data stream. To ensure that the data is properly handled in Data 360, reconcile and store it in Unified Individual data model objects (DMOs).
1. Create a custom field in the Individual DMO to store Do Not Share or Do Not Sell request data.
2. Map your Do Not Share or Do Not Share request data to that field.
3. Use reconciliation rules in your Identity Resolution rulesets to determine how the data is processed and stored for Unified Individuals.
## Filter for “Do Not Share” and "Do Not Sell" Requests
Filter out unified individuals who have opted not to have data shared during segmentation.
When setting up the segment, create a direct attribute based on the Unified Individual DMO field in which Do Not Share or Do Not Sell data is stored. Apply this filter to all data about individuals before providing it to third parties.
#### See Also
- [_Salesforce Help_: Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5 "A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.")
- [_Salesforce Help_: Segmentation Interface](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_interface.htm&release=264.0.0&type=5 "After you create a segment, narrow your data based on related or direct attributes on the segment canvas interface. Narrow down a subset of the population from a filtered audience to see who’s included and excluded. Segment exclusion is optional.")
# How the Max Token Setting Affects Chunking
When you set the chunking strategy in a search index configuration, you set the max token limit to control how much text is included in a chunk. In Data 360, the max token limit is set to 512 by default.
Embedding models create tokens from text and they ignore any text beyond their max token limit. However the concept of "token" differs by language as well as by embedding model, so it is not reliable to count chunks directly from text.
When you create a search index, token creation works as follows: Data 360 separates sentences in your content and then merges the sentences into chunks based on your specified max token setting. Finally, the embedding algorithm converts each chunk into a vector.
To approximate the token count when merging sentences into chunks, Data 360 uses the number of words for Latin-based languages and the number of punctuation marks for non-Latin-based languages (such as Japanese). In Latin-based languages, a word is approximately one token, but in non-Latin-based languages, the relationship between characters and tokens isn’t as clear. With that in mind, a Latin-based language chunk of 512 words is typically within the 512 token limit. For non-Latin-based languages, however, 512 punctuation marks can exceed 512 tokens due to how the embedding algorithm works. In such cases, not all text that is included in the chunk gets included in the embedding, which can impact the relevance of your search results. For this type of content, use a max token limit lower than 512.
# How to Write a Good Prompt for Einstein Segments in Data 360
When creating a segment, use certain formats and language to get the best results possible. Provide descriptive names for data model objects (DMOs) and attributes to ensure that generative AI can understand them. OpenAI was trained on data that leans toward the United States, which influences Einstein’s responses. If you require a specific country, enter the name of the country in the prompt.
## Writing Good Prompts
Here are some examples to help you improve your results. The generative AI model isn’t always consistent when answering requests, so you might get different results when entering the same prompt.
| Best Practice | Not Recommended Prompt | Recommended Prompt |
| --- | --- | --- |
| Use custom field names in the prompt. | Create a segment of all Northern Trail Customers | Create a segment of all Brand="Northern Trail" customers |
| Make the prompt specific, not general. | Customers who live in the UK | Customers who live in the UK who engaged with my product in the past 60 days |
| When requesting brand data, specify it. | Customers who engaged with my website | Customers who engaged with the website "mywebsite.com" |
| Use “and” instead of commas. | Customers who like running, cycling, swimming | Customers who like running and cycling and swimming |
| Don’t use one-word prompts. | Fishermen | Customers who enjoy fishing |
| Be explicit, not implicit. | Top customers | 10% highest paying customers |
| Avoid complex date filters | Customers with cases closed in the last week of every month | Customers with cases that closed this past month |
## Supported Operators
When you write a prompt, enter accurate descriptive text. Use these operators to specify information. When writing prompts, you can’t use the OR and Exclude operators.
Text
- Equal
- Not Equal
- In
- Not In
- Has Value
- Has No Value
Numbers
- Equal
- Not Equal
- Less Than
- Less Than Or Equal
- Greater Than
- Greater Than Or Equal
- Between
- Has Value
- Has No Value
- Is Not Between
Dates
- Is Anniversary Of
- Is Not Anniversary Of
- Day Of Month
- Is Yesterday
- Is Today
- Is Tomorrow
- Before Day Of Month
- After Day Of Month
- Not Day Of Month
- Day of Week
- Equal
- Between
- Month Of Year
# Hybrid Search
To provide relevant information to an LLM with gen AI applications and generate the correct response, requires both vector search and keyword search. Vector search understands semantic similarities and context, but lacks specific domain vocabulary. Keyword search excels at lexical similarity but not at semantic similarity. In Data 360, hybrid search combines the strengths of semantically aware vector search with the precision and speed of keyword search.
### Required Editions
For example, vector search understands that “How to log in to my account?” and “How can I sign on?” are similar queries. But vector search can fail to understand that a search on “LaserPrinter TX 400” and “LaserPrinter TX 440” are also similar because it doesn’t match numbers well or specific domain terms such as a LaserPrinter, which keyword search can.
Hybrid search indexes the information in the DMO or UDMO to retrieve relevant results. Before you create a hybrid search index, unstructured data stored in DMOs and UDMOs are chunked. Chunking breaks the DMOs and UDMOs into manageable, semantically meaningful units.
Next, data indexing generates vector embeddings for a vector search index and a keyword search index for the DMOs and UDMOs. You manage the search index creation, deletion, and hydration using the Data 360 search index UI interface and APIs.
With hybrid search, the vector search index is queried to retrieve information based on semantic similarity and the keyword search index is queried to retrieve information based on lexical similarity. Hybrid search then merges and ranks the results provided by both types of searches to generate the best response. You can also configure additional ranking factors, such as recency or popularity of records, to influence the search results returned.
After you create a search index in Data 360, you can perform searches on that data from apps such as Prompt Builder, AI agents, or Tableau.
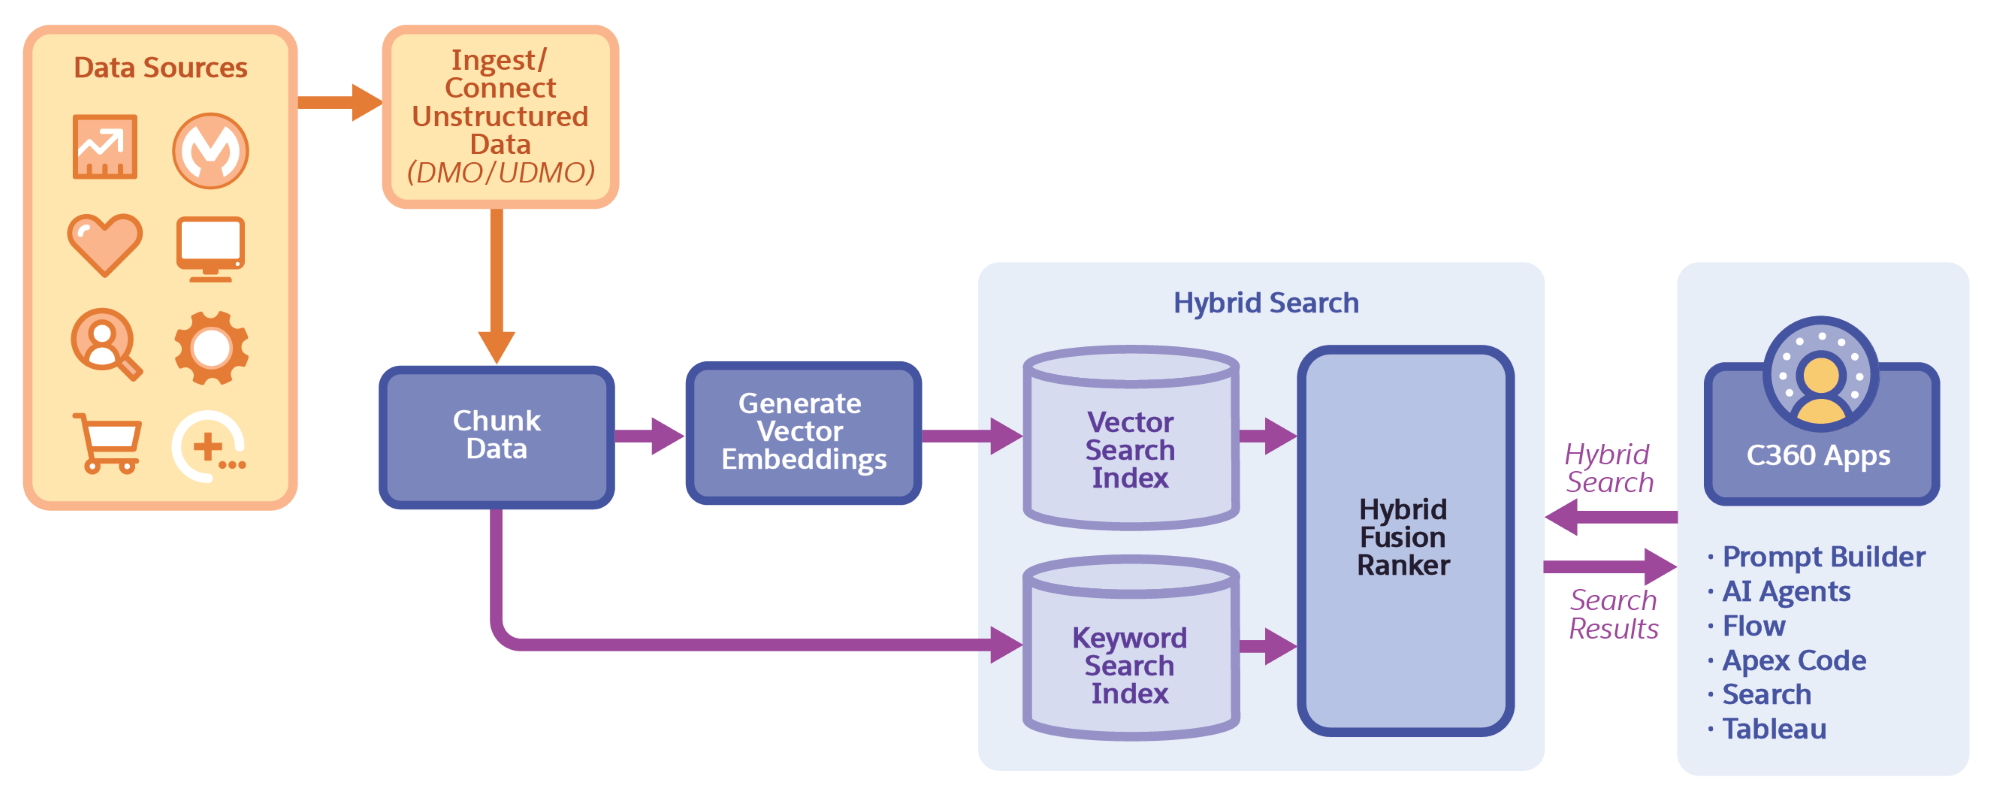
- **[Create a Hybrid Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&release=264.0.0&type=5)**
Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.
- **[Run Hybrid Search Queries with Query API](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_query.htm&release=264.0.0&type=5)**
Use Query API to run hybrid searches in Data 360. Use these examples as starting points.
- **[Hybrid Search Query Expressions](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_query_expressions.htm&release=264.0.0&type=5)**
Enhance your hybrid search queries with pre-filtering fields and join expressions to access fields.
- **[Hybrid Search Fusion Ranking](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_fusion_ranking.htm&release=264.0.0&type=5)**
Ranking reorders the search results so that the most relevant results to a user query are at the top. Data 360 Hybrid search retrieves results from two indexes—keyword and vector— based on the similarity with the query and then merges (fuses) the results. The ranking model then reranks the merged results.
- **[Influence Hybrid Search Relevance Ranking](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_relevance_configuration.htm&release=264.0.0&type=5)**
Increase the accuracy of search index query results and improve the quality of RAG applications by sending relevance-specific parameters. Using SQL, you can send relevance configuration settings for supported fusion ranker models and improve the result relevance for your specific use case.
- **[Hybrid Search Autodrop Results](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop.htm&release=264.0.0&type=5)**
Dynamically filter out results that show a sharp decrease in relevance scores to increase the precision of search results for your prompts and RAG use cases. Data 360 hybrid search autodrop is a method by which you can filter out irrelevant search results that can mislead upstream applications like prompt builder using those results.
- **[Hybrid Search Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_best_practices.htm&release=264.0.0&type=5)**
Enhance your hybrid search retrieval and search relevance by chunking the correct fields, selecting pre-filter fields, and adding ranking factors.
- **[Hybrid Search Autodrop Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop_best_practices.htm&release=264.0.0&type=5)**
Use these best practices to configure autodrop for Data 360hybrid search results.
#### See Also
- [_Salesforce Help_: Create Vector Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_index.htm&release=264.0.0&type=5 "In Data 360, you can create searchable semantic vector embeddings from your unstructured and structured data. Vector search helps your generative AI, automation, and analytics applications understand semantic similarities and context between embeddings.")
# Hybrid Search Autodrop Best Practices
Use these best practices to configure autodrop for Data 360hybrid search results.
- Use these recommended values for autodrop, for keyword search results use 2 and for vector search results use 5. Test these configurations and adjust them as needed for your use case and queries.
- For keyword search results we recommend autodrop value of 2 and for vector search results we recommend a autodrop value of 5.
```
{ "autodrop_keyword": {"num_drops": 2}, "autodrop_vector":{"num_drops": 5 }}
```
- The default autodrop value is less aggressive for keyword search results.
```
{ "autodrop_keyword": {"num_drops": 5}, "autodrop_vector":{"num_drops": 5 }}
```
- Due to the nature of hybrid search results distribution autodrop can lead to unexpected behavior. We recommend that you use the “autodrop\_vector” and “autodrop\_keyword” parameters instead of the “autodrop\_hybrid” parameter.
```
select * from hybrid_search(
table(),
‘’,
'',
'',
‘{ "autodrop_keyword": {"num_drops": 2}, "autodrop_vector":{"num_drops": 5 }}’
);
```
- To ensure your search results include the most relevant results, calibrate the number of autodrops with a set of test queries and gradually vary the value until the relevant results are present in the result set.
To make hybrid search autodrop less aggressive and retain more results, consider increasing the num\_drops value. An overly aggressive autodrop can cut off important documents, especially if score drops aren't pronounced in your data set or if you have a broader definition of relevant results. You can adjust “autodrop\_keyword”, “autodrop\_vector”, or “autodrop\_hybrid” based on where you notice a loss of relevant results.
To make hybrid search autodrop more aggressive and retain the most highly relevant results, decrease the value of num\_drops. For instance, if your search results still include a significant number of irrelevant documents even after the initial autodrop, and the default num\_drops doesn’t’ effectively filter out the noise, you should decrease the num\_drops value.
- If the value of autodrop exceeds the actual number of score drops in the list, no truncation is applied.
- If documents contain many similar terms, applying autodrop on keyword results helps to keep only the most relevant results.
- Alternatively, you can simply reduce your result set by setting a limit on the number of results returned for a query. For more details see, [Run Hybrid Search Queries with Query API](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_query.htm&type=5&language=en_US). In this example, the limit is set to two results for the query.
```
select * from hybrid_search(
table(Knowledge_full_index__dlm),
'How to input special mark/character when using keyboard input data field','', 2)
```

Example This example shows a hybrid search query without autodrop configuration.
```sql
select Chunk__c, hybrid_score__c, keyword_score__c, vector_score__c, chk.SourceRecordId__c
from hybrid_search(table(Indeed_English_index__dlm), 'Maximize', '', 100, '{ "dfr" : {} }') hsearch
join Indeed_English_chunk__dlm chk on hsearch.RecordId__c = chk.RecordId__c
ORDER BY hybrid_score__c DES
```
With autodrop configured for vector search results and keyword search results, the search results are scoped down to the most relevant results.
```
select Chunk__c, hybrid_score__c, keyword_score__c, vector_score__c, chk.SourceRecordId__c
from hybrid_search(table(Indeed_English_index__dlm), 'Maximize', '', 100, '{ "autodrop_keyword": {"num_drops": 2}, "autodrop_vector":{"num_drops": 5 }}') hsearch
join Indeed_English_chunk__dlm chk on hsearch.RecordId__c = chk.RecordId__c
ORDER BY hybrid_score__c DESC
```
# Hybrid Search Autodrop Results
Dynamically filter out results that show a sharp decrease in relevance scores to increase the precision of search results for your prompts and RAG use cases. Data 360 hybrid search autodrop is a method by which you can filter out irrelevant search results that can mislead upstream applications like prompt builder using those results.
When you initiate a search query, the [hybrid search fusion ranking](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_fusion_ranking.htm&type=5&language=en_US) model derives an optimal ranking score for each search result it retrieves. The hybrid search autodrop option allows you to drop the results from one or more score cutoff points where the scores drop significantly. You can consider results beyond this cutoff point as less relevant to the query.
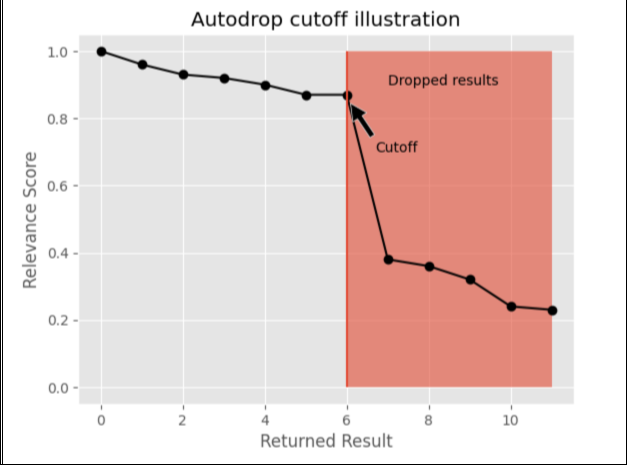
Autodrop is available only with hybrid search. Since hybrid search combines both vector search and keyword search, you can use query API to configure autodrop for the results of each search type in hybrid search, including vector search results, keyword search results, and the fused hybrid search results. Hybrid search analyzes the search result scores and filters irrelevant results. Hybrid search autodrop is disabled by default. Enable autodrop using Data cloud Query API.
- **[Hybrid Search Query Expressions for Autodrop](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop_query.htm&release=264.0.0&type=5)**
Use Data 360 Query API to configure autodrop for hybrid search results.
#### See Also
- [_Salesforce Help_: Hybrid Search Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop_best_practices.htm&release=264.0.0&type=5 "Use these best practices to configure autodrop for Data 360hybrid search results.")
# Hybrid Search Best Practices
Enhance your hybrid search retrieval and search relevance by chunking the correct fields, selecting pre-filter fields, and adding ranking factors.
Use chunking fields that provide context and semantic meaning. You can select multiple fields for chunking your data. Consider how you expect the retrieved results to be used in your gen AI application. For example, select fields such as title, body, or description of your records. Fields that have a small set of values, such as Open or Closed, aren’t ideal for chunking.
Increase the precision of search results by adding filter fields to narrow the results. Use filters that make sense for your application. For example, pre-filtering on the case status field can improve the relevance of search results on case conversation transcripts.
Refine result relevance with ranking models by sending relevance-specific parameters. Use advanced formulas from the Reciprocal Rank Fusion (RRF) and Linear Fusion Ranker (LFR) models to tweak parameter values and achieve relevant results.
Enhance relevance by adding ranking factors to your search index configuration.
- Add the popularity of records as a factor, such as selecting fields that track ViewCount. For instance, when you index a DMO created from CRM knowledge articles, import the entity KnowledgeArticleViewStat into Data 360, and use KnowledgeArticleViewStat.ViewCount as the popularity factor.
- Add recency of records as a factor. For example, when you index a DMO created from CRM knowledge articles, use LastModifiedDate\_\_C field as the recency factor.

Example This POST request creates a hybrid search index configuration on the Knowledge\_kav\_Home object. The configuration uses the Content field to chunk the data and the LastModifiedDate\_\_c field to track recency.
```
{
"label": "record9357",
"developerName": "record9357",
"description": "A sample description",
"sourceDmoDeveloperName": "Knowledge_kav_Home__dlm",
"chunkDmoName": "chunk9357",
"vectorDmoName": "vector9357",
"chunkDmoDeveloperName": "chunk9357",
"vectorDmoDeveloperName": "vector9357",
"searchType": "HYBRID"
"vectorEmbedding": {
"vectorEmbeddingRelatedFields": [
{
"relatedDmoDeveloperName": "Knowledge_kav_Home__dlm",
"relatedDmoFieldDeveloperName": "ssot__Name__c",
"relationships": [
{
"sourceDmoDeveloperName": "Knowledge_kav_Home__dlm",
"sourceDmoFieldDeveloperName": "Content_c__c",
"targetDmoDeveloperName": "Knowledge_kav_Home__dlm",
"targetDmoFieldDeveloperName": "Content_c__c"
}
]
}
]
},
"rankingConfigurations": [
{
"relatedDmoDeveloperName": "Knowledge_kav_Home__dlm",
"relatedDmoFieldDeveloperName": "LastModifiedDate__c",
"rankType": "RECENCY",
"developerName": "rank_time_freshness",
"relationships": [
{
"sourceDmoDeveloperName": "Knowledge_kav_Home__dlm",
"sourceDmoFieldDeveloperName": "Content_c__c",
"targetDmoDeveloperName": "Knowledge_kav_Home__dlm",
"targetDmoFieldDeveloperName": "Content_c__c"
}
]
}
],
"chunkingConfiguration": {
"fieldLevelConfigurations": [
{
"sourceDmoDeveloperName": "Knowledge_kav_Home__dlm",
"sourceDmoFieldDeveloperName": "Content_c__c",
"config": {
"id": "passage_extraction",
"userValues": [
{
"id": "max_tokens",
"value": "512"
},
{
"id": "strip_html",
"value": "true"
}
]
}
}
]
},
"vectorEmbeddingConfiguration": {
"embeddingModel": {
"id": "e5_large_v2",
"userValues": [
{
"id": "dimension",
"value": "1024"
},
{
"id": "max_token_limit",
"value": "512"
}
]
},
"index": {
"id": "HNSW",
"userValues": [
{
"id": "hnswEfConstruction",
"value": "8"
},
{
"id": "M",
"value": "4"
}
```
#### See Also
- [_Salesforce Help_: Hybrid Search Fusion Ranking](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_fusion_ranking.htm&release=264.0.0&type=5 "Ranking reorders the search results so that the most relevant results to a user query are at the top. Data 360 Hybrid search retrieves results from two indexes—keyword and vector— based on the similarity with the query and then merges (fuses) the results. The ranking model then reranks the merged results.")
- [_Salesforce Help_: Create Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&release=264.0.0&type=5 "Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.")
- [_Salesforce Help_: Hybrid Search Autodrop](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_relevance_configuration.htm&release=264.0.0&type=5 "Increase the accuracy of search index query results and improve the quality of RAG applications by sending relevance-specific parameters. Using SQL, you can send relevance configuration settings for supported fusion ranker models and improve the result relevance for your specific use case.")
# Hybrid Search Fusion Ranking
Ranking reorders the search results so that the most relevant results to a user query are at the top. Data 360 Hybrid search retrieves results from two indexes—keyword and vector— based on the similarity with the query and then merges (fuses) the results. The ranking model then reranks the merged results.
During setup, you can configure additional ranking factors, such as recency of records and popularity, to influence the ranking. The ranking factors are based on search index object fields or related object fields. For example, you can use the LastModifiedDate field of an indexed DMO to define the recency of a record.
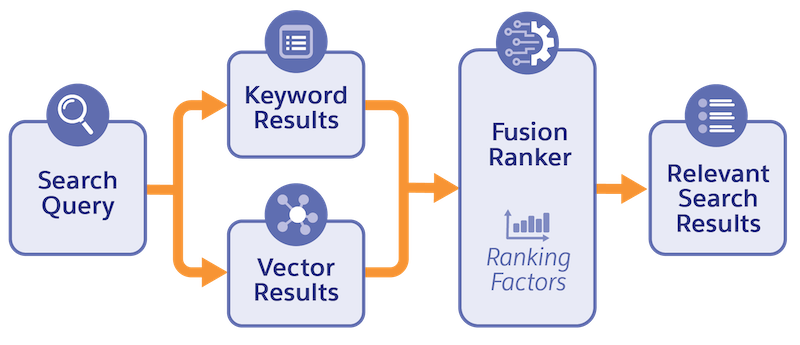
The Salesforce fusion ranker model is optimized on internal benchmarks for a variety of search-based tasks. The benchmarks measure the performance for precision, robustness, and sensitivity to produce a high-quality model. The criteria for evaluation are curated from a combination of user interactions on search responses and annotations. The training and evaluation data is based on captured queries from both Salesforce Einstein Search and RAG applications, such as Einstein Search Answers.
There are many factors that affect vector and keyword search similarity scores. For example, a keyword similarity score depends on the query text and the contents of the search index DMO. A vector similarity score depends on the query text and the specific embedding model for the search index. The fusion ranker model returns a hybrid search score that's a linear combination of the keyword and vector similarity scores along with the ranking factors.
To provide the best results for a general hybrid search use case, the model is fine-tuned for optimal combinations that include the normalization strategies for each score along with weights for each score. The fusion ranking model determines the final rank for a result based on the derived hybrid search score. The model can rank a result with a high hybrid search score even when one of the search similarity scores is zero. For example, a result with zero keyword score may get a high hybrid search score if its vector score is high enough relative to the vector scores of alternate results for the same search query.
Hybrid Search Scores
| Search Type | Score Parameter | Description |
| --- | --- | --- |
| Vector search | vector\_score\_\_c | The similarity score returned by the underlying vector search index for a given query. |
| Keyword search | keyword\_score\_\_c | The similarity score returned by the underlying keyword search index for a given query. |
| Hybrid search | hybrid\_score\_\_c | The score derived from combining the keyword and vector scores. This score takes ranking factors. such as document popularity and recency, into account. This score determines the rank of the results. |

Example Consider a hybrid search query with a search string that has a specific domain term, such as “V2MOM.” The ranking model returns a vector score, keyword score, and hybrid search score and then ranks the result set.
```sql
select * from hybrid_search(
table(),
"When is the V2MOM due?",
, );
```
| Chunk ID | Vector Score | Keyword Score | Hybrid Score | Final Rank |
| --- | --- | --- | --- | --- |
| A | 0.85 | 10.0 | 0.9 | 1 |
| B | 0.90 | 1.0 | 0.8 | 2 |
| C | 0.80 | 0.5 | 0.6 | 3 |
| D | 0.75 | 0.01 | 0.5 | 4 |

Example In this example, the hybrid search query includes the popularity and recency ranking factors, which influence the final rank.
```sql
select * from hybrid_search(
table(),
"How do I reset the password for my Acme account?",
, );
```
| Chunk ID | Vector Score | Keyword Score | Popularity | Recency(Days) | Hybrid Score | Final Rank |
| --- | --- | --- | --- | --- | --- | --- |
| A | 0.91 | 10.0 | 1000 (Highly Popular) | 10 (Recent) | 0.9 | 1 |
| B | 0.90 | 10.5 | 1 | 15 | 0.875 | 2 |
| C | 0.80 | 2 | 5 | 25 | 0.8 | 3 |
| D | 0.80 | 1 | 10 | 100 | 0.75 | 4 |

Note The examples show how hybrid search scores are derived from keyword and vector similarity scores along with the ranking factors. The score values aren’t absolute and realistically must be used only to compare ranking results for the same query.
#### See Also
- [_Salesforce Engineering Blog Post_ : How Data Cloud Hybrid Search Combines Keyword and Vector Retrieval to Elevate the Search Experience](https://engineering.salesforce.com/how-data-cloud-hybrid-search-combines-keyword-and-vector-retrieval-to-elevate-the-search-experience/)
# Hybrid Search Query Expressions
Enhance your hybrid search queries with pre-filtering fields and join expressions to access fields.
## Filter Expressions in Hybrid Search
Expressions Types
Examples
Notes
Expressions with NOT, IN, AND, OR operators
strField1 != 'v1' and
strField2 = 'v2' and
(strField3 = 'v3' or
strField4 not in ('a', 'b', 'c') or
strField5 in ('a', 'b', 'c')
) and
strField6='v6'
You can combine individual filters using the logical and and
or operators.
Simple pre-filter expression in a SQL expression
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'RecordId__c=''1c1c533c-1bc0-40cb-8bd8-f4b6e6e101b7''',
10)
)
When the pre-filter condition is part of the SQL expression the quotes in the
filter expression have to be escaped by doubling them.
Complex pre-filter expression in a SQL expression
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'strField1 != ''v1'' and strField2 = ''v2'' and
(strField3 = ''v3'' or
strField4 not in (''a'', ''b'', ''c'') or
strField5 in (''a'', ''b'', ''c'')) and
strField6=''v6''', 10)
When the pre-filter condition is part of the SQL expression the quotes in the
filter expression have to be escaped by doubling them.
Pre-filtering on a field that is of Number data type
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'NumField=2',
10)select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'NumField>2',
10)
—
Pre-filtering on a field that is of Date/DateTime data type with the standard
(Z) offset
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'DateTimeTypeWithTimezone=2024-05-08T15:28:07.000Z',
10)select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'DateTimeTypeWithTimezone>=2024-05-08T15:28:07.000Z',
10)
The date value doesn’t have to be surrounded by two single quotes (as vector
search does).
Pre-filtering on a field that is of Date/DateTime data type with a custom
offset
select * from (
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'DateTimeTypeWithTimezone=2024-05-08T15:28:07.000-08:30',
10)
The date value doesn’t have to be surrounded by two single quotes (as vector
search does).
Pre-filtering on a field with Date only
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'DateType=2024-05-08',
10)select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'DateType<2024-05-08',
10)
The date value doesn’t have to be surrounded by two single quotes (as vector
search does).
Pre-filtering on a field which is of string data type with the LIKE
operator.
select * from
hybrid_search(
TABLE('some_VDMO'),
'some_search_text',
'StrField LIKE ''prefix%''',
10)
The LIKE operator must be used with a value with a single trailing wildcard
character (%). The following are examples of invalid LIKE
filters.
'StrField LIKE ''%prefix%'''
'StrField LIKE ''%prefix'''
'StrField LIKE ''prefix%suffix'''
The LIKE operator doesn't support the following characters, : ^
{ } [ ] ( ). For example, the expression
Field__c LIKE 'https:%', is invalid because it contains a
colon (:).
## Case Sensitivity on Pre-filtering Fields
Names of pre-filtering fields are case insensitive. For example, if the name of a field is `My_Column_c` , a filter expression with `my_column_c` correctly references that field. However, case matters for values used within filters. If the field has a value `SomeValue,` the filter expression `My_Column_c='somevalue'` or `My_Column_c='SOMEVALUE'` results in a no-match—only the expression `My_Column_c='SomeValue'` matches that record.
## Default Pre-filtering Fields
The field `DataSource__c` from the chunk data model object (CDMO) is a default pre-filtering field. It is always available in pre-filtering queries.
## Pre-filtering Values for Objects in 1:N Relationships
When creating a search index, you can index only one pre-filtering value.
Consider this example. You create a search index in which the indexed chunk data model object (CDMO) is in a 1:N relationship with related records from which a pre-filtering value is extracted. In the relationship, the CDMO `{"chunkId":"1"}` matches both `{"filterRecordId"="123": "filterValue": "tag1"}` and `{"filterRecordId"="123": "filterValue": "tag2”}`.
Data 360 indexes only one of these filtered values for retrieval, and there’s no guarantee which one is indexed. For example, Data 360 may index`{"chunkId":"1", "filterValue":"tag1"}` or `{"chunkId":"1", "filterValue":"tag2"}` but not `{"chunkId":"1", "filterValue":["tag1", "tag2”]}`.
## Join Expressions in Hybrid Search
Include joins to access fields from both the Chunk DMO and Search Index DMO associated with the index.
```
SELECT
src.ArticleNumber__c,
hsearch.hybrid_score__c
FROM
hybrid_search(
TABLE(Knowledge_index__dlm),
'DataWedge Decode Volume',
'',
10
) hsearch
join Knowledge_chunk__dlm chnk
on hsearch.SourceRecordId__c = chnk.RecordId__c
join Knowledge_kav_Home__dlm src
on chnk.SourceRecordId__c = src.Id__c
```
# Hybrid Search Query Expressions for Autodrop
Use Data 360 Query API to configure autodrop for hybrid search results.
### Required Editions
You can configure autodrop for keyword search results, vector search results, or hybrid search results. For best results either use autodrop for keyword search and vector search, or just hybrid search results. Do not use autodrop for all search types together in a query.
The num\_drops integer parameter passed to “autodrop\_keyword”, “autodrop\_vector”, and “autodrop\_hybrid” defines the number of significant score drops that hybrid search function must detect in the corresponding score list to truncate results.
Use this syntax for autodrop with keyword search and vector search results.
```sql
select * from hybrid_search(
table(),
‘’,
'',
'',
‘{ "autodrop_keyword": {"num_drops": 2}, "autodrop_vector":{"num_drops": 5 }}’
);
)
```
Where:
"autodrop\_keyword": {"num\_drops": 2}
Drops retrieved keyword search results at the second significant score cutoff point.
"autodrop\_vector":{"num\_drops": 5 }
Drops retrieved vector search results at the fifth significant cutoff point.
Use this syntax for autodrop with hybrid search results.
```sql
select * from hybrid_search(
table(),
‘’,
'',
'',
‘{{ "autodrop_hybrid": {"num_drops": 1}}’
);
```
Where:
{ "autodrop\_hybrid": {"num\_drops": 1}
Drops the combined hybrid search results at the first significant score cutoff point.
If you don’t apply a quality filter in a vector search query, the search always returns the number of results (topK results) requested. Keyword search returns results that only match terms of the query contained in the documents.

Example
For example, consider this scenario for keyword search result scores that includes two score drops.
1. Result A: Score 0.95
2. Result B: Score 0.92
3. Result C: Score 0.88
4. Result D: Score 0.40 - **Sharp drop in score**
5. Result E: Score 0.38
6. Result F: Score 0.35
7. Result G: Score 0.10 - **Sharp drop in score**
8. Result H: Score 0.80
9. Result I: Score 0.05
If you configure “autodrop\_keyword” with num-drops = 1, hybrid search detects the first significant drop after Result C (between 0.88 and 0.40). Hybrid search removes Results D, E, F, G, H, and I from the final search results. The search query returns results, Result A, Result B, and Result C.
If you configure “autodrop\_keyword” with num\_drops = 2, hybrid search detects the first drop after Result C (between 0.88 and 0.40) and a second drop after Result F (between 0.35 and 0.10). The search query removes Results G, H, and I and returns results A through F.
#### See Also
- [_Salesforce Help_: Hybrid Search Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop_best_practices.htm&release=264.0.0&type=5 "Use these best practices to configure autodrop for Data 360hybrid search results.")
# Identity Boost
Use identity boost to collaborate with identity providers in a clean room and enrich your first-party data with missing contact points. Use the enriched data in your activations to improve match rates.
### Required Editions
Creating AppExchange clean room packages: Developer Edition (packaging org only) Installing packages, creating collaborations, and accepting invitations: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
In identity boost, identity is the set of contact points that refer to an individual, such as email addresses and phone numbers. This meaning is separate from identity in enterprise IT, which is about authenticating a user at login and controlling what that user can access.
An identity provider maintains available contact point information in its identity graph and links the contact points that belong to the same person. When the consumer shares their first-party data in a clean room, the identity provider matches the contact points and returns related contact points that are missing from the first-party data.
For example, for a particular user, the consumer's first-party data includes the email address clark.kent@example.com. The identity provider's graph also includes that same email address, linked to other contact points, such as c.kent@example.net and (512) 555-1212. The identity provider uses clark.kent@example.com as the match key and returns the related contact points that are missing from the consumer's data. When the consumer activates the enriched record to an advertising platform, the platform gains more ways to match the person they want to reach. Activation match rates and campaign reach improve because the platform can match audience members who use different email addresses or phone numbers.
## Identity Boost Collaboration Overview
When a consumer initiates a clean room identity boost collaboration with an identity provider, the provider runs a query in their Snowflake environment. The enriched DMO returns to the consumer's Data 360 org. If the consumer wants to activate segments from this DMO, they choose the raw data or the enriched data. The consumer can only activate the enriched data to Ad Audience partner platforms. While the identity boost collaboration stays active, enriched segments stay available for activation.
## Privacy and Data Handling

Important Unlike standard clean room use cases, the identity boost use case shares personally identifiable information (PII) in unhashed form with the identity provider. Identity boost doesn't use hashing because address normalization variations (for example, different abbreviations of the same street address) produce different hash values, which reduces match quality. Before mapping your data, make sure that you have all required consumer consents and that you comply with applicable data usage agreements and privacy regulations. Data processing can occur outside your Salesforce region. Review the data sharing disclaimer shown in the mapping wizard before proceeding.
These privacy controls apply to identity boost collaborations.
- The provider receives only the fields that the consumer maps in the mapped template. No other data from the consumer's org is accessible.
- The enriched data that the provider returns is accessible only within approved activation contexts. Consumers can't directly browse or export the enriched PII.
- The data share that Data 360 creates between the consumer and provider is clean room–aware, so you can't reuse it for non-clean room data shares.
## Variations from Other Clean Room Use Cases
Identity boost differs from other clean room use cases in these ways.
| Aspect | Standard Clean Room | Identity Boost |
| --- | --- | --- |
| Package type | Data Collaboration Package. | Identity Boost Package. |
| PII handling | You must hash PII before it enters the clean room. | The consumer shares PII in unhashed form with the provider for matching. |
| Provider's data storage | Provider's Data 360 or AWS account. | Provider's Snowflake account. |
| Getting results | Consumer runs a query. | The provider runs the enrichment job in their Snowflake account. Data 360 then automatically refreshes the enriched data in the consumer's org. |
| Output | Aggregated results in an output DMO. | Enriched DMOs with more contact attributes, available for activations. |
- **[Set Up Clean Room Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_set_up_identity_boost.htm&release=264.0.0&type=5)**
Setting up and using a clean room identity boost involves steps for both the provider and the consumer. The provider creates a package and sets up their Snowflake environment. The consumer installs the package, creates a collaboration, and maps their data. After the provider accepts the invitation and runs the enrichment job, Data 360 automatically refreshes the enriched data in the consumer's org.
- **[Plan Your Snowflake Environment for Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_plan_snowflake_for_identity_boost.htm&release=264.0.0&type=5)**
Before accepting identity boost collaboration invitations, decide how to isolate customer data in your Snowflake account and which region to use. These decisions affect the architecture of every collaboration that you accept, so make them before you receive your first invitation.
- **[Configure Snowflake Trust Relationship for Clean Room Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_configure_snowflake_trust_relationship.htm&release=264.0.0&type=5)**
For each collaboration invitation for the identity boost use case, complete the required Snowflake setup and then accept the invitation in Data 360. Data 360 tests the Snowflake connection automatically on acceptance.
#### See Also
- [_Salesforce Help_: Identity Boost Custom Collaboration Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_id_boost_custom_template.htm&release=264.0.0&type=5 "The identity boost custom collaboration template is a JSON configuration that supports identity enrichment use cases in Data 360 Clean Rooms. Use this template to enrich your first-party individual data with third-party identity attributes, such as real IDs from identity resolution providers, in a privacy-safe environment.")
# Identity Boost Custom Collaboration Template
The identity boost custom collaboration template is a JSON configuration that supports identity enrichment use cases in Data 360 Clean Rooms. Use this template to enrich your first-party individual data with third-party identity attributes, such as real IDs from identity resolution providers, in a privacy-safe environment.
## Template Overview
The identity boost custom collaboration template includes these fields.
| Field Name | Data Type | Requirement | Description |
| --- | --- | --- | --- |
| `name` | string | Required | The name of the collaboration template. For identity boost, the value is MatchBoost. |
| `description` | string | Optional | A short description of the collaboration template. |
| `tables` | object | Required | The input tables used in the collaboration query. Contains the `FirstPartyDataSet` table configuration. |
| `queries` | object | Required | The queries that run in the clean room collaboration to support the use case. |
| `useCaseConfigs` | object | Required | The use case-specific configurations that define supported contact points and output object mappings for identity enrichment. |
## Table Configurations
Each input table used by the query must be defined in the `tables` field. The `tableConfigs` property is an array that can contain multiple table definitions.
- `tableConfigs` (array, required) – A list of table definitions. Each entry represents one table configuration. The identity boost template includes one table configuration, but you can add additional tables as needed.
| Field Name | Data Type | Requirement | Accepted Values | Description |
| --- | --- | --- | --- | --- |
| `name` | string | Required | N/A | The name of the table. Value: FirstPartyDataSet. |
| `description` | string | Optional | N/A | A short description of the table. Value: Data set comprising first party information. |
| `role` | string | Required | Provider or Consumer | The role sharing the table in the collaboration. Value: Consumer. |
| `columns` | array | Required | N/A | The schema of the table. Each column object defines a field in the table. |
## Query Configurations
The queries section defines all queries allowed on the combined dataset in the clean room. The identity boost template includes one query through the `queryConfigs` property.
- `queryConfigs` (array, required) – A list of query configurations. The identity boost template includes one query configuration.
| Field Name | Data Type | Requirement | Accepted Values | Description |
| --- | --- | --- | --- | --- |
| `name` | string | Required | N/A | The name of the query. Value: MatchBoost. |
| `useCase` | string | Required | MatchBoost | The use case that this query supports. Value: MatchBoost. |
| `description` | string | Optional | N/A | A short description of the query. Value: Enrich first party dataset using third party data. |
| `type` | string | Required | SQL | The type of query. Value: `null` (determined at runtime). |
| `source` | string | Required | N/A | The actual SQL query text. Value: `null` (determined at runtime). |
| `queryParameters` | object | Optional | N/A | The dynamic parameters used in the query. Value: `null`. |
| `referencedTables` | array of strings | Required | N/A | A list of all tables that the query references. Value: \["FirstPartyDataSet"\]. |
## MatchBoost Use Case Configurations
The `useCaseConfigs` section defines the use case-specific settings for identity enrichment, including supported contact points and output object mappings.
| Field Name | Data Type | Requirement | Description |
| --- | --- | --- | --- |
| `useCaseType` | string | Required | The type of use case. Value: MatchBoost. |
| `supportedContactPoints` | array of strings | Required | The contact point types used to match and enrich your data. The identity boost template supports Email and PhoneNumber. |
| `outputObjects` | object | Required | Defines where Data 360 writes the enriched data in your org. |
## Output Objects
The `outputObjects` section tells Data 360 where to write the enriched identity data. When the clean room query runs, it creates three types of output:
- A bridge table that connects your original customer IDs to the enriched Real IDs from the identity provider
- Enriched individual records that link the Real IDs to your Data 360 Individual objects
- Enriched contact point records that link the Real IDs to your Data 360 ContactPointEmail objects
The template defines three output objects that work together to store this enriched data.
- `outputObjectConfigs` (array, required) – A list of output object configurations. Each entry defines where Data 360 stores one type of enriched data.
| Field Name | Data Type | Requirement | Description |
| --- | --- | --- | --- |
| `objectName` | string | Required | The name of the custom object created in your Data 360 org to store the output. |
| `bridgeTable` | object | Optional | Used for the mapping table that connects your source IDs to Real IDs. Contains the `sourceIdFieldName` property. |
| `relatedTable` | object | Optional | Used for enriched data tables that link to standard Data 360 objects. Contains the `sourceObjectName` (which Data 360 object to link to) and `pathFromBridgeTable` (how to join the tables). |
## SAMPLE\_BRIDGE\_TABLE
This output creates a mapping table between your customer identifiers and the Real IDs from the identity provider.
| Field | Value | Description |
| --- | --- | --- |
| `objectName` | `SAMPLE_BRIDGE_TABLE` | The name of the bridge table object in your org. |
| `bridgeTable.sourceIdFieldName` | `SourceId__c` | The field that stores your original customer ID. |
| `relatedTable` | `null` | This is a bridge table, not linked to a Data 360 object. |
## SAMPLE\_INDV\_BOOSTED
This output creates enriched individual records and links them to your Data 360 Individual objects.
| Field | Value | Description |
| --- | --- | --- |
| `objectName` | `SAMPLE_INDV_BOOSTED` | The name of the enriched individual object in your org. |
| `bridgeTable` | `null` | Not a bridge table. |
| `relatedTable.sourceObjectName` | `ssot__Individual__dlm` | Links the enriched data to the Individual data model object in Data 360. |
| `relatedTable.pathFromBridgeTable` | Relationship path | Uses the Real ID to connect enriched individual data to your Data 360 individuals. |
## CONTACTEMAIL\_BOOSTED
This output creates enriched contact email records and links them to your Data 360 `ContactPointEmail` objects.
| Field | Value | Description |
| --- | --- | --- |
| `objectName` | `CONTACTEMAIL_BOOSTED` | The name of the enriched contact email object in your org. |
| `bridgeTable` | `null` | Not a bridge table. |
| `relatedTable.sourceObjectName` | `ssot__ContactPointEmail__dlm` | Links the enriched data to the `ContactPointEmail` DMO in Data 360. |
| `relatedTable.pathFromBridgeTable` | Relationship path | Uses the Real ID and Party ID to connect enriched email data to your Data 360 `ContactPointEmail` records. |

Note The `pathFromBridgeTable` property defines how to join the enriched data tables with the bridge table and Data 360 objects. It specifies which fields to use as keys when connecting the records.
## Example Scenario
Bridge table mapping: If your customer ID is CUST12345, the bridge table creates a record that connects CUST12345 to the enriched Real ID REAL98765.
Enriched individual records: The enriched individual record for Real ID REAL98765 is linked to your existing Individual record in Data 360.
Enriched contact email records: The enriched email record for Real ID REAL98765 is linked to the corresponding email address in your Data 360 `ContactPointEmail` object.
- **[Identity Boost Custom Template Sample JSON](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_id_boost_custom_template_json.htm&release=264.0.0&type=5)**
Copy the template code below or download it directly in Data 360 to begin creating your custom template for the identity boost use case. Fill in the required and optional fields with appropriate values.
# Identity Boost Custom Template Sample JSON
Copy the template code below or download it directly in Data 360 to begin creating your custom template for the identity boost use case. Fill in the required and optional fields with appropriate values.
```
{
"name": "MatchBoost",
"description": "Boost matching population",
"tables": {
"tableConfigs": [
{
"name": "FirstPartyDataSet",
"description": "Data set comprising first party information",
"role": "Consumer",
"columns": [
{
"name": "IndividualId",
"description": "Captures the Individual Id",
"type": "STRING"
},
{
"name": "RealId",
"description": "Captures the Real ID that is minted by the identity provider",
"type": "STRING",
"defaultValue": "DEFAULT"
},
{
"name": "FirstName",
"description": "Captures the First Name of the user",
"type": "STRING",
"defaultValue": "DEFAULT"
},
{
"name": "LastName",
"description": "Captures the Last Name of the user",
"type": "STRING",
"defaultValue": "DEFAULT"
},
{
"name": "EmailAddress",
"description": "Captures the Email address",
"type": "STRING"
},
{
"name": "PhoneNumber",
"description": "Captures the Phone Number",
"type": "STRING",
"defaultValue": "DEFAULT"
}
]
}
]
},
"queries": {
"queryConfigs": [
{
"name": "MatchBoost",
"useCase": "MatchBoost",
"description": "Enrich first party dataset using third party data",
"type": null,
"source": null,
"queryParameters": null,
"referencedTables": ["FirstPartyDataSet"]
}
]
},
"useCaseConfigs": {
"MatchBoost": {
"useCaseType": "MatchBoost",
"supportedContactPoints": [
"Email",
"PhoneNumber"
],
"outputObjects": {
"outputObjectConfigs": [
{
"objectName": "SAMPLE_BRIDGE_TABLE",
"bridgeTable": {
"sourceIdFieldName": "SourceId__c"
},
"relatedTable": null
},
{
"objectName": "SAMPLE_INDV_BOOSTED",
"bridgeTable": null,
"relatedTable": {
"sourceObjectName": "ssot__Individual__dlm",
"pathFromBridgeTable": [
{
"sourceAttribute": {
"objectName": "SAMPLE_INDV_BOOSTED3",
"fieldName": "Id__c"
},
"targetAttribute": {
"objectName": "SAMPLE_BRIDGE_TABLE3",
"fieldName": "RealId__c"
}
}
]
}
},
{
"objectName": "CONTACTEMAIL_BOOSTED",
"bridgeTable": null,
"relatedTable": {
"sourceObjectName": "ssot__ContactPointEmail__dlm",
"pathFromBridgeTable": [
{
"sourceAttribute": {
"objectName": "CONTACTEMAIL_BOOSTED3",
"fieldName": "PartyId__c"
},
"targetAttribute": {
"objectName": "SAMPLE_BRIDGE_TABLE3",
"fieldName": "RealId__c"
}
}
]
}
}
]
}
}
}
}
```
# Identity Boost for Ad Audiences Partners
Expand the addressable audience for your ad campaigns by enriching your first-party data with contact points from a certified identity provider. Identity Boost fills the coverage gaps in your first-party data so that you can reach more of your audiences in Ad Audiences partner activations.
### Required Editions
Creating AppExchange clean room packages: Developer Edition (packaging org only) Installing packages, creating collaborations, and accepting invitations: Enterprise Edition (home org) Available with add-on license: Ad Audiences
When you activate a segment to an Ad Audiences partner platform, your match rate depends on how complete the contact points in your first-party data are. Missing or outdated contact points, such as email addresses and phone numbers, shrink the list of audiences that the Ad Audiences partner can match and target on their platform. Identity Boost closes those gaps directly in Data 360. A certified identity provider enriches your first-party data with contact points from their identity graph, and the enriched data returns to your Data 360 org, ready to activate. You gain a larger, more accurate audience list without manual data append processes or third-party data purchases.
In Identity Boost, identity means the contact points that refer to one person, such as email addresses and phone numbers. This use of identity is separate from authenticating a user at login and controlling what that user can access.
## Identity Boost Collaboration
Identity Boost uses a Data 360 Clean Rooms collaboration between these two parties.
- **Consumer**: The advertiser who wants to enrich their first-party data and activate it to Ad Audiences partner platforms.
- **Identity provider**: A certified partner who enriches the consumer's data with contact points from their identity graph.
The consumer starts a clean room identity boost collaboration and maps their metadata to the metadata that the identity provider requires. After the clean room is active, the identity provider enriches the consumer's data and returns it to the consumer's Data 360 org as enriched data model objects (DMOs). When the consumer activates segments that use an enriched DMO to Ad Audiences partner platforms, they can activate raw data or enriched data.
To activate the data they enriched, the clean room collaboration with the identity provider must be in an active state. Because the data refreshes automatically while the clean room collaboration stays active, you can activate it on an ongoing basis.

Note You can activate enriched data only to Ad Audiences partner destinations. Data 360 makes the enriched contact points available for activation to these partners through the Ad Audiences add-on license. You can't browse or export the enriched contact points directly.
## Identity Boost Set Up
To set up and manage Identity Boost, go to the Data 360 Clean Rooms section.
#### See Also
- [_Salesforce Help_: Identity Boost](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_identity_boost.htm&release=264.0.0&type=5 "Use identity boost to collaborate with identity providers in a clean room and enrich your first-party data with missing contact points. Use the enriched data in your activations to improve match rates.")
- [_Salesforce Help_: Segment Activations to Ad Audiences Partner Platforms](https://help.salesforce.com/s/articleView?id=data.c360_a_ad_audiences_segment_activations.htm&release=264.0.0&type=5 "Activate audience segments to Ad Audiences partner platforms for targeting advertising campaigns to known customers.")
- [_Salesforce Help_: Create an External Platform Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&release=264.0.0&type=5 "To publish segments to your external advertising platforms like Amazon Ads, create an external platform activation target in Data 360. An external platform can have multiple activation targets, but you can attach only one activation target to an external platform account.")
# Identity Resolution Calculated Insight: Consolidation Rates for Unified Profiles
Review the consolidation rate of matched profiles for each data source. Data sources with duplicate profiles are expected to have higher consolidation rates than data sources with many unique profiles. Use this calculated insight after creating unified profiles with an identity resolution ruleset.

Tip An unexpectedly high consolidation rate could be a sign of data source quality issues.

Identity Resolution - Summary by Source

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
IndividualIdentityLink__dlm.ssot__DataSourceId__c as DataSourceId__c,
IndividualIdentityLink__dlm.ssot__DataSourceObjectId__c as DataSourceObjectId__c,
APPROX_COUNT_DISTINCT(IndividualIdentityLink__dlm.UnifiedRecordId__c) AS unq_Unified_Individuals__c,
COUNT(IndividualIdentityLink__dlm.SourceRecordId__c) AS cnt_Source_Records__c,
(1 - APPROX_COUNT_DISTINCT(IndividualIdentityLink__dlm.UnifiedRecordId__c)/COUNT(IndividualIdentityLink__dlm.SourceRecordId__c))*100 as per_consolidation_rate__c
FROM IndividualIdentityLink__dlm
GROUP BY
DataSourceId__c,
DataSourceObjectId__c
```
# Identity Resolution Calculated Insight: Outlier Unified Profiles
Review the number of matched contact points for each unified profile. A high number of matches per contact point, like profiles with hundreds of source records matched with the same email address, could indicate issues with data quality or source data. Use this calculated insight after creating unified profiles with an identity resolution ruleset.

Tip
- Use this calculated insight for multiple rulesets by creating a calculated insight for each Unified Data Model Object (DMO).
- To search for outlier profiles in Profile Explorer, use the Unified\_Individual\_Id from the calculated insight.
- Consider removing repeat values from your source data and ingesting data into Data 360 again.
- Consider filtering out repeat values using a formula field in Data Streams.

Unified Individual - CP Summary

Tip Modify the SQL in the example based on your data mappings.
```sql
SELECT
UnifiedIndividual__dlm.ssot__Id__c AS Unified_Individual_Id__c,
APPROX_COUNT_DISTINCT(IndividualIdentityLink__dlm.SourceRecordId__c) AS cnt_Lineage__c,
APPROX_COUNT_DISTINCT(ssot__Individual__dlm.ssot__FirstName__c) AS unq_FirstNames__c,
APPROX_COUNT_DISTINCT(UnifiedContactPointPhone__dlm.ssot__Id__c) AS unq_PhoneCPs__c,
APPROX_COUNT_DISTINCT(UnifiedContactPointEmail__dlm.ssot__Id__c) AS unq_EmailCPs__c,
APPROX_COUNT_DISTINCT(UnifiedContactPointAddress__dlm.ssot__Id__c) AS unq_AddressCPs__c,
APPROX_COUNT_DISTINCT(ssot__PartyIdentification__dlm.ssot__Id__c) AS unq_PartyIdentifiers__c
FROM UnifiedIndividual__dlm
LEFT JOIN IndividualIdentityLink__dlm ON IndividualIdentityLink__dlm.UnifiedRecordId__c = UnifiedIndividual__dlm.ssot__Id__c
LEFT JOIN UnifiedContactPointPhone__dlm ON UnifiedContactPointPhone__dlm.ssot__PartyId__c = UnifiedIndividual__dlm.ssot__Id__c
LEFT JOIN UnifiedContactPointEmail__dlm ON UnifiedContactPointEmail__dlm.ssot__PartyId__c = UnifiedIndividual__dlm.ssot__Id__c
LEFT JOIN UnifiedContactPointAddress__dlm ON UnifiedContactPointAddress__dlm.ssot__PartyId__c = UnifiedIndividual__dlm.ssot__Id__c
LEFT JOIN ssot__PartyIdentification__dlm ON ssot__PartyIdentification__dlm.ssot__PartyId__c = UnifiedIndividual__dlm.ssot__Id__c
LEFT JOIN ssot__Individual__dlm ON ssot__Individual__dlm.ssot__Id__c = IndividualIdentityLink__dlm.SourceRecordId__c
GROUP BY
Unified_Individual_Id__c
```
# Identity Resolution Match Methods
Match rule methods determine how source data is transformed for comparison during matching. Changing the match method on a field typically changes the consolidation rate based on that field.

Warning Data is transformed for matching purposes when the Fuzzy and Exact Normalized match methods are selected. However, reformatted data is not stored in unified profiles. The format of the value stored in a unified profile is based on source data and determined by reconciliation rules.
Match methods describe the precision with which data is matched during identity resolution. The anticipated consolidation rate is lower when precision matching is required. Selecting a less precise match method typically raises the consolidation rate, but can result in undesirable matches.
Up to five match methods are available for use in creating criteria for custom match rules. The match methods available for each object and field vary. Fuzzy match methods aren’t available for fields from the Account object.
- Exact
- Exact Normalized
- Fuzzy - High Precision
- Fuzzy - Medium Precision
- Fuzzy - Low Precision
You can refine custom match criteria further by allowing matches to be made between blank fields.

Tip To determine the most effective match method for your data, configure multiple rulesets with different criteria. Compare consolidation rates and decide which match method works best for your unified profiles.
## Exact Match Method
The **Exact** match method is available for all objects and fields. If this match method is used, values match regardless of case.

Example
Because exact match is case-insensitive, these four source data values are an exact match:
- Maryanne
- maryanne
- MARYANNE
- MaryAnne
## Exact Normalized Match Method
The **Exact Normalized** match method is available for specific fields for the Contact Point Email, Phone, and Address objects.
When this match method is selected, source data is transformed to address issues like trailing spaces, inconsistent formatting, special characters, and more.
Object
Fields with Exact Normalized Match Method Support
Normalization Process
Individual
Standardizes capitalization so that matches are case-insensitive
Contact Point Email
Standardizes capitalization so that matches are case-insensitive
Removes white space from the beginning and end of an email address
Removes non-alphanumeric characters like quotes (“”) and
brackets (<>) from email address
For email addresses with the gmail.com domain, removes both period (.) and
plus (+) characters from email address
Contact Point Phone
Formatted E164 Phone Number
Removes white spaces from phone number
Removes non-alphanumeric-characters like asterisk (*) and
parentheses (()) from phone number
Validates phone number with Google's common Java, C++ and JavaScript library for parsing, formatting, and
validating international phone numbers
Uses the country code or name for normalization if it’s available or
identifiable based on contact point phone or address records.
If a country code is provided and mapped to the phone country code field
(ssot__CountryCode__c ) in the Contact Point Phone
DMO, the country code is used for normalization.
If the country code isn't available, and if the country name is provided
and mapped to the country name field
(ssot__CountryId__c ) in the Contact Point Phone DMO,
the country name is used for normalization.
If a country code or name isn't identifiable from data in the Contact
Point Phone DMO, and Contact Point Address DMO exists with a valid mapping
to country name, the country name in Contact Point Address DMO is used for
normalization.
If a country code or name isn't available, the phone number is normalized
without it.
For data sources with phone number country codes, map the Phone Country Code field.
Contact Point Address
Address Line 1
Address Line 2
Address Line 3
State Province
Country
Standardized based on country-specific rules for addresses

Example
These source data values are an exact normalized match:
Contact Point Email Object
Source Values
Exact Normalized Email Address Field Value
<MichelleNoris@gmail.com>
"MichelleNoris"@gmail.com
michellenoris@gmail.com
michellenoris@gmail.com

Example
These source data values are an exact normalized match:
Contact Point Phone Object
Source Values
Exact Normalized Formatted E164 Phone Number Field Value
+1 (650) 277-9500
+1 650 277-9500
1 (650) 277-9500
+16502779500

Example
These source data values are an exact normalized match:
Contact Point Address Object
Source Values
Exact Normalized Address Line 1 and Address Line 2 Field Values
Exact Normalized State Province and Country Field Values
Source 1
Address Line 1: 220 Laurier Avenue West
Address Line 2: Suite 1000
State Province: ON
Country: CA
Source 2
Address Line 1: 220 Laurier Ave W
Address Line 2: Ste 1000
State Province: Ontario
Country: Canada
220 Laurier Ave W Ste 1000
Ontario Canada
Source 1
Address Line 1: 56 Abascal
Address Line 2: Calle de José
State Province: Madrid
Country: ES
Source 2
Address Line 1: Abascal 56
Address Line 2: Calle de José
State Province: Madrid
Country: Spain
Calle De José Abascal 56
Madrid Spain

Tip Exact normalized matches generally lead to higher consolidation rates than exact matches. To determine the most effective match method for your data, configure multiple rulesets. Compare the consolidation rate of each ruleset and decide which works best for our data.
## Fuzzy Match Methods
The **Fuzzy** match methods are available for most fields.
If any of these match methods are used, matches are based on an Artificial Intelligence (AI) model trained with data from over 150 countries, 3 billion English words, and 20 million names. The AI model is built with the Bidirectional Encoder Representations from Transformers (BERT) Language Model to match common misspellings, diacritical marks, synonyms, and more. The AI model has a 0.7 confidence threshold.
To allow more control over the granularity of matching, three levels of precision are available: high, medium, and low precision.
Fuzzy Matching Precision Levels
Precision Level
Description
Matching Values
Low Precision
Matches values with loose similarities.
Lisa, Liza
Cathi, Cathy
Lucia, Luc
Medium Precision
Matches values with the same initials, gender variants, shuffled names, and similar
subnames.
S., Sharon
A.M., Anthony Michael
Cathi, Cathie
Lilian, Liliana
Gabriel, Gabrielle
José Andrés, Pepe
Joey James, James Joseph
High Precision
Matches values across nicknames, punctuation, international abbreviations,
international alphabet characters, and cross-cultural spellings.
Beatriz, Beatrice
William, Bill
Mary-Jo, MaryJo
Håkon, Hakon
Catherine, Katherine

Tip Fuzzy matches generally lead to higher consolidation rates than exact matches. To determine the most effective match method for your data, configure multiple rulesets with different criteria. Compare consolidation rates and decide which match method works best for your unified profiles.
#### See Also
- [_Salesforce Help_: Advanced Match Criteria Settings](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_advanced_settings.htm&release=264.0.0&type=5 "Access match rule modifier settings in Advanced Match Criteria Settings for each match rule.")
# Identity Resolution Match Rule Terminology
Understand the roles that match rules, match criteria, and match methods play in identity resolution rulesets. Adding, adjusting, and removing match rules, match criteria, and match methods can change the consolidation rate of the overall ruleset.
Match Rules
Each match rule is an opportunity for records to be matched. Records must match the criteria of only one match rule to get matched by the ruleset. The more match rules you create, the more opportunities you give your records to be matched. Adding more rules to a ruleset raises the ruleset’s consolidation rate.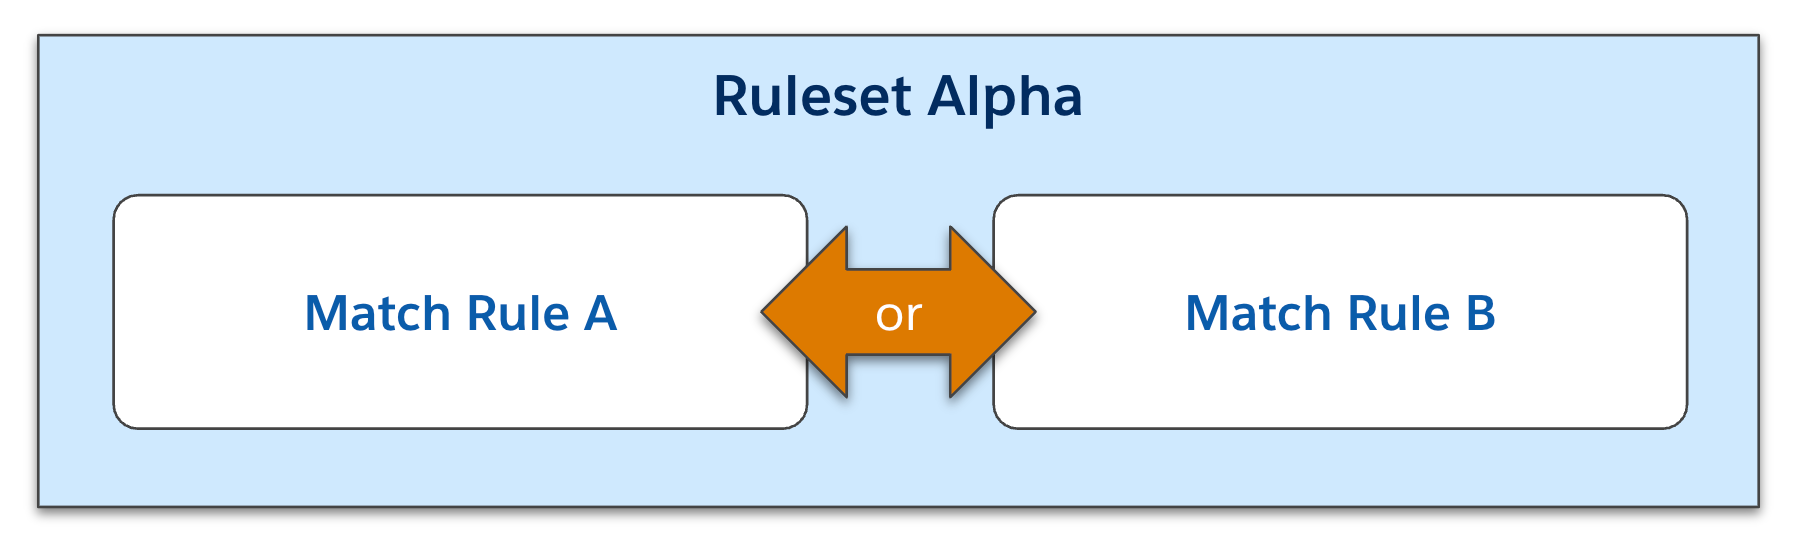
Match Criteria
Within each match rule, the criteria determine how precise a particular match rule is. Any two records must match all criteria within a match rule to be matched. The more criteria you include, the harder it is for any two records to match. Adding more criteria to a match rule lowers the ruleset’s consolidation rate.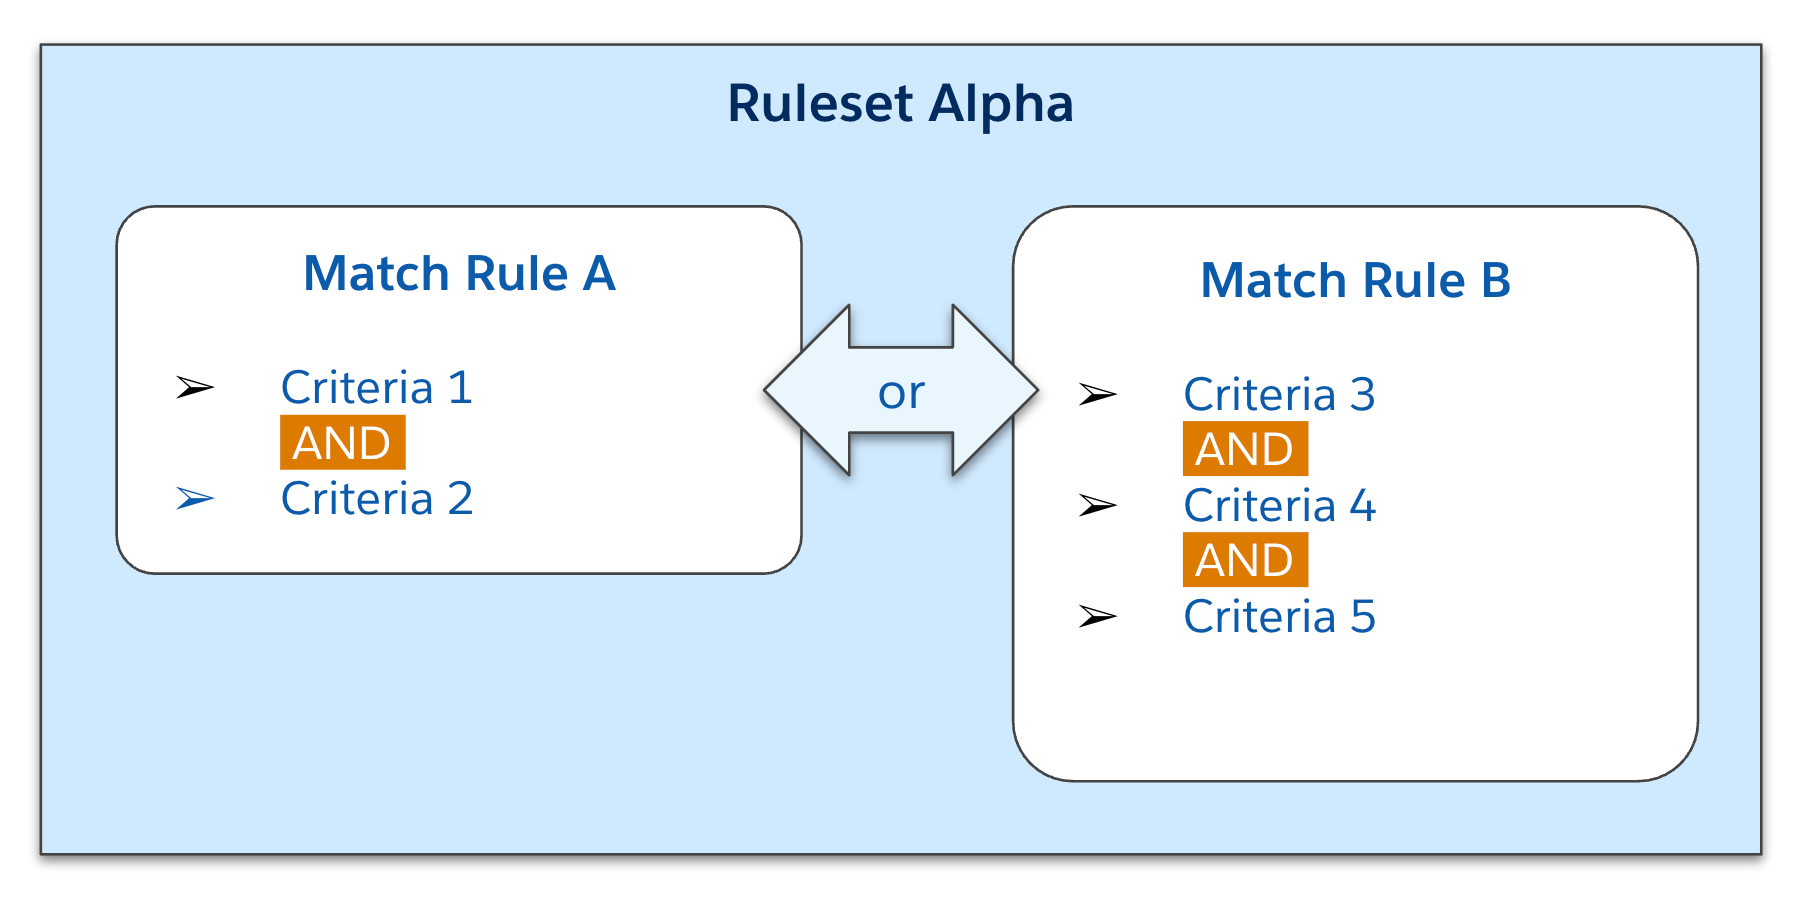
Match Methods
Match methods are different ways identity resolution can transform data before trying to match it. You can select from up to five match methods, but not all methods are available for all objects and fields. Match methods that make criteria more stringent, such as Exact or Exact Normalized, can lower consolidation rates, while match methods that are more permissive, such as Fuzzy Match - Low Precision, can raise consolidation rates.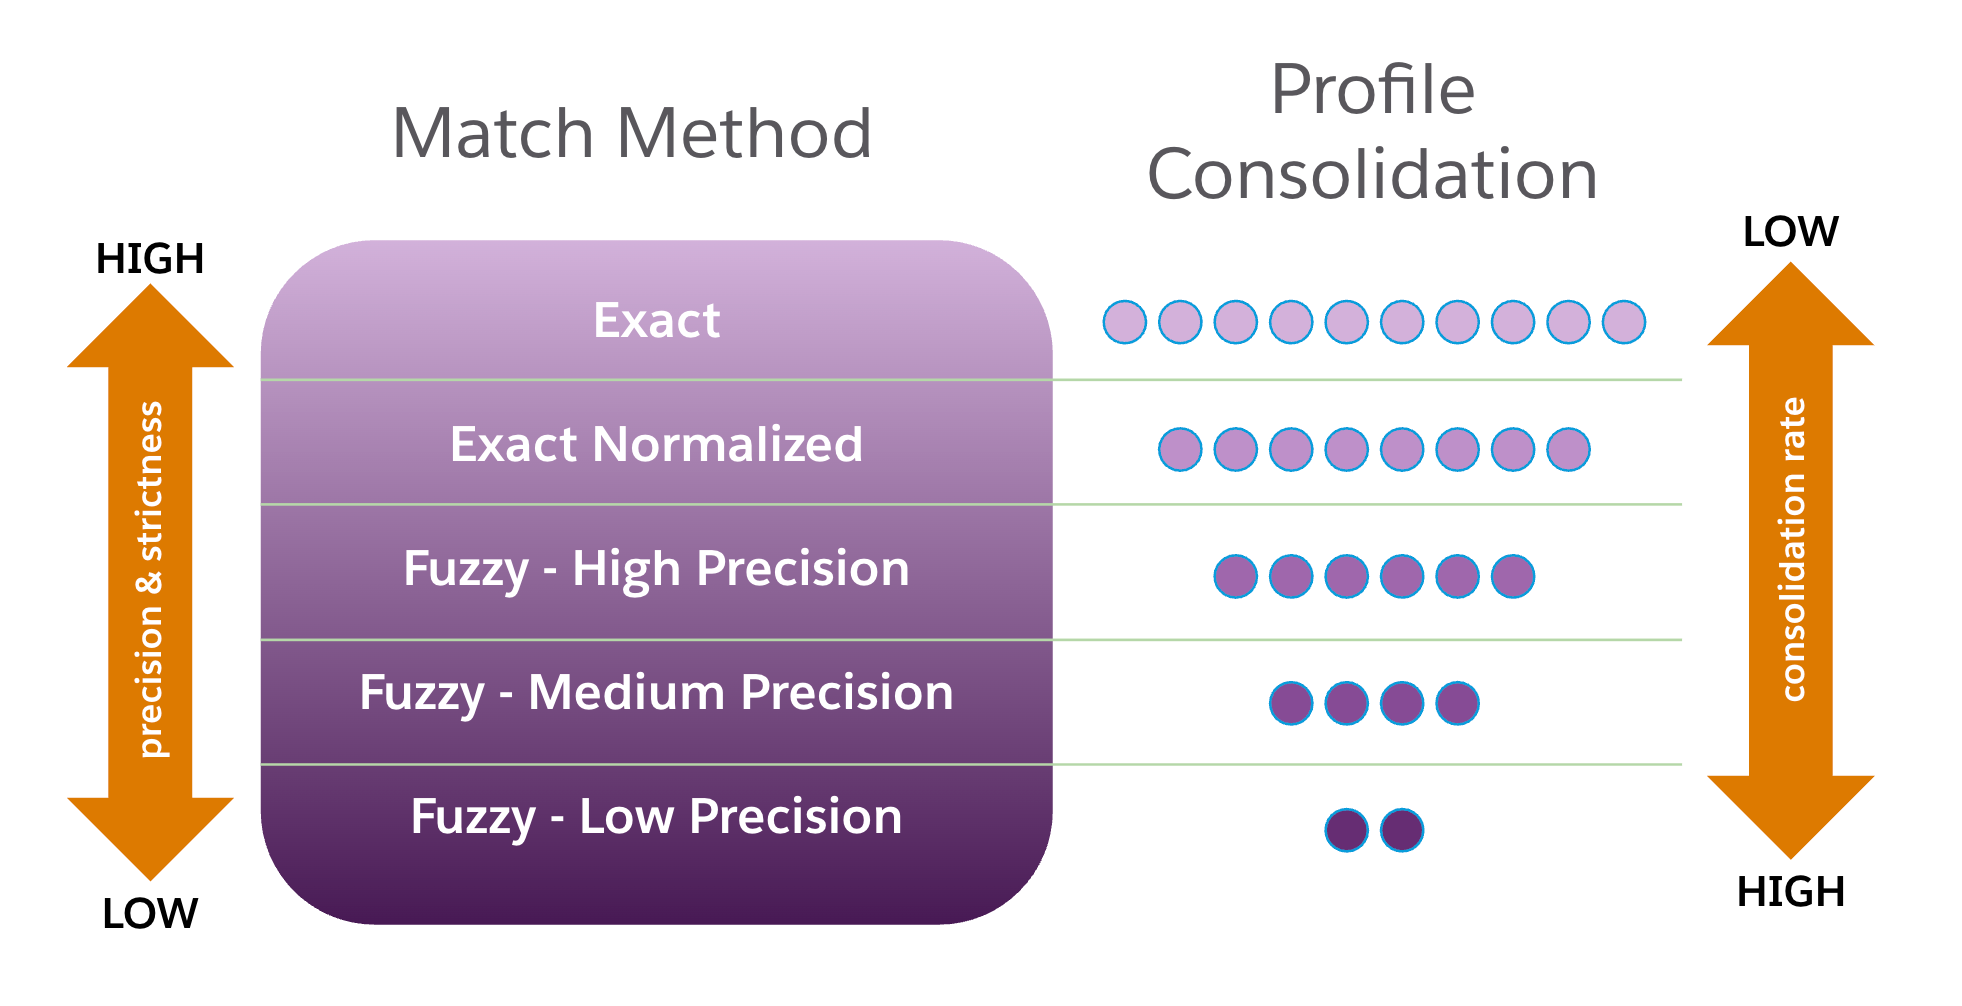
When a ruleset is being run for real-time matching, all match criteria except phone numbers and email addresses are run using the Exact match method regardless of what scheduled match method you selected when you set up your ruleset. In real-time matching, phone numbers and email addresses are run using Exact Normalized matching unless you speciyfied Exact matching as the scheduled match method.
#### See Also
- [_Salesforce Help_: Identity Resolution Terminology](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_terms.htm&release=264.0.0&type=5 "Understand what terms like rulesets and unified objects mean when used in the context of identity resolution.")
# Identity Resolution Match Rules
Match rules tell Data 360 which profiles to unify during the identity resolution process. Each match rule contains one or more criteria. Profiles are matched when all criteria within a match rule are satisfied.
Create multiple match rules to widen matching options. A unified profile is created if any single match rule is activated.
Match rules can be created only on certain objects. Available objects vary depending on whether you’re matching individuals or accounts. Ensure these objects are properly mapped to make them available for identity resolution.
- When matching accounts—Account, Contact Point Address, Contact Point Phone, Contact Point Email, Party Identification
- When matching individuals—Individual, Contact Point Address, Contact Point App, Contact Point Email, Contact Point Phone, Contact Point Social, Party Identification
Use criteria to determine how strict each match rule is. Consider adding more criteria if accuracy is your top priority. You’re more likely to create unique unified profiles with more criteria in your match rules. If increased consolidation is a priority, reduce the number of criteria to allow profiles to more easily be matched.
- **[Identity Resolution Match Rule Terminology](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rule_terms.htm&release=264.0.0&type=5)**
Understand the roles that match rules, match criteria, and match methods play in identity resolution rulesets. Adding, adjusting, and removing match rules, match criteria, and match methods can change the consolidation rate of the overall ruleset.
- **[Configure Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5)**
Specify how identity resolution identifies matching records in Data 360.
- **[Identity Resolution Match Methods](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_criteria_fuzzy_normalized.htm&release=264.0.0&type=5)**
Match rule methods determine how source data is transformed for comparison during matching. Changing the match method on a field typically changes the consolidation rate based on that field.
- **[Advanced Match Criteria Settings](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_advanced_settings.htm&release=264.0.0&type=5)**
Access match rule modifier settings in Advanced Match Criteria Settings for each match rule.
- **[Default and Custom Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_criteria.htm&release=264.0.0&type=5)**
Identity resolution provides out-of-the-box, default match rules for different types of matching. Use custom match rules to resolve use cases that aren’t covered by default rules. Developing balanced, effective sets of match rules across different types of criteria improves consolidation rates for individuals and accounts.
#### See Also
- [_Salesforce Help_: Data Mapping Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_required_data_mappings.htm&release=264.0.0&type=5 "Mappings and relationships are set up automatically only for data streams that are deployed through standard data bundles. However, you must ensure that the required mappings and relationships are set up properly for custom data streams.")
- [_Salesforce Help_: Select Unified Individual for Activation Membership](https://help.salesforce.com/s/articleView?id=data.c360_a_unified_profile_activation.htm&release=264.0.0&type=5 "To take advantage of identity resolution, use the Unified Individual data model object (DMO) as the Activation Membership. With identity resolution, you combine data from disparate data sources to create one Unified Individual. When selecting Unified Individual as the DMO, the Individual ID attribute is included and not the Unified Individual ID.")
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
# Identity Resolution Reconciliation Rules
A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.

Note Reconciliation rules don’t apply to contact points such as email or phone number. All contact points remain part of a unified profile, so all contact points are available when creating activations for segments on unified profile. Use the source priority order in activations to make sure you deliver a contact point from the desired source to your activation target.
The reconciliation process determines only what information is shown in the unified profile. It isn’t intended to determine a “best” value for a field across all applications. Reconciled values are shorthand used to summarize and label a customer 360 profile.
Unified link objects connect your unified profile to all source data so that you can choose which view of the customer to use. Use your unified profiles to guide you to the best source data to use in your use case.
## Reconciliation Rule Settings
Select a reconciliation rule for a field based on the type of data that field holds and your organization’s preferences.
Reconciliation Rule
Definition
Last Updated
This rule specifies that the value from the most recently updated record must
be selected for inclusion in the unified profile.
The Last Updated record is
determined by the Last Modified Date field on your primary data model object. This
reconciliation rule is available only when the Last Modified Date field is mapped
from the data stream.
If matching records have the same last updated date
and time, a value is selected alphabetically.
Most Frequent
This rule specifies that the most frequently occurring value must be selected
for inclusion in the unified profile.
If Ignore Empty Values is selected, the
identity resolution process doesn’t select null values, even if null is the most
frequently occurring value for the field.
If values occur at identical rates
of frequency, the last updated value is selected.
Source Priority
This rule sorts your data lake objects in order of most to least preferred for
inclusion in the unified profile.
To stabilize ID values, use the Source Priority
reconciliation rule on ID fields.
If Ignore Empty Values is selected, the
identity resolution process selects the highest-priority non-null value.
If
records from the same source are matched, individual fields within the record are
reconciled according to field-level reconciliation rules. If the field-level
reconciliation rule is also source priority, the last updated value is
selected.

Example Suppose a unified profile is created with data from multiple sources that contain different data about a customer’s first name. For example, the First Name field is Samantha in the first source and Sam in the second source.
If the active reconciliation rule for the field is Last Updated and the second source was modified most recently, the value from the second source is selected for the unified profile's First Name. The reconciled value, Sam, is used in segmentation and activation.
However, if the active reconciliation rule for the field is Source Priority and the first data source is prioritized above the second data source, the reconciled value is Samantha.
- **[Set a Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setdefault.htm&release=264.0.0&type=5)**
Set a default reconciliation rule for each object in your identity resolution ruleset. The default reconciliation rule tells the identity resolution process how to select values for all fields in an object.
- **[Override an Object’s Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setfieldspecific.htm&release=264.0.0&type=5)**
Override an object’s default reconciliation behavior by applying a reconciliation rule to a specific field.
- **[Reconciliation Rule Warnings](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_warnings.htm&release=264.0.0&type=5)**
Reconciliation rule warnings help you identify fields to change or review. You can ignore a reconciliation rule warning. Identity resolution processes run even with these warnings.
#### See Also
- [_Salesforce Help_: Reconciliation Rule Warnings](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_warnings.htm&release=264.0.0&type=5 "Reconciliation rule warnings help you identify fields to change or review. You can ignore a reconciliation rule warning. Identity resolution processes run even with these warnings.")
- [_Salesforce Help_: Set a Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setdefault.htm&release=264.0.0&type=5 "Set a default reconciliation rule for each object in your identity resolution ruleset. The default reconciliation rule tells the identity resolution process how to select values for all fields in an object.")
- [_Salesforce Help_: Override an Object’s Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setfieldspecific.htm&release=264.0.0&type=5 "Override an object’s default reconciliation behavior by applying a reconciliation rule to a specific field.")
# Identity Resolution Ruleset Processing Results
Summary statistics are available after a ruleset job runs for the first time. Results of the most recent run are shown in the Resolution Summary. Results from previous days are listed in the processing history table. If the ruleset was processed more than one time per day, the results in the processing history table reflect the last run completed during the day.
Term
Definition
Ruleset Name
The name given to the ruleset.
Ruleset Status
Indicates the ruleset’s status.
New—The ruleset was created, but no match or reconciliation rules have been
added. The ruleset job hasn’t run yet.
Publishing—Ruleset publication is in progress. Data from the last publish is
available until publishing is complete. Reload the page to see the updated status.
Published—The ruleset was published. Changes to the ruleset are used the next
time that the ruleset job runs.
Deleting—Ruleset deletion is in progress.
Delete Failed—The ruleset deletion failed. Contact Salesforce Customer Support
for help.
Error—The ruleset has a problem. Contact Salesforce Customer Support for
help.
Last Job Status
Indicates the status of the most recent ruleset job.
Blank (no status)—The ruleset was created, but no match or reconciliation rules
have been added.
Scheduled—The ruleset job is ready and waiting to start running.
In Progress—The ruleset job is running. Unified profiles from the last
successful publish are available until the job is completed.
Succeeded—The ruleset job ran successfully.
Succeeded with Warnings—The job was completed but one or more errors resulted in
some records being skipped or filtered out during matching. See Troubleshoot Identity Resolution Ruleset Processing Errors for help with understanding and resolving errors.
Skipped—The ruleset job was skipped because there were no changes to data
streams, to records in the source data model object, or to the ruleset's
configuration.
Error—There was a problem running the ruleset job. Contact Salesforce Customer
Support for help.
Failed—The ruleset job failed. Contact Salesforce Customer Support for
help.
Source Profiles
The count of profiles in the source data model objects.
Total Unified Profiles
Number of unified customer profile records that the ruleset job created.
Consolidation Rate
The amount by which source profiles were combined to produce unified profiles,
calculated as 1 - (number of unified individuals / number of source individuals).
For
example, if you ingest 100 source records and create 80 unified profiles, your
consolidation rate is 20%.
To increase the consolidation rate, try adding more match
rules. To reduce the consolidation rate, try removing some match rules.
Known Unified Profiles
The number of unified profiles made up of at least one known source profile.
Anonymous Unified Profiles
The number of unified profiles made up of only anonymous source profiles.
# Identity Resolution Rulesets
Rulesets contain match and reconciliation rules that tell the customer data platform how to link multiple sources of data into a unified profile. Unified profile information is stored in data model objects created by the ruleset.
- **[Create Identity Resolution Rulesets](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_ruleset_create.htm&release=264.0.0&type=5)**
Get started with identity resolution by setting up a ruleset to unify accounts, individuals, leads, or households. The primary data model object for your ruleset determines which records are unified. Match and reconciliation rules you add to your ruleset after creating it guide how records are matched.
- **[Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules.htm&release=264.0.0&type=5)**
Match rules tell Data 360 which profiles to unify during the identity resolution process. Each match rule contains one or more criteria. Profiles are matched when all criteria within a match rule are satisfied.
- **[Identity Resolution Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5)**
A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.
- **[Scheduled and Real-Time Matching in Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_type_compare.htm&release=264.0.0&type=5)**
Identity resolution can perform two types of ruleset runs: scheduled or real-time. They differ in how and when the two types of ruleset runs are performed, and how they interact with other features.
- **[Identity Resolution Ruleset Processing Results](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_summary.htm&release=264.0.0&type=5)**
Summary statistics are available after a ruleset job runs for the first time. Results of the most recent run are shown in the Resolution Summary. Results from previous days are listed in the processing history table. If the ruleset was processed more than one time per day, the results in the processing history table reflect the last run completed during the day.
#### See Also
- [_Salesforce Help_: Identity Resolution Terminology](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_terms.htm&release=264.0.0&type=5 "Understand what terms like rulesets and unified objects mean when used in the context of identity resolution.")
# Identity Resolution Terminology
Understand what terms like rulesets and unified objects mean when used in the context of identity resolution.
Rulesets
Identity resolution rulesets contain match and reconciliation rules that specify how to link multiple sources of data into a unified profile. Match rules specify how to compare field values to identify matching records. Reconciliation rules specify how to select values from among multiple data sources to use as summary data in the unified profile.
To learn about match rules, see [Identity Resolution Match Rule Terminology](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rule_terms.htm&release=264.0.0&type=5 "Understand the roles that match rules, match criteria, and match methods play in identity resolution rulesets. Adding, adjusting, and removing match rules, match criteria, and match methods can change the consolidation rate of the overall ruleset.").
To learn about reconciliation rules, see [Identity Resolution Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5 "A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.").
Ruleset Job
The ruleset job processes source profiles according to how your source data is mapped and the match, and reconciliation rules you configure. The job runs at least one time a day for each ruleset, unless it detects no changes in source data or ruleset configuration. If nothing has changed, the ruleset job is skipped.
Unified Profile Objects
Identity resolution links source profiles info unified profiles that can be used in processes such as segmentation and activation, calculated insights, reporting, and more. Unification is determined based on the data mappings you create and on match and reconciliation rules specified in the ruleset.
When a ruleset is based on the Individual DMO, information such as first name and last name from multiple data sources is consolidated into unified individual objects. When a ruleset is based on the Account DMO, information such as business name, location, and type is consolidated into unified account objects. Each unified profile object contains summary information about the profile selected using reconciliation rules and IDs that point to source data, allowing you to decide which is the best data source for a given use case.
Unified Contact Point Objects
An individual or account can have multiple valid contact points that must be preserved for each unified individual or unified account. For example, an individual can have both a home phone number and a mobile phone number. Data 360 creates unified contact point objects to aggregate contact points from different data sources, based on mappings and rules in each ruleset. Unified contact point objects retain all unique contact points for a unified profile.
During reconciliation, only the attributes that describe contact points are reconciled if there’s a conflict between sources. For example, if a phone number is listed as personal number in some sources, and a business number in other sources, reconciliation rules determine if the phone number is listed as personal or business.
Unified Link Objects
Unified link objects serve as the link between the source data and unified objects. Unified link objects allow you to view source data of each unified profile and are required for creating calculated insights for unified profiles.
- **[Unified Link Objects and Relationships to Unified Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_unified_and_link_objects.htm&release=264.0.0&type=5)**
Identity resolution creates the following link tables as a bridge between source objects and unified profile objects.
#### See Also
- [_Salesforce Help_: Identity Resolution Match Rule Terminology](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rule_terms.htm&release=264.0.0&type=5 "Understand the roles that match rules, match criteria, and match methods play in identity resolution rulesets. Adding, adjusting, and removing match rules, match criteria, and match methods can change the consolidation rate of the overall ruleset.")
- [_Salesforce Help_: Identity Resolution Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5 "A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.")
# Imbalanced Distribution Alert
Imbalanced distribution indicates a disproportionate ratio of observations in each class of the training data.
## Actions to Consider
Training a model on an imbalanced dataset can result in a less reliable model with biased predictions. When you create a model version, Einstein:
- increases the frequency in the minority class by upsampling the data.
- correct values that reflect an extraordinary, non-recurring, or infrequent event.
## Detection Methodology
Model Builder automatically alerts you when it detects an imbalanced distribution.
## Example
An e-commerce company wants to predict whether its customers will cancel their subscription or churn. To achieve this, the company builds a binary classification model with these input variables.
- customer ID
- monthly cost
- monthly login frequency
- subscription type
- tenure
- churn
After model training, an alert displays because the variable “churn” has a disproportional class distribution, with 95% of customers labeled as active and only 5% as churned. This imbalance can cause the model to favor predicting “active" customers, reducing its ability to accurately identify the ones that churned (high false negatives). To resolve the issue, here are some actions to consider:
- Follow recommendations provided by the alert to balance the dataset.
- Retrain the model with an updated dataset.
# Impact of Custom Permissions on Policies
Custom permissions in Data 360 play a key role in determining how a policy is applied. You can assign them to users through custom permission sets or profiles to act as user attributes within the policy builder.
When defining an access policy, you select one or more custom permissions in the User tab. These permissions indicate which users the policy should apply to or explicitly exclude.
- You can specify multiple custom permissions in the same policy.
- For the policy to be effective, a user must have at least one of the listed custom permissions.
- Attribute-based access control policies are applied to users based on the custom permissions assigned to them.
- You can add custom permissions only to custom permission sets. Standard permission sets and their clones don’t support custom permissions.
#### See Also
- [_Salesforce Help_: Custom Permission Sets in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions_custom.htm&type=5&language=en_US)
# Impact of Data Modeling on Data Subject Rights Requests
Learn more about how Data Modeling impacts your Data Subject Rights Requests in Data 360.
Map all personal data stored in Data 360 to the Individual entity to ensure that it’s processed as part of any Data Subject Rights request.
You can map fields containing personal data to the Individual entity using a standard or custom attribute in Data 360. If you’re storing personal data in another standard or custom entity, create a relationship in the object data model between the field mapped to the customer identifier on that entity and the Individual ID field.

Example Northern Trail Outfitters ingests sales order data from Sales Cloud and stores it in the Sales Order entity in Data 360. This sales order data includes a field for customer email address, which is considered personal data. Northern Trail Outfitters creates a relationship in the object data model between a custom Customer Id attribute on the Sales Order entity and the Individual Id field.
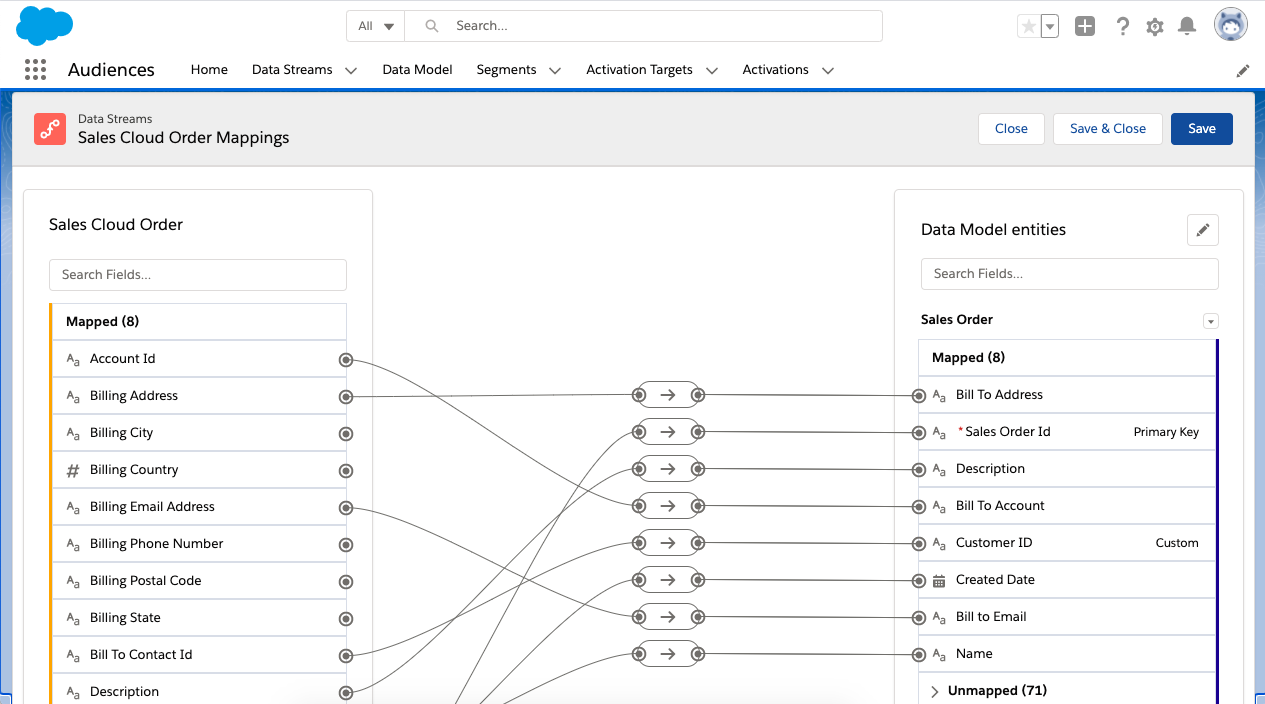

Example Northern Trail Outfitters receives a request from Samantha Smith to delete her personal data. Northern Trail Outfitters finds Samantha's personal data on Individual Id 1234 in Data 360 and submits a data deletion request to the Consent API using that Individual Id. Because a relationship has been defined between a custom Customer ID attribute on the Sales Order entity and the Individual Id field, both entities are deleted as part of the data deletion request.
#### See Also
- [_Salesforce Developer_: Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm)
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Implement a Data Foundation in Marketing Cloud Engagement Using Data from Data 360
You can establish a data foundation by activating data from an external system into Marketing Cloud Engagement and linking it to the Engagement Contact Model. You can then refresh and reuse this data across Journey Builder for journey decisioning, wait activities, and exits. You can also use the data for the content personalization of event-triggered campaigns. This solution kit offers a general blueprint on how to set up a data foundation using Data 360.
This solution kit maximizes both marketer efficiency and end-to-end scale performance while reducing the chances of unintentional billing consumption.
Not all campaigns require implementing a data foundation, such as batch sends, transactional messages, and journeys that don’t use the Engagement Contact Model for decision splits.
Consider these configuration settings when your campaign does trigger a journey. Use Email as the type when creating the Data Extension in Engagement. In Data Cloud, there isn’t an email type so the field is text. For the journey to send to contacts that aren’t in Engagement, use the Journey Builder setting to use email from any source.
## Use Case 1
Cumulus Bank and Financial Services want to integrate Data 360 with Engagement. They’re using Data 360 to establish a data foundation in Engagement. They then want to use the data foundation as part of their campaigns, including their initial customer campaign: a 30-day journey to welcome new auto policy holders and to introduce them to their policy and benefits.
To complete this use case, review the features used, permissions required, and associated skills.
Products or Features
Data 360
Activation
Activation Target
Calculated Insight
Identity Resolution
Marketing Cloud Engagement
Contact Builder
Journey Builder
Roles and Permissions
Data 360
Data Cloud Activation Manager or Specialist permission sets
Marketing Cloud Engagement
Salesforce Marketing Cloud Engagement | General | Access
Salesforce Marketing Cloud Engagement | Campaigns | General | Access
Contacts | Contact Builder | Administer Contact Model
Requirements or Skills Needed
Understanding of activation and activation targets in Data 360
Understanding of the Contact Model in Marketing Cloud Engagement
## Related Content
To help guide you through these use cases we suggest the following related content.
 [_Trailhead_: Data and Identity in Data 360](https://trailhead.salesforce.com/content/learn/modules/data-and-identity-in-salesforce-cdp)
 [_Trailhead_: Explore Synchronized Data Sources](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-contact-management/explore-synchronized-data-sources)
 [_Trailhead_: Segmentation in Data 360](https://trailhead.salesforce.com/en/content/learn/modules/customer-360-audiences-segmentation)
 [_Trailhead_: Marketing Cloud Engagement Contact Management](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-contact-management)

- **[Associated Terms for Data Foundation](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_terms.htm&release=264.0.0&type=5)**
Review terms that you must know when creating your data foundation.
- **[Is This Data Foundation Solution Kit Right for My Organization?](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_right_for_org.htm&release=264.0.0&type=5)**
You can establish a data foundation in Marketing Cloud Engagement in multiple ways. Each customer implementation is unique and has different factors to consider. Use this grid to help guide your decision on which data foundation pattern makes sense for your organization. Your needs might require a hybrid approach and a combination of aspects from multiple patterns.
- **[Data Foundation Solution Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_solution.htm&release=264.0.0&type=5)**
Review the solution workflow for integrating your initial data foundation in Marketing Cloud Engagement.
- **[Establish Data Foundation Requirements for Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_req.htm&release=264.0.0&type=5)**
When integrating Data 360 and Marketing Cloud Engagement, clearly delineate the roles and responsibilities between each product. Data 360 is designed to ingest, resolve, transform, segment, and enrich data. Marketing Cloud Engagement is an engagement product that orchestrates personalized messaging campaigns.
- **[Create Your Core Activations in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_core.htm&release=264.0.0&type=5)**
Let’s review the steps for creating your core activations in Data 360.
- **[Link Core Activations to the Marketing Cloud Engagement Contact Model](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_link.htm&release=264.0.0&type=5)**
Data specialists perform these steps in Marketing Cloud Engagement to establish the data foundation.
- **[Use Data 360 Data Throughout Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_usedata.htm&release=264.0.0&type=5)**
It’s important for Marketers to understand that their interaction with the data foundation varies based on the type of campaign that they’re activating. These recommendations maximize system performance.
- **[Use Case: Cumulus Bank and Financial Services Event-Triggered Journeys](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus.htm&release=264.0.0&type=5)**
Cumulus Bank and Financial Services want to integrate Data 360 with Marketing Cloud Engagement. They’re using Data 360 to establish a data foundation in Marketing Cloud Engagement. They then want to use the data foundation as part of their campaigns, including their initial customer campaign: a 30-day journey to welcome new auto policy holders and to introduce them to their policy and benefits.
- **[Cumulus Establishes Data Foundation Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus_req.htm&release=264.0.0&type=5)**
Cumulus Bank and Financial Services want to integrate Data 360 with Marketing Cloud Engagement. They’re using Data 360 to establish a data foundation in Marketing Cloud Engagement. They then want to use the data foundation as part of their campaigns, including their initial customer campaign: a 30-day journey to welcome new auto policy holders and to introduce them to their policy and benefits.
- **[Cumulus Creates Core Activations in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus_act.htm&release=264.0.0&type=5)**
In this use case, to build their data foundation the Cumulus team creates Data 360 activations for their audiences to Marketing Cloud Engagement. These activations comprise their data foundation.
- **[Cumulus Activates Segments and Adds Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus_att.htm&release=264.0.0&type=5)**
Because the team has chosen to create a Collective Core Audience Model, the marketer repeats these steps for each activation in their data foundation.
- **[Cumulus Links Core Activations to the Marketing Cloud Engagement Contact Model](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus_link.htm&release=264.0.0&type=5)**
Cumulus follows these steps to link core activations to the Marketing Cloud Engagement Contact Model.
- **[Cumulus Uses Data 360 Data Throughout Marketing Cloud Engagement to Create Event-Triggered Journeys](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_cumulus_uses.htm&release=264.0.0&type=5)**
Now that the team at Cumulus Bank and Financial Services has set up their Marketing Cloud Engagement data foundation, their data from Data 360 can be used throughout Engagement in a scalable, reusable way.
- **[Data Foundation Considerations and Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_mcdf_best_practices.htm&release=264.0.0&type=5)**
Generally, we recommend using the Individual portion of your data foundation as much as possible. When executing a journey that uses content personalization or decisioning attributes from the Unified Individual portion of the data foundation, keep these considerations and best practices in mind.
# Implementation Tasks for Predictive AI Solutions
The process of implementing predictive AI solutions typically involves a series of tasks.
### Required Editions
## Common Tasks
#
Task
Description
More Information
1
Define the Outcome to Predict
Define an outcome that you want to improve. It’s most likely a
key performance indicator (KPI) for your business. Most
organizations have many outcomes that are candidates for
improvement. Start with one outcome that’s significant in your
business. Over time, you can develop and apply predictive AI models
to many different outcomes concurrently.
AI Strategy
AI +
Data: Project Planning
2
Assemble the Training Data
Design and populate the training data (in a Data Model Object, or
DMO) to contain the historical data you want the model to learn
from. The DMO contains tabular data that you normalize for model
training. You can use Salesforce data as well as data that’s
external to Salesforce.
Prepare Your Training Data
3
Create the Model
Based on the training data, create and configure a predictive
model that tells Einstein how to analyze your data. Models provide
the settings and preferences that Model Builder uses to generate
insights.
Create Predictive AI Models From Scratch
4
Evaluate Model Quality
Assess performance and refine the predictive model.
Evaluate Model Quality
Address Data Issues
5
Predict and Improve Outcomes
Predict outcomes and get prescriptions using the model you
deployed.
Get Predictions, Prescriptions, and Top Predictors
## Iterative Refinement and Continuous Improvement
Implementation is an iterative process rather than a linear one. Model Builder is designed for rapid exploration, experimentation, and implementation. You learn as you go. Every step of the way, you use built-in feedback to check your results, review your assumptions, ask new questions, make adjustments, and try again. Add a column to your training data. Change model settings. Resolve alerts, refine thresholds, and filter data. As you fine-tune your approach, each improvement can help lead you to better operational outcomes.
# Improve Predictive Models
Model quality is a critical success factor in predictive AI solutions. AI Models (formerly Einstein Studio) supports continuous, iterative improvement for predictive models. Measure model quality in production over time. Use quality alerts to identify and address areas for improvement. Experiment with new model versions. Efforts to improve model quality result in better business outcomes.
## Monitor for Model Drift
In production, models generally become less accurate over time, a phenomenon known as drift. Models drift when characteristics in the real-world data diverge significantly from the training data used to build them. Operational changes, trends, seasonal fluctuations, new or discontinued categories, and other factors can change the composition of your data.
## Predictive Model Lifecycle
To keep your models from drifting off course and staying on track, implement the model lifecycle, which involves continuous and iterative operational tasks.
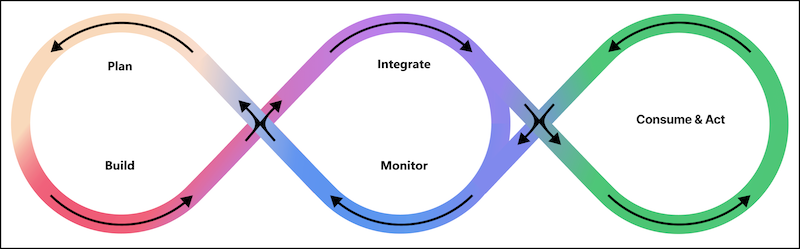
| Phase | Description |
| --- | --- |
| Plan | Design the first or the next version of the predictive model. Define or refine the model’s predictive target (output) and model features (inputs). |
| Build | Populate the training data in Data 360. In Model Builder, build a version of the predictive model. |
| Integrate | Test, integrate, and activate the predictive model in your solution. |
| Consume & Act | In production, request and consume the output (predictions, prescriptions, and top factors) of the predictive model. Use predictive intelligence to make better decisions and take actions that improve business outcomes. |
| Monitor | Monitor the quality of the predictive model’s output. Measure performance, assess model quality, review quality alerts, and identify improvement opportunities. |
## Iterative Refinement and Continuous Improvement
Model implementation is an iterative process rather than a linear one. Model Builder is designed for rapid exploration, experimentation, and implementation. You learn as you go. Every step of the way, you use built-in feedback to check your results, review your assumptions, ask new questions, make adjustments, and try again. Add a column to your training data. Change model settings. Resolve alerts, refine thresholds, and filter data. As you fine-tune your approach, each improvement can help lead you to better operational outcomes.
# Improve Your Einstein Segment Creation Results in Data 360
What happens if you receive unclear results, or if the results aren’t necessarily what you’re hoping for? Use these suggestions to gain more accurate results.
## Refine your metadata with Metadata Studio
Einstein Segment Creation results are optimized with Einstein Data Prism. To get the best results with Data Prism, use the Metadata Studio to review the generated descriptions for objects and fields, enter missing information, and remove obsolete objects from the data source. See [Metadata Studio](https://help.salesforce.com/s/articleView?id=ai.generative_ai_prism_metadata_studio.htm&type=5&language=en_US).
## Make your prompt specific to your brand
Include terms that you use to describe your brand that might not be common for others outside of your company. For example, if you use a specific customer type, specify this in your prompt, such as “all members who are customer type= NSH”. If you want to include a specific product or website, specify this in your prompt, for example, “customers who engaged with website= “mywesite.com.”
## Check whether your prompt is ignoring specific fields
If specific fields are being ignored, try using more brand-specific terms or prepositions to simplify the prompt.
## Remove unwanted attributes
If your results contain attributes that you don’t need or want, deselect them so that they aren’t included with your segment.
## Use descriptive terms
If you need specific information, use descriptive terms in your prompt. For example, if you want data about active users, specify this in your prompt: “active users who engaged today.”
## Broaden your search to increase your population count
If you receive a message that your result will produce a small population, try to broaden your search and focus on the data that you know exists.
# Increase Segment Refresh from Data 360 to the Activation Targets
Increase the frequency of segment refresh and shorten publishing time for activations from Data 360 to the activation targets using Rapid Publish. When you create a segment, choose Rapid Publish to run on a daily schedule at a 1-hour or 4-hour interval.
Segments using rapid publish are prioritized in the publish queue. You can configure lookback window for both publish types. After you create a segment, you can't change a standard publish to a rapid publish. Then activate to Marketing Cloud Engagement, Data Cloud, or file storage targets like Amazon S3, Microsoft Azure, SFTP, and Google Cloud Storage (GCS). You can create up to 20 segments with Rapid Publish.
You can use Rapid Publish in Incremental Refresh mode. For more information, see [Activation Refresh Types.](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_publish_types.htm&type=5&language=en_US)
Standard and rapid segments activate as data extensions in Marketing Cloud Engagement. Incremental Rapid Activations index based on the profile ID mapped to the subscriber key.

Example
A financial services company creates a standard segment targeting customers who viewed a loan product page in the last 30 days. They select rapid publish, set a 30-day lookback window, and configure a 1-hour interval running Monday through Friday so activation data reaches their marketing team throughout the business day.
#### See Also
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Index DMO
The index data model object (IDMO) stores generated vector embeddings.
The Index DMO has these attributes.
| Field Label | Field API Name | Data Type | Description |
| --- | --- | --- | --- |
| `Data Source` | `DataSource__c` | Text | API name of the field from the DMO/UDMO that contains content for the generated chunk. This is a default pre-filtering field. |
| `Data Source Object` | `DataSourceObject__c` | Text | A field populated with the internal filename that contains the chunk for which the vector embedding was generated |
| `Internal Organization` | `InternalOrganization__c` | Text | Unused |
| `Key Qualifier Record Id` | `KQ_RecordId__c` | Text | Key qualifier field for Record ID |
| `Record Id` | `RecordId__c` | Text | Primary key: Unique identifier of each vector embedding |
| `Source Record Id` | `SourceRecordId__c` | Same as Primary ID of source record | Primary ID of the generated chunk table. This matches the chunk table's `RecordId__c`. |
| `Vector Embedding` | `VectorEmbedding__c` | Array of floats | Generated vector embedding |
# Individual Object Data Modeling Requirements
Map the following fields during data modeling to prepare data about individuals for the identity resolution process.
## Required Mappings and Relationships
Required relationships for Contact Point Email, Contact Point Phone, Contact Point Address, Contact Point App, Contact Point OTT Service, and Party Identifier objects are always Many:1 relationships in the data model because many contact points can belong to one individual.
Required relationships for the Individual object are always 1:Many relationships in the data model because one individual can have multiple contact points.
Object Name
Object API Name
Field Labels
Field API Names
Required Mapping
Individual
ssot__Individual__dlm
Individual Id (primary key)
First Name
Last Name
ssot__Id__c
ssot__FirstName__c
ssot__LastName__c
Individual.ID → ContactPointAddress.Party
Individual.ID → ContactPointApp.Party
Individual.ID → ContactPointEmail.Party
Individual.ID → ContactPointPhone.Party
Individual.ID → PartyIdentificationId.Party
Contact Point Address
ssot__ContactPointAddress__dlm
Contact Point Address Id (primary key)
Address Line 1
City
Party
Postal Code
State Province
ssot__Id__c
ssot__AddressLine1__c
ssot__CityId__c
ssot__PartyId__c
ssot__PostalCodeId__c
ssot__StateProvinceId__c
ContactPointAddress.Party → Individual.ID
Contact Point App
ssot__ContactPointApp__dlm
Contact Point App Id (primary key)
ssot__Id__c
ContactPointApp.Party → Individual.ID
Contact Point Email
ssot__ContactPointEmail__dlm
Contact Point Email Id (primary key)
Party
Email Address
ssot__Id__c
ssot__PartyId__c
ssot__EmailAddress__c
ContactPointEmail.Party → Individual.ID
Contact Point Phone
ssot__ContactPointPhone__dlm
Contact Point Phone Id (primary key)
Formatted E164 Phone Number
Party
ssot__Id__c
ssot__FormattedE164PhoneNumber__c
ssot__PartyId__c
ContactPointPhone.Party → Individual.ID
Contact Point OTT Service
ssot__ContactPointOTTService__dlm
Contact Point OTT Service Id (primary key)
Party
Username
ssot__Id__c
ssot__PartyId__c
ssot__Username__c
ContactPointOTTService.Party → Individual.ID
Party Identification
ssot__PartyIdentification__dlm
Party Identification Id (primary key)
Identification Name
Identification Number
Party
Party Identification Type
ssot__Id__c
ssot__Name__c
ssot__IdentificationNumber__c
ssot__PartyId__c
ssot__PartyIdentificationTypeId__c
PartyIdentificationId.Party → Individual.ID
#### See Also
- [_Salesforce Help_: Data Mapping](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping.htm&release=264.0.0&type=5 "Data ingested by all data streams is written to data lake objects (DLOs). After creating your data streams, you must associate your DLOs to data model objects (DMOs). Only mapped fields and objects with relationships can be used for Segmentation and Activation.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Connect Data](https://help.salesforce.com/s/articleView?id=data.c360_a_connectors.htm&release=264.0.0&type=5 "Data sources are ingested into or connected to Data 360 in different ways with specific requirements and steps that an admin configures before creating a data stream.")
# Influence Hybrid Search Relevance Ranking
Increase the accuracy of search index query results and improve the quality of RAG applications by sending relevance-specific parameters. Using SQL, you can send relevance configuration settings for supported fusion ranker models and improve the result relevance for your specific use case.
Hybrid search supports three fusion ranking models: the industry standard Reciprocal Rank Fusion (RRF) model, a customizable Linear Fusion Ranker (LFR) model, and a more robust Deep Fusion Ranker (DFR) model.
A hybrid search query accepts a JSON string that represents the relevance configuration setting.
`select * from hybrid_search( table(), ‘’, '', '', ‘<”Relevance Ranking Configuration” (JSON)>’ );`
## Reciprocal Rank Fusion Model
The Reciprocal Rank Fusion (RRF) model uses a reciprocal ranking fusion formula that considers the weight for each search type to get the most relevant results.
The reciprocal rank fusion formula is the sum of both the keyword search (sparse) and vector search (dense) reciprocal rank scores with a default decay of k=60. The formula also provides an alpha parameter, which controls the sparse weight in a convex combination of the two scores. The search results are ranked using the sum derived from the RRF rank fusion formula.
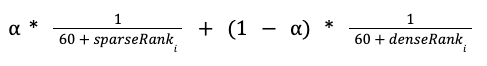
For example, this hybrid search query expression passes the keyword search (sparse) weight parameter for the RRF model.
`select * from hybrid_search( table(), ‘’, '', '', ‘{ "rrf": { "keyword_weight": 0.4 } }’ );`
Input parameters for relevance configuration:
- **rrf**: Enable Reciprocal Ranking Fusion model
- **keyword\_weight**: The importance or weight of the keyword search component in hybrid search. The range is between zero and one. The vector search importance is automatically calculated by deducting the keyword weight from 1.0.
The RRF model also supports an advanced formula that can affect the ranking factors you configure when you create the search index. For more information on ranking factors, see [Hybrid Search Fusion Ranking](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_fusion_ranking.htm&release=264.0.0&type=5 "Ranking reorders the search results so that the most relevant results to a user query are at the top. Data 360 Hybrid search retrieves results from two indexes—keyword and vector— based on the similarity with the query and then merges (fuses) the results. The ranking model then reranks the merged results.").
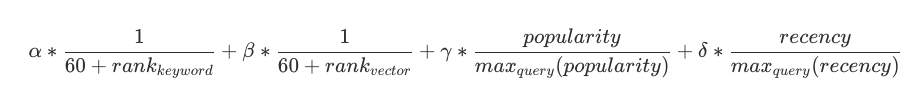
Input parameters for relevance configuration in the advanced RRF formula:
- **Alpha (a)**: represents the importance given to keyword search. Default is 0.5f
- **Beta (B)**: represents the importance given to vector search and is calculated based on the importance given to keyword search (1-alpha).
- **Gamma (Y)**:represents the importance of ranking factor popularity. Default is 0.00074478f. Maximum is 1.
- **Delta (D)**:represents the importance given to ranking factor recency. Default is 0.00028472f. Maximum is 1.
Specify the importance of weights in your query. Tweak and refine the values in low increments to make sure you achieve the right relevance for your results.
## Linear Fusion Ranking Model
The Linear Fusion Ranking (LFR) model is a customizable form of the default fusion ranker model, which calculates a weighted sum of the transformed scores from both vector search (dense) and keyword search (sparse). The search results are ranked using the sum derived from the LFR formula.
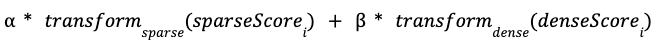
By default, hybrid search provides the best linear fusion ranker configuration using transformations and weights based on internal experiments and benchmarks. With LFR, ranking is further configurable using the transformation functions for the keyword search (sparse) score and vector search (dense) score, and their weights.
The LFR model can also use the recency and popularity ranking factors which can be configured while setting up hybrid search for a DMO. The additional ranking factors are configurable using transformation functions and weights.
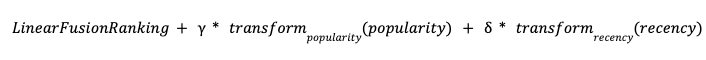
For example, this hybrid search query expression passes relevance parameters for the LFR model.
`select * from hybrid_search ( table(), ‘’, '', '', ‘{ "lfr": { "vector": { "score_transform": { "type": "reciprocal_rank", "decay": 60 }, "weight": 0.66913 }, "keyword": { "score_transform": { "type": "query_min_max", "theoretical_min": 0.1 }, "weight": 4.0343633 } } }’);`
Input parameters for relevance configuration:
- **lfr** - Enable Linear Fusion Ranking model
- **vector**: Configures ranking for vector search
- **keyword**: Configures ranking for keyword search
Each of the ranking configurations for vector and keyword search can take these parameters:
- **score\_transform**: The configuration for score transformation for the search component
- **type**: The type of score transformation
- reciprocal\_rank
- query\_min\_max
- **decay**: Supported only for Reciprocal Rank Transform, the decay parameter controls the gradient between result ranks. For example, the reciprocal rank score between results ranked 1 and 2 are farther apart with a decay of 10 versus a decay of 20.
- If the query includes a decay parameter, then score = 1/(rank+decay).
- **theoretical\_min**: Supported only for Theoretical Min/Max Transform, represents the theoretical minimum score for the underlying search feature. Use this parameter to scale the feature distribution up or down in a range between \[0,1\]. So choose a value that is the lowest value for the feature to get the best outcome. For the keyword search score, 0 is the appropriate value. Do not tweak this value unless you have data indicating a higher value provides better relevance.
- **weight**: The importance to give to this component of hybrid search
## Deep Fusion Ranker Model
The Deep Fusion Ranker (DFR) model enhances search relevance by integrating traditional signals such as vector similarity, keyword matches, popularity, and recency with a deeper understanding of the query text. By leveraging deep learning techniques and transformer architectures, the model captures complex feature interactions and jointly scores records. The search results are accurate, refined, and contextually relevant. This model effectively handles missing and noisy data, which ensures reliable performance across diverse search scenarios.
Enable the Deep Fusion Ranker model using the dfr relevance configuration setting. There are no other customizations available for this model.
For example, this hybrid search query expression passes the relevance parameter for the Deep Fusion Ranker model.
`select * from hybrid_search ( table(), ‘’, '', ')', ‘{ "dfr": {}}’ );`
Input parameters for relevance configuration:
- **dfr**: Enable Deep Fusion Ranker Model
#### See Also
- [_Salesforce Help_: Hybrid Search Autodrop](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_autodrop.htm&release=264.0.0&type=5 "Dynamically filter out results that show a sharp decrease in relevance scores to increase the precision of search results for your prompts and RAG use cases. Data 360 hybrid search autodrop is a method by which you can filter out irrelevant search results that can mislead upstream applications like prompt builder using those results.")
- [_Elastic Search_: Reciprocal Rank Fusion Method](https://www.elastic.co/guide/en/elasticsearch/reference/current/rrf.html)
- [_Trailhead_: Hybrid Search for RAG: Quick Look](https://trailhead.salesforce.com/content/learn/modules/hybrid-search-for-rag-quick-look)
# Ingest and Map Data from Sales Cloud
In Data Cloud, you can connect to many data sources. Many of the Salesforce connectors have a starter data bundle to help you quickly set up a data streams, create data lake objects, and map to the data model automatically. However, you must map custom objects and some required fields to the Customer 360 Data Model to use Identity Resolution.
## Create a Sales Cloud Data Stream
While many data sources can be connected to Data Cloud, in this use case we create a Sales data stream based on a bundle.
1. In Data Cloud, go to the **Data Streams** tab and click **New**.
2. Select the Salesforce CRM data source and click **Next**.
3. To create your data stream, select a Salesforce org. If you have only one Salesforce org connected to Data Cloud, it’s selected by default.
4. Select the Sales data bundle and click **Next**. The default data space is selected, and all the fields in the bundle are listed.
5. Leave the selections as is, and click **Next**.
6. Enter the deployment details and how often you want to refresh the data. Review the fields to include in your data stream and click **Next**.
7. Click **Deploy**.
Your Sales Cloud data stream is now created.

Tip If you run into issues while creating a data stream, check the object and field permissions in your Sales account. See [Enable Object and Field Permissions to Access Salesforce CRM in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&type=5&language=en_US).
## Map Data Stream to DMO
During data ingestion, data is brought in as is—fields and their data types are imported without transformation. You create a data stream to bring in the data into Data Cloud. Data ingested by all data streams is written to data lake objects (DLOs) A data bundle maps standard fields, but for this use cases, you manually create and map the phone number field. This field is used in identity resolution to match two or more accounts or individuals that have the same name and phone number.
1. In Data Cloud, on the Data Streams tab, select the Contact data stream.
2. In the Data Mapping section, click **Review**.
The data lake objects (DLOs) and the object that you selected are listed on one side of the screen. The searchable data model objects (DMOs) are listed on the other side.
3. Under Data Lake Objects, click the **Business Phone** field.
4. Under Data Model entities, use the search box to find the Formatted E164 Phone Number field in the Contact Point Phone object. You might need to click the Unmapped to expand the section.
5. Click the **Formatted E164 Phone Number** field to map it to Business Phone on the left.
A solid line connects the two fields.
6. Click **Save**.
7. Repeat these steps for the Lead data stream.
8. Map the Phone field on the Lead DLO to the Formatted E164 Phone Number field on the Contact Point Phone DMO.
9. Click **Save**.
View a data stream’s status from the Data Stream tab. If you don’t see a status, click the dropdown and select **Refresh Now**.
# Ingest and Map Data from Service Cloud
In Data Cloud, you can connect to many data sources. Many of the Salesforce connectors have a starter data bundle to help you quickly set up a data streams, create data lake objects, and map to the data model automatically. However, you must map custom objects and some required fields to the Customer 360 Data Model to use Identity Resolution.
## Create a Service Cloud Data Stream
While many data sources can be connected to Data Cloud, in this use case we create a Service data stream based on a bundle.
1. In Data Cloud, go to the **Data Streams** tab and click **New**.
2. Select the Salesforce CRM data source and click **Next**.
3. To create your data stream, select a Salesforce org. If you have only one Salesforce org connected to Data Cloud, it’s selected by default.
4. Select the Service data bundle and click **Next**. The default data space is selected, and all the fields in the bundle are listed.
5. Leave the selections as is, and click **Next**.
6. Enter the deployment details and how often you want to refresh the data. Review the fields to include in your data stream and click **Next**.
7. Click **Deploy**.
Your Service Cloud data stream is now created.

Tip If you run into issues while creating a data stream, check the object and field permissions in your Sales account. See [Enable Object and Field Permissions to Access Salesforce CRM in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&type=5&language=en_US).
## Map Data Stream to DMO
During data ingestion, data is brought in as is—fields and their data types are imported without transformation. You create a data stream to bring in the data into Data Cloud. Data ingested by all data streams is written to data lake objects (DLOs) A data bundle maps standard fields, but for this use cases, you manually create and map the phone number field. This field is used in identity resolution to match two or more accounts or individuals that have the same name and phone number.
1. In Data Cloud, on the Data Streams tab, select the Contact data stream.
2. In the Data Mapping section, click **Review**.
The data lake objects (DLOs) and the object that you selected are listed on one side of the screen. The searchable data model objects (DMOs) are listed on the other side.
3. Under Data Lake Objects, click the **Business Phone** field.
4. Under Data Model entities, use the search box to find the Formatted E164 Phone Number field in the Contact Point Phone object. To expand the section, click the **Unmapped** section.
5. Click the **Formatted E164 Phone Number** field to map it to Business Phone on the left.
A solid line connects the two fields.
6. Click **Save**.
View a data stream’s status from the Data Stream tab. If you don’t see a status, click the dropdown and select **Refresh Now**.
# Ingest and Model Digital Identifiers for JSON-based External Activation Targets
Ingest and model your digital identifier data by using the standard `ContactPointDigitalId` data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.
### Required Editions
Available in: Lightning Experience Available in: Developer , Enterprise and Unlimited Editions

Note To activate anonymous digital identifiers, it's recommended to use ContactPointDigitalID DMO instead of mapping the digital identifiers to custom fields on the Individual DMO.
Before mapping your data, it’s important to understand the target blueprint. Map your source identifiers to the `ContactPointDigitalId` DMO. For activations to work, this DMO must have an established Many-to-One (N:1) relationship to the Individual DMO (linking `ContactPointDigitalId.ssot__IndividualId__c` to `Individual.ssot__Id__c`). You can verify or create this relationship in the Data Model tab. This mapping is mandatory when you use the activation toolkit for JSON-based external activation platforms that rely on specific digital identifiers (for example, UID2, RampID).

Note
If your activation only targets email or phone-based destinations (by using `ContactPointEmail` or `ContactPointPhone`), this DMO is optional, though it’s recommended to centralize all digital identities here.
## Prepare Your Source Data
You can ingest data via multiple methods, including CSV/File ingestion, Ingestion API, or WebSDK. Regardless of the ingestion method (batch or streaming), your source data structure must support the granular mapping required by the DMO. Pivot your source data so that you have one column for the identifier's type and another for its value.

Example
Example Source Data Structure
Individual_ID
FirstName
Digital_ID_Type
Digital_ID_Value
1001
Ana
TD ID
cdcbe3dd-8fe3-44d6-a4b3-ba55e4400000
1001
Ana
GoogleID
584eb2cf-182c-409a-b1f0-9a4827179841
1002
Bob
TD ID
74e6751f-8f86-4dbb-a96e-d9123456789

Note The 'Digital ID Type' and 'Digital ID Value' are specific fields on the ContactPointDigitalId DMO. Your source data must be explicitly mapped and ingested into these fields.
## Configure the ID Type Mapping
Before you begin mapping your data stream, make sure that the identifier types in your source data perfectly match the configuration in the Data 360 Setup page.
As a Data 360 Admin user, go to **Data 360 Setup > External Activation Target > \[Target Name\] > ID Type Mapping** and configure the ID type mapping.
The exact string value in your source data's Digital\_ID\_Type column (for example, "TD ID") must perfectly match the string configured in the ID Type column by the Data 360 administrator. Because Data 360 uses this string as a strict filter during activation, a case-sensitive mismatch (for example, a value in your data might appear as “TDID,” whereas the Data 360 setup lists it as “TD ID”) results in zero activated records.

Note
During activation, the final computation includes both the partner-supported ID type in the left column (for example, Google) and all mapped aliases in the right column (for example, GID, gid, and GAid). In this example, any record in the `ContactPointDigitalId` DMO with a `DigitalIdType` value of Google, GID, gid, or GAid is activated to the corresponding destination.
## Create and Map Your Data Stream
After preparing your source file, create your data stream and map it to the standard DMOs.

Note Data 360 doesn’t automatically link new DMOs. After you complete these mapping steps, you’ll likely need to create the relationship manually between `ContactPointDigitalId` and `Individual`.
1. Create a data stream and point it to your data source.
2. In the mapping canvas, map your profile data to the Individual DMO.
- Map Individual\_ID -> Individual.IndividualId
- Map FirstName -> Individual.FirstName
- If you're activating anonymous users, you don't have standard profile data like a First Name or a known Customer ID. In this case, you must use a persistent digital identifier (such as a Device ID or Cookie ID) to act as the individual's profile ID. Map this value to the `ssot__IndividualId__c` field to represent the anonymous individual in the data model.
3. In the mapping canvas, map your source fields from the data lake object (DLO) to the specific fields on the ContactPointDigitalId DMO. Correct field-level mapping is critical to prevent zero population errors during activation.
| Target Field (ContactPointDigitalId DMO) | Source Field Description | Notes |
| --- | --- | --- |
| ssot\_\_Id\_\_c (Primary Key) | Unique record ID (for example, Device ID, Event ID, or UUID) | This must be a unique key for the record itself (For Example, device\_id or event\_id). Don’t map the Digital ID value here. |
| ssot\_\_IndividualId\_\_c | Individual ID | Links this digital ID to a specific profile. |
| ssot\_\_DigitalIdType\_\_c | Type string (for example, "TDID", "GoogleID") | This identifies what kind of ID it is. This ID is case-sensitive. |
| ssot\_\_DigitalIdValueText\_\_c | The actual ID token | The alphanumeric string used by the platform (For Example, the UID2 token). |
4. Map the relationship field that links the two objects. This step is critical.
- Map Individual\_ID -> ContactPointDigitalId.IndividualId\_\_c
- Verify or create the Data Model relationship. Go to the Data Model tab and make sure a Many-to-One (N:1) relationship exists between ContactPointDigitalId and Individual. If it doesn’t exist, create it manually by linking `ContactPointDigitalId.ssot__IndividualId__c` to `Individual.ssot__Id__c`.
This mapping creates the correct, related data structure that is required for activations.
#### See Also
- [_Salesforce Help_: Map Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&language=en_US)
- [_Salesforce Help_: External Activation Platforms](https://help.salesforce.com/s/articleView?id=data.c360_a_build_external_activation_platforms.htm&language=en_US)
# Ingest Data by Uploading a File
Create a data stream by bringing in data from a local CSV file into Data 360.
### Required Editions
User Permissions
Needed
To upload data using a file
Permission set:
**Before You Begin**
- Verify that your file is less than 2 GB and has a maximum of 1,050 columns.
- Use the four-digit (“yyyy”) format for date and time records that include a year. When data from an ingested file uses the two-digit (“yy”) format, additional date and time pattern rules for the [“year”](https://docs.oracle.com/javase/8/docs/api/java/text/SimpleDateFormat.html) are applied. This can result in an unexpected date value.
- Use a supported format when your file contains date or date-time values. See [Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.").
- If you create or update a sandbox org, activate the **UploadedFiles** connection from Setup, in **Other Connectors**.
Watch this video or follow the steps to use this feature.
1. In Data Cloud, go to the Data Streams tab and click **New**.
2. Select the File Upload tile, and click **Next**.
3. Select the CSV file with your data.
You can upload up to 2 GB.
4. Specify your data lake object (DLO), and API name.
5. In the Properties section, select the category for your data stream and primary key.
6. To change a field's data type, click the Supported Fields tab.
7. Click **Next.**
8. (Optional) If needed, change the data stream name. The data stream uses the uploaded file name.
9. (Optional) If needed, choose a data space and set filters.
10. To create your data stream, click **Deploy**. This ingests your data into the DLO.

Important
You can create a maximum of 100 data streams and DLOs from file uploads.

Note
If you upload a file to the data stream and no records are visible after the upload, check if there are null values in the primary key column of the file. If the column contains null values, remove them from the file and upload it again.

Note
When you install a File Upload Stream in a target org using a Data Kit, the stream is inactive and returns the error "INVALID\_ARGUMENT: Invalid tenantId in FullyQualifiedPath". This issue occurs because the stream points to file storage in the source org, which the target org can't access. To resolve the issue, open the stream in the target org, click **Update File**, and upload the file to reconnect it to the target org's storage.
- **[Data Stream Updates Using File Upload](https://help.salesforce.com/s/articleView?id=data.c360_a_upload_a_csv_file_update_data_stream.htm&release=264.0.0&type=5)**
Update the data of an existing data stream created using File Upload. Quickly update your data by re-uploading the revised CSV file with added or removed records. Updating data replaces the data that was previously stored in the associated Data Lake Object (DLO). It also ensures that the data stream is always current with the latest information.
# Ingest File Attachments from Salesforce CRM Objects into Data 360
Use the Salesforce CRM connector to ingest into Data 360 content files such as documentation or customer support files. You can ingest content files attached to standard and custom CRM objects, including 100K of the most recently uploaded historical files and all new files going forward. Data 360 converts the content into searchable vectors for generative AI, analytics, and automation while preserving search context.
### Required Editions
User Permissions
Needed
To ingest content document data
Additional permissions
## How File Attachment Ingestion Works
When you set up file attachment ingestion, Data 360 ingests all files attached to CRM objects, regardless of when you created the connection to the CRM org and its data streams. The relevant data streams are:
- [Content Document](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_contentdocument.htm?q=contentdocument): Represents documents uploaded to a library in Salesforce CRM.
- [Content Version](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_contentversion.htm?q=contentdocument): Represents the specific version of a document in Salesforce CRM.
- [Content Document Link](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_contentdocumentlink.htm?q=contentdocument): Represents a link to users, groups, records, or libraries that the file is shared with.
You can ingest file attachments of the types listed under [Unstructured Data File Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&language=en_US)
During setup, install a content bundle to deploy the three content data streams, and then create a search index to enable file attachment ingestion. The search index triggers an initial day-0 ingestion of up to 100,000 of the most recent historical files that were attached to the CRM object before you deployed the content bundle. This 100,000 limit applies to each CRM object, regardless of how many search indexes you create. After the initial ingestion, all new file attachments are incrementally ingested and relevant search indexes are automatically refreshed.
The **ContentDocument**, **ContentVersion**, and **ContentDocumentLink** data streams ingest metadata for all files. The 100,000 limit applies only to file content.

Note
If you've been ingesting file attachments from CRM to Data 360 prior to July 2026, the **ContentVersion** data stream behaves differently from other CRM content objects.
- **ContentDocument** and **ContentDocumentLink** (structured data) ingest all the content during the initial ingestion.
- **ContentVersion** (unstructured file content) ingests only five versions that you create or update after you create the data stream. To trigger historical file ingestion, delete the existing ContentVersion data stream and deploy the standard content\_bundle. Then, either create new Salesforce objects with file attachments or use the existing attachments to the existing Salesforce objects.
- File attachment ingestion doesn’t support full refresh or total replacement for the ContentVersion data stream.
Before you set up a file attachment ingestion, plan your workflow by one of these scenarios.
Scenario
Steps
First-time setup
Use the Salesforce CRM connector to install the content_bundle that deploys
the Content Document, Content Version, and Content Document Link data streams.
Attach files to standard or custom Salesforce objects, and deploy a data stream
for your desired CRM object. Create a Search Index with the appropriate source and
attachment DMO.
You created content data streams before July 10, 2026
Any content data streams that you created before July 2026 aren’t compatible
with this file attachment ingestion workflow.
If you created the ContentDocument, ContentVersion, and ContentDocumentLink
data streams before July 2026, you can only ingest files that were attached to
CRM objects after you created the data streams.
To ingest your historical file attachments, delete the existing content data
streams and deploy the standard content_bundle. Then, either create new
Salesforce objects with file attachments or use existing attachments to existing
Salesforce objects.
## Set Up File Attachment Ingestion
### Before You Start
1. Identify the objects in your CRM org that have file attachments you want to ingest (for example, Account).
2. To ingest file attachments from an external CRM org, [set up an external CRM org connection to that org](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_crm_connection.htm&release=264.0.0&type=5 "A data source and data action target are automatically created for the org where you set up Data 360. To connect other Salesforce orgs, manually set up a connection."). For a [CRM home org](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_salesforce_orgs.htm&release=264.0.0&type=5 "Connect your Salesforce orgs to Data 360 to ingest data from Salesforce objects for processing and unification in Data 360. Depending on the type of connection that you select, you can send back only data actions or harmonized Data 360 data. To access Data 360 data and features in your Salesforce CRM orgs, set up a Salesforce companion connection. Platform components, such as Flow, Apex, CRM, and data enrichment, can also access Data 360 data across companion orgs."), Data 360 automatically creates the connection for you.
## Step 1: Deploy a Data Stream for Your Desired CRM Object
Create or deploy a data stream for the specific CRM object (standard or custom) to which the files you want to ingest are attached (for example, Case, Opportunity). [Learn how to create a Salesforce CRM data stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.").
## Step 2: Deploy the Standard Content\_Bundle

Note If you already have the Content Document, Content Version, and Content Document Link data streams, delete them first. Delete any downstream dependencies, such as search indexes or retrievers.
Install the standard Content\_Bundle to deploy the Content Document, Content Version, and Content Document Link data streams. Learn more about [installing standard data bundles powered by data kits](https://help.salesforce.com/s/articleView?id=data.c360_a_install_standard_data_bundles_powered_by_data_kits.htm&release=264.0.0&type=5 "After you create your Data 360 instance and set up your Salesforce CRM connection, you can install standard data bundles that are powered by data kits to deploy data within Data 360.").
1. From the app launcher, open Data 360 (Data Cloud).
2. In Data 360, go to the **Data Streams** tab.
3. Click **New** to create a new data stream.
4. Select data source: Salesforce CRM, and click **Next**.
5. Select the CRM org with the file attachments that you want to ingest, and click **View Bundles**.
6. Under **Standard Bundles**, select **Content\_Bundle** and click **Next**.
7. On **New Data Stream**, make sure that for each data stream on the left, all the fields are selected. You don’t need to configure any other setting.
8. Click **Next** to continue.
9. Select the relevant data space and click **Deploy**. The content data bundle deploys these three data streams for your CRM object and their inter-relationships.
10. Go to your **Data Streams** tab to confirm the relationships are created and active.
Content Document: Represents documents uploaded to a library in Salesforce CRM.
Content Version: Represents the specific version of a document in Salesforce CRM.
Content Document Link: Represents a link to users, groups, records, or libraries that the file is shared with.
## Step 3: Create a Relationship Between the Desired CRM Object DMO and the Content Document DMO
After Data 360 deploys the three content data streams and their inter-relationships, configure the object relationship.
1. In Data 360, go to the **Data Model** tab.
2. From Data Model Objects, select the **Content Document Relationships**.
3. Open the **Relationships** tab and click **Edit**.
4. Add a new relationship row with these values.
Object Content Document Relationship Field Related Item Cardinality N:1 Related Object Data Cloud and the object that has file attachments Related Field The primary key of the object that has file attachments, for example: Account Id
5. Save the new relationship.
6. Go to **Data Model** and then **Data Model Objects** and **Content Document Relationship** to ensure that a relationship exists between the object DMO (for example, Case, Opportunity, Account, or your custom object DMO) and the ContentDocumentRelationship DMO.
7. Confirm the following relationships also exist. Data 360 usually creates these relationships automatically during the Content\_Bundle deployment. If one them doesn’t exist, create it manually using these values.
Object Content Document Relationship Field Content Document Cardinality ManyToOne Related Object Content Document Related Field Content Document Id
Object Content Document Field Last Published Version Cardinality ManyToOne Related Object Content Version Related Field Content Version Document Id
Object Content Document Version Field ContentDocument Cardinality ManyToOne Related Object Content Document Related Field Content Document Id
#### See Also
- [_Salesforce Help_: Map a Custom DMO](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&release=264.0.0&type=5 "Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.")
- [_Salesforce Help_: Create a Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
- [_Salesforce Help_: Map Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_content_data_mappings.htm&release=264.0.0&type=5 "Content data streams enable you to upload and ingest files that you’ve attached to Knowledge objects. Manually map the listed fields of the Content Document and Content Document Link objects to DMOs in Data 360.")
## Step 4: Create Search Index with Advanced Setup
If you create the content data streams without an accompanying search index, Data 360 ingests only file metadata. To trigger file ingestion, create a search index. After you create it and select the correct attachment data model, Data 360 automatically detects and ingests historical file attachments in reverse chronological order (newest first).

Note For existing search indexes, Data 360 doesn't ingest the historical file attachments. To ingest historical file attachments, [rebuild the search index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_rebuild_search_index.htm&language=en_US).
1. From Data 360, open the **Search Index** tab and click **new** to create a new search index.
2. Click **Advanced Setup**, and then click **Next**.
3. Under **Select Search Type**, select **Vector Search** or **Hybrid Search**.
4. Select the relevant data space and the source data model object (DMO) where your file attachments reside.
5. On **Select Fields to Chunk**, click **Include File Attachments**.
6. Select the ContentDocumentVersion DMO, and click **Save**.
7. Configure other settings as needed and save the Search Index.
After you create a search index, Data 360 immediately starts to ingest and index file attachments to make the contents available in the search index. To validate that Data 360 ingested and indexed your files, you can query the Chunk DMO via Query Editor and then confirm you see relevant chunks from your files.
Data 360 refreshes the data as described in [Data Refresh Process for Extraction](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5 "Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge_kav objects."). New files are included in this incremental ingestion. Data 360 captures any new file attachments or deleted files as events from the data streams.
# Ingest Google Analytics into Data Cloud
To gain insight into your customer interactions, connect Sales or Service Cloud and Google Analytics data in Salesforce Data Cloud. Enrich your customer information with web engagement data to better segment key audiences and personalize customer interactions.
Adding Google Analytics data to Data Cloud gives you valuable insights into how visitors interact with your websites. For example, you can learn how much time a user spends on your website, which pages they visit, and where they’re geographically located.
This solution helps you:
- Connect your Google Analytics data to BigQuery.
- Link your Sales Cloud or Service Cloud data to Google Analytics.
- Set up the Google Cloud Storage connector in Data Cloud.
- Import your Google Analytics data into Data Cloud.
- Schedule recurring queries to add Google Analytics data to Data Cloud regularly.
## Products or Features
To complete this use case, review the features used, permissions required, and associated skills.
- Salesforce Data Cloud
- Sales Cloud or Service Cloud
- Google Analytics 360 version or Google Analytics 4
- Google BigQuery
- Google Cloud Storage
- CRM Analytics
## Permissions
- Data Cloud Architect
- Google Analytics Administrator
- Google Analytics Editor
- Google BigQuery admin
## Configuration Considerations
Consider the following information when you ingest Google Analytics data into Data Cloud.
Google Analytics
If you currently use the Salesforce Web and Mobile SDK or Marketing Cloud Personalization to enrich Data Cloud profiles with behavioral data, confirm which attributes are prioritized. Prevent data duplication using Google Analytics.
BigQuery Projects
- BigQuery Export is available only in Google Analytics 360.
- Data in Google Analytics BigQuery resides in the United States, by default. Therefore, Google Analytics BigQuery Export is incompatible with Google Cloud Platform (GCP) policies that prohibit the creation of datasets in the United States. To align with these policies, localize your dataset to the European Union.
- Don’t link more than 300 Google Analytics reporting views to a single BigQuery Project because doing so degrades the export of intradata trading.
- You can link only one Google Analytics reporting view to each property.
- After connecting your Google Analytics data to your BigQuery project, Analytics data appears within 24 hours. Each day, the previous day’s data is exported as a single file, and the current day’s data is exported as three.
- You can link only one Google Analytics reporting view to each property.
- The service account must have EDIT access to your BigQuery project to turn on data exporting.
Measurement Protocol Google Analytics
- Salesforce data integrated using the measurement protocol is stored in Google Analytics as custom dimensions.
- Google Analytics generates client IDs.
- Google Analytics only tracks events associated with a user ID.
- Google Analytics tracks only events associated with a user ID. Unassociated events are discarded from the user ID profile.
- If a visitor signs in or registers during a session, events before the authentication are associated with the user ID.
- When using the measurement protocol with your own visitor identifier (UID), your Google Analytics view is split: one profile shows all your website traffic without insights on cross-device activity, and the other shows only user ID traffic with cross-device insight.
- If you can’t assign an ID to a user, don’t send the uid parameter. All users without the necessary data still count against your data limits and can cause reporting discrepancies.
- For Marketing Cloud Engagement customers, you can use the Subscriber ID (sfmc\_id) as the uid for tracking. To pass the sfmc\_id query parameter to the uid field in the Google Analytics tag, set up a Custom Dimension in Google Analytics and modify the Google Analytics tag to include a ‘URL’ variable.
Customer 360 Data Model Schema
- If you want to bring custom attributes into Data Cloud from Google Analytics 4 or 360, you must first create custom data model objects from existing data model objects.
- You can use only mapped fields and objects with relationships for segmentation and activation.
## Related Content
- Trailhead: [Salesforce CRM](https://trailhead.salesforce.com/content/learn/modules/lex_implementation_basics)
- Trailhead: [Understand Your Web Users with Google Analytics](https://trailhead.salesforce.com/content/learn/trails/understand-your-web-users-with-google-analytics)
- Trailhead: [Google Analytics 360 Integration for Marketing Cloud Engagement](https://trailhead.salesforce.com/content/learn/modules/google-analytics-360-integration-for-marketing-cloud)
1. **[Follow Steps to Ingest Google Analytics into Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_ga_task_steps.htm&release=264.0.0&type=5)**
Connect your CRM and Google Analytics data in Data 360 using the following configurations. This multi-step solution includes multiple roles and permission sets to complete steps in Data 360, Sales Cloud or Service Cloud, CRM Analytics, and Google Analytics.
# Ingest Hierarchical Data
Bring Salesforce CRM organizational hierarchies such as Role, Manager, and Territory into Data 360. After ingestion, you can reference these hierarchies in hierarchy-based record-level security (RLS) policies.
### Required Editions
User Permissions Needed
To access Data 360 Setup:
Permission set:
Before completing this task, consider these guidelines and limitations.
- Hierarchy data is synchronized periodically. It can take up to 15 minutes for changes in the source system to be reflected in Data 360.
- For the hierarchy operator to appear as an option in Policy Builder, complete the hierarchy setup.
- After you configure a hierarchy, you can’t edit or delete it.
- To use RLS hierarchy, install the required version of the Salesforce Standard Data Model SSOT package in your org. Hierarchy ingestion fails if the required version isn't installed.
- Role hierarchy requires SSOT version 1.83 or later, which includes the `ssot_UserRole__dlm` object.
- Manager hierarchy requires SSOT version 1.116 or later, which introduces the `ManagerId__c` field in the `ssot_User_dlm` object.
- If you use both Role and Manager hierarchy, install SSOT version 1.116 or later.
To configure hierarchy ingestion:
1. Go to **Data Cloud Setup**.
2. From Quick Find, search for and select **Hierarchy Ingestion**.
3. On the Hierarchy Ingestion page, click **New Hierarchy Ingestion**.
4. From the Source Connection dropdown menu, select the connector for your Salesforce org that you want to ingest hierarchy data from.
One data lake object (DLO) is created for each connection, and all DLOs in a hierarchy are mapped to a single data model object (DMO) within each data space.
- For a Role hierarchy, two DLOs are created: UserRole and User.
- For a Manager hierarchy, one DLO is created: User.
- For a territory hierarchy, three DLOs are created: User, Territory2, and UserTerritory2Association.
5. From the Hierarchy dropdown menu, select the hierarchy to ingest. For example, **Role**.
Currently, only Role, Manager, and Territory hierarchies are supported. When you set up a hierarchy, Data 360 automatically creates hierarchy data objects. You can secure these hierarchy objects independently, similar to other DLOs and DMOs.
6. From the Data Space dropdown menu, select the corresponding data space for this hierarchy. For example, **AMER** or **EMEA**.
7. (Optional) To add additional hierarchies, click **+Add Hierarchy**.
8. **Save** your configuration.
# Ingest Lead Ad Data into Data Cloud
Set up the Lead Capture app to pull leads from Meta (formerly known as Facebook) into Sales Cloud, connect Sales Cloud to Data Cloud, and receive leads into a data lake object (DLO). Having lead information in Data Cloud can help with event orchestration, activation to ad networks, and lead scoring.
### Required Editions
This multi-step solution includes multiple roles and permission sets to complete steps in Data Cloud, Sales Cloud, and Meta. Bookmark this page or keep it open in a separate window to refer to this topic.
## Step 1: Install Lead Capture for Salesforce
To use this solution, you must have the Lead Capture app installed. To install and configure Lead Capture, complete the following steps.
1. Review the [implementation guide](https://appexchange.salesforce.com/partners/servlet/servlet.FileDownload?file=00P4V00000wVG7NUAW) and [user guide](https://appexchange.salesforce.com/partners/servlet/servlet.FileDownload?file=00P4V00000wVG7XUAW) before installation that's available on **AppExchange** (Admin—15 minutes)
2. [Configure Lead Capture Cloud](https://appexchange.salesforce.com/appxListingDetail?listingId=a0N4V00000HA0mqUAD&tab=d) available on **AppExchange** (Admin—10 minutes).
3. Confirm leads are received from Meta into the Lead Object in **Salesforce** (Admin—2 minutes).
## Step 2: Create a Salesforce CRM Data Stream
To create a Salesforce CRM data stream in Data Cloud, you must first connect your Salesforce account. Then, create a Salesforce CRM data stream based on a Lead Object.
1. [Set Up the Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_crm_connection.htm&type=5&language=en_US) in **Data Cloud** (Data Cloud Architect Permission Set—2 minutes).
2. [Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&type=5&language=en_US) in **Data Cloud** (Data Cloud Architect Permission Set—2 minutes).
## Step 3: Map Data Stream to DMO
Customize where the data streams are mapped to. When the Salesforce connector is set up, a Lead DMO is created automatically.
1. [Create a Custom Data Model Object from an Existing Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_dmo_from_existing.htm&type=5&language=en_US) in **Data Cloud** (Data Cloud Architect Permission Set—5 minutes).
2. [Map Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&type=5&language=en_US) in **Data Cloud** (Data Cloud Architect Permission Set—2 minutes).
## Step 4: Confirm Leads Route from Meta into Data Cloud DMO
Meta provides a tool for creating test leads to simulate an end user creating a lead, which shows the flow of data you’ve set up in Salesforce and Data Cloud.
1. [Testing and Troubleshooting](https://developers.facebook.com/docs/marketing-api/guides/lead-ads/testing-troubleshooting/)—[Create a Custom Data Model Object from an Existing Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_dmo_from_existing.htm&type=5&language=en_US) in **Data Cloud** (5 minutes).
2. Check in the Lead Object with the name: (Admin—5 minutes).
3. Go to **Data Cloud** and click **Data Explorer**. Find your leads instance in the dropdown menu. Learn about how to [View Your Data in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_your_data.htm&type=5&language=en_US) (Data Cloud Architect Permission Set).
The integration of Lead Capture from Meta into Sales Cloud and Data Cloud has been successfully established. This multi-step solution has streamlined the flow of leads, enabling leads captured in Meta to be sent to the Customer 360 Data Model. You now have a comprehensive lead management solution, combining the strengths of Sales Cloud and Data Cloud. The integrated system enables you to harness valuable lead data, identify actionable insights for event orchestration, create targeted ad network activation, and use data-driven lead scoring.
# Ingesting Consent Preferences
Ingest consent preferences from wherever you’re storing them using connectors. Common storage locations include data extensions (Marketing Cloud Engagement Connector), Sales or Service Cloud standard or custom objects (Salesforce CRM Connector), or external sources (Cloud Storage Connector).
We recommend that consent preferences be mapped to objects from the [Privacy Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_privacy_data_model.htm&type=5&language=en_US), but they can be mapped to custom objects as well.

Note When using the Engagement Connector, only subscribers with Active status are ingested into Data 360.
For example, Northern Trail Outfitters ingests an Engagement Data Extension that includes Communication Subscription Consent and Engagement Channel Type Consent. These objects allow Northern Trail Outfitters to determine which engagement channels and communication subscription topics they can use to contact their customers. When creating the Data Stream for this Data Extension, Northern Trail Outfitters maps the Consent Preferences object to Data Model Objects (DMOs) from the Privacy Data Model.

Tip Map the relevant contact point objects for your consent objects. For Northern Trail Outfitters, they mapped Contact Point Email since Communication Subscription Consent and Engagement Channel Type Consent both contain email data. Northern Trail Outfitters also mapped the Party Identification object to create the required relationship with the Individual object.
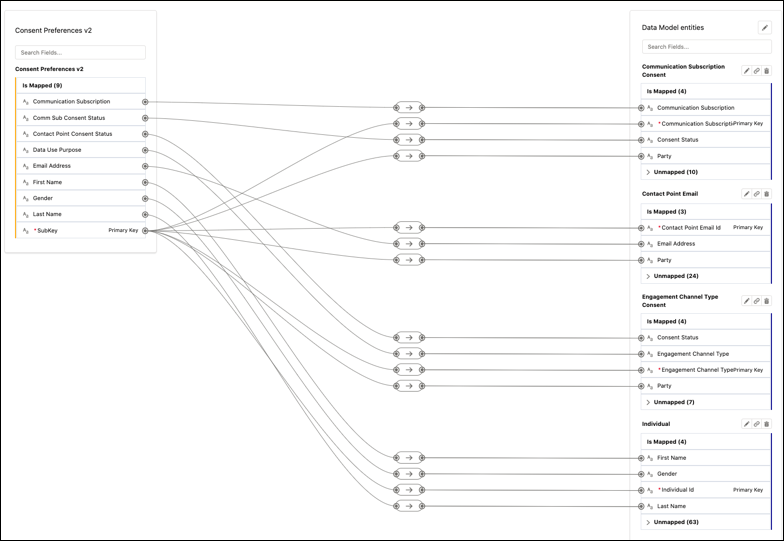
#### See Also
- [_Salesforce Help_: Marketing Cloud Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_cloud_data_sources.htm&release=264.0.0&type=5 "Connect Marketing Cloud Engagement to Data 360 using a starter data bundle or data extension.")
- [_Salesforce Help_: Salesforce CRM Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector.htm&release=264.0.0&type=5 "A standard Salesforce CRM connection establishes a connection between Data 360 and a Salesforce org, allowing Data 360 to ingest data from the connected org. Data 360 ingests data and sends back only data actions. This type of connection doesn’t share any data back to the connected org.")
- [_Salesforce Help_: Unify Individuals or Accounts Based on Party Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_partyidentifier.htm&release=264.0.0&type=5 "Party identifier refers to the exact match of the Identification Number, Identification Name, and Party Identification Type fields in the Party Identification object. This type of match is useful for matching unique identifiers, such as government ID, first-party cookies, external MDM systems, and vendor-specific IDs.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Inner Join
An inner join includes only matching rows from the left and right input data source objects. The join includes all matched rows in the output data when multiple rows match.

Example
Our company's marketing team captures demographic data in an external data source for opportunities stored in Salesforce. To compare opportunities by education level of the customer, let’s first combine both sets of data using an inner join.
To illustrate how this batch data transform function handles unmatched rows and duplicate keys, we included them in both input data sources.
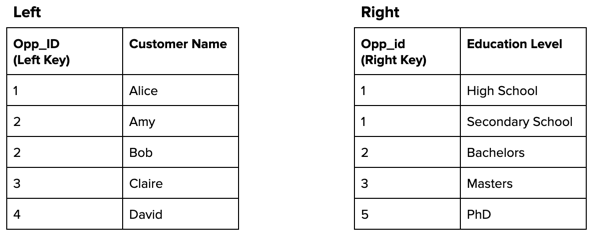
After performing the inner join based on the matching keys, the batch data transform produces the following output data.
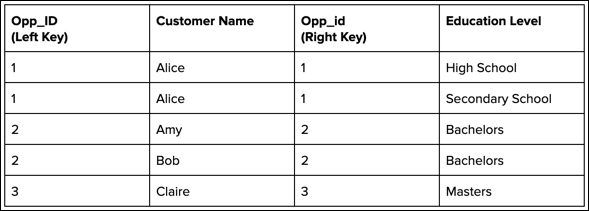
All rows that have a match are included in the output. Because of multiple matches, you see two records with `Opp_ID` 2 (Amy and Bob) and two records with `Opp_id` 1 (High School and Secondary School). Notice also that `Opp_ID` 4 and `Opp_id` 5 are excluded from the target because neither have a match.
# Input and Output Nodes: Add Data and Write to a Batch Data Transform
Add data to a batch data transform with an input node. To save batch data transform output, write your data to one or more output nodes. Input and output nodes can be either data lake objects or data model objects of type Profile or Other. You can’t have a data lake object input node and a data model object output node, and vice versa. Typically data aware specialists and engineers have access to data lake objects and data model objects, whereas marketers and analysts have access only to data model objects.
- **[Add an Input Node to a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_input_node.htm&release=264.0.0&type=5)**
Create an input node for each set of data that you want to add to the batch data transform. The batch data transform creates an input node when you initially select your input data, but to add more data you add another node.
- **[Write the Batch Data Transform Results to a Data Lake Object Output Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_output_node_dlo.htm&release=264.0.0&type=5)**
To use your batch data transform as input to identity resolution, calculated insights, or segmentation, you write the results to a new or existing data lake object (DLO) in an output node. The object that holds the output is called a target data lake object. You can’t save a batch data transform without an output node.
- **[Write the Batch Data Transform Results to a Data Model Object Output Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_output_node_dmo.htm&release=264.0.0&type=5)**
Write the results of a batch data transform to an existing data model object or one created through the output node. The object that holds the output is called a transform data model object. You can only write to a transform type data model object within a data transform. You can use a transform type data model object as input to another batch data transform and downstream processes such as identity resolution, calculated insights, and segmentation.
- **[Merge Records with Multi-Definition Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_multidefinition_merge.htm&release=264.0.0&type=5)**
A transform definition specifies the sequence of operations applied to the data during a batch data transform. Definitions appear as nodes in the data flow canvas. You can combine multiple definitions to produce a single, unified output.
- **[Data Preview Sampling](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_data_sampling.htm&release=264.0.0&type=5)**
Use data preview sampling to see a more accurate picture of your data at each node in Preview. By widening the sample size and selecting the mode to arrange your data, data sampling helps prevent working without preview data. Select **Filtered Rows** to isolate specific values.
# Insights List View
After creating a calculated insight in Data 360, see the details and edit your record from the Calculated Insights list view. The status, last run time, last run status, and schedule fields are updated in near-real time.
Use the dropdown arrow next to the calculated insight to change its content or status.
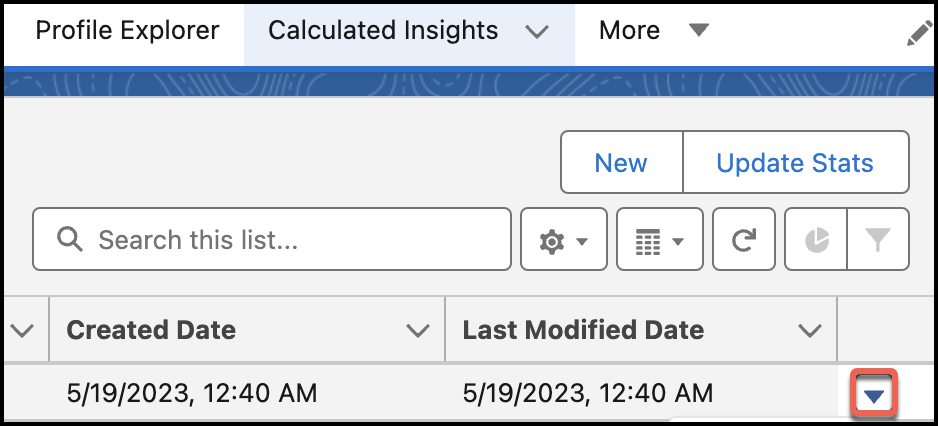
Function
Purpose
Edit
Change the calculated insight name and field names.
Clone
Duplicate and edit the SQL function from this record.
Enable/Disable
Turn processing on or off for a calculated insight.
Show in Builder
View calculated insight logic in the builder. Available only for calculated
insights created with the builder.
Delete
Permanently remove a calculated insight and its connections.
Update Stats
Update the status, last run time, last run status, and last modified date of the
selected calculated insight.
Publish Now
Run a calculated insight immediately instead of processing it as a batch
schedule.
Track History
Captures data at a specific time and appends the calculated insight
object values to the history tracking object.
Schedule
Modify the processing schedule of a calculated insight.
# Install Standard Data Bundles Powered by Data Kits
After you create your Data 360 instance and set up your Salesforce CRM connection, you can install standard data bundles that are powered by data kits to deploy data within Data 360.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set

Note In Standard Data Bundles, the data kits that back the standard data bundles are available based on your current licensing and products you use within Salesforce. The data kits that power the Service Cloud and Sales Cloud are available if you’ve set up your Salesforce CRM.

Note The Installed Version is the version currently installed. The Latest Version is the most current version of the standard data bundle.
1. Go to **Data Cloud Setup**.
2. Under Salesforce Integrations, select **Salesforce CRM**.
3. In the list of Standard Data Bundles, click  for the desired bundle, and select **Install**.
4. In the Package Install flow, follow the standard process for installing a data kit.
To uninstall a standard data bundle, click  for the desired bundle, and select **Uninstall**. Then, follow the standard uninstall process for a data kit.
#### See Also
- [_Salesforce Help_: Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_data_package_kits.htm&release=264.0.0&type=5 "Use a data kit in Data 360 to streamline package creation and installation. You can manage all packageable Data 360 features in the data kit. You can create data stream bundles and also include data model customization and relationships.")
# Integrating Data 360 Data Actions with Flow
Data 360 data actions can send streaming events and insights to Salesforce Flow to drive an orchestration. An orchestration uses stages, steps, and decisions to organize complex business processes.
Before you integrate data actions with flow, review the tasks you must complete.
- **[Create a Custom Object in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_custom_object_in_customer_data_platform.htm&release=264.0.0&type=5)**
Create a custom object to integrate data actions with a flow. Custom objects store information that’s specific to your company or industry. It helps you track everything related to your business in one place.
- **[Create a Platform Event-Triggered Flow](https://help.salesforce.com/s/articleView?id=data.c360_a_build_a_flow_in_customer_data_platform.htm&release=264.0.0&type=5)**
Automate your business process and launch a flow internally when a data record changes. A flow collects data and performs actions in Salesforce or an external system.
# Intelligent Context in Data 360
Process unstructured or structured data and create search index configurations tailored to specific business contexts by interacting with prompts in the Intelligent Context workspace.
Before you create a full search index, test your configuration on a small set of unstructured data. To start, add a few supported files or a data model object (DMO) in the Intelligent Context workspace. Respond to prompts to evaluate how the system processes your unstructured data and verify that you receive your expected results. Intelligent Context automatically saves your configuration, which then appears in the list.
After testing your configuration, apply it to an unstructured data model object (UDMO) or a DMO to create a precise, relevant search index.
Key benefits include:
- **Improved search accuracy:** Give your teams and users quick access to accurate information by using LLM-powered content understanding, domain-specific intelligence, and user feedback loops.
- **Support for multiple file types:** Upload a wide variety of file types, including DOCX, HTML, JPEG, JPG, PDF, PNG, PPTX, and TXT.
- **Structured data support:** Select a data model object (DMO) as a source to build a precise search index directly from structured data, with no manual file exports required.
- **Customizable views:** Gain multiple business perspectives from a single document. Design each lens to prioritize information critical to specific business functions so your teams can access relevant details without mining raw data.
- **Low-code setup:** Use an intuitive interface to convert unstructured data into consumable search indexes without extensive technical expertise.
- **Efficient problem resolution:** Diagnose and resolve common issues immediately, such as malformed tables in search results.
- **Harmonized citations:** Harmonize your source content into a single, consistent schema to provide a uniform, renderable view across all source documents.
## Intelligent Context Requirements
- **Enable Agentforce:** Intelligent Context requires generative AI features available through Agentforce. If you haven't already, [turn on Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5).
- **Turn On Einstein Generative AI:** To use the generative AI features in Intelligent Context, you must [turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) in Data 360.
## How to Use Intelligent Context
- **Validate content end-to-end:** Before you use content in production systems, upload sample documents or select a DMO to verify that the search index locates critical information.
- **Customize prompts:** Fix extraction issues, such as a malformed table, by adding simple prompts without rebuilding the entire search index. For example, "Extract the drivetrain table as markdown".
- **Metadata-driven refinement:** Use SI Optimization to prepend metadata to generated chunks and apply pre-filter conditions, so searches return more precisely labeled, relevant results.
- **Deploy from test to production:** Validate search quality on sample files, and then scale to thousands of documents by applying configurations to unstructured data model objects (UDMOs) or data model objects (DMOs).
## Example: Adapting a Product Specification Document
Review how different teams can create distinct lenses to analyze a single product specification document.
- **Sales lens:** Automatically extract information valuable to sales professionals, such as competitive advantages, pricing structures, and customer value propositions. This setup enables sales teams to identify and articulate product benefits quickly.
- **Service lens:** Emphasize critical details for service and support teams, including support prerequisites, troubleshooting steps, and maintenance guidelines. This setup provides service teams with immediate access to information needed to resolve customer issues.
- **[Create an Intelligent Context Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_intelligent_context_create_configuration.htm&release=264.0.0&type=5)**
Creating an Intelligent Context configuration includes these key steps: uploading sample documents for evaluation, configuring the Intelligent Context configuration, testing the results, iterating on the configuration, and publishing to a search index.
- **[Billing Considerations for Intelligent Context](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_intelligent_context.htm&release=264.0.0&type=5)**
Use of Intelligent Context impacts the consumption of credits in these usage types.
# IP Addresses Used by Data 360 Services
Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.
## AWS ID IP Table
SF Region Name
AWS Region
VPCE ID
Source IP Addresses
prod1
us-east-1
CDP1: vpce-0312582e73eb4b67b
"52.70.135.185/32", "52.22.251.194/32", "18.211.105.61/32", "54.224.187.8/32",
"52.6.67.129/32", "52.21.246.29/32"
CDP2: vpce-0748e87deb882f074
"54.204.177.212/32", "35.153.189.123/32", "54.82.22.132/32", "54.87.94.242/32",
"52.200.70.195/32", "3.223.146.214/32"
CDP3: vpce-047a313aba68ad369
"35.172.101.255/32", "54.163.7.205/32", "100.24.85.239/32", "54.84.139.2/32",
"3.221.222.84/32", "18.233.68.195/32"
CDP5: vpce-03f044667b67d9c9a
"100.24.192.103/32", "35.169.43.43/32", "54.243.39.10/32", "54.157.109.255/32",
"54.83.133.32/32", "44.219.151.101/32"
prod5
us-west-2
CDP1: vpce-056a2a3ccf7143acb
"44.225.11.146/32", "44.232.104.84/32", "54.69.137.103/32", "44.233.252.31/32",
"44.224.244.187/32", "52.33.255.186/32"
CDP2: vpce-0ad88d6ef08b06837
"35.166.9.73/32", "44.228.248.228/32", "54.68.145.82/32", "54.184.44.221/32",
"44.226.118.211/32", "44.241.14.16/32"
CDP3: vpce-03b561c3cf0c6049b
"44.232.239.151/32", "54.212.160.61/32", "54.71.251.107/32",
"35.82.255.247/32", "44.230.197.227/32", "54.200.73.135/32"
prod3
eu-central-1
CDP1: vpce-033226ebed78c238f
"18.156.144.84/32”, "18.159.12.44/32”, “35.156.54.210/32”, "18.156.161.183/32”,
"18.192.111.185/32”, "35.157.176.56/32"
CDP2: vpce-0da1389b13cad1a4f
“18.193.163.242/32”, “3.126.68.114/32”, “35.158.17.154/32”, “18.198.246.75/32”,
“18.198.9.100/32”, “3.64.2.81/32”
prod2
ap-south-1
CDP1: vpce-09103c53849a185a3
"3.111.113.154/32", "65.1.196.147/32", "65.2.105.153/32", "35.154.249.170/32",
"13.127.149.148/32", "3.109.251.157/32"
CDP2: vpce-024f40fe5e273871b
"13.234.104.135/32", "13.234.164.77/32", "13.234.85.198/32",
"15.207.149.137/32", "52.66.167.97/32", "13.126.189.23/32"
prod9
ap-northeast-1
CDP1: vpce-0426216047d48b939
"35.72.221.86/32", "52.193.83.32/32", "54.248.72.59/32", "54.92.26.48/32",
"52.194.176.7/32", "54.168.58.124/32"
CDP2: vpce-0d74d6da45b384786
"13.112.168.102/32", "13.230.112.45/32", "54.248.14.219/32",
"35.73.181.174/32", "13.112.182.207/32", "18.178.180.96/32"
prod4
ap-southeast-2
CDP1: vpce-004234b90404b66eb
"13.55.154.125/32", "3.24.206.174/32", "52.64.191.101/32", "3.24.254.23/32",
"54.252.73.57/32", "13.211.223.109/32"
CDP2: vpce-0464e1a50a65685a0
"13.237.255.187/32", "13.54.109.116/32", "13.55.180.195/32", "54.66.113.26/32",
"13.210.166.78/32", "54.79.200.32/32"
prod8
ca-central-1
CDP1: vpce-0d063ad77445a3a69
"3.97.88.239/32", "3.98.246.168/32", "15.223.138.191/32", "3.99.254.231/32",
"35.182.152.164/32", "52.60.48.144/32"
CDP2: vpce-007faa5b049bbeb5b
"3.98.111.171/32", "3.97.239.71/32", "99.79.178.202/32", "3.98.79.254/32",
"15.223.107.129/32", "52.60.81.101/32"
prod13
eu-west-2
CDP1: vpce-0d708a02de6fa5b2d
"13.41.242.95/32", "18.170.151.236/32", "18.171.92.28/32", "35.179.51.230/32",
"18.168.17.99/32", "18.132.115.229/32"
CDP2: vpce-01a1362b7daa162be
“18.133.93.17/32”, “35.178.241.5/32”, “18.135.137.69/32”, “18.135.71.27/32”,
“18.169.77.164/32”, “3.11.220.18/32”
prod11
sa-east-1
CDP1: vpce-011b1c1d5e6f91e3b
"54.207.61.209/32", "54.232.75.170/32", "18.231.32.111/32",
"18.229.189.163/32", "52.67.115.33/32", "54.233.246.197/32"
CDP2: vpce-09acbfb320b0da368
"52.67.8.154/32", "54.94.202.204/32", "54.94.15.104/32", "18.231.84.132/32",
"54.207.21.255/32", "52.67.77.221/32"
prod21
us-east-2
CDP1: vpce-00f23829cd936ad5b
"18.216.4.46/32", "18.220.191.28/32", "3.132.156.116/32", "3.138.48.97/32",
"18.117.44.67/32", "13.59.6.141/32"
CDP2: vpce-0d8d83db8b7effe00
"52.15.242.74/32", "52.14.190.51/32", "3.147.169.136/32", "3.20.62.47/32",
"13.59.240.150/32", "3.142.20.224/32"
CDP3: vpce-0ae3d5f1f4c0dc956
"18.119.148.43/32", "3.16.85.131/32", "3.13.4.205/32", "3.22.146.240/32",
"3.141.233.173/32", "18.219.220.102/32"
prod15
eu-central-2
CDP1: vpce-0f8eade2950c7585f
"16.63.105.170/32", "16.63.169.183/32", "16.63.173.8/32", "16.63.135.208/32",
"16.63.193.172/32", "16.63.200.120/32"
CDP2: vpce-022673bc0a09d2527
"16.62.222.12/32", "16.63.16.206/32", "16.63.60.209/32", "16.63.184.251/32",
"16.63.184.86/32", "16.63.76.116/32"
prod10
ap-southeast-1
CDP1: vpce-07a591d60c5672f70
"52.220.67.237/32", "18.138.47.180/32", "52.77.202.253/32", "54.251.46.51/32",
"3.1.15.15/32", "13.251.20.141/32"
prod17
ap-southeast-3
CDP1: vpce-0df38226baab5d4e4
"16.78.137.73/32", "43.218.197.105/32", "43.218.153.56/32", "108.137.125.35/32",
"108.137.200.186/32", "43.218.59.36/32"
prod12
eu-west-3
CDP1: vpce-0284e2bc02c8e823d
"15.188.36.125/32", "13.39.133.74/32", "13.36.226.140/32", "13.37.136.122/32",
"13.37.147.46/32", "15.188.224.204/32"
prod14
ap-northeast-2
CDP1: vpce-09d2d453ff8a0adf4
"52.79.255.184/32", "3.39.110.221/32", "43.203.12.250/32", "13.209.220.34/32",
"43.203.101.209/32", "52.79.42.147/32"
prod18
me-central-1
CDP1: vpce-0f5cb8ee17329aba4
"3.28.77.18/32", "51.112.147.80/32", "51.112.94.214/32”, “3.28.28.236/32",
"51.112.2.2/32", "51.112.80.9/32"
prod16
eu-north-1
CDP1: vpce-0d2089f31b74a26c2
"51.21.57.127/32", "51.21.34.147/32", "16.170.44.234/32", "13.60.100.199/32",
"13.49.181.214/32", "13.60.108.238/32"
CDP2: vpce-0e957e1db3d219b32
"13.53.233.128/32", "13.50.212.238/32", "51.21.93.98/32", "16.170.89.177/32",
"13.48.233.18/32", "13.50.163.96/32"
prod19
eu-south-1
CDP1: vpce-0cb4f543aae044fb5
"15.161.23.10/32", "18.102.186.218/32", "15.160.45.178/32", "18.102.170.15/32",
"18.102.109.72/32", "18.102.136.31/32"
prod20
il-central-1
CDP1: vpce-02cdca13959122540
"51.16.224.90/32", "51.84.22.190/32", "51.84.31.163/32", "51.17.96.144/32",
"51.16.211.246/32", "51.17.198.202/32"
prod22
ap-northeast-3
CDP1: vpce-0f33b62c35ba12755
"15.168.83.81/32", "15.168.226.127/32", "15.168.127.192/32", "15.152.194.57/32",
"15.168.124.39/32", "15.152.244.176/32"
prod24
ap-south-2
CDP1: vpce-0cb7a9496a22bce53
"18.60.213.9/32", "98.130.90.217/32", "98.130.83.123/32", "18.61.49.74/32",
"18.60.13.89/32", "18.61.147.74/32"
prod27
us-east-1
CDP1: vpce-0929f0f60fea7cc5e
"54.172.26.41/32", "44.193.95.183/32", "3.219.57.44/32", "98.95.189.46/32",
"52.71.84.153/32", "50.17.26.184/32"
prod26
af-south-1
CDP1: vpce-0045da3e7746b9c21
"145.224.193.0/24","145.224.217.0/24"
prod28
us-west-2
CDP1: vpce-0e744691f622a0eb5
"155.226.128.0/21", "155.226.151.0/24"

Tip Remove the special character double quotes "" enclosing the IP addresses when you add them to your allowlist.
You can use a VPC endpoint instead of IP source addresses when securing the customer S3 Bucket shared with Data 360. Using an endpoint is a better solution because an IP address can change or be altered over time. The customer bucket must be in the same region as the VPC Endpoint for access to work. When the bucket can't be in the same region you can use the IP addresses to limit access to the customer bucket. To determine your region, see [Where is my Salesforce instance located?](https://help.salesforce.com/s/articleView?id=000396845&type=1&language=en_US).

Note If the customer bucket is in the same region as the Data 360 instance, Data 360 always uses a VPC endpoint to access the S3 bucket to keep the traffic private. Specifying IP source addresses doesn’t work and interferes with VPC endpoint ingestion.
# Is This Data Foundation Solution Kit Right for My Organization?
You can establish a data foundation in Marketing Cloud Engagement in multiple ways. Each customer implementation is unique and has different factors to consider. Use this grid to help guide your decision on which data foundation pattern makes sense for your organization. Your needs might require a hybrid approach and a combination of aspects from multiple patterns.
This solution kit describes only how to use Data 360 as the primary data foundation within Marketing Cloud Engagement.
Considerations
Data 360 Marketing
Cloud Engagement Data Foundation Other Marketing Cloud Engagement Data
Foundations
Implementation Strategy Overview
Use Data 360 to activate core audiences to Marketing Cloud
Engagement, and then connect the resulting data extensions to the Engagement
Contact Model.
Core data extensions contain commonly used attributes that can be used for
content personalization and decisioning across many different Journey Builder use
cases.
To activate core audiences to Marketing Cloud Engagement, use Synchronized Data
Sources, your own external systems, or third-party tools. Then connect the
resulting data extensions to the Engagement Contact Model.
Core data extensions contain commonly used attributes that can be used for
content personalization and decisioning across many different Journey Builder use
cases.
Implementation Pattern Overview
Core Audience Model
Use Data 360 to
activate two core data extensions containing your full audience and all required
attributes. One data extension is for Individuals, and the other is for Unified
Individuals. Then connect these core data extensions to the Engagement Contact
Model.
Collective Core Audience Model
Use Data 360 to activate multiple core data extensions containing your
full audience and all required attributes. Create multiple data extensions for
Individuals, and one or more for Unified Individuals. Then connect the multiple core
data extensions to the Engagement Contact Model.
Synchronized Data Sources
Use
Marketing Cloud Connect
to establish a data foundation by syncing CRM contact and attribute data directly
from Salesforce CRM and into the Engagement Contact Model. Then separately use CRM
data in Data 360 for detailed insights, segmentation, and
retargeting.
External Systems
Use your own external systems or
third-party tools to establish a data foundation by building core data extensions
and connecting them to the Engagement Contact Model. Then separately use data in Data 360 for detailed insights, segmentation, and retargeting.
Customer Traits and Considerations
Your organization:
Wants to remove or minimize existing processes for importing data directly to
Marketing Cloud Engagement
Is confidently able to import and harmonize required data within Data 360
Understands that the data foundation refreshes from Data 360
to Marketing Cloud Engagement occur every 12+ hours
Has organizational experience with customer data platforms
Doesn’t have or fully use Marketing Cloud Connect to sync CRM contacts into
Marketing Cloud Engagement
Your organization:
Uses Salesforce Sales, Service, or Industries Cloud products
Uses the Synchronized Data Sources feature
Creates Engagement contacts as Salesforce CRM contacts
Has an intentional CRM contacts strategy for anonymous messaging, such as
anonymous mobile app users, SMS subscribers who sign up by texting JOIN, or email
subscribers who register with only an email address
Wants to supplement but not replace this pattern with some attributes from Data 360 , such as Calculated Insights
Your organization;
Is in the early onboarding or implementation stages with Data 360
Has little expertise with Data 360
Has already successfully established a Marketing Cloud Engagement data
foundation using an external source
Is able to keep managing the external imports to Marketing Cloud Engagement in
near-term
Has imported core data extensions with foreign keys to join
Wants only to supplement this pattern with some attributes from Data 360 , such as Calculated Insights
Has near real-time latency needs for refreshing data in the Marketing Cloud
Engagement data foundation
Has internal strategies that require consent and preference data to be
directly imported into Marketing Cloud Engagement instead of or in addition to
Data 360
# Issues with Using Cyclic Paths in Segment Attributes
When you choose a DMO more than one time while selecting a related attribute, you create a cyclic path. Cyclic paths are relationships that use cyclic behavior (a→b→a). Cyclic paths degrade segment performance and can lead to count or publish failures. To avoid these issues, Data 360 prevents you from creating cyclic paths through Segment Builder by default.
Consider this example cyclic path where Email Engagement is used twice.
Here’s another example where the “Segment On” entity is used in related attributes. The path leads from Account (Segment On Entity) to Case, and then back to Account.

Note Data 360 retains previously created cyclic paths in your segments.

Note If specific situations require you to use a cyclic path, contact Support to enable cyclic paths in your org.
#### See Also
- [_Salesforce Help_: Troubleshoot Segment Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_troubleshooting.htm&release=264.0.0&type=5 "Get tips for solving the most common segment errors in Data 360.")
# ISV Ecosystem Activation Using the Activation Toolkit
The Data 360 Activation Toolkit allows Independent Software Vendors (ISV) to build activation platforms on AppExchange. These platforms let subscriber organizations install and use ISV activation services. It lets them to match Data 360 data with destination data payloads and use advanced features like multi-key matching, contact point filtering, and supporting additional DMOs in Activation Membership.
### Required Editions
Available in: Lightning Experience Available in: Developer , Enterprise and Unlimited Editions
The Activation Toolkit is a metadata-driven solution that streamlines activation in Data 360. It enables ISVs to onboard activation platforms that support grouping by segment and ID type to unlock additional attributes. It also allows business users to connect and map Data 360 data to specific schemas required by customer engagement platforms.
Key capabilities include:
- Onboarding destinations—ISVs upload destination metadata, which is packaged and distributed to customer orgs via Salesforce Package Manager.
- Creating activation targets and activations—the toolkit configures authentication, schema mapping, and activation workflows based on destination metadata.
- Flexible activation—supports batch activations, multi-key matching, attribute mapping from any DMO, and dynamic filtering for personalized experiences.
The toolkit lets marketing, sales, and data teams to activate both known and anonymous first-party data across external platforms. You can map attributes from any standard or custom data model object (DMO) in Data 360, optimizing campaign execution.
- **[Create an External Activation Platform Using JSON (ISV Partners)](https://help.salesforce.com/s/articleView?id=data.c360_a_external_activation_platform_json.htm&release=264.0.0&type=5)**
Build an external activation platform in Data 360 Developer Edition using the Activation Toolkit to engage your customers.
# Join Data in a Streaming Transform
Joins enable data augmentation by combining data from two separate streams based on a primary key. In streaming data transformations, \`INNER JOIN\` and \`LEFT JOIN\` clauses in SQL statements are used to combine data from two distinct streams. A join expression consists of two objects: one identifies the object that triggers the streaming transform on update, and the other specifies the object used to evaluate the join.
### Required Editions
User Permissions Needed
To edit a streaming transform
Permission set:
- The join condition must include the `ON` clause. The `ON` clause has the form `column = column`
- Each side of the `ON` clause can only reference one column from one side of the join, and the other side references the other side of the join.
- Columns used in the ON clause must have the same data type.
- Multiple joins can be combined using additional `INNER JOIN` or `LEFT JOIN` clauses. Up to 5 objects can be joined in one SQL statement.
- Any object that can be used as a source object in a streaming transform can be used in a join.
- The event time field column must be used for non-streaming ‘engagement’ inputs. All other joins must include a primary key from either object in the join.
1. Create a target DLO or DMO for the data of the joined records.
2. Create a new streaming transform by clicking New on the Data Transforms tab.
3. On the Target Data Lake Object or Target Data Model Object page, select the DLO or DMO you created.
4. In the Expression field, enter a SQL statement to define the join.
- Use `INNER JOIN` or `LEFT JOIN` to specify the tables to join.
- Use `ON` to specify the predicate that determines which records from each table should be matched and included in the final result set.
- Specify the columns that you want to include in the target DLO.
5. Click **Next**.
6. From the Review section, you can select a streaming source object if multiple streaming sources are available.
When new records are added to the chosen streaming source object, changes in the streaming transform source will cause the transform to run.
7. Click **Save**.

Example
This example demonstrates an inner join of two tables: a sessions table and a customer table. The sessions table logs every customer engagement event, recording the customer's ID and the timestamp of their page access. The customer table stores customer information such as age, gender, and ID. Joining this data allows for analysis such as determining the number of customers from a specific state who visited a page on a given date.
**Target DLO**
Create a new DLO by cloning the existing DLO for the sessions table. Include columns that are required for the join from the customers table.
**SQL Expression**
`SELECT sessions__dll.page_visited__c as page_visited__c, sessions__dll.sesson_id__c as session_id__c, sessions__dll.timestamp__c as timestamp__c, sessions__dll.user_id__c as user_id__c, customers_dll.age__c as age__c, ustomers_dll.state__c as state__c, customers_dll.customer_name__c as customer_name__c FROM session__dll INNER JOIN customer__dll ON customers__dll.customer_id__c = sessions__dll.user_id__c`
SQL
Description
FROM session__dll INNER JOIN customer__dllThe tables to join.
ON customers__dll.customer_id__c = sessions__dll.user_id__cThe condition from which the records are matched.
page_visited
session_id
timestamp
age
state
customer_name
The condition from which the records are matched.
**Results**
If `sessions__dll` is selected as the stream source object when saving the data stream, the transform is only triggered when new records are added to the `sessions__dll` streaming object. New `customer__dll` records don't trigger the streaming transform.
# Join Objects in a Batch Data Transform
On the batch data transform canvas, use a node to create a join between data objects. To make sure that data from multiple data objects is combined accurately and not duplicated, always add a key qualifier field to create a fully qualified key (FQK) in a join. To ensure that null values in a key qualifier field are matched correctly, use a null-safe join by replacing null values with null strings or empty strings.
All data lake object (DLO) fields used in the data transform table join must have an associated key qualifier. See [Data Interpretation with Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_data_inter_fqk.htm&type=5&language=en_US) and [Configure a Key Qualifier Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_or_view_key_qualifier.htm&type=5&language=en_US). Data 360 automatically adds key qualifiers to data model object (DMO) fields.
1. Between two input data sources or at the end of the batch data transform, click **Add Node** .
To show the Add Node button between two input data source objects, hover the cursor on the connecting line. To join an input source to itself, drag the Add Node button to it and select **Join**.
2. Select **Join**.
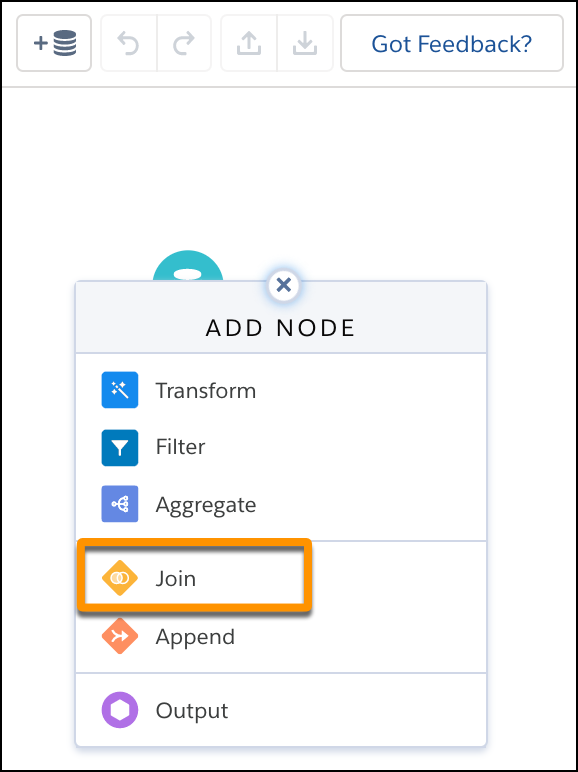
3. Select the data to join, choose which fields to include and click **Next**.
Currency fields on each side of a join must match. If no currency is selected, the left side of the join's currency is used. For right outer join's, the right side of currency is used.
4. Choose the join type.
The batch data transform adds suggested join keys from both sets of input data. To improve results, use up to five keys to match records. For example, when you’re adding contact information to lead data, using only names as a match can result in duplicate matches if different leads have the same name. Instead, use two keys—one to match on name and one for company—to ensure that you’re matching the correct data.
For better performance, use a primary key column as one of the keys in your join condition.
5. To create FQKs and ensure that the table join works correctly, under Join Keys, click the plus sign (+) and add key qualifier fields.
6. Apply your changes.
7. On the canvas, in a key qualifier field column on one side of the join, replace all null values with string values.
You can’t compare null values with each other. If a null value is present, the table join doesn’t work correctly.
1. Click **Add Node** and select **Transform**.
2. Under Columns, select a key qualifier field.
3. In the Transform toolbar, click the Replace icon.
4. Select **Search for null** (1), and in the Replace text box, enter \--NULL-- (2). Alternatively, enter an empty string (" ") or a value that doesn’t conflict with the value of an existing key qualifier field when compared to the other side of the join.
5. Apply your changes.
6. Repeat these steps for the other side of the join.
7. Preview your changes, and on both sides of the join, make sure that no null values appear in the key qualifier field column.
8. To prevent API name conflicts between fields in the left and right data sources, enter a prefix for fields coming from the data source on the right.
The join node prepends the API name prefix of all fields on the right. For example, if you specify Case as the prefix, all field API names on the right begin with “Case.”
9. On the Columns tab in the right panel, select the columns to include in the batch data transform.
The Source column shows the object that each column comes from.
10. To preview column data, click **Preview**.
To hide columns while in Preview, click the Hide button (). Hidden columns are still included in the data transform. To show columns, click the Show button (). Preview can display up to 100 columns.
11. Apply your changes, and save the batch data transform.
#### See Also
- [_Salesforce Help_: Lookup](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_lookup.htm&release=264.0.0&type=5 "A lookup returns all rows from the left input data source object and only matching rows from the right object, the lookup source. To ensure that the grain of the results doesn’t change, the lookup output data includes one row for each row in the left object.")
# Join Operations
Batch data transforms support these join operations.
- **[Lookup](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_lookup.htm&release=264.0.0&type=5)**
A lookup returns all rows from the left input data source object and only matching rows from the right object, the lookup source. To ensure that the grain of the results doesn’t change, the lookup output data includes one row for each row in the left object.
- **[Left Join](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_leftjoin.htm&release=264.0.0&type=5)**
Like a lookup, a left join includes all rows from the left input data source object and only matching rows from the right object. Unlike a lookup, a join includes all matched rows in the output data when multiple rows match.
- **[Right Join](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_rightjoin.htm&release=264.0.0&type=5)**
A right join includes all rows from the right and only matching rows from the left input data source objects. The join includes all matched rows in the data output when multiple rows match.
- **[Full Outer Join](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_outerjoin.htm&release=264.0.0&type=5)**
A full outer join includes all rows from the left and right input data source objects, regardless of whether they have matches. The join includes all matched rows in the output data when multiple rows match.
- **[Inner Join](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_innerjoin.htm&release=264.0.0&type=5)**
An inner join includes only matching rows from the left and right input data source objects. The join includes all matched rows in the output data when multiple rows match.
- **[Cross Join](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_crossjoin.htm&release=264.0.0&type=5)**
A cross join combines unrelated records and includes all rows from the left and the right input data source objects. Unlike other joins that use keys to find matches, the cross join pairs every row from one data source with every row of another data source.
- **[Considerations for Using Joins](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_considerations.htm&release=264.0.0&type=5)**
Unlike a lookup, a join creates a separate record for each match in the output data when multiple rows match. Before using a join, ensure that you understand the implications of duplicate rows.
# JSON Metadata Usage and Examples for External Activation Platforms
Here are the JSON examples followed by the field descriptions and best practices to help you define your external activation platform.
Sample JSON for Output Grouping by PER\_USER
`{ { "name": "abc-user-identifiers", "apiName": "abc_user_identifiers", "description": "Activation platform to activate only user identifiers", "platformType": "Advertising", "outputGrouping": "PER_USER", "refreshFrequency": "TWENTY_FOUR", "refreshMode": "FULL", "connector": { "connectorType": "S3", "bucketName": "example-uswest2-cdp001-sample-data", "exportDirectory": "datacloud-activations" }, "activationAttributes": [ { "displayName": "Hashed Email", "destinationName": "EmailAddress", "objectName": "ContactPointEmail", "fieldName": "Email", "isRequired": true, "applyHash": true, "isIdentifier": true }, { "displayName": "Hashed Phone", "destinationName": "PhoneNumber", "objectName": "ContactPointPhone", "fieldName": "E164FormattedPhoneNumber", "isRequired": true, "applyHash": true, "isIdentifier": true }, { "displayName": "Hashed Digital id value", "destinationName": "DigitalIdValue", "objectName": "ContactPointDigitalId", "fieldName": "DigitalIdValue", "isRequired": true, "applyHash": true, "isIdentifier": true } ], "fields": [ { "name": "AccountId", "helpText": "", "isRequired": true, "isHidden": false, "type": "Text" }, { "name": "AccountName", "helpText": "", "isRequired": false, "isHidden": true, "type": "Text", "values": [ { "isDefault": true, "value": "Name of your account" } ] } ], "activationPlatformCustomMetadata": { "connectorType": "S3", "accessKey": "DUMMY1234EXAMPLE5678KEY", "secretKey": "dUmMySeCrEtKeY12345EXAMPLE67890" }, "activationPlatformAdditionalMetadata": { "hashMethod": "SHA256", "outputProperties": { "outputFormat": "CSV", "compression": "GZIP", "maxFileSizeInMB": 128, "maxRecordsPerFile": 1000000, "minRecordsPerFile": 10000, "outputPartitions": 20, "delimiter": "COMMA" }, "partnerSupportedIds": [ { "destinationName": "DigitalIdValue", "supportedIdTypes": [ "Google", "Facebook", "Trade desk", "Instagram" ] } ], "subscriberOverrideOptions": {}, "supportCustomAttributes": false } }`
Sample JSON for Output Grouping by PER\_SEGMENT
`{ "name": "abc-segment", "apiName": "abc_segment", "description": "ActivationTest platform to activate user identifiers and additional match keys", "platformType": "Advertising", "outputGrouping": "PER_SEGMENT", "refreshMode": "FULL", "connector": { "connectorType": "S3", "bucketName": "example-uswest2-cdp001-sample-data", "exportDirectory": "datacloud-activations" }, "activationAttributes": [ { "displayName": "First Name", "destinationName": "fName", "objectName": "Individual", "fieldName": "FirstName", "isRequired": true, "applyHash": false, "isIdentifier": false }, { "displayName": "Last Name", "destinationName": "lname", "objectName": "Individual", "fieldName": "LastName", "isRequired": false, "applyHash": false, "isIdentifier": false }, { "displayName": "Hashed Digital id value", "destinationName": "DigitalIdValue", "objectName": "ContactPointDigitalId", "fieldName": "DigitalIdValue", "isRequired": true, "applyHash": true, "isIdentifier": true }, { "displayName": "Hashed Email", "destinationName": "EmailAddress", "objectName": "ContactPointEmail", "fieldName": "Email", "isRequired": false, "applyHash": true, "isIdentifier": true } ], "fields": [ { "name": "AccountId", "helpText": "", "isRequired": true, "isHidden": false, "type": "Text" }, { "name": "AccountName", "helpText": "", "isRequired": false, "isHidden": false, "type": "Text" } ], "activationPlatformCustomMetadata": { "connectorType": "S3", "accessKey": "DUMMY1234EXAMPLE5678KEY", "secretKey": "dUmMySeCrEtKeY12345EXAMPLE67890" }, "activationPlatformAdditionalMetadata": { "hashMethod": "SHA256", "outputProperties": { "outputFormat": "CSV", "compression": "GZIP", "maxFileSizeInMB": 128, "maxRecordsPerFile": 1000000, "minRecordsPerFile": 10000, "outputPartitions": 20, "delimiter": "COMMA" }, "partnerSupportedIds": [ { "destinationName": "DigitalIdValue", "supportedIdTypes": [ "Google", "Facebook", "Trade desk", "Instagram" ] } ], "subscriberOverrideOptions": {}, "supportCustomAttributes": false } }`
Field Name
Description
Required (Y/N)
Allowed Values
Sub Fields
Allowed Values
Sub Fields Description
Required (Y/N)
name
Name of the activation platform
Y
NA
NA
NA
NA
NA
apiName
Unique API name of the activation platform
Y
NA
NA
NA
NA
NA
description
A short description of the activation platform
Y
NA
NA
NA
NA
NA
platformType
Specifies the type of activation platform
Y
Advertising
Publishing
Analytics
Marketing
Technology
NA
NA
NA
NA
logoUrl
The URL of the Activation Platform logo
N
NA
NA
NA
NA
NA
outputGrouping
Specifies how the activation payload output is delivered to the partner. Output
grouping by segment groups all attributes within a segment into a single file, while
output grouping by user identifier activates each user identifier in a separate
file, such as CSV. This field can't be modified during the edit workflow.
Y
PER_SEGMENT
PER_USER
NA
NA
NA
NA
refreshMode
Refresh mode for the activation platform. For "outputGrouping":
"PER_USER" only Full is supported.
Y
INCREMENTAL
FULL
NA
NA
NA
NA
refreshFrequency
Refresh frequency for the activation platform. Applicable only when
"outputGrouping": "PER_USER" is true
Y
TWENTY_FOUR
NA
NA
NA
NA
periodicFullRefresh
Indicates how often you want to schedule a full refresh for Incremental
Refresh. Applicable only when "outputGrouping": "PER_SEGMENT" is
true and refresh mode is incremental.
Y
REFRESH_30
REFRESH_60
NA
NA
NA
NA
connector
Amazon S3 Connector details
Y
NA
"connectorType"
"bucketName"
"exportDirectory"
NA
exportDirectory: The folder path where the data is exported.Y
activationPlatformCustom Metadata
Contains the connector credential details.
Y
NA
"connectorType"
"accessKey"
"accessSecret"
NA
NA
Y
fields
An array containing details of the activation target fields. Add
at least one field (for example, Account ID). You can add a maximum of five
fields.
Y
NA
"name"
NA
The name of the field to be displayed in the activation target.
Y
NA
"helpText"
NA
A short descriptive text providing guidance for the field in the activation
target.
N
NA
"isRequired"
true
false
Indicates whether the field is required. A required field can't be hidden, and
vice versa.
Y
NA
"isHidden"
true
false
A required field can't be hidden, and vice versa. Hidden fields must always
have a default value.
Y
NA
"type"
NA
The data type defined by the user based on the field requirement.
N
NA
"values"
"isDefault"
"value"
NA
This is optional unless "isHidden": true, in which case, you
must set "isDefault": true and provide a default value as shown in
the example. Hidden fields must always have a default value.
N
activationAttributes
The attributes array contains all attributes that you allow your
customers to map, including details on required and optional attributes. After
defining an attribute, it can’t be removed during edit flow.
Y
NA
"objectName"
NA
This is used as a hint for customers and it refers to the data model object
(DMO) name . This helps customers map destination fields to Data 360 DMO
attributes during activation mapping. For the ContactPointDigitalId
DMO, the object name must be "ContactPointDigitalId".
N (Read further for specific conditions where this field is required.)
NA
"fieldName"
NA
This is used as a hint for customers and it refers to the attribute
name in the DMO for the corresponding destination field. This helps customers map
destination fields to Data 360 DMO attributes during the activation mapping
process.
N
NA
"displayName"
NA
The user-friendly name for the corresponding
destinationName , which is displayed on the right side of the
activation mapping interface.
Y
NA
"destinationName"
NA
Refers to the destination schema field name. This
destinationName is used as the column header in the exported
file (for example, CSV) when the output is grouped by segment. When the output is
grouped by a user identifier, destinationName is used as the
name of the folder that’s created automatically for each user identifier. This field
can’t be Id, ID, or id for any of the activation attributes. This field value is
displayed as thePreferred Attribute Namein the Contact Point
filtering page.
Y
NA
"isRequired"
true
false
Indicates whether this attribute is a required field.
Y
NA
"isIdentifier"
true
false
Indicates whether this attribute is used as a user identifier.
Y
NA
"applyHash"
true
false
Indicates whether the attribute value should be hashed during Activation. It is
recommended to set this flag to "true" for user identifier fields, unless partners
prefer to retain the original values without hashing.
Y
activationPlatformAdditional Metadata
This object contains additional metadata that partners can
configure as needed.
NA
NA
"hashMethod"
"SHA256"
NA
Required if any field is set to "applyHash": true
NA
“outputProperties"
"outputFormat"
CSV
JSON
PARQUET
NA
Y
NA
"compression"
GZIP
BZIP2
NONE
NA
Y
NA
"maxFileSizeInMB"
Defaults to 128 MB if not configured
Make sure that no file exceeds the specified file size. Recommended to not
exceed 512 MB.
N
NA
"maxRecordsPerFile"
Defaults to 1 million records per file if not configured
Make sure that no file contains more than the specified number of records.
Recommended to not exceed 5 million.
N
NA
"minRecordsPerFile"
Min -1
The minimum number of records that must be present in a file.
N
NA
"outputPartitions”
Min -1
Controls the number of files created in the output payload.
N
NA
"delimiter”
COMMA
SEMICOLON
TAB
PIPE
COLON
TILDE
CARET
HASH
UNDERSCORE
BROKEN_PIPE
SLASH
NA
Required if the output format is CSV
NA
"partnerSupportedIds"
NA
NA
Required if ContactPointDigitalId is used
as objectName in activationAttributes
NA
"destinationName"
NA
The field name on the destination schema which accepts Digital identifiers.
Once defined, this can’t be changed during edit flow.
NA
"supportedIdTypes"
NA
The digital identifier types supported by the partner (for example, Google,
Meta, Instagram).
Required if ContactPointDigitalId is used as objectName
in activationAttributes
## Guidelines to Prevent JSON Validation Errors
- The apiName value can't contain spaces.
- When outputGrouping is set to `PER_USER`, make sure that all the activation attributes are configured as identifiers by setting isIdentifier to true.
- When outputGrouping is set to `PER_SEGMENT`, make sure that at least one attribute is an identifier by setting isIdentifier to true.
- Specify the hash method as "hashMethod": "SHA256" in activationPlatformAdditionalMetadata when atleast one attribute is set to “applyHash” : true.
- The array of fields in the activation target must contain at least one entry, but can’t exceed five entries. AccountId is a required field. Use the field "name": "AccountId" as provided in the sample JSON. Don’t update or remove this field.
- If you’re including ContactPointDigitalId as objectName in the attributes list, provide the "PartnerSupportedIds" object in the activationPlatformAdditionalMetadata. Make sure that the destinationName for ContactPointDigitalId matches the destinationName specified in “partnerSupportedIds.” Don’t use Id, ID, or id as the destinationName for any of the activation attributes.
- If the destinationName of an activationAttribute matches the destinationName of partnerSupportedIds, specify the objectName for such an activationAttribute as "objectName": "ContactPointDigitalId".
- If partnerSupportedIds is defined, specify the supportedIdTypes, and don't enter null for the destinationName field.
- At least one supportedIdTypes must be retained when updating the JSON.

Important After creating the package and setting up the activation platform, don't update the JSON to change `outputGrouping`, `destinationName`, or remove activation attributes or `supportedIdTypes`. These changes could impact existing customers who have already set up activations using these configurations.
## Best Practices and Recommendations
- For email data normalization to work, set the preferred destinationName for email to EmailAddress(case-sensitive).
- Set "applyHash" : true at each attribute level if you want to hash the user identifier values for attributes such as email and phone.
- After activation, certain folders are automatically created in the Amazon S3 bucket with the preferred destinationName. However, when the Contact Point Digital Id DMO is used, the values specified by the ISV partner in the supportedIdTypes field are used as folder names.
- For optimal performance, it's recommended not to exceed 512 MB for maxFileSizeInMB. If this optional field isn't configured, it defaults to 128 MB.
- It's recommended to not exceed 5,000,000 maxRecordsPerFile. If this optional field isn't configured, the system defaults to 1,000,000 records.
- Including maxFileSizeInMB and maxRecordsPerFile values make sure that each output file stays within the specified size and record count limits.
- Make sure that minRecordsPerFile is less than or equal to maxRecordsPerFile, if configured.
- The outputPartitions controls the number of files generated in the output location per activation run. When output is grouped by segment, the outputPartitions defined in the JSON is applied per segment publish, which is considered an activation run. See [Find External Activation Platform Segments in Cloud File Storage](https://help.salesforce.com/s/articleView?id=data.c360_a_package_external_activation_platform_find_metadata.htm&release=264.0.0&type=5 "After admins install your external activation platform, you can receive segments to Cloud File Storage (Amazon S3). For each activation target, you receive a success file, metadata file, and activation output files once a day for each identifier type when the output is grouped by user identifiers (PER_USER). Because files arrive only once a day, there’s a delay between Data 360 customers updating segments and those changes arriving to S3.") for more information.
- When the platform output is grouped per user identifier, then the 24-hour refresh frequency is considered as an activation run for each activation target created by the customer. See [Find External Activation Platform Segments in Cloud File Storage](https://help.salesforce.com/s/articleView?id=data.c360_a_package_external_activation_platform_find_metadata.htm&release=264.0.0&type=5 "After admins install your external activation platform, you can receive segments to Cloud File Storage (Amazon S3). For each activation target, you receive a success file, metadata file, and activation output files once a day for each identifier type when the output is grouped by user identifiers (PER_USER). Because files arrive only once a day, there’s a delay between Data 360 customers updating segments and those changes arriving to S3.") for more information.
- outputPartitions and minRecordsPerFile determine how data is divided into partitions. If outputPartitions is set, it takes precedence. Otherwise, partitions are calculated based on minRecordsPerFile and the total number of records in all the output files. If the outputPartitions field isn't configured, the total record count is divided by minRecordsPerFile value to calculate the number of partitions.
- In the PartnerSupportedIds section, include under supportedIdTypes only those attributes that are mapped to ContactPointDigitalId in the activationAttributes section. For example, exclude email and phone attributes from supportedIdTypes if they aren’t mapped to ContactPointDigitalId.

Note When the exportDirectory is set to `"exportDirectory": "/"`, activation files are uploaded to the root directory of the specified S3 bucket. A date-based folder structure is automatically created and maintained to organize the exported files.
# Keep DMO Mappings When Deploying Data Transforms via Data Kits
When you deploy a Data Transform using a Data Kit, the mappings between Output Data Lake Objects (DLOs) and Data Model Objects (DMOs) aren't automatically included. To carry over these mappings, explicitly add the Output DLOs to the Data Kit.
Including a [Data Transform in a Data Kit packages](https://help.salesforce.com/s/articleView?id=data.c360_deploy_data_kit_components.htm&type=5&language=en_US) its SQL logic and input and output parameters. However, the mappings between Output DLOs and DMOs function as independent dependencies. Deploying only the Data Transform component results in a successful deployment where the DLOs may remain unmapped. To ensure the Output DLO-to-DMO mappings are carried over during deployment, the Output DLOs themselves must be explicitly added to the Data Kit configuration.
1. Navigate to the Data Kits tab and open your kit.
2. Add the Data Transform.
3. Add Output DLOs.
1. Navigate to the Data Lake Objects section of the Data Kit.
2. Click **Add**.
3. Manually select and include all Output DLOs generated by your Data Transform.
By explicitly adding the Output DLOs, the Data Kit dependency engine recognizes and bundles the DLO-to-DMO mapping metadata. When this Data Kit is deployed to the target org, the Data Transform arrives with all its downstream mappings fully intact and ready for use.
# Key Concepts for Predictive AI
Learn key concepts for working with predictive models in AI solutions.
### Required Editions
## Predictive Models
A predictive model is a custom statistical tool that predicts future business outcomes based on trends and patterns in past results, plus current business data. The model’s equation is the result of a thorough statistical analysis of past data with known outcomes, powered by machine learning and AI. Predictive models are used extensively around the world—across industries, organizations, disciplines—and they’re involved in so many aspects of everyday life. Businesses use predictive models to integrate data-driven decision making throughout all levels and functions of their organization.
## Predictions
A prediction is a derived value, produced by a predictive model, that represents a possible future business outcome. An outcome is the business result you’re trying to understand and improve. An outcome is typically a key performance indicator (KPI), such as sales margin or opportunity wins. A prediction represents an output value that the model generates based on the provided input values (predictors).
Although the future is unknown and uncertain, a prediction can reduce that uncertainty by providing a value that falls within a calculated range of probability. When it does occur, the actual outcome can differ from the predicted outcome. This is expected. We measure the accuracy of the prediction by how small or large this difference is.
## Top Predictors
Top predictors are the conditions that most significantly drive the predicted outcome. If requested, top predictors are returned from a predictive model in decreasing order of magnitude. A condition is a data value associated with a column. Predictors are also known as predictor variables or independent variables.
## Prescriptions
A prescription is a suggested action that a user can take to improve the predicted outcome. The prescription affects the predicted outcome, not necessarily the actual one. Prescriptions are associated with variables over which users have some discretionary control or influence, such as the shipping method or a subscriber’s membership level. By enacting Einstein's suggestions, users can increase their chances of a more favorable outcome.
## Predictive Models at Run Time
A predictive model organizes data by variables and records. A variable is a category of data, such as a field in a Data Model Object (DMO). A model has inputs (values for predictor variables) and outputs predictions for the outcome variable, along with additional information if requested.
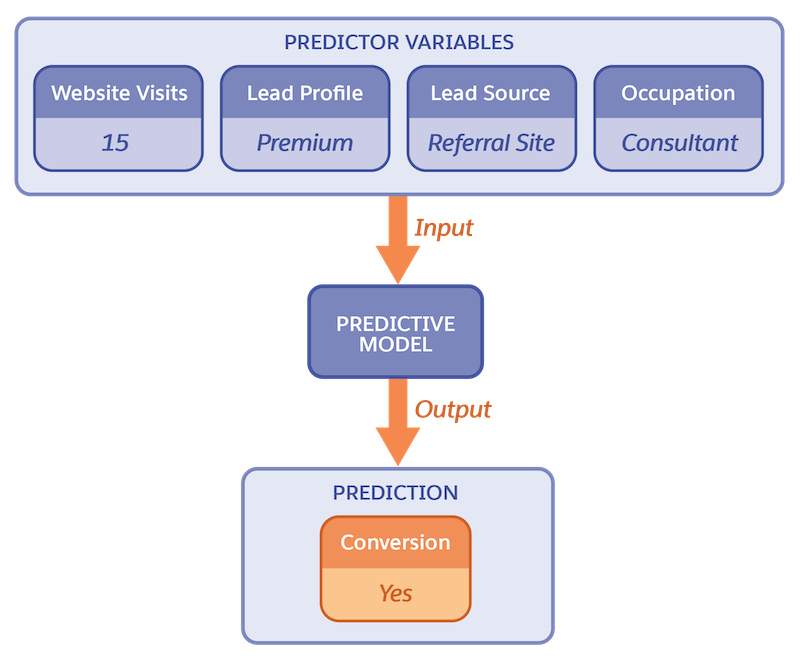
Optionally, a prediction request can be configured to include top predictors and prescriptions in the response.
## How Do Predictive Models Differ from Generative Models?
Both are AI models, but they’re designed and built for different purposes. Predictive models are trained by machine learning on historical data to make predictions or decisions according to input data. Generative models create content according to input data from prompt instructions. For a detailed comparison between predictive and generative AI, see [Discover AI Techniques and Applications](https://trailhead.salesforce.com/content/learn/modules/data-fundamentals-for-ai/discover-ai-techniques-and-applications) in the [Data Fundamentals for AI](https://trailhead.salesforce.com/content/learn/modules/data-fundamentals-for-ai) module in Trailhead. For more about generative models, see [Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai.htm&type=5&language=en_US).
#### See Also
- [_Salesforce Help:_ AI Glossary](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_glossary.htm&release=264.0.0&type=5 "Familiarize yourself with terminology that is commonly associated with predictive AI in AI Models (formerly Einstein Studio).")
# Keyboard Shortcuts
Perform basic actions from your keyboard.
Global Shortcuts
Description
Ctrl+F (Windows)
Cmd+F (macOS)
Move to the search bar.
Ctrl+/ (Windows)
Cmd+/ (macOS)
Open or close keyboard shortcuts.
Ctrl+O (Windows)
Cmd+O (macOS)
Add input data.
Ctrl+Z (Windows)
Cmd+Z (macOS)
Undo last action.
Ctrl+Y (Windows)
Cmd+Y (macOS)
Redo last undone action.
Ctrl+D (Windows)
Cmd+D (macOS)
Toggle Preview on or off.
Ctrl+S (Windows)
Cmd+S (macOS)
Save.
| Canvas Keyboard Shortcuts | Description |
| --- | --- |
| Arrow key → | Move to the next outgoing node. |
| Arrow key ← | Move to the closest incoming node. |
| Arrow key ↓ | Move to the nearest node below. |
| Arrow key ↑ | Move to the nearest node above. |
| Shift+B | Open node’s Add Branch menu. |
| Tab | Move to the next group of connected nodes. |
| Shift+C | Move to the next outgoing link. |
# Left Join
Like a lookup, a left join includes all rows from the left input data source object and only matching rows from the right object. Unlike a lookup, a join includes all matched rows in the output data when multiple rows match.

Example
Our company's marketing team captures demographic data in an external data source for opportunities stored in Salesforce. To help create more targeted campaigns, the team is segmenting our current opportunities by the Education Level demographic. Let’s use a left join to add demographic data to the opportunity data.
To illustrate how this batch data transform handles unmatched rows and duplicate keys, we included them in both input data sources.
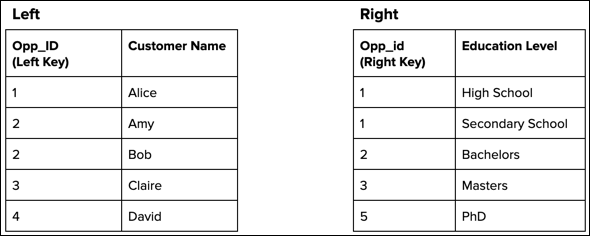
After performing the left join based on the matching keys, the batch data transform produces the following output data.
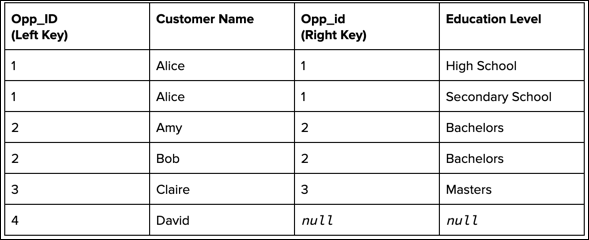
All rows from the left, including those without a match and those with multiple matches, are included in output. Because `Opp_ID` 1 has two matches on the right (High School and Secondary School), the output contains a separate record for each education level. Also, because `Opp_ID` 4 doesn’t have a match, the `Opp_id` and `Education Level` fields are null for that record.
# Limitations and Key Considerations
Review these limitations before you use Simple Start:
- **Availability limit:** Data 360 limits Simple Start exclusively to new orgs provisioned starting in July 2026. Existing organizations don’t receive access to this automated configuration tool.
- **Connection limit:** The automated setup operates only from your home org connection. It doesn’t support companion orgs.
- **Data space limit:** Simple Start creates all auto-synced components such as data lake objects (DLOs), data streams, and mappings only in the default data space.
- **Object support:** Data 360 automates setup for a designated list of standard CRM objects from your home org, such as `Account` and `Contact`. It doesn’t support all standard objects, custom objects, or non-CRM objects. See [Data 360 Simple Start Guide](https://resources.docs.salesforce.com/rel1/doc/en-us/static/pdf/Data360_SimpleStart_Guide.pdf).
- **Bundle field exclusions:** Simple Start provisions standard data bundles that omit mappings for _CreatedBy_, _Created Date_, and _Last Modified Date_.
# Link Core Activations to the Marketing Cloud Engagement Contact Model
Data specialists perform these steps in Marketing Cloud Engagement to establish the data foundation.
1. [Create attribute groups](https://help.salesforce.com/s/articleView?id=mktg.mc_mp_who_receives_your_message.htm&type=5&language=en_US) in Contact Builder.
Implementation Pattern
Example Attribute Groups
Core Audience Model
Collective Core Audience model
Identity & Consent
Subscriptions & Preferences
Demographics & Psychographics
Ecommerce
2. In each attribute group, data specialists link the data extensions that marketers activated in Data 360.
- Ensure that the data deletion feature is turned off for the commonly shared data extensions.
- Relate the Individual data extensions with a 1:1 relationship to the root on ContactKey↔Individual ID.
- Link the activated Unified Individual data extensions directly to the Individual data extension in a 1:1 relationship Individual ID↔Individual ID.
Implementation Pattern
Example Attribute Groups
Example Data Extensions in the Attribute Groups
Core Audience Model
Collective Core Audience model
Identity & Consent
Subscriptions & Preferences
Demographics & Psychographics
Ecommerce
MC Identity & Consent
MC Subscriptions & Preferences
MC Demographics & Psychographics
MC ecommerce
3. In Marketing Cloud Engagement, create a Contact Model attribute group for ad hoc campaigns.

Note To prevent data sprawl and performance impacts, turn on the data deletion feature only for the ad hoc data extensions so that their stored data is deleted after the journey is complete. It’s also best practice to routinely check and delete old data extensions from the Contact Model.
# Link or Unlink Data Shares and Data Share Targets
Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.
### Required Editions
User Permissions
Needed
To link or unlink data shares:
Permission set:
1. In Data 360, go to the Data Shares tab.
2. Click the data share that you want to link or unlink.
3. On the data share’s record home page, click **Link/Unlink Data Share Target**.
4. Select the data share target.
If you’re unlinking a data share target, follow the same process and deselect it.
5. Click **Save**.
Linked data share targets are listed on the data share record home page.
# List Which Pages Synced Successfully
View the details of the pages and attachments that were successfully ingested by the Web Content (Crawler or Sitemap) connector.
Use this procedure to view ingestion details about specific pages and their related attachments.
1. From App Launcher, select **Data Cloud**.
2. Open the **Data Streams** tab, open the relevant data stream, and copy the data stream Object API Name, for example: `SffWeb-Crawler__dll`.
3. Open the Query Editor tab, and create a new query. Get familiar with the [Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_create_queries_a_query_editor.htm&language=en_US) to understand how to create queries.
4. For your new query, use this format and adjust the limit according to the number of records the connector ingested: `SELECT * FROM "" LIMIT 4000`
#### See Also
- [_Salesforce Help_: Monitor the Status of Data Ingestion for Unstructured Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_the_status_of_unstructured_connectors_data_ingestion.htm&release=264.0.0&type=5 "You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.")
# LLM-based Parsing and Preprocessing
Use LLM-based parsing and preprocessing to extract and prepare text, metadata, tables, and images from unstructured documents for chunking.

Note Using LLMs to parse and preprocess content impacts credit consumption. This is billed against the Intelligent Processing usage type. For more information, see [Billing Considerations for Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&language=en_US&type=5).
LLM-based parsing converts text and metadata from unstructured document formats into structured or semi-structured representations. For example, parsing identifies document structures (headings, paragraphs, or tables), removes irrelevant content (headers, footers, or HTML tags), and further prepares the text for pre-processing and chunking.
LLM-based visual data preprocessing prepares multimodal elements, such as images and tables for chunking. For example, preprocessing extracts context from images and extracts data from tables while maintaining the context and relationships within the table data.
You cannot select both LLM-based parsing and LLM-based Visual Data Preprocessing options for a search index. Use LLM-based parsing for documents that contain rich visual content—such as images, charts, and tables —throughout the documents. In such cases, processing the entire document holistically provides better context and understanding.
Alternatively, use LLM-based visual data preprocessing when you want to specifically process structured and visual elements like tables, charts, and images, rather than the full content of a document.

Note Parsing and preprocessing options are only available for unstructured data model objects (UDMOs) including file attachment UDMOs. Supported file types include PDF, HTML, DOCx, XLSX, and PPTX.
# Load Data from Data 360 into Marketing Cloud Intelligence
Connect Data 360 to Marketing Cloud Intelligence to analyze your customer data and build dashboards and reports.
The data is refreshed daily by default. You can change the frequency schedule, but using a different refresh rate could delay data subject rights and other compliance-based updates from flowing to Marketing Cloud Intelligence.
You can load your data using an Intelligence Data 360 connector (TotalConnect or Granular Data Center) or by installing the Data Cloud app from the Intelligence Marketplace.
Another connector exists in Intelligence for Data 360 (Data Cloud CI connector) and appears if you previously used it, or if you installed the Data Cloud app. However, we recommend using the Data 360connectors instead. For more information, see [Pull Data Cloud Data into Marketing Cloud Intelligence](https://help.salesforce.com/s/articleView?id=mktg.dato_data_connect_api_concept_datacloud.htm&type=5&language=en_US).
Before loading data from Data 360 into Intelligence, review the prerequisites. See [Prerequisites Before Pulling Data Cloud Data](https://help.salesforce.com/s/articleView?id=mktg.dato_data_connect_cdp_prerequisites.htm&type=5&language=en_US).
#### See Also
- [_Salesforce Help_: Integrate and Analyze Marketing Data with Marketing Cloud Intelligence](https://help.salesforce.com/s/articleView?id=mktg.datorama.htm&type=5&language=en_US)
- [_Salesforce Help_: Pull Data Into Intelligence from Data 360](https://help.salesforce.com/s/articleView?language=en_US&id=sf.dato_data_connect_api_cdp_totalconnect.htm&type=5)
- [_Salesforce Help_: Use the Granular Data Center to Pull Data 360 Data Into Intelligence](https://help.salesforce.com/s/articleView?id=mktg.dato_data_connect_api_cdp_gdc.htm&type=5&language=en_US)
- [_Salesforce Help_: Customer Insights for Marketing Cloud Data 360 App](https://help.salesforce.com/s/articleView?id=mktg.dato_market_customer.htm&type=5&language=en_US)
# Locate the Data Extension in Marketing Cloud Engagement
After it’s activated, a data extension is added to the Marketing Cloud Engagement business unit identified in activation.
Here’s the data extension based on this activation use case.
SubscriberKey
Id
EmailAddress
FirstName
RA_PolicyInformation_02
Raul_J_123
Raul_J_123
Raul.J@example-email.com
Raul
[
{
"policy_number": 1234,
"starting_date": "2021-11-15T00:00:00.000Z",
"product_type": "Auto",
"RA_PolicyProducts": [
{
"product_type_1": "Auto",
"productId": "A123",
"RA_Account02": [
{
"membername": "Raul",
},
{
"membername": "Jennifer"
}
]
}
]
}
]
The first three columns are required based on the activation type (email). The FirstName column is the selected direct attribute. The last column contains the related attributes formatted as a JSON code block in one data extension field. The column name, RA\_Policies\_02, is named after the API name of the related attribute’s main DMO.
- Policy Number
- Starting Date
- Product Type
- Product Type 1
- Product Id
- Member Name
The first three attributes are shown first in the JSON code block.
```json
[
{
"policy_number": 1234,
"starting_date": "2021-11-15T00:00:00.000Z",
"product_type": "Auto",
```
The next attributes come from the RA\_PolicyProducts data model object.
```json
"RA_PolicyProducts": [
{
"product_type_1": "Auto",
"productId": "A123",
```
The final code shows data from the RA\_Account02 data model object. In this example, the customer has two members, Raul and Jennifer.
```json
"RA_Account02": [
{
"membername": "Raul"
},
{
"membername": "Jennifer"
}
]
}
]
}
]
```
#### See Also
- [_Salesforce Help_: Salesforce Data Extensions in Marketing Cloud Connect](https://help.salesforce.com/s/articleView?id=mktg.mc_co_salesforce_data_extensions.htm&type=5&language=en_US)
# Lookup
A lookup returns all rows from the left input data source object and only matching rows from the right object, the lookup source. To ensure that the grain of the results doesn’t change, the lookup output data includes one row for each row in the left object.

Example
Our company's marketing team captures demographic data in an external data source for opportunities stored in Salesforce. To help create more targeted campaigns, the team is building a dashboard that segments our current opportunities by the customers demographics. Let’s use a lookup to add the demographic data to each opportunity record.
Consider the following two input data sources. The left object contains opportunity records. The right contains demographic data. Both objects contain unmatched rows and duplicate keys.
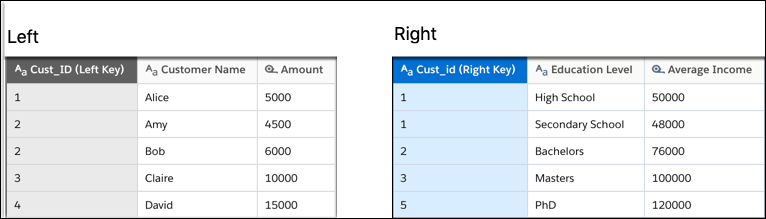
To return a single match when multiple matches are found, the lookup produces the following results based on the matching keys.
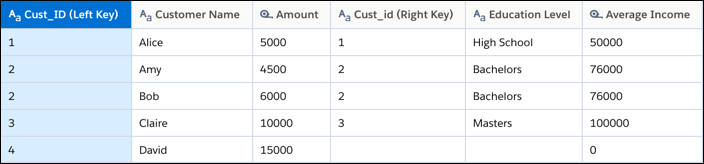
All rows from the left, including rows without a match, are included in the results. Although `Cust_ID` 1 has two matches on the right, the lookup returns only the first matching record. Also, because `Cust_ID` 4 doesn’t have a match, the `Cust_id` and `Education Level` fields are null and `Average Income` is 0 for that record. Unmatched dimensions are set to null. Unmatched measures are set to 0.
# Loyalty Data Model
The Customer 360 Data Model loyalty subject area tracks and manages reward and recognition programs.
The data in this subject area comes from Salesforce platform objects such as Loyalty Program, Loyalty Tier, and Member Benefits.
Loyalty Programs
Loyalty Journals
To view a larger version, right-click or control-click the image and select “Open Image in New Tab” or view the [Loyalty Program](https://developer.salesforce.com/docs/platform/data-models/guide/loyalty-programs.html) or [Loyalty Journals](https://developer.salesforce.com/docs/platform/data-models/guide/loyalty-journals.html) architecture.
These DMOs are represented in the loyalty subject area.
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Account Contact | The Account Contact DMO is a Data 360 data model object for the contact that’s associated with a loyalty program member. | [Account Contact](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_account_contact_dmo.htm) |
| Loyalty Aggregated Point Expiration Ledger | The Loyalty Aggregated Point Expiration Ledger DMO is a Data 360 data model object for points accrued by members based on the currency and points expiration date. | |
| Loyalty Benefit | The Loyalty Benefit DMO is a Data 360 data model object for a perk or betterment that is available to members of a Loyalty Program. Examples could include waived airline baggage fees, complimentary hotel stays, or a rental car upgrade. | [Loyalty Benefit](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_benefit_dmo.htm) |
| Loyalty Benefit Type | The Loyalty Benefit Type DMO is a Data 360 data model object for type of benefits, such as Support Benefits, available to the loyalty program member. | [Loyalty Benefit Type](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_benefit_type_dmo.htm) |
| Loyalty Journal Subtype | The Loyalty Journal Subtype DMO is a Data 360 data model object for a subtype of a loyalty journal type, for example, a watched video or product review. | [Loyalty Journal Subtype](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_journal_subtype_dmo.htm) |
| Loyalty Journal Type | The Loyalty Journal Type DMO is a Data 360 data model object for information about a transaction type, for example, accrual or redemption. | [Loyalty Journal Type](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_journal_type_dmo.htm) |
| Loyalty Ledger | The Loyalty Ledger DMO is a Data 360 data model object to record the points credited or debited for a member across transactions. | [Loyalty Ledger](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_ledger_dmo.htm) |
| Loyalty Member Currency | The Loyalty Member Currency DMO is a Data 360 data model object representing the value a loyalty member selects to receive, for example, as airline miles or as points. | [Loyalty Member Currency](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_member_currency_dmo.htm) |
| Loyalty Member Tier | The Loyalty Member Tier DMO is a Data 360 data model object for the benefit tier within the program that a member is assigned. | [Loyalty Member Tier](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_member_tier_dmo.htm) |
| Loyalty Partner Product | The Loyalty Partner Product DMO is a Data 360 data model object for a product offered by a partner in a loyalty program that is co-marketed to members of the loyalty program. | [Loyalty Partner Product](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_partner_product_dmo.htm) |
| Loyalty Program Partner Promotion | The Loyalty Program Partner Promotion DMO is a Data 360 data model object for promotions that a loyalty program is running in collaboration with a partner. | [Loyalty Program Partner](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_partner_dmo.htm) |
| Loyalty Program | The Loyalty Program DMO is a Data 360 data model object for a marketing strategy designed to encourage customers to continue to shop at or use the services of a business associated with the program. | [Loyalty Program](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_dmo.htm) |
| Loyalty Program Badge | The Loyalty Program Badge DMO is a Data 360 data model object for badges that are assigned to loyalty program members as rewards by a loyalty program. | |
| Loyalty Program Currency | The Loyal Program Currency DMO is a Data 360 data model object for the currency data used by a loyalty program. | [Loyalty Program Currency](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_currency_dmo.htm) |
| Loyalty Program Engagement Attribute | The Loyalty Program Engagement Attribute DMO is a Data 360 data model object for engagement attributes that are used to track loyalty program members’ long-term behavior. For example, an attribute can track the number of times a member has logged in to the company’s shopping site. | |
| Loyalty Pgm Engmt Attribute Promotion | The Loyalty Pgm Engmt Attribute Promotion DMO is a Data 360 data model object for promotions that are associated with engagement attributes. Promotions are offered to members when they achieve the targets of engagement attributes. | |
| Loyalty Pgm Group Member Relationship | The Loyalty Program Group Member Relationship DMO is a Data 360 data model object for a loyalty program member and their contribution towards a group that they’re part of. | |
| Loyalty Program Member | The Loyalty Program Member DMO is a Data 360 data model object for a person who has joined a loyalty program. | [Loyalty Program Member](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_member_dmo.htm) |
| Loyalty Program Member Attribute Value | The Loyalty Program Member Attribute Value DMO is a Data 360 data model object for tracking the value that loyalty program members have achieved towards an engagement attribute’s target. | |
| Loyalty Program Member Badge | The Loyalty Program Member Badge DMO is a Data 360 data model object for a badge that has been assigned to a loyalty program member by a loyalty program. | |
| Loyalty Program Member Case | The Loyalty Program Member Case DMO is a Data 360 data model object for a case created by a loyalty program member. | |
| Loyalty Program Member Promotion | The Loyalty Program Member Promotion DMO is a Data 360 data model object that represents details about a promotion available to a loyalty program member. For example, Double Points on Outdoor purchases. | [Loyalty Program Member Promotion](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_member_promotion_dmo.htm) |
| Loyalty Program Partner | The Loyalty Program Partner DMO is a Data 360 data model object for company’s with loyalty program offerings. | [Loyalty Program Partner](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_program_partner_dmo.htm) |
| Loyalty Tier | The Loyalty Tier Levels DMO is a Data 360 data model object of a Loyalty Program where member benefits increase at higher levels of the hierarchy. | [Loyalty Tier](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_tier_dmo.htm) |
| Loyalty Tier Benefit | The Loyalty Tier Benefit DMO is a Data 360 data model object for a benefit that is available in a specific loyalty member tier. | [Loyalty Tier Benefit](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_tier_benefit_dmo.htm) |
| Loyalty Tier Group | The Loyalty Tier Group DMO is a Data 360 data model object for Loyalty Programs that have multiple sets of benefit tiers organized into groups aligned to their objectives, for example Lifetime, Marketing and Regular. | [Loyalty Tier Group](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_tier_group_dmo.htm) |
| Loyalty Transaction Journal | The Loyalty Transaction Journal DMO is a Data 360 data model object for tracking activities, member behavior, and adjustments, | [Loyalty Transaction Journal](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_loyalty_transaction_journal_dmo.htm) |
| Market Segment | The Market Segment DMO is a Data 360 data model object for a segment in Data 360. Segments are used to decide the target audience for promotions. | [Market Segment](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_market_segment_dmo.htm) |
| Member Benefit | The Member Benefit DMO is a Data 360 data model object for a benefit available within the loyalty program, that a member is qualified for, and has elected to receive. | [Member Benefit](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_member_benefit_dmo.htm) |
| Product | The Product DMO is a Data 360 data model object for a company’s available products. | |
| Product Category | The Product Category DMO is a Data 360 data model object for a category of products sold by the company. | [Product Category](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_category_dmo.htm) |
| Promotion | The Promotion DMO is a Data 360 data model object for details about a promotion associated with the loyalty program, such as the type of promotion, issue of a voucher or credit points, promotion enrollment, and promotion status. | [Promotion](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_promotion_dmo.htm) |
| Promotion Loyalty Partner Product | The Promotion Loyalty Partner Product DMO is a Data 360 data model object for the promotion of a product that a partner is co-marketing to loyalty program members. | [Promotion Loyalty Partner Product](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_promotion_loyalty_partner_product_dmo.htm) |
| Promotion Market Segment | The Promotion Market Segment DMO is a Data 360 data model object for a promotion that’s associated with a market segment. Promotions are associated with market segments to use the segment’s audience as the target audience of the promotion. | |
| Unit of Measure | The Unit of Measure DMO is a Data 360 data model object for units of measure that are used to determine the quantity of products purchased by loyalty program members. | |
| Voucher | The Voucher DMO is a Data 360 data model object for details about a voucher definition that’s associated with a loyalty program. | [Voucher](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_voucher_dmo.htm) |
| Voucher Definition | The Voucher Definition DMO is a Data 360 data model object for details about a voucher definition that’s associated with a loyalty program such as an effective data or expiration date. | [Voucher Definition](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_voucher_definition_dmo.htm) |
# Loyalty Filters
Here are some examples of common loyalty use cases.
## Reward Recent Loyalty Program Individuals
Find individuals who recently joined your loyalty program and offer special rewards to retain them.
This filter finds individuals who joined your loyalty program in the last 5 months.

Example
- Loyalty Program Member | Count | At Least | 1
- Enrollment Date | Last Number of Months | 5

This filter finds individuals who joined your loyalty program in the last 5 months and have greater than $200 in Grand Total Amount.

Example
- Loyalty Program Member | Count | At Least | 1
- Enrollment Date | Last Number of Months | 5
AND
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 200
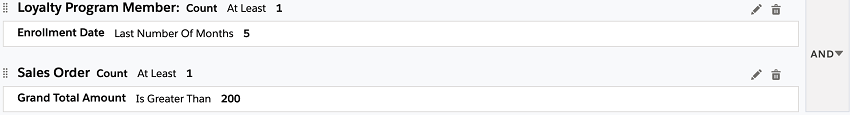
## Offer Special Discounts to High Status Loyalty Members
This filter finds individuals whose loyalty tier is gold or higher.

Example
- Loyalty Member Tier | Count | At Least | 1
- Tier Name | Is In | Gold, Platinum, Diamond

## Find Individuals with Member Points
This filter finds individuals with a point balance greater than 1,000.

Example
- Loyalty Members Currency | SUM | Point Balance | Is Greater Than | 1000
- Points Balance | Is Greater Than | 0

## Find Individuals with Silver Status and Member Points
This filter finds individuals with a silver tier status with more than 2,000 points.

Example
- Loyalty Member Tier | Count | At Least | 1
- Tier Name | Is Equal To | Silver
AND
- Loyalty Members Currency | SUM | Point Balance | Is Greater Than | 2000
- Points Balance | Is Greater Than | 0
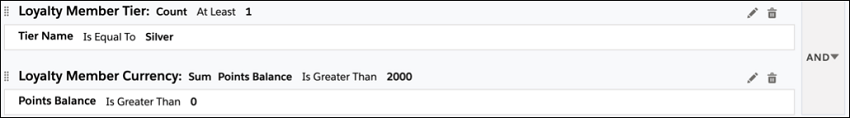
## Identify Loyalty Members with Gold or Higher Status and High Engagement
This filter finds members who opened or clicked at least 10 emails in the last 2 months.

Example
- Email Engagement | Count | At Least | 10
- Engagement Channel Action | Is In | Click, Open
- AND
- Engagement Date Time | Last Number Of Months | 2
AND
- Loyalty Member Tier | Count | At Least | 1
- Tier Name | Is In | Gold, Platinum, Diamond
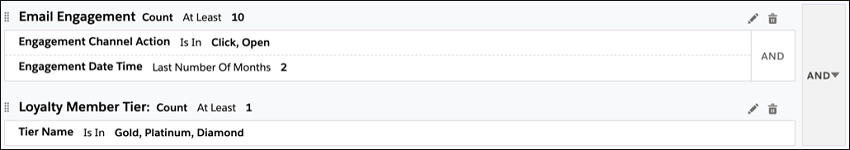
## Find Individuals with More Than 5 Transactions in the Last Year
This filter finds individuals who made more than 5 transactions in the last year.

Example
- Loyalty Transaction Journal | Count | At Least | 5
- Transaction Amount | Is Greater Than | 0
- AND
- Activity Date | This Year

## Find Members That Made Single Transactions Larger Than $1,000
This filter finds members who made single transactions larger than $1,000.

Example
- Loyalty Transaction Journal | Count | At Least | 1
- Transaction Amount | Is Greater Than | 1000

## Find Members with Vouchers
This filter finds members who have used a voucher in the last 30 days.

Example
- Voucher | Count | At Least | 1
- Discount Percentage | Is Greater Than| 10
- AND
- Used Date | Last Number of Days | 30

## Find Members with a Voucher Expires Soon
This filter finds members who have a voucher expiring in the next 7 days.

Example
- Voucher | Count | At Least | 1
- Expiration Date | Next Number of Days | 7

## Remind Members That Vouchers Are Usable Soon
This filter finds members who have a voucher with an effective date in the next 5 days.

Example
- Voucher | Count | At Least | 1
- Effective Date | Next Number of Days | 5

#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Loyalty Management Bundle Data Mappings
The Loyalty Management data lets you track and manage reward and recognition programs. Loyalty Management is a Salesforce Industry Cloud application. The data is available from Salesforce Platform objects, including Loyalty Program, Loyalty Tier, and Member Benefits. These data mappings relate to the Loyalty Management bundle available in Data 360. You can add more mappings by the bundle, and customize the data mappings. The Loyalty Management bundle is accessible only when object permissions have been set for your Loyalty Management objects.
These data streams are created from the Loyalty Management data bundle categorization.
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| Benefit | Other | [Benefit Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_benefit.htm) |
| Benefit Type | Other | [Benefit Type Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_benefit_type.htm) |
| Category | Other | [Category Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_category.htm) |
| Contact | Profile | [Contact Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_contact.htm) |
| Journal Subtype | Other | [Journal Subtype Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_journal_subtype.htm) |
| Journal Type | Other | [Journal Type Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_journal_type.htm) |
| Loyalty Aggregated Point Expiration Ledger | Other | [Loyalty Aggregated Point Expiration Ledger Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loyalty_agg.htm) |
| Loyalty Ledger | Engagement | [Loyalty Ledger](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loyalty_ledger.htm) |
| Loyalty Member Currency | Other | [Loyalty Member Currency Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loyalty_lmember_curr.htm) |
| Loyalty Member Tier | Other | [Loyalty Member Tier Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loyalty_member_tier.htm) |
| Loyalty Partner Product | Other | [Loyalty Partner Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_partner_prod.htm) |
| Loyalty Program | Other | [Loyalty Program Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog.htm) |
| Loyalty Program Badge | Other | [Loyalty Program Badge Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_badge.htm) |
| Loyalty Program Currency | Other | [Loyalty Program Currency Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_cur.htm) |
| Loyalty Program Engagement Attribute | Other | [Loyalty Program Engagement Attribute Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_eng_att.htm) |
| Loyalty Program Engagement Attribute Promotion | Other | [Loyalty Program Engagement Attribute Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_eng_att_promo.htm) |
| Loyalty Program Group Member Relationship | Other | [Loyalty Program Group Member Relationship Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_group.htm) |
| Loyalty Program Member | Profile | [Loyalty Program Member Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_mem.htm) |
| Loyalty Program Member Attribute Value | Other | [Loyalty Program Member Attribute Value Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_mem_att.htm) |
| Loyalty Program Member Badge | Other | [Loyalty Program Member Badge Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_mem_bad.htm) |
| Loyalty Program Member Case | Other | [Loyalty Program Member Case Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_mem_case.htm) |
| Loyalty Program Member Promotion | Other | [Loyalty Program Member Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_mem_promo.htm) |
| Loyalty Program Partner | Other | [Loyalty Program Partner Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_partner.htm) |
| Loyalty Program Partner Promotion | Other | [Loyalty Program Partner Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_prog_part_promo.htm) |
| Loyalty Tier | Other | [Loyalty Tier Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_tier.htm) |
| Loyalty Tier Benefit | Other | [Loyalty Tier Benefit Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_tier_ben.htm) |
| Loyalty Tier Group | Other | [Loyalty Tier Group Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_loy_tier_group.htm) |
| Member Benefit | Other | [Member Benefit Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_member_benefit.htm) |
| Product | Other | [Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_product.htm) |
| Promotion | Other | [Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_promotion.htm) |
| Promotion Loyalty Partner Product | Other | [Promotion Loyalty Partner Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_promo_loy.htm) |
| Promotion Market Segment | Other | [Promotion Market Segment Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_promo_mark_seg.htm) |
| Segment | Other | [Segment Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_segment.htm) |
| Transaction Journal | Engagement | [Transaction Journal Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_transaction_journal.htm) |
| Unit of Measure | Other | [Unit of Measure Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_unit_measure.htm) |
| Voucher | Other | [Voucher Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_voucher.htm) |
| Voucher Definition | Other | [Voucher Definition Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_voucher_def.htm) |
With Loyalty Management, use the data mappings for these objects.
#### See Also
- [_Salesforce Help_: Loyalty Management](https://help.salesforce.com/s/articleView?id=xcloud.loyaltyoverview.htm&type=5&language=en_US)
- [_Salesforce Developer_: Loyalty Management Standard Objects](https://developer.salesforce.com/docs/atlas.en-us.loyalty.meta/loyalty/loyalty_api_overview.htm&type=5)
# Make Segment Names Available in Data 360
Segment names are stored in the Salesforce Platform. To include them in your clean room query results, make them available in Data 360 by connecting to the Market Segment data by using the CRM Connector. If you don't ingest segment names into Data 360, your query reports only contain the segment IDs.
### Required Editions
Available in: Enterprise Edition (home org)
## Ingest Segment Names into Data 360
Create a data stream and formula to ingest the segment names that are stored in Salesforce into Data 360. The formula truncates the segment ID to 15 characters so that it can be used for data model relationships.
### Required Editions
User Permissions Needed
To create a data stream
Data Cloud Architect permission set
Connect Data 360 to a CRM org. Configure a CRM connector in Data Cloud Setup.
1. In Data Cloud, on the Data Streams tab, click **New**.
1. Select **Salesforce CRM**, and click **Next**.
2. Select the Salesforce org for the clean room.
3. Select **View Objects**.
4. Search for and select the **Segment** object.
5. Click **Next**.
2. On the Standard Fields tab, select **Segment Name**, **Population** and any other field that identifies the segment.
The required fields are auto-selected.
3. Map the fields of the DLO to the Market Segment DMO. Map the **Population** field to the **Last Segment Member Count** field.
4. On the Formula Fields tab, click **New Formula Field** and enter these details.
1. Enter a Field Label. The field label acts as the display name for a data stream field.
2. Update the Field API name to match the field label in the prescribed format. The field API name acts as the programmatic reference for a data stream field.
3. For Formula Return Type, select **Text**.
5. In the Search function window, under Text, find and select the **Substring** function.
6. Click **Apply Function**.
1. In the example formula, delete “text,” and select **Segment ID** from the Attributes tab to replace it.
2. Replace “beginindex” with 0, and replace “endindex” with 15.
The function appears as SUBSTRING(sourceField\[‘Id’\],0,15)
3. Under Tested Value, enter a segment ID that’s more than 15 characters, and click Test.
The output should truncate the segment ID to 15 characters.
4. Click **Save**.
7. On the Formula Fields tab, select the new field and click **Next**.
8. Select the data space.
9. Click **Deploy**.
10. (Optional) To use Clean Rooms in multiple data spaces, ingest the Segment object for all the required data spaces.
1. On the Data Streams tab, select the data space that you want to add.
2. Click **Add Space Member**.
3. Select the DLO that you ingested.
## Create a Relationship to the Market Segment DMO
Create a relationship between the Individual - Latest DMO and the Market Segment DMO so that the segment names are mapped to the relevant fields in the Individual - Latest DMO.
### Required Editions
User Permissions Needed
To create a DMO relationship
Data Cloud Architect permission set
1. In Data Cloud, go to the Data Model tab.
2. Search for and select the **Individual - Latest DMO**. If you can’t find the DMO, change the List View from **Mapped** to **All**.
3. On the Relationships tab, click **Edit**.
4. Click **New Relationship** and enter this information.
1. For Field, select **Segment Id**.
2. For Cardinality, select **1:1**.
3. For Related Object, enter Market Segment.
4. For Related Field, select the formula field that you created.
5. Click **Save**.
6. If applicable, repeat these steps for the Unified Individual - Latest DMO.
The segment names are now connected to the Individual - Latest DMO and are included in the clean room query results.
# Manage a Communication Capping Configuration
Each organization is limited to one active communication capping configuration in Data Cloud. If you want to modify the dimensions in a communication capping configuration, create another communication capping configuration. To create another one, you must disable the active communication capping configuration.
### Required Editions
Permission Sets Needed
To use Communication Capping:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
To disable a communication capping configuration, remove any active activation targets mapped to it.
1. In Data Cloud, click **Communication Capping**.
2. Disable or enable a communication capping configuration using the dropdown menu next to it, or open it and click Disable or Enable.
# Manage AI Notebooks
Manage your generative AI notebooks in Data 360 Notebook AI. By default, a notebook is private to the user who creates it.
### Required Editions
User Permissions
Needed
To allow users to access Notebook AI in Data 360 :
Enable Notebook AI Custom Permission Set
## Create a Notebook
Use Notebook AI to explore content for research, building proposals, or analysis.
1. From App Launcher, select **Data Cloud**.
If you are using the Notebook AI web application, go to [notebookai.salesforce.com](http://notebookai.salesforce.com/) and enter your domain and credentials. You can also access the Notebook AI application from Salesforce orgs.
2. Select **Notebook AI** and click **New Notebook**.
3. Enter a name, select a data space, and add an appropriate description for your notebook.
You can create notebooks in the default data space and data spaces that Notebook AI has access to.
4. Click **Save**.
Data 360 creates a new notebook in the default workspace. Now, you can build your resource libraries in the notebook.
## Add a Resource Library and Sources
Use a resource library to group related resources. You can build or import a resource library. A notebook can contain multiple resource libraries.
1. To add a resource library, click **New Resource Library** or start by adding sources to the personal library.
2. Enter a name that describes the collection of sources.
For example, you can group resource libraries for a support issue on DC Sandbox as Customer Meeting Gemini Notes, DC Sandbox Product Doc, or DC Sandbox Community Cases.
3. To import a resource library, click **Import Resource Library**.
Import resource libraries from other notebooks you have access to or enterprise resources such as search indexes created by your team.
You can also rename a resource library if your project scope changes. You can remove a resource library if it becomes irrelevant to the scope of your research.
After you create a resource library, add sources to your library. These sources can be your personal files like meeting notes or web links. Notebook AI supports the following file types.
System Permissions
| FILE TYPE | Extension |
| --- | --- |
| Web | HTML, XML, ASPX |
| Image | JPEG, PNG, JPG |
| Text | TXT, PDF, DOCX, RTF |
| Slide | PPTX |
| Email and contacts | MSG, EML |
| Spreadsheets | CSV, XLSX |
| Log | LOG |
| Markup | MD |
## Explore Your Resources
Start exploring the sources by asking questions in your workspace and generating new content from your analysis.
1. In your notebook workspace, select relevant resources.
By default, Notebook AI selects all sources. For example, select a resource library for product manuals and wikis.
2. Ask a question in chat and review the responses.
For example, you may want to know what are the supported topologies for Data Cloud Sandboxes.
Notebook AI provides source citations with each response.
3. (Optional) Download the contents of your workspace as a PDF or copy to clipboard.
You can use this content to create enterprise content such as knowledge base articles.
## Generate a Resource Summary
Reduce time spent on document reviews, transform technical content into clear overviews, and get key highlights by summarizing your source content.
1. Select the sources that you want to summarize. For example, Request for proposal (RFP) documents, architecture guides, product documentation or troubleshooting manuals.
2. Click **Summarize Content** at the bottom of the workspace.
3. (Optional) To save the output, click **Export Message to PDF** or **Copy to Clipboard**.
# Manage Data 360 Objects and Field Mappings
Edit or remove objects and field mappings associated with a data model object (DMO) or data lake object (DLO). Manage mappings and objects to ensure data accuracy and maintain the integrity of your data model.
### Required Editions

Note You can delete a DMO only if it's a custom object. You can't delete standard objects. Use the trash icon to remove all field mappings to the DMO or to delete the DMO.
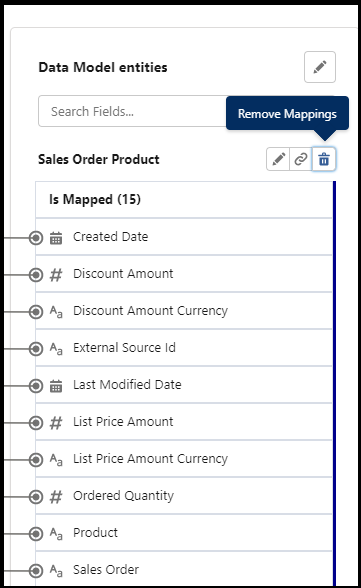
You can't remove mappings in these scenarios:
- The field mapping referential integrity check fails. When you try to remove a field mapping, Data 360 performs a referential integrity check. This makes sure that downstream dependencies such as identity resolution, calculated insights, and segments aren’t impacted. If the referential integrity check fails for any of the DMO fields that are currently mapped, you can’t remove the field mapping.
- A DMO field maps to only one DLO source. Removing the last mapping leaves the field empty. Because a custom DMO requires at least one active mapping, you must delete the entire DMO.
- The DLO is used in the [source priority](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&type=5&language=en_US) of identity resolution reconciliation rules. You can’t remove the field mapping until you remove these reconciliation rule dependencies.

Important This dependency isn’t visible in the error dialog. You must manually confirm it through the Identity Resolution reconciliation rules configuration page.
- The field corresponding to the mapping that you’re trying to remove is used on a Data 360 Lightning page. First, [remove the field from the Data 360 page](https://help.salesforce.com/s/articleView?id=data.c360_a_remove_a_field_mapping_from_customer_data_platform_flexipage.htm&type=5&language=en_US).

Important This dependency isn’t visible in the error dialog. You must manually confirm it through the Lightning page configuration tool.
#### See Also
- [_Salesforce Help_: Remove a Field from a Data 360 Page](https://help.salesforce.com/s/articleView?id=data.c360_a_remove_a_field_mapping_from_customer_data_platform_flexipage.htm&release=264.0.0&type=5 "A FlexiPage represents the metadata associated with a Lightning page. A Lightning page is a customizable screen made up of regions containing Lightning components. A Lightning page is created only for derived data model objects (DMO) that have unified objects such as UnifiedIndividual and UnifiedAccount. You can remove a field from the Data 360 page to remove field mappings.")
- [_Salesforce Help_: Segment Membership Data Model Object](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_membership_data.htm&release=264.0.0&type=5 "Each time you publish a segment, a data model object (DMO) is created or updated to store segment membership information. To identify who's included in a segment, use the Segment Membership DMO (type Segment_Membership). If there are no dependencies on the DMO, you can delete segment membership DMOs manually.")
## Delete an Object
The **Delete Object** option removes field mappings from all DLOs that are mapped to the DMO, and then deletes the DMO. While custom objects are fully deleted, standard objects are placed in an inactive state. Inactive standard objects continue to exist in the system and automatically reactivate after a field is re-mapped to them.
This option is unavailable when the DMO has downstream dependencies, such as identity resolution, segments, calculated insights, and activations. You must remove all dependencies before you can delete the object.
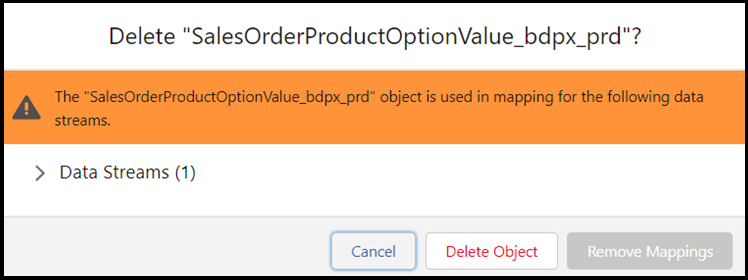
When at least one of the DMO fields is mapped from a single DLO, the **Remove Mappings** button is unavailable. In this situation, you can delete the object entirely.
## Delete an Object with Dependencies
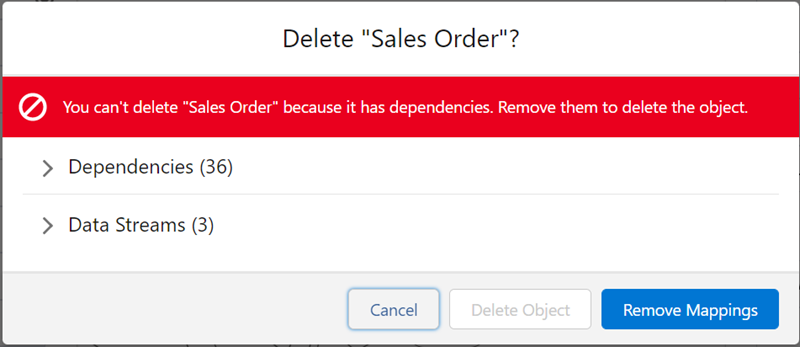
When you attempt to delete a DMO with dependencies, Data 360 lists the dependencies you must remove first. This integrity check is performed for each DMO field, not just the DMO. You can also view which data streams use the DMO, but data streams don't prevent deleting an object. After reviewing the dependency list, if you choose to disassociate the current DLO from its mapping to the DMO but not delete the object, click **Remove Mappings** instead of **Delete Object**.
1. To delete a profile DMO, delete all segments related to the DMO.
2. Delete the associated Segment Membership DMOs created by Data 360. Go to the Data Models tab and change the List Views from Mapped to All.
3. Search for the name of the profile DMO that you want to delete. Then, delete both of the associated Segment Membership DMOs.
4. Delete the profile DMO.
## Replace Field Mappings
You can map to a different DLO field if it has the same data type as the DMO field.

Note You can’t replace field mappings in Developer Edition or sandbox orgs.
1. Select the new DLO and DMO fields you want to map. The new mapping overrides the old one. For example, you can replace the incorrectly mapped DLO field "Last Name" with "First Name" to the same DMO field.
2. Review dependent features to make sure that the DMO fields receive the correct data.
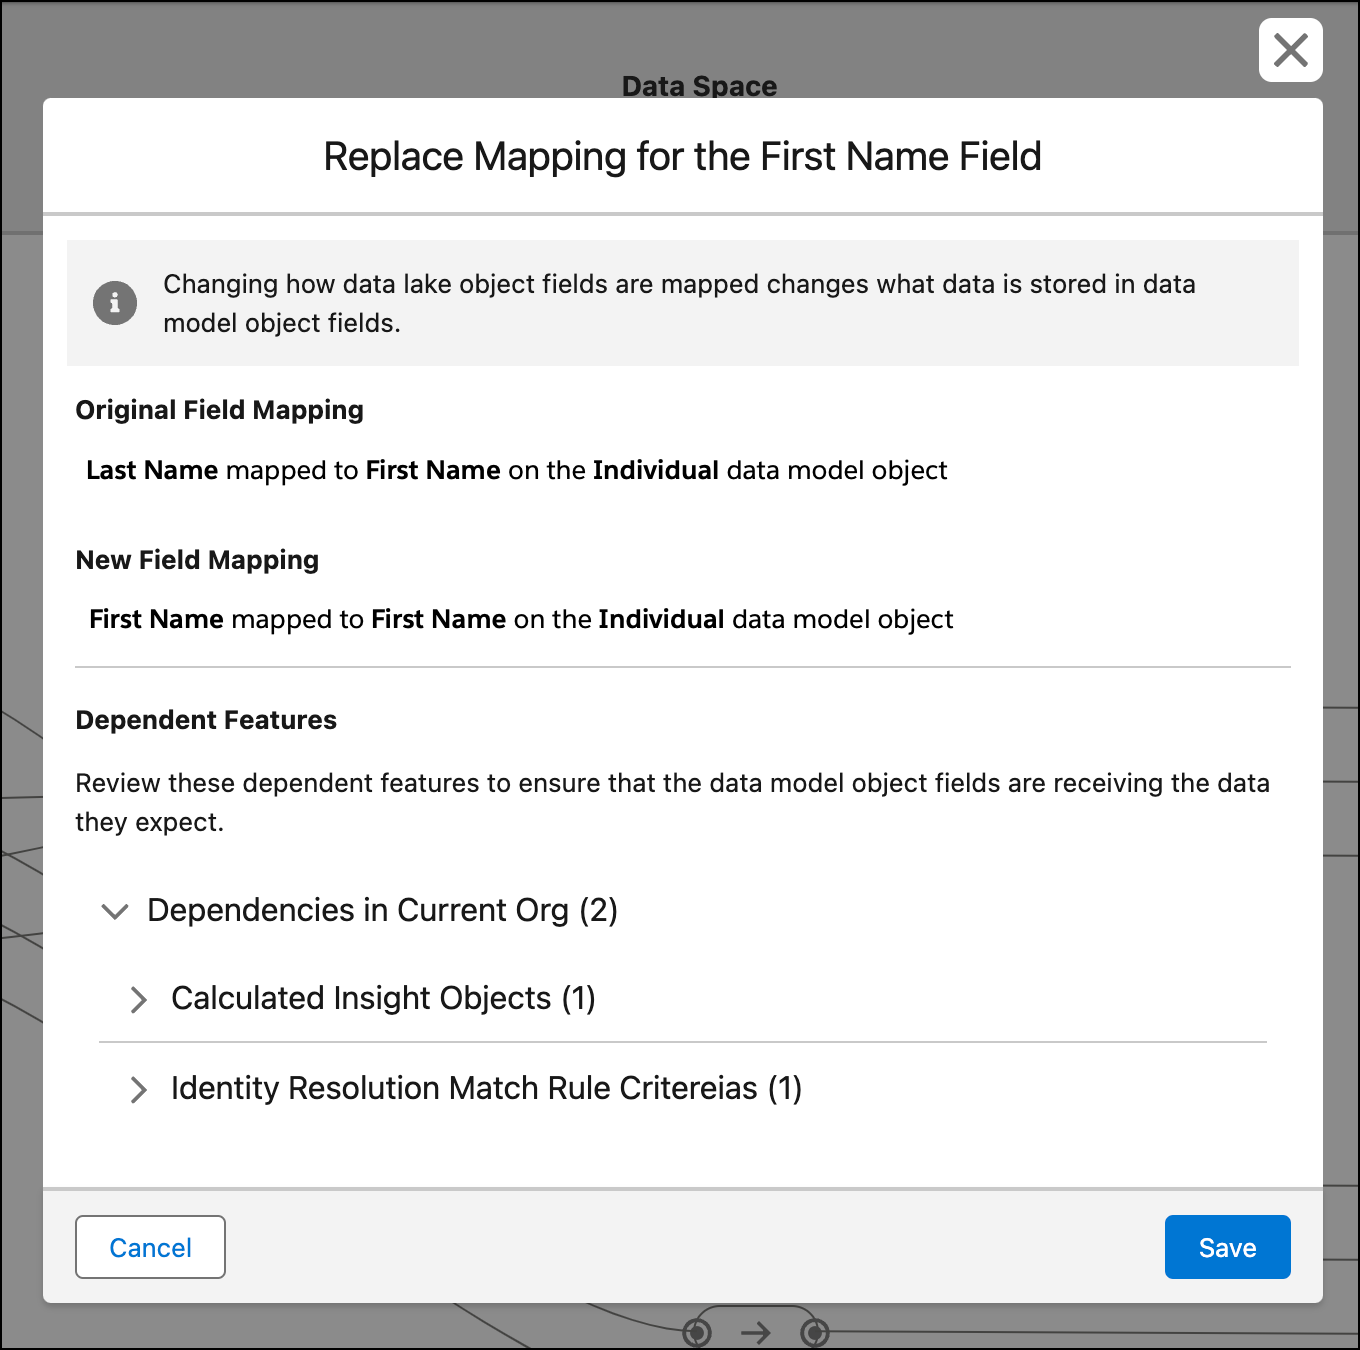
# Manage Data 360 Segment Schedules
The segment scheduling options provide you with granular control over segment publish frequency. You can schedule your segments to run at the frequency that best suits your needs.
### Required Editions
Permission Sets Needed
To schedule a publish:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
[Create a Standard Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&release=264.0.0&type=5 "Create a standard segment based on a data model object and then publish the segment to activation targets."). Then, schedule it based on your needs.
## Schedule a Standard Publish
1. After entering the segment details, select **Standard Publish** for publish type.
2. For Run Mode, select **Schedule**.
3. For Frequency, select how often to publish the segment. You can publish daily, weekly, or monthly.
4. If you selected **Daily** frequency, complete these substeps:
1. Choose 12 hours or 24 hours from the dropdown to set the interval.
2. Enter the **Start Date** and **Start Time** to begin the schedule.
3. Select the days of the week to run the publish.
4. (Optional) To set an end date, select **At a time**, and enter the **End Date** and **End Time**.
5. If you selected **Weekly** frequency, complete these substeps:
1. Enter the number of weeks to determine how often to run the publish.
2. Enter the **Start Date** and **Start Time** to begin the schedule.
3. Select the day of the week to run the publish.
4. (Optional) To set an end date, select **At a time** from the **End** dropdown, and enter the **End Date** and **End Time**.
6. If you selected **Monthly** frequency, complete these substeps:
1. Enter the number of months to determine how often to run the publish (up to 24 months).
2. Choose the day of the month by selecting **On day** and entering the specific day, or select **On last day** to schedule it for the last day of the month.
3. Enter the **Start Date** and **Start Time** to begin the schedule.
4. (Optional) To set an end date, select **At a time**, and enter the **End Date** and **End Time**.

Note If you select day 29, 30, or 31 for scheduling and the selected month doesn't include that day (for example, February or months with 30 days), the segment publish is skipped for that month.
7. Save the segment.
## Schedule a Rapid Publish
1. After entering the segment details, select **Rapid Publish** for publish type.
2. For Run Mode, select **Schedule**.
3. For Frequency, **Daily** is selected by default.
4. Choose **one** hour or **four** hours from the dropdown to set the interval.
5. Enter the From and To time to determine the duration within the day to run the publish.
6. Enter the **Start Date** and **Start Time** to begin the schedule.
7. Select the days of the week to run the publish.
8. (Optional) To set an end date, select **At a time**, and enter the **End Date** and **End Time**.
9. Save the segment.

Note To ensure your segment's final refresh runs, set the **End Time** to be after the calculated final refresh time. If your schedule's End Time is identical to a refresh time (for example, a 24-hour refresh ending at `T15:00Z` and an End Time of `T15:00Z`), the system prioritizes expiration, and that final refresh is skipped.

Note When you update the scheduled publish date and time, the **Next Publish Date Time** field isn't updated immediately on the segment record page. The value is recalculated and updated only after the next publish is complete.
You can view this schedule on the segment details page.
# Manage Data Cloud Data Access Levels for Salesforce Users
You can configure permission sets to grant Salesforce users view access to related list enrichments or other SOQL queries to Data Cloud data without granting access to Data Cloud or permission to view Data Cloud in other contexts.
To update data access levels, in Setup, select the permission set and go to the Data Cloud Data Space Management, then select a data space.
## Grant Controlled by Parent Access to Data Cloud Data
Relationships between objects are referred to as “parent-child” relationships when one object (the parent object) contains values used by another object (the child object).
Granting Controlled by Parent access on a data space lets users view data in a child object as long as they have access to view the data in the related parent object. If you grant Controlled by Parent access to Data Cloud data, Salesforce users can view Data Cloud data in related lists or SOQL query results as long as they have permission to view the record the data is related to.

Example For example, assume Data Cloud ingests information about your contacts from the Contact object in your Salesforce org. Your contact records and related records, such as engagement records, are then processed by identity resolution and included in unified profiles. An system admin creates an enriched related list on the Contact object that shows all the engagement data from the unified profile for each contact. The admin wants to let users see the enriched related list data without letting them access Data Cloud or view unified profiles directly. In this scenario, the admin can give Controlled by Parent access to users who have permission to view Contact object records to allow them to also view the enriched related list.
# Manage Data Returned in Data Graphs
Use conditions and sort and limit to manage the data that’s included in a data graph. Conditions control which records are included based on conditions, while child record limits control how many related child records are returned. Together, these features reduce storage, improve performance, and include only the most relevant data. The sort and limit and condition filters can be applied together for better performance.
### Required Editions
## Configure Filters for Data Graph Nodes
Ensure a stable and predictable data graph by enforcing a configurable limit on child records per parent. Setting limits on child records offers greater control and customization, allowing you to specify the selection order (ascending or descending) based on any field. You can set the maximum number of child records to up to 1000, or use the default value of 100. This enhancement provides a scalable and user-friendly solution for managing cardinality and maintaining performance in complex data graph environments. Additionally, for engagement category data model objects (DMOs), use Recency filter options to sort records based on a time limit.
You can also configure sort and limit filters for calculated insight (CI) nodes in a data graph. This configuration lets you limit the number of CI records included in the final JSON output and specify a sort field and sort order to control which records are prioritized.
The differences between CI and DMO node behavior:
- Sort and limit filters for CI nodes are opt-in. Unlike DMOs, CI nodes don't apply a default record limit or sort order. You must explicitly configure sort and limit filters for each CI node.
- Sort and limit filter configuration for CI nodes is available through the Connect API only. No UI is supported.
- After sort and limit filters are set on a CI node, you can update the configuration, but you can't remove it entirely.
Supported Operators
| Operator | Description |
| --- | --- |
| Equals | Returns records where the field value is equal to the specified value. |
| Does Not Equal | Returns records where the field value isn't equal to the specified value. |
| Less Than | Returns records where the field value is less than the specified value. |
| Greater Than | Returns records where the field value is greater than the specified value. |
| Less Than or Equal To | Returns records where the field value is less than or equal to the specified value. |
| Greater Than or Equal To | Returns records where the field value is greater than or equal to the specified value. |
| Contains | Returns records where the field value contains the specified substring. |
| Does Not Contain | Returns records where the field value doesn’t contain the specified substring. |
| Starts With | Returns records where the field value begins with the specified substring. |
| Ends With | Returns records where the field value ends with the specified substring. |
- **[Applying Filters in the Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_apply_filters_dg.htm&release=264.0.0&type=5)**
You can apply filters when creating a new data graph or editing an existing one.
#### See Also
- [_Salesforce Help_: Create a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_graph.htm&release=264.0.0&type=5 "Before creating a data graph in Data 360, decide which existing data model object (DMO) to use as the primary DMO. The primary DMO determines which related objects you can include in the data graph.")
- [_Salesforce Help_: Edit a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_data_graph.htm&release=264.0.0&type=5 "You can change a data graph’s name and description, associate new data model objects (DMO), and make additive changes to the existing primary and associated DMOs.")
- [_Salesforce Help_: Clone a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_clone_a_data_graph.htm&release=264.0.0&type=5 "When you clone a data graph, the clone inherits the data space and primary data model object (DMO) from the original data graph. You can’t change the data space or primary DMO, but you can select different related objects and fields. You can also change the cloned data graph’s name, API name, filter settings, and description.")
# Manage Data Shares
Create, edit, clone, or delete data shares in Data 360. You can also link or unlink a data share to a data share target.
- **[Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&release=264.0.0&type=5)**
Select the Data 360 objects that you want to include in a data share to share with an external system.
- **[Clone a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_clone_data_shares.htm&release=264.0.0&type=5)**
You can create a data share by cloning an existing one. You can add or remove data objects during cloning.
- **[Edit a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_data_shares.htm&release=264.0.0&type=5)**
You can add or remove the data lake objects, data model objects, and calculated insights objects in a data share. When you add a Data 360 object to a data share, it’s accessible through the linked data share target. Similarly, when you remove a Data 360object, it’s inaccessible through the linked data share target.
- **[Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5)**
Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.
- **[Delete a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_shares.htm&release=264.0.0&type=5)**
In Data Cloud you can delete an unlinked data share that's no longer needed.
- **[Delete a Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_shares_target.htm&release=264.0.0&type=5)**
You can delete unlinked data share targets that you no longer need.
# Manage Document AI Configurations
View, edit, publish, export, and rebuild Document AI configurations. Package Document AI configurations in data kits. Save Document AI configurations as drafts, and refine your extraction schemas over multiple sessions.
### Required Editions
User Permissions Needed
To manage Document AI configurations
Permission set:
**Document AI Requirements**
- To use Document AI in Data Cloud 360, [turn on Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&language=en_US&type=5) and [Agentforce](https://help.salesforce.com/s/articleView?id=ai.agent_setup_enable.htm&language=en_US&type=5).
- Make sure that you have a Data 360 license. Document AI isn't available with Customer Data Platform.
## View Document AI Configuration Details
The details page for a Document AI configuration shows whether it's in **Draft** or **Activated** state, its runtime status, source, output data, and other information.
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Select a Document AI configuration and review the details.
4. To review the output schema, click **Output**.
## Edit a Draft Configuration
Modify and refine a draft configuration before publishing it.
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Select the draft configuration that you want to edit.
4. Click **Edit**.
5. Make your changes to the fields, tables, or other configuration settings.
6. Click **Test** to verify the extraction results.
7. Select **Save Draft** to save your changes.
## Publish a Document AI Configuration
When your schema meets the required accuracy, publish your draft configuration to activate it for document processing.
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Select the draft that you want to publish.
4. Review the details and test results.
5. Click **Publish**.
## Delete a Document AI Configuration
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Select the Document AI configuration that you want to delete.
4. From the object view, click **Delete**.
## Rebuild a Document AI Configuration
If a document schema configuration isn't processed correctly, rebuild the configuration.
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Click the document schema configuration that you want to rebuild.
4. On the details page, select **Rebuild**.
After the rebuild completes, the Last Run Status field changes to Ready.
## Export a Document AI Configuration as JSON
Export and reuse a Document AI configuration as a JSON file.
1. From the App Launcher, select **Data Cloud**.
2. Click **Process Content** | **Document AI**.
3. Select the dropdown menu to export the Document AI configuration.
4. Select **Export JSON**.
The configuration downloads as a JSON file that you can [import](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_no_source.htm&release=264.0.0&type=5) into another org or environment.
## Add a Document Schema Configuration to a Data Kit
Add a document schema configuration to a data kit to share functionality across users and environments.
1. Go to **Data Cloud Setup**.
2. In Tools, click **Data Kits** | **New**.
3. Name the data kit and add an optional description.
4. Click **Save**.
5. Under Document Schemas, click **Add**.
6. Select the document schemas to add to the data kit, and click **Next**.
7. Click **Save**, and then click **Publish**.
Your data kit is created. You can now publish it in [Package Manager](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_package_kit.htm&type=5&language=en_US).
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
- [Auto-extract the Document Schema](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config.htm&release=264.0.0&type=5 "Use the document schema builder to auto-extract the document schema, including fields, tables, and columns.")
- [Add Tables to Extract](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai_new_config_manual.htm&release=264.0.0&type=5 "Configure the tables to extract.")
# Manage Feature Access Across Multiple Data Spaces
Learn to manage feature access across multiple data spaces.
### Required Editions
User Permissions Needed
To manage data spaces:
Manage Dataspace Scope
If you have Data Cloud users who need to access multiple data spaces, create a dedicated permission set for feature access. This dedicated permission set connects a user with a specific data space to grant only feature-level access within it. It contains no object permissions. Use standard Data Cloud permission sets to grant users role-based object permissions. You can apply the dedicated permission set to any feature that is data space aware.
1. Create a dedicated permission set for each data space that requires specific access.
2. In **Data Cloud Data Space Management** settings, connect the dedicated permission set to the data space.
3. To grant users role and object permissions, assign a standard Data Cloud permission set, for example, Data Cloud Data Aware Specialist.
4. To grant users access to features in a specific data space, assign a dedicated permission set.
5. To control user access at the record level, under **Data Cloud Feature Permissions**, enable **View** or **Customize** for each feature.
# Manage Feature Access for Data Space-Aware Data Cloud Features
By default, Data Cloud standard permission sets control access to Data Cloud features with preset object permissions. You can further restrict feature access within each data space assigned to a permission set by changing the data space’s feature permissions.
Feature access is managed on the permission set level with object permissions, and on the data space level within a permission set with feature permissions.
## Set Default Feature Access in a Permission Set with Object Permissions
Object permissions apply to all data spaces associated with a permission set by default. To update object permissions on a permission set, in Setup, select the permission set and go to the Object Settings.
Considerations
Feature permissions can’t be applied if object permissions on any object for the feature are “View All Records” or Modify All Records.” If object permissions are set to View All Records, the Read access setting in feature permissions is overridden. If object permissions are set to Modify All Records, the Customize access setting is overridden.
Changing object permissions doesn’t change feature permissions in associated data spaces. For example, if you change object permission on the Activation Definition object from View to Create, the Customize checkbox in feature permissions for associated data spaces isn’t changed. To allow users assigned to the permission set to customize activations, a system admin must manually set Customize on Activations in the feature permissions for each associated data space.
## Restrict Access Within Specific Data Spaces in a Permission Set with Feature Permissions
Feature permissions override object permissions and are used to further restrict access within specific data spaces. Feature permissions act only within the data space they’re set for. You can’t use feature settings to give more access than what is permitted by the permission set’s object permissions.
Feature permissions control levels of access using two settings: View or Customize. These settings correlate with the object permissions on the primary object for the feature. If the permission set’s object permissions grant Read access on the feature’s primary object, then View is available in the associated data space’s feature permissions. Deselecting View removes Read access for that feature within the data space. Users assigned to the permission set can’t see data associated with the data space. If the object permissions include Create, Edit, or Delete, then Customize is available in the feature permissions. Deselecting Customize removes permission to create, edit, or delete data within the feature.
| Feature | Primary Object |
| --- | --- |
| Activations | Activation Definition |
| Calculated Insights | Calculated Insight Object Definitions |
| Segmentation | Market Segment Definitions |
| Data Actions | Data Action Definitions |
| Identity Resolution | Identity Resolution Definitions |
| Data Shares | Data Share Definitions |
| Data Graphs | Data Graph Definitions |
To update feature permissions for a data space, in Setup, select the permission set and go to the Data Cloud Data Space Management, then select a data space.
#### See Also
- [_Salesforce Help_: Object Permissions](https://help.salesforce.com/s/articleView?id=platform.users_profiles_object_perms.htm&type=5&language=en_US)
# Manage Large Language Model (LLM) Access by Hiding Configurations
Hide an LLM configuration when you want users in Prompt Builder to change to a different model in their prompt templates. They can select a newer LLM version or a different LLM, possibly from a different provider. You can suspend access to a new LLM until you've completed testing. Optionally, you can later show a hidden LLM configuration to make it visible for selection.
1. In Model Library, click the LLM configuration you want to hide.
The Model Visibility column shows whether a model is shown or hidden from selection in Prompt Builder.
2. Click the Configured Models tab.
3. For the LLM configuration you want to hide, choose **Hide Model** from the dropdown menu.
The Model Visibility column shows the model configuration as **Hidden**. The text **(Not Available)** appears in front of the model configuration name.
4. To show a hidden model, choose **Hide Model** from the dropdown menu.
Prompt templates that currently use a hidden model will run the same as before. In Prompt Builder, the prompt template shows that the model is hidden. To change to a different model, the user selects an available model from the Models list. If they clone a prompt template with a hidden model, they must select another model before saving the cloned copy.
# Manage Models
After creating a predictive model, you can edit to update your settings or delete it if it’s no longer needed.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
Before you activate a model, you can update its settings, which saves time and the effort in creating a model.
1. Go to Model Details, and click the model version that you want to edit.
2. Click **Edit** to review and update your settings. Editing a model version creates a new version of your model.
3. Save your work.
After deleting a model, you can’t recover any versions of the model or its prediction jobs.
# Manage Quality Alerts
Model Builder displays quality alerts when it detects issues in your model's training data, quality metrics, or during cross-validation. The alerts can surface in the model setup, details, and inspector.
### Required Editions
USER PERMISSIONS NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create, update,
delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and improvements
derived from a model.
## Alerts in the Model Setup
You can manage alerts when setting up a model's variables. We also recommend that you address any alerts when reviewing your settings, before you save and train the model. To manage alerts when setting up variables, follow these steps.
1. Click a model to access its setup.
2. Click **Prepare Variables** to view any variable alerts.
3. To learn about issues impacting your model, go to the right side of the page, and choose an action. For example, you can resolve a multicollinearity alert by excluding a specific variable before model training.
## Alerts in the Model Details
After model training, alerts can surface in the model details. Here, you can get an overview of an alert, its impact on training data, and the model metrics. To manage alerts in the model details overview, follow these steps.
1. Click a model to view its details.
2. In the "Overview" tab, review what alerts are impacting your model.
3. To learn about the issues impacting the model, click **Review**. This opens the model details, where you can address the alert.
## Alerts in the Model Inspector
After model training, alerts can also surface in the model inspector, where you can learn about the model's training quality and related metrics. To manage alerts in the model inspector, follow these steps.
1. Click the model to view its settings. Here, you can review the model alert details such as the alert type, county, and more.
2. To learn about issues impacting the model, look at the section below the alert.
3. (Optional) To review the alert later, click **Mute**. You can unmute when you're ready to review and address your alerts.
4. To learn about the issues impacting the model, click **Review Alerts**. This opens the model setup, where you can take further action.
# Manage Retrievers
Create and customize retrievers for Retrieval Augmented Generation (RAG) in Data 360. To see the list of retrievers, navigate to the Retrievers tab in AI Models (formerly Einstein Studio). To learn about a retriever, select View Details from the dropdown menu. Each time you edit a custom retriever and save the changes, a new version is created. You can create multiple versions, but you can have only one version active at a time.
Retrievers adhere to the data governance policies set up for your data. Access checks on the results make sure that the user can securely access the standard object and records. If the AI agent or user calling the retriever doesn’t have access to the source record, it doesn’t appear in the retriever results. For more information see, [Best Practices for Agent User Permissions](https://help.salesforce.com/s/articleView?id=ai.agent_user.htm&type=5&language=en_US). To manage retrievers using Data 360 Connect API see, [Data 360 Connect REST API: Retrievers Reference](https://developer.salesforce.com/docs/data/connectapi/references/spec#tag/Machine-Learning).
- **[Create an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_create.htm&release=264.0.0&type=5)**
To improve the relevancy of the content returned to a prompt for a particular use case, create a custom individual retriever in AI Models (formerly Einstein Studio). To customize the retriever, select its search index, define filters, and specify what information it returns.
- **[Create an Ensemble Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_ensemble_create.htm&release=264.0.0&type=5)**
Use ensemble retrievers to get the most relevant information from multiple searches or data sources. In AI Models (formerly Einstein Studio), an ensemble retriever is a collection of individual retrievers. When you run an ensemble retriever, it runs all the individual retrievers, combines their results into a single list, reranks the list according to relevance to the search request, and returns just the most relevant information to the prompt or agent.
- **[Create a Custom SQL Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_customsql_retriever_create.htm&release=264.0.0&type=5)**
Use a custom SQL retriever to query Data 360 objects using a SQL statement. To build your query, select an object, write a SQL query, specify parameter values, and configure citations. Review and run your query to validate accurate results before you save and activate the retriever.
- **[Activate or Deactivate a Retriever Version](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_version_activate.htm&release=264.0.0&type=5)**
Activate a retriever version in AI Models (formerly Einstein Studio) and use it in prompt templates. Only one retriever version can be active at a time. Activating a new version deactivates the current one. Deactivate a version only if no prompt templates depend on it.
- **[Edit or Delete a Retriever Version](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_version_edit.htm&release=264.0.0&type=5)**
Edit retriever versions in AI Models (formerly Einstein Studio) to create versions for testing different configurations and responses within a prompt. You can edit only custom individual retrievers. If no prompt templates depend on a retriever, you can delete it.
# Manage Scheduled Queries
Review the queries scheduled to run on segment publish in a collaboration, check their status, and delete a schedule that you no longer need.
### Required Editions
Available in: Enterprise Editions
User Permissions Needed
To view and manage scheduled queries:
Data Cloud Architect OR Data Cloud Activation Manager OR Data Cloud Activation Specialist
## View Scheduled Queries
Review the queries scheduled to run on segment publish in a collaboration and check their status.
1. In Data 360, go to the **Clean Rooms** tab.
2. Under **Collaborations**, open the collaboration to review schedules for.
3. Click the **Scheduled Queries** tab to view the details of each query schedule.
## Delete a Schedule
Delete a schedule to stop it from running on future segment publishes. Deleting a schedule doesn't remove the results of runs that it already completed.
1. On the **Scheduled Queries** tab, find the schedule to remove.
2. Click **Delete**.
3. To confirm, click **Delete**.

Note You can't recover a deleted schedule. To schedule the query again, set up a new schedule for the collaboration.
# Manage Search Indexes
Create, view, edit, and delete search index configurations.
- **[Create a Search Index Configuration with Easy Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_easy_setup_search_index.htm&release=264.0.0&type=5)**
Follow a few automated steps to create a hybrid search index configuration for a data model object (DMO) or an unstructured data model object (UDMO). Data 360 automatically applies defaults for the chunking and vectorization strategies, and creates chunk and index model objects.
- **[View Search Index Status and Process History](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_view_search_index.htm&release=264.0.0&type=5)**
View details of search index configurations from the Search Index list view and the object record view to monitor the indexing process.
- **[Edit Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_edit_search_index.htm&release=264.0.0&type=5)**
If needed, you can edit Data 360 search index configurations to add fields or file extensions for chunking. You can view but not modify other existing settings.
- **[Rebuild a Search Index Configuration](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_rebuild_search_index.htm&release=264.0.0&type=5)**
If a Data 360 search index doesn't process properly, you can trigger a full rebuild of the index from the list page or the object record view.
- **[Delete Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_delete_index_config.htm&release=264.0.0&type=5)**
You can delete Data 360 search index configurations from the list view and the object record view.
- **[Add a Search Index Configuration to a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_in_data_kit.htm&release=264.0.0&type=5)**
In Data 360, add search index configurations to a data kit to share functionality across users and environments.
- **[Create a Search Index Configuration from a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_index_config_data_kit.htm&release=264.0.0&type=5)**
After you have deployed your data kit in Data 360, you can create a new search index configuration from a index it contains.
# Manage Semantic Enrichments
Edit, deactivate, or delete semantic enrichments as your data model and business rules evolve.
### Required Editions
As your data model, business rules, and terminology change, keep your semantic enrichments up to date to ensure the Data 360 Data Q&A Agent continues to provide accurate responses.
## View and Filter Enrichments
1. From Setup, in the Quick Find box, enter Semantic Enrichments, and select **Semantic Enrichments (Beta)**.
2. The Semantic Enrichments page displays all enrichments in a list view. Each row shows:
- **Name:** The enrichment's display name
- **Scope:** Data Space, Object, or Field
- **Status:** Active or Inactive
- **Critical:** Whether the enrichment is marked as critical
- **Tags:** Organizing labels applied to the enrichment
3. Use the filters at the top of the page to narrow the list:
- Filter by **Status** to see only active or inactive enrichments.
- Filter by **Scope** to see enrichments for a specific data space, object, or field.
- Filter by **Tags** to find related enrichments grouped by category.
## Edit an Enrichment
Update an enrichment's statement, scope, tags, or critical flag as your business rules change.
1. From the Semantic Enrichments page, find the enrichment you want to edit.
2. Click the enrichment's name to open it.
3. Make your changes:
- Update the **Semantic Statement** to reflect new business logic or improved clarity.
- Adjust **Tags** to keep enrichments organized.
- Change the **Critical** flag if priority has shifted.
- Modify the **Scope** if the enrichment should apply more broadly or narrowly.
4. Click **Save**.
Changes take effect immediately. Test the updated enrichment by asking the agent a related question.
## Deactivate an Enrichment
Deactivate an enrichment when it's no longer relevant or needs revision. Inactive enrichments are not used by the agent, but they remain in the system and can be reactivated later.
1. From the Semantic Enrichments page, find the enrichment you want to deactivate.
2. Click the enrichment's name to open it.
3. Change the **Status** to **Inactive**.
4. Click **Save**.
To reactivate later, open the enrichment, set **Status** to **Active**, and save.
## Delete an Enrichment
Permanently remove an enrichment when it's no longer needed. You can't undo this action.
1. From the Semantic Enrichments page, find the enrichment you want to delete.
2. Click the enrichment's name to open it.
3. Click **Delete**.
4. Confirm the deletion when prompted.

Warning Deleting an enrichment can't be undone. If you're unsure, deactivate it instead.
## Organize with Tags
Use tags to group related enrichments by theme, domain, or purpose. For example:
- **revenue:** All enrichments related to revenue calculations and fields
- **customer-segmentation:** Rules for defining customer types and tiers
- **data-quality:** Guidance on which fields to use or avoid
- **compliance:** Rules related to regulatory requirements
Consistent tagging makes it easier to find, review, and update enrichments as your organization grows.
## Best Practices
- Review enrichments quarterly or when major data model changes occur.
- Deactivate enrichments that conflict with new business rules rather than deleting them immediately.
- Test enrichments after editing by asking the agent questions that should trigger them.
- Use clear, consistent tags across your enrichments to simplify bulk management.
- Document the reason for deactivating or deleting enrichments in team notes or change logs.
- At scale (50+ enrichments), audit for conflicts regularly. Contradictory guidance for the same data can produce inconsistent responses.
- Use the Critical flag sparingly. If too many enrichments are marked as critical, the prioritization becomes less effective.
- Group related enrichments with consistent tags. For example, tag all revenue-related enrichments with "revenue" so you can review them together when revenue calculations change.
# Manage Workspaces in Query Editor
Create and delete workspaces in Query Editor to build, execute, and save SQL queries for Data Lake Objects (DLOs), Data Model Objects (DMOs), and data graphs in Data 360.
### Required Editions
## Create a Workspace
User Permissions
Needed
To create a workspace:
Data Cloud Activation Specialist
1. In Data Cloud, go to the Query Editor tab.
2. Choose **New**.
3. Enter the workspace name.
4. From the Data Space dropdown, select the data space.
Query Editor displays only the objects available in the selected data space.
5. Choose **Save**.
## Delete a Workspace
User Permissions
Needed
To delete a workspace:
Data Cloud Activation Specialist
1. In Data Cloud, go to the Query Editor tab.
2. Select the workspace, and from the dropdown, select **Delete**.
3. To confirm, click **Delete**.
Deleting a workspace removes all queries associated with it.
# Managing Insights
Manage calculated insights to drive data-informed decisions with precision. Configure history tracking to monitor long-term metric trends and maintain data integrity. You can schedule automated processing, manually trigger updates, and validate results to ensure your team accesses accurate analytics. Efficiently organize your insight using the list view to edit or delete records as your business needs evolve.
### Required Editions
User Permission Needed
Manage calculated insights
Data Cloud Architect permission set
- **[Track Metrics with Calculated History Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_insight__history_tracking_overview.htm&release=264.0.0&type=5)**
Track how your metrics evolve over time to make data-driven decisions.
- **[Insights List View](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_record_home.htm&release=264.0.0&type=5)**
After creating a calculated insight in Data 360, see the details and edit your record from the Calculated Insights list view. The status, last run time, last run status, and schedule fields are updated in near-real time.
- **[Edit an Insight](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_calculated_insight_in_customer_data_platform.htm&release=264.0.0&type=5)**
If you created an insight using SQL or Insight Builder, you can change its attributes or logic and reuse it.
- **[Process an Insight Manually](https://help.salesforce.com/s/articleView?id=data.c360_a_quick_execution_of_a_calculated_insight_in_customer_data_platform.htm&release=264.0.0&type=5)**
Instead of waiting for a calculated insight to be processed in a scheduled batch, run it manually.
- **[Schedule a Calculated Insight in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_schedule_a_calculated_insight_in_data_cloud.htm&release=264.0.0&type=5)**
Schedule runs of a calculated insight to keep it up to date with data and process new changes in Data 360.
- **[Validate an Insight in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_validate_an_insight_in_data_cloud.htm&release=264.0.0&type=5)**
After creation, validate your calculated or streaming insight in Data Explorer to ensure that your data and formulas are accurate. You must validate an insight before you use it in a segment.
# Manual and Automatic Tagging in Data 360
There are two ways to apply tags to data: manual tagging and automatic tagging.
## Manual Tagging
Manual tagging allows users to directly assign tags to data objects and fields. This method is precise and allows users to apply their domain knowledge, making it ideal for tagging sensitive or business-critical data where context matters.
## Automatic Tagging
Automatic tagging scales this process across large datasets by generating tag suggestions using AI. In Data 360, the Suggest Tags feature uses a large language model (LLM) to look at information such as object and field names and suggests tags based on defined taxonomies. To ensure privacy, it doesn’t access or analyze customer data. Instead, it analyzes metadata to suggest relevant tags at the object and field levels. These tags aren’t applied automatically. A data steward or admin reviews and approves them to ensure that final control remains with someone who understands the business context. To further refine this process, you can add manual tags on top of the auto-suggestions.
- **[Apply a Tag to an Object or Field Manually](https://help.salesforce.com/s/articleView?id=data.c360_a_apply_tag_to_object_field.htm&release=264.0.0&type=5)**
In Data 360, attach a predefined tag to a data object or field to classify it based on sensitivity, usage, or category.
- **[Use Automatic Tag Suggestions in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_automatic_tagging.htm&release=264.0.0&type=5)**
Data 360 suggests tags by analyzing the metadata of objects and fields, such as their names and types. This helps streamline tagging by providing intelligent, context-aware suggestions without scanning the actual data.
# Map Data for a Clean Room Use Case
Create a mapped template to save your data mappings for a specific use case. You can create a template before a clean room collaboration is active. You can also map your data while creating a collaboration or accepting an invitation to collaborate.
### Required Editions
Available in: Enterprise Edition (home org)
User Permissions Needed
To map data for a use case:
Permission set:

Note If the user segments that you want to associate with the clean room aren’t created, see [Prepare Your Data for a Clean Room](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_prepare_data.htm&release=264.0.0&type=5 "To share segments in a clean room, complete these steps to prepare your data. Preparation includes required steps such as ingesting the data, mapping the data lake object (DLO) to a data model object (DMO), hashing fields to protect personal information, and creating segments. You can share segments only in a clean room.").
If you’re a provider using AWS clean rooms, see [Preparing data tables for queries in AWS Clean Rooms](https://docs.aws.amazon.com/clean-rooms/latest/userguide/prepare-data.html). If you’re a consumer mapping your data to collaborate with an AWS-based provider, see [Data types](https://docs.aws.amazon.com/clean-rooms/latest/sql-reference/s_Supported_data_types.html) for more information on permitted data types.
1. In Data 360, on the Clean Rooms tab, under Mapped Templates, click **New**.
2. Select your role for the use case that you’re mapping data for.
3. Select the use case.
4. Select a data space and the data model object.
5. Click **Next**.
6. For each attribute, click the edit icon and select the attribute to map to the data model object field.
7. Select the path for the attribute.
The path length determines the time needed to process the query results. To save time, use the shortest path. Only select a longer path if the query must run through other DMOs or tables.
8. Click **Save**.
9. To map to a subset of an attribute, apply a filter. Applying a filter is recommended for large datasets.
1. Click the mapping field’s filter icon.
2. Select the operator, and enter a value for the filter.
3. Click **Save**.
10. After mapping all the fields, click **Next**.
11. Name the template and add an optional description.
12. Click **Save**.

Note If you’re mapping data for identity boost, you must share personally identifiable information (PII) in unhashed form with the identity provider. Identity boost doesn’t use hashing because address normalization variations (for example, different abbreviations of the same street address) produce different hash values, which reduces match quality. Before mapping your data, make sure that you have all required consumer consents and that you comply with applicable data usage agreements and privacy regulations. Data processing can occur outside your Salesforce region.
# Map Data Model Objects
Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.
### Required Editions
Available in: Lightning Experience

Note
- You can map a DLO to one or more DMOs.
- You can map only one DLO field to a DMO field. A single DMO field can't have more than one source DLO field
- You can map a DLO field to more than one DMO field in the same DMO.

Warning When a custom DMO has the same object API name as a standard DMO:
- If the standard DMO has field mappings, you can still edit existing mappings. But if all mappings are deleted and you save the DMO, you can’t map any DLOs to this standard DMO.
- If the standard DMO doesn’t have field mappings, you can’t map any DLOs to this standard DMO.
1. Go to the Data Streams tab.
2. Search for and click the data stream you want to map.
3. Click **Start Data Mapping**.
4. Click **Select Objects**.
The field-mapping canvas shows your source DLOs on the left and target DMOs on the right.
You can select an object from your data model or add a new custom object to your data model.
5. Click **New Custom Object** in the Custom Data Model.
1. Review Object Label, Object API Name, and Fields.
You can’t change the field properties after you save the object.
2. Save your changes.
6. Select the field to map in the DLO and click the related field in the DMO to establish mapping connection.
A confirmation appears with an arrow connecting the fields.
7. If you don’t see a field in the DMO that represents the field in your source data, you can add a field to the DMO.
1. Click the arrow next to unmapped fields.
2. Click **Add New Field**.
3. Enter a field label or display name.
The Field API Name is auto-completed with a suggestion based on the naming convention.
4. Choose the field data type.
The field data type must be compatible with the data type of the source field. You can set up a mapping between fields only if they have compatible data types. For example, you can’t map a text field data type to a number field data type.
5. Save your changes.

Tip You can create a DMO from the Data Model tab.
And you can also create field mappings from the Data Lake Objects tab.
Make sure to indicate how a [custom data object relates](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_relationships.htm&release=264.0.0&type=5 "A Data 360 data model object (DMO) can have a standard or custom relationship with other DMOs. The relationship can be structured as a one-to-one or many-to-one relationship. You can view the relationships and their statuses on a DMO record’s Relationships tab.") to other objects in the data model. View your custom DMO from the Data Model tab and create relationships between objects and fields as required.

Note When working with DMOs in custom data spaces, all available fields appear on the field mapping page. In the DMO record page, you can view these fields.
- Mapped fields
- Custom fields
- Unmapped fields that were mapped initially
- System fields such as Created Date and Source System
# Map Data Model Objects in a Data Space
Create connections between data lake objects (DLOs) in a data space and data model objects (DMOs). You can use only mapped fields and objects with relationships for segmentation and activation.
### Required Editions
User Permissions
Needed
To map data objects:
Permission set:
Before you map a data object to a data space, review [Data Mapping](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping.htm&type=5&language=en_US) to understand the requirements and DMO relationships.
1. In Data 360, go to the Data Streams tab.
2. Open the data stream that you want to map. The Data Mapping section shows all the data spaces that a DLO is associated with.
3. Click **Start**.
4. Under Data Model entities, click **Select Objects**.
On the canvas, the source DLOs are on the left, and the target DMOs are on the right. All standard DMOs are available for mapping.
5. To select a custom data model, go to the Custom Data Model tab, and click **New Custom Object**.
6. Review the object label, object API name, and fields.
7. Click **Save**.
8. To establish a mapping, select the field in the DLO, and click the related field in the DMO. A confirmation appears with an arrow connecting the fields.
9. Click **Save**.
#### See Also
- [_Salesforce Help_: Map Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&release=264.0.0&type=5 "Data mapping relates Data Lake Object (DLO) fields to Data Model Object (DMO) fields, paving the way for unifying your source data into a single standardized Customer 360 data model.")
# Map Your Communication Capping Activation Targets to Parameters
To apply communication capping to an activation target, you must map the targets to the parameters.
### Required Editions
Permission Sets Needed
To create activation targets and use Communication
Capping:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. In Data Cloud, click **Activation Targets**.
2. Select the activation target.
3. In the Map Target to Parameters section, click **Add**.
4. Select the parameters such as channel, department, and city.
5. Click **Save**.
When you create the activation for communication capping activation targets, the mapped parameters are displayed in the Activation Summary.
After mapping the targets to parameters, create customer segments and activate them to the communication capping activation targets.
# Mapping for DateTime, Date, and Boolean Objects
The Salesforce CRM connector maps the objects DateTime, Date, and Boolean based on the object and field type.
Mapping for the Date and DataTime objects when deploying a data stream and when creating a data stream using a starter bundle.
| Object | Field | Mapping |
| --- | --- | --- |
| Standard Object | Standard Date Field | DateTime |
| Standard Object | Custom Date Field | Date |
| Custom Object | Custom Date Field | Date |
Mapping for the Boolean object when deploying a data stream and when creating a data stream using a starter bundle.
| Object | Field | Mapping |
| --- | --- | --- |
| Standard Object | Standard Boolean Field | Text |
| Standard Object | Custom Boolean Field | Boolean |
| Custom Object | Custom Boolean Field | Boolean |
Mapping for the Currency object when deploying a data stream and when creating a data stream using a starter bundle.
| Object | Field | Mapping |
| --- | --- | --- |
| Standard Object | Standard Currency Field | Number |
| Standard Object | Custom Currency Field | Currency |
| Custom Object | Custom Currency Field | Currency |
# Mapping Org IDs
The internal organization ID is commonly referred to as the Salesforce.com Organization ID or simply the Org ID. It’s a reference ID to the business unit or other internal organization that owns the data record and is a standard audit field for every standard DMO. However, this reference ID value is not populated by the CRM connector.
- The Internal Organization ID is not mapped automatically for CRM sources:
- It is also not mapped for CRM connected or remote orgs.
- For other sources it is meant to be sub-scope or tenant ID and can be queried or searched.
- Data Source and Data Source Object are system fields and the mapping is managed by the system.
- For the home org:
- Data Source has a static value of "Salesforce\_Home" and can be queried or searched.
- Data Source Object gets a value of the source Object name and can be queried or searched.
- For connected or remote orgs:
- Data Source gets a static value of "Salesforce\_{OrgId}" and can be queried or searched.
- Data Source Object has a value of the source Object name and can be queried or searched.
# Mapping UDLOs to UDMOs
Workloads in Data 360 that consume unstructured data do so through unstructured data model objects (UDMOs). When you create a UDLO, you map it to a UDMO.
The relationship between UDLOs and UDMOs can be 1:1 or N:1. In other words, each UDLO can be mapped to at most 1 UDMO, while multiple UDLOs can be mapped to a single UDMO.
For example, consider that you’re referencing case recording data from multiple external blob stores. Three different UDLOs reference data from these three sources: `CaseRecordingsFromAWSBucket1`, `CaseRecordingsFromAWSBucket2`, and `CaseRecordingsfromGCS`. Because these sources are logically the same object, the individual UDLOs are mapped to one UDMO: `CaseRecordings`.
## UDMO Field Mapping
Data 360 automatically creates the field level mappings between UDLOs and UDMOs because the schemas across the two objects are identical. When you create a new UDLO, you have two options.
- Map the UDLO to a new UDMO.
- Map the UDLO to an existing UDMO.
View which UDMO a UDLO maps to in the data mapping section for the UDLO. When you create a UDLO, Data 360 assigns the category, Directory Table to the DLO. Field mappings between a UDLO to UDMO are read-only. You can’t review or edit field mappings between a UDLO and UDMO.
# Marketing Cloud Account Engagement Connector
Ingest data from Account Engagement into Data 360 to drive calculated insights and build segments based on marketing asset engagement.
### Required Editions
Available in: Enterprise , Performance , and Unlimited Editions with Account Engagement
Review the data stream mappings for Account Engagement before you import your data.
- **[Marketing Cloud Account Engagement Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_mcae_data_bundle.htm&release=264.0.0&type=5)**
A data stream maps data model objects (DMOs) in Data Cloud to objects in your Salesforce org. The Marketing Cloud Account Engagement CRM data kit contains predefined data streams and mappings for activity related to emails, landing pages, web pages, marketing forms, and marketing links.
- **[Create a Marketing Cloud Account Engagement Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_mcae_create_data_stream.htm&release=264.0.0&type=5)**
To begin the flow of data, create a data stream and then configure the connector in Marketing Cloud Account Engagement.
#### See Also
- [_Salesforce Help_: Connecting Account Engagement and Data 360](https://help.salesforce.com/s/articleView?id=mktg.mcae_data_cloud_parent.htm&type=5&language=en_US)
# Marketing Cloud Account Engagement Data Mappings
A data stream maps data model objects (DMOs) in Data Cloud to objects in your Salesforce org. The Marketing Cloud Account Engagement CRM data kit contains predefined data streams and mappings for activity related to emails, landing pages, web pages, marketing forms, and marketing links.
| DATA SOURCE | Description | Mapping Reference |
| --- | --- | --- |
| Custom URL Activity | How customers interact with your custom URLs, such as clicks. | [Custom URL Activity Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_mcae_custom_url_activity.htm) |
| Email Activity | How customers interact with your emails, such as opens, clicks, and unsubscribes. | [Email Activity Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_mcae_email_activity.htm) |
| Form Activity | How customers interact with your non-embedded forms, such as views and submissions. | [Form Activity Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_mcae_form_activity.htm) |
| Form Handler Activity | How customers interact with your third-party forms, such as views and submissions. | [Form Handler Activity Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-mcae-form-handler-activity.html) |
| Web Page Activity | How customers interact with tracked web pages, such as page views. | [Web Page Activity Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_mcae_web_page_activity.htm) |
# Marketing Cloud Engagement Connector
Connect Marketing Cloud Engagement to Data 360 using a starter data bundle or data extension.
A starter data bundle imports system-defined or standard datasets from Marketing Cloud Engagement into Data 360. Because the schemas or blueprints for these datasets are already known to Data 360, the data lake objects (DLOs) are created and automatically mapped to data model objects (DMOs).
Data extensions are user-defined or customized datasets in Marketing Cloud Engagement. Data 360 offers suggestions on the schema, and you can then confirm the definition and map the DLO into the data model.
The process to initiate movement between Marketing Cloud Engagement and Data 360 is the same for a starter bundle and a data extension. The only difference is the manual work required when working with a data extension.
Data 360 ingests only 90 days of engagement data when creating Marketing Cloud Engagement data streams. Additionally, fields with NULL values are converted to empty strings.
- **[Set Up a Marketing Cloud Engagement Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_marketing_cloud_connection.htm&release=264.0.0&type=5)**
After you create your Data 360 instance, control the scope of data ingestion and activation from Marketing Cloud Engagement and other sources. Before integrating with Data 360, make sure that your Engagement user’s default business unit (BU) is set to the Enterprise ID (EID). Set up your data sources to tell Data 360 where to pull data from, also known as ingest, for data mapping and segments. You can connect multiple EIDs to a single Data 360 org, where each EID has its own connection to Data 360. For each of these connections, you can set up multiple data streams using data bundles or data extensions. Each connection also has its own business unit-to-data space mapping configuration. Data 360 supports only Engagement Enterprise 2.0 account connections.
- **[Marketing Cloud Engagement Starter Data Bundles in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_starter_data_bundles.htm&release=264.0.0&type=5)**
Marketing Cloud Engagement offers starter data bundles for Email Studio, MobileConnect, MobilePush, and WhatsApp. Data 360 doesn’t support formula fields for Marketing Cloud Engagement data streams.
- **[Create Data Streams from a Marketing Cloud Engagement Starter Bundle](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_data_stream.htm&release=264.0.0&type=5)**
To begin the flow of data from a Marketing Cloud Engagement source to Data 360, create data streams from starter bundles. Data 360 only supports formula fields for the Salesforce Marketing Cloud (SFMC) Enterprise Profile Attribute data stream.
- **[Create a Data Stream from a Marketing Cloud Engagement Data Extension](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_data_extension.htm&release=264.0.0&type=5)**
A data extension is a table within Marketing Cloud Engagement that contains your data. Use that data in Data 360 by creating a data stream in Data 360 from a Marketing Cloud Engagement data extension.
- **[Marketing Cloud Engagement Refresh Mode](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_cloud_refresh_mode.htm&release=264.0.0&type=5)**
When ingesting data into Data 360 from Marketing Cloud Engagement, the refresh mode is either upsert or full refresh. Each handles your data differently.
# Marketing Cloud Engagement Data Action Targets
Use data and insights to drive business metrics and reduce delay in interacting with customers with Journey Builder API events and transactional emails sent in Marketing Cloud Engagement. Automate and personalize transactions by combining Data 360 with Engagement. You can automate simple operational tasks with data-triggered email messages and journeys, maximize conversions, and minimize customer drop-off rates.
### Required Editions
Engagement data action targets offer these benefits:
- Reduced latency—By using Data 360 data actions through Engagement, data becomes actions in near real time.
- Simple setup and usage—An intuitive UI makes it easy for anyone to create a data action.
- Flexibility—Apply near real-time orchestration to any use case regardless of company size.
Trigger emails and journeys to customers from Data Cloud data model objects and calculated insights based on their behavior or actions.
- **[Create a Marketing Cloud Engagement Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_marketing_cloud_data_action_target.htm&release=264.0.0&type=5)**
Send automated emails and journeys to customers based on behavioral or transactional event data routed from Data 360. Trigger emails and journeys to customers from data model objects (DMOs) and calculated insights. For example, a customer purchases an item and searches for “installation manual” on your website. You trigger an event that sends the customer an email with a how-to video or installation instructions.
- **[Create a Data Extension in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_extension_in_data_cloud.htm&release=264.0.0&type=5)**
Quickly create a data extension for Journey Builder API Events of a data action directly in Data 360. This automated process removes the need to go to Marketing Cloud Engagement.
# Marketing Cloud Engagement Data Bundle Information
When ingesting data from Marketing Cloud Engagement, Data 360 creates data streams and data lake objects (DLOs) for each starter bundle, along with schema and mappings to data model objects (DMOs).
Marketing Cloud Engagement starter data bundle data streams are grouped in data types: campaigns and journeys, contact, or engagement data. Learn about the created data streams, their associated bundles and categories, and links to mapping reference documentation.
Type, Description, and Reference
Data Stream
Bundle
Category
Campaigns and Journeys
These data streams relate
to campaign and journey data associated with Marketing Cloud Engagement.
Marketing Cloud
Engagement: Campaigns and Journeys
SFMC Campaign
Email, WhatsApp
Other
SFMC Email Publication
Email
Other
SFMC Email Template
Email
Other
SFMC Journey
Email, WhatsApp
Other
SFMC Journey Activity
Email, WhatsApp
Profile
SFMC Push Template
MobilePush
Other
SFMC SMS Template
MobileConnect, WhatsApp
Other
SFMC WhatsApp Message Template
WhatsApp
Other
Contact
These data streams relate to contact
data found in Marketing Cloud Engagement.
Marketing Cloud
Engagement: Contact Mappings
SFMC Contact Point App
MobilePush
Profile
SFMC Contact Point Email
Email
Profile
SFMC Contact Point Phone
MobileConnect, WhatsApp
Profile
SFMC Contact Point WhatsApp
WhatsApp
Profile
SFMC Subscriber
Email, WhatsApp
Profile
Engagement
These data streams relate to
engagement data found in Marketing Cloud Engagement.
Marketing Cloud
Engagement: Engagement Mappings
SFMC EES Email Snapshot
Email
Other
SFMC EES Push Snapshot
MobilePush
Other
SFMC Einstein Email Scores
Email, MobilePush
Insights
SFMC Email Complaint
Email
Engagement
SFMC Email Engagement Bounce
Email
Engagement
SFMC Email Engagement Click
Email
Engagement
SFMC Email Engagement Open
Email
Engagement
SFMC Email Engagement Send
Email
Engagement
SFMC Email Unsubscribe
Email
Engagement
SFMC Msg Engagement Event
MobileConnect, WhatsApp
Engagement
SFMC Push Engagement Event
MobilePush
Engagement
SFMC Push Undeliver Event
MobilePush
Engagement
SFMC WhatsApp MO Event
WhatsApp
Engagement
SFMC WhatsApp Send Event
WhatsApp
Engagement
SFMC WhatsApp Tracking Event
WhatsApp
Engagement
# Marketing Cloud Engagement Refresh Mode
When ingesting data into Data 360 from Marketing Cloud Engagement, the refresh mode is either upsert or full refresh. Each handles your data differently.
## Upsert Mode
If your data stream is created in upsert mode, for each refresh, new information is added and the old information is retained.
## Full Refresh
If your data stream is created in full refresh mode, your data is replaced with the new import in each refresh cycle. Contacts can be deleted if they aren’t listed in a new ingestion. We recommend that you delete from the source only the contacts that you want to remove from your Data 360 data.
# Marketing Cloud Engagement Starter Data Bundles in Data 360
Marketing Cloud Engagement offers starter data bundles for Email Studio, MobileConnect, MobilePush, and WhatsApp. Data 360 doesn’t support formula fields for Marketing Cloud Engagement data streams.
## Email Studio
The Email Studio dataset has email engagement events, such as sends, opens, clicks, bounces, complaints, unsubscribes, and Einstein Engagement Scores. These metrics come from campaign, journey, and email template metadata. In addition to these system-defined tables, the email connector brings in a user-defined data stream called Enterprise Profile Attributes. This data provides demographic context around the subscriber base interacting with the emails.
## MobileConnect
The MobileConnect dataset has engagement events, such as sends, delivers, undelivers, opt-ins, and opt-outs. These metrics come from campaign, journey, and message template metadata. MobileConnect engagement data is available at the business-unit level, and data streams relating to this bundle are generated at the business-unit level.
## MobilePush
The MobilePush dataset has engagement events, such as sends, opens, displays, undelivers, geofence entries and exits, and Einstein Engagement Scores. These metrics come from campaign, journey, contact point (app), and push template metadata. MobilePush engagement data is available at the business-unit level. Data streams relating to this bundle are generated at the business-unit level.
## WhatsApp
The WhatsApp dataset has engagement events, such as sends, delivery receipts, opt-ins, and opt-outs. These metrics come from campaign, journey, and message template metadata. WhatsApp engagement data is available at the business-unit level, and data streams relating to this bundle are generated at the business-unit level.
All data streams across Email Studio, MobileConnect, MobilePush, and WhatsApp, except the profile attributes data stream for email, are defined and mapped to the data model for you. You can focus on building and activating segmentation use cases to unlock insights about your data. You can click a data stream created in association with the starter bundle to see a list of raw data fields being ingested. You can also access a read-only view of the mapping between those raw data fields and the Data 360 data model.
- **[Marketing Cloud Engagement Data Bundle Information](https://help.salesforce.com/s/articleView?id=data.c360_a_mc_bundle_data_categories.htm&release=264.0.0&type=5)**
When ingesting data from Marketing Cloud Engagement, Data 360 creates data streams and data lake objects (DLOs) for each starter bundle, along with schema and mappings to data model objects (DMOs).
# Marketing Cloud Personalization Bundle Mappings
When creating a data stream in Data Cloud using a Marketing Cloud Personalization (formerly Interaction Studio) starter bundle, the system creates standard mappings for you.
Event and attribute mappings that aren’t included in the starter data bundle data streams must be defined manually after bundle creation:
- Shopping cart and order line item events
- Custom events
- Custom user attributes
Attributes for standard and custom events are fixed. Event data ingested from Marketing Cloud Personalization into Data 360 is limited to the standard attributes for both standard events and custom events. If you add, delete, or rename attributes in Marketing Cloud Personalization after creating and deploying a Marketing Cloud Personalization data stream, these changes won't be reflected in your data stream.
When ingesting data from Marketing Cloud Personalization, Data 360 creates data lake objects (DLOs) for each starter bundle along with schemas and mappings to Data Model Objects (DMOs). Use these tables to identify how the data is ingested from the DLO and how it’s mapped to the DMO within Data 360.
Data for users and four engagement events is ingested. Each is mapped to a separate data stream, and each populates a separate DLO. Events are immutable and appended. Shopping cart and order events both have an event CSV and a line items CSV, which creates two data streams for each event. A total of seven data streams are created, one for users and six for engagement events.
| Data Lake Objects (DLOs) | Customer 360 Data Model Objects |
| --- | --- |
| Base Events | WebsiteEngagement |
| Cart | ShoppingCartEngagement |
| Cart Events | |
| CartItem | ShoppingCartProductEngagement |
| Cart Events Items | ShoppingCartEngagement |
| Catalog | ProductBrowseEngagement |
| Catalog Events | ProductBrowseEngagement |
| Consent | PrivacyConsentLog |
| Users | Individual, EmailContactPoint, PartyIdentification |
| Order | ProductOrderEngagement |
| Order Events | ProductOrderEngagement |
| OrderItems | SalesOrderProductEngagement |
| Order Line Items | |
## Users DLO Mapping
| Field API Name | Customer 360 Data Model Objects | Object Field |
| --- | --- | --- |
| profileId\_\_c | Individual | Id |
| profileId\_\_c | ContactPointEmail | Contact Point Email Id |
| profileId\_\_c | ContactPointEmail | Party |
| emailAddress\_\_c | ContactPointEmail | EmailAddress |
| profileId\_\_c | PartyIdentification | Party Identification Id |
| sfmcContactKey\_\_c | PartyIdentification | IdentificationNumber |
| sfmcPartyIdentificationName\_\_c | PartyIdentification | IdentificationName |
| sfmcPartyIdentificationType\_\_c | PartyIdentification | IdentificationType |
| anonymous\_\_c | | |
| customerId\_\_c | | |
| extUserId\_\_c | | |
| sfUserId\_\_c | | |
| DataSource\_\_c | | |
| DataSourceObject\_\_c | | |
| InternalOrganization\_\_c | | |
## Catalog Events DLO Mapping
Catalog events record when a user looks at an item.
| Field API Name | Customer 360 Data Model Objects | Object Field |
| --- | --- | --- |
| id\_\_c | ProductBrowseEngagement | Id |
| eventTime\_\_c | ProductBrowseEngagement | Created Date |
| eventTime\_\_c | ProductBrowseEngagement | Engagement Date Time |
| profileId\_\_c | ProductBrowseEngagement | Individual |
| emailAddress\_\_c | | |
| sfmcContactKey\_\_c | | |
| customerId\_\_c | | |
| action\_\_c | ProductBrowseEngagement | Engagement Channel Action |
| itemAction\_\_c | | |
| flagPageView\_\_c | | |
| sourceChannel\_\_c | ProductBrowseEngagement | Engagement Channel Type |
| sourceLocale\_\_c | ProductBrowseEngagement | Device Locale |
| sourcePageType\_\_c | | |
| sourceUrl\_\_c | ProductBrowseEngagement | Product View URL |
| sourceUrlReferrer\_\_c | ProductBrowseEngagement | Referrer URL |
| sourceDevice\_\_c | | |
| sourceOperatingSystem\_\_c | | |
| sourceOperatingSystemVersion\_\_c | | |
| sourceApplication\_\_c | | |
| sourceApplicationVersion\_\_c | | |
| catalogItemType\_\_c | ProductBrowseEngagement | Product |
| catalogItemId\_\_c | | |
| EventDate\_\_c | | |
| DataSource\_\_c | | |
| DataSourceObject\_\_c | | |
| InternalOrganization\_\_c | | |
## Order Events DLO Mapping
Order events record when a user completes a transaction.
| Field API Name | Customer 360 Data Model Objects | Object Field |
| --- | --- | --- |
| id\_\_c | ProductOrderEngagement | Id |
| eventTime\_\_c | ProductOrderEngagement | Created Date |
| eventTime\_\_c | ProductOrderEngagement | Engagement Date Time |
| profileId\_\_c | ProductOrderEngagement | Individual |
| emailAddress\_\_c | | |
| sfmcContactKey\_\_c | | |
| customerId\_\_c | | |
| action\_\_c | ProductOrderEngagement | Engagement Channel Action |
| itemAction\_\_c | | |
| flagPageView\_\_c | | |
| sourceChannel\_\_c | ProductOrderEngagement | Engagement Channel Type |
| sourceLocale\_\_c | ProductOrderEngagement | Device Locale |
| sourcePageType\_\_c | | |
| sourceUrl\_\_c | | |
| sourceUrlReferrer\_\_c | ProductOrderEngagement | Referrer URL |
| sourceDevice\_\_c | | |
| sourceOperatingSystem\_\_c | | |
| sourceOperatingSystemVersion\_\_c | | |
| sourceApplication\_\_c | | |
| sourceApplicationVersion\_\_c | | |
| orderId\_\_c | ProductOrderEngagement | Sales Order Id |
| orderTotalValue\_\_c | ProductOrderEngagement | Net Order Amount |
| orderCurrency\_\_c | ProductOrderEngagement | Currency |
| EventDate\_\_c | | |
| DataSource\_\_c | | |
| DataSourceObject\_\_c | | |
| InternalOrganization\_\_c | | |
# Marketing Cloud Personalization Connector
With Marketing Cloud Personalization (formerly Interaction Studio) data in Data 360, you can ingest user profiles and behavioral events to enrich the customer profile and increase personalization. The connector also lets you use Marketing Cloud Personalization as an activation target.
- **[Set Up a Connection to Marketing Cloud Personalization](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_interaction_studio_connector.htm&release=264.0.0&type=5)**
After you create your Data 360 instance, connect to Marketing Cloud Personalization (formerly Interaction Studio) to enrich customer profiles with user profile data and events.
- **[Create a Marketing Cloud Personalization Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_interaction_studio_starter_bundle.htm&release=264.0.0&type=5)**
To begin the flow of data from a Marketing Cloud Personalization (formerly Interaction Studio) starter bundle, create a data stream.
- **[Marketing Cloud Personalization Bundle Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_interaction_studio_bundle_mappings.htm&release=264.0.0&type=5)**
When creating a data stream in Data Cloud using a Marketing Cloud Personalization (formerly Interaction Studio) starter bundle, the system creates standard mappings for you.
- **[Enhancing Personalization User Mappings for Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_interaction_studio_user_mappings_for_match.htm&release=264.0.0&type=5)**
To successfully use your Marketing Cloud Personalization data in segmentation and activations, map the user fields for Identity Resolution.
- **[Use Your Customer ID as a Party Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_use_your_own_customerid_as_party_identifier.htm&release=264.0.0&type=5)**
By default, the Marketing Cloud Personalization bundle maps the Profile ID to the Data 360 Individual ID. Personalization also connects the Salesforce Marketing Cloud contact key to the party identification number. To unify profiles for identity resolution, use your own Customer ID as the party identifier in Marketing Cloud Personalization and Data 360.
#### See Also
- [_Salesforce Help_: Set Up a Connection to Marketing Cloud Personalization](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_interaction_studio_connector.htm&release=264.0.0&type=5 "After you create your Data 360 instance, connect to Marketing Cloud Personalization (formerly Interaction Studio) to enrich customer profiles with user profile data and events.")
- [_Salesforce Help_: Integrate Personalization with Salesforce Data 360](https://help.salesforce.com/s/articleView?id=mktg.mc_pers_salesforce_cdp.htm&type=5&language=en_US)
# Masking Unstructured Data in Data 360 (Beta)
Mask sensitive information in unstructured files, such as PDFs and text documents, so that only authorized users can view it. Masking policies work on sensitive data that’s automatically tagged or identified.
### Required Editions
## How Unstructured Data Masking Works
Tagging is the foundation for masking unstructured data. When Data 360 ingests unstructured files as unified data lake objects (UDLOs), it analyzes the content and automatically applies personally identifiable information (PII) tags based on recognized patterns. For example, an email address such as mymail@example.com is automatically tagged with `pii.email`. For the list of supported PII tags, see [Einstein Trust Layer Region and Language Support](https://help.salesforce.com/s/articleView?id=ai.generative_ai_trust_lang_region.htm&type=5&language=en_US). After data is tagged, masking policies hide sensitive fields in query results. For example, a support rep sees a customer’s purchase history, while details such as phone numbers and email addresses remain masked.
You can tag UDLOs up to 5 GB per object. For larger data, split it into multiple UDLOs and create separate search indexes.
A single value can match multiple data types. For example, in mariarodriguez@example.com, the entire string matches an email address, while the substring rodriguez also matches the last name. In this instance, Data 360 fully masks the value to prevent accidental exposure. For example, mariarodriguez@example.com becomes **XXXXXXXXXXXXXXXXXXXXX**.
Unstructured tagging supports content in these languages:
- English
- Japanese
- German
- Spanish
- French
- Italian

Note Content tagging isn’t supported for orgs that have Bring Your Own Key (BYOK) enabled because encrypted data can’t be processed for tagging.
- **[Configure Automatic Content Tagging (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_auto_content_tagging.htm&release=264.0.0&type=5)**
Configure automatic content tagging for unstructured files and define a confidence threshold. Data 360 approves tags that meet or exceed the threshold, but others require manual review.
# Match Leads to Accounts
Cross object matching lets you match your leads to existing accounts so that you can identify customers you already have a relationship with.
To match leads to accounts, select Leads as the primary data model object when creating a ruleset.
#### See Also
- [_Salesforce Help_: Match Rules for Accounts](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_accounts.htm&release=264.0.0&type=5 "Identity resolution provides two preconfigured default match rules based on Account Name combined with other common data. Default match rules allow you to quickly select one of the four common match rule configurations. You can combine default and custom rules in a ruleset to create multiple ways for records to match. To get the best results from account matching, we recommend using match rules that match by account name and geographical location. The specific address data you select impacts the quality and precision of your matches.")
- [_Salesforce Help_: Tips for Improving Account Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_accounts_tips.htm&release=264.0.0&type=5 "Creating rules with overly broad criteria can result in poor account matching. Consider these guidelines when setting up identity resolution match rules for unifying accounts.")
# Match Rules for Accounts
Identity resolution provides two preconfigured default match rules based on Account Name combined with other common data. Default match rules allow you to quickly select one of the four common match rule configurations. You can combine default and custom rules in a ruleset to create multiple ways for records to match. To get the best results from account matching, we recommend using match rules that match by account name and geographical location. The specific address data you select impacts the quality and precision of your matches.
## Match Accounts with Default Match Rules
Default match rules are pre-configured rules that you can opt to include in your ruleset. We offer two default match rules for matching accounts.
Match Rule Name
Match Criteria
Exact Name and Normalized Address
Account Name (Exact)
Contact Point Address - Address-Line-1 (Exact Normalized)
Contact Point Address - City (Exact)
Contact Point Address - Country (Exact Normalized)
Exact Name and Normalized Address and Normalized Phone
Account Name (Exact)
Contact Point Address - Address-Line-1 (Exact Normalized)
Contact Point Address - City (Exact)
Contact Point Address - Country (Exact Normalized)
Contact Point Phone - Formatted E164 Phone Number (Exact Normalized)
## Match Account on Party Identifier
If your source data includes strong account identifiers, consider creating a match rule based on party identifiers. The following can be good account identifiers and create efficient matches.
- DUNS Number
- Government tax identifier
- An account ID created by an master data management system
Before using party identifier to match accounts, create a relationship with N:1 cardinality between the Party field in the Party Identification object and the Account ID field in the Account object.
## Match Accounts on Name and Location
These two match rules use geographical data to confirm name matches, which balances precision, correctness, and thoroughness of matches without being overly restrictive. While similar to the default match rules for account matching, these rules use fuzzy matching to increase matching across variations on an account’s name and address.
Match Rule Name
Match Criteria
Name and Address
When your source data includes good address data, a
match rule with these criteria generates highly comprehensive matches with
excellent geographical confirmation.
(Fuzzy Match - Medium Precision) Account Name AND
(Normalized) Address-Line-1
(Fuzzy Match - Medium Precision) City
(Normalized) Country
Name and City
If street address details are inconsistent or
unavailable, a match rule with these criteria generates good matches with strong
geographical confirmation.
(Fuzzy Match - High Precision) Account Name
(Fuzzy Match - Medium Precision) City
(Normalized) Country
- **[Tips for Improving Account Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_accounts_tips.htm&release=264.0.0&type=5)**
Creating rules with overly broad criteria can result in poor account matching. Consider these guidelines when setting up identity resolution match rules for unifying accounts.
#### See Also
- [_Salesforce Help_: Tips for Improving Account Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_accounts_tips.htm&release=264.0.0&type=5 "Creating rules with overly broad criteria can result in poor account matching. Consider these guidelines when setting up identity resolution match rules for unifying accounts.")
# Match Rules for Households
You can add only one match rule to a ruleset when configuring household matching in Data 360 identity resolution. Each unified household contains one or more individuals. We recommend matching individuals into households based on either last name and address or on party identifier.
Individuals can be matched into multiple households. For example, an individual with two street addresses can be matched into two different households based on each street address.
## Match Households on Last Name and Address
This match rule allows matching on last name and geographical address. To use this rule, select the Fuzzy Name and Normalized Address default match rule.
- (Fuzzy - Medium Precision) Individual.Last Name AND
- (Exact Normalized) ContactPointAddress.Address Line 1 AND
- (Fuzzy - Medium Precision) City AND
- (Exact Normalized) Country
## Match Households on Party Identifiers
If your source data includes strong identifiers, consider creating a match rule based on party identifiers. Matching on party identifier lets you match individuals into groups based on a commonality other than name address.
Here are a few useful party identifiers if you have strong data governance practices in place for your party identification data.
- Match car owners based on vehicle identification number (VIN)
- Match loan applicants based on loan application number
- Match event attendees based on ticket order number
This match rule allows matching based on party identification. To use this rule, create a custom match rule with these criteria.
- (Exact Match) Party Identification.Identification Number
# Match Rules for Individuals
Identity resolution provides four preconfigured default match rules based on Individual First Name and Individual Last Name combined with other common data. You can combine default and custom rules in a ruleset to create multiple ways for records to match.
## Default Match Rules for Individuals
Default match rules allow you to quickly select one of the four common match rule configurations.

Note
Identity resolution will match records that have the same Individual.Id, even if you don't create a rule to match them.
Match Rule Name
Match Criteria
Fuzzy Name and Normalized Email
Individual - First Name (Fuzzy - Medium Precision)
Individual - Last Name (Exact)
Contact Point Email - Email Address (Exact Normalized)
Fuzzy Name and Normalized Phone
Individual - First Name (Fuzzy - Medium Precision)
Individual - Last Name (Exact)
Contact Point Phone - Formatted E164 Phone Number (Exact Normalized)
Fuzzy Name and Normalized Address
Individual - First Name (Fuzzy - Medium Precision)
Individual - Last Name (Exact)
Contact Point Address - Address Line 1 (Exact Normalized)
Contact Point Address - City (Exact)
Contact Point Address - Country (Exact Normalized)
Fuzzy Name and Normalized Phone and Normalized Email
Individual - First Name (Fuzzy - Medium Precision)
Individual - Last Name (Exact)
Contact Point Phone - Formatted E164 Phone Number (Exact Normalized)
Contact Point Email - Email Address (Exact Normalized)
## Custom Match Rules for Individuals
Configure custom match rules to meet use cases that aren't covered by the default match rules, for example, when better matches could be made using Party Identification data or other identifiers such as device. Consider adding some of these criteria to your custom match rule.
When configuring custom match rules, select an object, field, and match method for each criteria. Depending on field type, some match methods aren't available.
To allow a match to be made when a field is empty, select Match on Blank.

Warning Carefully consider the value of allowing empty fields to match. Selecting this option can result in low match quality or unusably large profiles when applied to the wrong fields or when data quality is low.
To require that a match be made only when two pieces of data use the same case, select Case Sensitive. For example, suppose you want to identify matches based on the 15-digit CRM ID. Since the original data is case-sensitive, case insensitive matching could result in matching errors. In this case, accurate matching requires that case sensitivity be respected.
## Match Individuals on Party Identification
If your source data includes strong account identifiers, consider creating a match rule based on party identifiers.

Note We recommend using party identifiers only if you have strong data governance practices in place for your party identification data.
This match rule will allow matching based on party identification.
- (Exact match) Party Identification.Identification Number
If you suspect data quality issues with the Identification Number field, you can increase the matching reliability of party identifier matches by also considering the individual’s name.
- (Exact Match) PartyIdentification.IdentificationNumber
- (Fuzzy - Medium Precision) Individual.First Name
- (Exact match) Individual.Last Name
## Match Individuals on Device
Matching based on an exact device lets identity resolution detect matches across profiles created on the same device. The matching algorithm compares Advertiser IDs (Apple’s IDFA or Android’s AAID) to determine a match.
Using the Advertiser Id lets you unify records such as:
- Records across apps and Mobile Push
- Records created by multiple apps by one customer
- Records across apps and offline files, like media logs
This match rule will allow matching on device.
- (Exact Match) Device.AdvertiserId
To strengthen matching, add the device type and operating system as match criteria.
- (Exact Match) Device.AdvertiserId
- (Exact Match) Device.OperatingSystem
To strengthen matching, you can also include the device type and operating system as match criteria.
To match on device, map the Advertiser Id field in the Device object. The Device object must be related to a Contact Point App object through a Device field, which in turn is related to the Individual object through the Party field.
Optionally, map the device type and operating system to include in the match rule.
- **[Anonymous and Known Profiles in Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_summary_anonymous_vs_known_profiles.htm&release=264.0.0&type=5)**
A unified individual profile is considered known if any source profile was designated as known in the source data. A unified individual profile created only from anonymous source profiles is considered an anonymous unified profile. Account profiles are always known profiles.
# Merge Multiple Data Streams Use Case
The Marketing Cloud Engagement connector in Data 360 uses two profile data streams to ingest data from Marketing Cloud Engagement. Both data streams include the same set of primary keys. When these data streams are mapped directly to the Individual data model object (DMO), duplicate records appear in the DMO. To solve this problem, merge the data streams into one data lake object (DLO) before mapping to the Data 360 data model.
To merge multiple data streams, set up multiple streaming data transforms that write to the same target DLO.
# Merge Records with Multi-Definition Transforms
A transform definition specifies the sequence of operations applied to the data during a batch data transform. Definitions appear as nodes in the data flow canvas. You can combine multiple definitions to produce a single, unified output.
### Required Editions
User Permission Sets
Needed
To create batch data transforms
Permission set:
A transform must have at least one definition, but it can support up to five. When writing to an output object, Upsert (or "merge") Mode processes only new and updated records. This feature optimizes resource usage and limits unnecessary reprocessing. Upsert Mode is typically used with multi-definition transforms.
Consider these limitations when using multi-definition transforms:
- If you have multiple transform definitions for a single transform, only one definition can be scheduled to run at a time, but a flow can trigger any of the definitions to run.
- Definitions within a single transform can write to the same output object. Different transforms can’t write to the same output object. For example, when multiple definitions belong to the same transform, a single definition can write to the same output object.

Example You can use multi-definitions and Upsert Mode to isolate a particular definition to fix errors in the output of a transform. This entails a corrected transform definition that writes to the same output object in Upsert Mode.
# Metadata Extraction and Refresh
The metadata extraction framework extracts standard and custom metadata from a Salesforce org. Data 360 stores the metadata in a metadata data lake object (mDLO). A metadata extraction pipeline monitors the metadata's lifecycle, extraction, and ingestion into the catalog. The extraction pipeline handles bulk (Day 0), incremental metadata ingestion, and refresh between the Salesforce org and Data 360.
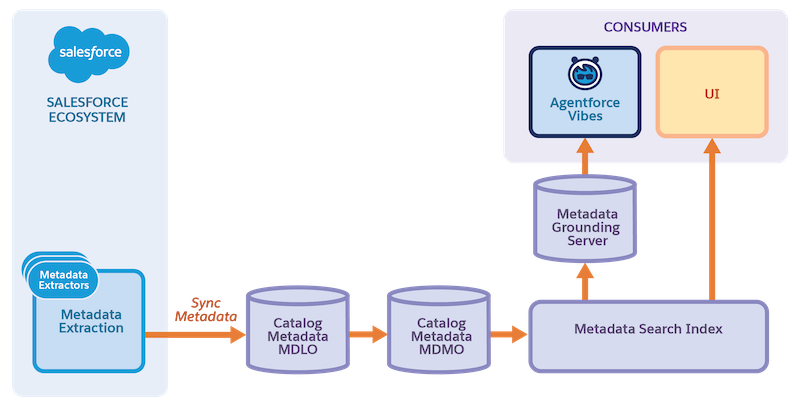
After you turn on Salesforce Catalog, Data 360 runs an initial full sync to extract and ingest your org's metadata. Provisioning the catalog can take time depending on the size of your org.
After the initial sync completes, Salesforce Catalog keeps your metadata current through two mechanisms:
- **Incremental metadata sync**: For supported metadata types, Salesforce Catalog detects changes as they happen, such as adding a custom field, modifying an object, or updating an agent definition. It updates the catalog without waiting for the next scheduled refresh.
- **Daily full refresh**: Every 24 hours, Salesforce Catalog runs a complete metadata refresh to ensure coverage across all metadata types, including types not yet supported by incremental sync.
# Metadata Grounding Capabilities
With metadata grounding, you discover, understand, and reuse metadata through natural language interactions. Metadata grounding capabilities accelerate development and customization by making your Salesforce ecosystem accessible and actionable.
Key capabilities include:
- **Discover Metadata:** Use natural language to search across your metadata. Powered by Data 360 hybrid search, find relevant objects, fields, and metadata components by using semantic and keyword searches via the Metadata Grounding Model Context Protocol (MCP) server. For example, search for "fields related to lease end date or contract expiration" or "Which objects track reservations or bookings?" without knowing exact API names or browsing through the setup.
- **Understand Metadata**: Get clear explanations of what metadata represents and how it functions in Salesforce. Understand the purpose of custom objects, the meaning of field names, security configurations, and how components solve specific business problems. Use this contextual understanding to make informed decisions about reusing existing metadata versus creating configurations. For example, ask “What does the Lease End Date field track?”
- **Reuse Metadata:** Use existing metadata patterns to create customizations quickly. Reference working configurations as templates for new fields, objects, or metadata components. Use existing patterns to configure other metadata types, such as building flows that reference specific fields, create page layouts with existing components, or write metadata validation rules based on your existing data model.
For more information on Metadata Grounding MCP Server, see [Metadata Grounding MCP Server (Beta)](https://developer.salesforce.com/docs/platform/hosted-mcp-servers/guide/metadata-grounding.html).
# Metadata Ownership in Connected Orgs
An object is owned by the org in which it originated, even when it's shared with Data 360 or from Data 360 to other connected orgs. You can only edit or delete data in the org that owns it.
The Owned by Connection field identities the org that owns a record using the org’s connection name. You can only modify a record in the org that owns it even if it’s shared in a shared data space.
Records owned by the home org can be referenced by companion orgs that have access to the data space. You can clone records owned by companion orgs, however, but they can’t be referenced by any other orgs, even if they’re in a shared data space.
# Metrics on Metrics
Organize complex Calculated Insights (CI) SQL data into logical steps and stitch powerful workflows. With metrics on metrics you can improve and reuse metrics for multiple scenarios.
You can create metrics in your metrics for more complex expressions in Calculated Insights. Build comprehensive insights such as customer engagement scores, health scores, and attribution scores. And you get metrics with calculations at multiple levels.
You can use the capability to build higher scores and improve metric reuse such as to calculate the email open count per customer.
```sql
SELECT
COUNT(ssot_EmailEngagement_dlm.ssot_Id_c) as email_open_count_c,
ssot_Individual_dlm.ssot_Id_c as customer_id_c
FROM
ssot_Individual_dlm
JOIN ssot_EmailEngagement_dlm
on (ssot_Individual_dlm.ssot_Id_c = ssot_EmailEngagement_dlm.ssot_IndividualId_c)
WHERE ssot_EmailEngagement_dlm.ssot_EngagementChannelActionId_c = ‘Open’
GROUP BY customer_id__c
```
Then use the metrics (`Email_Open_Count`) to create another calculated insight to group customers.
```sql
SELECT
NTILE (50) over (ORDER BY SUM( NTO_Email_Open_Count_cio.email_open_count_c ) desc) as
customerengagementbuckets_c,
NTO_Email_Open_Count_cio.customer_id_c as customer_id_c
FROM
NTO_Email_Open_Count_cio
GROUP BY customer_id__c
```
# Migrate Data Cloud Permission Sets using User Access Policies
Learn how to use user access policies to grant updated Data Cloud permission sets to groups of users based on criteria you set.
### Required Editions
User Permissions
Needed
To modify user access policies:
Manage User Access Policies
Follow these steps to migrate all users assigned to a specific permission set to a new permission set.

Note New permission sets become available on a rolling basis starting on September 4, 2025. For more information about the new permission sets, see these resources.
- [Refine User Access with New Data Cloud Standard Permission Sets](https://help.salesforce.com/s/articleView?id=release-notes.rn_cdp_2025_summer_new_perm_sets.htm&release=256&type=5&language=en_US)
- [Data Cloud Permission Set Transition Guide](http://sfdc.co/samergeguide)
- [Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&release=264.0.0&type=5 "A permission set defines the level of access and visibility that Salesforce users have to data and features in Data 360. Depending on your license, there are several standard permission sets provided for Data 360. The Salesforce admin assigns permission sets to users. We don’t recommend creating a custom permission set for Data 360 access, however you can combine the permissions sets with other Salesforce permission sets.")
To migrate subsets of users, add additional criteria to define your subgroups.
1. From Setup, in the Quick Find box, enter User Management Settings, and then select User Management Settings. Make sure that both the User Access Policies and Enhanced Interface for User Access Policies settings are enabled.
2. In the Quick Find box, enter User Access Policies, and then select **User Access Policies**.
3. Click **New User Access Policy**.
4. Enter a value for the Policy Name and Description.
5. Click **Save**.
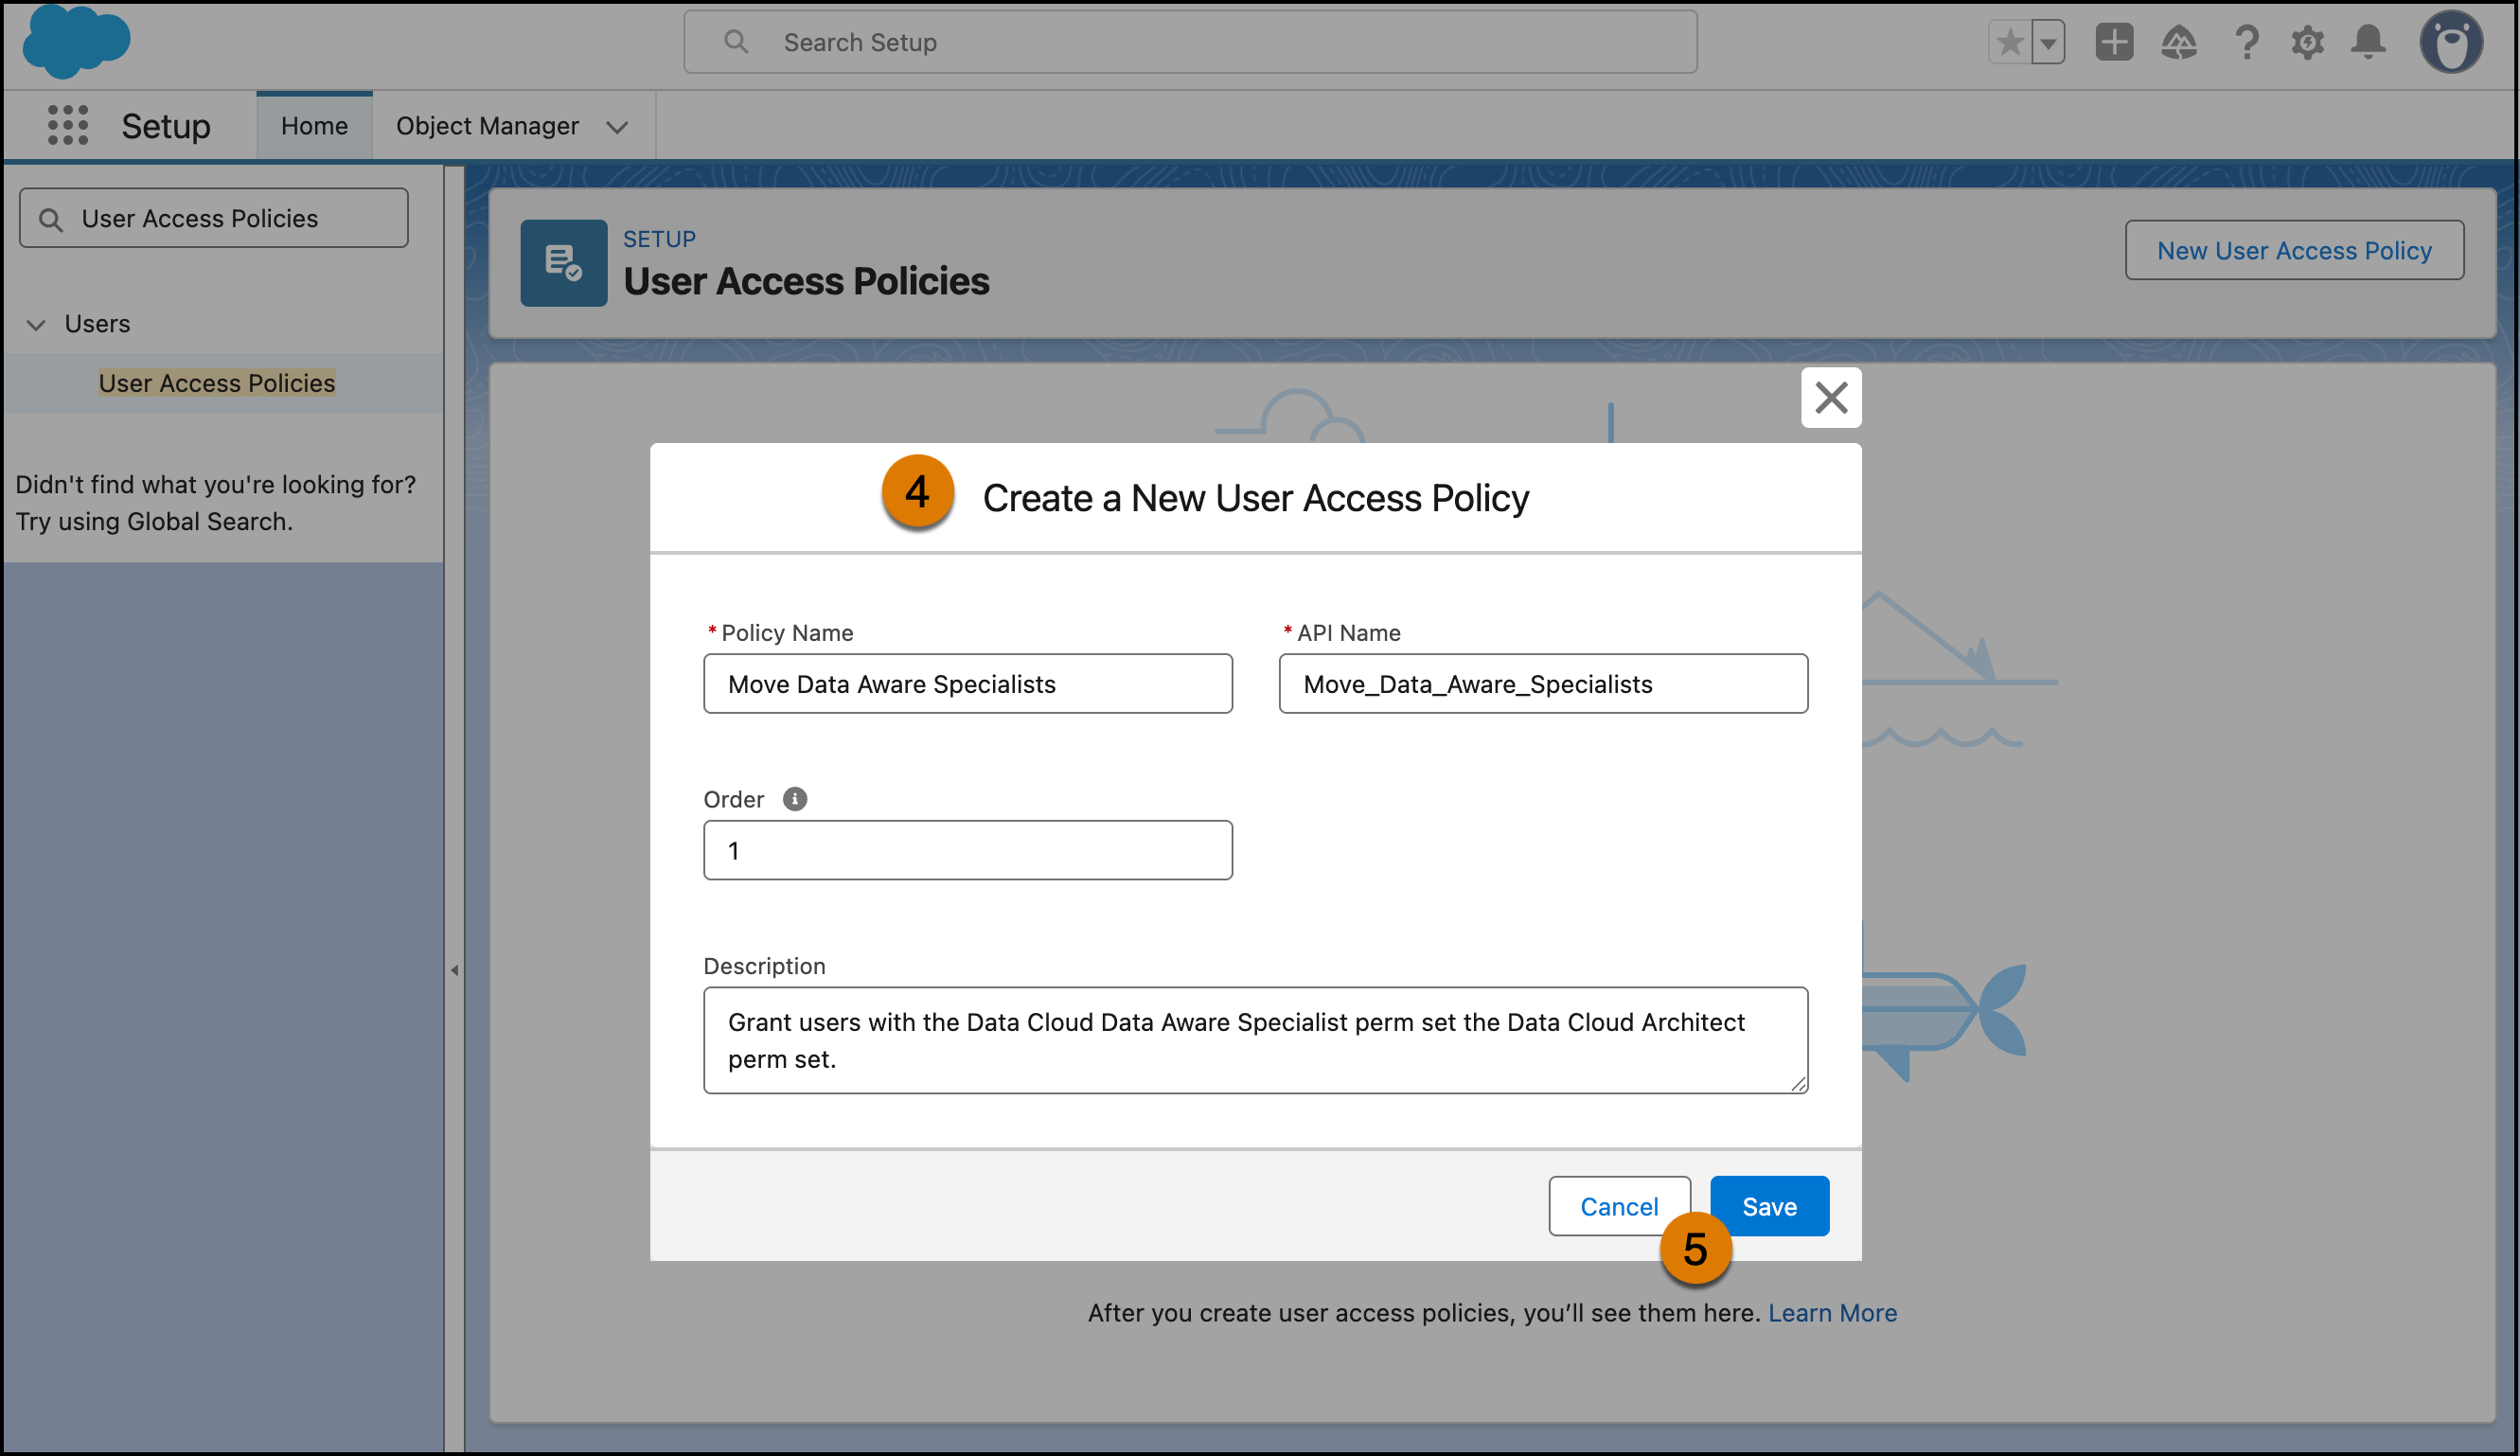
6. On the user access policy’s detail page, click **Edit Criteria** to configure the policy’s user criteria filters and actions.
7. For Define User Criteria, select the following.
1. For Resource, select Permission Set
2. For Operator, select Equals
3. For Value, select the API name of the permission set users currently have.
8. For Define Actions, select the following.
1. For Action, select Grant.
2. For Target, select Permission Set.
3. For Value, select the API name of the permission set you want to grant to users. For a list of permission set API names, see the [Data Cloud Permission Set Transition Guide](http://sfdc.co/samergeguide).
9. Click **Save**.
10. Click **Apply Policy**. You can select a subset of users to apply the policy to, or click **Apply to All**.
To confirm that the users were granted access correctly, review their individual user records. On the policy’s detail page under Recent User Access Changes, you can see when this policy was applied and the affected users.
After you’ve assigned new permission sets, use user access policies to revoke old perm sets.
#### See Also
- [_Salesforce Help_: Manually Grant or Revoke Access with a User Access Policy (Beta)](https://help.salesforce.com/s/articleView?id=platform.perm_manual_user_access_policies.htm&type=5&language=en_US)
# Migrate Data Shares with Legacy Snowflake Data Share Target
Move data shares that are linked to a legacy Snowflake data share target to a Snowflake V2 data share target. Verify that data sharing works before you unlink the legacy target.
### Required Editions

Important Don’t unlink an existing data share from its legacy Snowflake data share target until you verify that the Snowflake V2 connection works. Downstream processes in Snowflake can refer to the database that was created using the legacy target.
User Permissions Needed
To link or unlink data shares:
Data Cloud Architect permission set
Snowflake V2 data share targets replace legacy Snowflake data share targets. Migrate each data share that’s linked to a legacy Snowflake data share target to a Snowflake V2 data share target.
1. In Data 360, go to the Data Shares tab.
2. Select a data share that’s linked to a legacy Snowflake data share target.
3. Link the data share to a Snowflake V2 data share target.

Note If you see an error stating that you can link only to data share targets of the same type, ignore it. This is a known issue and doesn't block the migration. Click **Save** to continue.
For more information, see [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.").
4. On the data share’s record home page, confirm that the Snowflake V2 data share target is linked. Then, in Snowflake, confirm that the Snowflake V2 database contains the same objects and data as the legacy database.
5. In Snowflake, swap the Snowflake V2 database into the name used by your existing pipelines and dashboards.
This swap keeps downstream references working. For the automated skill and the SQL function, see [Snowflake documentation](https://docs.snowflake.com/en/user-guide/data-integration/zero-copy/salesforce/migrate-legacy-share).
6. On the data share’s record home page, click **Link/Unlink Data Share Target**.
7. Deselect the legacy Snowflake data share target.
When you unlink the legacy target, you will see a warning to delete the database in the data share target account before you unlink it. For this migration, don’t delete the database. You already swapped the Snowflake V2 database into the existing database name, so you can ignore the warning and click Continue.
8. Click **Save**.
# Migrate Users from a Customer Data Platform License to a Data Cloud License
When you add a Data Cloud license to an org that was previously operating Data 360 under a Customer Data Platform license, the permission sets granted by the Customer Data Platform license no longer grants access to Data 360. To provide users continued access to Data 360, you must assign the permission sets associated with the Data Cloud license to your users.
### Required Editions
User Permissions Needed
To assign permission sets:
Assign Permission Sets
AND
View Setup and Configuration
1. Identify which Data Cloud permission sets are associated with the Data Cloud license.
2. Optionally, customize the standard permission sets granted by the Data Cloud license or create custom permission sets from them.
3. Assign the permission sets granted by the Data Cloud license to users.
To automate the process, use [User Access Policies](https://help.salesforce.com/s/articleView?language=en_US&id=sf.perm_manual_user_access_policies.htm&type=5) to migrate permission sets for groups of users.
4. Remove the permission sets granted by the Customer Data Platform license.
To automate the process, use [User Access Policies](https://help.salesforce.com/s/articleView?language=en_US&id=sf.perm_manual_user_access_policies.htm&type=5) to migrate permission sets for groups of users.
# Model Endpoint Formats
To connect a predictive model and get inferences, you must use the relevant endpoint request and response formats.
## Request Format
The endpoint format to request data. A request is a client's request to a specific URL or endpoint on a server. This request includes the HTTP method, headers, parameters, and, if applicable, a request body.
## Response Format
The endpoint format to request a response to a client request. The response includes the HTTP status code indicating the success or failure of the request, and headers providing metadata about the response. If applicable, it includes a response body containing the requested data or additional information.
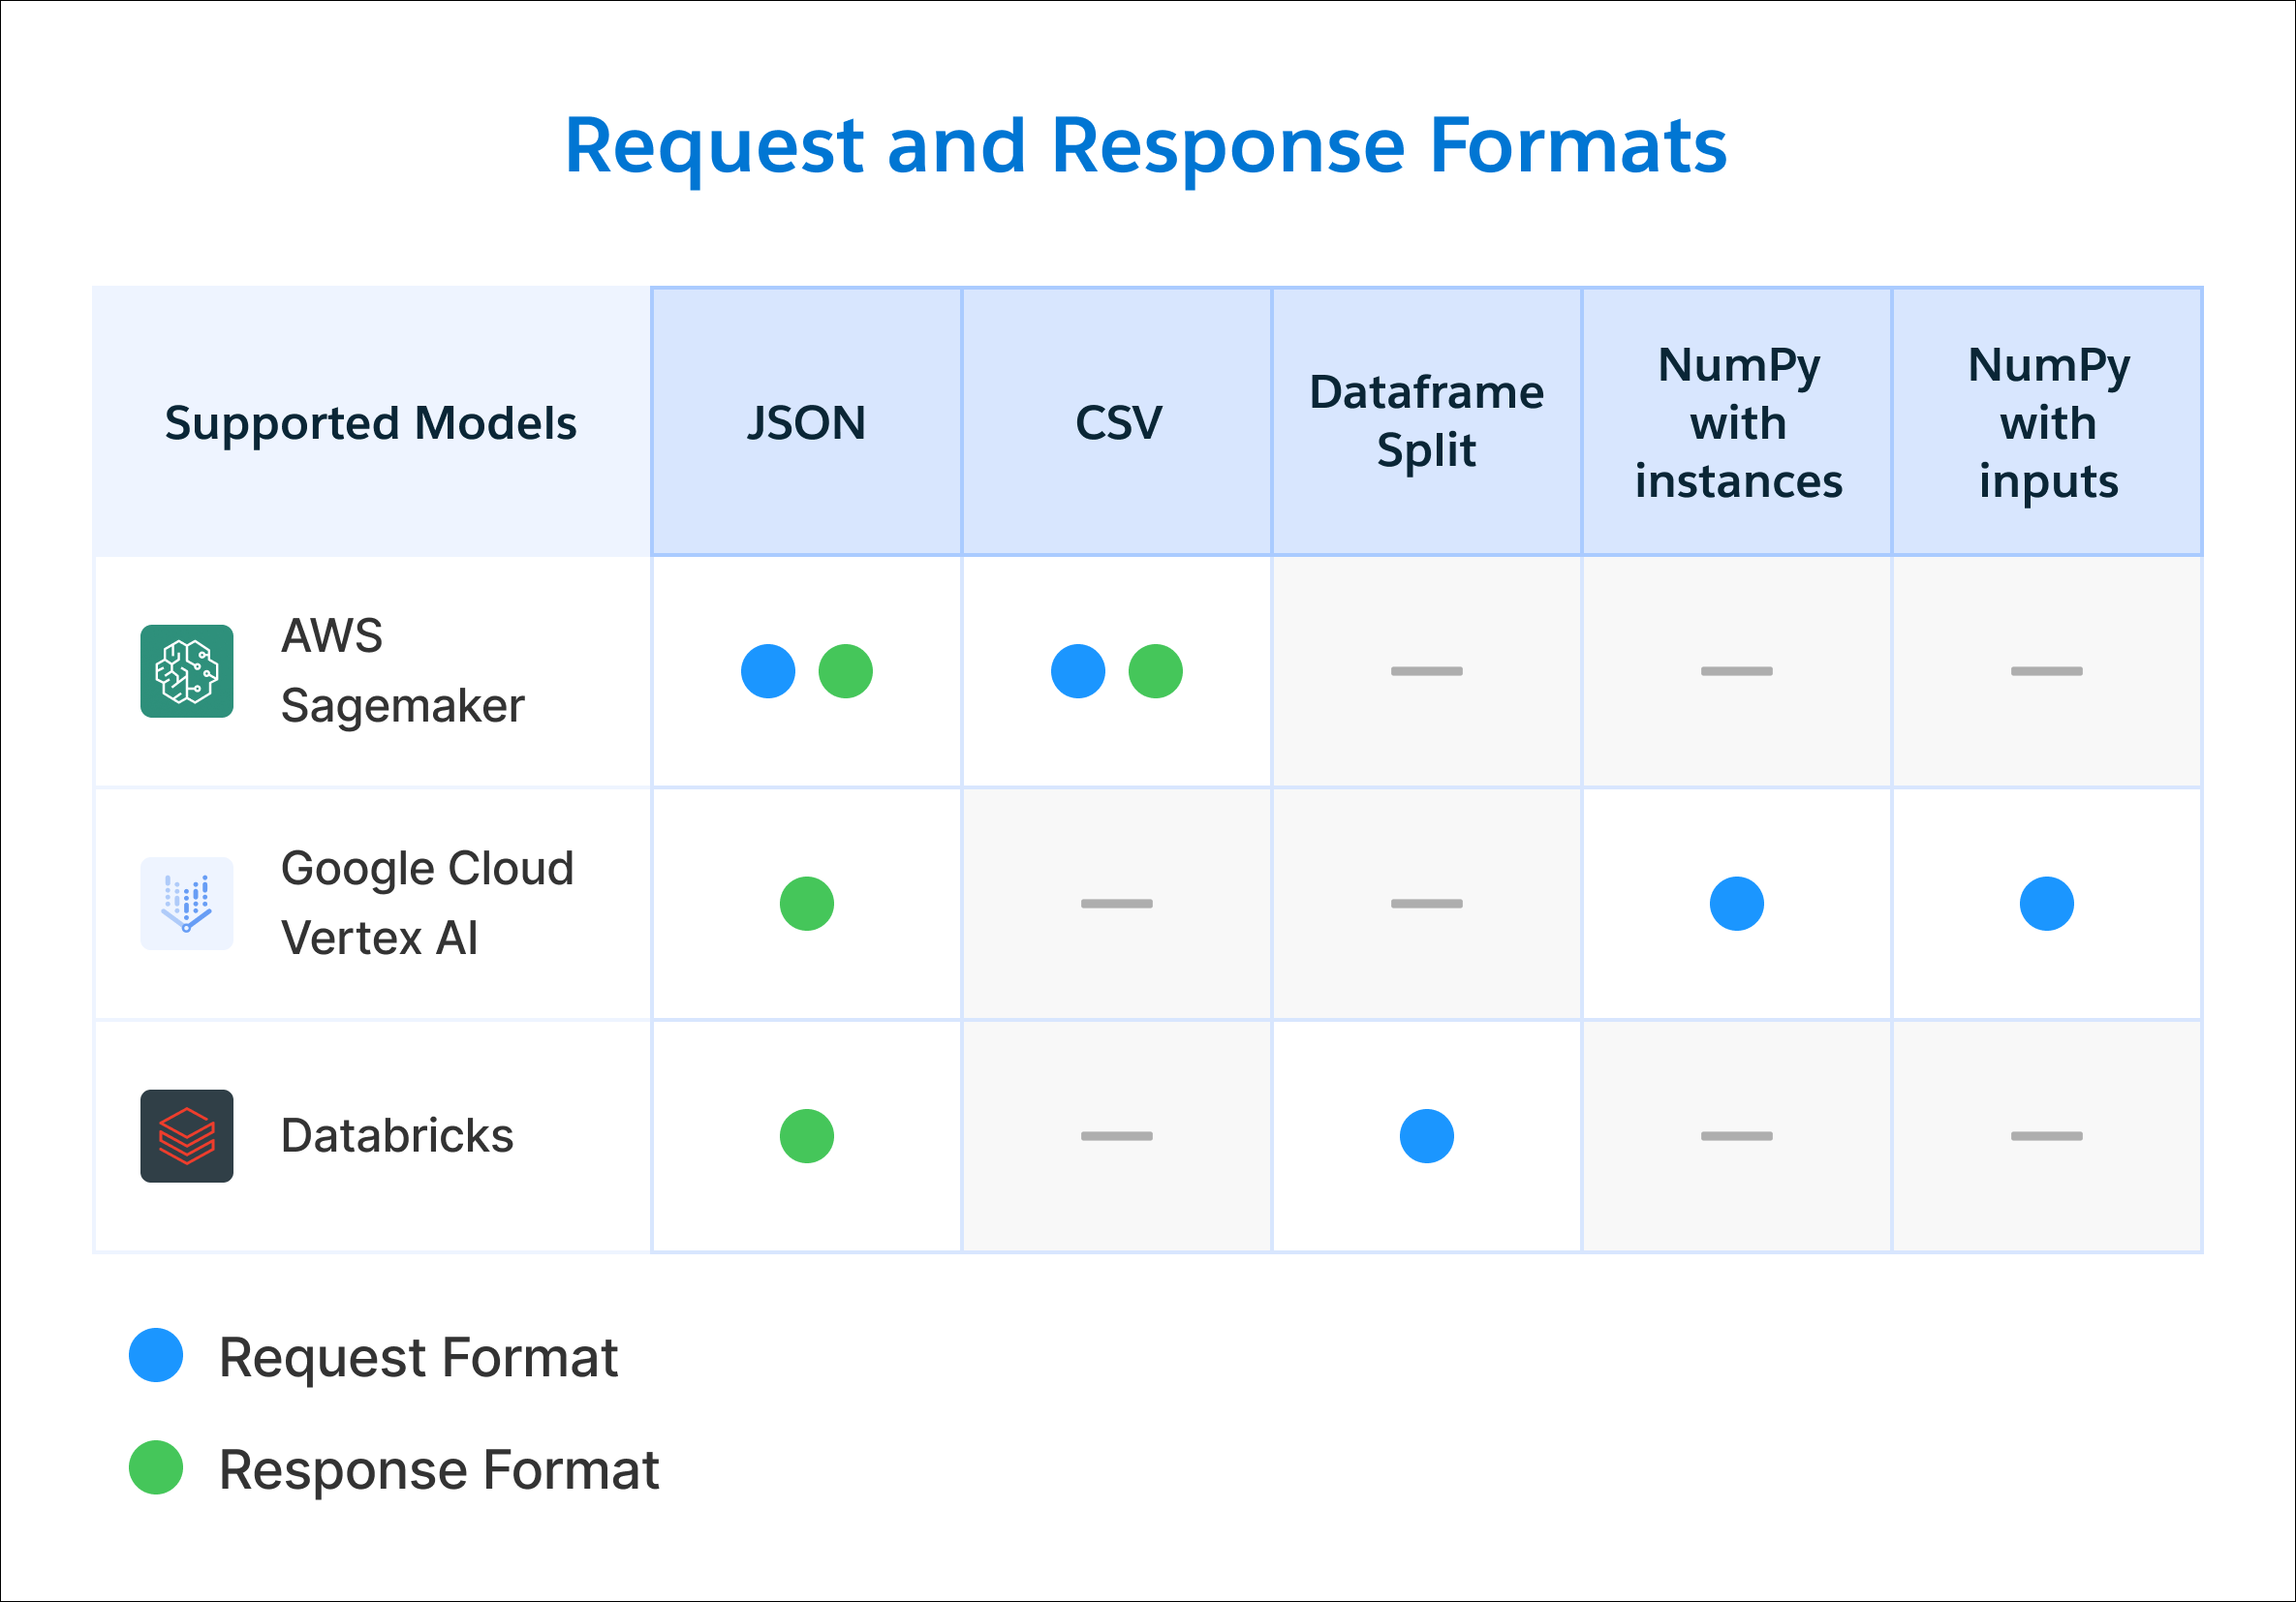
# Model Lineage in AI Models
Model lineage provides a traceable history of an AI model's lifecycle, from training data, versioning, deployment, and its use with live data. Data 360 integrates this capability in AI Models (formerly Einstein Studio) and Governance.
In AI Models, you can see a predictive model's downstream visibility on its details page and in the Integrations tab. This view is vital for creating auditable, reproducible, and trustworthy assets because it clearly details the model's usage, dependencies, and integrations. While the model details show some metadata at the top of the page, the integrations are inference channels used by a model through its lifecycle.
Metadata
Each integration shows the model status (active or inactive), type, last run date, run status, and data model objects (DMOs)**.**
You can view these inference channels in the Integrations tab.
- Batch Data Transforms: Data transforms that use the AI node for inferences.
- Flows: Flows that reference the model by using Data 360 actions.
- Predict jobs: Streaming or batch jobs used for inferences.
- Personalization Maps: Predictions from models used in Salesforce Personalization targeting rules to refine personalization decisions.
Insights from these integrations provide:
**Operational Efficiency**
The list view consolidates this information in one single location and it drastically reduces investigation time.
**Impact Analysis**
Before retraining or deleting a model, you can immediately see which business processes (such as a specific flow or transform) the change impacts.
**Direct Navigation**
The view provides access to each integration for quick edits or troubleshooting.
# Model Your Contact Data for Omnichannel Journeys
This solution kit is designed for customers who have implemented single-channel contacts in Marketing Cloud Engagement. Customers who have implemented single-channel contacts in Marketing Cloud Engagement must follow this solution kit to execute omnichannel journeys. Determine whether you’ve implemented omnichannel or single-channel Contacts.
## Omnichannel Contacts
If your Contacts are already configured as Omni-Channel contacts, congrats! Your Marketing Cloud Engagement SubscriberKeys can natively execute each channel within an Omni-Channel journey. In the context of this solution kit, Omni-Channel contacts have a shared SubscriberKey that you can use across all three channels.
In this scenario, the person John Smith is represented by the single SubscriberKey John.Smith in Marketing Cloud. The SubscriberKey has an associated address stored in Marketing Cloud Engagement for each channel: email, SMS, and MobilePush.
Marketing Cloud Engagement Contact
System
SubscriberKey: John.Smith
Email Channel Contact
SMS Channel Contact
MobilePush Channel Contact
EmailAddress
PhoneNumber
DeviceID
john.smith@example.com
555-123-1234
bac87c7c-3d40-472f-8dd6-d5cb0bc9f40c
If you’ve implemented Marketing Cloud Engagement in this way, you could use Data 360 to activate a single channel for an Individual without using Identity Resolution and successfully deliver messages to email, SMS, and MobilePush channels. Because the contact is already unified in Marketing Cloud Engagement, the SubscriberKey is shared by all channels. Journey Builder can use the SubscriberKey value John.Smith to look up the default send addresses stored in Marketing Cloud Engagement for each channel and deliver messages to them.
## Single-Channel Contacts
Customers commonly implement Marketing Cloud Engagement using single-channel contacts. Each SubscriberKey has an address for one or two channels but not all three channels.
In the context of this solution kit, single-channel contacts have a unique SubscriberKey for each of the three channels.
This example illustrates a series of separate single-channel contacts within Marketing Cloud Engagement. In this scenario, the person John Smith is represented by three different SubscriberKeys in Marketing Cloud Engagement: John.Smith.Email, John.Smith.SMS, and John.Smith.MobilePush. In this case, the SubscriberKeys can’t execute each channel within an Omni-Channel journey.
Marketing Cloud Engagement Contact
System
SubscriberKey: John.Smith.Email
SubscriberKey: JohnSmith.SMS
SubscriberKey: John.Smith.MobilePush
Email Channel Contact
SMS Channel Contact
MobilePush Channel Contact
EmailAddress
PhoneNumber
DeviceID
john.smith@example.com
555-123-1234
bac87c7c-3d40-472f-8dd6-d5cb0bc9f40c
For example, because the customer has separate SubscriberKey values for each channel, Journey Builder can use only the SubscriberKey value John.Smith.Email to retrieve and send to the default send address stored in the Marketing Cloud Engagement email channel. In this instance, SubscriberKey John.Smith.Email sends to email john.smith@example.com. However, this same SubscriberKey can’t send to SMS contact 555-123-1234 or MobilePush SubscriberKeybac87c7c-3d40-472f-8dd6-d5cb0bc9f40c.
If you’re using single-channel contacts, follow this solution kit to use Data 360 to build a Unified Individual that represents a single person consisting of separate Individuals with different contact points. You can then use Data 360 to orchestrate an Omni-Channel journey in Marketing Cloud Engagement.

Note It’s common for customers to implement Marketing Cloud Engagement so that the person is represented by two different contacts. One contact supports two channels, for example, SubscriberKey John.Smith.1 is used by email and MobilePush. The other contact supports a third channel, for example, SubscriberKey John.Smith.2 is used by SMS. We recommend following this solution kit to learn how to relate these two separate contacts within Data 360.
# Monitor Data 360 Companion Connections
Review the status of Data 360's connections, and check which data spaces are shared with each companion org.
1. Go to **Data Cloud Setup**.
2. Select **Data Cloud One**.
3. On the Data Cloud One Companion Connections page, select **Companion Connections**.
4. To check which data spaces are shared, click the connection name.
5. To identify your home org, click **Home Org Details**.
- **[Data Cloud One Companion Connection Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connection_statuses.htm&release=264.0.0&type=5)**
These statuses indicate how companion connections are functioning.
- **[Version Mismatch Errors in Data Cloud One Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_version_mismatch.htm&release=264.0.0&type=5)**
Data Cloud One supports mixed versions between home and companion orgs, but version mismatches can cause temporary metadata syncing delays in some circumstances. Metadata syncing between a home org and its companion org can be delayed when an object's schema changes between minor Salesforce versions. You can continue using all previously synced metadata even when syncing is in a temporary error state. Version mismatch errors resolve themselves as soon as both orgs upgrade to the same version.
# Monitor Model Activity
View your model inference use and errors in a dashboard. Use important indicators to help you track, adjust, and improve model performance.
To monitor the performance of a model that you configured, go to AI Models (formerly Einstein Studio) Model Home. Select the model and refer to the Model Activity tab.
## Inferences
A foundation model is pretrained on large datasets, but it also learns from prompts during inference when generating human-like text or performing specific language-related tasks. It’s important to adapt your model and fine-tune hyperparameters for domain-specific requirements. When doing so, factor in model efficiency, deployment infrastructure, and ethical implications.
The model activity provides a snapshot of total inferences from all configured models that you used in a specific period.
## Errors
Errors can occur during the operation and deployment of the model. The errors can impact the performance, reliability, and security of an LLM in real-world applications. Common issues include inaccurate or biased responses, latency, and scalability issues.
# Monitor the Event Activity of a Data Action
Track key metrics for a data action, such as events identified, processed, published, and failed in the Event Activity dashboard. Get enhanced visibility into your data as it moves through the data action pipeline in near real time. This gives you transparency around the volume of events and data delivery.
### Required Editions
User Permission Sets
Needed
To monitor a data action:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, go to the Data Actions tab.
2. Select a data action and go to the Event Activity tab.
3. Select the time interval to view events.
- **Events Identified** - The approximate number of events for the changes in the primary object on which the data action is created. For example, 1 million records in a Data Model Object (DMO) are changed.
- **Events Processed** - The approximate number of events after applying filters set in the data action. For example, 0.5 million records are eligible for action after the filter condition is applied.
- **Events Published** - The approximate number of change events published to the data action target. For example, 0.4 million records are successfully sent to the target.
- **Events Failed** - The approximate number of events that failed during processing or publishing. For example, 0.1 million records failed due to various publishing issues and weren’t consumed by the customer.

Note
Metrics shown in the dashboard are based on recent data changes and are approximate. The dashboard doesn't reflect changes that occurred in the last few minutes.
# Monitor the Status of Unstructured Connectors Data Ingestion
You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.
The topics included here are general in nature and can be used for all unstructured connectors. For specific troubleshooting issues, consult the documentation for the specific connector.
Choose a topic to continue:
- [Check Connector Status](https://help.salesforce.com/s/articleView?id=data.c360_a_check_connector_status.htm&release=264.0.0&type=5 "Get the current status of your Web Content (Crawler or Sitemap) connector.")
- [Find How Many Pages Synced Successfully](https://help.salesforce.com/s/articleView?id=data.c360_a_find_how_many_pages_synced_successfully.htm&release=264.0.0&type=5 "Determine the total number of records ingested during each Web Content (Crawler or Sitemap) connector run.")
- [Find How Many Records of a Specific Type Synced Successfully](https://help.salesforce.com/s/articleView?id=data.c360_a_find_how_many_records_of_a_specific_type_synced_successfully.htm&release=264.0.0&type=5 "Determine how many records of a specific file type (for example, HTML, PDF, and images) from the Web Content (Crawler or Sitemap) connector were ingested.")
- [Find Which Pages Synced Successfully](https://help.salesforce.com/s/articleView?id=data.c360_a_find_which_pages_synced_successfully.htm&release=264.0.0&type=5 "View the details of the pages and attachments that were successfully ingested by the Web Content (Crawler or Sitemap) connector.")
#### See Also
- [_Salesforce Help_: Check Connector Status](https://help.salesforce.com/s/articleView?id=data.c360_a_check_connector_status.htm&release=264.0.0&type=5 "Get the current status of your Web Content (Crawler or Sitemap) connector.")
- [_Salesforce Help_: View the Number of Successfully Synced Pages per Connector Run](https://help.salesforce.com/s/articleView?id=data.c360_a_find_how_many_pages_synced_successfully.htm&release=264.0.0&type=5 "Determine the total number of records ingested during each Web Content (Crawler or Sitemap) connector run.")
- [_Salesforce Help_: Find How Many Records of a Specific Type Synced Successfully](https://help.salesforce.com/s/articleView?id=data.c360_a_find_how_many_records_of_a_specific_type_synced_successfully.htm&release=264.0.0&type=5 "Determine how many records of a specific file type (for example, HTML, PDF, and images) from the Web Content (Crawler or Sitemap) connector were ingested.")
- [_Salesforce Help_: List Which Pages Synced Successfully](https://help.salesforce.com/s/articleView?id=data.c360_a_find_which_pages_synced_successfully.htm&release=264.0.0&type=5 "View the details of the pages and attachments that were successfully ingested by the Web Content (Crawler or Sitemap) connector.")
# Monitoring Data Stream Problem Records
Records that can’t be ingested into Data 360 due to data quality issues are logged as problem records and stored in a problem record data lake object (DLO). Problem records are created when data is ingested through: all structured ingest connectors, Web and Mobile App connectors, and Ingestion APIs.
## Problem Record Considerations
- The problem record DLO is named `PR_DLO_Name`. The name indicates the data stream that the record is associated with.
- Data 360 stores problem records for 30 days. However, if you delete a data stream with problem records before the 30 days, its problem record DLOs are also deleted.
- You can’t package problem record DLOs.
- You can use a problem record DLO as an input to a data transform but not as an output.
- The data stream Refresh History tab lists all problem records related to data stream ingestion from a data source.
- You can query the DLO using Data Explorer, the Query Editor, or Query API.
## Example of a Problem Record DLO Payload
```json
"error_context__c": "{"dataStreamJobId":"ec579524-993f-433f-b3bd-48114a9f4ac5","sourceFile":"bad_row.csv"}",
"error_code__c": "TRANSFORM_EVALUATION_ERROR",
"error_timestamp__c": "2024-02-23T17:50:33.547Z",
"detailed_error__c": "{"errorMessage":"Transformation error","additionalInfo":{"transformationErrors":[{"fieldName":"datetime__c","errorMessage":"INVALID_DATE_FORMAT - Cannot parse source field DateTime with value \\"abc-ef-gh 03:03:03\\" using common date patterns"}]}}",
"error_row"__c: "{"id__c":"3","firstname__c":"Loree","datasourceobject__c":"s3://dev1-uswest2-cdp001-test-data/jack/person/person_with_invalid_date_time.csv","internalorganization__c":null,"lastname__c":"Drewski","datasource__c":"jack_person_with_invalid_date_time_csv_2","datetime__c":null}",
"error_fields__c": "datetime__c"
```
## Schema Attributes of a Problem Record DLO
The problem record DLO has these schema attributes.
| Field Name | Field API Name | Field Type | Description |
| --- | --- | --- | --- |
| Id | `id__c` | Text | The auto-generated unique ID used for the primary key. |
| Error Context | `error_context__c` | Text | The JSON string along with the job ID. |
| Error Code | `error_code__c` | Text | Error code string that describes the reason for a record drop. |
| Error Timestamp | `error_timestamp__c` | DateTime | Timestamp of when the error record was ingested in Data 360. |
| Detailed Error | `detailed_error__c` | Text | Additional details about the record error. |
| Error Row | `error_row__c` | Text | Displays the content in the problem record. |
| Error Fields | `error_fields__c` | Text | Displays a concatenated string of all error fields for record rejection. It applies only to fields with error\_code =TRANSFORM\_EVALUATION\_ERROR. |
These are the different error types that result in a problem record.
| Error Code | Description |
| --- | --- |
| `NOT_NULL_CONSTRAINT_VIOLATION` | The record is dropped due to null value in a required field. For example, the primary key value is null. |
| TRANSFORM\_EVALUATION\_ERROR | A partially rejected record. An error occurs during the transformation process of a field. There can be multiple errors in one record processing multiple fields. |
| UNHANDLED\_ERROR | The record is dropped due to an error during row processing. |
| DUPLICATE\_ROW | The record is dropped because multiple records with the same primary key are in the batch. |
# MuleSoft Connectors in Flow
MuleSoft connectors are available within Flow Builder. When configuring an action in your activation-triggered flow, you can select from these connectors. To find the supported connectors and their corresponding actions, see [Third-Party Connectors](https://help.salesforce.com/s/articleView?id=platform.automate_flow_ref_third_party_connectors.htm&language=en_US).
# Multi-Brand Management in Data 360
To manage multiple brands, set up Data 360 across different location tenants.
Data 360 can combine multiple Engagement accounts’ EID data into one Data 360 org.
Within one Engagement EID, you can selectively map multiple business units (BU) to get data flowing into Data 360, which tracks the data lineage of this data. You can also add the data lineage field to filter out different BUs’ data to create a segment with only selected BUs.
Data 360 doesn’t segregate data by users or apply any data filter automatically with the exception of GDPR flags.
For the CRM connector, Data 360 can be installed in any CRM org.

Example If you have CRM 1 with Sales Cloud in the UK and another CRM 2 in France, you can install the Data 360 app into either CRM or a new one. Multiple CRMs’ data can flow into one Data 360 org.
# Multicollinearity Alert
Multicollinearity indicates that two or more variables in a dataset are highly correlated (for example, “city” and “postal code”). Because these variables can have a duplicate impact on the outcome, high collinearity can lead to overfitting—the model performs well on training data but could perform poorly on data that the model hasn't been exposed to yet.
## Actions to Consider
To improve results, choose just one variable. Use the most descriptive field (for example, “city”) to make insights more easily interpretable.
## Detection Methodology
Model Builder displays a data alert when the Cramér’s V algorithm that tests for multicollinearity, returns a value of 0.5 or higher for two variables.
## Example
A real estate agency wants to predict house prices for new listings. To achieve this, the agency builds a regression model with these input variables.
- house size (sq. ft)
- number of bedrooms
- number of bathrooms
- age of house
- neighborhood median income
- renovation status
After model training, an alert displays because the ”house size,” “number of bedrooms,” and “number of bathrooms” variables are highly correlated. As a result, the model can’t determine the importance of each variable, leading to unreliable coefficients. To resolve the issue, here are some actions to consider.
- Exclude one of the correlated variables to improve generalization on data that isn’t yet trained. For example, include “house size” and exclude "number of bedrooms" from the dataset.
- Use variable selection techniques, such as principal component analysis (PCA) or lasso regression, to reduce redundancy.
- Retrain the model with an updated dataset.
# Multiple Identity Resolution Rulesets in Segments
Compare the impact of different identity resolution rulesets for the same entity on segment population counts. After using identity resolution to create different rulesets for the same entity, entities and attributes created by both rulesets are available in segmentation. Use attributes from both rulesets to validate, or A/B test, different population counts. Entities and attributes names include the Ruleset ID at the end when you select what entity to Segment On or add attributes in the attribute library.
Use Identity Resolution to create two different rulesets for the Individual entity. For the first ruleset, use strict match rules. For the second ruleset, use more general match rules and add Ruleset ID fzzy. To build a new segment based on the fzzy ruleset, Segment On **Unified Individual fzzy**.

Tip Use the second ruleset as a temporary way to create the best ruleset for your data, and then delete the second ruleset. Unified profiles from all rulesets count toward your entitlement limit.
# Multiple Marketing Cloud Engagement Business Units in Segments
Filter segments by business unit (BU) to determine the true size of segments for campaign planning. If segments aren’t filtered by business unit, the difference between a Data 360 segment population and Marketing Cloud Engagement data extension count can be significant.
- In Data 360 Setup, make sure that Allow Profile Business Unit Mapping Data is enabled.
1. For new and existing segments, add another rule.
2. Select the Affiliation entity from the attribute library under Related Attributes.
3. Drag the Affiliated To attribute to the segmentation canvas.
4. Use an Is Equal To operator and enter a Business Unit Value (MID) for the segment.
# Multivalue Functions for Formulas
Multivalue data is limited to use in formulas. To work with multivalue data in downstream processes from batch data transforms in Data 360, such as reporting in CRM Analytics, convert it into a string.

Note Formula steps in transforms cannot directly output arrays. Therefore, functions that produce arrays, such as 'sequence', must be combined with functions that process arrays and return non-array results, such as 'explode' or 'array\_join'.
## `array_join`
Converts multivalue data into a string with elements separated by the specified delimiter. If no string is specified for nullReplacement, nulls are ignored.
### Syntax
```
array_join(mvField,delimiter,nullReplacement(optional))
```
### Parameters
- mvField—(Required) the multivalue text column to be converted to a string.
- delimiter—(Required) the value to separate the elements in the string. This can be a field or a text string.
- nullReplacement—(Optional) he value that replaces the nulls. This can be a field or a text string.
### Returns
A string that contains the multivalue data separated by the specified delimiter.
## `explode`
Converts an array into a new column where each element is a row.
### Syntax
```
explode(array)
```
### Parameters
- array—A field or formula expression.
### Example
```
explode(sequence(dateField1, dateField2, interval 6 months))
```
### Returns
Returns one row for each element in the array. The output includes a new field that has the value of each element in the array.
## `sort_array`
Sorts the input array in ascending or descending order according to the natural ordering of the array elements. Null elements will be placed at the beginning of the returned array in ascending order or at the end of the returned array in descending order.
### Syntax
`sort_array(array,ascendingOder)`
### Parameters
- array—(Required) is the array to be sorted..
- ascendingOrder—(Required) sorts the elements as strings in ascending order.
### Returns
The reference to the same array, now sorted.
# Next Steps with Data Cloud
The use cases detailed in this guide give you a glimpse into how you can use Data Cloud to power your unified Customer 360. When you connect and unify more data sources, the more useful your unification, insights, and analytics become.
## Enhance Your Business Use Cases
Embed Insights into Pages
Add cleaned and harmonized data from across your organization to your org through Data Cloud enrichments. Create related list and copy field enrichments for your record pages with data from Data Cloud.

Note Learn how to [Enrich Your Org with 360 Data and Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_enrich_your_org_with_data_and_insights.htm&type=5&language=en_US).
Create Data Cloud-Triggered Flows in CRM Orgs
Create a record-triggered flow to publish platform events of Data Cloud actions. For example, you could create tasks to clean up unified contacts who belong to more than one account or increase revenue and improve relationships by identifying opportunities in priority accounts in near real time

Note Learn how to [Create a Record-Triggered Flow in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_custom_platform_event.htm&type=5&language=en_US).
## Get More Help
Salesforce Professional Services
Professional Services can help you accelerate your time to value with Data Cloud. Get advice and help with planning and implementation, including determining how many Data Cloud instances you need, which orgs to enable Data Cloud on, and setup and configuration.

Note Learn more from [Data Cloud Implementation Packages](https://www.salesforce.com/content/dam/web/en_us/www/documents/services/launch-for-data-cloud-with-formula1.pdf) from Professional Services.
Salesforce Certified Data Cloud Partners
We have a large ecosystem of experienced Data Cloud experts to help support your use cases. Find available apps and experts on [AppExchange page](https://appexchange.salesforce.com/mktcollections/cloud-collections/customerdataplatform).

# Normalize Data with `UNION` Use Case
Normalize data ingested into Data 360 with streaming data transforms.
Let’s look at an example. The source data lake object CRMContacts contains up to three phone numbers for each customer.
| CustomerId | Name | MobilePhone | HomePhone | WorkPhone |
| --- | --- | --- | --- | --- |
| C1 | John | 408-512-2234 | | 650-342-4612 |
| C2 | Peter | | 310-453-3421 | 915-870-9900 |
If the data lake object CRMContacts is directly mapped to the data model object Contact Point Phone, only one contact point—MobilePhone or HomePhone or WorkPhone—can be mapped. As a result, only one of the three phone numbers is available in product areas that consume the data model object, such as calculated insights, identity resolution, and segmentation.
Here’s how to use a streaming data transform to make all three phone numbers available.
```
SELECT CONCAT(CRMContacts.CustomerId, "_Mobile") as PhoneId,
CRMContacts.CustomerId as CustomerId,
CRMContacts.MobilePhone as PhoneNumber,
"Mobile" as PhoneType
FROM CRMContacts
WHERE ISNOTNULL(CRMContacts.MobilePhone) AND CRMContacts.MobilePhone <> ""
UNION
SELECT CONCAT(CRMContacts.CustomerId, "_Home") as PhoneId,
CRMContacts.CustomerId as CustomerId, CRMContacts.HomePhone as PhoneNumber,
"Home" as PhoneType
FROM CRMContacts
WHERE ISNOTNULL(CRMContacts.HomePhone) AND CRMContacts.HomePhone <> ""
UNION
SELECT CONCAT(CRMContacts.CustomerId, "_Work") as PhoneId,
CRMContacts.CustomerId as CustomerId,
CRMContacts.WorkPhone as PhoneNumber,
"Work" as PhoneType
FROM CRMContacts
WHERE ISNOTNULL(CRMContacts.WorkPhone) AND CRMContacts.WorkPhone <> ""
```
After the data transform runs, the target DLO contains one record for each type of phone number.
| PhoneId | CustomerId | PhoneNumber | PhoneType |
| --- | --- | --- | --- |
| C1\_Mobile | C1 | 408-512-2234 | Mobile |
| C1\_Work | C1 | 650-342-4612 | Work |
| C2\_Home | C2 | 310-453-3421 | Home |
| C2\_Work | C2 | 915-870-9900 | Work |
Then, you can map the target Phones DLO to the Contact Point Phone DMO. The Contact Point Phone DMO now contains all three phone numbers for each customer.
To use the `UNION` operator in a streaming data transform, each `SELECT` statement must:
- Reference the same source data lake object. In the example above, all three `SELECT` statements use the same source data lake object CRMContacts.
- Map to the same fields for the target DLO. Each `SELECT` statement must have the same schema. In our example, all three `SELECT` statements map to the same set of fields: `PhoneId`, `CustomerId`, `PhoneNumber`, and `PhoneType`.
- Generate a unique value for the primary key field. If non-unique values are generated for the primary key field, one of the non-unique values is selected randomly. In our example, the `CONCAT()` function generates unique values for the primary key field on the target DLO.
- Have a unique field mapped to a primary key, or a set of fields mapped to a primary key in an expression.
`UNION` can be used with a maximum of five `SELECT` statements.
#### See Also
- [_Salesforce Help_: Normalized and Denormalized Data](https://help.salesforce.com/s/articleView?id=data.c360_a_normalized_and_denormalized_data.htm&release=264.0.0&type=5 "Data originates from multiple sources and can be normalized or denormalized. The Data 360 standard data model is normalized, so incoming data must be normalized before it can be mapped to the data model. Because not all source systems provide normalized export options or normalize data, assess your field-level data to establish how to transform and map the source data to the standard data model.")
# Normalize Denormalized Data Use Case
In this use case, the data comes from a single Marketing Cloud Engagement data extension but must be normalized to map to the Data 360 data model objects (DMO).
The source data has two email addresses and two phone numbers for a customer. However, in the Data 360 data model, you can map only one email address and one phone number to the individual DMO. To retain the customer’s additional contact details, you normalize the contact point data before ingesting it.
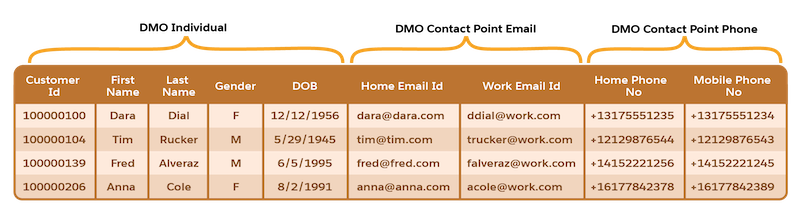
To normalize the data, divide the data into three tables that can map to the Individual DMO, Contact Point Email DMO, and Contact Point Phone DMO and define the relationship between them.
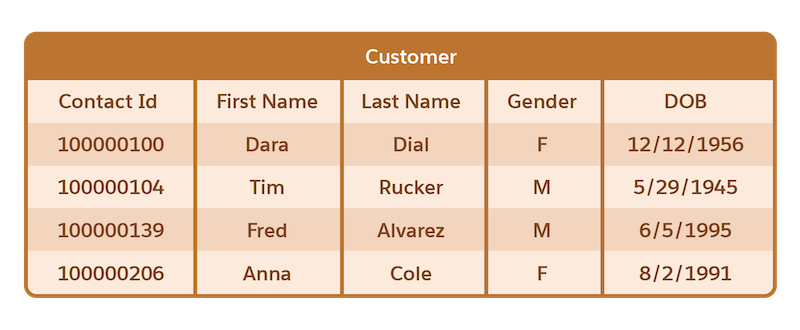
When mapping data to a DMO, each record requires a primary key that uniquely identifies it across all the data sources.
To map attributes to the Contact Point Email and Contact Point Phone DMO, you need more than the Contact Id value, because you’re ingesting multiple email addresses and phone numbers for a single Contact Id. Therefore, you extend the data at ingestion through the use of formula fields and generate primary keys.
To map to the Contact Point Phone DMO, create a primary key CP\_Phone\_Id using a composite key by concatenating the Contact Id and Phone Number fields. This primary key is a representative example of how primary keys can be generated at ingestion time using formula fields.
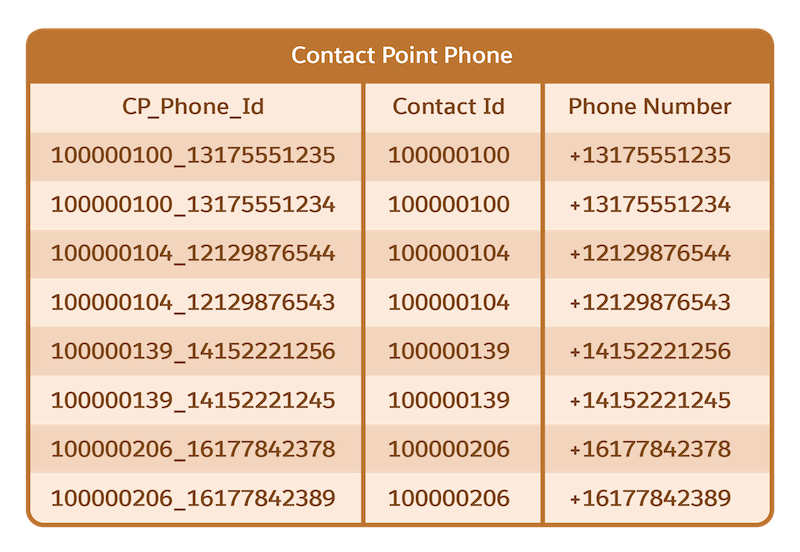
Similarly, to map to the Contact Point Email DMO, create a primary key CP\_Email\_Id using a composite key by concatenating the Contact Id and Email Address fields.
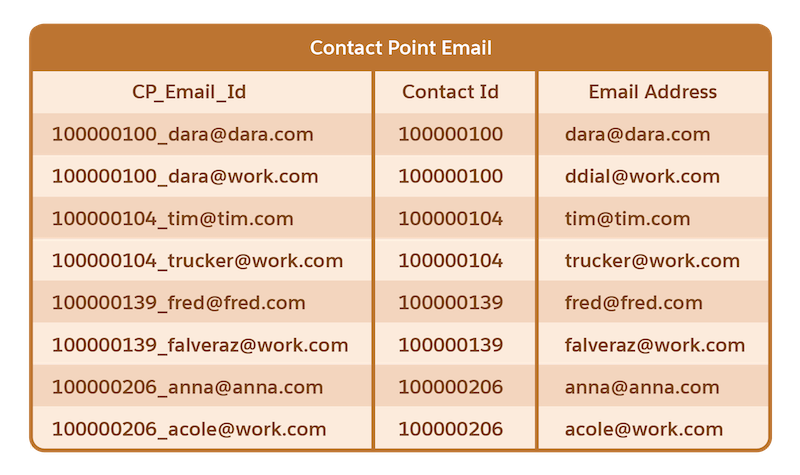
# Normalized and Denormalized Data
Data originates from multiple sources and can be normalized or denormalized. The Data 360 standard data model is normalized, so incoming data must be normalized before it can be mapped to the data model. Because not all source systems provide normalized export options or normalize data, assess your field-level data to establish how to transform and map the source data to the standard data model.
Normalized data is divided into multiple tables with established relationships to reduce redundancy and inconsistency.
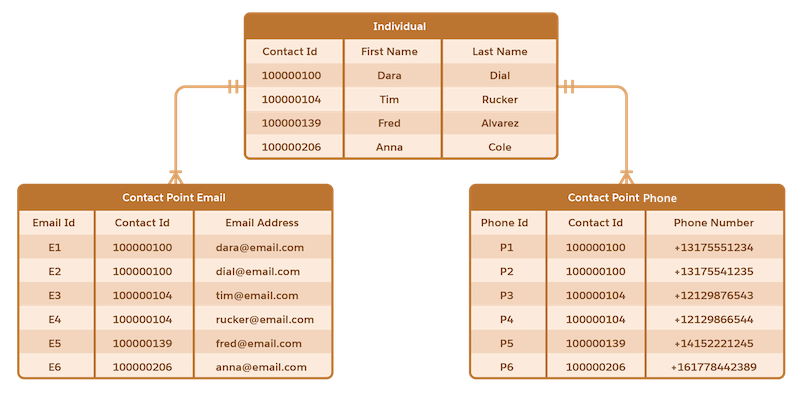
Denormalized data is combined into a single table to make data retrieval faster. The rows contain relational data as column attributes. This format is commonly known as a spreadsheet view, and Marketing Cloud Engagement data extensions have the same format.
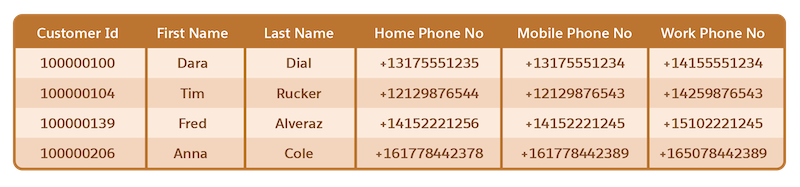
#### See Also
- [_Salesforce Help_: Use Case Normalize Denormalized Data](https://help.salesforce.com/s/articleView?id=data.c360_a_uc_normalize_denormalized_data_from_marketing_cloud.htm&release=264.0.0&type=5 "In this use case, the data comes from a single Marketing Cloud Engagement data extension but must be normalized to map to the Data 360 data model objects (DMO).")
# Notation for String Formulas
If you manually type your formulas, use single quotes `‘` for string literals and double quotes `“` for joined fields with dot notation or reserved keywords.
# Now
Create a column that displays the current date and time in a specified format. This transformation works without interacting with any other columns.
1. In a Transform node of a batch data transform select the Formula button () in the Transform toolbar.
2. Select **Now**.
3. Select the date format.
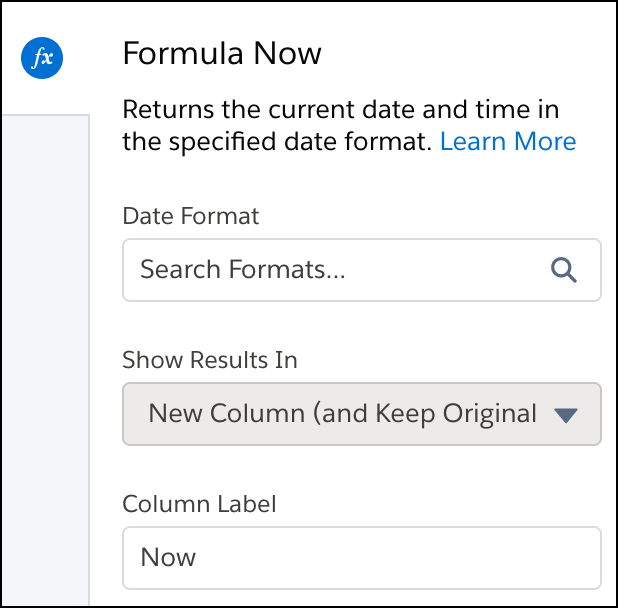
4. Optionally, change the label of the column that stores the Now data in the Column Label field.
5. To add the transformation to the Transform node, click **Apply**. The Preview tab shows the new Now column.
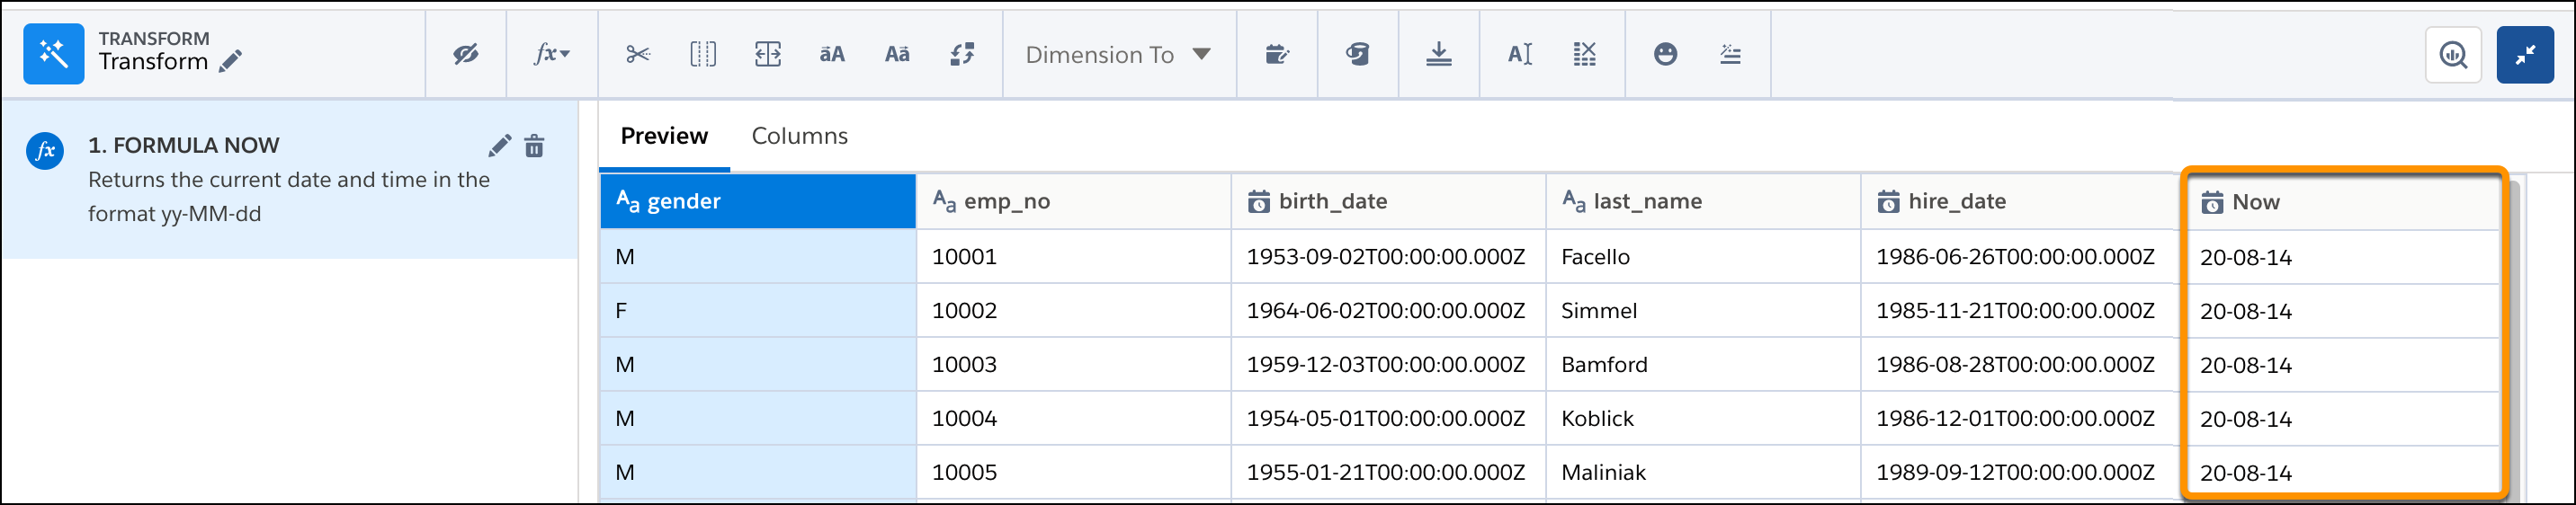
6. To view the canvas area, click the Collapse button ().
The Now option uses the date and time when the batch data transform last ran, based on the UTC timezone.
# Number to Text Transformation: Convert the Column Type
To group and filter by a numeric column, use the Number To Text transformation. You can group and filter by text columns only.
1. In the Transform node, select the number column that you want to convert to the Text column type.
2. In the Transform toolbar, select **Number to** | **Text**.
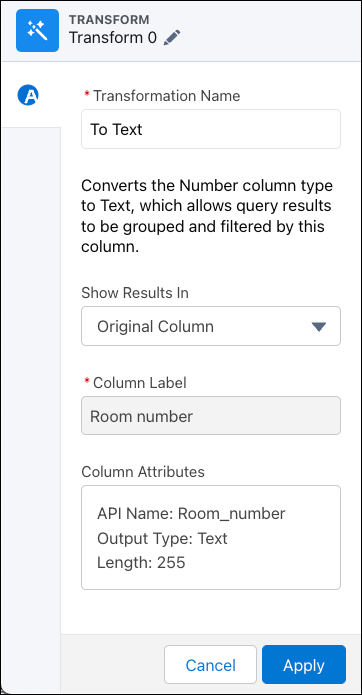
3. Under Show Results In, select whether the new values appear in a new column and whether to keep the original column.
4. If you elect to create a column, set the label under Column Label.
5. To change more column attributes, click the **Column Attributes** box, change them, and click **Apply**.
6. Based on the output column’s datatype, you can set these attributes.
Attribute
Description
API Name
The API name of the column. The column API name can each be up to 255 characters.
The API name must also be unique within the batch data transform.
Precision
The maximum number of digits in a numeric column. Includes all numbers to the left and
to the right of the decimal point (but excludes the decimal point character). Enter an
integer between 1 and 18, inclusive.
If a numeric value exceeds the specified precision, the value is set to 0 or null. For
example, if precision is set to 5, the numeric value is replaced with null.
Scale
The number of digits to the right of the decimal point in a numeric column. Enter an
integer between 0 and 17, inclusive. The scale must be less than the precision. For
example, if the numeric value is 123456.789 and you set the scale to 2, the number appears
as 123456.78.
Length
The maximum number of characters in a text column. Enter an integer between 1 and
32000, inclusive. The default length is 255 characters.
Date Format
The date format of a date column.
For more guidelines, see Field Name Restrictions in [Analytics External Data Format Developer Guide: External Data Metadata Format Reference](https://developer.salesforce.com/docs/atlas.en-us.bi_dev_guide_ext_data_format.meta/bi_dev_guide_ext_data_format/bi_ext_data_schema_reference.htm).
7. To add the transformation to the Transform node, click **Apply**. The Preview tab shows the text column.
8. To view the canvas area, click the **Collapse** button ().
Run the batch data transform to convert the column type to Text.
# Numeric Operators and Functions for Formulas
Use numeric functions to calculate values from measures. For example, you can round, truncate, and determine the absolute value of a number. The arguments for numeric functions can be numbers or measure fields.
When entering a formula, use the API name of the field in the expression, not the label. The parameters section is surrounded by parentheses. For example, you can enter the following expression.
```
round(Total_Amount/Unit_Price, 2)
```
You can use the following math operators.
| Operator | Description |
| --- | --- |
| + | Calculates the sum of two values. |
| \- | Calculates the difference between two values. |
| \* | Multiplies the two values. |
| / | Divides the first value by the second. |
| () | Specifies that the expressions within the parentheses are evaluated first. All other expressions are evaluated using standard operator precedence. |
You can also use the following numeric functions in an expression.
Numeric Function
Description
Syntax
absCalculates the absolute value of a number. The absolute value of a number is the number
without its positive or negative sign.
abs(field )
field is a number
or measure field that you want to determine the absolute value of.
Example:
abs(Amount)
ceilRounds a number up to the nearest integer.
ceil(field )
field is a number
or measure field that you want to round up to the nearest integer.
expReturns a value for e raised to the power of a number you specify.
exp(field )
field is a number
or measure field to which you want to raise e.
floorReturns a number rounded down to the nearest integer.
floor(field )
field is a number
or measure field that you want to round down to the nearest integer.
format_numberFormats a number by rounding to the specified number of decimal places or by applying a
certain format, for example #,###,###.##.
format_number(expr ,format )
expr
is a number or measure field that you want to change the format
of.
format is the new format to be applied to the numbers in the
field. The parameter can be in the format composed as '#,###,###.##' or actual numerals like
‘12,332.1235’. This parameter is optional. If you don’t specify a format, the field is
truncated to an integer.
Example: format_number(12332.123456,
'###,###,###,###,###,###.###') returns 12,332.123
logReturns the logarithm of the number in the base that you specify.
log(value ,field )
value
is a number or measure field used as the base of the
logarithm.
field is a number or measure field that you want to
take the logarithm of.
powerRaises a number to the power of another number.value
power(field ,
value )
field is a number or measure field
that you want to raise to the specified power.
value is a number or
measure field that is the power that you want to raise the specified number to.
roundReturns the nearest number to a number you specify, constraining the new number by a
specified number of digits.
round(field ,numberOfDigits )
field
is a number or measure field that you want to round.
numberOfDigits
is a number or measure field that specifies the number of digits to round the specified
number to.
sqrtReturns the positive square root of a given number.
sqrt(field )
field is a number
or measure field that you want to find the square root of.
truncNumberTruncates the specified number of decimal values from the number, or converts to an
integer.
truncNumber(field ,scale )
field
is a number or measure field that you want to truncate.
scale is
the number of digits you want to the right of the decimal point. This parameter is required.
If you don’t specify want any decimal values, use a 0.
Example:
scale(13.111, 1) returns 13.1
# Object Support for CRM Data Streams
When you create a Salesforce CRM data stream, the CRM connector doesn’t support the ingestion of all objects or object types from the connected CRM orgs. Use only supported objects and object types for your data stream.
## Supported Objects

Note Additional considerations can affect whether Data 360 can stream Salesforce CRM objects. See [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.") and [Troubleshooting CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_refresh_history.htm&release=264.0.0&type=5 "If you have trouble with creating, refreshing, or disconnecting a Salesforce CRM data stream, see these common issues.").
- Account
- AccountContactRelation
- Asset
- AuthorizationFormConsent
- AuthorizationFormText
- BriefcaseAssignment
- Campaign
- CareBarrier
- CareBarrierDeterminant
- CareBarrierType
- CareDeterminant
- CareDeterminantType
- CareDiagnosis
- CareObservation
- CareObservationComponent
- CarePerformer
- CarePreauth
- CarePreauthItem
- CareProgram
- CareProgramEligibilityRule
- CareProgramEnrolleeProduct
- CareProgramEnrollmentCard
- CareProgramProduct
- CareProgramProvider
- CareProgramTeamMember
- CareProviderFacilitySpecialty
- CareRegisteredDevice
- CareRequestDrug
- CareRequestItem
- CareSpecialty
- Case
- CaseHistory2
- ClinicalAlert
- ClinicalEncounter
- ClinicalEncounterFacility
- ClinicalEncounterIdentifier
- ClinicalEncounterProvider
- ClinicalEncounterReason
- ClinicalEncounterSvcRequest
- ClinicalServiceRequest
- CodeSetBundle
- CommSubscription
- CommSubscriptionChannelType
- CommSubscriptionConsent
- Contact
- ContactPointAddress
- ContactPointConsent
- ContactPointEmail
- ContactPointTypeConsent
- ContentDocument
- ContentDocumentLink
- ContentVersion
- Contract CoverageBenefit
- CoverageBenefitItem
- CoverageBenefitItemLimit
- DiagnosticSummary
- EmailMessage
- EngagementChannelType
- EnrollmentEligibilityCriteria
- Entitlement EventRelation
- HealthCareDiagnosis
- HealthcareFacility
- HealthCareProcedure
- HealthcareProvider
- HealthcareProviderSpecialty
- HealthCondition
- HealthConditionDetail
- Identifier Incident
- IncidentRelatedItem
- Individual
- IndividualApplication
- Lead
- Medication
- MedicationDispense
- MemberPlan
- OperatingHours
- Opportunity
- OpportunityContactRole
- OpportunityLineItem
- Order
- OrderItem
- PartyConsent
- PatientHealthReaction
- PatientImmunization
- PatientMedicalProcedure
- PatientMedicationDosage
- PersonLanguage
- PersonName
- PlanBenefit
- PlanBenefitItem
- Pricebook2
- Problem
- ProblemIncident
- Product2
- ProductAttribute
- ProductCategory
- PurchaserPlan
- PurchaserPlanAssn
- QuickText
- Quote
- QuoteLineItem
- Recommendation
- ReturnOrder
- ReturnOrderLineItem
- ServiceAppointment
- ServiceContract
- ServiceResource
- ServiceResourceSkill
- Skill Survey
- SurveyPage
- SurveyQuestion
- SurveyQuestionChoice
- SurveyQuestionResponse
- SurveyResponse
- SurveyVersion
- Task
- TaskRelation
- TimeSlot
- User
- WebStore
- WebStoreCatalog
- WorkOrder
- WorkOrderLineItem
- WorkType
## Unsupported Objects
- AcceptedEventRelation
- AccountHistory
- ApiEvent
- Attachment
- AuthProvider
- Announcement
- ApexPageInfo
- AppDefinition
- AppTabMember
- AuthSession
- BackgroundOperationResult
- BrandTemplate
- BulkApiResultEventStore
- CampaignMember
- CaseHistory
- CaseStatus
- CategoryNode
- ClientBrowser
- ColorDefinition
- ConnectedApplication
- ContentFolderItem
- ContentFolderMember
- ContentNote
- ContentWorkspace
- ContentWorkspaceDoc
- ContractStatus
- CorsWhitelistEntry
- CustomBrand
- CustomBrandAsset
- DashboardComponent
- DatacloudCompany
- DatacloudAddress
- DatacloudContact
- DatacloudDandBCompany
- DatamodelTaxonomy
- Datatype DataobjectCategory
- DocumentAttachmentMap
- EltExternalFile
- EltWorkflow
- EltWorkflowNode
- EltWorkflowJobHistory
- EdgeMartDatafile
- EmailDomainKey
- EmailServicesAddress
- EmailServicesFunction
- EmailTemplate
- EmailServicesAddress
- EnvironmentHub
- EnvironmentHubInvitation
- EnvironmentHubMember
- EmbeddedServiceDetail
- EmbeddedServiceLabel
- EntityDefinition
- EntityParticle
- EntitySubscription
- EventBusSubscriber
- EventWhoRelation
- ExternalSocialAccount
- ExpressionSetview
- ExternalEncryptionRootKey
- FeedAttachment
- FeedComment
- FeedItem
- FeedRevision
- FeedPollChoice
- FeedPollVote
- FieldDefinition
- FileAction
- FileEventStore
- FlowDefinitionView
- FlowVariableView
- FlowVersionView
- FormulaFunction
- FormulaFunctionAllowedType
- FormulaFunctionCategory
- IdeaComment
- IdentityProviderEventStore
- IdentityVerificationEvent
- IconDefinition
- JournalReason
- KnowledgeArticle (use Knowledge\_\_ka)
- KnowledgeArticleVersion (use Knowledge\_\_kav)
- LightningUriEvent
- ListViewChartInstance
- ListViewEvent
- LoginAsEvent
- LoginEvent
- LoginIp
- LogoutEvent
- MktDatamodelObject
- OauthToken
- OrderItemType
- OrderStatus
- OrgWideEmailAddress
- OutboundField
- OwnerChangeOptionInfo
- PackageLicense
- PartnerNetworkSyncLog
- PartnerRole
- PermissionSetEventStore
- PicklistValueInfo
- PlatformAction
- PlatformEventUsageMetric
- Publisher
- PromotionRuleTemplate
- QuoteLineItemAttribute
- RecentChangeSignal
- RecentlyViewed
- RelatedListColumnDefinition
- RelatedListDefinition
- ReportEvent
- SelfServiceUser
- ServiceAppointmentStatus
- SocialPersona
- SocialPost
- SocialPostFeed
- SolutionStatus
- SsoUserMapping
- SvcCatalogFilterCriteria
- TabDefinition
- TaskPriority
- TaskStatus
- TaskWhoRelation
- ThirdPartyAccountLink
- TopicAssignment
- UnifiedActivity
- UriEvent
- UserAppMenuItem
- UserLogin
- UserPackageLicense
- UserPermissionAccess
- UserRecordAccess
- UserSetupEntityAccess
- Vote
- WebLink
- WebLinkLocalization
- WorkOrderLineItemStatus
- WorkOrderStatus

Note The [TenantEnrichedUsageEvent data lake object (DLO)](https://help.salesforce.com/s/articleView?id=xcloud.wallet_teue_reference.htm&language=en_US) is available in sandbox orgs. Because consumption cards are tied strictly to production orgs, you can view the consumption data for both sandbox and production orgs only in a production org, on the Digital Wallet **Consumption Cards** tab.
These object types and derived fields aren't supported.
## Unsupported Object Types
- Big Objects — `__b`
- Setup Objects
- Current CDP Objects — `__dll`, `__dlm`
- External Objects — `__x`
- History Objects
## Unsupported Derived Fields
| Object | Derived Fields |
| --- | --- |
| Account | ActivityMetric, ActivityMetricRollup, ActivityMetricRollup, ChannelProgramLevelName, ChannelProgramName, CompareName, CompareSite, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, CssLastLoginDate, HasPrivacyHold, IsBuyer, IsCssEnabled, IsCustomerPortal, IsPartner, IsPersonAccount, OrgAdjustedTodaysDate, OrgId, OrgNumLicenses, OrgStatus, OrgTimeZoneSidKey, OwnerAlias, PersonActionCadence, PersonActionCadenceAssignee, PersonActionCadenceState, PersonActiveTrackerCount PersonFirstCallDateTime, PersonFirstEmailDateTime, PersonScheduledResumeDateTime, PhotoUrl, Territories Tier |
| AccountContactRelation | Division, Name |
| AccountContactRole | AccIdConIdFormula, AccIdIsPrimIdFormula |
| ActionCadence | FolderNameIsWaitAllowedBeforeDaisyChain, NameLower,TotalSteps |
| ActionCadenceStep | AllEmailsBouncedCount, AllEmailsDeliveredCount, AllEmailsSentCount, AllTotalCallsCount, HasVariant, IsOrphan, IsScreenFlowActive, IsStepAutomationActive, ScreenFlowReference, StepAutomationReference, TypeDetail, DayGroup, SubCadenceName |
| ActionCadenceStepTracker | IsActionTaken, SecondsOverdue, StateStepTypeFormula, UniquenessCheck |
| ActionCadenceTracker | IsTrackerActive, UniquenessCheck |
| AppExtension | ManageableState |
| Asset | AssetLevel, Availability, ProductCode, ProductDescription, ProductFamily, ProductIsArchived, Reliability, StockKeepingUnit |
| AuthorizationFormConsent | Party |
| BriefcaseDefinition | FullName, ManageableState, Metadata |
| CallTemplate | NameLower, TotalCalls |
| Campaign | ShowCampMembChart, Tenant |
| CampaignMember | City, CompanyOrAccount, Country, Description, DoNotCall, Email, Fax, FirstName, HasOptedOutOfEmail, HasOptedOutOfFax, LastName, LeadOrContact, LeadOrContactOwner, LeadSource, MilestoneStatus, MilestoneStatusIcon, MobilePhone, Name, Phone, PostalCode, RecordType, Salutation, State Street, Title, Type |
| CampaignMemberStatus | Label |
| CandidateAnswer | CandidateAnswerIndexFormula |
| CartDeliveryGroup | CartDeliveryGroupIdOrIsDefault, GrandTotalAmount, TotalAdjustmentAmount, TotalAdjustmentTaxAmount, TotalAmount, TotalChargeAmount, TotalChargeTaxAmount, TotalProductAmount TotalProductTaxAmount, TotalTaxAmount |
| CartItem | BasisTransactionItem, CartItemByDeliveryGroupAndType, DerivedNetUnitPrice, EndDate, GrossAdjustmentAmount, NetAdjustmentAmount, ObligatedAmount, ParentSalesTransactionItem, PeriodBoundary, PeriodBoundaryDay, PeriodBoundaryStartMonth, PricebookEntry, PricingTransactionType, ProFormaBillingPeriodAmount, ProrationPolicy, StartDate, StartingPriceTotal, StartingUnitPriceSource, StockKeepingUnit, TotalAdjustmentDistAmount, TotalAmount, TotalLineGrossAmount, TotalLineNetAmount, TotalPriceTaxAmount, TotalPromoAdjustmentTaxAmount, TotalTaxAmount |
| CaseMilestone | StartDate, SlaProcess, IsCompleted, IsViolated, IsPaused, TimeRemainingInMins, TimeRemainingInHrs, TimeRemainingInDays, ElapsedTimeInMins, ElapsedTimeInHrs, ElapsedTimeInDays, TimeSinceTargetInMins, TimeSinceTargetInHrs, TimeSinceTargetInDays, StoppedTimeInMins, StoppedTimeInHrs, StoppedTimeInDays, ActualElapsedTimeInMins, ActualElapsedTimeInHrs, ActualElapsedTimeInDays |
| CartItemPriceAdjustment | TotalGrossAmount, TotalNetAmount, TotalTax |
| CartValidationOutput | TypeLevel |
| Case | ClosedOnCreate, Comments, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, ContactEmail, ContactFax, ContactMobile, ContactPhone, CreatedByAlias, CreatorFullPhotoUrl, CreatorName, CreatorSmallPhotoUrl, EscalationDateTime, HasCssComments IsSelfClosed, IsVisibleInCss, LastModifiedByAlias, MilestoneStatus, MilestoneStatusIcon, RuleFilter |
| ChangeRequest | StatusCode |
| CommSubscriptionConsent | Party |
| Contact | AccountName, ActionCadence, ActionCadenceAssignee, ActionCadenceState, ActiveTrackerCount, ActivityMetric, ActivityMetricRollup, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, EngagementMap, EngagementScore, FirstCallDateTime, FirstEmailDateTime, HasPrivacyHold, IsEmailBounced, IsPriorityRecord, LastActivityDate, PhotoUrl, ReportsToName, ScheduledResumeDateTime |
| ContactPointConsent | Party |
| ContentDocument | ContentSize, Description, FileExtension, FileType, Name, SharingOption, SharingPrivacy |
| ContentVersion | Checksum, FileExtension, IsAssetEnabled, IsEncrypted, Name, TagCsv, VersionData, VersionDataUrl, VersioningPolicy |
| Contract | ActivityMetric, ActivityMetricRollup, CustomerExpirationNoticeDate, HasPurchaseRule, OwnerExpirationNoticeDate, TotalPaid |
| ContractLineItem | ListPrice, Product2, Status, StatusIndicator, Subtotal, TotalPrice |
| CryptoTransactionEnvelope | SignaturesCompleted |
| CustomEntityDataTemplate | Comments, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate |
| DocumentFeature | DocumentFeatureIndexFormula |
| EinsteinAnswerFeedback | AnswerTypeFormula |
| EmailMessage | AttachmentIds, From, IsOpened, LargeBody, Name, ValidatedFromAddress |
| EmailTemplate | B2bmkSpamComplaintRate, B2bmktClickThroughRate, B2bmktClickToOpenRatio, B2bmktDeliveryRate, B2bmktOpenRate, B2bmktOptOutRate, B2bmktTotalDelivered, B2bmktUniqueClickThroughRate, ControllerKey, ControllerType, DeliveryRate, EntityType, FolderName, FullName, HasSalesforceFiles, IsBuilderContent, ManageableState, Metadata, NameNorm, TotalDelivered, TotalSent |
| EngagementInteraction | MappedState |
| Entitlement | Status, StatusIndicator |
| Event | ArchivedDate, Attendees, DueDate, Email, EndDate, EndDateTime, EventSubtype, IsArchived, IsRecurrence2, IsRecurrence2Exception, MasterEvent, Organizer, Phone, Recurrence2PatternStartDate, Recurrence2PatternTimeZone, StartDateTime |
| EventRelayConfig | FullName, ManageableState, Metadata |
| Expense | Subtotal, TotalPrice |
| ExternalDataSource | ApiKey, FullName, ManageableState, Metadata |
| FieldServiceMobileSettings | ManageableState |
| FtestGrandChild | EffectiveDate |
| FtestMain | DerivedField192, DerivedFieldPre192, DerivedText, Formula, FormulaWithIdRef, LeadUnique |
| Incident | MilestoneStatus, StatusCode |
| IncidentRelatedItem | UniqueKeyIndex |
| Individual | HasPrivacyHold, PartyType |
| IndividualApplication | AcademicTerm, ApplicantEmail, ApplicantPhone, DecisionReleaseDate, DueDate, LearningProgram |
| LandingPage | FormErrorRate, FormSubmissionRate |
| Lead | ActionCadence, ActionCadenceAssignee, ActionCadenceState, ActiveTrackerCount, ActivityMetric, ActivityMetricRollup, Campaign, CampaignMemberStatus, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, CreatedByID, EngagementMap, EngagementScore, FirstCallDateTime, FirstEmailDateTime, HasPrivacyHold, InternalSource, IqScore, IsPriorityRecord, LastModifiedByID, PhotoUrl, ScheduledResumeDateTime, ScoreIntelligence |
| LearningItemProgress | DaysInProgress, OutcomeProgressPercent, OverallStatus, ProgressStatus |
| ListEmail | ClickThroughRate, ClickToOpenRatio, DeliveryRate, OpenRate, OptOutRate, SpamComplaintRate, TotalDelivered, UniqueClickThroughRate |
| LiveChatTranscript | Abandoned, ChannelType, ChatDuration, WaitTime |
| LoanApplicantEmployment | MonthlyTotalIncomeAmount |
| LoanApplicationFinancial | CashFromOrToBorrowerAmt, LoanAmount, TotalCashDueFromBorrower, TotalCredit, TotalEstPaymentAmt, TotalMortgageLoanAndCreditAmt, TotalMortgageLoansAmount |
| Macro | FolderName |
| ManagedContentVariant | HasLocks, IsPrimary, IsPublished, VersionNumber |
| MarketSegment | MarketSegmentType |
| MarketingForm | ErrorRate, SubmissionRate |
| Opportunity | ActivityMetric, ActivityMetricRollup, AgeInDays, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, Fiscal, HasOpenActivity, HasOverdueTask, HasUnlikelyToCloseInsight, IqScore, IsPriorityRecord, LastActivityInDays, LastStageChangeInDays, OpportunityScore, Pricebook, PushCount, TopInsight |
| OpportunityContactRole | IsPrimary |
| OpportunitySplit | EffectiveDate, SplitAmount, UserUniqueToSplitType |
| Order | AccountNumber, ContractEndDate, ContractName, GrandTotalAmount, TotalAdjDeliveryAmtWithTax, TotalAdjProductAmtWithTax, TotalAdjustmentAmount, TotalAdjustmentDistAmount, TotalDeliveryAdjDistAmtWithTax, TotalListAmount, TotalProductAdjDistAmtWithTax, TotalProductAmount |
| OrderItem | AdjustedLineAmtWithTax, BillingFrequency, Contract, IsReductionOrder, OriginalOrder, OriginalOrderActivatedDate, OriginalOrderItemQuantity, OriginalOrderShippingAddress, ParentOrderItem, ProductCode, RoundedLineAmtWithTax, StockKeepingUnit, SubscriptionTerm, TotalAdjustmentAmtWithTax, TotalAdjustmentDistAmtWithTax, TotalAmtWithTax, TotalLineAdjustmentAmtWithTax, TotalPrice |
| PricebookEntry | ActivePriceAdjustmentQuantity, Name, ProductCode, StandardPrice |
| Problem | StatusCode |
| ProcessInstance | ElapsedTimeInDays, ElapsedTimeInHours, ElapsedTimeInMinutes |
| ProcessInstanceStep | ElapsedTimeInHours, ElapsedTimeInMinutes |
| Product2 | ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, SpecificationType |
| ProductConsumed | IsProduct2Serialized, ListPrice, Product2, ProductName, QuantityUnitOfMeasure, Subtotal, TotalPrice |
| ProductItem | IsProduct2Serialized, ProductName, UniqueConstraint |
| ProductRequired | ParentRecordType, ProductName |
| ProductTransfer | CanUpdateIsReceived, IsProduct2Serialized, Product2TransferRecordMode, ProductRequest, ReturnOrder, ShipmentExpectedDeliveryDate, ShipmentStatus, ShipmentTrackingNumber, ShipmentTrackingUrl |
| QuickText | FolderName |
| Quote | Account, CanCreateQuoteLineItems, Discount, EffectiveDate, GrandTotal, TotalAdjustmentAmount, TotalAdjustmentDistAmount, TotalListAmount, TotalPriceWithTax, TotalProductAmount |
| QuoteLineItem | EffectiveDate, HasSchedule, ListPrice, ObligatedAmount, ParentQuoteLineItem, PricingTerm, PricingTermUnit, ProFormaBillingPeriodAmount, ProductCode, SalesItemType, SellingModelType, StockKeepingUnit, SubscriptionTermUnit, Subtotal, TotalAdjustmentDistAmount, TotalPrice, TotalPriceWithTax |
| Recommendation | ActionReference, IsActionActive |
| RecommendationReaction | ContextRecordIdStr, ContextRecordType, OnBehalfOfIdStr, OnBehalfOfType, TargetActionIdStr, TargetActionType, TargetIdStr, TargetType |
| RegulatoryCode | IsActive |
| RegulatoryCodeViolation | DaysOpen |
| ReturnOrder | GrandTotalAmount, TotalDeliveryAdjustAmtWithTax, TotalDeliveryAmtWithTax, TotalFeeAdjustAmtWithTax, TotalFeeAmtWithTax, TotalProductAdjustAmtWithTax, TotalProductAmtWithTax |
| ReturnOrderLineItem | TotalAdjustmentAmountWithTax, TotalAmount, TotalLineAmountWithTax, TotalPrice, TotalTaxAmount |
| ServiceAppointment | ParentRecordStatusCategory, ParentRecordType |
| ServiceContract | Discount, GrandTotal, Status, StatusIndicator |
| ServiceReport | Date, FooterHeight, HeaderHeight, Type |
| ServiceReportLayout | ManageableState |
| SkillRequirement | MandatorySkillRequirement |
| SocialPost | TruncatedContent |
| Task | ArchivedDate, ConnectionReceived, ConnectionReceivedDate, ConnectionSent, ConnectionSentDate, DueDate, Email, IsArchived, IsHighPriority, IsRecurrence2, IsRecurrence2Exception, Phone, PrioritySortOrder, Recurrence2PatternStartDate, Recurrence2PatternTimeZone, TaskSubtype |
| Territory2AlignmentLog | StatusT2Formula |
| TimeSheet | TotalDurationInHours |
| TransactionJournal | CreditAmount, DebitAmount |
| User | BadgeText BannerPhoto, BannerPhotoUrl, CurrentStatus, DataStorageUsage, FileStorageUsage, FullPhotoUrl, HasAccessCoreServiceProtection, HasActivateMultiCurrency, HasActivateSkinnyTables, HasAdvancedDevDiagnostics, HasApexDiagnostics, HasAppRouter, HasBulkSignup, HasCreateAnalyticsMasterApp, HasDeepSeaTokenizerAccess, HasDefenseIntegration, HasDeleteCleanupOrg, HasDevDiagnostics, HasEditApiPermission, HasEditLicenses, HasEditLoginMessages, HasEditOrgStatus, HasEditPartnerIdentifier, HasEditPartnerInfo, HasEditTrialUserRestricted, HasEditUserFields, HasEditUserRestricted, HasEnableDots, HasGridforceOps, HasHeapDumpGenerator, HasHideSetup, HasHttpTracesViewer, HasInspectOm, HasLockUsersAndKillSessions, HasLoginAsUsers, HasMakeBtUsersUber, HasManageAnalyticsBlacktab, HasManageBtUsers, HasManageCoreServiceProtection, HasManageCustomIndexes, HasManageDataExportScheduling, HasManageImportQueue, HasManageOrgDomains, HasManagePackaging, HasManagePerfDiagnostics, HasManagePods, HasManageProvisioning, HasManageSearch, HasManageServiceCloudRealtime, HasManageSites, HasMassUpdateOrgPerms, HasMobileLoginAs, HasMultiNodeDiagnostics, HasOrgMigration, HasOrgSplit, HasOverrideConfiguration, HasOverrideSecuritySettings, HasPremierAdministrator, HasProductManagerRestricted, HasQaDiagnostics, HasRollups, HasRunPhysicalDelete, HasRunSqlInBlackTab, HasSecurityOps, HasSignupInstanceMapping, HasSplunkTokenizerAccess, HasSupportDiagnostics, HasUiDiagnostics, HasViewProvisioningResults, IsBadged, IsCheckoutEnabled, IsExtIndicatorVisible, IsPartner, IsPortalEnabled, IsPrmSuperUser, IsSelfServiceUser, LockoutDate, MediumBannerPhotoUrl, MediumPhotoUrl, NeedsNewPassword, OutOfOfficeMessage, PasswordAnswer, PasswordExpirationDate, PasswordMd5, PasswordQuestion, PasswordQuestionType, PasswordResetAttempt, PasswordResetLockoutDate, PasswordResetType, PasswordSha256, PortalRole, ProfileLicenseType, ProfilePhoto, SfdcAdminUser, SmallBannerPhotoUrl, SmallPhotoUrl, StorageUsage, WirelessTrialExpirationNotifyDate, YubiKeySerialNumber, YubiKeyStatus |
| WebCart | CartByAccountStatusAndStore, CartByStoreAccountOwner, CartByStoreAndAccount, CartByStoreAndOwner, GrandTotalAmount, TotalAdjustmentDistAmount, TotalAmount, TotalAmountAfterAllAdjustments, TotalTaxAmount, UniqueCartByStatus |
| WebCartAdjustmentGroup | TotalAmountWithTax |
| WorkOrder | Discount, GrandTotal, MilestoneStatus, MilestoneStatusIcon, ReturnOrder, ServiceAppointmentCount |
| WorkOrderLineItem | ListPrice ReturnOrder, ServiceAppointmentCount, Subtotal, TotalPrice |
| WorkPlan | ParentRecordType |
| WorkStep | ParentRecordType, WorkPlanExecutionOrder |

Note Refer to the [list of standard objects for the Salesforce Platform](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_list.htm). The values in Salesforce CRM objects and object fields may not always match the standard values in Data 360. This is because in Salesforce CRM, special user-specific fields, such as [Account.LastViewedDate](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_account.htm) and [Account.LastViewedDate](https://developer.salesforce.com/docs/atlas.en-us.object_reference.meta/object_reference/sforce_api_objects_case.htm), vary between users.
# Object-Level and Field-Level Tags in Data 360
In data governance, you can use object-level tags and field-level tags to label and manage data at different levels of granularity.
Tags in Data 360 are applied to entire data objects such as data lake objects (DLOs), data model objects (DMOs), and calculated insight objects (CIOs). These tags describe the overall nature or sensitivity of the object. For example, you can apply a Confidential or Customer Data tag to an entire sales dataset.
You can use field-level tags to identify individual parts of an object, such as Email, Social Security Number, or Date of Birth. These tags identify sensitive fields that require masking, restricted access, or special handling.
Using both levels of tagging lets organizations protect sensitive fields while allowing broader access and control at the object level.
- **[Create a Tag in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_tag.htm&release=264.0.0&type=5)**
Tags are essential for organizing, classifying, and managing data at scale. They act as metadata labels that describe the content, sensitivity, usage, or purpose of a data object or field. Tags can have one parent and multiple child tags, but they don't support more than one level of hierarchy.
- **[Edit or Delete a Tag in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_tag.htm&release=264.0.0&type=5)**
You can delete a tag or edit the tag name, API name, and classifications. You can't delete tags that are used in policies. This includes default tags provided by Data Cloud.
# Object, Field, and Record Level Security
Data governance policies in Data 360 control access to data at different levels such as object, field, and row, based on user roles, attributes, or relationships.
## Examples
Here are some examples of the different levels of access that you can control.
- **Object-Level Security (OLS):** The Customer\_Orders object is accessible to users in the Sales department who are assigned to the appropriate data space.
- **Field-Level Security (FLS):** Hide the Credit Card Number field for users outside the finance team.
- **Record-Level Security (RLS):** Show customer records from a specific region to a user, or display only the records they own by comparing data from the protected object with attributes of the logged-in user. All supported attributes are Salesforce IDs stored in 18-character format:
- User ID – Unique ID of the logged-in user
- Role ID – User’s Salesforce role
- Org ID – User’s Salesforce organization
- **RLS with Joins:** Extends record-level security by allowing access rules to reference external mapping or lookup tables, enabling more dynamic and context-aware access conditions. For example, you can create a permit access policy to allow users to access opportunity records if those records are owned by them or by someone in their reporting chain, based on the manager hierarchy.
- **RLS with Hierarchy**: Allows you to set access rules based on reporting structures from Salesforce CRM, such as manager or role hierarchies. You can create a policy rule so that a manager automatically sees records owned by them and their team, while team members can view only their own records.
- **[Create an Object or Field-Level Access Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_ols_fls_policy.htm&release=264.0.0&type=5)**
In data governance, define who can access specific data objects or fields based on user and data attributes. Create object-level or field-level access policies for users.
- **[Create a Record-Level Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_rls_policy.htm&release=264.0.0&type=5)**
Define who can access specific records within an object based on user and data attributes.
- **[Ingest Hierarchical Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ingest_hierarchy_data.htm&release=264.0.0&type=5)**
Bring Salesforce CRM organizational hierarchies such as Role, Manager, and Territory into Data 360. After ingestion, you can reference these hierarchies in hierarchy-based record-level security (RLS) policies.
# Objects Shared with Companion Orgs
Data model objects (DMOs) and calculated insights objects (CIOs) in shared data spaces are shared with the companion org. You can reference data from these objects with Data 360 features and use the data with platform features, such as Flow and related list enrichments.
Companion org users with access to the Data Cloud One app can view DMO data in Data Explorer and Profile Explorer. You can access CIOs in Data Explorer or Profile Explorer.
# Obtain an Individual ID
Learn how to obtain an Individual ID in Data 360.
You can obtain Individual Ids through three different methods: Segmentation, Source System, and Query API.
## Via Segmentation
You can retrieve an Individual ID by creating a segment using any available identifying information as segment filter criteria. This information includes email address, phone number, or first and last name. You can activate your segment to Amazon S3. The published activation file includes the Individual IDs for the segment population.
## Via Source System
When data is mapped to the Individual entity, you must map your imported data customer identifiers to the Individual ID field. This Individual ID field reflects the value from your Data Stream source. You can retrieve Individual IDs by consulting the source systems for your Data Streams.
## Via Query API
You can retrieve an Individual ID by submitting a request to the Query API. Submit requests to the Query API using email address, phone number, or first and last name.
#### See Also
- [_Salesforce Help_: Create and Activate Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&release=264.0.0&type=5 "Use segmentation in Data 360 to break down your data into useful segments to understand, target, and analyze your customers. After you create a segment, you can publish it to an activation target.")
- [_Salesforce Help_: Create a Cloud File Storage Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_cloud_file_storage_activation_target.htm&release=264.0.0&type=5 "Create an activation target in Data 360 to publish segments and batch data model objects (DMOs) to external file storage activation platforms like Amazon S3, SFTP, Google Cloud Storage (GCS), or Microsoft Azure blob storage.")
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
# Omnichannel Considerations and Best Practices
There are important aspects and trade-offs to consider before implementing this solution. This guide is just one example of how to enable an omnichannel experience for your customers. For example, instead of separate single-channel journeys, users can create seamless customer experiences by using Data Cloud to orchestrate one journey with all Email, SMS, and MobilePush activities together.
## Potential Risks of Using the Unified Individual in This Solution
This solution assumes that you haven’t implemented Marketing Cloud Engagement to create omnichannel contacts in Engagement for use across all Email, SMS, and MobilePush channels. This guide outlines how you can create Identity Resolution rules in Data Cloud to relate separate Individuals—Email, SMS, and MobilePush SubscriberKeys—to a single representation of a person—a Unified Individual.
Generally, we recommend using the Individual profile as much as possible. We recommend limiting the use of Unified Individuals in campaigns to promotional use cases but not transactional or event-triggered use cases.
Messaging the Wrong Person
Consider Unified Individuals as dynamic, and treat them with caution because they could change. Unified Individuals are based on the rules you set within Identity Resolution and the data stored within your Data Cloud instance. Based on newly imported data from your external data sources or changes that you make in the Identity Resolution ruleset, the Identity Resolution process can add or remove Individual profiles and their associated contact point addresses from a given Unified Individual. Therefore, it’s possible that you could be sending messages to the wrong person.
Example: Data Cloud can have a Unified Individual for the person John Smith. Based on your Identity Resolution rules, the Unified Profile for John Smith is initially made up of three different Individuals (SubscriberKeys from Marketing Cloud Engagement): John.Smith.Email, John.Smith.SMS, and John.Smith.MobilePush. Cumulus activates the Unified Individual of John Smith to use in Journey Builder.
Sourced from Unified Individual
Profile of John Smith
Individual ID EmailAddress FullName PhoneNumber Country MobilePushSubscriberKey
John.Smith.Email
john.smith@example.com
John Smith
555-123-1234
United States
John.Smith.MobilePush
Selected from the Individual profile
of John.Smith.Email Selected from the Individual profile
of John.Smith.SMS Selected from the Individual profile of
John.Smith.MobilePush
Midway through the journey, Identity Resolution receives new information that results in the determination that the Individual John.Smith.MobilePush doesn’t belong to the Unified Individual for John Smith. In fact, this Individual profile belongs to a separate person who has the same name, Unified Individual John Smith, Sr. As a result, the journey could have sent emails and SMS messages to John Smith and sent push notifications with potentially sensitive information to John Smith, Sr.
Selecting Opted Out Individuals or Contact Points
When Data Cloud segments on the Unified Individual, it qualifies the Unified Individuals that have at least one Individual that meets the criteria.
When activating on the Unified Individual, Data Cloud uses [your source order prioritizations](https://help.salesforce.com/s/articleView?id=data.c360_a_contact_points.htm&release=264.0.0&type=5 "Contact point selection determines which objects and fields are included in an activation and sent to an activation target. Use the source priority order to determine which contact point value is selected for the activation.") and engagement histories to select the contact points to activate, regardless of their consent or preference type. Customers are solely responsible for activating contact points and obtaining consent to send messages to any contact points.
For example, the Unified Individual for John Smith can have two Individuals related to it, each imported from separate data sources and each with their own associated SMS phone numbers: John.Smith.1 from System A and John.Smith.2 from System B. If Cumulus segments on the Unified Individual with criteria of whether the Unified Individual has opted in for SMS messages, the Unified Individual for John Smith qualifies for the audience, even if John.Smith.A had opted in to SMS messaging and John.Smith.B had opted out. As part of activation, Data Cloud could select the opted-out phone number from John.Smith.B if Cumulus had selected to prioritize SMS contact points that came from source system System B.
Using the Wrong Context of a Person
When Data Cloud segments on the Unified Individual, it qualifies Unified Individuals that have at least one Individual that meets the criteria.
When activating on the Unified Individual, Data Cloud selects a channel’s contact point from one of the Individuals within the Unified Individual’s profile. These contact points can come from various systems, brands, divisions, or subsidiaries within your company. Then, Data Cloud selects attribute values based on the source system determined by the [Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5 "A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.") set for your company.
This action can lead to a personalized customer experience that uses the wrong customer context, because the customer might be getting targeted content or promotions on a contact point that they didn’t expect.

Example Cumulus stores the contact points for each of its brands within one centralized source system. The person John Smith signed up for the Cumulus email newsletter with Brand A of the company—the insurance brand—using john.smith@example1.com. Separately, John Smith later signed up with Brand B–the credit card brand–using john.smith@example2.com. Finally, John Smith eventually signed up on the Cumulus mobile app with Brand C–the stock-trading brand–using john.smith@example3.com.
The marketing team in charge of Brand A creates a segment to find Unified Individuals who are likely to upgrade their home insurance. As part of activation, Data Cloud selects the email address that is most engaged: john.smith@example3.com.
However, these brands and addresses aren’t contextually related. When Cumulus sends a promotion for the customer to upgrade their existing mortgage, it goes to the email address used for the stock-trading app instead of the email address associated with his insurance.

Example
Each brand within Cumulus has a different source data system, and each one imports data to Data Cloud. The person John Smith signed up for the Cumulus email newsletter with Brand A of the company–the insurance brand. Separately, John Smith later signed up with Brand B–the credit card brand. Finally, John Smith eventually signed up on Cumulus mobile app with Brand C–the stock-trading brand.
The marketing team in charge of Brand A creates a segment to find Unified Individuals who are likely to upgrade their home insurance. As part of this activation, the team selects to source priority for Email, SMS, and MobilePush contact points so that they come first from system A, then system B, and finally system C.
The resulting data extension contains John’s email from system A (insurance brand), his phone number from system B (credit card brand), and the MobilePush Key from System C (the stock-trading app).
However, these brands and addresses aren’t contextually related. When Cumulus sends a promotion for the customer to upgrade their existing mortgage with them, it makes sense to use the email address that is used by the insurance brand. But it wouldn’t be appropriate to use the phone number associated with the credit card brand or the app associated with the stock-trading brand.
## Consent Behaviors for Each Channel
Marketing Cloud Engagement has a variety of capabilities that you may use to manage customer consent and preferences.
In this solution, because the journey is being orchestrated using MobilePush Key as the SubscriberKey, the consent status for the email address john.smith@example.com is checked against the record for John.Smith.MobilePush.
SMS Messages: The native consent statuses in Marketing Cloud Engagement for SMS sending are stored at the phone number level (and keyword) and not at the SubscriberKey level (unlike Email). In this solution, the consent status for phone 555-123-1234 is checked regardless of the orchestrating SubscriberKey. Note: If you configure the SMS activity to Subscribe all contacts to a keyword, native consent is overridden and the contact is opted in.
Email Activities Only
- For each Email activity in the journey, associate a [suppression list](https://help.salesforce.com/s/articleView?id=mktg.mc_es_suppression_lists.htmppression_lists.htm&type=5&language=en_US) that prevents sends to the given email address. We recommend this option only for journeys or lists with less than 200,000 members. Before sending an email, Journey Builder checks the email address suppression status associated with the list.
- For each Email Activity in the journey, associate a [publication list](https://help.salesforce.com/s/articleView?id=mktg.mc_es_publication_lists.htm&type=5&language=en_US). Before sending an email, Journey Builder checks the publication status associated with the contact to see if they’re subscribed.
Email, SMS, and MobilePush Activities
- Use [exit criteria](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_exit_criteria.htm&type=5&language=en_US) in your journeys to monitor attributes from the Contact Model that you know are current to represent the person’s consent or preferences. Journey Builder monitors these values for the duration of the journey.
- Before using the activated data extension for journey entry, run an automation in [Automation Studio](https://help.salesforce.com/s/articleView?id=mktg.mc_as_automation_studio.htm&type=5&language=en_US) to validate the consent or preference status of each contact or contact point against a separate data extension. Invalid contacts are removed before they enter the journey.
- As part of your journey Entry Source, [configure filter criteria](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_configure_the_data_extension_entry_source.htm&type=5&language=en_US) to exclude contacts from entering the journey. Invalid contacts are removed before they enter the journey.
Alternative Omnichannel Orchestration Approach
Instead of a journey with all Email, SMS, and MobilePush activities together, create a similar customer experience by using Data Cloud to filter and orchestrate a series of separate single-channel journeys.
## Default Address Behaviors
This solution kit recommends that you update the Default Send Addresses within Journey Builder Settings to override the MobilePush Key’s default Email and SMS addresses to instead send to the EmailAddress and PhoneNumber stored within the activated data extension. This practice can cause downstream updates in the Marketing Cloud Engagement and Data Cloud systems.
Updates to MobilePush Key (MobilePush SubscriberKey) Contact Record
The Email and SMS addresses used in the send are added to the MobilePush Key (MobilePush SubscriberKey) Contact record in Engagement, resulting in a SubscriberKey that has both an Email address and SMS contact point address. Then, this information syncs to Data Cloud and is reflected on the Individual record of the MobilePush SubscriberKey, resulting in an Individual that now has both an Email and SMS contact point address.
This action can cause conflicting updates. Engagement might be updating the Contact record with new default Email and SMS contact point addresses while Data Cloud is activating a new audience using different Email and SMS contact point addresses for that same contact.
Reporting and Troubleshooting
- All send and journey reporting is based on the SubscriberKey being used for the journey. For this solution kit, the value for MobilePush Key acts as the SubscriberKey for the journey.
- Depending on your reporting strategy, you might need additional processes to harmonize this value back to the Email or SMS SubscriberKey or contact points that the journey’s sends were based on.
- Journeys that use this solution can’t use activations that refresh on a scheduled basis. Refreshes overwrite the required send relationship setting that relates the MobilePush Key attribute to a Subscriber Key. As such, Journey Builder defaults all orchestration, personalization, and sending lookups based on the value of the MobilePush Key (representing the MobilePush SubscriberKey).
# Omnichannel Inventory Connector
In Data Cloud, you can establish a connection to Omnichannel Inventory using the provided connector. The connection process creates the data streams and maps the data source objects to the data model objects (DMO) and establishes DMO relationships.
- **[Set Up an Omnichannel Inventory Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_oci_connection.htm&release=264.0.0&type=5)**
Ingest your Omnichannel Inventory data into Data 360 using the Omnichannel Inventory connector.
- **[Disconnect an Omnichannel Inventory Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_oci_connection.htm&release=264.0.0&type=5)**
You can delete a connection to Omnichannel Inventory if you don't need it. Removing the connection stops Data 360 from using your inventory as a data source and data action target.
- **[Omnichannel Inventory Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_oci_data_mappings.htm&release=264.0.0&type=5)**
The Omnichannel Inventory connector maps the data source objects to the data model objects (DMO) and establishes DMO relationships.
# Omnichannel Inventory Data Mappings
The Omnichannel Inventory connector maps the data source objects to the data model objects (DMO) and establishes DMO relationships.
The Omnichannel Inventory connecter creates these data streams in the Data Stream workspace in Data Cloud using this format.
- LocationGroupExclusion\_\[Omnichannel Inventory org name\]
- LocationInventory\_\[Omnichannel Inventory org name\]
- GroupInventory\_\[Omnichannel Inventory org name\]
Don’t remove these data streams. Removing them breaks the Omnichannel Inventory connection.
This table lists information about the source objects.
| Source Object | Description | Mapping Reference |
| --- | --- | --- |
| Location Group Product Exclusion Change | Represents a change to the Location Group Product Exclusion list. | [Location Group Product Exclusion Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_oci_locationgroupproductexclusionchange.htm) |
| Location Product Inventory Change | Represents a change to product inventory at a location. | [Location Product Inventory Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_oci_locationproductinventorychange.htm) |
| Location Group Product Inventory Change | Represents a change to product inventory at a location group. | [Location Group Product Inventory Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_oci_locationgroupproductinventorychange.htm) |
#### See Also
- [Set Up an Omnichannel Inventory Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_oci_connection.htm&release=264.0.0&type=5 "Ingest your Omnichannel Inventory data into Data 360 using the Omnichannel Inventory connector.")
- _Salesforce Help_: Set Up an Omnichannel Inventory Connection
- [_Salesforce Help_: Set Up Omnichannel Inventory](https://help.salesforce.com/s/articleView?id=commerce.inv_get_started_with_omnichannel_inventory.htm&type=5&language=en_US)
# Omnichannel Journey Solution Workflow
Review the solution workflow for creating an omnichannel journey in Marketing Cloud Engagement using data from Data 360.
Stage Data in Data 360
Create an Omnichannel Audience in Data 360
Configure Journey Settings in Marketing Cloud Engagement
Define match rules for Identity Resolution to relate separate Individuals
To prioritize values for Unified Individual, define Reconciliation Rules
To select the MobilePush SubscriberKey, create a Calculated Insight
Create a segment to qualify the correct Unified Individuals
Activate the audience with applicable contact points and attributes
Update the send relationship on the activated data extension
Configure journey entry to use the activated data extension audience
Configure journey settings to use the desired send address
Add consent or preference filters as needed
# Optimize Identity Resolution
Consider these best practices and troubleshooting tips for the data you bring in and send out of Data 360 to get the most of your unified profiles.
## Review Source Data

Note Complete all required mappings for identity resolution before getting started.
Verify that data ingestion and modeling from your source data to Data 360 was successful.
Question to Consider
How to Verify
Did all the data from my data stream make it into Data 360 ?
Use the Summary by Source Calculated Insight
Are all my data mappings correct?
Go to Data Explorer to review your Data Lake Objects (DLOs) and
Data Model Objects (DMOs) for accurate values on key fields.
Review mappings for important objects in Data Streams and check
for warnings.
Does the Account DMO or Individual DMO have the expected fields and field values?
Go to Data Explorer to review the data model object's data.
## Review Summary Statistics and Unified Profiles
Verify that summary statistics and unified profiles make sense based on your source data after creating your ruleset.
| Question to Consider | How to Verify |
| --- | --- |
| Does the consolidation rate make sense for your data source? | Check the consolidation rate for your ruleset against what you know about how clean your data sources are. You can review the consolidation rate in the Identity Resolution Summary, using the Identity Resolution Tableau Dashboard, or by creating a calculated insight. |
| Do your unified profiles have the expected information? | Use the Profile Explorer or the Identity Resolution Tableau Dashboard to review random unified profiles for accurate values. |
- **[Explore Individual Profile Unification in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_tableau_dashboard.htm&release=264.0.0&type=5)**
Dig into your unification data visually with the Identity Resolution Tableau accelerator. Pre-configured charts provide at-a-glance information such as how many profiles were ingested from each source and how they contributed to your unified individual profiles.
- **[Evaluate Account Matching in Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_evaluate_account_matching.htm&release=264.0.0&type=5)**
Check the effectiveness of your account unification match rules by reviewing Unified Account profiles with Query Editor.
- **[Troubleshoot Identity Resolution Ruleset Processing Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ir_errors.htm&release=264.0.0&type=5)**
Understand what ruleset processing errors mean and how to resolve them.
- **[Troubleshoot Identity Resolution Results with Calculated Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting.htm&release=264.0.0&type=5)**
Build calculated insights to investigate the quality of your unified profile data and profile consolidation rates.
# Optimize Queries with Secondary Indexes
When you create a secondary index on a data lake object (DLO) or materialized data model object (DMO), Data 360 quickly finds and returns data based on defined secondary field values. A secondary index improves performance and reduces credit usage.
Data 360 automatically indexes objects. For Profile and Other categories, the index is the primary key. For the Engagement category, the index is the Event Time Field. You can use a secondary index to filter and join data by using fields other than the primary key, which can improve query performance.
In Data 360, a secondary index is a batch data transform on the provided DLO or materialized DMO that adds the specified field as the new index.
Data 360 keeps each secondary index current by refreshing it on a schedule. Secondary index refreshes are incremental and only rebuild the portion of the index affected by changed data. You can choose how often each index refreshes to balance data freshness against cost.
## Use Cases and Best Practices
Consider this guidance when you create a secondary index.
- A secondary index can improve query speed for large DLOs or materialized DMOs that you frequently filter on a non-primary field.
- Secondary indexes work best for queries that filter on fields with many distinct values, where queries return nearly unique objects. For example, customer-id, phone number, email, or “Global ID” fields.
- Use a secondary index to quickly search a range of data in a large object. For example, use a secondary index to find customers in a defined zip code range.
- A secondary index can speed up queries on materialized DMOs, such as customer segments or aggregated metrics.
- You can create multiple secondary indexes on one DLO or DMO so that queries use the most efficient index.
- Because a DMO can map to multiple DLOs, a DMO query reads from every mapped DLO. For the best performance, create the secondary index on the mapped field in each DLO that is large enough to impact query speed. If you index only some of the mapped DLOs, the query still scans the DLOs that aren’t indexed.
- Consider packaging your secondary index configurations in [standard data kits](https://help.salesforce.com/s/articleView?id=data.c360_a_data_package_kits.htm&release=264.0.0&type=5 "Use a data kit in Data 360 to streamline package creation and installation. You can manage all packageable Data 360 features in the data kit. You can create data stream bundles and also include data model customization and relationships.") for easy sharing and consistent configuration.
For information on credit usage, see [Billing Considerations for Secondary Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_secondary_index.htm&release=264.0.0&type=5 "Data 360 Secondary Indexes enable faster query performance and more efficient data retrieval with attributes other than the primary identifier. Use of secondary indexes impacts the consumption of credits used for billing in these usage types.").
## Secondary Indexes and SQL
- Data Model Object (DMO) queries that filter on a field mapped to a DLO or DMO secondary index field use the secondary index to improve query performance.
- In `WHERE` clauses (filters), secondary indexes only work with a direct match on the indexed field. The indexed field can’t be based on calculations, functions, or fuzzy patterns.
- When joining two large objects on a non-primary field, results improve when one of the objects has a small number of rows.
- When filtering on a secondary index and another field, use the `AND` clause. The secondary index narrows the result set before the other field is evaluated.
For query examples and detailed guidance on writing filters that use a secondary index, see [Filter Your Query Results](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/filter-query-results.html) in the Data 360 Query Guide.
## Limitations
Consider these limitations when you define your secondary indexes.
- Secondary indexes don’t support zero-copy Data 360 objects or unstructured DLOs.
- Secondary indexes don’t support DevOps data kits or managed packages.
- Only materialized DMOs (Derived, Bridge, or Transform types) support secondary indexes. Non-materialized DMOs (simple views without underlying physical tables) can’t be indexed.
- You can’t create a secondary index in a companion org. However, queries from a companion org to a DLO in the shared data space of the home org use the defined secondary index.
- By default, Data 360 refreshes secondary indexes daily. Secondary indexes work best on objects that update at most every 24 hours. For frequently updated objects, refreshing more often can increase cost without improving freshness, because a large portion of the index can be rebuilt on each refresh.
## Next Steps
- **[Billing Considerations for Secondary Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_secondary_index.htm&release=264.0.0&type=5)**
Data 360 Secondary Indexes enable faster query performance and more efficient data retrieval with attributes other than the primary identifier. Use of secondary indexes impacts the consumption of credits used for billing in these usage types.
- **[Create a Secondary Index](https://help.salesforce.com/s/articleView?id=data.c360_a_query_create_secondary_index.htm&release=264.0.0&type=5)**
Create secondary indexes in Data 360 to improve query performance and reduce credit usage on data lake objects (DLOs) or materialized data model objects (DMOs) by optimizing data retrieval beyond primary key fields.
- **[Schedule a Secondary Index Refresh](https://help.salesforce.com/s/articleView?id=data.c360_a_schedule_secondary_index_refresh.htm&release=264.0.0&type=5)**
Set how often Data 360 refreshes a secondary index so that the index stays current with the underlying object. Choose a refresh frequency that keeps the index fresh enough for your queries without refreshing more often than your data changes.
# Optimizing Search Indexes: Field Selection and Chunking
When you create a search index in the advanced builder, you can optimize your search index to deliver more accurate results by paying attention to the field selection and chunking strategies you use.
## Indexing Text Fields
If you want to add text fields when creating a search index, select text fields with longer, free-text content. You can even index multiple text fields from a DMO. For example, if you select the `Description`, `Summary`, `Content`, and `Resolution` fields from a DMO, Data 360 stores all corresponding vectors in the same search index.
You can separate vectors on the basis of the `DataSource__c` field in the [Index DMO](https://help.salesforce.com/s/articleView?language=en_US&id=data.c360_a_search_index_index_dmo.htm&type=5). The `DataSource__c` field contains the original field name. Because this field is in the Index DMO, you can use it in a retriever’s prefilter. For example, you can configure a retriever to evaluate queries on semantic similarity to a specific field only, such as `Description` and not `Resolution`.
Avoid selecting too many similar fields or redundant fields (for example, `Summary`, `Title`, and `Description`). Doing so can lead to decreased recall if your retriever doesn’t have prefilters on `DataSource__c`. Because these fields all likely contain the same, or very similar information, at least three chunks (one chunk for each field) from the same document can appear highly ranked in the query results. These bring the same information to the LLM, and if you configure the retriever to retrieve, for example, nine results, only three documents will be represented in the results. This reduces variation in your search results and can lead to documents being missed.
We recommended that when two or more fields represent the same content, but in a different form, select the field with the longest text, such as `Description`. Consider prepending that field with a shorter, more condensed version, such as `Title`.

Tip Don’t select categorical columns as index fields. Categorial data is single-word or two-word descriptors that map to a picklist in Salesforce. To create useful results, semantic search requires a longer textual scope and more context.
## Using Prepend Fields
One way to optimize your [chunking strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_supported_chunking_strategies.htm&release=264.0.0&type=5 "Data 360 supports several chunking strategies. Data 360 automatically chooses the optimal chunking strategy based on the content type you're working with.") is to use prepend fields to add context to chunks and make them easier to identify. For example, suppose you have a chunk that contains a sequence of troubleshooting steps. By prepending that chunk with the `Title` field that contains the text “How to Fix Device X When It Shows Behaviour Y,” you make it easier to identify that content as relevant to a user’s question. Prepending fields like `Title` or `Product Name` add those values to a chunk, which makes them visible in prompt augmentation or in the Data 360 Query Editor.
## Adjusting Chunk Size
Another way to optimize chunking is to tune the chunk size.
When you create a default search index, Data 360 uses the semantic-based passage extraction markers to chunk your content into pieces as small as possible. Data Cloud then lumps the chunks back together until it reaches the chunk size you specify, or the default maximum chunk size (512 tokens).
You’ll find this requires some experimentation, as the optimal chunk size and strategy varies per RAG or agent implementation.
For more information, refer to [How the Max Token Setting Affects Chunking](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_max_token_setting.htm&type=5&language=en_US).
## Optimizing Chunks for Retrieval
When planning the size of your chunks for retrieval, consider the information density and organizational structure of the content you’re chunking. Remember that one chunk results in one vector. All the content in the chunk is represented in this single vector. Consider how many words are needed to adequately understand the meaning of a chunk. Will 400 to 500 words work? Or can fewer words sufficiently capture a self-contained, piece of information (possibly enhanced with field prepending or chunk enrichment)? Those are the kinds of questions that should come up in your planning.
## Optimizing Chunks for Prompt Augmentation
You should also consider chunking from a prompt augmentation perspective. How many chunks does your LLM need to generate a sufficiently usable response? Is a small, individual factoid useful enough, or does your LLM require more context?
For UDMO-based search indexes, augmentation of content typically relies on chunk size, in which case, chunks need to be larger to include extra context.
For DMO-based indexes, you have more options because you can use additional fields for augmentation. It’s even possible to augment the prompt using the original document (for example, a knowledge article) instead of a single chunk. This increases the resolution of your prompt resolution, so consider the context window of your LLM in relation to the selected number of results. But keep in mind that such prompts increase the cost of response generation: in other words, if you increase the prompt and response size, you consume more Einstein Requests.
# Organization Unit Identifier
The Organization Unit Identifier is an optional field that allows you to specify business units in your Data 360 data.
When set, the Organization Unit Identifier is used in the Data Lineage of a record. The Marketing Cloud Engagement connector has a notion of business units, so this field lets you consistently tag all your other data source objects with a business unit if desired. If your data isn’t business unit specific but want to configure this field, use a formula field to write a hardcoded string value and set that formula field to the Organization Unit Identifier.
# Outliers Alert
Outliers are data points that significantly differ from the majority in a dataset. The alert indicates that at least one outlier was detected and that there's a presence of uncommonly small or large numbers. Outliers can skew model performance, reduce accuracy, and lead to incorrect forecasts.
## Actions to Consider
There are two types of outliers.
- incorrect values due to data entry errors, processing errors, or other issues.
- correct values that reflect an extraordinary, non-recurring, or infrequent event.
Investigate to determine which outliers to keep and which ones to exclude from your model. Exclude incorrect values and consider fixing them before model training.
## Detection Methodology
For a variable, Model Builder:
- calculates the global mean and global standard deviation of its values.
- designates an outlier as any value that's greater than, or less than five standard deviations away from the global mean.
## Example
A retailer wants to predict unit sales for different products. To achieve this, the retailer builds a regression model with these input variables.
- product ID
- unit price
- day of the week
- store location
- stock availability
- competitor unit price
- promo event
After model training, an alert displays because a high outlier score is detected for a product. Most products sell between 10 and 100 units per day but records show sales over 1000 units per day. To resolve the issue, here are some actions to consider.
- Remove data points that may have resulted from errors.
- Include the outliers score during training to help the model learn patterns that indicate regular sales amounts. Then, use the data to identify transactions that significantly deviate from the norm.
- Retrain the model with an updated dataset.
# Override an Object’s Default Reconciliation Rule
Override an object’s default reconciliation behavior by applying a reconciliation rule to a specific field.
1. Navigate to the record home page of your identity resolution ruleset.
2. Select a field, or, select multiple fields and click **Assign**.
3. Disable the Default Reconciliation Rule and select a different rule.
4. Click **Save**.
#### See Also
- [_Salesforce Help_: Set a Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setdefault.htm&release=264.0.0&type=5 "Set a default reconciliation rule for each object in your identity resolution ruleset. The default reconciliation rule tells the identity resolution process how to select values for all fields in an object.")
# Package Your External Activation Platform for Distribution with Package Manager
After you created your External Activation Platform and custom metadata, use Package Manager to package and distribute your External Activation Platform to Data 360 Admins. A managed package is recommended because you can provide updates to admins when anything changes with the package. Only managed packages can be distributed through AppExchange.

Warning Distributing unmanaged packages could expose your Amazon S3 credentials and prevent you from pushing new package versions to admins.
1. Navigate to Package Manager.
2. Under Namespace Settings, make sure you have an existing Namespace before creating a package. If you don’t, click **Edit** to create one.
3. Under the Packages section, click **New** or select an existing package.

Important Each org supports only one managed package. If you already have an existing managed package in this org, select that package and upload a new version to it instead of creating a new package. Adding a new version doesn't affect previously published versions.
4. For a new package, enter information about your package. The Package Name is what your Data 360 Admins see to install.
5. Select the **Managed** checkbox.

Note The Managed checkbox is only available when creating a new package. If the checkbox is grayed out, your org already has a managed package. In that case, select the existing managed package and upload a new version.
6. Click **Save**.
7. In Components, click **Add**.
8. For Component Type, select **Activation Platform**.
9. Select your External Activation Platform.
10. Click **Add to Package**.
11. Under the Components tab, click **Add** again.
12. For Component Type, click the dropdown list and select **ActivationPlatformCredential**.
13. Select the checkbox next to your auto-created custom metadata. For JSON-based external activation platforms, the platform credential displayed matches the platform's developer name specified in the JSON configuration.
14. Click **Add to Package**.
15. Click **Upload**. Package Manager generates a URL for your package.
16. Enter information about your package details like Version Name and Version Number.
17. In Release Type, select **Managed - Release** production distribution.

Tip Select **Managed - Beta** for testing in a non-production environment before production distribution.
18. Click **Upload**.
19. When your upload is complete, share the installation URL directly with admins, or become an ISV Partner and list your package as an app on AppExchange.
Your External Activation Platform is packaged and ready for Data 360 Admins to install and use.

Note Some changes to your external activation platform versions require admins to resave previously created activation targets. To avoid problems when distributing new versions of your package, we recommend:
- Not removing existing identifier types, like hashed email, in future version upgrade.
- Maintaining the same optional or required settings for fields and the same default value for hidden fields.
- **[Testing an Activation Platform Package](https://help.salesforce.com/s/articleView?id=data.c360_a_test_your_new_activation_platform_package.htm&release=264.0.0&type=5)**
Test an activation platform package by installing it either in an Enterprise or Developer Edition org that has a provisioned Data 360 license. For more rapid testing and inspection of file outputs as you develop your app, use a Dev org to trigger manual activation publish. When testing your activation platform app in an Enterprise org, activation files are published every 24 hours if the activation output is grouped by user identifiers (PER\_USER). If the activation output is grouped by segments (PER\_SEGMENT), the refresh schedule is tied to the segment publish schedule.
# Packaging Data 360 Enrichments
Use second-generation managed packaging (2GP) to move Data 360 enrichments between orgs.
### Required Editions
User Permissions Needed
To create packages:
Create AppExchange Packages permission
To upload packages:
Upload AppExchange Packages permission
To create a data kit:
Data Cloud Architect permission set
You need a Salesforce developer edition org to create the package and a subscriber org to install it.
Using a first-generation managed package (1GP) to deploy direct DMO metadata has significant limitations. All dependencies must be included within a single package, meaning foundational CRM components, the `FieldSrcTrgtRelationship`, the data kit, and any CRM customizations that reference the relationship can't be split into separate packages. Currently, 1GP provides no way to control or sequence the order in which metadata is deployed in the target org during installation. As a result, if the package contains both the relationship metadata and a referencing customization (such as a page layout, Apex class, or Flow) the deployment may fail because we can't guarantee that the relationship is created before the customization. Due to these sequencing and dependency constraints, direct DMO packaging is not supported with 1GP managed packages and should instead be implemented using 2GP packaging, which allows dependencies to be split across packages and installed in a set order.
1. In your Salesforce DX project, create a scratch org to serve as the source of truth for package development.
2. In the scratch org, configure foundational CRM metadata such as custom objects and custom fields.
3. Configure your direct DMO relationship, which creates a `FieldSrcTrgtRelationship`.
4. Create a Data 360 data kit containing any custom Data 360 metadata you created.
5. Review and publish the data kit to ensure all required dependencies are included.
6. Retrieve the metadata for your CRM components, data kit, and relationship into the Salesforce DX project.
7. Create the first 2GP package, which contains foundational CRM metadata (custom objects, custom fields); the `FieldSrcTrgtRelationship` and custom lookup field for the relationship; and the data kit.
8. In the same scratch org, create additional CRM customizations (such as page layouts, Apex classes, or Flows) that reference the direct DMO relationship.
9. Retrieve these customizations into your project.
10. Create the second 2GP package, which contains CRM customizations that reference the direct DMO relationship.
11. Install both packages in sequence (first foundational, then customizations) to deploy direct DMO functionality in the target org.
# Packaging in Data 360
A package can contain small individual components or a large set of related apps. You create a data kit with the packageable features and add the data kit to a package. You can distribute this package to other Salesforce users and orgs, including people outside your company.
### Required Editions
Available in: Lightning Experience in all editions except Starter
## Packageable Components
To know more about the support available for Data 360 packageable components, see [Data Cloud Extensibility Readiness Matrix](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_isv_readiness_data.htm).
## Managed Package
Use a managed package if you plan to list an app on AppExchange. Managed packages use namespaces that make the content unique to the developer. They also support versioning and push upgrades that allow you to upgrade the packages that are installed in subscriber orgs.
Some Salesforce customers use packaging as part of their application lifecycle management.
## Unmanaged Package
You can create an unmanaged package in any Salesforce edition (Enterprise, Unlimited, Performance, and Developer). Unmanaged packages aren’t upgradable, but all the contents in the package are editable after installation. To replace the installed contents with a newer version, uninstall then reinstall the newer unmanaged package.
## Dedicated Data 360 Package
When creating a managed package with Data 360 metadata, you must isolate the Data 360 metadata from the other Salesforce metadata by creating separate packages that contain only Data 360 metadata. Then create package dependencies between your dedicated Data 360 package and any related packages.
## Unlocked Packages
An unlocked package is a container for your Salesforce metadata. It provides a trackable way to add, edit, remove, and deploy customizations across orgs, making it easier to manage and upgrade internal business applications. Unlocked packages aren't supported for Data 360 objects.
## Second-Generation Managed Packaging in Data 360
Salesforce has first-generation managed packaging (1GP) and second-generation managed packaging (2GP). Going forward, we recommend that all new packages be created using the second-generation managed package. You can use managed 2GP packaging to organize your source, build small modular packages, integrate with your version control system, and better use your custom Apex code. With version control being the source of truth, there are no packaging or patch orgs.
## Locking and Unlocking Metadata in a Managed Package
All Data 360 feature metadata in a managed package is locked. As a package owner, you can control and protect the data kit metadata from unauthorized changes. After you install a package and deploy the data kit components, the components are locked. Susbcribers can add entities but can't modify or delete any deployed mappings or entities. If modifications are made to the deployed metadata entities, they're overwritten when the data kit is redeployed.
## Versioning
Package versions let you evolve the components in managed packages gracefully by releasing subsequent package versions without breaking existing users using the package.
## Push Upgrade
Automatically upgrade your subscriber to a newer version of the package. You can use this feature to ensure that all your orgs are on the same or latest version of your package.
## AppExchange
Packages must be in a Managed-Released state to be listed on AppExchange for distribution.
## Additional Resources
To learn more about this topic, review the associated Trailhead content.
[Packaging and Data Kits in Data Cloud](https://trailhead.salesforce.com/content/learn/modules/packaging-and-data-kits-in-salesforce-cdp)

- **[Create and Install Your Managed Package for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_install_package.htm&release=264.0.0&type=5)**
Use a managed package to build a Data 360 app and distribute it on AgentExchange. Packaging is the container that you fill with metadata, and it holds the set of related features, customizations, and schema that make up your app. A package can include many different metadata components, and you can package a single component, an app, or library.
- **[Packaging Data 360 Enrichments](https://help.salesforce.com/s/articleView?id=data.c360_a_packaging_data_cloud_enrichments.htm&release=264.0.0&type=5)**
Use second-generation managed packaging (2GP) to move Data 360 enrichments between orgs.
#### See Also
- [_Salesforce Help_: Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_data_package_kits.htm&release=264.0.0&type=5 "Use a data kit in Data 360 to streamline package creation and installation. You can manage all packageable Data 360 features in the data kit. You can create data stream bundles and also include data model customization and relationships.")
# Parent-Child Hierarchy in Data 360
A parent-child tag hierarchy organizes tags in a logical, multi-level structure, where broader, general tags (parents) are linked to more specific, detailed tags (children).
This hierarchical approach standardizes tagging, improves clarity, and enables scalable policy application across related data elements. For example:
- Personal Information (Parent Tag)
- Email Address (Child Tag
- Phone Number (Child Tag)
- Home Address (Child Tag)
Tag hierarchies standardize data labeling across your organization and support inheritance. When you assign a parent tag to an object, its related child tags can be included as part of the classification to make it easier to apply policies at scale. If you assign a child tag to an object, the corresponding parent tag is automatically applied, and any policies linked to the parent tag are enforced. However, if you assign only the parent tag, policies tied to child tags aren’t enforced unless you explicitly add those child tags to the object.
# Parsing and Preprocessing Content
Prepare unstructured data for chunking by using Data 360 content parsing and preprocessing methods. Parsing and preprocessing identify document structures, such as headings, paragraphs, or tables, remove irrelevant content, and prepare the text for chunking and indexing.
- **[LLM-based Parsing and Preprocessing](https://help.salesforce.com/s/articleView?id=data.c360_a_llm_parsing_preprocessing.htm&release=264.0.0&type=5)**
Use LLM-based parsing and preprocessing to extract and prepare text, metadata, tables, and images from unstructured documents for chunking.
- **[Docling Parser](https://help.salesforce.com/s/articleView?id=data.c360_a_docling_parser.htm&release=264.0.0&type=5)**
The Docling parser is a third-party intelligent document parsing framework that brings together multiple open-source models for layout understanding and table extraction. To enhance responses from information available in images and complex tables, combine the Docling parser with image processing by using Large Language Models (LLMs).
# Party Data Model
The Customer 360 Data Model party subject groups data model objects (DMO) that reflects contact information (personal or business) for a specific customer or account.
The term “party” can refer to a subject area, a DMO called Party Identification, or unique identifying fields in Data 360.
| Term | Description | How It’s Used |
| --- | --- | --- |
| Party Subject Area | The party subject area is a grouping of DMOs related to a contact’s data. | A subject area helps organize similar DMOs in a data model. |
| Party Identification DMO | A DMO that contains multiple fields about a contact, including identifiers and unique numbers, like a driver’s license. | Data stream data is mapped to this DMO. |
| Party Identification ID | A field in the Party Identification DMO. | This field is used as a primary key and the unique identifier of a contact. |
| Party | A field in the Party Identification DMO. | This reference ID is used as a foreign key. It’s also used in the Individual DMO. |
The party data model includes the individual, account, and, if using identity resolution, unified individual DMOs.
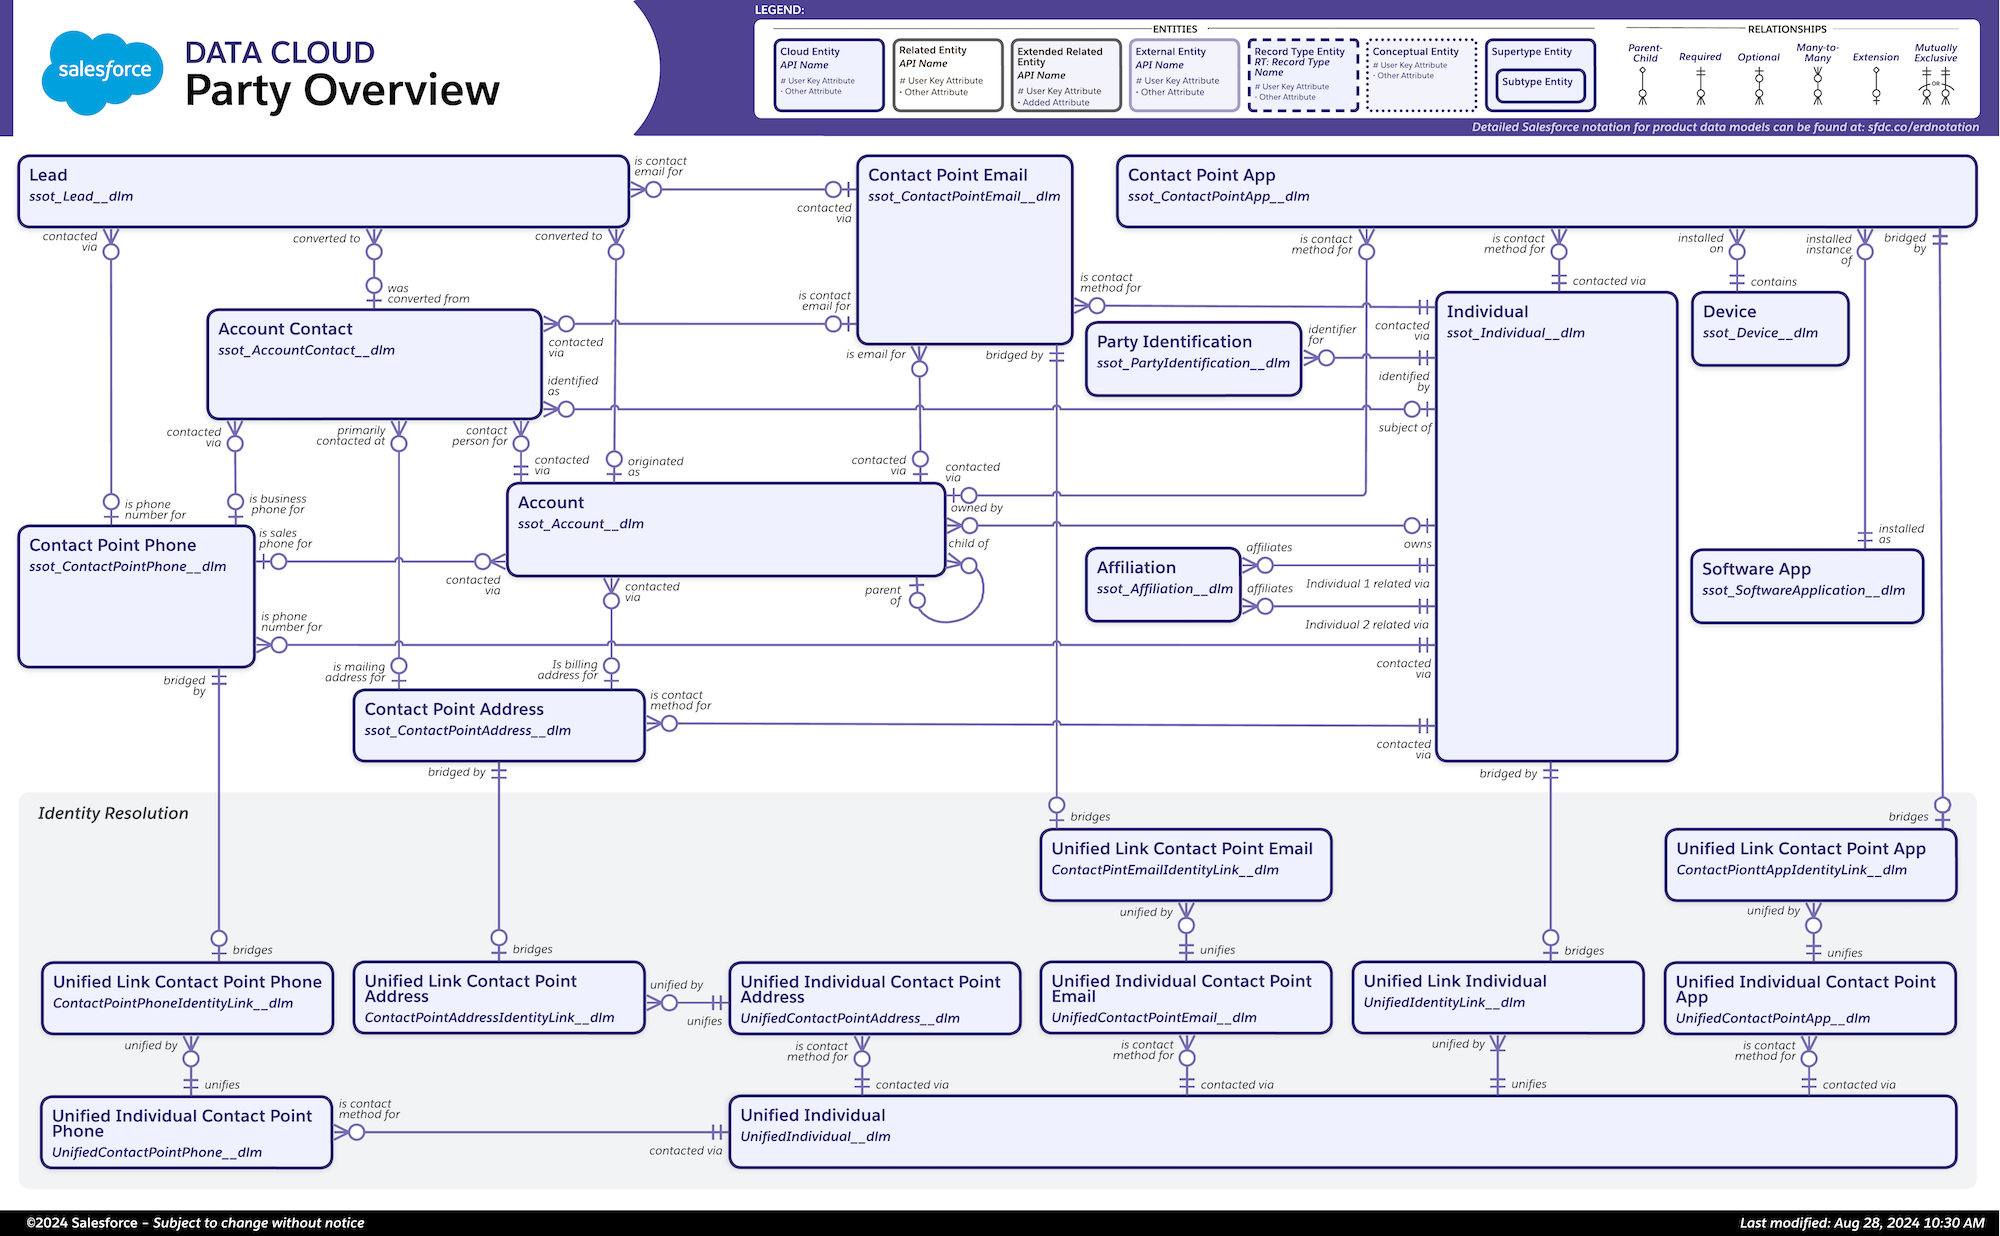
For more details and a larger image, visit the [Data Model Gallery](https://developer.salesforce.com/docs/platform/data-models/guide/party.html).
These DMOs are represented in the party subject area.
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Account | A Data 360 DMO for how a party wants to interact with your company. | [Account DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_account_dmo.htm) |
| Account Contact | A Data 360 DMO for an individual who has a role specific to an account. | [Account Contact DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_account_contact_dmo.htm) |
| Contact Point Address | A Data 360 DMO based on the mailing address of a party. | [Contact Point Address DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_address_dmo.htm) |
| Contact Point App | A Data 360 DMO for the software application of a party on a specific device. | [Contact Point App DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_app_dmo.htm) |
| Contact Point Email | A Data 360 DMO for the email address of a party. | [Contact Point Email DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_email_dmo.htm) |
| Contact Point Phone | A Data 360 DMO for the phone number of a party. | [Contact Point Phone DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_phone_dmo.htm) |
| Contact Point Social | A Data 360 DMO for the social media information of a party. | [Contact Point Social DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_social_dmo.htm) |
| Individual | A Data 360 DMO for contacts, customers, or other people interested in your company’s products or services. | [Individual DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_individual_dmo.htm) |
| Lead | A Data 360 DMO for a person or company that shows interest in your company’s products or services. | [Lead DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_lead_dmo.htm) |
| Party Identification | A Data 360 DMO for the ways to identify a party, for example, a driver’s license or a birth certificate. | [Party Identification DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_party_identification_dmo.htm) |
# Plan Your Data 360 Data Strategy
Before you implement Data 360, it’s important to plan ahead and discuss your strategy. Review org architecture, your own organizational data, and Data 360 data concepts.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
To learn more about this topic, review the associated trail, [Build a Data Strategy for Data 360](https://trailhead.salesforce.com/en/content/learn/trails/build-a-cdp-data-strategy).

- **[Data 360 Architecture Strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_architecture_strategy.htm&release=264.0.0&type=5)**
As you plan your multi-org architecture, consider these data tenancy, residency details, and administrative management details. In some cases, you need more than one Data 360 instance to fulfill legal or business requirements.
- **[Real-Time Capabilities in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_real_time_capabilities.htm&release=264.0.0&type=5)**
By using the real-time capabilities of Data 360, you can enable consistent, synchronized customer data across all platforms. Real-time features provide sub-second data processing across multiple customer interactions.
- **[Data Model Concepts](https://help.salesforce.com/s/articleView?id=data.c360_a_understanding_and_using_the_data_model.htm&release=264.0.0&type=5)**
Improve the interoperability of data across applications, and map data between your connected data sources and the Data 360 Customer 360 Data Model.
# Plan Your Snowflake Environment for Identity Boost
Before accepting identity boost collaboration invitations, decide how to isolate customer data in your Snowflake account and which region to use. These decisions affect the architecture of every collaboration that you accept, so make them before you receive your first invitation.
### Required Editions
Available in: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
## Choose a Multitenant Isolation Model
If you're collaborating with multiple consumers, choose how to isolate each consumer's data in your Snowflake environment. Choose one of these two isolation models.
| Feature | Object per Tenant (OPT) | Account per Tenant (APT) |
| --- | --- | --- |
| Isolation boundary | Separate database and schema within one Snowflake account for each customer | Separate Snowflake account per customer |
| Security guarantee | Depends on role-based access control (RBAC) configuration | Hard platform boundary — not dependent on RBAC |
| Operations overhead | Lower — one account, one job deployment | Higher — separate account, job deployment, and security integration per customer |
| Recommended for | Partners with a mature Snowflake RBAC practice | Partners with regulated-industry customers or strict data isolation requirements |

Note In the Object Per Tenant model, your enrichment job runs at the account level. A misconfigured role can expose another customer's data to the enrichment job. If you use this model, scope each customer's enrichment job execution role strictly to that customer's database and schema, and never use ACCOUNTADMIN or SYSADMIN roles for enrichment job execution.
## Choose a Snowflake Account Region
When your Snowflake account is in the same AWS region as a consumer's Data 360 instance, Data 360 uses Snowflake's zero-copy sharing for the data share, which doesn't consume Data 360 credits. If the regions differ, Data 360 physically replicates the data and consumes Data 360 credits.
When you receive an invitation, the **Consumer Salesforce Region** field on the Accept Clean Room Collaboration Invitation wizard shows the consumer's region. Use that value to confirm that your account is in a compatible region before you accept.
If you serve customers across multiple regions, provision one Snowflake account per region to avoid cross-region data transfer fees. If you maintain a single account, AWS US-east-2 (Ohio) is compatible with all US-based Data 360 regions.
# Platform Encryption for Data 360
Some customers require tenant-specific encryption keys, control over key material, or improved key visibility for auditing and compliance reporting. Platform Encryption for Data 360 extends Data 360’s robust security services by adding options for encryption key control and visibility.
### Required Editions
Available in: All Editions supported by Data 360. See Data 360 edition availability . Available with add-on license: Enterprise , Performance , Unlimited , and Developer Editions. Requires purchasing Salesforce Shield or Shield Platform Encryption, and Platform Encryption for Data Cloud. Also, to use the optional External Key Management, requires purchasing the Platform Encryption for Consumption license.
## Encryption Options in Data 360
Salesforce offers three key management options for encrypting data in Data 360.
These options give customers flexibility in how they manage encryption keys and comply with their internal security policies.
Encryption Option
Description
Customer Managed Keys (CMK)
Salesforce generates and manages tenant-specific keys in the Salesforce
UI.
EKM
Customers manage encryption keys externally using an AWS KMS account.
Bring Your Own Key (BYOK)
Customers can bring their own key material directly into the Salesforce UI
without needing an AWS KMS account. This option benefits customers who prefer not to
access AWS KMS or use other key storage providers such as Azure or on-premise
vaults.
All data in Data 360 is encrypted at rest in AWS by Salesforce-managed data encryption keys (DEKs). This is the Customer Managed Keys option. With Platform Encryption for Data 360, you create a Data 360 root key in Salesforce. You can also use EKM to create the key in an external Key Management System (KMS) or BYOK. Your Data 360 root keys are specific to your org, and control the DEKs that encrypt and decrypt your data, giving you ownership of the key chain that secures your information.
Platform Encryption for Data 360 encrypts data only in your production environment. Sandbox environments are not automatically encrypted when you enable encryption in production. To encrypt data in a sandbox, you need to turn on Manage Data 360 Keys feature separately in each sandbox.
Root keys are compatible with Sub-Second Real-Time feature. However, when you enable Sub-Second Real-Time in an org with an active Salesforce root key for Data 360, the root key becomes usable within 24 hours.
## Default Data 360 Encryption without Platform Encryption
By default, Data 360 uses end-to-end encryption to secure data as it transits into Data Cloud and between products within the trust boundary. Hyperforce’s infrastructure-level encryption provides cloud-native disk encryption for data stored at rest. While infrastructure-level keys aren’t tenant-specific, Salesforce stores these keys securely and rotates them regularly.
To learn more about how Data 360 and Hyperforce secure your data, see [Salesforce Security and Compliance page](https://compliance.salesforce.com/en)
- **[Set Up Platform Encryption for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_platform_encryption_data_cloud.htm&release=264.0.0&type=5)**
When you enable Platform Encryption, your first Data 360 root key generates automatically. This key encrypts all previously ingested data in Data 360. After the initial setup, you can continue to use the generated root key or configure an external key using External Key Management (EKM), or leverage your own key material using Bring Your Own Key (BYOK) in the Salesforce UI to encrypt data in Data 360. You can rotate root keys periodically and view key metadata, such as creation time and creator, in Setup.
- **[Root Key Lifecycle](https://help.salesforce.com/s/articleView?id=data.c360_a_root_key_lifecycle.htm&release=264.0.0&type=5)**
Root key statuses in Platform Encryption define the usage of each key for data encryption and decryption.
#### See Also
- [_Salesforce Help_: Encrypt Data Cloud with Customer-Managed Root Keys](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_enable_pe_for_data_cloud.htm&type=5&language=en_US)
- [_Salesforce_: Security and Compliance](https://compliance.salesforce.com/en)
- [_Salesforce Help_: Strengthen Your Data’s Security with Shield Platform Encryption](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_overview.htm&language=en_US)
- [_Salesforce Help_: Differences Between Classic Encryption and Shield Platform Encryption](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_vs_classic_encryption.htm&language=en_US)
- [_Salesforce_: Shield Platform Encryption Architecture](https://resources.docs.salesforce.com/254/latest/en-us/sfdc/pdf/security_shield_platform_encryption.pdf)
- [_Salesforce Help_: Encrypt Data 360 with Customer-Managed Root Keys](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_enable_pe_for_data_cloud.htm&type=5&language=en_US)
# Policy Behavior on Core Applications in Data 360
Core applications such as Related Lists and Copy Field Enrichment follow specific policy behaviors. While some features honor user-level access controls, others run in system mode and require additional security measures at the CRM level.
## Key Enforcement Callouts for Creating Core Application Configurations in Data 360
feature area
how policies are enforced
Related List
The Data Cloud architect permission set includes View All and Modify All
permissions. As a result, the Data Cloud architect can have unrestricted access
when configuring the related list metadata.
Copy Field Enrichment
The process runs in system mode, so all records are copied from Data 360
objects to the target CRM objects. You can then apply CRM security on top.
# Policy Behavior on Process Definitions
Data 360 process definitions describe the workflows and tasks used to manage data such as data streams, transformations, calculated insights, segments, and identity resolution. These definitions help standardize how data operations are created and executed. Data governance policies are enforced when users create or consume these definitions.
## Key Enforcement Callouts for Creating Process Definitions in Data Data 360
Here's how policy enforcement works when you create a process definition:
- Objects available for selection are filtered according to the user's context and policy.
- Data graphs are available for use when the user has access to the ID, value, and fragment DMOs in addition to the underlying DMOs and CIOs used in the definition.
- Calculated Insights are available for use when the user has access to the underlying DMOs and CIOs used in the definition. Access to the Calculated Insight output object is also required.
- Users with View All and Modify All permissions on the data object can view all metadata and can create process definitions.
Here are some additional nuances or exceptions related to field enforcement and the View All and Modify All permission experiences.
feature area
how are policies enforced
Activation
Users with View All and Modify All permissions on the data object can save the
activation, but can’t construct the activation definition as they don’t have
direct access to the underlying entities required for the attribute library map
(ALM) to load.
Field enforcement is in effect for this experience.
Calculated Insight (CI)
An object’s field list isn’t filtered to honor the policy. However, field
access is verified when validating or saving the CI. As such, users with
insufficient access to a field can't save the CI.
Objects or fields that are manually referenced in the syntax fail to validate
if the user has insufficient privileges due to policy.
Users with View All and Modify All permissions on the data object can see all
metadata when creating a CI. However, the CI fails to validate and save if the
user has insufficient privileges based on the policy.
Code Extensions
Object and field enforcement doesn’t apply to this experience. You must
manually assign and audit the appropriate governance tags on target DLOs or DMOs
that your code extension scripts create or update, including the
DataCustomCodeLogs__dll DLO.
Row-level security (RLS) policies apply during code extension script
development when you query data from outside Data 360, but not during runtime
execution. As a result, you may see fewer records during development than are
processed during execution.
Data Actions
Data Graph
Object and field enforcement is in effect for this experience.
Creating a data graph on an engagement type DMO requires access to a “Date”
type field to establish recency criteria. Without these fields, users can’t save
the data graph.
Users with View All and Modify All permissions on the data object can
initially view all metadata when selecting the primary DMO. But since object
enforcement applies on the Policy Builder canvas, the data graph fails to save
if the user who creates the data graph doesn't have access to the Primary
DMO.
Exception to data graph behavior: Data graphs are available for use when the
user has access to the ID and value DMOs and all of their fields. There’s no
underlying access check on the DMOs or CIOs used in the data graph.
If a DMO has a deny field-level security (FLS) policy, access to the entire
data graph is restricted.
If a data graph includes restricted objects, it remains visible in the list
view while in draft state, but its definition isn’t accessible.
Segmentation
Object and field enforcement is in effect for this experience.
Users with View All and Modify All permissions on the data object can save the
segment, but can’t construct the segment definition as they don’t have direct
access to the underlying entities required for the attribute library map (ALM)
to load.
Row-level security (RLS) policies aren’t enforced during segment creation. As
a result, all records within the object are considered when a segment is
created.
Transforms
Object and field enforcement is in effect for this experience.
To enable data preview in the Input node, users must first select a data
space. If no data space is selected, the preview is disabled. When joining
multiple DLOs, all input nodes must use the same data space to enable downstream
previews. If different data spaces are selected, the transform can still be
authored and saved, but preview functionality is disabled for subsequent
nodes.
Users with View All and Modify All permissions on the data object can
initially preview all data and metadata when building a transform. However, the
transform fails to preview or save if the user lacks access to required fields
or objects based on data governance policies.
If fields or objects are manually referenced in expressions or SQL syntax, the
transform fails to validate if the user does not have access based on the
applied policy.
Row-level security (RLS) policies are enforced during transform preview, but
not during runtime execution. As a result, users may see fewer records during
preview than are processed during execution.
Einstein Studio
Object and field enforcement is in effect for this experience.
Users with View All and Modify All permissions on the data object can
initially view all metadata when selecting a predictive model entity. But since
object enforcement applies on the Policy Builder canvas, search index fails to
save if the creating user doesn’t have access to the DMO used for the predictive
model entity.
Search Index
Object and field enforcement is in effect for this experience.
Users with View All and Modify All permissions on the data object can
initially view all metadata when selecting the Search Index On entity. But since
object enforcement applies on the Policy Builder canvas, search index fails to
save if the creating user doesn’t have access to the DMO used for the Search
Index On entity.
Identity Resolution
High Scale Flow
## Key Enforcement Callouts for Consuming Process Definitions in Data Cloud
A process definition appears in the list view for the feature area when a consuming user:
- Has access to the data space
- Has access to all of the dependent objects that are used in the definition
A user with View All and Modify All permissions for the data object can view all process definitions in the list view.
feature area
how policies are enforced
Activation
Users must have access to all underlying CIOs and DMOs, including entities in
the relationship path.
When working with data graphs or segments, users must have access to all
entities within the data graph or segment.
Calculated Insight (CI)
To view the CI process definition, users must also have access to the
underlying DMO, DLO, and CIO.
Data Actions
Users can view the data actions only if they have permission to access all the
related objects.
Data actions shown on the data action target are filtered to only those that
the user has permission to view.
Data Graph
Users must have access to the ID, value, and fragment DMOs in addition to the
underlying DMOs/ CIOs used in the definition.
Users with View All and Modify All permissions can initially see all data
graph process definitions in the list view, but they can’t view the data graph
definition in Policy Builder if they don’t have access to all the necessary
inputs.
Segmentation
For the waterfall segment, the segment name appears in the filter criteria,
but the user can’t access the original segment's definition.
Activations displayed on the segment record home are filtered to include only
those where the user has access to all related dependent objects.
Users with View All and Modify All permissions can initially see all segment
process definitions in list view, but they can’t view the segment definition if
they don’t have access to all necessary inputs.
Transforms
Transforms are hidden from the list view if the user lacks access to the
underlying object or all of its fields.
Search Index
Users must have access to all the DMOs in the relationship path.
Users must have access to the search, index, chunk, and attachment DMOs.
Identity Resolution
Users must have access to the unified result and the unified link DMOs in
addition to the DMOs used in the rule.
High Scale Flow
When a scheduled flow is triggered the governance policies applied at the time
of creation of the flow is enforced.
Row-level security (RLS) policies aren’t enforced when flow is triggered on
schedule.
# Policy Behavior When Consuming Data Streams and Data Objects
When you view or work with data objects in Data 360, access policies determine what you can see and use.
object type
what users can do
Data Stream
Users can view a data stream only if they have access to the underlying data
lake object (DLO).
Users can see the data stream mapping if they have access to the data space.
However, the mapped field counts show only fields relevant to the user, excluding
any fields on data model objects (DMOs) they can't access.
DLO
Users can use only those DLOs that are permitted by their policies.
DMO
Users can use DMOs that their access policies permit.
Users can use DMO relationships that their access policies permit.
CIO
Users can view a calculated insight object (CIO) only if they have access to the CIO object.
You can apply field-level security (FLS) policies to a CIO to restrict which
fields are visible to each user.
## Key Enforcement Callouts When Consuming Data Objects
Here are some key callouts on how governed data behaves in Data 360, including its unique policy rules and exceptions.
object type
what users can do
DLO
Users with View All and Modify All on the DLO can view all metadata. Data
space assignment and policy control query access.
Users can view masked fields in object-level pages such as Data Explorer,
Profile Explorer, and Query Editor, depending on their access.
CIO
CIOs don’t have their own dedicated tab, so enforcement in the UI relies on
the CI process definition along with the CIO.
When an FLS policy restricts access to a dimension and you query an
aggregatable metric, the metric value automatically excludes the restricted
dimension and rolls up to the defined dimension level.
When an FLS policy restricts access to a dimension, any non-aggregatable
metric is automatically restricted, even if no tags or explicit policies are
defined.
When you add a CIO to a semantic data model and apply an FLS policy that
restricts access to a dimension, users are also restricted from viewing any
metric that uses the same aggregation function.
When you apply a masking policy, metric results in semantic data model queries
can vary based on the rounding behavior that the policy defines.
DMO
Users with View All and Modify All permissions on the DMO can access DMO
metadata, but the policy determines whether it permits the query.
Users can still view masked fields in object-level pages such as Data Explorer,
Profile Explorer, and Query Editor, depending on user access. For users where
masking applies, these fields appear as masked.
Search Index
When you create a search index, the system automatically generates derived
objects such as chunk and vector DMOs, to store the searchable data. These derived
objects inherit the security policies, including object-level, field-level, and
record-level security, applied to the source DMO. This ensures that search results
and retrieval augmented generation (RAG)-driven insights consistently respect the
governance rules of the original data.
Data Graph
Policies are enforced at a granular level when users access data through a
data graph. Users can view only the portions of the data graph that they have
permission to access. Data 360 excludes restricted DMOs and fields from the
results.
Tags on a data graph are inherited from source DMOs and aren’t directly
assigned. The data graph UI doesn’t currently display propagated tags.
## Security Propagation in Chunk and Index DMOs
Security controls applied to source DMOs are enforced on their derived chunk and index DMOs through tag propagation, row-level filtering, and query-time joins. Data 360 also propagates masking to chunk text at the span level.
- Object-Level Security: Data 360 carries object-level security from the source DMO to the derived chunk and index DMOs through classification tag propagation. Access to a chunk or index DMO requires access to the source DMO.
- Field-Level Security: Data 360 enforces field-level security on the chunk DMO through row-level filtering rather than tag propagation. Because the chunk DMO represents each source field as a separate row, Data 360 uses the Data Source field to identify the source field. When FLS denies access to a source field, Data 360 filters out the corresponding row from the chunk DMO.
- Record-Level Security: Data 360 enforces record-level security at query time through joins to the source object. The chunk DMO uses one join, from the chunk to the source object. The index DMO uses two joins: from the index DMO to the chunk DMO, and from the chunk DMO to the source object. Users access only derived rows for source records they already have access to.
- Span Masking: Data 360 applies field-level masking from the source field to the corresponding text in the chunk DMO by using span masking. Span masking masks only the affected portion of the text rather than the entire field.
# Policy Behavior When Creating Data Streams and Data Objects
When you create data streams, data lake objects (DLOs), or data model objects (DMOs), Data 360 enforces access policies to make sure you can only interact with the objects and fields you're allowed to use.
object type
what users can do
Data Stream
Users with permission to create data lake objects can deploy bundles.
After a successful deployment, the resulting data streams, DLOs, and DMOs are
subject to the policy. If the user who initiated the deployment doesn't have
access to the outputs of the bundle, they can't view them afterward.
DLO
Users can create a new DLO from an existing DLO. The DLOs available for
selection are those permitted by their access policies.
After creating a DLO, users still need permission to see it in the list view,
unless they have View All and Modify All permissions.
DMO
Users can create a new DMO from an existing DMO. The DMOs available for
selection are those permitted by their access policies.
After creating the DMO, users must be granted access to it in order to see it in
the list view, unless they have View All and Modify All permissions.
Users can create DMO relationships from a list of objects and fields that are
permitted by their access policies.
Calculated Insight Object (CIO)
Users with permission to create CIOs can use DMOs as inputs to build their
insights. Policies applied to DMOs can impact the DMOs, fields, and rows that the
users can access when defining a CIO.
After creating a CIO, users can apply tags and define policies to further secure
access to CIO data.
Tags are automatically propagated from a DMO to a CIO if the CIO dimension
fields exactly match the corresponding DMO fields. If the CIO dimension is derived
from a formula, tags aren’t automatically propagated.
# Policy Behavior When Querying Data
When you query data in Data 360, whether through Data Explorer, Profile Explorer, or Tableau, governance policies control what you can retrieve. Even if metadata is visible in the UI, actual access is enforced at query time to protect sensitive data.
## Key Enforcement Callouts When Consuming Query API
Here's how governed data behaves in Data 360, including its unique policy rules and exceptions.
In general, when querying data:
- Users can query objects if they have access as defined by the policy.
- Users can query DMOs if they have access to them. There's no underlying access check on DLOs.
- Users can query data graphs if they have access to the ID and value DMOs and all their fields. There's no underlying access check on DMOs or CIOs used within the data graph.
- Users can query calculated insights if they have access to the underlying calculated insight object.
- Field enforcement is applied at the query layer. Users can query fields only if they have access as defined by the policy.
- The View All and Modify All data object permissions don't apply when querying data.
- Users can create or edit masked fields if they have access to the underlying objects and fields. Masking applies at the query layer and doesn’t prevent data input or updates.
feature area
how policies are enforced
Data Explorer
If an FLS policy is applied to a Primary Key or Fully Qualified Key, the query
fails, even if the key isn't included as a selected column.
Exception to data graph behavior: Users can only see the data graphs if they
have permission for all the underlying objects (DMOs/CIOs) and their
fields.
Exception to CI behavior: Users can only see the CI if they have permission
for all the underlying objects (DMOs/CIOs).
Users with View All and Modify All permissions on the data object see all
metadata when interacting with the UI. However, the query fails if the user has
insufficient privileges according to the policy.
Profile Explorer
For unified objects:
If an FLS policy is applied to a Primary Key or Fully Qualified Key, the query
fails, even if the key isn't included as a selected column.
If a user tries to search for a field value that they don’t have access to
under RLS, they can’t view the data.
Query Editor
If a user queries an object with access to only a subset of fields, for
example, SELECT *, the query returns results only for the fields they are
permitted to access.
If a user explicitly references a field they don’t have access to, for
example, SELECT 'ssot__Individual__c', the query fails.
If a user queries an object they don’t have access to, the query fails.
Tableau
If a user queries an object where they only have access to a subset of fields,
the query returns metadata and data results for the permitted fields only.
# Policy Enforcement in Data 360
Policies are enforced across different feature areas in Data 360 depending on whether the user is creating or consuming data. Policy enforcement doesn't take effect immediately in dashboards.
To ensure policies are applied correctly, refresh the dashboard or clear the cache.
- **[Policy Behavior When Creating Data Streams and Data Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_behavior_creating_streams_objects_in_datacloud.htm&release=264.0.0&type=5)**
When you create data streams, data lake objects (DLOs), or data model objects (DMOs), Data 360 enforces access policies to make sure you can only interact with the objects and fields you're allowed to use.
- **[Policy Behavior When Consuming Data Streams and Data Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_behavior_consuming_streams_objects_in_datacloud.htm&release=264.0.0&type=5)**
When you view or work with data objects in Data 360, access policies determine what you can see and use.
- **[Policy Behavior When Querying Data](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_behavior_when_querying_data_in_datacloud.htm&release=264.0.0&type=5)**
When you query data in Data 360, whether through Data Explorer, Profile Explorer, or Tableau, governance policies control what you can retrieve. Even if metadata is visible in the UI, actual access is enforced at query time to protect sensitive data.
- **[Policy Behavior on Process Definitions](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_behavior_on_process_definitions_in_datacloud.htm&release=264.0.0&type=5)**
Data 360 process definitions describe the workflows and tasks used to manage data such as data streams, transformations, calculated insights, segments, and identity resolution. These definitions help standardize how data operations are created and executed. Data governance policies are enforced when users create or consume these definitions.
- **[Policy Behavior on Core Applications in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_behavior_core_applications_in_datacloud.htm&release=264.0.0&type=5)**
Core applications such as Related Lists and Copy Field Enrichment follow specific policy behaviors. While some features honor user-level access controls, others run in system mode and require additional security measures at the CRM level.
# Policy Types in Data 360
Data 360 offers two policy categories in data governance: role-based access control (RBAC) and attribute-based access control (ABAC).
## Role-based Access Control
Role-based access control (RBAC) allows you to manage data access by assigning permissions to users based on their roles.
Use RBAC to grant access to specific data objects, such as data lake objects (DLOs), data model objects (DMOs), and calculated insight objects (CIOs), within a data space through permission sets. RBAC is assigned to individual objects.
## Attribute-based Access Control
Attribute-based access control (ABAC) is a data access control model that grants or denies access to data based on a combination of attributes. These attributes can belong to the user, the data, or the environment.
- User attributes: custom permissions
- Data attributes: tags, sensitivity level, owner, classification
In ABAC, policies use logical conditions that evaluate attributes at runtime. To maintain performance, ABAC policy authoring includes built-in limits based on resource usage. Each policy’s usage depends on the number of rules and the complexity of its conditions. More complex policies use more resources during data access. Data 360 checks this usage against a maximum condition element threshold when you create, update, or delete a policy. Most users won’t reach this limit, but it helps prevent complex policies from affecting performance.
## Tags and Classifications
In ABAC, you can add tags and classifications as decision-making attributes to determine if access is allowed. For example, if an object or a field is tagged as "Confidential" or classified as "PII" (Personally Identifiable Information), you can write access policies that reference these tags. Here’s a sample policy.
“Grant access to users in the Compliance team if the data is classified as Confidential.” Or, “Deny access to any data tagged as PII for users outside the Support team.”
Using tags and classifications this way enables dynamic, context-aware controls that adapt to both the sensitivity of the data and the attributes of the user. It simplifies policy management and ensures consistent enforcement across your data ecosystem.
- **[Create a Role-Based Access Control Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_rbac_access_control_policy.htm&release=264.0.0&type=5)**
Manage object permissions for users asigned to a data space.
- **[Create an Allow All Policy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_allow_all_policy.htm&release=264.0.0&type=5)**
To maintain broad user access without enforcing restrictions, create an Allow All policy in Data 360. This policy grants access to objects within the data spaces assigned to users through permission sets.
# Policy-Based Governance in Data 360
Data governance policies are rules and guidelines that define how data is accessed, used, protected, and managed. These policies help align data handling with security requirements, compliance standards, and business objectives.
Data 360 enables you to simplify policy-based governance and scale it across your data environment with tags and metadata.
- **Apply tags:** Apply tags to data objects and fields to classify them based on sensitivity, business purpose, or compliance needs. Tags enable scaling the data governance policies as multiple objects are protected based on a single metadata attribute.
- **Assign custom permissions:** Assign custom permissions to apply the policy to the appropriate users.
- **Define a policy criteria:** Create data access or masking policies using tags and classifications and assign them to users based on custom permissions. For example, define a policy that grants access to all data tagged as “Non-Sensitive” or masks all fields tagged as “PII.”

Note After creating or modifying a policy, allow 2 to 3 minutes for it to take effect. During this time, the policy’s access controls aren’t active.
## Key Components
Policy-based governance in Data 360 comprises several core components that work together to determine how data access is controlled.
- **Metadata:** Describes the structure of the data, such as object names, field types, and tags that classify and govern the data.
- **Resource:** Refers to the actual data object or field being governed. For example, a customer table or an email field.
- **Subject:** Identifies the user or group the policy applies to. This is defined through custom permissions or user attributes.
- **Policy Definition:** Contains the rule that determines who can access what data, and under what conditions.
- **Policy Enforcement:** The execution layer that applies the policy at runtime, ensuring users only access the data they’re authorized to view and modify.
## Access
Access policies determine if a user can view or interact with specific data. These policies typically allow or deny actions.
An allow policy explicitly allows access to data when certain conditions are met. For example, “Allow access to Sales records where the user’s region matches the record’s region.” Allow policies are commonly used to define who can access data.
A deny policy explicitly blocks access to data, even if other policies allow it. For instance, “Deny access to records marked as Confidential if the user isn’t in the Compliance team.” Deny policies take precedence over Allow policies and are useful for enforcing stricter controls or exceptions.
- **[Policy Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_types_in_dg.htm&release=264.0.0&type=5)**
Data 360 offers two policy categories in data governance: role-based access control (RBAC) and attribute-based access control (ABAC).
- **[Object, Field, and Record Level Security](https://help.salesforce.com/s/articleView?id=data.c360_a_data_access_policies.htm&release=264.0.0&type=5)**
Data governance policies in Data 360 control access to data at different levels such as object, field, and row, based on user roles, attributes, or relationships.
- **[Dynamic Data Masking Policies in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_dynamic_data_masking_policies.htm&release=264.0.0&type=5)**
Dynamic data masking conceals sensitive data without altering its usability, accuracy, or relationships. It applies to all Data 360 objects and fields, regardless of the access method.
- **[Policy Enforcement in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_policy_enforcement_in_datacloud.htm&release=264.0.0&type=5)**
Policies are enforced across different feature areas in Data 360 depending on whether the user is creating or consuming data. Policy enforcement doesn't take effect immediately in dashboards.
# Preconfigured Taxonomies in Data 360
Preconfigured taxonimies are built-in, ready-to-use classification structures provided by the system. They cover common data categories such as personal information, financial data, or health records. Preconfigured taxonomies get you started quickly and follow standard best practices without the need to define categories from scratch.
Data 360 provides these taxonomies out of the box.
Taxonomy or Taxonomy Classification Name Classification Tags Description
Personal Data
PII
Personally Identifiable Information (PII) is any data that can be used to
identify, contact, or locate a single person.
Personal Data
Digital Identifier
Digital Identifier is any data that can be used to recognize, track, or
associate a person with their digital activity across systems or platforms.
Personal Data
Biometrics
Biometrics is any data derived from a person's physical or behavioral traits
that can be used to verify or identify their identity.
Personal Data
Demographics
Demographics is any data that describes the characteristics of a person, such
as age, gender, income, education, or occupation.
Personal Data
Location
Location is any data that identifies or describes a person's physical or
geographical position, such as address, GPS coordinates, or place of work.
Healthcare Data
PHI
Protected Health Information (PHI) is any information in a medical record that
can be used to identify an individual.
Financial Data
PCI
Payment Card Information (PCI) is any data associated with a credit or debit
card that can be used for transactions.
Financial Data
Account Info
Account Info is any data related to a person’s financial, service, or
membership accounts, such as account numbers, login credentials, or customer
IDs.
Ethical AI Standards
Ethical AI
Ethical AI is the classification and organization of principles and guidelines
that govern the ethical development and use of AI. This taxonomy covers key areas
such as fairness, accountability, privacy, and transparency.
Data Categorization
Data Sensitivity
Data Sensitivity focuses on managing, protecting, and ensuring the proper use
of data. Tags such as Data Quality address accuracy and reliability, while Data
Sensitivity ensures data security and privacy. Field Usage is how data fields are
used. Data Compliance is how data is kept up to date with rules like CCPA, COPPA,
GDPR, HIPAA, and others.
Data Categorization
Data Quality
Data Quality is any data that indicates the accuracy, completeness,
consistency, or reliability of other data, helping assess its fitness for
use.
Data Categorization
Field Usage
Field Usage is any data that describes the functional status or role of a
field, such as whether it is active, hidden, or marked as a deprecation
candidate.
Data Categorization
Data Compliance
Data Compliance is any data that indicates alignment with privacy laws,
industry regulations, or organizational policies, such as CCPA, COPPA, GDPR, HIPAA,
PCI DSS, or PII-related requirements.
#### See Also
- [_Salesforce Help_: Create a Custom Taxonomy in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_custom_taxonomy.htm&type=5&language=en_US)
# Predictive AI
Predictive AI uses models built with machine learning (ML) and your historical data to predict business outcomes and recommend ways to improve predicted outcomes.
Your Journey with Predictive AI
# Predictive Model Monitoring
Maintain the accuracy, stability, and reliability of your deployed predictive models with model monitoring in AI Models (formerly Einstein Studio). This ongoing process provides in-depth insights into model's performance and identifies data quality or connectivity issues. Without consistent monitoring in Data 360, model performance can decline and lead to inaccurate predictions, unexpected outcomes, and reduced confidence in your results.
Model monitoring is crucial for these reasons:
- Maintains reliability and trust of a model for continuous use.
- Monitors how an activated model performs with live data to ensure that it fulfils its goal.
- Provides an understanding of corrective actions such as retraining the model with new data.
- Tracks performance to understand a model’s behavior over time based on these metrics.
- Model usage statistics for live models, including those created from scratch (Einstein- created models) and connected models (Bring Your Own Models—BYOM).
- Connectivity issues (connected models)
- Data quality issues (models created from scratch)
## Model Usage (Created from Scratch and Connected Models)
Track the usage of models created from scratch and connected models to get insights about model inferences and statistics using live prediction data. Time series charts offer flexible periodicities, allowing you to view data over the last 24 hours, 7 days, or 30 days.
| STATISTICS | DESCRIPTION | KEY METRICS |
| --- | --- | --- |
| Activity Metrics | Key usage data and errors compared to a previous time period. | Total Inferences, connection errors, time out errors, and authentication errors, often with a trend indicator (for example, +1.3% vs last 30 days). |
| Total Inferences Over Time | Time series chart with the total inference count generated across the selected time period. | Total inferences with a trend indicator. Activated version numbers are represented as vertical markers. |
| Inferences by Integration Channel | Bar chart showing the distribution of predictions based on the integration channel. | Inferences by the integration channels such as predict job, transforms, flows, and APIs. |
## Data Quality (Created from Scratch Models Only)
Model performance relies on data quality, and issues can occur if live data differs significantly from training data. Monitor to track data quality issues such as missing values and out-of-bounds values. Alerts for these issues surface when the number of records are affected by an issue for a specific variable.
| ISSUE | DeSCRIPTION | |
| --- | --- | --- |
| Missing Values | Total count of missing values across all variables against the total number of inferences. | Count of missing values, total inferences, and a trend percentage. The trend indicator shows if values are up by 20% or down by 30% in comparison to the selected time period. |
| Missing Values by Variable | Bar chart with variables that contain missing values. A card that also displays metrics by variable and integration channel. | Percentage of missing values for each variable. |
| Out-of-Bound (OOB) Values by Variable | Bar chart with variables that contain values outside the expected range. A card also displays metrics by variable and integration channel. | Percentage of out-of-bounds values for each variable. |
## Connectivity (Connected Models Only)
Alerts that are surfaced for connectivity issues include connection, timeout, and authentication errors, which are tracked with live data.
| ERROR | DeSCRIPTION | key metric |
| --- | --- | --- |
| Connectivity Errors | Displays the total number of errors (connection, time out, authentication) against the total number of inferences. | Total connectivity errors with a trend indicator. |
| Connection Errors Over Time | Time series chart with connectivity issues by the cause over a period of time. | Connectivity issues over time with a trend indicator. |
- **[Drift Monitoring (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_drift.htm&release=264.0.0&type=5)**
Use Drift Monitoring in Data 360 to track predictive model degradation, which occurs when the distribution of model predictions changes significantly over time. Drift indicates shifts in customer behavior, business conditions, or underlying data patterns.
# Predictive Model Templates
Build predictive models quickly by using preconfigured templates in Model Builder. Templates provide a starting point, including model details, variables, and recommended algorithms that you configure before model training.
### Required Editions
## Before You Begin
Before you configure a template, complete these setup steps.
- Obtain the license for the products that include the predictive template. For example, the Collections Risk Score template is visible only with a Financial Services Cloud license.
- In Feature Manager, turn on the settings for the template that you want to use.
## Template Capabilities
Use templates configured for specific business scenarios to reduce setup time and analyze the features that matter most to your business.
- **Specific use cases:** Templates are available only for specific use cases.
- **Flexible customization:** Customize any step of the template during the setup flow to align with your organization's goals.
- **Algorithmic optimization:** Templates automatically recommend the optimal algorithm for your use case, eliminating the need for complex mathematical adjustments.
- **Unified review:** The summary page displays all your configured settings before you start model training.
## Available Templates
Model Builder provides these preconfigured templates.
- **Collections Risk Score:** Predicts customer payment risk. This template is visible only with a Financial Services Cloud license.
- **Propensity to Buy** (Beta): Predicts which customers are most likely to purchase a product within a specified time frame.
- **Fundraising** (Pilot): Predicts donor behaviors and fundraising outcomes based on historical engagement.
- **[Propensity to Buy Template (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_template_propensity_to_buy.htm&release=264.0.0&type=5)**
The Propensity to Buy template establishes a starting point for predicting which customer will buy a product or product category within a particular time frame. The template preconfigures model details, prediction inputs, and selects an algorithm. To align the model with your data, customize default variables and set a prediction window—the number of days used to calculate the purchase likelihood. After model training, Model Builder generates purchase likelihood scores on your records so you can identify high-value customer segments and drive targeted marketing campaigns.
# Predictive Models in Companion Orgs
Access predictive models trained and activated in a home org from your Data Cloud One companion org. Data Cloud One supports multiorg access, which is ideal when a business is spread across different teams, countries, or brands. Model governance in the home-organization also simplifies model management and enables you to scale predictive AI across your entire ecosystem.
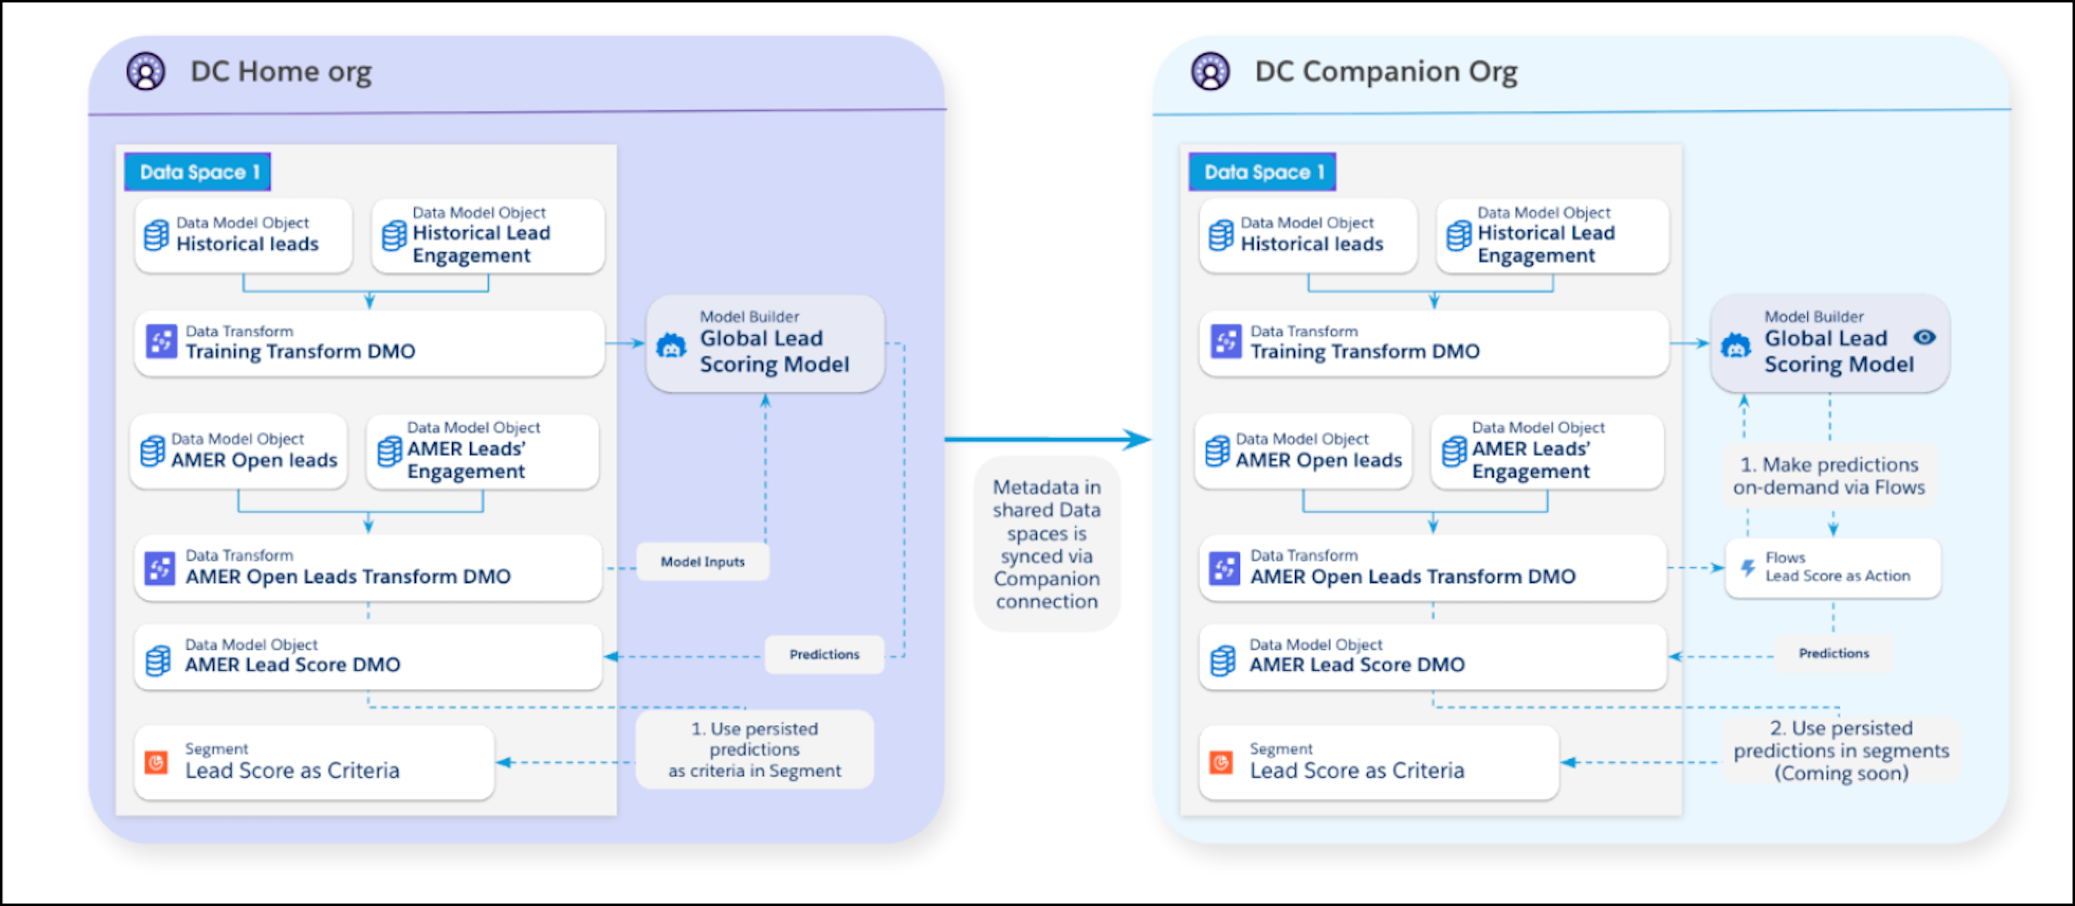
While models from AI Models in companion orgs are read-only, you can still leverage their predictive capabilities. Here are some ways to get predictions from a model activated in a home org.
- Predictions in a Data Model Object:
Home org users can use a batch data transform or predict job to persist predictions to a data model object (DMO). Companion org users can use predictions in the DMOs as criteria or filters in segments to group data or in flows to automate based on prediction scores.
- On-Demand Predictions:
Companion org users can use Flow, Apex, or agents to invoke a model to get predictions on-demand.
# Prepare and Model Data
Data being brought into Data 360 can be transformed and prepped before mapping. During data mapping, the preserved data source schema is mapped to an opinionated and extensible data model, called the Customer 360 Data Model. After the data is mapped, you can further query and manipulate your data to make it easier to work with for use across Salesforce.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
The data model is powered by the Customer 360 Data Model, by way of a data lake object (DLO) to data model object (DMO) mapping and relationship experience. Information about an individual is stored in the Unified Individual DMO, enabling marketers to create a segmentation strategy and publish segments to activation targets.
To learn more, review the associated Trailhead content.
[Customer 360 Data Model for Data 360](https://trailhead.salesforce.com/content/learn/modules/customer-360-data-model-for-customer-data-platform)
[Batch Data Transforms in Data 360: Quick Look](https://trailhead.salesforce.com/content/learn/modules/batch-data-transforms-in-data-cloud-quick-look)
[Streaming Data Transforms in Data 360: Quick Look](https://trailhead.salesforce.com/content/learn/modules/streaming-data-transforms-quick-look)

- **[Data Cleansing and Preparation](https://help.salesforce.com/s/articleView?id=data.c360_a_cleansing_data.htm&release=264.0.0&type=5)**
Cleaning and preparing your data is crucial for success when using the Data 360 segmentation and activation capabilities.
- **[Data Mapping](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping.htm&release=264.0.0&type=5)**
Data ingested by all data streams is written to data lake objects (DLOs). After creating your data streams, you must associate your DLOs to data model objects (DMOs). Only mapped fields and objects with relationships can be used for Segmentation and Activation.
- **[Data Model Objects (DMOs)](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5)**
Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.
- **[Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graphs.htm&release=264.0.0&type=5)**
A data graph brings together structured data from your Data Model Objects (DMOs) in Data 360. It combines this data to create easy-to-use views of your information.
- **[Simple Start in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_simple_start.htm&release=264.0.0&type=5)**
Streamline your initial Data 360 setup with Simple Start. Bypass manual bundle configuration and field mapping by syncing metadata and creating standardized data structures for your Salesforce CRM data in minutes. Because the system initially syncs only metadata, you consume credits only after activating related data streams and downstream processes.
# Prepare Your Data for a Clean Room
To share segments in a clean room, complete these steps to prepare your data. Preparation includes required steps such as ingesting the data, mapping the data lake object (DLO) to a data model object (DMO), hashing fields to protect personal information, and creating segments. You can share segments only in a clean room.
### Required Editions
Available in: Enterprise Edition (home org)

Note If you already created Salesforce segments with a unique segment name and match key, you can directly [create a DMO containing all the fields you want to use as match keys and hash sensitive fields for clean rooms](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_prepare_data.htm&release=264.0.0&type=5 "Combine multiple fields into a single DMO that can be used as match keys to match records between the two parties.").
This process is a multi-step solution that can require different roles and permission sets to complete in Data Cloud. Bookmark this page or keep it open in a separate window to refer to this topic.
#### See Also
- [_Salesforce Help_: append Transformation](https://help.salesforce.com/s/articleView?id=analytics.bi_integrate_append_transformation.htm&language=en_US)
- [_Salesforce Help_: Identity Resolution Ruleset Processing Results](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_summary.htm&language=en_US)
## Connect Data to Data 360
You can ingest profile data and engagement data. To ingest both types, create a separate data stream for each type. Your profile data must contain a unique ID for the individual, such as an email address, phone number, PPID, or device ID. You can hash your data with the SHA256 algorithm. The algorithm transforms data to lowercase and removes white spaces. If your data isn’t hashed with the SHA256 algorithm, you can transform it after ingestion.
### Required Editions
User Permissions Needed
To connect data to Data Cloud
Data Cloud Architect permission set
Choose your data ingestion method based on your data source.
- Use [accelerated query federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&release=264.0.0&type=5 "Caching retrieves data from the external source and temporarily stores it in a data lake object in Data 360. When you enable acceleration while creating a data stream, you turn on caching. We recommend caching when accessing large data sets or when data changes frequently. You can refresh the cached data at your preferred frequency.") to connect your external data sources with Data 360 and access your data without moving it. Clean rooms support accelerated data streams only. File federation and live-query data federation are not supported.
- Create a data stream by [uploading a CSV file](https://help.salesforce.com/s/articleView?id=data.c360_a_upload_a_csv_file.htm&release=264.0.0&type=5 "Create a data stream by bringing in data from a local CSV file into Data 360.") or by using [a data kit](https://help.salesforce.com/s/articleView?id=data.c360_a_install_package_kit.htm&release=264.0.0&type=5 "When you create a data stream from a data kit in your target org, the data model objects are available automatically. When adding a data model to a data kit, a custom data model is added as is. If you’re adding a standard data model, only the custom mappings and custom fields are packaged.").
- Use a file-based storage connector, such as Amazon S3 or Google Cloud Storage.
- Use a [Salesforce CRM connector](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector.htm&release=264.0.0&type=5 "A standard Salesforce CRM connection establishes a connection between Data 360 and a Salesforce org, allowing Data 360 to ingest data from the connected org. Data 360 ingests data and sends back only data actions. This type of connection doesn’t share any data back to the connected org.") to ingest data from a connected Salesforce org.
- Capture real-time data from a website or mobile app by using the [Web and Mobile App connector](https://help.salesforce.com/s/articleView?id=data.c360_a_web_mobile_app_connector.htm&release=264.0.0&type=5 "Connect your web and mobile apps to Data Cloud to collect customer engagement data. This data helps you customize messages, create automations, or support AI projects. After it’s connected, set up data streams to ingest your data into Data Cloud, allowing you to access and query this data for various uses.").
## Map Data to Data Model Objects
Associate the ingested data stream or DLO to the relevant standard DMOs in Data Cloud.
### Required Editions
You can map profile data to the Individual - latest DMO or Contact Point DMO. For engagement data, use an appropriate standard DMO, but map the contact point to the individual - latest DMO. If you’re a provider, you can also create a custom DMO to map your data. You must map the party-related fields. The Party attribute connects all the pieces of information and helps Data 360 identify that they all belong to the same person.
User Permissions Needed
To map data for a clean room
Data Cloud Architect permission set
1. On the Data Streams tab, open the data stream that you created for the clean room.
2. [Map your data to DMOs.](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&language=en_US)
Here are some recommended field mappings for profile data. You must map the party-related fields. The Party attribute connects all the pieces of information and helps Data Cloud identify that they all belong to the same person.
- Email address maps to Email Address
- First name maps to First Name
- Last name maps to Last Name
- Customer ID or Unique ID (primary key) maps to External Record ID
- Customer ID or Unique ID (primary key) maps to Party
- Customer ID or Unique ID (primary key) maps to ContactPointEmail ID
- Customer ID or Unique ID (primary key) maps to Individual ID (primary key)
Here are some recommended field mappings for engagement data.
- Date-time stamp maps to Engagement date time
- Email address maps to Individual
- Product ID maps to External record ID
- Product name maps to Name
- Purchase price maps to Product Order Event Type
- Unique transaction ID (Primary key) maps to Product order engagement (primary key)
## Create a Data Model Object for Match Keys
Combine multiple fields into a single DMO that can be used as match keys to match records between the two parties.
### Required Editions
User Permissions Needed
To use batch transforms
Data Cloud Architect permission set
Using multiple identifiers to link the data of both parties in a collaboration increases the chance of finding a match. Use unique values like email ids, phone numbers or ID numbers.
1. In Data Cloud, on the Data Transforms tab, click **New**. If the Data Transforms tab isn’t visible, click More and select **Data Transforms**.
2. Select **Batch Data Transform**, and click **Next**.
3. For the data source, select **Data Model Objects**.
4. Select the data space to transform, and click **Next**.
5. Click **Add Input Data**, and select the **Contact Point Email** DMO, to include the email address as a match key.
6. Select the Party and Email Address columns.
7. Click **Next**.
8. Click the Add Node icon, and select **Transform** as the node type.
The selected columns are shown in the preview window.
9. Create a column that contains the type of data in the DMO.
1. Click the function icon (fx) and select **Custom Formula**.
2. Enter a Transformation Name.
3. In the text pane, delete the placeholder text Enter your formula… and enter ‘HEM’ to denote hashed email.
4. For Output Type, select **Text**, and retain the default value in the Length field.
5. Enter the column label as Type and the API name as Type\_\_c.
6. Click **Apply**.
This function creates a Type column for all the fields in the Contact Point Email DMO with the value as HEM.
10. Apply the SHA2 function to hash the data.
1. Click the function icon (fx) and select **Custom Formula**.
2. Enter a Transformation Name.
3. Search for and select **SHA2** as the function.
4. Delete the placeholder text field, and then search for and select the **Email Address** column.
5. For the bitlength value, enter 256.
The function appears as sha2(ssot\_\_EmailAddress\_\_c, 256)
6. For Output Type, select **Text** and enter 256 for the length.
7. Enter the column label as HashedContact and the API name as HashedContact\_\_C to denote the column that stores the hashed values.
8. Preview the transform to verify that the email address field is hashed correctly, and then click **Apply**.
11. After creating a column with hashed email IDs, remove the column with actual email IDs from the DMO.
1. Click the Drop Columns icon.
2. Search for and select the Email Address column and click **Apply**.
12. Add a universally unique identifier string for each record.
1. Click the function icon (fx) and select **Custom Formula**.
2. Search for and select **UUID** as the function.
3. For Output Type, select **Text**, and retain the default value in the Length field.
4. Enter the column label as ID and the API name as ID\_\_C.
5. Click **Apply**.
13. Apply the same transform to the Contact Point Phone DMO and any other DMO that you want to include as a match key.
1. Click the **Add Input Data** icon and select the DMO.
2. Create a column that contains the type of data in the DMO. For the Contact Point Phone DMO, enter the value for the Type field as ‘HPH’ to denote hashed.
3. Apply the SHA2 function to hash the data.
4. Remove the column with actual email IDs from the DMO.
5. Add a universally unique identifier string for each record.
14. [Combine the transforms using the Append Node.](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_append_node.htm&type=5&language=en_US)
15. Collapse the transformation window and add an output node to the transformation.
16. Create a DMO for the output.
1. Select **Create New**.
2. For Write Mode, select **Replace**.
3. Enter an object name to identify the object that stores the hashed values.
4. Update the Object API name to match the object name.
5. Select **Contact Point Email ID** as the primary key and **Key Qualifier Contact Point Email ID** as the key qualifier.
6. Click **Apply**.
17. Click **Save**.
18. On the Data transform home page, select the transform you created and click **Run Now**.
You can also choose to schedule the transform to run at specific intervals.
After the transform runs, the hashed data is stored in the output DMO.
## Map Output DMO to Individual DMO
Add a relationship between the output DMO with the hashed data and the Individual DMO.
### Required Editions
User Permissions Needed
To map data
Data Cloud Architect permission set
1. In Data Cloud, go to the Data Model tab.
2. Search for and select the output DMO with the hashed data. If you can’t find the DMO, change the List View from **Mapped** to **All**.
3. On the Relationships tab, click **Edit**.
4. Click **New Relationship** and enter this information.
1. For Field, select **Party**.
2. For Cardinality, select **N:1**.
3. For Related Object, select **Individual**.
4. For Related Field, select **Individual ID**.
5. Click **Save**.
## (Optional) Create Identity Resolution Rules
To link multiple sources of data about the same person or account into a unified profile, create identity resolution rules. The unified data is consolidated in the Unified Individual DMO.
### Required Editions
User Permissions Needed
To create identity resolution rules
Data Cloud Architect permission set
1. [Create identity resolution rulesets.](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_ruleset_create.htm&release=264.0.0&type=5 "Get started with identity resolution by setting up a ruleset to unify accounts, individuals, leads, or households. The primary data model object for your ruleset determines which records are unified. Match and reconciliation rules you add to your ruleset after creating it guide how records are matched.")
2. [Configure identity resolution match rules.](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5 "Specify how identity resolution identifies matching records in Data 360.")
3. [Configure reconciliation rules.](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&release=264.0.0&type=5 "A reconciliation rule specifies how to select a single value to save to a unified field that can’t have multiple values, such as an individual’s name, during the identity resolution process. Reconciliation rules are set at the object level and can be overridden by field-specific reconciliation rules. The reconciliation process doesn’t delete or change any source profile data, update your connected source systems, or tell you which source data to use when working with your customers.")
4. On your ruleset record home page, click **Run Ruleset**.
## Create a Segment
You can only share segments in a clean room. Create segments based on the Individual or Unified Individual DMO. Each segment must contain a unique segment name and match key.
### Required Editions
User Permissions Needed
To create a segment
One of these permission sets: Data Cloud Architect, Data Cloud Activation Manager, or
Data Cloud Activation Specialist.
1. [Create a segment](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&release=264.0.0&type=5 "Create a standard segment based on a data model object and then publish the segment to activation targets.").
2. (Optional) For more complex segment criteria, use the [Segment Canvas](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_canvas_interface.htm&release=264.0.0&type=5 "Use the segment canvas in Data 360 to select direct and related attributes to narrow down a created segment to your target audience.") to build segment rules.
3. [Publish a segment.](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_segment.htm&release=264.0.0&type=5 "After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.")
# Prepare Your Training Data
Effective data preparation is the key to getting great results with your predictive model. Harness the power of data integration in Data 360. Load and transform data from one or more data sources into a data model object (DMO) with optimized training data. You can pull data from Salesforce and external sources. You can also use third-party tools and utilities to further expedite data cleansing and wrangling tasks.
### Required Editions
## What is Data Prep?
Data prep is the process of preparing your data so that it’s optimized for AI Models (formerly Einstein Studio) to train predictive models. Better predictive models derive more useful predictions and prescriptions, resulting in better decisions and improved business outcomes.
Data preparation involves aggregating and optimizing data associated with the outcome variable you're investigating, along with potential predictor variables that can influence the outcome. Data preparation is also a process of iterative refinement. As you dig deeper into your data, new clues emerge. Discoveries can cause you to reassess previous assumptions and adjust your data prep implementation accordingly.
## Invest in Data Prep for Your Solution
Data scientists typically invest significant time and effort to plan and prepare their data. They know how much the quality of the output depends on the design and quality of the input. If you aren’t able to match the wizard-level knowledge, skills, and training that data scientists bring to the data prep process, you can still succeed if you:
- have domain knowledge of the data associated with the business outcome you’re trying to optimize
- use Data 360’s extensive data integration capabilities to aggregate, clean, and populate the DMO with data that’s optimized for model training
- apply common data prep techniques to produce high-quality data that is accurate, complete, representative of your business operations, and relevant to your solution
- improve business results by applying basic principles to help implement your solution - even if you aren’t a data scientist.
## Use Data 360’s Data Integration Capabilities
AI Models relies on data stored in Data 360 data model objects (DMOs). Data Cloud provides a variety of powerful tools you can use to prepare (extract, load, and transform) your data. That way, you can populate a DMO with information that’s optimized for AI Models to use for model training.
#### See Also
- [_Salesforce Help:_ Data Cleansing and Preparation](https://help.salesforce.com/s/articleView?id=data.c360_a_cleansing_data.htm&type=5&language=en_US)
- [_Trailhead:_ Data Quality](https://trailhead.salesforce.com/content/learn/modules/data_quality)
- [_Trailhead:_ Prepare Your Data for AI trail](https://trailhead.salesforce.com/content/learn/trails/prepare-your-data-for-ai)
- [_Trailhead:_ Data Fundamentals for AI](https://trailhead.salesforce.com/content/learn/modules/data-fundamentals-for-ai)
# Preview Results in a Batch Data Transform
Catch mistakes early by reviewing the results of each node and transformation that you add to a batch data transform. Each user can initiate up to 4,000 previews per hour. The preview shows a sample of the latest available data, up to 5,000 rows.
When you preview a DLO transform, the data preview applies the data space filter for the selected data space. However, when the transform is actually run, this filter is not applied, and all data within the DLO is processed.
DMOs always have an associated data space and the data space filter is consistently applied both when viewing the data preview and when running the transform.
1. In the batch data transform, select a node in the canvas to view its results.
If you add a Filter node, the preview filters the currently sampled rows. For example, the batch data transform processes 20,000 rows. The preview shows 5,000 sample rows for the Aggregate node. If you add a Filter node after the Aggregate node, you might see only 4,000 of the same sampled rows. The preview doesn’t retrieve an updated sample of 5,000 rows for the Filter node.
2. If needed, edit the node to ensure that it produces the correct results.
3. In a Transform node, select a transformation step.
If needed, edit the transformation to ensure that it produces the correct results. If the data preview for a node doesn’t complete immediately, view its build status at a glance with the progress wheel. Mouse over the wheel to see the percent built.
4. To focus on columns that are impacted by a node or transformation, hide a column from the preview.
Hiding a column from preview doesn’t remove it from the data transform, but it can increase performance when previewing results. By default, the first 100 columns of each source object in an input node are shown in preview. To hide a column that doesn’t require preview, select it and click the Hide button in the Transform toolbar.
1. In the Preview tab, select a column in the Preview tab.
2. Click the Hide button .
3. To increase preview performance, click **Hide Unused** in the Transform toolbar.
5. If data preview is delayed, disable data preview. You can always turn it back on when you want to see your progress.
6. To view only the columns and hide the data, click the **Columns** tab.
7. Save the data transform.
# Primary Key
To create a data stream in Data Cloud, select a primary key or unique identifier for that source. If a data source doesn't have a field that can be used as a primary key, create a composite key by combining two or more source fields using a formula field.
Carefully select a primary key for each data stream. The primary key is the basis for deciding whether to add a new record or update an existing record. Add key qualifiers to your primary keys, to differentiate records from data sources that have the same primary key.
## An Example Primary Key
In this product catalog data source, every record has a unique value for SKU (the product's Stock Keeping Unit). Since it's unique, the SKU is selected as the primary key.
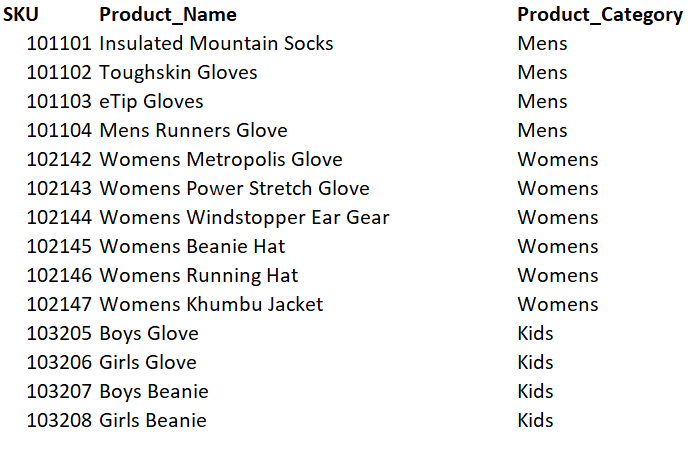
To designate the primary key in Data 360, select the SKU field from the Primary Key dropdown.
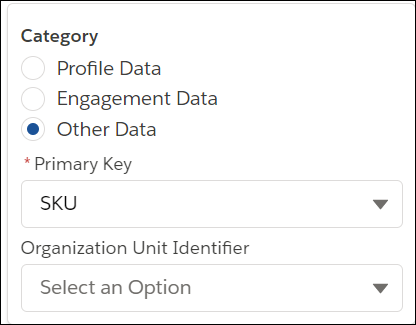
- **[Composite Key](https://help.salesforce.com/s/articleView?id=data.c360_a_composite_key.htm&release=264.0.0&type=5)**
Use a composite key to uniquely identify a record.
#### See Also
- [_Salesforce Help_: Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_fully_qualified_keys.htm&release=264.0.0&type=5 "Use Fully Qualified Keys (FQK) to avoid key conflicts when data from different sources are harmonized in the Data 360 data model.")
# Privacy Data Model
The Customer 360 Data Model privacy subject tracks and stores certain data privacy preferences. Keep in mind that deciding how to honor customer privacy preferences is up to you.
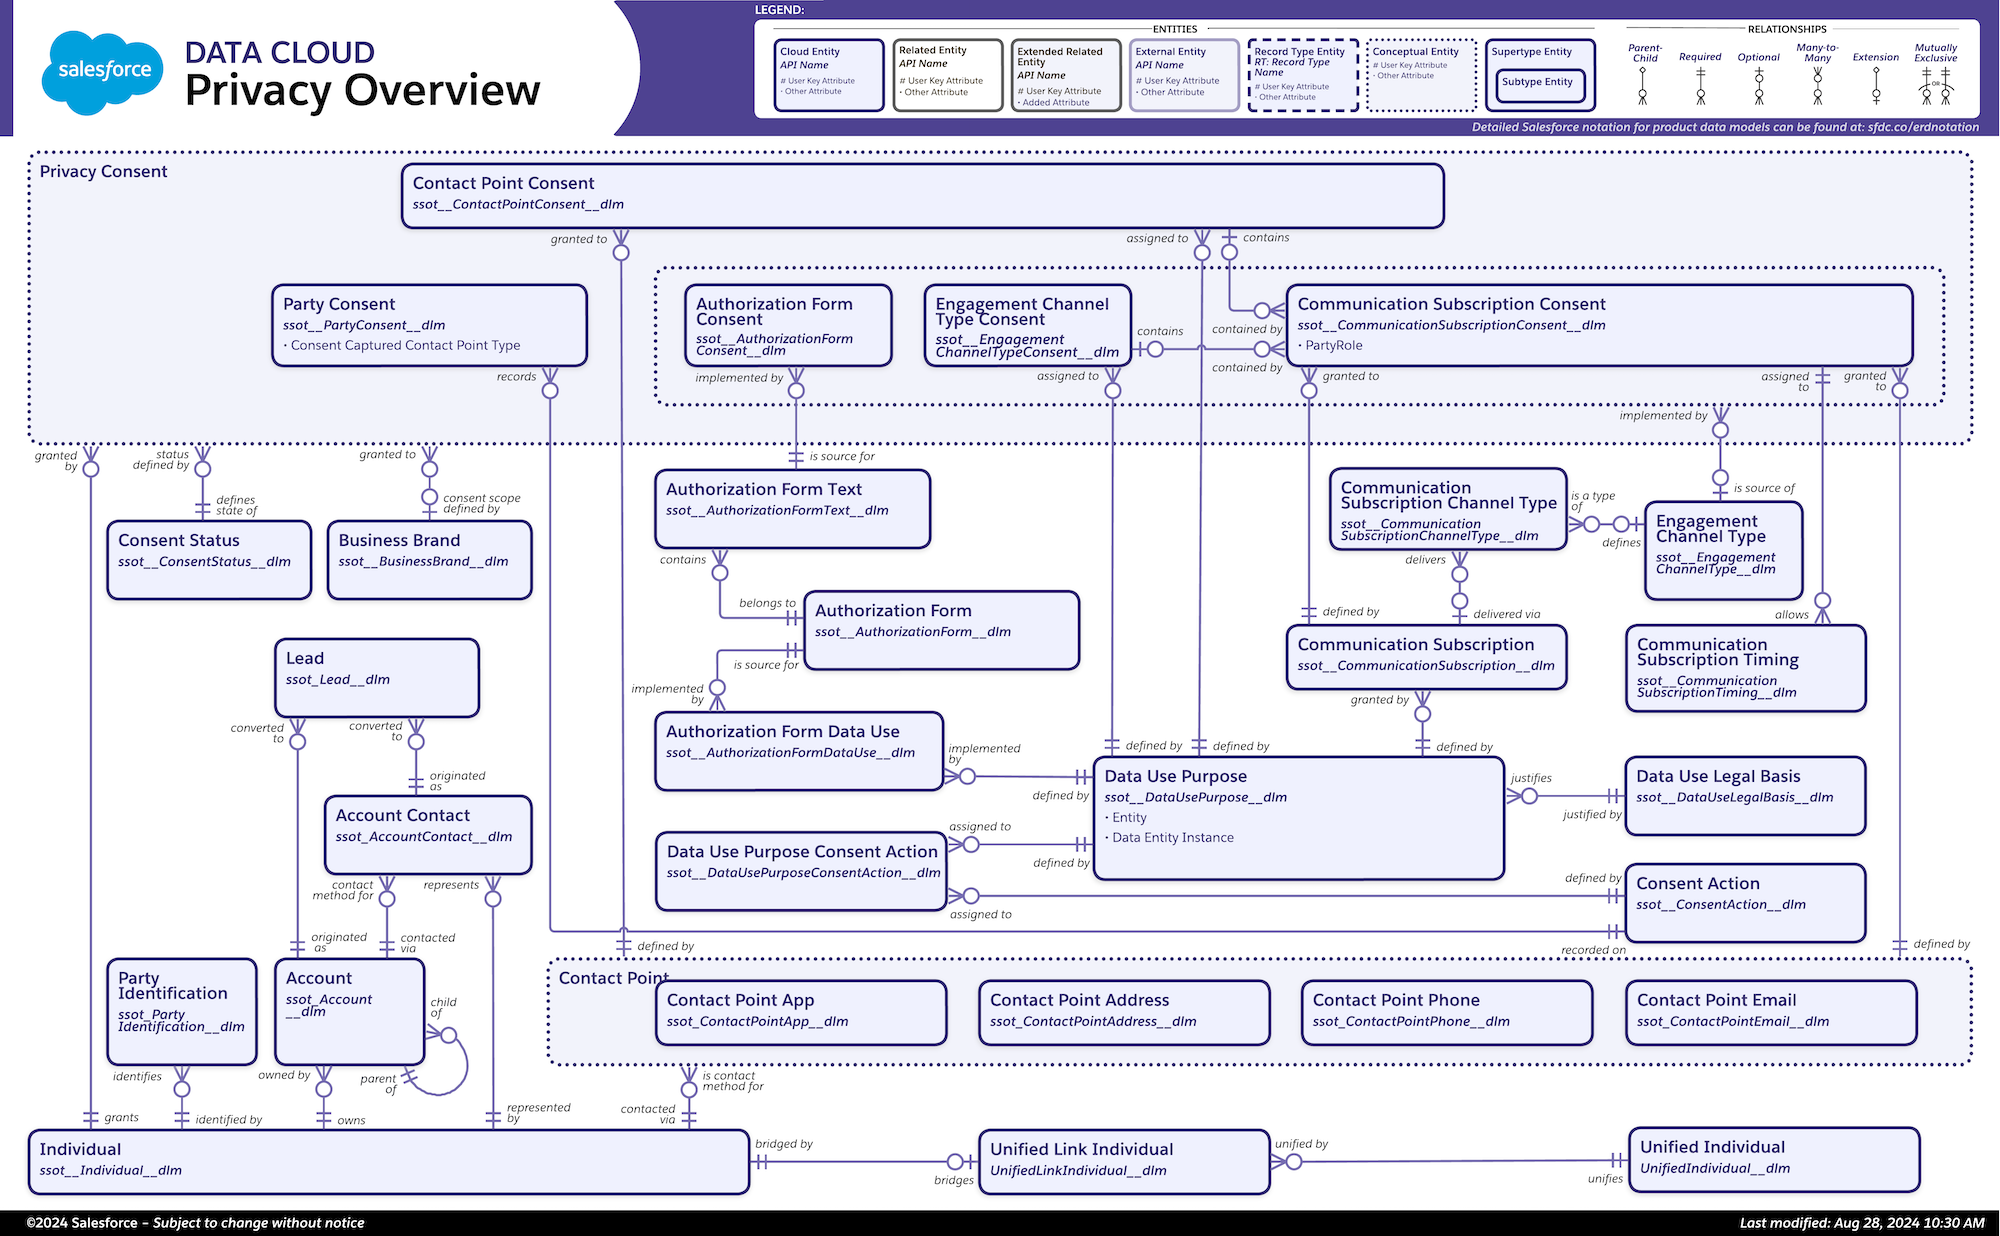
For more details and a larger image, visit the [Data Model Gallery](https://developer.salesforce.com/docs/platform/data-models/guide/privacy-overview.html).
These privacy DMOs are represented in Data 360.
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Authorization Form Consent | A Data 360 DMO for details about where, when, and how consent was granted for a specific form, set of terms and conditions, or privacy policy. | [Authorization Form Consent DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_authorization_form_consent_dmo.htm) |
| Communication Subscription | A Data 360 DMO for a customer’s subscription preferences for a specific communication. | [Communication Subscription DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_communication_subscription_dmo.htm) |
| Communication Subscription Consent | A Data 360 DMO for the engagement or communication channel preferences of a customer. | [Communication Subscription Consent DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_communication_subscription_consent_dmo.htm) |
| Contact Point Consent | A Data 360 DMO for individual consent preferences for a specific contact point, such as an email address, including double opt-in information. | [Contact Point Consent DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_contact_point_consent_dmo.htm) |
| Engagement Channel Type Consent | A Data 360 DMO for individual privacy preferences for a specific engagement channel, such as SMS or email. | [Engagement Channel Type Consent DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_engagement_channel_type_consent_dmo.htm) |
| Party Consent | A Data 360 DMO for individual’s consent preferences. | [Party Consent DMO](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_party_consent_dmo.htm) |
## Contact Consent Configuration
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Authorization Form | A Data 360 DMO for the set of terms and conditions, such as privacy policy, contract, or consent forms. | [Authorization Form DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_authorization_form_dmo.htm) |
| Authorization Form Data Use | A Data 360 DMO for the data uses consented to in an authorization form. | [Authorization Form Data Use DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_authorization_form_data_use_dmo.htm) |
| Authorization Form Text | A Data 360 DMO for an authorization form’s text and language settings. | [Authorization Form Text DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_authorization_form_text_dmo.htm) |
| Communication Subscription Timing | A Data 360 DMO for a customer's timing preferences for receiving a communication subscription. | [Communication Subscription Timing DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_communication_subscription_timing_dmo.htm) |
| Data Use Purpose Consent Action | A Data 360 DMO for individual consent preferences for consent actions, for example, sharing for a specific data use purpose, such as billing or service. | [Data Use Purpose Consent Action DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_data_use_purpose_consent_action_dmo.htm) |
## Contact Consent Setup
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Communication Subscription Channel Type | A Data 360 DMO for a specific engagement channel for reaching customers, such as SMS or email. | [Communication Subscription Channel Type DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_communication_subscription_channel_type_dmo.htm) |
| Consent Action | A Data 360 DMO for what a user consents to be done with their data, for example, data collection or web activity tracking. | [Consent Action DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_consent_action_dmo.htm) |
| Consent Status | A Data 360 DMO for the status of consent, for example opted in or out of data collection. | [Consent Status DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_consent_status_dmo.htm) |
| Data Use Legal Basis | A Data 360 DMO for the legal reason for contacting a customer, such as billing or contract. | [Data Use Legal Basis DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_data_use_legal_basis_dmo.htm) |
| Data Use Purpose | A Data 360 DMO for the purpose of contacting a prospect or customer, such as for billing, marketing, or surveys. | [Data Use Purpose DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_data_use_purpose_dmo.htm) |
## Engagement
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Engagement Channel Type | A Data 360 DMO for the channels supported by individual preferences. For example, individuals can set consent preferences for SMS but not for a phone call. | [Engagement Channel Type DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_engagement_channel_type_dmo.htm) |
# Private Connect Considerations
Private Connect for Data 360 establishes a secure connection between Virtual Private Clouds (VPC), bypassing the public internet and enhancing security.
## Privately Connecting Your VPC
A VPC is a private network within a public cloud. It allows cloud providers like Amazon to create a secure, isolated space for their data and apps. To prevent public internet access, data lakes typically use secure measures such as a VPC. However, this measure also restricts access for Data 360. Private Connect for Data 360 provides a solution by establishing private network access, making sure that traffic remains off the public internet.
Private Connect for Data 360 currently supports Amazon Web Services (AWS) PrivateLink to create a secure point-to-point connection between the Data 360 AWS VPC and your AWS VPC. This private connection is exclusive to individual tenants, permitting you to grant access solely to your Data 360 while maintaining internet restrictions.
## Private Connect for Data 360 Architecture
Private Connect for Data 360 uses a high performing, scalable architecture, which provides each tenant with dedicated capacity and security. This architecture supports a wide range of use cases, including high-volume initial ingestion of unstructured data and low-latency queries for analytics.
## Private Connect and Private Connect for Data 360 Are Different Products
Salesforce Private Connect and Private Connect for Data 360 are distinct products with different features and pricing structures. Salesforce Private Connect isn’t compatible with Data 360. Private Connect for Data 360, however, supports Data 360.
## Data Kit Support for Private Connect
Currently, data kits don’t support Private Connect but there’s a manual workaround available for both Snowflake and Redshift. This manual workaround doesn’t block the use of data kits for other use cases.
## Solution for Snowflake
This workaround requires you to create a PNR in your target org and to activate it as follows:
- Deploy DevOps data kit on the target org. The deployment fails, which isn’t an issue.
- Create a Private Connect Private Network Route (PNR) in the target org.
- Go to **Data Cloud Setup** and locate the Snowflake connection. It is in an INACTIVE state. Activate it as follows:
- Turn on the toggle for **Private Connect**.
- Select the PNR that you created.
- Enter the URL, keys, and other details as directed.
- The setup connection shows an ACTIVE state.
- Go to App Launcher, select **Data Cloud**, and select **Data Streams**. The data stream shows an error state.
- Click the error symbol and try the stream creation again. The connection succeeds and the data stream moves to an ACTIVE state.
## Solution for Redshift
This workaround requires you to create a PNR, but it unblocks the transfer of other components, such as connectors and data streams. After you’ve downloaded the data kit that you need, open it, open the DataKitObject template, and update the `outboundnetworkconnection` value.
- Create a Private Connect Private Network Route (PNR) in the target org. As you create the PNR, copy and save the **Private Network Route ID**. You need it for step 4.
- On the target org, use the Salesforce command-line interface (CLI) to fetch the data kit.
- In the retrieved package, open the **DataKitObjectTemplate**.
- Locate the parameter named `outboundnetworkconnection.` Replace its value with the **Private Network Route ID** you collected in step 1. For example: `{"paramName":"outboundnetworkconnection","value":""}`.
- Post the Data Kit deployment using a UI/Change set. The connection succeeds and moves to an INACTIVE state. Activate it as follows:
- - Turn on the toggle for **Private Connect.**
- Select the PNR that you created.
- Enter the URL, keys, and other details as directed.
- The setup connection shows an ACTIVE state.
- Go to App Launcher, select **Data Cloud**, and select **Data Streams**. The data stream displays an error state.
- Click the error symbol and try the stream creation again. The connection succeeds and the data stream moves to an ACTIVE state.
## Amazon Simple Storage Service (S3)
Data 360 supports private network connectivity with S3 without Private Connect for Data 360. Network traffic occurs via public IP but is [guaranteed](https://docs.aws.amazon.com/AmazonS3/latest/userguide/privatelink-interface-endpoints.html) to stay on the AWS network, remaining on the AWS backbone and not traversing the public internet.
- Connect an S3 bucket and a Data 360 instance within the same AWS region with a private IP address. Update your bucket policy to include Data 360's AWS VPC endpoint for that region in the allowlist for private S3 access.
- Access to buckets in a different region from the Data 360 tenant occurs via public IP.
For more information, see [AWS PrivateLink for Amazon S3](https://docs.aws.amazon.com/AmazonS3/latest/userguide/privatelink-interface-endpoints.html) and [IP Addresses Used by Data 360 Services](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_ip_address_allowlist.htm&release=264.0.0&type=5 "Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.").
## Difference Between Private and Public IP Addresses
A public IP address is visible to the internet. But a private IP address isn’t visible because it uses a range of non-internet facing IP addresses typically reserved for an internal network. When using Private Connect for Data 360, allowlisting public IPs is optional. Private Connect utilizes private IP addresses and doesn’t use public IP addresses.
## Private Connect for Data 360 Credit Consumption
In general, credit consumption is independent across all types as seen on the [rate cards](https://www.salesforce.com/products/platform/customer-data-cloud/services/). For example, with Zero Copy Federation, the consumption rate is 70 credits for every million rows accessed. If you’re using a private connection to ingest Zero Copy Federation, the rate is 70 credits per million rows accessed in addition to 500 credits for every GB transferred.
## IP Allowlisting for Snowflake
Many organizations prevent access to their Snowflake instance through their Snowflake [Network Policies](https://docs.snowflake.com/en/user-guide/network-policies). They also allow access from a select set of IPs or other uniquely identifiable sources. When using Private Connect to create a Data 360 connection to Snowflake, the traffic originates from a single AWS PrivateLink VPC endpoint. This endpoint has one of a wide array of private Data 360 IP addresses. Allowlist the traffic from the VPC endpoint so that Data 360 connects to Snowflake. Use either a Data 360 VPC endpoint ID or the IP range 10.0.0.0/8. We recommend that you allowlist the ID of the VPC endpoint. Retrieve the ID from the details page of an existing Private Network Route.
If you're using an IP range, we recommend adding the full 10.0.0.0/8 range to the allowlist. This range avoids the need for ongoing maintenance and outages caused by network disruption. Data 360 doesn’t support allowlisting by specific IP address because internal private IP addresses can change at any time, without notice.
To troubleshoot connection issues, you can use `dig` or `nslookup` on the Data 360 VPC endpoint Domain Name System (DNS) available from the details page of the network route to find associated IP addresses.
## Snowflake Data Share
The relationship between a Snowflake Federation connection and a Snowflake Private Network Route occurs when you create the connection. Private Connect behaves differently for Data Share. If a Snowflake Private Network Route and the Data Share Target are using the same URL, the target creation process uses Private Connect. For any other URL types, Data 360 tries to create the target by first using the public internet.
The Data 360 Snowflake Data Share feature uses Snowflake's Secure Data Sharing (SDS) for private Snowflake instances. Verify ownership of the sharing account through an OAuth sign-in when creating a Data Share Target. After it’s verified, Data 360 deletes all sign-in data, including OAuth tokens.
For successful Data Share Target creation, the originating computer must have network access to Snowflake from an accepted network location. A typical setup involves the user connecting to a corporate VPN, with Snowflake configured to allow requests from that network. Other requests do not use this account to log in. This step usually requires Salesforce Private Connect or temporarily allowlisting the Data 360 public IP addresses so that Data 360 can reach the OAuth API endpoints.
## Redshift and Snowflake Data Share Implementation
The implementation of Data Share differs for Redshift and Snowflake. Redshift's implementation doesn't require Private Connect. For Snowflake, Private Connect is necessary during the initial creation of the Data Share Target. This difference means that credit consumption only occurs during creation, requiring approximately 1 credit. No additional credit consumption occurs for Private Connect for Snowflake Data Share, regardless of the volume of data shared or accessed.
For more information, see [Harness Zero Copy data sharing from Salesforce Data Cloud to Amazon Redshift for Unified Analytics – Part 2](https://aws.amazon.com/blogs/big-data/harness-zero-copy-data-sharing-from-salesforce-data-cloud-to-amazon-redshift-for-unified-analytics-part-2/).
## Support for Multiple Redshift Instances
Multiple Redshift instances on a single VPC can't use a single Redshift Private Network Route for access. In addition, a one-to-one mapping exists between the Private Network Route (PNR) and the Redshift instance.
# Private Connect for Data 360
Private Connect uses Amazon Web Services (AWS) PrivateLink to establish a point-to-point network integration between your AWS virtual private cloud (VPC) and your Data 360 tenant. Private Connect provides a connection from Data 360 to your data source without exposing your network traffic to the public internet.
Private Connect for Data 360 is specifically designed to connect Data 360 to a data source. Private Connect for Data 360 is different from Salesforce Private Connect, which is used to connect a Salesforce org to a data source.
Currently, Private Connect for Data 360 supports Snowflake and Redshift through a network connection. Using Private Connect, you can use both federation and data share with Snowflake in an AWS VPC. If you're using Redshift, you can bring data into Data 360 using a federation connection. However, Private Connect for Data 360 isn't required to share data from Data 360 to Redshift.
To access a data source, you need a VPC endpoint service. Your data source vendor can provide this service for you, or you can create and manage your own endpoint service.
After your endpoint is set up, you create a Data 360 private network route. Each private network route has its own unique VPC endpoint. Data 360 manages the VPC endpoint, and your cloud provider manages the VPC endpoint service.
For Snowflake, Data 360 has a global limit of one private network route for each instance. You can use the one private network route towards a sandbox or production environment. However, you can have as many Snowflake connections as you want and you can reuse the same private network route for all of them within a single environment.
Private Connect for Data 360 allows you to connect to third-party systems. However, the implementation and management of these third-party systems aren't maintained by Salesforce.
- **[Private Connect Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_considerations.htm&release=264.0.0&type=5)**
Private Connect for Data 360 establishes a secure connection between Virtual Private Clouds (VPC), bypassing the public internet and enhancing security.
- **[Add a Private Network Route for Snowflake on Amazon Web Services (AWS)](https://help.salesforce.com/s/articleView?id=data.c360_a_add_network_route_snowflake.htm&release=264.0.0&type=5)**
Connect your Snowflake data source and Data 360 tenant with a dedicated network connection by using Private Connect for Data 360. Create a single connection to a specific instance, even if you have multiple Data 360 instances. Before you set up a Snowflake federation connection or data share, create a Private Network Route (PNR).
- **[Add a Private Network Route for Redshift](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_redshift.htm&release=264.0.0&type=5)**
To enable federation connections, connect your Redshift data source and your Data Cloud tenant with a dedicated network route using Private Connect for Data Cloud. Private Connect supports self-managed PrivateLink. Redshift-managed PrivateLink isn't currently supported.
- **[Add a Private Network Route for Amazon MSK](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_add_pnr_amazon_msk.htm&release=264.0.0&type=5)**
Connect your Amazon Managed Streaming for Apache Kafka (MSK) data source and your Data Cloud tenant with a dedicated network connection using Private Connect for Data Cloud. You can create a single connection to a specific instance regardless of how many Data Cloud instances you have. Before setting up a connection for Amazon MSK, establish a private network route.
- **[Add a Self-Managed Private Network Route for Snowflake on Azure](https://help.salesforce.com/s/articleView?id=data.c360_a_add_a_private_network_route_for_snowflake_on_azure.htm&release=264.0.0&type=5)**
Connect your Snowflake instance and Data 360 tenant to a dedicated network route with Private Connect for Data 360. Create a single route to a specific instance even if you have multiple Data 360 instances. Before you set up a Snowflake federation connection or data share, establish a Private Network Route (PNR).
- **[Add a Salesforce-Managed Private Network Route for Snowflake on Azure](https://help.salesforce.com/s/articleView?id=data.c360_a_add_a_private_network_route_for_snowflake_on_azure_sf_managed.htm&release=264.0.0&type=5)**
Connect Data 360 to your Snowflake on Azure data source with a Salesforce-managed private network connection by using Private Connect Multicloud for Data 360. Salesforce provisions and maintains the cross-cloud connection between Data 360 and Snowflake on your behalf. No configuration is needed on AWS or Azure.
- **[Add a Self-Managed Private Network Route for Databricks on Azure](https://help.salesforce.com/s/articleView?id=data.c360_a_add_a_private_network_route_for_databricks_on_azure.htm&release=264.0.0&type=5)**
Connect your Databricks data source and Data 360 tenant with a dedicated network connection using Private Connect for Data 360. Create a single connection to a specific instance regardless of how many Data 360 instances you have. Before you set up a Databricks federation connection or data share, establish a network route.
- **[Add a Salesforce-Managed Private Network Route for Databricks on Azure](https://help.salesforce.com/s/articleView?id=data.c360_a_add_a_salesforce_managed_private_network_route_for_databricks_on_azure.htm&release=264.0.0&type=5)**
Connect Data 360 to your Azure Databricks workspace by using Private Connect Multicloud for a Salesforce-managed private network connection. Salesforce provisions and maintains the cross-cloud connection on your behalf, without needing you to configure Azure. In general, you authorize Salesforce private endpoints from your Azure environment as follows: two endpoints for a private workspace storage and one endpoint for public workspace storage.
- **[Set Up a Snowflake Federation Connection for Private Connect](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_a_snowflake_federation_connection_for_private_connect.htm&release=264.0.0&type=5)**
Set up a connection between Snowflake and Private Connect for Data Cloud to access the data.
- **[Set Up a Redshift Federation Connection for Private Connect](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_a_redshift_federation_connection_for_private_connect.htm&release=264.0.0&type=5)**
Set up a connection between Redshift and Private Connect for Data Cloud to access the data.
- **[Delete a Private Connect Network Route](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_private_connect_network_route.htm&release=264.0.0&type=5)**
You can delete a private network route that isn’t used in a data stream.
#### See Also
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines_cdp.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize the adoption of Data 360 by Customer Data Platform customers for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. This article is about the legacy Customer Data Platform license, which is no longer available for purchase.")
# Process an Insight Manually
Instead of waiting for a calculated insight to be processed in a scheduled batch, run it manually.
1. In Data 360, go to the Calculated Insights tab.
2. Open the calculated insight that you want to process.
3. In the top right, click the dropdown, and select **Publish Now**.
The calculated insight is processed immediately.
# Process Content in Data Cloud
Use generative AI-based tools in Data Cloud to process unstructured data for use in AI, automation, and analytics workflows.
Processing capabilities available in Data Cloud include:
- Prompt-based customization: Use custom prompts or prompts powered by agents to chunk and further process your unstructured data for search index optimization. You can also use prompts to fix extraction issues, such as malformed tables, without rebuilding the entire search index.
- Indexed audio and video transcriptions: Simplify search and retrieval of audio from audio and video data by transcribing and indexing content automatically in Data Cloud. You can then query transcriptions to retrieve relevant information or similar items based on the text.
- Enriched indexes: Use AI to extract metadata from indexed content. Extracted metadata includes keywords, entities, topic overviews, questions answered by the content, and content summaries.
- Content parsing and preprocessing: Use prompts to identify document structure and convert text and metadata from unstructured documents into structured or semi-structured representations (parsing). Or ensure that data extracted from images and tables maintains the context and relationships from the source (preprocessing).
- Document schema extraction: Generate structured output from unstructured content. Define schemas to extract, classify, or generate fields and tables using prompts or programmatically with the Data Cloud Connect API.
Consider these key use cases for content processing in Data Cloud.
- For Retrieval Augmented Generation (RAG): By processing unstructured data and adding your content to a Data Cloud search index, you enable AI to retrieve precise context and ground its responses in your specific data for more accurate and relevant outputs. This is the foundation of RAG.
- For Service Cloud: Content processing extracts key information and topics from knowledge articles, emails, support tickets, and chat logs. This structured output allows AI agents to find precise answers, craft better responses, and proactively suggest solutions to customer issues.
- For Sales Cloud: Processing unstructured sales data, such as emails, call transcripts, and notes, extracts key details and sentiment. AI agents use this information to generate highly relevant meeting briefings and summaries, and to fuel personalized content recommendations that boost engagement.
- For automation flows: Content processing provides the semantic understanding needed to compare records, such as cases, based on their descriptions. This allows AI agents to automatically identify duplicates, accelerate resolution times by finding similar historical examples, and accurately classify incoming records.
- For analytics: Processing unstructured data prepares it for deep analysis in Tableau. By extracting themes and classifying topics within your content, you can reveal patterns and gain insights that are often missed by traditional analytics methods.
Process content in Data Cloud using these tools.
- **[Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_process_content_unstructured_data.htm&release=264.0.0&type=5)**
Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.
- **[Chunk Data](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_grounding.htm&release=264.0.0&type=5)**
To add your data to Data 360’s search index, you must first chunk it. Chunking break your data into meaningful chunks, and Data 360 turns those chunks into machine-readable vector embeddings.
- **[Intelligent Context](https://help.salesforce.com/s/articleView?id=data.c360_a_intelligent_context.htm&release=264.0.0&type=5)**
Process unstructured or structured data and create search index configurations tailored to specific business contexts by interacting with prompts in the Intelligent Context workspace.
- **[Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5)**
Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.
- **[Parsing and Preprocessing Content](https://help.salesforce.com/s/articleView?id=data.c360_a_parsing_preprocessing_content.htm&release=264.0.0&type=5)**
Prepare unstructured data for chunking by using Data 360 content parsing and preprocessing methods. Parsing and preprocessing identify document structures, such as headings, paragraphs, or tables, remove irrelevant content, and prepare the text for chunking and indexing.
- **[Data 360 Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_process_content_search_index.htm&release=264.0.0&type=5)**
Data 360 uses a search index to manage structured and unstructured content in a search-optimized way. Create a search index configuration to chunk and vectorize your content. Chunking breaks the text into smaller units, reflecting passages of the original content, such as sentences or paragraphs. Vectorization converts chunks into numeric representations of the text that capture semantic similarities.
- **[Content and Knowledge Harmonization](https://help.salesforce.com/s/articleView?id=data.c360_a_harmonize_content_for_consistent_viewing.htm&release=264.0.0&type=5)**
Use Harmonization to transform knowledge articles and unstructured content ingested into Data 360. Harmonization normalizes and enriches content, resulting in a single harmonized schema suited for consistent rendering in the Content Viewer. Access the viewer through Data 360's Data Explorer or in Service Cloud's Enterprise Knowledge component.
- **[Salesforce Catalog](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_catalog.htm&release=264.0.0&type=5)**
The Salesforce Catalog is a unified registry that discovers, indexes, and connects metadata across Salesforce and its ecosystem. This semantically rich foundation powers intelligent automation, agents, and high accuracy natural language queries at scale.
# Processing Frequency for Identity Resolution
Identity resolution processes rulesets as frequently as every 60 minutes to 24 hours, depending on the data source. Each data source is processed on its own timeline according to when data is received and how many changes accumulate.
To process all data sooner, run the ruleset manually or kick it off with an API command. Rulesets won’t run if no records have changed since the previous run.
Identity Resolution Processing Frequency
Data Source
Connectors
data preprocessing?
processing frequency
Initial ingestion by a new data stream
Full refresh of a data source
Batch updates with more than 1 million records
Any ingestion connector
Yes
Up to 18 hours
Streaming ingestion connectors after the initial ingestion
Batch updates with more than 1 million records
Streaming ingestion connectors
Website and Mobile App Connections
Ingestion API
Other connectors that use a streaming ingestion method
Any batch ingestion connector
No, because the data stream only includes new and changed records
1 hour or when 500 changes accumulate in change data capture, whichever is
sooner
Federated Data
Zero Copy Data Federation (Accelerated)
Amazon Redshift
Databricks
Google Big Query
Snowflake
Yes
When accelerated data is received, as often as every 1 hour
Federated Data
Zero Copy Data Federated (Non-accelerated)
Amazon Redshift
Databricks
Google Big Query
Snowflake
Yes
Up to 24 hours
Real-time data
Data 360 Web SDK
No
Immediately
For a complete list of connectors, see [Data 360: Connectors and Integrations](https://help.salesforce.com/s/articleView?id=data.c360_a_sources_targets.htm&type=5&language=en_US).
## Data Preprocessing in Identity Resolution
Data from batch and federated sources is preprocessed to remove records that don't need to be match before source records are sent to identity resolution. This ensures that identity resolution is only processing records that are new or changed, and isn’t rerunning unchanged source records. Preprocessing helps identity resolution run rulesets faster in order to achieve incremental processing, and ensures that credits aren’t consumed by running identity resolution on records that have already been unified in their current form.
To determine if a record is new or changed, source records are converted to an MD5 hash value. The hash value of each record is compared to the hash values of records previously run by identity resolution. Only records with unique hash values are sent for processing by identity resolution.
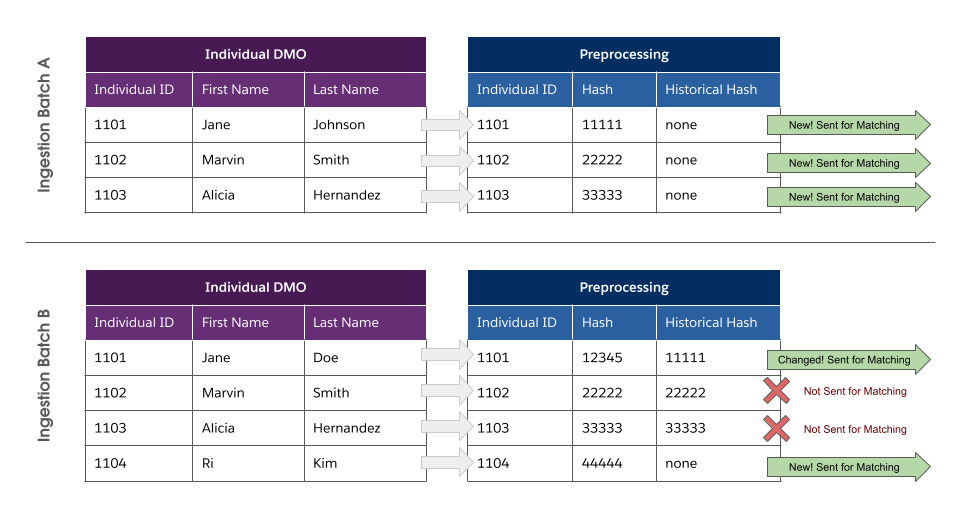
Record preprocessing prevents identity resolution from running unchanged records even if a data source runs a full refresh.
# Product Subject Area
The Customer 360 Data Model product subject area defines anything you plan to sell or any part of a product to track for service purposes.
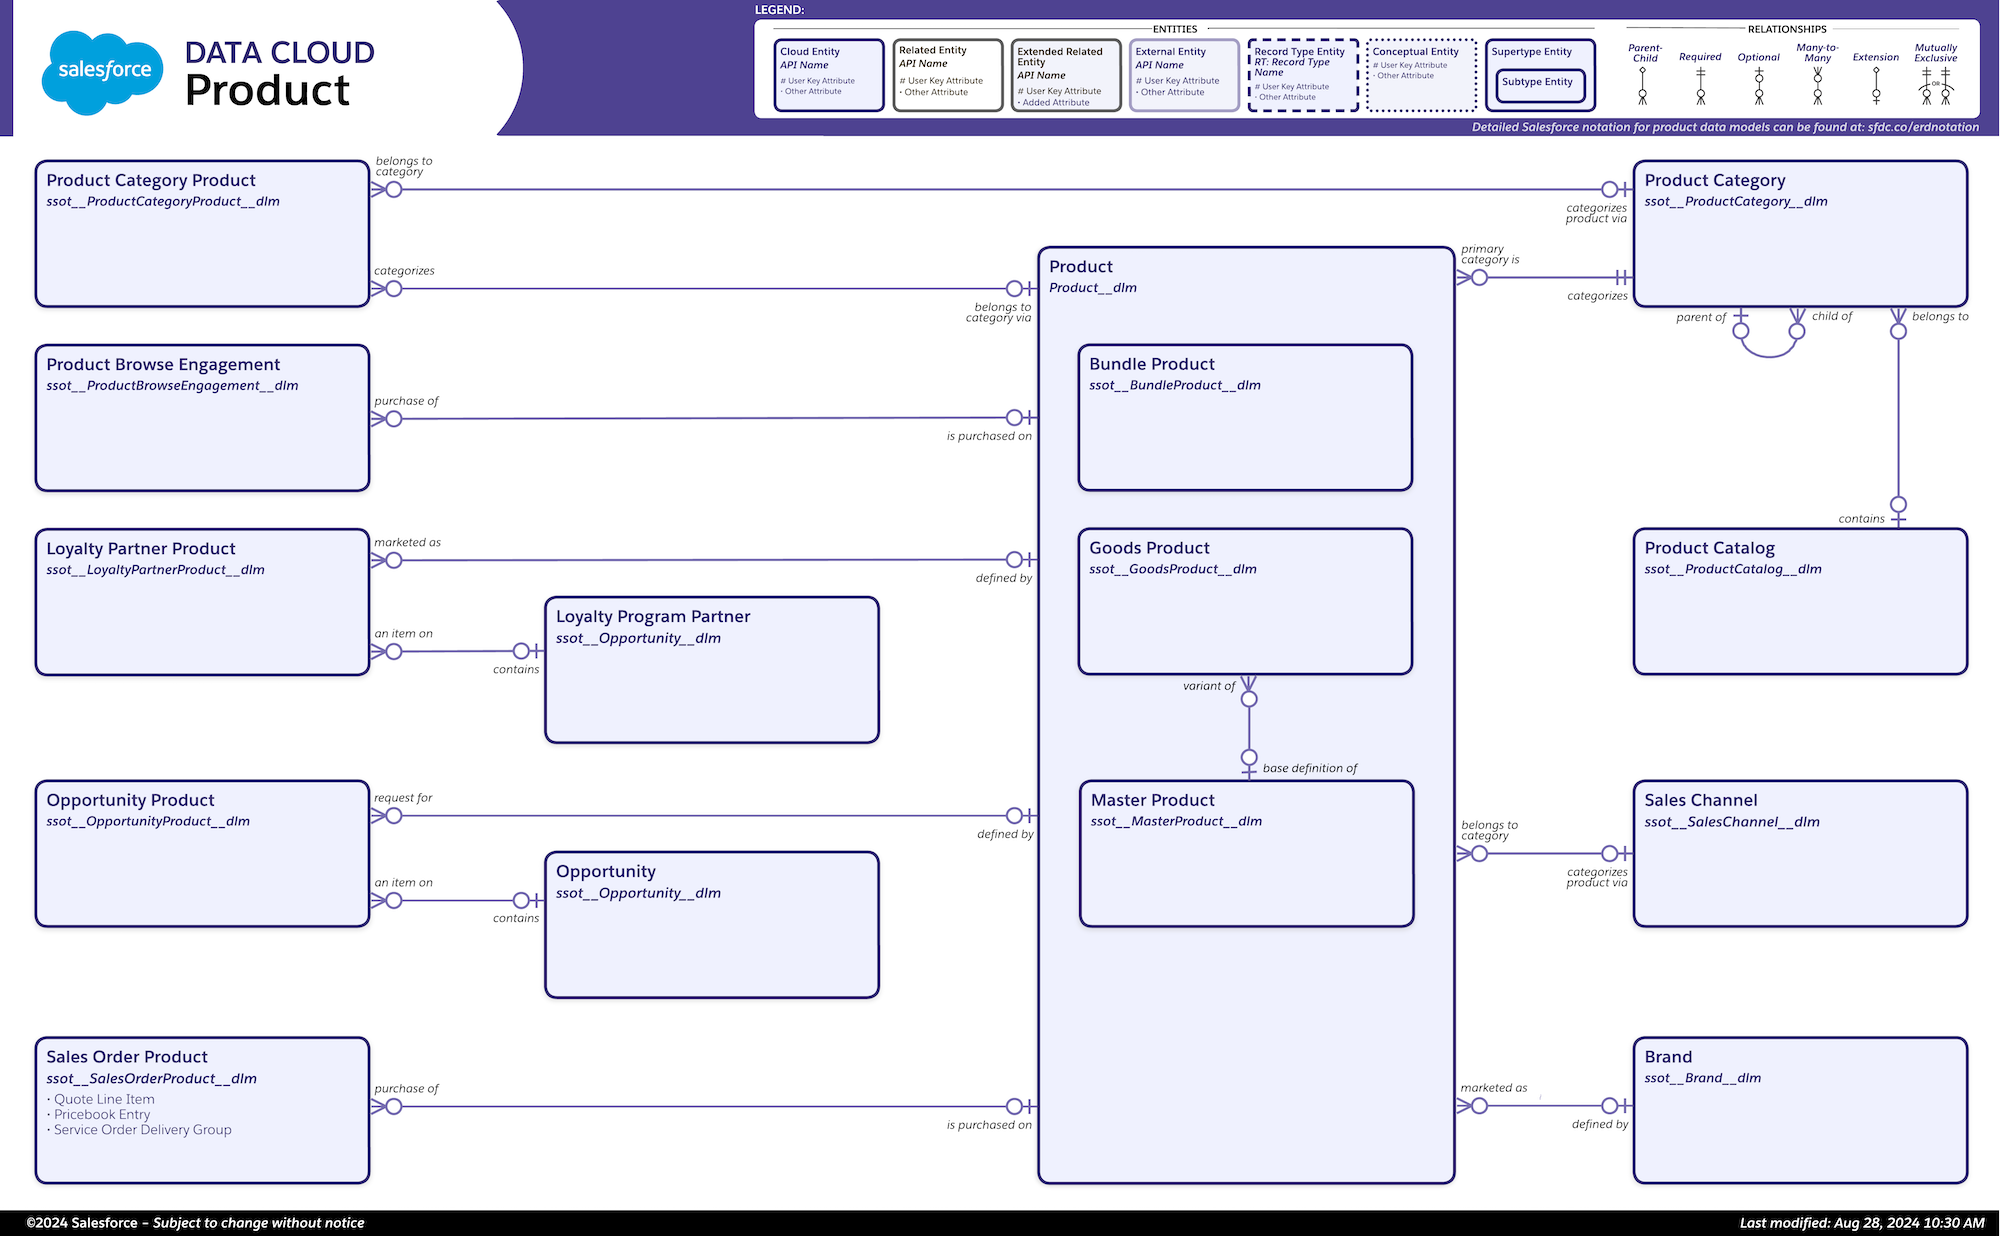
For more details and a larger image, visit the [Data Model Gallery](https://developer.salesforce.com/docs/platform/data-models/guide/product.html).
The following objects from the Product subject area are represented in Data 360.
## Product
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Brand | A Data 360 DMO for the product’s brand, for example, Northern Trail Outfitters. | [Brand DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_brand_dmo.htm) |
| Goods Product | A Data 360 DMO for a specific product, for example, a carton of milk or a set of towels | [Goods Product DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_goods_product_dmo.htm) |
## Product Catalog
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Product Catalog | A Data 360 DMO for a company’s inventory or merchandising catalog. | [Product Catalog DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_catalog_dmo.htm) |
| Product Catalog Category | A Data 360 DMO for the category of the product catalog, for example, shoes, trucks or housewares. | [Product Catalog Category DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_catalog_category_dmo.htm) |
| Product Category | A Data 360 DMO for the types of products a company has or offers, like shoes or types of services. | [Product Category DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_category_dmo.htm) |
| Product Category Product | A Data 360 DMO used to identify how products are assigned to categories. For example, Northern Trail Outfitter’s could use this DMO to identify how a specific running shoe could be assigned to both a shoe and running categories. | [Product Category Product DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_product_category_product_dmo.htm) |
# Profile Explorer Considerations
When using Profile Explorer or the Data 360 Unified Profile Lightning apps, keep these considerations in mind.
- Use Profile Explorer and Unified Profile Lightning apps to show data from data model objects that are part of a unified profile.
- The Last Job Status of the most recent ruleset run of the Identity Resolution ruleset that generated the Unified Profile must be Successful.
- The Profile Explorer individual view and Data 360 Unified Profile Lightning apps only show profile data when you view Unified Individual records from the data space and for the Unified Individual data model object selected during configurations.
- The Data 360 Profile Insights app only shows an result if the configured calculated insight has one dimension and is associated with the Unified Profile selected.
- To display a calculated insight when viewing a Unified Profile in Profile Explorer, include the UnifiedIndividiual.ssot\_id\_\_c field in the outer query.
- The Data 360 Profile Insights app displays numerical metrics using a graph. If the app was configured to display a non-numeric metrics (for example, text or date metrics), an error is returned because these values can’t be displayed in graph format.
# Profile Explorer in Data 360
Get a complete view of a unified profile for an account or individual for purposes such as validating unified profile data and checking for discrepancies. Customers can deploy a set of Lightning apps to customize and expand the experience.
Unified profile information for the unified account or unified individual you select is shown in a dashboard view created from Lightning apps. Customize the profile explorer’s individual view by configure the Lightning apps to show the data most relevant to your Data 360 users.
- Data 360 Profile Related Records—Shows up to 10 fields from a unified data model objects related to the unified individual. This component can be added to the Contact record home page.
- Data 360 Profile Insights—Shows a measure from a selected Calculated Insight with a single dimension. This component can be added to the Contact and Lead record home pages.
- Data 360 Profile Engagements—Shows records from related unified engagement data model objects in the Activity area. This component can be added to the Contact and Lead record home pages.
- CDP Details Panel—Shows selected fields from the unified individual object in up to 4 columns.
- CDP Highlights Panel—Shows selected fields from the unified individual object in up to 2 columns under a custom section title.
- **[View Unified Profiles in Profile Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_search_for_unified_profiles.htm&release=264.0.0&type=5)**
Unified Account and Unified Individual profiles are shown in Profile Explorer. You can search for them by attributes or related attributes.
- **[Data 360 Unified Profile Lightning Apps](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_lightning_apps.htm&release=264.0.0&type=5)**
Display data about unified profiles on certain pages using Lightning apps. In the Profile Explorer, the Data 360 Unified Profile Lightning apps are used to display data on the unified individual profile record page.
- **[Profile Explorer Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer_considerations.htm&release=264.0.0&type=5)**
When using Profile Explorer or the Data 360 Unified Profile Lightning apps, keep these considerations in mind.
#### See Also
- [Profile Explorer Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer_considerations.htm&release=264.0.0&type=5 "When using Profile Explorer or the Data 360 Unified Profile Lightning apps, keep these considerations in mind.")
- [_Salesforce Developer_:Query Customer Profile Information with Profile API](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_profile_call_overview.htm)
# Profile Unification Types
Identity resolution in Data 360 offers several different ways to unify your records. The unification type you select determines what types of objects you can base your unified profiles on, the output objects created by the ruleset, and the speed at which records can be unified.
- **[Unify Individuals or Accounts](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_individuals.htm&release=264.0.0&type=5)**
Identity resolution in Data 360 offers several different ways to unify your records. The unification type you select determines what types of objects you can base your unified profiles on, the output objects created by the ruleset, and the speed at which records can be unified.
- **[Match Leads to Accounts](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_leads_accounts.htm&release=264.0.0&type=5)**
Cross object matching lets you match your leads to existing accounts so that you can identify customers you already have a relationship with.
- **[Group Individuals into Households](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_households.htm&release=264.0.0&type=5)**
Household matching lets you consolidate unified individuals into groups of individuals called households. Households use the Unified Individual object as the primary data model object for the ruleset and output to the Unified Household object.
# Propagate Tags to Downstream Objects and Fields
In Data 360, apply tags automatically from primary data objects to their related downstream objects to ensure consistent policy enforcement.
### Required Editions
| User permission needed | |
| --- | --- |
| To propagate tags: | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. Click **Tagging Manager**.
3. Click **Propagate Tags**.
4. Select an object.
5. If you select a data model object or a calculated insight object, select a data space.
6. Select the object that you want to apply tags downstream to and click **Next**.
7. Review the selected objects, and click **Propagate Tags**.
# Propensity to Buy Template (Beta)
The Propensity to Buy template establishes a starting point for predicting which customer will buy a product or product category within a particular time frame. The template preconfigures model details, prediction inputs, and selects an algorithm. To align the model with your data, customize default variables and set a prediction window—the number of days used to calculate the purchase likelihood. After model training, Model Builder generates purchase likelihood scores on your records so you can identify high-value customer segments and drive targeted marketing campaigns.
## Required Objects and Fields
To use the template and train your model successfully, map these data model objects (DMOs) and fields. Other fields are optional but can improve predictions.
Data Model Object (DMO)
Fields
Individual (ssot__Individual__dlm )
ID (ssot__Id__c )
First Name (ssot__FirstName__c )
Created Date (ssot__CreatedDate__c )
Gender (ssot__GenderId__c )
Yearly Income Range (ssot__YearlyIncomeRangeId__c )
Contact Address (ssot__ContactPointAddress__dlm )
Product (ssot__GoodsProduct__dlm )
ID (ssot__Id__c )
Name (ssot__Name__c )
Primary Product Category
(ssot__PrimaryProductCategory__c )
Product Category (ssot__ProductCategory__dlm )
ID (ssot__Id__c )Name
(ssot__Name__c )
Sales Order Product (ssot__SalesOrderProduct__dlm )
ID (ssot__Id__c )
Sales Order (ssot__SalesOrderId__c)
Product (ssot__ProductId__c )
Total Line Amount (ssot__TotalLineAmount__c )
Product Browse Engagement
(ssot__ProductBrowseEngagement__dlm )
ID (ssot__Id__c )
Individual (ssot__IndividualId__c )
Engagement Date & Time
(ssot__EngagementDateTm__c )
Product ID (ssot__ProductId__c )
Sales Order (ssot__SalesOrder__dlm )
ID (ssot__Id__c )
Sold To Customer ID (ssot__SoldToCustomerId__ )
Purchase Order Date (ssot__PurchaseOrderDate__c )
Grand Total Amount (ssot__GrandTotalAmount__ )
Shopping Cart Engagement
(ssot__ShoppingCartEngagement__dlm )
ID (ssot__Id__c )
Individual (ssot__IndividualId__c )
Engagement Date & Time
(ssot__EngagementDateTm__c )
Product ID (ssot__ProductId__c )
Shopping Cart Event Type ID
(ssot__ShoppingCartEventTypeId__c )
Product Quantity (ssot__ProductQuantity__c )
- **[Configure a Propensity to Buy Template (Beta)](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_model_configure_propensity_to_buy.htm&release=264.0.0&type=5)**
Configure the Propensity to Buy (beta) template to automatically create the data transforms, output data model objects, and predictive model required to generate propensity scores. Query the scores to assess a customer's likelihood of making a purchase within your specified prediction window.
# Publish a Clean Room Package to AppExchange
After creating a clean room package in Data Cloud Setup, use data kits to package it. Then use the package manager to create a managed package and publish it on AppExchange. You can only publish managed packages on AppExchange.
### Required Editions
Available in: Developer Edition
User Permissions Needed
To publish a clean room package to AppExchange:
AppExchange partner

Note You must be an AppExchange partner to publish a package to AppExchange.
1. [Create a data kit.](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_bundle_package_kits.htm&release=264.0.0&type=5 "Streamline package creation and the installation experience for Data 360 objects by wrapping together the metadata and relationships into a standard data kit. Use a Developer Edition org that supports managed packages to create and publish a standard data kit. Use a DevOps data kit to migrate metadata across orgs.")
2. After saving the data kit, under Clean Room Providers, select the provider name.
3. Verify that the publishing sequence of the data kit is visible and synced.
4. [Publish the data kit.](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_bundle_package_kits.htm&release=264.0.0&type=5 "Streamline package creation and the installation experience for Data 360 objects by wrapping together the metadata and relationships into a standard data kit. Use a Developer Edition org that supports managed packages to create and publish a standard data kit. Use a DevOps data kit to migrate metadata across orgs.")
5. [Add the data kit to Package Manager](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_package_kit.htm&release=264.0.0&type=5 "After creating and publishing your data kit in Data 360 source org, add the data kit to a package and upload it using Package Manager in your Salesforce org.").

Important Select Managed when you create the package.
See the [AppExchange ISV Onboarding Guide](https://www.salesforce.com/en-us/wp-content/uploads/sites/4/documents/partners/readiness/appexchange_isv_onboarding_guide.pdf) for the requirements and steps to become a Salesforce Partner.
See the [The AppExchange Partner Console Guide](https://www.salesforce.com/en-us/wp-content/uploads/sites/4/documents/partners/readiness/the_appexchange_partner_console_guide.pdf) to use the Salesforce Partner Console.
**Next steps:**
- If you’re using Data 360 as the clean room platform, map your data as required in the collaboration template and save it as a mapped template. When a consumer deploys your package and sends an invitation, use the mapped template for the collaboration.
- If you’re using AWS Clean Rooms, publishing the package is your last action in Data 360. You accept the collaboration invitation and manage the rest of the collaboration in AWS Clean Rooms. See [Collaborating with an AWS Clean Rooms Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_with_aws_provider.htm&release=264.0.0&type=5 "As a consumer using Data 360 clean rooms, you can initiate collaborations with a provider who uses AWS Clean Rooms. AWS-based providers use Data 360 once to create and publish the clean room package, then complete every other action in AWS Clean Rooms. Consumers manage their side of the collaboration entirely in Data 360.").
#### See Also
- [_AWS Documentation_: Creating a Membership and Joining a Collaboration](https://docs.aws.amazon.com/clean-rooms/latest/userguide/create-membership.html)
# Publish a Segment in Data 360
After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.
### Required Editions
Permission Sets Needed
To publish a segment:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data 360, go to **Segments**.
2. Select your segment from the list.
3. On the segment details page, to have the activation target pick up the segment, click the dropdown menu and select **Publish Now**.
The amount of time it takes to publish the segment depends on your volume and activation target. To see when the segment was published, check the Publish History page. To schedule publishing, edit the segment’s properties.
- **[Increase Segment Refresh from Data 360 to the Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_rapid_segment_publish.htm&release=264.0.0&type=5)**
Increase the frequency of segment refresh and shorten publishing time for activations from Data 360 to the activation targets using Rapid Publish. When you create a segment, choose Rapid Publish to run on a daily schedule at a 1-hour or 4-hour interval.
- **[Segment Types and Statuses](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_types_statuses.htm&release=264.0.0&type=5)**
Learn more about the values provided about each segment. View details in the Segments section of Data 360, or in Publish History for a specific segment. Depending on how you create the segment, the type can be UI (created via the Segment Builder) or DBT (created via the API).
#### See Also
- [_Salesforce Help_: Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_targets.htm&release=264.0.0&type=5 "Depending on your use case, data can be activated to various targets, from file storage, external activation, or to other data model objects (DMOs) in Data 360. Once you know where you want to act on the segmented data from Data 360, create activation targets for each platform.")
- [_Salesforce Help_: Edit a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_segment.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can edit its rules or properties to provide updates or change the purpose. Changing the segment name doesn’t change the segment API name.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- [_Salesforce Help_: Customer Data Platform Billable Usage Calculations](https://help.salesforce.com/s/articleView?id=data.c360_a_billing.htm&release=264.0.0&type=5 "Previously named Customer Data Platform orgs are billed based on contracted entitlements. Understanding which usage is included for billing helps you make data management decisions.")
# Purchases Filters
Here are some examples of common purchases use cases.
## Delayed Product Sales Orders
This filter finds individuals who made a purchase and have an order status of delayed.

Example
- Sales Order | Count | At Least | 1
- Sales Order Status | Is Equal To | Delayed

## Find Combined Purchases and Order Number
This filter looks for individuals who made purchases with a combined total greater than $1,000, their order numbers contained MARCH, and they self-identified their phone's contact point as based in New York City.

Example
- Sales Order | Count | At Least | 1
- Order Number | Contains | MARCH
- AND
- Grand Total Amount | Is Greater Than | 1000
AND
- Contact Point Phone | Count | At Least | 1
- City Name | Is Equal To | New York City
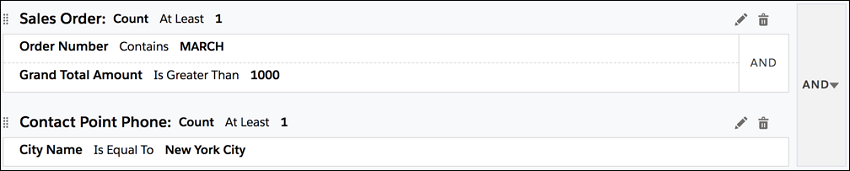
## Combined Purchases and Order Start Date
This filter finds individuals who made a combined purchase greater than $1,000, have an order start date in March, and a contact point city equal to New York City.

Example
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 1000
- AND
- Order Start Date | Month Of Year | March
AND
- Contact Point Phone | Count | At Least | 1
- City Name | Is Equal To | New York City
## Gender, Sales Order, and Location
This filter finds males who spent more than $300 and have a location of New York or Boston.

Example
- Sales Order | Sum | Grand Total Amount | Is Greater Than | 300
- Grand Total Amount | Is Greater Than | 300
AND
- Contact Point Phone | Count | At Least | 1
- City Name | Is In | New York, Boston
AND
- Gender | Is Equal To | Male

Alternative Example
- Sales Order | Sum | Grand Total Amount | Is Greater Than | 300
- Grand Total Amount | Is Greater Than | 300
AND
- Contact Point Phone | Count | At Least | 1
- City Name | Is In | New York
- OR
- City Name | Is Equal To | Boston
AND
- Gender | Is Equal To | Male
## Order Number, Sales Store, and Subject Line Engagement in the Last 3 Days
This filter looks for customers who made a purchase in store number 1283, their order number contained 2020, and they clicked or opened an email with a subject line of NYC In Store Factory Refurbished Sale.

Example
- Sales Order | Count | At Least | 1
- Sales Store | Begins With | 1283
- AND
- Order Number | Contains | 2020
- AND
- Order Start Date | Last Number Of Days | 3
AND
- Email Engagement | Count | At Least | 1
- Engagement Channel Action | Is In | Click, Open
- AND
- Subject Line Text | Is Equal To | NYC In Store Factory Refurbished Sales
- AND
- Engagement Date Time | Last Number Of Days | 3
## Purchases in the Last 30 Days by Gender
This filter finds individuals who aren’t male and made an order start date within the last 30 days.

Example
- Sales Order | Count | At Least | 1
- Order Start Date | Last Number Of Days | 30
AND
- Gender | Is Not Equal To | Male
## Previous Purchase but Not in the Last 30 Days by Gender
This filter finds individuals who aren’t male and made a purchase more than 90 days ago but not in the last 30 days.

Example
- Sales Order | Count | Is Equal To | 0
- Order Start Date | Last Number Of Days | 30
AND
- Sales Order | Count | At Least | 1
- Order Start Date | Greater Than Number Of Days | 90
AND
- Gender | Is Not Equal To | Male
## Purchase a Product in the Last 30 Days
This filter looks for customers who purchased at least two non-black hiking boots in the same order in the last 30 days.

Example
- Sales Order Product | Count | At least | 2
- Product Name | Is Equal to | Hiking Boots
- AND
- Product Description | Is Not Equal To | Black
- AND
- Order Start Date | Last Number of Days | 30
## Purchased a Product by Month
This filter looks for customers who purchased hiking boots or tents in May.

Example
- Sales Order Product | Count | At least | 1
- Product Name | Is In | Hiking Boots, Tents
- AND
- Order Start Date | Month Of Year | May
## Purchased a Product but Not Another Product
This filter looks for customers who purchased kayaks but no safety vests within a certain time frame.

Example
- Sales Order Product | Count | At least l 1
- Product Name | Is Equal To | Kayaks
- AND
- Order Start Date | Is Between | 2020-05-01 AND 2020-06-01
AND
- Sales Order Product | Count | Is Equal To | 0
- Product Name | Is Equal To | Safety Vests
- AND
- Order Start Date | Is Between | 2020-05-01 AND 2020-06-01
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Queries in Clean Rooms
Run queries in a clean room to compare your data with a collaborator's data and gain insights, without exposing raw records.
### Required Editions
Available in: Enterprise Editions
Query results vary based on the use case of the collaboration.
## How Queries Work in a Collaboration
A collaboration is based on a use case. When a use case includes more than one query, every query in the use case is available in the collaboration, and you select which query to run. A query compares a consumer segment with the provider's data and returns a result that meets the privacy rules that the template defines.
Run a query in two ways.
Manual run
Run the query ad hoc and get a result for the segment that you select.
Scheduled run based on segment publish
Schedule the query to run each time its consumer segment publishes. The query follows the segment's existing publish schedule, so the result refreshes on the same cadence as the segment.
To schedule a query on segment publish, the consumer segment needs a publish schedule. If the segment doesn't have a publish schedule, an associated query runs ad hoc only.
When a use case includes more than one query, schedule each query to run on the segment publish schedule. The queries share the same publish trigger but produce separate results. Data 360 prevents a duplicate schedule for the same combination of query, segment, and parameter values, so you can't create the same schedule twice.
Scheduling a query doesn't remove the ad hoc option. Run a scheduled query manually on demand — a manual run doesn't change the schedule.

Run and Schedule Queries for a Campaign
A marketing team (consumer) collaborates with a publisher (provider) on a use case that includes two queries: an audience overlap query and a reach summary query. Because the use case has multiple queries, both are available in the collaboration, and the team chooses which one to run.
The team schedules the overlap query to run on segment publish for their Loyalty Members segment, which publishes every week. Each time the segment publishes, the query reruns automatically, so the team always has a current overlap count without running the query by hand.
Midweek, the team starts a promotion and needs current numbers before the next scheduled run. They run the overlap query for the same segment. The manual run returns an immediate result and doesn't change the weekly schedule. Later, they run the reach summary query to check the performance of the promotion.
## Next Steps
Continue with these related tasks.
- To run a query now or schedule one, see [Collaborate in a Clean Room](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_in_clean_room.htm&release=264.0.0&type=5 "Set up a query in a Data 360 clean room collaboration to compare a consumer segment with the provider's data, without exposing raw records. Run a query manually for an immediate output, or schedule it to run each time the segment publishes.").
- To stop a run that's in progress, see [Cancel a Query Run](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_cancel_a_query_run.htm&release=264.0.0&type=5 "Cancel a query run that's in progress when you no longer need the result or you started the run by mistake.").
- To find query output and reports, see [View Clean Room Query Results](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_view_clean_room_query_results.htm&release=264.0.0&type=5 "Check the latest output for a clean room query whenever a manual or scheduled run completes.").
- To review or delete your scheduled queries, see [Manage Scheduled Queries](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_manage_scheduled_queries.htm&release=264.0.0&type=5 "Review the queries scheduled to run on segment publish in a collaboration, check their status, and delete a schedule that you no longer need.").
# Query Data in Data 360
A query is a structured request for specific information from Data 360. It's similar to asking a precise question of your data. Data 360 offers multiple ways to query your data.
## Data 360 Query Tools
You can query Data 360 data in several ways:
- **Integrated Apps:** Use integrated apps like [Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor.htm&release=264.0.0&type=5 "With the Data 360 Query Editor, you can directly query harmonized customer data using Data 360 SQL (Structured Query Language). You can build queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.") and [DBeaver](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/data-cloud-jdbc.html) to visually explore and query data.
- **Data 360 Connect API:** Connect mobile apps, websites, and third-party applications to retrieve filtered and localized data using the [Connect REST API](https://developer.salesforce.com/docs/data/connectapi/references/about-sample-api/about-connect-api.html).
- **Custom Applications:** Connect your custom applications to Data 360 to access and use its data through [language-specific libraries](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/lang-specific-libraries.html).
- **Data 360 SQL:** Use Data 360 SQL to write precise queries and retrieve very specific information about your data. For detailed information on writing queries, see [Query Data in Data 360](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/query-guide-get-started.html).
- **Query Federation:** Use query federation to query your partner-managed compute without duplicating your data into Data 360.
## Topics
- **[Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor.htm&release=264.0.0&type=5)**
With the Data 360 Query Editor, you can directly query harmonized customer data using Data 360 SQL (Structured Query Language). You can build queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.
- **[Optimize Queries with Secondary Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_query_secondary_indexes.htm&release=264.0.0&type=5)**
When you create a secondary index on a data lake object (DLO) or materialized data model object (DMO), Data 360 quickly finds and returns data based on defined secondary field values. A secondary index improves performance and reduces credit usage.
#### See Also
- [_Salesforce Help_: Data 360 Billable Usage Types](https://help.salesforce.com/s/articleView?id=data.c360_a_data_usage_types.htm&release=264.0.0&type=5 "Usage of certain Data 360 features impacts credit consumption. If you purchased credits before February 24, 2026, your org consumes Data Services credits for Data 360 services. Orgs purchasing or renewing after February 24, 2026 can have either Data Services or Flex Credits. To monitor your usage in these Data Services usage categories, access your org’s Digital Wallet. If your org has a Data 360 Profiles-type license, some usage types aren't consumed. For more information on how usage is billed, refer to your contract or contact your account executive.")
# Query Data in Data Model using Tableau
Download your segment membership data in Data 360 and then analyze in Tableau.
### Required Editions
Permission Sets Needed
To download a file:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. In Data Cloud, click **Data Model**.
2. Check the box next to your DMO table name (for example: Individual - Latest).
3. Click **Download Tableau Source File**.
# Query Data using SOQL
In Data 360, you can analyze segment membership data using SOQL in Data Explorer.
### Required Editions
Permission Sets Needed
To view data in Data Explorer and to run a query:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
1. In Data Cloud, click **Data Explorer**.
2. From the Object dropdown list, select **Data Model Object**.
3. Select your DMO table name (for example: Individual - Latest).
4. Click **Copy SOQL**, and click **Copy**.
To run a query, paste the SOQL statement into the Developer Console.
#### See Also
- [_Salesforce Help_: Open the Developer Console](https://help.salesforce.com/s/articleView?id=platform.code_dev_console_opening.htm&type=5&language=en_US)
# Query Editor
With the Data 360 Query Editor, you can directly query harmonized customer data using Data 360 SQL (Structured Query Language). You can build queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.
Query Editor empowers you to:
- Explore and understand data: Get a complete view of your unified customer profiles, engagement history, and all connected data within Data 360.
- Perform ad-hoc analysis: Quickly write and execute SQL queries to answer specific business questions, validate data integrity, or investigate data patterns.
- Validate data and transformations: After you set up data streams and transformations, use the Query Editor to verify that your data is processed as expected.
- Build and test SQL queries: Develop and refine the SQL logic for custom segments, calculated insights, or data extracts before implementing them in other Data 360 features or external systems.
- Troubleshoot data issues: Pinpoint and diagnose discrepancies, missing data, or unexpected values by querying the raw and transformed data directly.
## Topics
- **[Manage Workspaces in Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor_create_workspace.htm&release=264.0.0&type=5)**
Create and delete workspaces in Query Editor to build, execute, and save SQL queries for Data Lake Objects (DLOs), Data Model Objects (DMOs), and data graphs in Data 360.
- **[Create Queries in Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor_create_queries.htm&release=264.0.0&type=5)**
Build Data 360 SQL queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.
- **[Use Query Editor in a Data Cloud One Companion Org](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor_data_cloud_one.htm&release=264.0.0&type=5)**
Query Editor has the same features in the Data Cloud One app as it does in Data 360. However, its settings and data access capabilities vary depending on the companion org.
# Query Unstructured Data Using Query API
Use Query API to retrieve a URL to view unstructured data files. Queries return a presigned URL that you can open in your browser.
### Required Editions
Query API supports this special query operator: `GET_PRESIGNED_URL`: Returns a presigned URL.

Note Presigned URLs are only available for Amazon S3 and Cloud Storage.

Example
Use this syntax to retrieve an object from an external blob store.
```
SELECT get_presigned_url('', udmo.ResolvedFilePath__c, ) from as udmo;
```
Where:
- is a string that represents the name of the Directory Table.
- an integer that specifies the amount of time in seconds the requested object is available. The maximum TTL is 1,800 seconds (30 minutes).
# R2 Quality Alert
R2 (R-squared), or the coefficient of determination, is a performance metric that evaluates how well a regression model fits the data.
## Actions to Consider
- A low R2 indicates that the model doesn’t perform well. Improve the model before you activate it.
- A high R2 indicates that the model performs so well that data leakage can be a factor. Investigate and remove any variables that cause data leakage.
## Detection Methodology
Model Builder displays an alert when it detects a high or low R2 score based on these values.
- Below 0.3 (low)
- Above 0.95 (high)
## Example
A retail brand wants to predict monthly sales for each store. To achieve this, the retailer builds a regression model with these input variables.
- store size (sq. ft)
- number of employees
- average customer footfall per day
- advertising spend per month
- local population density
After model training, an alert displays because the R-squared score is 0.45, which is considered low. The score indicates that the model explains only 45% of variation in the "monthly sales" target variable and that it isn’t capturing other factors that are influencing sales. Thus, the predictions can be unreliable. To resolve the issue, here are some actions to consider.
- Improve model performance with additional variables such as “store promotion” or “competitor proximity".
- Check the data quality to identify missing values, outliers, and inconsistencies.
- Use more historical sales data to improve the quality of data.
- Use more complex modeling algorithms, such as random forest or gradient boosting, if linear models underperform.
- Compare the difference between actual and predicted sales to uncover patterns or inconsistencies.
- Retrain the model with an updated dataset.
# Real-Time Capabilities in Data 360
By using the real-time capabilities of Data 360, you can enable consistent, synchronized customer data across all platforms. Real-time features provide sub-second data processing across multiple customer interactions.
For example, an ecommerce retailer can elevate shopping experiences by providing real-time personalized recommendations or next-best actions based on user behavior. The platform can target its top offers based on a customer's past purchases and current browsing activity.
To use real-time capabilities, you must first create a real-time data graph.
# Real-Time Identity Resolution
Real-time identity resolution identifies customers in milliseconds so you can personalize your site or communications during an engagement.
Real-time identity resolution is performed by comparing profile information for an active user with existing profiles using the rules in an existing ruleset. To designate a ruleset for real-time identity resolution, use its output as the input for a real-time data graph.
If you use a ruleset for real-time identity resolution, all match rule criteria will be run using exact or exact normalized match methods, even if you selected a different match method when configuring the ruleset. Match on Blank is ignored in real-time runs.
Profile information that’s received for real-time identity resolution is also stored and unified to a profile during the next scheduled ruleset run using your selected match method. Unifying real-time identity information via the scheduled ruleset run to ensure your unified profiles contain the most complete and updated information about your customers.
#### See Also
- [_Salesforce Help_: Unify Individual Profiles in Real Time](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_realtime.htm&release=264.0.0&type=5 "Real-time profile unification reviews profile information immediately and completes real-time profile matching in milliseconds. Real-time matching matches information about an active end user to a unified profile so that you can personalize your app or website within milliseconds.")
- [_Salesforce Help_: Configure Real-Time Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_configure_real_time_matching.htm&release=264.0.0&type=5 "You can configure any ruleset for real-time matching after its first ruleset run is completed by creating a real-time data graph based on the ruleset’s output unified profile data model object.")
# Reapply Tags for a Data Graph
After updating or removing tags at the DMO level, reapply tags to synchronize a data graph with the latest tag configuration from its source DMOs. When you reapply tags, all existing tags on the data graph are removed and replaced with the current tags from source DMOs and fields.
### Required Editions
User Permission Set Needed
To reapply tags for a data graph:
Permission set:
Data 360 recalculates access to objects and fields, and subsequent queries return data based on the updated access rules. This action replaces the entire tag configuration.
1. In Data Graph, locate the data graph that you want to update.
2. In the confirmation dialog, click **Reapply**.
# Rebuild a Search Index Configuration
If a Data 360 search index doesn't process properly, you can trigger a full rebuild of the index from the list page or the object record view.
### Required Editions
User Permissions
Needed
To rebuild a search index configuration:
Permission set:
The volume of data determines the time that it takes to rebuild a search index. The rebuild time can differ from the initial build because the amount of data in the data model object may have changed. This action reprocesses all data in the search index and can potentially consume a significant number of credits. Search indexes update continuously, so you don't have to rebuild them manually. If Data 360 dosen't process new content automatically, contact Salesforce Customer Support before rebuilding.
1. From app Launcher, select **Data Cloud**.
2. Click the search index configuration that you want to rebuild.
3. On the details page, select **Rebuild**.
The rebuild process happens in the background. You can continue to query the search index during this time without any interruptions. After a new version of the index is successfully built, the current version of the index is seamlessly replaced. See [View Search Index Status and Process History](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_view_search_index.htm&release=264.0.0&type=5 "View details of search index configurations from the Search Index list view and the object record view to monitor the indexing process.") for an explanation of statuses.

Note
The Rebuild action isn't available for search indexes created by Agentforce Data Library (ADL) for file uploads. It's available only for search indexes created by Agentforce Data Library (ADL) for knowledge articles.
# Rebuild Streaming Transform Target Objects
Rebuild a streaming transform target object to ensure data consistency.
Streaming transforms take data from a source object, transform it, and write the output to a new object. If a system error occurs during processing, the output object's data may be incomplete. Rebuilding the transform target object reprocesses all the source data and generates new results for the target.
Another situation where rebuilding is useful is when a streaming transform is edited. Editing a transform applies to new records. Existing records in the output are not affected. If you want to apply the changes to all records, the transform target object must be rebuilt.
1. From the Data Transforms records page, select Rebuild from the drop down menu. This Rebuilds the target object that the data transform writes to.
2. Run the rebuild.
- If there’s only transform writing to the target object, confirm the rebuild and click **Run**.
- If there’s more than one transform writing to the same target object, you’re prompted to **Continue** and select the transform order for which the target object should be rebuilt. The order of the transforms is important because running one transform could overwrite the data that has already been written by a previous transform. After selecting the order, click **Run**.
3. View the refresh history page to track the progress of the data rebuild, which may take some time depending on the amount of data. During the rebuild process, the Last Run Status changes to Rebuild Pending and then to Rebuilding.
The rebuild deletes existing records in the target object and reprocesses records from the source object. The target object remains unchanged throughout the rebuild process. During this time, transforms that write to the target object can’t be created or deleted.
# Reconciliation Rule Warnings
Reconciliation rule warnings help you identify fields to change or review. You can ignore a reconciliation rule warning. Identity resolution processes run even with these warnings.
| Warning | Solution |
| --- | --- |
| Select a supported reconciliation rule for ID fields. | Reduce the frequency of value changes in ID fields by selecting the Source Priority reconciliation rule and then ordering source data lake objects by priority. |
# Record Caching and User Session Length in Real-Time Data Graphs
Configure your real-time data graph to manage the number of records held in the cache and user session length.
## Record Caching
Record caching keeps records of your recently active visitors in the real-time layer and allows instant personalization on the first page of your website or app. When record caching is enabled, profile and entity data for your recently active known visitors remains available in the real-time layer and does not require a fetch from the Data360 Lake House layer during a live session.
If record caching is disabled, the first page visited by your known visitors might not show personalization immediately because profile data must first come from the Data360 Lake House layer. Depending on system conditions, this fetch can take time before personalization appears.
When record caching is disabled, your sub-second real-time profiles and entities entitlements do not get consumed for the months in which caching remains disabled.
## User Session Length
The session length defines the amount of time after a user stops engaging with your website that the session is considered to be active. If you set the timeout period to 30 minutes, a user’s session is inactive 30 minutes after the most recent engagement from the user. Any engagement that happens at 31 minutes or after is a new session.
Data 360 maintains the required session length under normal conditions. However, if a significant spike in web traffic occurs, sessions can end earlier than expected.
The industry standard for session expiration is 30 minutes of inactivity. The maximum supported session duration is 48 hours.
#### See Also
- [_Salesforce Help_: Session Extension in Real-Time Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_sess_ext_data_graphs.htm&release=264.0.0&type=5 "To maintain consistency between a real-time data graph and a standard data graph, session extension preserves your data for a longer period while the standard graph updates.")
# Record Modified Field
The record modified field is set when defining the source object during setup in Data 360.
### Required Editions
Available in: Lightning Experience
The record modified field acts as a reference point when the system is deciding whether to update the record in the event data is received out of order.

Example Three files exist, each containing customer record 123. File 3 comes first, then File 1, then File 2. The files are ingested in a different order: File 1, File 2, File 3.
File 1 is received and, as it’s a new customer ID, the record is created and the customer’s favorite color is logged as Blue.
**Content of File 1**
| Customer\_ID | Favorite\_Color | Record\_Modified\_Date |
| --- | --- | --- |
| 123 | Blue | 12/17/2020 00:00:00 UTC |
When File 2 comes into the system, the Record Modified Field was set in the UI as Record\_Modified\_Date. The system compares the timestamp of the Blue record with the timestamp of the Red record and determines that the Red record is more up to date. So the system overwrites the Blue record with the Red record.
**Content of File 2**
| Customer\_ID | Favorite\_Color | Record\_Modified\_Date |
| --- | --- | --- |
| 123 | Red | 12/17/2020 02:00:00 UTC |
File 3 comes into the system. Because this record’s modified date is older than file 2, it isn’t the most current record. The favorite color attribute isn’t overwritten and remains Red.
**Content of File 3**
| Customer\_ID | Favorite\_Color | Record\_Modified\_Date |
| --- | --- | --- |
| 123 | Yellow | 12/15/2020 13:00:00 UTC |
# Redeploy a Data Kit When Its Data Graph Is Deployed
When you redeploy a data kit that contains an already-deployed data graph, Data 360 leaves the data graph unchanged and marks it as successful. This process ensures that the overall data kit deployment succeeds. The data kit version can change between deployments, and the new version might or might not include data graph changes. In either case, the redeployment doesn’t fail.
### Required Editions
User Permission Set Needed
To redeploy the data kit:
Permission set:
To redeploy the data kit:
1. From Setup, in the Quick Find box, enter Data Kits, and then select **Data Kits**.
2. Open the data kit, and click **Data Kit Deploy**.
3. In the Deploy window, enter the required org ID.
4. Click **Deploy**.
5. On the Deployment History tab, monitor the deployment status
When deployment finishes, the existing data graph and the overall data kit deployment show a successful status.
# Refine Segments with Grouping, Ranking, and Limiting
In Data 360 Segmentation, after setting your initial criteria in the Include and Exclude tabs, go to the Rank and Limit tab to further refine your segment. The first container is automatically created and locked to your segment's primary entity. This container defines your innermost filtering rule.
### Required Editions
Permission Sets Needed
To create a container:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. Drag an attribute into the container to define your grouping criteria and set the rule type to **Group By**.
2. Drag a second attribute into the container to define your ranking criteria. Set the rule type to **Sort By** and select a sort order.
3. Enter a number in the **Maximum Records** field to limit the records selected from each group.
The maximum number of records allowed is 2 billion.
4. Click **Add Ruleset** to create a second, outer container that defines the next layer of filtering.
5. In the new container, click the **Object** dropdown. The objects available are determined by the Group By attribute used in the previous step. Select the appropriate object for this rule.
6. Repeat the process of adding Group By and Sort By attributes and setting a maximum number to limit the records for this new group.
7. Continue adding rule sets as needed for each layer of filtering.
8. Click **Done**.

Example
First, let's create a segment that selects only the top two contacts from each account based on their authority level. This is useful for targeting key decision-makers.
In your first container:
1. Set the **Maximum number of Account Contacts** to 2.
2. For the **Group By** rule, use the **Account ID** attribute. This groups all contacts by the account they belong to.
3. For the **Sort By** rule, use the **Authority Level** attribute and set the order to Descending. This ranks the contacts within each account.
This single rule set limits the segment to only the two highest-ranked contacts from every account that meets your Include criteria.
Now, let's extend the example. Before finding the top contacts, find the top 10 accounts for each account owner, based on a Fit Score. This creates a targeted list of the most important contacts from the most promising accounts.
Add a second container (the outer rule):
1. Select the **Account** object from the dropdown.
2. Set the **Maximum number of Accounts** to 10.
3. For the **Group By** rule, use the **Account Owner** attribute.
4. For the **Sort By** rule, use the **Fit Score** attribute and set the order to **Descending**.
5. Click **Save**.
When you save, as illustrated, Data 360 finds the top 10 accounts for each owner, and then selects the top 2 contacts from each of those accounts.
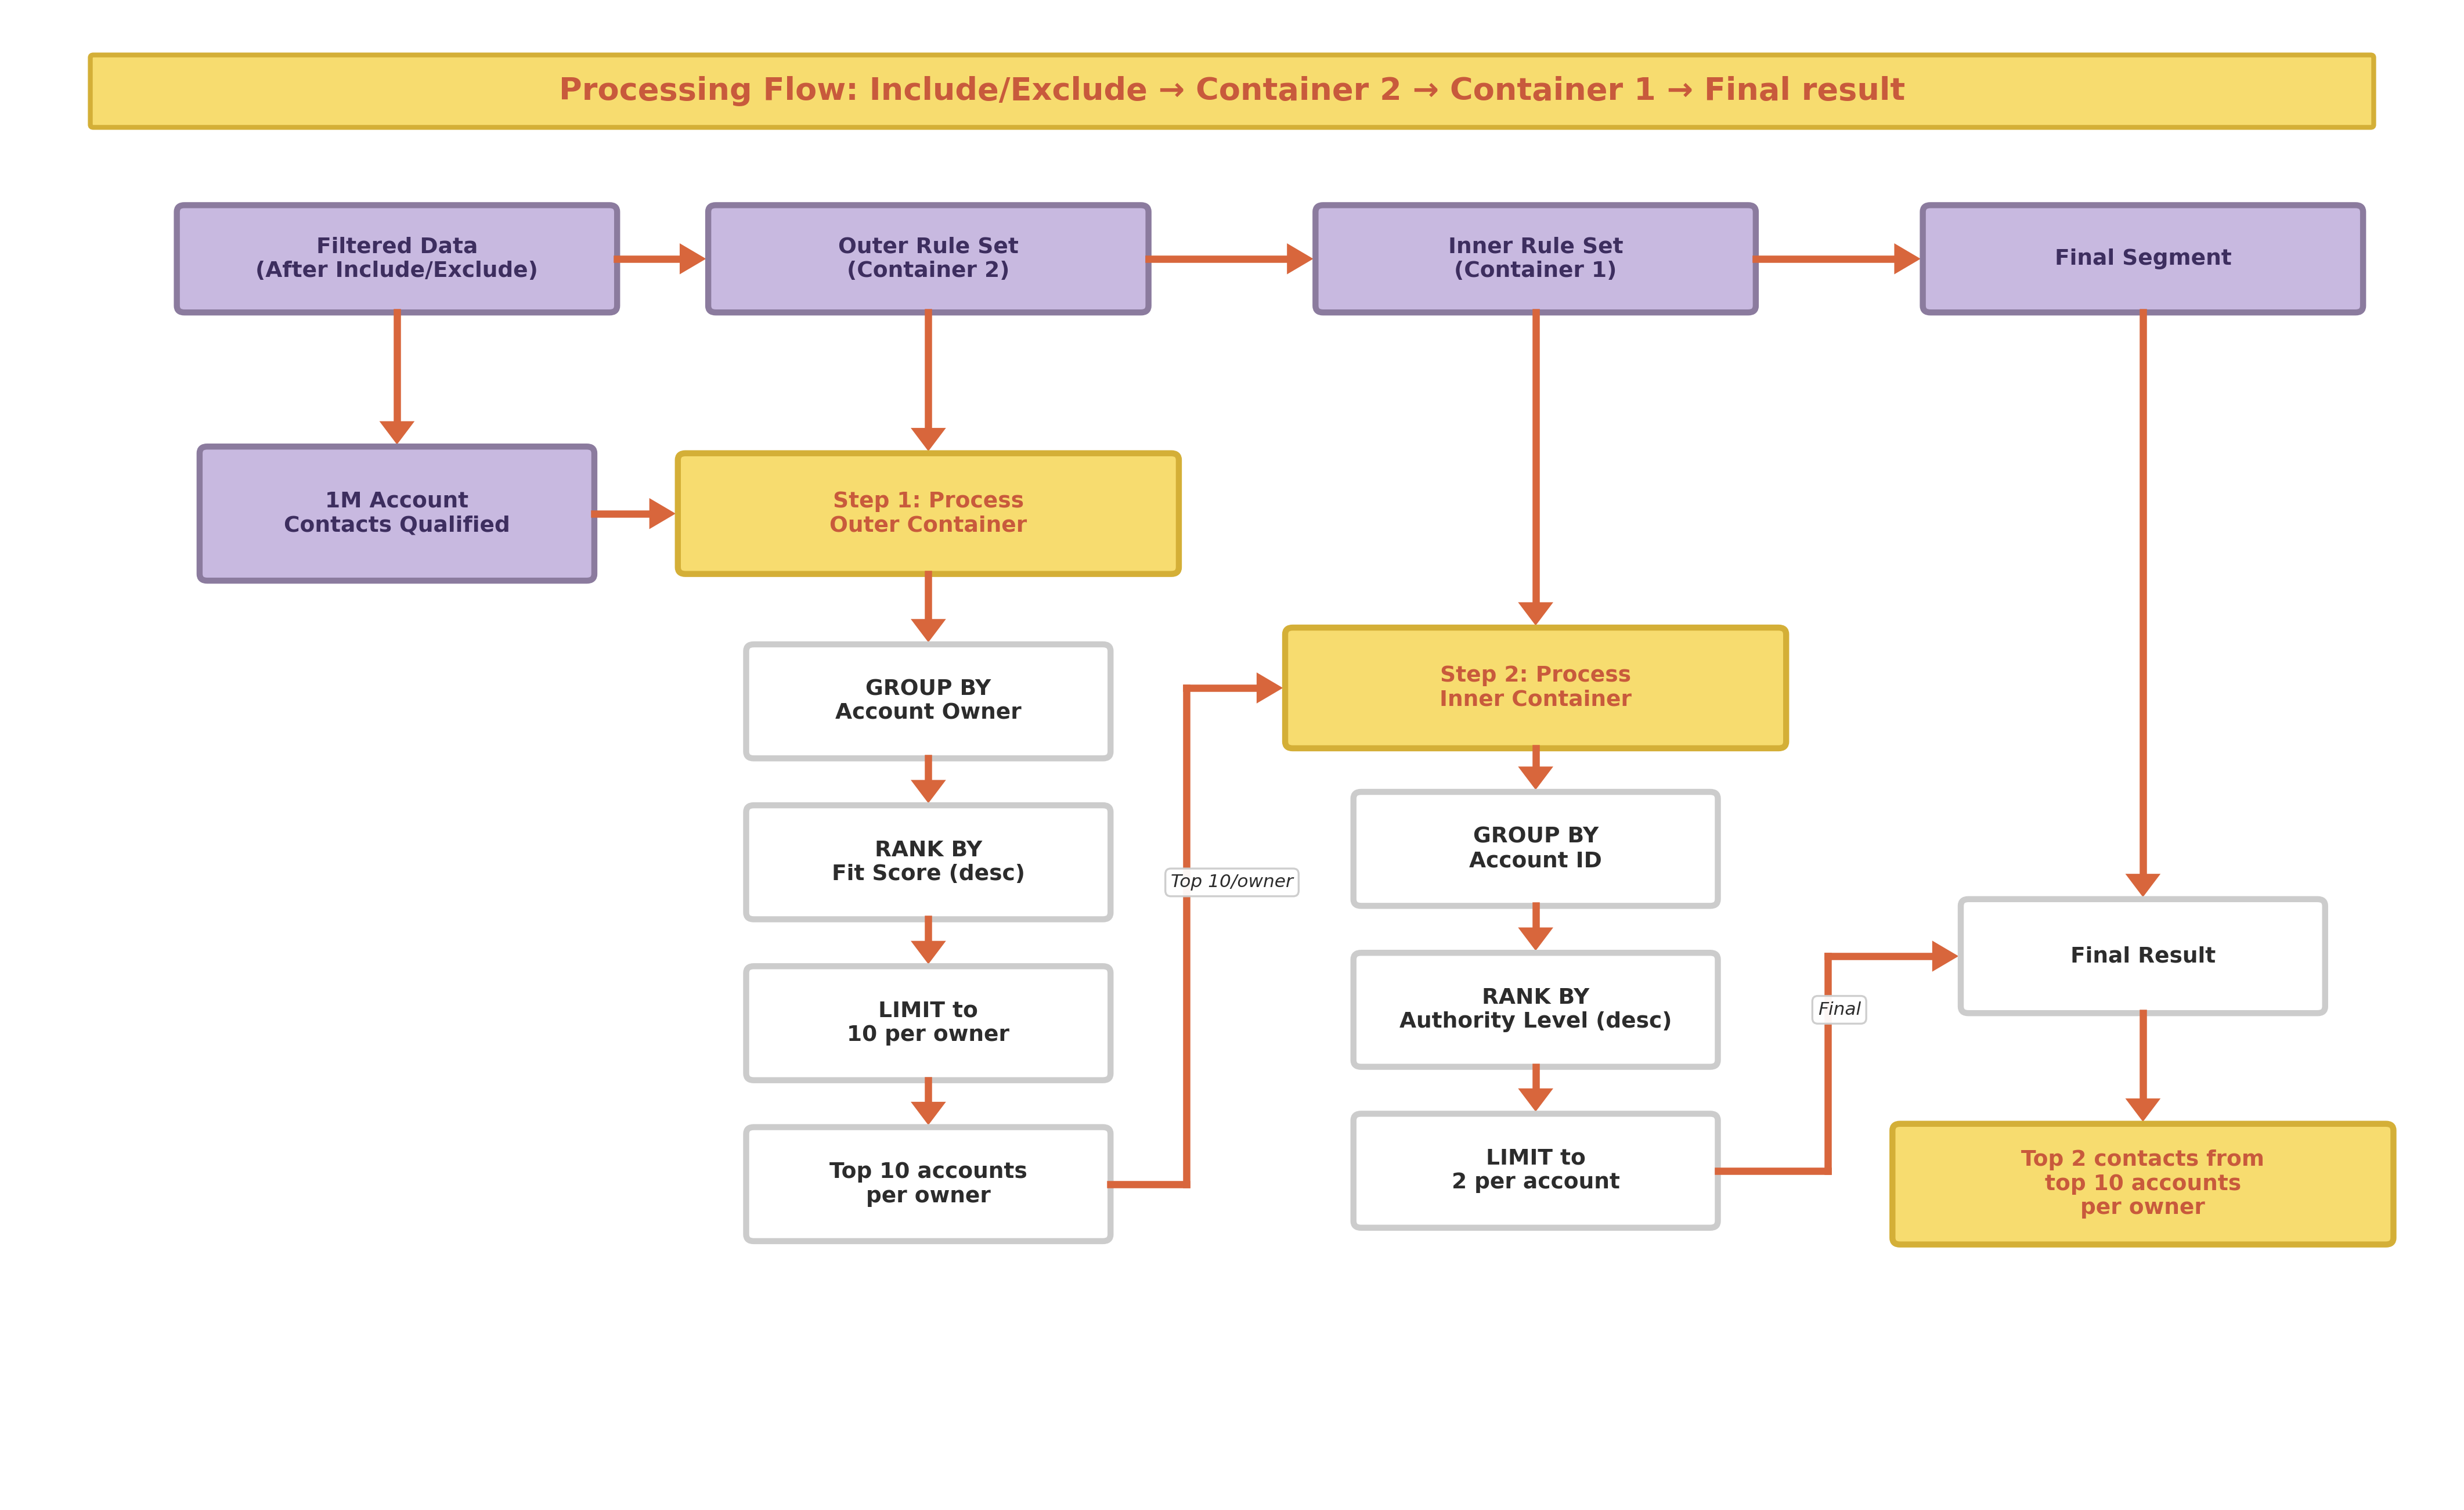
# Refresh a Data Graph
In Data 360, refreshing a data graph updates its underlying data with changes that occurred since the last refresh. A refresh takes the same amount of time as initial creation (15 minutes up to several hours, depending on data quantity). Data remains accessible while a refresh is in progress.
### Required Editions
User Permission Set
Needed
To refresh a data graph:
Permission set:
After a data graph is created, its refresh type can't be changed between streaming and scheduled.

Note During refresh, an exact empty string on a text join key is treated like a null value, preventing rows from incorrectly matching each other when upstream processes store missing values as empty strings on join key fields. Whitespace values are treated as real keys and continue to match. This applies to refresh joins only.
## Schedule a Refresh for a Data Graph
Set different refresh intervals to tailor refresh frequency to business requirements or data update rates. Shorter intervals increase processing and operational costs.
Track the schedule and status in the list view.
- Schedule:— Displays the refresh interval currently set.
- Last Refreshed On: —Displays the timestamp of the most recent refresh.
To schedule a refresh for a data graph:
1. In Data Graphs, next to the data graph that you want to schedule, select **Schedule**.
2. Select a refresh interval.
3. Save your work.
While the data graph is refreshing, it has an active processing status.
After a data graph is created, you can’t change the refresh type between streaming and scheduled. To use a different refresh type, create a new data graph with the required configuration.
## Manually Refresh a Data Graph
To manually refresh a data graph, select **Refresh Now**.
# Refresh for Data Extension Data Streams
For a data extension data stream with the refresh mode of upsert, you can choose to perform either an incremental or a full data refresh.
To perform a data refresh, navigate to the **Data Streams** tab, select your data stream, and then click **Refresh Now**. You have two refresh modes.
**Incremental Refresh**: For each incremental refresh, new information is upserted and the old information is retained. You can use incremental refresh for scenarios where a new formula field is created and needs to be repopulated in your data stream.
**Full Refresh**: For each full refresh, all your data from Marketing Cloud Engagement is synced, including formulas and deletions. Any records that are currently present in the Data 360 DLOs, but are unavailable in Marketing Cloud, are permanently deleted from the DLO. You can use a full refresh when you want to ensure the data deleted from Marketing Cloud is reflected in the Data 360 DLO.

Note
For a given Data Extension, you can perform a data refresh only once in 24 hours. Make sure that you are not modifying a datastream when a refresh is in progress. During the data refresh process, no new data will be ingested until the refresh completes.
# Regression Metrics
Metrics for regressions help evaluate the performance of a model that predicts numerical values for continuous data.
## Predicted vs Actual
The predicted vs actual scatter plot contrasts the predicted results of the model against the actual data results. The proximity of the points to the diagonal line indicates the accuracy of the model, with closer points representing higher accuracy.
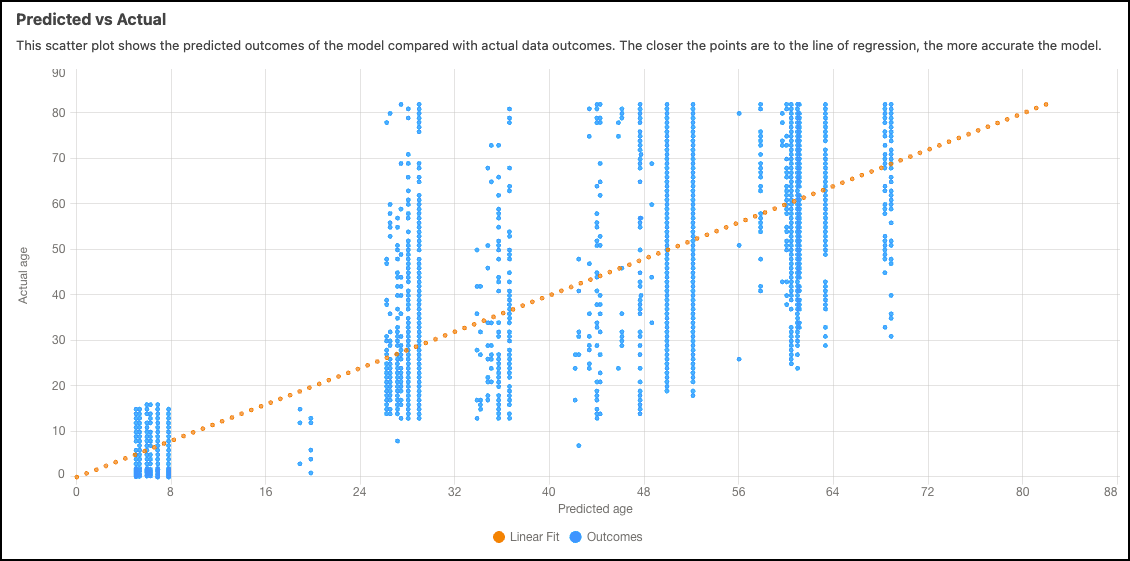
## Residuals
The scatter plot of residuals shows the variance between the actual and predicted values, known as residuals, in relation to predicted values. Ideally, the points should appear randomly scattered. On the y-axis, positive values indicate predictions that were too low, negative values indicate predictions that were too high, and values at zero indicate predictions that were exactly correct.
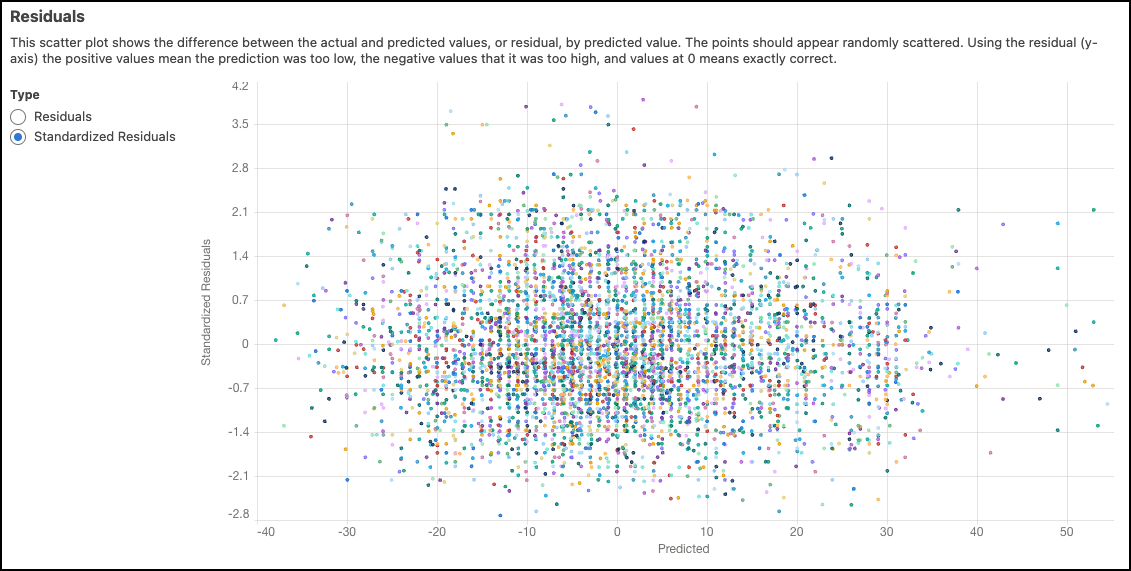
## 4-Fold Cross Validation Results
The 4-fold cross-validation approach mitigates sampling bias during the model validation process. In this method, the data is randomly divided into four separate partitions of equal size, and the model undergoes four test passes (folds). During each pass, three partitions serve as the training data, while the remaining one serves as the test data. By completing four test passes, each partition is used once as the validation data and three times as part of the training data, ensuring a comprehensive evaluation. Refer to the table of validation results to examine metrics corresponding to each fold of the data.
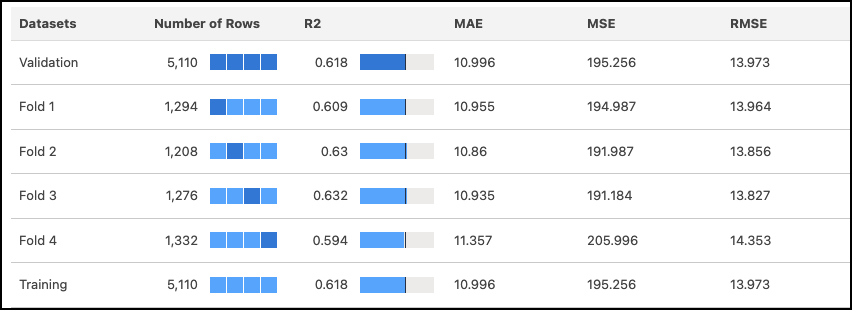
Metric
Description
Number of records
Total number of observations. The meaning of a value varies per column.
For the Training Data and Validation
Data columns, the numbers represent the total number of
observations in the entire data used in the creation of the model for training
and validation, respectively.
For the Fold # 1 through Fold #4
columns, this value represents how many observations fell in that fold
(approximately 25% of the entire data).
R2
R2 measures the model's ability to explain variation in the
outcome, which is an indicator of how predictive the model is.
Range:
0 means that the model is not able to explain any variability in the outcome
(random chance).
1 means that the model explains all of the variability (perfect model).
MAE
Mean Absolute Error. Measures the absolute difference between the actual value
and the prediction. All differences are weighted equally in this average, which
means that it is not as sensitive to outliers as MSE.
MSE
Mean Squared Error. Measures the average squared error of the model’s
predictions. MSE computes the square difference between the observed (actual)
outcome and the predicted values, and then averages them.
RMSE
Root Mean Squared Error. Represents the square root of MSE. RMSE measures the
difference between the values predicted by the model and the observed (actual)
values. You can think of this value as the “standard deviation of errors.”
# Related Attributes in Activation
Personalize Marketing Cloud Engagement communications using direct and related attributes from Data 360. Control the volume and variety of data that can be used in marketing segments.
This solution guide reviews three use cases for a fictional insurance company, Cumulus Bank and Financial Services.
## Use Case 1
Send an SMS message to customers who have achieved a new loyalty status in the past 7 days.
## Use Case 2
Push a reward message to Cumulus customer apps to notify customers who have earned Gold loyalty status.
## Use Case 3
Introduce new customers to their insurance policy and benefits using a series of emails.
## Before You Begin
To complete these use cases, review the features used, permissions required, and associated skills.
Products and Features
Data 360
Activation
Activation Target
Marketing Cloud Engagement
Content Builder
Journey Builder
MobileConnect
Permissions
Data 360 Architect or Data Cloud Activation Manager
permission setMarketing Cloud Engagement Content Creator
Requirements and Skills Needed
Understanding activation and activation targets in Data 360
Ability to use Guided Template Language (GTL) or Server-Side JavaScript (SSJS)
to parse JSON data
Access to configured SMS codes
Access to configured apps (iOS and/or Android)
## Related Content
To guide you through these use cases we suggest these resources.
 [_Salesforce Developer_: Guide Template Language Syntax](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/gtlSyntaxGuide.html)
 [_Salesforce Developer_: Guide Template Language Workbook](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/gtlWorkbook.html)
 [_Salesforce Developer_: Server-Side JavaScript](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/ssjs_serverSideJavaScript.html)
 [_Salesforce Help_: Add Related Profile Attributes to a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_activate_data_related_attributes.htm&type=5&language=en_US)
 [_Salesforce Developer_: Content Areas Within Template and Layout](https://developer.salesforce.com/docs/marketing/marketing-cloud/guide/gtlContentAreas.html)
 [_Salesforce Help_: Create a Marketing Cloud Engagement Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation_target.htm&language=en_US)
 [_Trailhead_: Marketing Cloud Engagement Programmatic Languages](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-programmatic-languages)
 [_Trailhead_: Segmentation in Data 360](https://trailhead.salesforce.com/en/content/learn/modules/customer-360-audiences-segmentation)

1. **[Associated Terms for Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_associated_terms.htm&release=264.0.0&type=5)**
Review the terms used in these examples.
2. **[Solution Workflow for Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_solution_workflow.htm&release=264.0.0&type=5)**
Review the solution workflow for the related attributes use cases.
3. **[Use Case 1: Loyalty Status SMS Notification](https://help.salesforce.com/s/articleView?id=data.c360_a_relatt_use_case_1.htm&release=264.0.0&type=5)**
Cumulus Bank and Financial Services want to send an SMS message to customers who have earned a new loyalty status.
4. **[Create the Audience Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_relatt_uc1_steps_in_cdp.htm&release=264.0.0&type=5)**
Create and activate an audience segment for a loyalty status SMS campaign.
5. **[Activate the Segment and Add Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_relatt_uc1_step2.htm&release=264.0.0&type=5)**
When your segment is complete, the next step is to activate it, add, and filter related attributes in Data 360.
6. **[Review the Data in Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_relatt_uc1_step3.htm&release=264.0.0&type=5)**
After the segment is activated, a data extension is added to the Marketing Cloud Engagement business unit that you identified in the activation.
7. **[Create an SMS Journey in Journey Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_relatt_uc1_step4.htm&release=264.0.0&type=5)**
With the data extension located and content reviewed, Cumulus can now build the SMS campaign.
8. **[Use Case 2: Loyalty Status App Push Notification](https://help.salesforce.com/s/articleView?id=data.c360_a_mobile_push_use_case.htm&release=264.0.0&type=5)**
Cumulus Bank and Financial Services wants to use MobilePush to send an app notification to customers who have reached Gold loyalty status, and they're eligible to redeem a $100 gift card from their favorite food delivery service.
9. **[Create the Audience Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_mobile_push_create_segment.htm&release=264.0.0&type=5)**
In Data 360 create an audience segment for a gold status notification campaign.
10. **[Activate the Segment and Add Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_mobile_push_activate_segment.htm&release=264.0.0&type=5)**
When your segment is complete, the next step is to activate it, add, and filter related attributes in Data 360.
11. **[Review Data in Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_mobile_push_review_data.htm&release=264.0.0&type=5)**
After the segment is activated, a data extension is added to the Marketing Cloud Engagement business unit that you identified in the activation.
12. **[Create a MobilePush Journey in Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_mobile_push_create_journey.htm&release=264.0.0&type=5)**
With the data extension located and content reviewed, Cumulus can now build the Push campaign.
13. **[Use Case 3: New Auto Policy Welcome Series](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_use_case_3.htm&release=264.0.0&type=5)**
Cumulus Bank and Financial Services wants to create a three part journey to welcome new auto policy holders that introduces them to their policy and benefits.
14. **[Create the Policy Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_create_policy.htm&release=264.0.0&type=5)**
Create an audience segment for the auto policy welcome journey.
15. **[Activate the Segment, Add, and Filter Related Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_activate_attributes.htm&release=264.0.0&type=5)**
When your segment is complete, the next step is to activate it and add related attributes. Because this campaign is specific to users with new auto policies within a specific date range, add filters to prevent other policies from being sent to Marketing Cloud.
16. **[Locate the Data Extension in Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_locate_data_extension.htm&release=264.0.0&type=5)**
After it’s activated, a data extension is added to the Marketing Cloud Engagement business unit identified in activation.
17. **[Compose the Email in Content Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_compose_email.htm&release=264.0.0&type=5)**
Let’s walk through the steps to create the first welcome email in this campaign.
18. **[Create a Welcome Series in Journey Builder](https://help.salesforce.com/s/articleView?id=data.c360_a_ra_welcome_series.htm&release=264.0.0&type=5)**
Now that the emails are complete, you can create the journey.
# Remove a Field from a Data 360 Page
A FlexiPage represents the metadata associated with a Lightning page. A Lightning page is a customizable screen made up of regions containing Lightning components. A Lightning page is created only for derived data model objects (DMO) that have unified objects such as UnifiedIndividual and UnifiedAccount. You can remove a field from the Data 360 page to remove field mappings.
### Required Editions
Available in: Lightning Experience
If you want to unmap a field from all DLOs that are mapped to the unified objects of a derived DMO, first remove the field from the Data 360 page.
1. In the Data 360, navigate to either the Data Explorer or the Profile Explorer tab.
- If you’re using the Data Explorer tab, select **Data Model Object** and a unified object, such as UnifiedIndividual.
- If you’re using the Profile Explorer tab, select a unified object and the attributes to use as filters.
2. Click the view link.
3. In the top right, click the gear icon, and select **Edit Page**.
4. In the Lightning App Builder, click the unified object component that you want to unmap. The available fields are listed in the right pane.
5. Under the field list, click **Select**.
6. Move the fields that you want to unmap to the left side and then save the page.
# Remove Data Lake Objects from Data Spaces
Before deleting a data lake object (DLO) from a data space, remove all the dependencies like mappings from the DLO.
### Required Editions
User Permissions
Needed
To remove DLOs from data spaces
Permission set:
1. In Data 360, go to the Data Spaces tab.
2. Select a data space from which you want to remove a DLO.
3. Search for the DLO and click its corresponding dropdown.
4. Select **Delete**.
# Remove Legacy Metadata from a Data 360 Sandbox
Data 360 sandboxes configured before August 2024 may contain legacy metadata. Use the cleanup process to remove legacy metadata from the sandbox.
### Required Editions
User Permission Set
Needed
To remove legacy metadata from a Data 360 sandbox:
Permission set:
1. In your sandbox org, select **Data Cloud Setup**.
2. On the Clean up and Reset page, click **Approve and Complete Setup** .
3. Review the list of metadata components scheduled for deletion. For a detailed list, click **Review Deletion Details**.
4. To complete the deletion process, click **I Approve Data Deletion**.
# Remove or Delete a Key Qualifier
To reduce clutter and avoid reaching your org's limit for key qualifiers, remove and delete unnecessary key qualifiers from the system. To delete a key qualifier, first remove it from all the data lake object (DLO) fields that it’s associated with and then delete it. You can also just remove a key qualifier from a DLO field but not delete it from the system. Removing a key qualifier from a DLO field can potentially affect the accuracy of calculated insights, segments, activations, and API queries.
### Required Editions

Note To remove key qualifiers from a companion org, remove them from the home org and wait at least 10 minutes for the companion org to sync with the home org.
User Permissions Needed
To remove and delete key qualifiers:
Permission set:
1. Identify the DLO fields associated with a key qualifier.
Before you remove or delete a key qualifier, remove it from its associated DLO fields. Identify all the DLO fields that share the key qualifier.
1. In Data Cloud, go to the Data Lake Objects tab.
2. Click the name of a DLO.
3. Click the dropdown next to any DLO field and select **View Key Qualifiers**.
4. In the Key Qualifier Details window, select the key qualifier that you want to delete (1) and note the DLO and DLO fields that are associated with it (2).
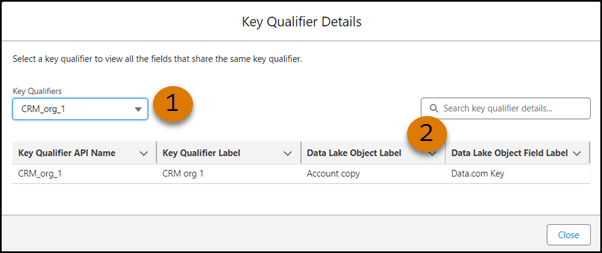
2. Remove the key qualifier from the DLO fields.
Before you can delete a key qualifier, remove it. You can also just remove it without deleting it.
1. On the Data Lake Objects tab, click the DLO that contains the field that you want to remove the key qualifier from.
2. Next to the DLO field that you want to remove the key qualifier from, click the dropdown, and select **Remove Key Qualifier**.
3. After you confirm the removal, the key qualifier is no longer associated with the DLO field.
If you’re only removing a key qualifier and not deleting it, you’re done.
3. Delete the key qualifier.
1. On the Data Lake Objects tab, click a DLO.
2. Click the dropdown next to any DLO field, and select **Add Key Qualifier**.
3. In the Add Key Qualifier window, select the key qualifier that you want to delete, click the dropdown next to it, and select **Delete**.
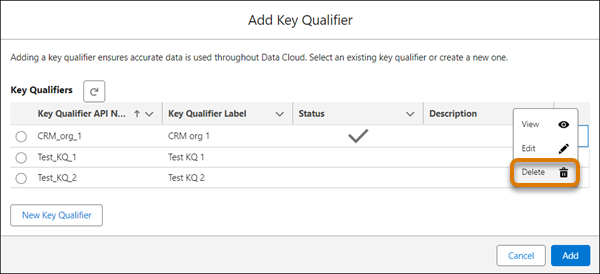
1. When prompted, confirm that you want to delete the key qualifier.
#### See Also
- [Configure a Key Qualifier Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_or_view_key_qualifier.htm&release=264.0.0&type=5 "After creating a data stream, add key qualifiers to your data lake object (DLO) fields to create fully qualified keys (FQK). Configure key qualifiers for all DLO fields that contain either a primary or foreign key. You can add up to 20 active key qualifiers. A key qualifier is active when it's used for a DLO field. Data 360 automatically adds and removes key qualifiers to and from data model object (DMO) fields. You can't edit these system fields.")
- _Salesforce Help_: Configure a Key Qualifier Field
# Replicate Data 360 Configurations Using Local Data Kits
Move Data 360 metadata and process definitions between data spaces within the same sandbox using the local data kit deployment method. Create a standard data kit in your default data space, and then use a change set to deploy it to other data spaces.
### Required Editions
User Permission Set
Needed
To deploy a standard data kit in the Data 360 sandbox:
Permission set:
Before you begin, make sure:
- You’re logged in to a sandbox.
- You’re working in the default data space.
## Create a Data Kit in Sandbox
1. In your sandbox org, select **Data Cloud Setup**.
2. Under Developer Tools, click **Data Kits**.
3. On the **Data Kits** tab, click **New**.
4. Select **Standard Data Kit** type.
5. Enter the data kit name and developer name.
6. Verify that the **Source Dataspace** is set to your default data space.
7. On the **Related** tab, in the **Data Kit Components** section, click **Add**.
8. Select the metadata types to include, such as data model objects (DMOs), calculated insights, or segments.
See [Data 360 Extensibility Readiness Matrix](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360a-api-isv-readiness-data.html).
9. Select the specific components and click **Add** to data kit.
10. Click **Save**.
## Deploy a Data Kit to Local Data Spaces
1. On the Data Kit Detail page, select the standard data kit.
2. Click **Local Data Kit Deploy**.
3. Select the target data space, org ID details, and select a connector type.
4. Click **Deploy**.
5. On the **Local Deployment History** tab, review the deployment log to verify the status of the deployment.
# Replicate Data 360 Sandboxes Using Cloning
Clone an existing parent sandbox to reuse Data 360 metadata and configurations, create testing environments faster, and streamline complex DevOps workflows. When you clone a sandbox with Data 360 provisioned, you automatically carry over the same Data 360 metadata and configurations to the cloned sandbox. This process saves setup time and avoids manual configuration.
### Required Editions

Example
Quickly create identical environments for testing, QA, or user-acceptance testing without manually recreating configurations. For example, you can clone a development sandbox called Dev\_Sbx\_1 that contains configured workflows, integrations, custom settings, and metadata. The result is a new sandbox environment with the same setup and configurations, which you can use to test or validate immediately in a consistent environment.
## When to Clone, Create, and Refresh a Sandbox
This table compares creating, cloning, and refreshing a sandbox. Use a new sandbox for development, testing, and training. Clone a sandbox to copy its data and metadata into another sandbox. Refresh an existing sandbox to update its contents.
| Feature | Create (New) | Clone (Copy) | Refresh (Update) |
| --- | --- | --- | --- |
| Source Material | Production | Existing sandbox | Production |
| Data 360 metadata | Blank Data 360 instance | Copies of data streams, data model objects (DMOs), relationships, and identity resolutions | Current production setup that overwrites existing sandbox configurations |
| Data kits | Install manually from production that uses a package. | Inherit data kits from the source sandbox. | Resync data kits from production, but override local changes. |
| Data streams | Recreate data streams from scratch. | Copy definitions, but reauthorize connections. | Update definitions, but reauthenticate connections. |
| Production that uses data | Excluded | Metadata only | Metadata from production (replaces all sandbox data) |
| Primary use case | Test a new Data 360 implementation strategy. | Create a parallel development environment for multiple team members. | Sync the test environment with the latest production schema or rules. |
## Best Practices for Cloning Data 360 Sandboxes
To use your cloned work immediately, follow these tips:
- Create a sandbox with your standard Data 360 architecture.
- When cloning, use names that reflect the lifecycle stage (for example, `D360_QA_Sprint22`) to track which configuration version you cloned.
- Keep your credentials ready to activate the data streams in the new clone. Cloning copies the mappings but excludes access credentials, such as Amazon S3 or Google passwords and keys.
## Considerations When Cloning a Data 360 Sandbox
Provision Data 360 in a cloned sandbox from an active parent sandbox that has a valid Data 360 setup. The cloning process copies only metadata and bypasses data replication.
- **[Clone a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_clone_a_data360_sandbox.htm&release=264.0.0&type=5)**
Create a Data 360 sandbox by cloning an existing configured sandbox to save time and maintain environment consistency. Cloning saves time by automatically copying data model objects, relationships, identity resolution rules, and data stream definitions from the source sandbox to the clone.
#### See Also
- [_Salesforce Help_: Clone a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_clone_a_data360_sandbox.htm&release=264.0.0&type=5 "Create a Data 360 sandbox by cloning an existing configured sandbox to save time and maintain environment consistency. Cloning saves time by automatically copying data model objects, relationships, identity resolution rules, and data stream definitions from the source sandbox to the clone.")
# Replicate Metadata Across Data Spaces Using Local Data Kit Deployment
Use a local data kit deployment to replicate Data Cloud metadata and process definitions across multiple data spaces within the same sandbox org. Packaging configurations into a local data kit reduces manual effort, ensures consistency, and accelerates time to value when your data space strategy requires standardized definitions across different spaces. Standardization is especially important for deployments across geographies or brands where processes are defined centrally.
### Required Editions
Permission Sets Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
Previously, replicating configurations such as calculated insights and segments required manual re-creation in each data space, which was time-consuming and prone to error. With local data kit deployment, Data 360 performs a pure upsert, automatically updating existing components or creating new ones with the appropriate data space prefix.
- Verify that you're working in a Data 360 sandbox environment.
- Log in to the default data space.
- Make sure that your metadata and process definitions are finalized in the default data space.

Note Local data kit deployment supports standard data kits only. To move changes from sandbox to production, use a DevOps data kit.
These high-level steps replicate metadata and promote it to production:
1. Create your data model objects (DMO) mappings, calculated insights, and segments in the default data space of your sandbox.
2. Package your finalized configurations into a standard local data kit.
3. Use the one-click deployment for each target data space within the sandbox.
4. Add the necessary filters to the data lake objects (DLO) mapped into each of the target data spaces.
5. Create a DevOps data kit for each data space to deploy the configurations to your production environment.
#### See Also
- [_Salesforce Help_: Replicate Data 360 Configurations Using Local Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_replicate_data360_configurations_using_local_data_kits.htm&language=en_US)
# Requesting Data Access and Export
Learn more about how to submit Data Access and Export requests in Data 360.
You can submit Data Access and Export requests for Individual profiles in Data 360. Submit all requests using the Consent API.
Data Access and Export requests triggers the export of all data stored within Data 360 for the specified Individual profiles. This export is published as a CSV file to your defined Amazon S3 bucket within 15 days.
#### See Also
- [_Salesforce Help_: Data Access and Export for Data 360](https://help.salesforce.com/s/articleView?id=xcloud.data_portability_c360_audiences.htm&type=5&language=en_US)
- [_Salesforce Developer_: Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm)
# Requesting Data Deletion or Right to Be Forgotten
Learn more about how to submit Data Deletion requests in Data 360.
You can submit Data Deletion requests of individual data profiles in Data 360. All requests must be submitted using the Consent API.
A Data Deletion request deletes the specified individual's record from the Individual data model object (DMO) and the individual's related records from the DMOs that are directly related to the Individual DMO through the individual's ID, such as Contact Point Address, Contact Point Email, and Contact Point Phone. The request also deletes the individual's records from the data lake objects (DLOs) mapped to these DMOs and from related calculated insights.

Warning A Data Deletion request removes only the records linked to the individual through the individual's ID. The request doesn't delete records from DMOs that aren't directly related to the Individual DMO through the individual's ID, or data stored in unrelated DMOs.
Data deletion, while not processed immediately, typically occurs within hours. This time can increase based on the number of records that need to be deleted.
Deletion requests are reprocessed after 30, 60, and 90 days to delete any added data and to verify full deletion.
You must submit data deletion requests in every connected system and Salesforce cloud.

Example
The example below shows the deletion behavior among many DLOs, wherein only specific ones are impacted by the deletion request. For instance, matching records from DLO 2 are deleted because it’s mapped directly to the Individual DMO, and matching records from DLO 4 and DLO 7 are deleted because they’re mapped to the Contact Point Address DMO. Matching records from the other DLOs aren’t deleted because they’re not mapped to either the Individual DMO or the Contact Point Address DMO. 
#### See Also
- [_Salesforce Developer_: Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm)
- [_Salesforce Help_: Customer 360 Data Model: Individual and Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_cloud_information_model_individual_and_contact_points.htm&release=264.0.0&type=5 "When using the Customer 360 Data Model, Data 360 prepares a list of Salesforce-published objects, fields, metadata, and relationships to ensure consistency across applications and business processes. Individual and contact point objects are important concepts for successful and complete data streams.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Data Deletion for Data 360](https://help.salesforce.com/s/articleView?id=xcloud.data_deletion_c360_audiences.htm&type=5&language=en_US)
- [_Salesforce Help_: Data Subject Rights Request](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights_request.htm&release=264.0.0&type=5 "Learn more about how to submit Data Subject Rights requests in Data 360.")
# Requesting Restriction of Processing
Learn more about how to submit Restriction of Processing requests in Data 360.
You can submit Restriction of Processing requests for Individual and Unified Individual profiles in Data 360. All requests must be submitted using the [Consent API](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm).
Restriction of Processing requests restrict all data processing for the specified Individual and Unified Individual profiles within 24 hours.

Note It can take up to 90 days to process your request. In the interim, some records submitted for deletion remain visible.
Carefully consider consumer rights and expectations when building segments based on objects other than Individual and Unified Individual.
Submit any Restriction of Processing requests in all connected systems and Salesforce clouds.
#### See Also
- [_Salesforce Help_: Consent Management for Data 360](https://help.salesforce.com/s/articleView?id=xcloud.consent_management_c360_audiences.htm&type=5&language=en_US)
- [_Salesforce Developer_: Use the Consent API with Data 360](https://developer.salesforce.com/docs/atlas.en-us.api_rest.meta/api_rest/resources_consent_cdp_params.htm)
# Required Field Mappings to Activate to B2C Commerce
When activating a segment to B2C Commerce, certain data field mappings are required for B2C Commerce and non-B2C Commerce data sources.
## B2C Commerce Data Source
When activating a B2C Commerce data source, the data fields from the Sales Order Customer data lake object (DLO) must be mapped to the Individual data model object (DMO) in Data Cloud. The field mappings are automatically deployed by the B2C Commerce Connector Order Bundle. All required DMO fields must have valid values.
| DLO NAME | DLO FIELD | DMO NAME | DMO FIELD |
| --- | --- | --- | --- |
| Sales Order Customer | customerId | Individual | CustomerId |
| Sales Order Customer | customerListId | Individual | CustomerListId |
| Sales Order Customer | customerNo | Individual | CustomerNo |
| Sales Order Customer | usId | Individual | UsId |
| Sales Order Customer | visitorID | Individual | IndividualId |
## Non-B2C Commerce Data Source
When activating a non-B2C Commerce data source (for example: Amazon S3), the data fields used to store the B2C Commerce fields in your DLO, must be mapped as custom fields to the Individual DMO in Data Cloud. All required DMO fields must have valid values.
DMO NAME
DMO FIELD
Individual
CustomerId
Individual
CustomerListId
Individual
CustomerNo
Individual
UsId
Individual
IndividualId
Individual
InternalOrganizationId
For Amazon S3, map SiteId using the Organizational Unit Identifier. Ingestion API isn’t supported for non-B2C Commerce activations.
# Requirements for External Activation Targets
Consider these requirements when creating an activation target to an external platform account in Data 360.
## Meta (Facebook) Requirements
- The Ad account must be associated with a Meta Business Manager account.
- A user must first accept Meta’s Custom Audience Terms of Service for the Business Manager account that owns or manages the Ad account. For information on Meta’s Terms of Service and how they’re applied, see the [Meta Marketing API](https://developers.facebook.com/docs/marketing-api/audiences/reference/custom-audience-terms-of-service/) Documentation.
- You can create a Meta activation target only if you’re the owner of the ad account connected to Meta Business Manager, or the owner has provided you with either admin or advertiser permissions. If your account is new or if you’ve recently linked to an existing account, it can take a few weeks before you’re able to create or share a customer list custom audience. If your new account is part of a tenured business account, you might be able to go through business verification. For more information, see [Meta Business Help Center](https://www.facebook.com/business/help/170456843145568).
## Google Requirements
- To use Google Customer Match, your account must be in compliance and have a good payment history.
## Google Ads Considerations
- Certain Customer Match features are available within a Google Ads account depending on the history and lifetime spend of that account. You can find more information on feature availability in [Google's Advertising Policies Help Documentation.](https://support.google.com/adspolicy/answer/6299717?hl=en)
- Some categories of products or services are deemed "sensitive" by Google, and consequently, Customer Match isn’t available for Ad Accounts within those categories. Comprehensive information about what Google considers a sensitive interest category under Personalized ads and Customer match policies can be found on the Google website, under the [Personalized advertising policies](https://support.google.com/adspolicy/answer/143465) article.
- Features available to advertisers depend on which requirements your account satisfies.
## Amazon Consent Considerations
- For Amazon Marketing Cloud (AMC) and Amazon DSP, include the Country Code attribute in the activation target. If the Country Code doesn’t include a selected attribute, it defaults to Unknown and decreases match rates. You can find more information in [Amazon's Help Documentation.](https://advertising.amazon.com/API/docs/en-us/guides/amazon-marketing-cloud/audiences/audience-management-service#country-code)
# Reserved Keywords in Formulas
Batch data transforms have reserved keywords that need special handling when manually writing formulas. Use double quotes “ when referencing fields that share a name with reserved keywords. To avoid cross-referencing your field names with this list, the best practice is to use double quotes around all field names.
Enclose fields that share a name with a reserved keyword in double quotes. For example, if your data has a field named **Month**, you can enter this expression:
```
case when "Month" = ‘New’ then ‘High’ else ‘Low’
```
## Reserved Keywords
ABS
ADD_MONTHS
AND
ARRAY
ARRAY_JOIN
ARRAY_CONTAINS
BETWEEN
CASE
CEIL
CHAR_LENGTH
COALESCE
CONCAT
CONTAINS
CURRENT_DATE
CURRENT_TIMESTAMP
DATE_ADD
DATEDIFF
DATE_FORMAT
DATE_SUB
DATE_TRUNC
DAY
DAYOFMONTH
DAYOFWEEK
DAYOFYEAR
DISTINCT
ELSE
END
ENDSWITH
EXP
FALSE
FROM
FLOOR
FORMAT_NUMBER
FROM_UNIXTIME
HOUR
IN
INTERVAL
IS
ISNTR
LAST_DAY
LIKE
LOG
LOWER
LTRIM
MINUTE
MONTH
MONTHS_BETWEEN
NEXT_DAY
NOW
NOT
NULL
NULLIF
OR
POWER
QUARTER
REPLACE
ROUND
RTRIM
SECOND
SIZE
SPLIT
SQRT
STRING
SUBSTR
SUBSTRING
STARTSWITH
THEN
TITLE
TO
TO_DATE
TO_TIMESTAMP
TO_UNIX_TIMESTAMP
TRIM
TRUE
TRUNC
TRUNCNUMBER
UPPER
WHEN
WEEK
WEEKOFYEAR
YEAR
## Additional Keywords for Multiple Row Formulas
These keywords are reserved in formulas with the **Multiple row formula** turned on. Use double quotes `"` when referencing fields that have any of these names.
- `CURRENT`
- `DENSE_RANK`
- `FIRST_VALUE`
- `LAG`
- `LAST_VALUE`
- `LEAD`
- `RANK`
- `ROW_NUMBER`
- `SUM`
# Resolve Connection Errors in Data Cloud One Sandbox Orgs
Establish a Data Cloud One connection from a home org sandbox to a companion org sandbox using the same steps as with production orgs. The connection succeeds when there’s no metadata drift between the orgs. If metadata drift occurs, delete the specified drifted entities in the error log in the companion sandbox to establish the connection. Manual cleanup of all Data 360 metadata isn’t required.
### Required Editions
Metadata drift can occur when:
- Sandboxes are created or refreshed at different times.
- The companion sandbox inherits metadata that the home sandbox doesn't recognize.
User Permissions Needed
Home org sandbox
To set up a Data Cloud One connection
Data Cloud Architect
Companion org sandbox
To view and delete drifted objects or configurations
Data Cloud One User
1. To resolve metadata drift, in the companion sandbox org, from Setup, enter Data Cloud in the Quick Find box, and then select **Data Cloud**.
2. In the **Connections** section, locate the companion connection displaying the error status, and click the error icon to download the error log.
3. Review the list of entities that caused the metadata drift.
4. Open the **Data Cloud One** app from the **App Launcher**.
5. For each entity listed in the error log, navigate to the corresponding section, such as Calculated Insights or Segments, and delete the entity. Delete objects or configurations without dependencies first, and then delete their parent entities.

Note
You must have access to the Data Cloud One app in the companion sandbox org to delete the entities.
After you delete all listed entities in the error log, the next automated sync cycle detects the cleanup and establishes the connection. To verify, navigate to the companion connection details section in the companion sandbox org to confirm that the connection status shows success.
#### See Also
- [_Salesforce Help_: Considerations for Data Cloud One in a Sandbox Org](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_sandboxes.htm&language=en_US)
# Restrict Access to Activation Targets for Specific Users
Use permission sets to make sure users only have access to specific activation target data. Since Marketing Managers, Marketing Specialists and Data Aware Specialists, can view all activation targets by default, use permission sets to manage their access. To manage access, clone an existing permission set and share access to specific activation targets with users assigned to that permission set only. For example, restrict access to specific activation targets for users in specific departments or geographies.
1. In Salesforce Setup, in the Quick Find box, enter Permission Sets.
2. To view the permission set you want to clone, select it.
3. Click **Clone**, make desired changes, and click **Save**.

Tip Name your cloned permission set so you can easily distinguish between the different permission sets.
4. Click **Object Settings**, select the **Activation Targets** object, and click **Edit**.
5. Deselect **View All Records**(1) and **Modify All Records**(2), and click **Save**(3).
6. In the Quick Find box, enter Sharing Settings.
7. In the Manage sharing settings for dropdown, select **Activation Targets**.
8. Under Activation Targets Sharing Rules, click **New**.
9. Name the rule, specify who to share the rule with, which records to share, the access level, and click **Save**.

Tip Use roles or groups to restrict activation target access to specific users.
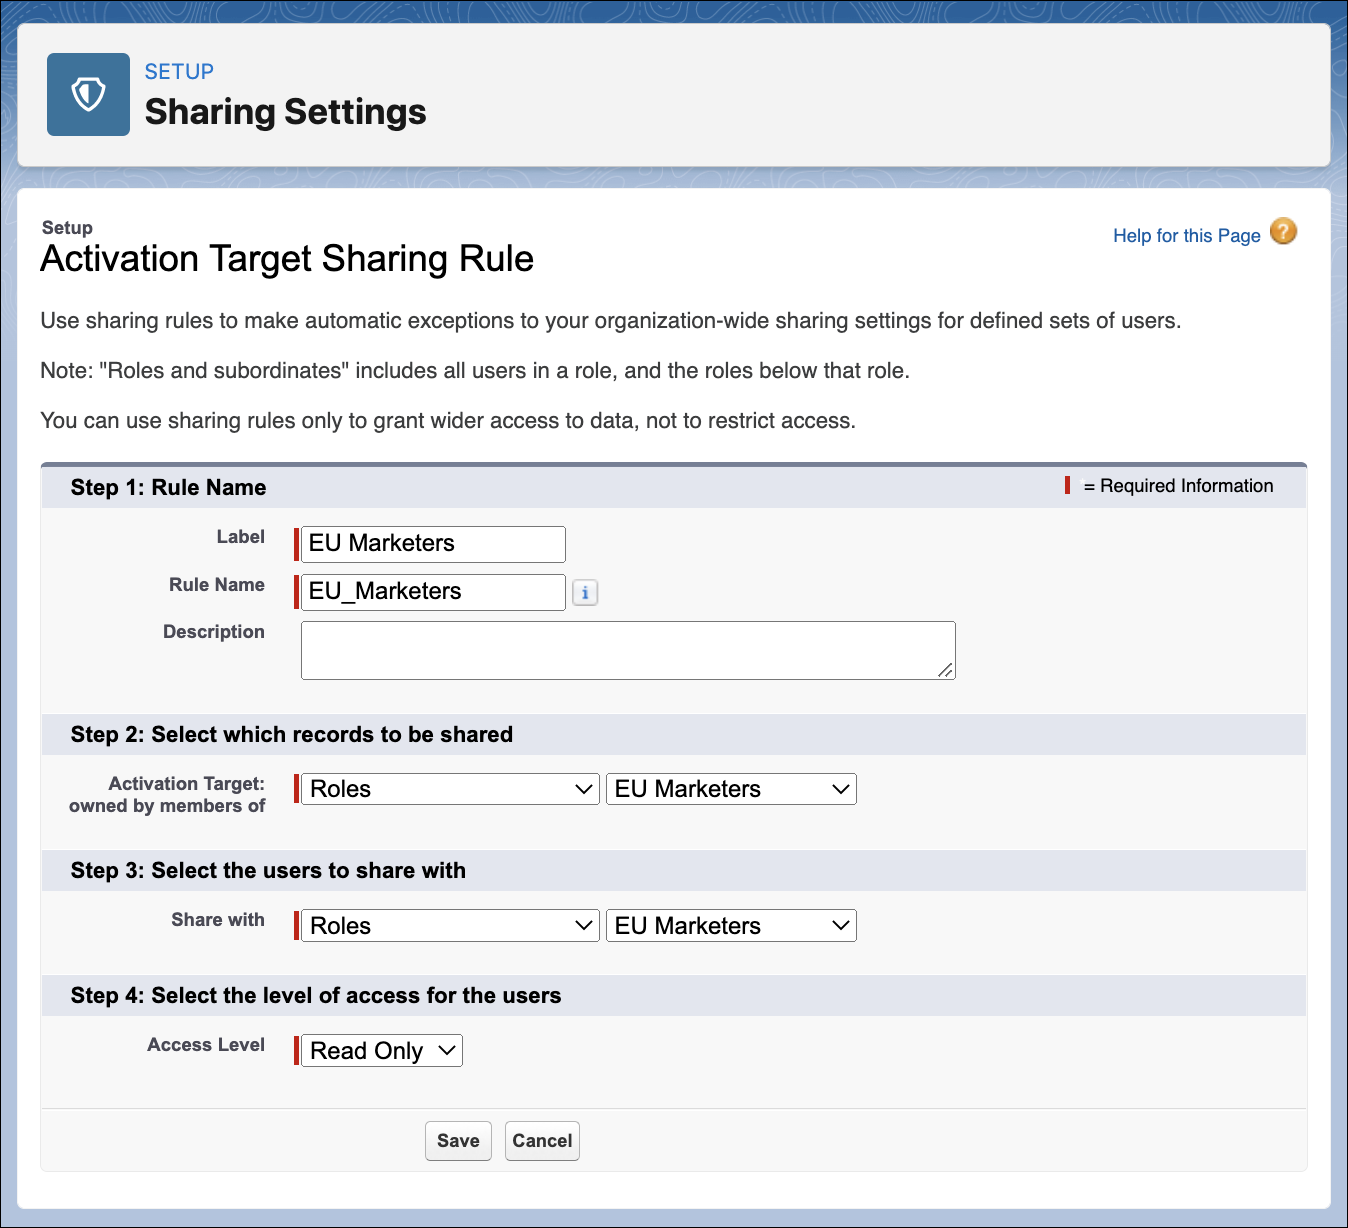
Users assigned to your new permission set can only see and create activations for specific activation targets in Data 360.
#### See Also
- [_Salesforce Help_: Business Unit Aware Integration: Marketing Cloud and Data 360 (PDF)](https://resources.docs.salesforce.com/242/latest/en-us/sfdc/pdf/cdp_bu_aware_guide.pdf)
# Retrieval Response with Enriched Search Index
Enriched indexing enhances retrieval response by matching a question to a passage with the best possible answer in your knowledge base. While Data 360 hybrid search combines the strengths of sematically aware vector search with the precision and speed of keyword search, enriched indexing closes the gap further by finding the chunks closest to the users' question.
## Enriched Indexing and Retrieval Augmented Generation (RAG)
Enriched indexing closes the gap in two ways. First, it generates questions based on the original plain chunk – a question chunk–so vector search finds a near-perfect alternate question for the user question. Second, it extracts a rich metadata chunk for each original plain chunk — a title, summary, keywords, named entities, and topic categories. Because Data 360 embeds the metadata chunk as a vector, it improves both vector and keyword search scores. The distilled, concept-rich text gives vector search a better semantic match, and the explicit keywords help keyword matching. Both the derived chunks point back to the original plain chunk as the source at time of retrieval.
If a search retrieves a plain chunk more than once, the retrieval process retains only one instance of the plain chunk. This duplication occurs when multiple enriched chunks point back to the same plain chunk as the source chunk.
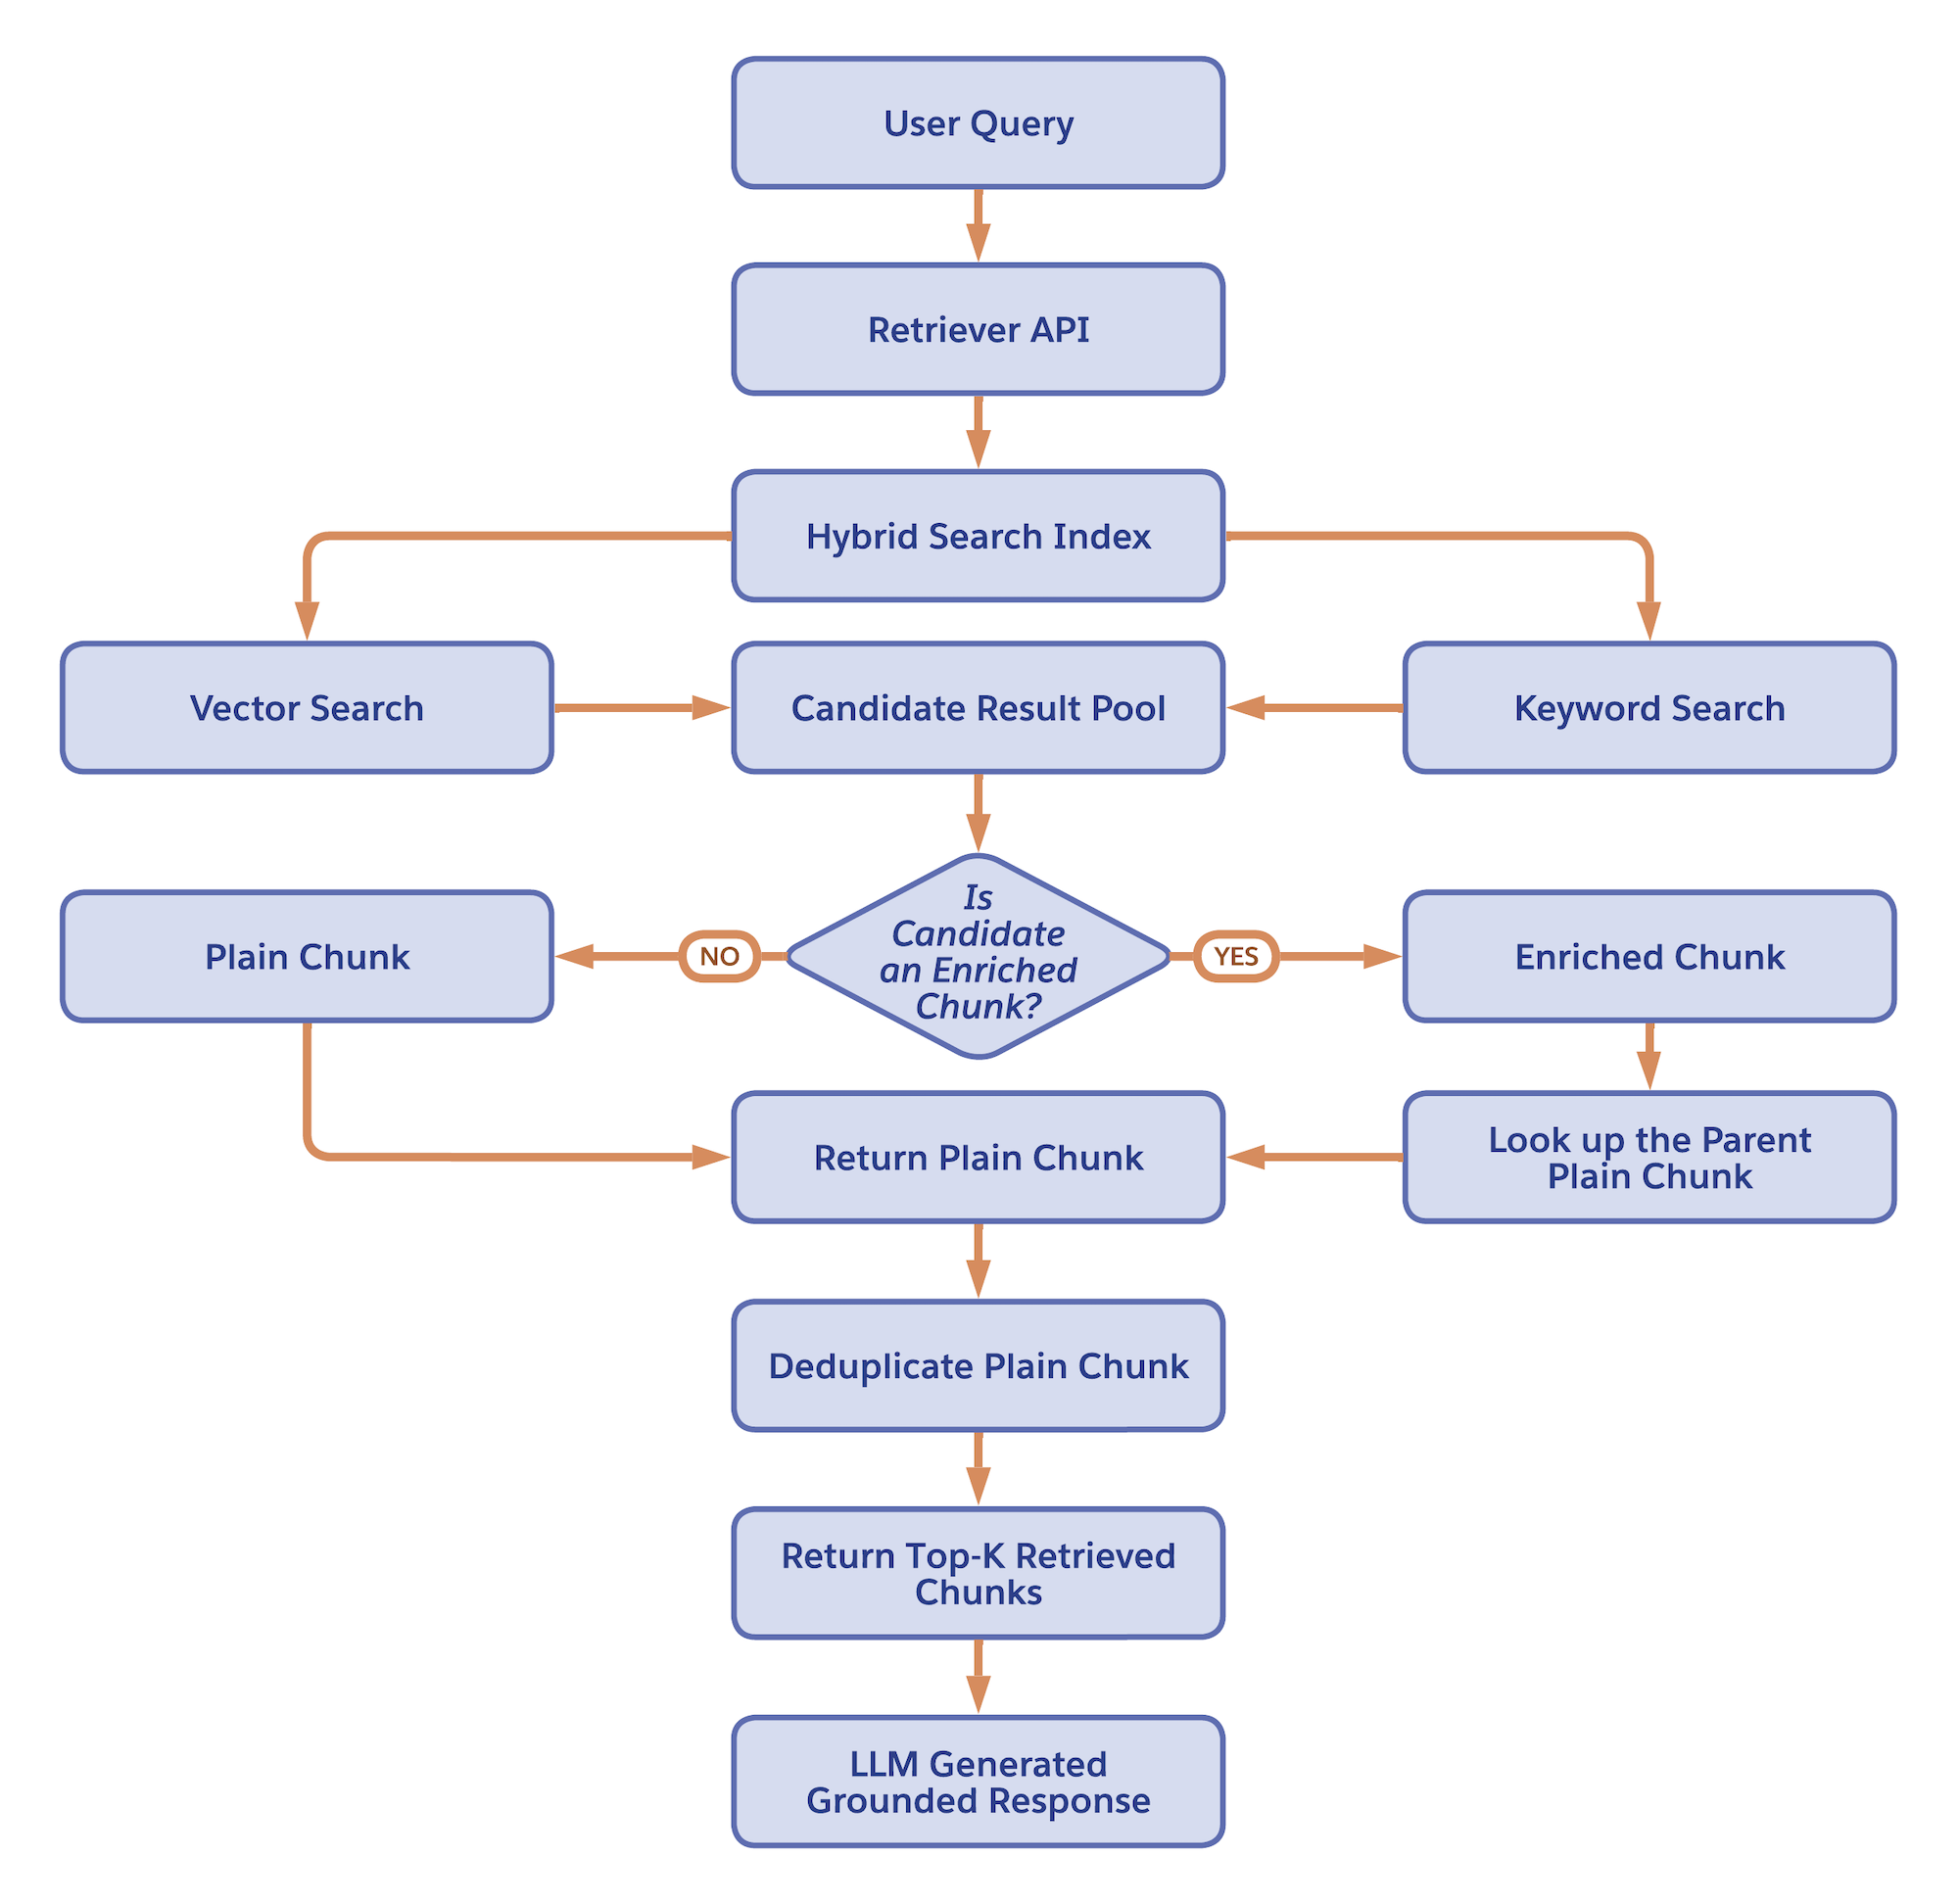

Example Let's consider a user query: “How do I reset my password?”
**The Response**: Your knowledge base includes an article with the right response. The article has a section written as a procedure, “Navigate to the recovery page and enter your email address.”
**The Gap**: The passage written as a procedure has a different meaning than the question. Data 360 ingests and indexes the knowledge article. During the retrieval process, this chunk can score much lower than expected because of this gap. As a result, the retrieval sometimes excludes this passage.
When you turn on enriched indexing using Large Language Models (LLMs), Data 360 creates a metadata chunk and a question chunk for the original plain chunk that includes this procedure content.
The metadata chunk includes rich metadata about the plain chunk, such as:
**Title:** _"Password recovery"_
**Summary:** _"Steps to reset login credentials via the recovery page."_
**Keywords:** _recovery, credentials, reset link, email_
**Entities:** _recovery page, registered email (named things in the passage)_
**Topics:** _account management, authentication_
The Questions chunk includes natural language questions that the plain chunk answers such as:
“How do I reset my password?"
"What do I do if I forget my login?"
"How long is a password reset link valid?"
"Where do I go to recover account access?"
All three chunks are part of the same index. So, when you search for a response any chunk type can match. In this example, the original query matches the question chunk. Data 360 search index returns the original plain chunk, the actual document text and not the derived enriched chunks. The original plain chunk that contains the right answers scores higher than other matches.
# Retrieve Data
Use a retriever to search and return relevant data from a search index. Create and customize retrievers in AI Models (formerly Einstein Studio) for Retrieval Augmented Generation (RAG) in Data 360. Retrievers augment prompt templates by providing relevant, specialized grounding information for prompts.
### Required Editions
## Data Preparation
Data preparation for retrieval from a search index involves loading, chunking, vectorizing, and storing content in a search-optimized way. Data 360 uses a vector data store for unstructured data, such as documents and conversation histories. A search index stores chunked and vectorized data that can be searched and retrieved from other applications. You can create and manage search indexes in Data 360. They’re defined in a data space and associated with a data model object (DMO).
With advanced document processing and indexing capabilities in Data 360, retrievers can retrieve and ground agent responses by processing both text and images. Turn on image processing for the unstructured data model object search indexes to process documents with images and other visuals, such as tables and flow charts. For more information on advanced setup for search indexes, see [Use Search for AI, Automation, and Analytics](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&type=5&language=en_US).
## Search and Retriever Configuration
Search indexes are often designed for general usage, such as indexing an entire knowledge base. You use retrievers to conduct specialized searches on search indexes and provide relevant results to agents, prompt templates, flows, and other features. Individual retrievers for search indexes apply the multi-purpose search index to a particular use case. For example, retrievers can return content that’s filtered based on a category of articles, the most recent information (such as the last 90 days), or geographical region.
You build retrievers in AI Models and then activate it to make it available to Prompt Builder users. In Prompt Builder, you ground a prompt template with knowledge by inserting and configuring a retriever. At run time, the retriever provides the LLM with accurate, current, and pertinent information to improve the relevance, accuracy, and value of LLM responses.
Retrievers adhere to the data governance policies set up for your data. Row-level access checks make sure that users have access to the data and knowledge returned by the retriever.
## Retrievers in Data Cloud One Configurations
When you create a retriever in a Data 360 home org, you can view it in the companion org and use it within Prompt Builder and Flow. You can also create and manage retrievers locally in a companion org. For more information see, [Retriever Support in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_data_cloud_one.htm&type=5&language=en_US) and [Data Cloud One Companion Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connections.htm&type=5&language=en_US).
## Individual Retrievers
Use individual retrievers to retrieve data from from a search index. To create an individual retriever in AI Models, you select its search index, define filters, and specify what information it returns. Filters narrow the search focus to more relevant data. The search index defines the fields that you can use for filtering. You also configure the data returned to the prompt, including the fields of data to return and the number of results. Each time you edit and save an individual retriever, another version is created in AI Models. Only one version of a retriever can be active.
Data 360 no longer creates default Retrievers automatically when you create a search index. Previously, when you created a search index in Data 360, a default retriever was created automatically. You can use existing default retrievers in apps, such as Prompt Builder or flow.
## Custom SQL Retrievers
Define, validate, and create retrievers with SQL queries directly in the retriever user interface (UI) without switching between the Query Editor, Apex, and Prompt Builder. Use parameterized queries to build reusable retrievers. Developers get a dedicated UI experience to programmatically build retrievers before deploying them in agents. You can also query other Data 360 objects such as data model objects (DMO), data lake objects (DLO), and calculated insights in the Custom SQL retriever UI.
## Ensemble Retrievers
An ensemble retriever is a collection of individual retrievers. When you run an ensemble retriever, it executes the individual retrievers, combines their results into a single list, reranks the list according to relevance to the search request, and returns just the most relevant information to apps.
Considerations for ensemble retrievers:
- Ensemble retrievers don't support retrievers of type Code.
- Individual retrievers with dynamic filters can’t be part of an ensemble retriever.
- In the Retriever Playground, test and validate pre-filter conditions for individual retrievers only when you configure them separately. You can't edit or test individual retrievers directly within an ensemble retriever.
- Ensemble retrievers with custom SQL retrievers can’t be tested in the playground.
## Dynamic Retrievers
Dynamic retrievers use placeholders that accept at run time values from prompt templates. A dynamic retriever has a placeholder for a value specified at runtime based on the needs of the prompt template.
- **[Get Trusted AI Responses with Retriever Citations](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_citations_retriever.htm&release=264.0.0&type=5)**
Citations link AI-generated responses to the source content relevant to each response. Citations allow users to compare the LLM response with the source data to verify the validity of the response and identify any potential inaccuracies or hallucinations. Enable citations in AI Models (formerly Einstein Studio) at the individual retriever level to give access to citations to solution components that call the retriever, such as a prompt template.
- **[Manage Retrievers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_version.htm&release=264.0.0&type=5)**
Create and customize retrievers for Retrieval Augmented Generation (RAG) in Data 360. To see the list of retrievers, navigate to the Retrievers tab in AI Models (formerly Einstein Studio). To learn about a retriever, select View Details from the dropdown menu. Each time you edit a custom retriever and save the changes, a new version is created. You can create multiple versions, but you can have only one version active at a time.
- **[Customize, Test, and Validate Retrievers with Retriever Playground](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test.htm&release=264.0.0&type=5)**
Fine-tune and validate retrieval logic for retrieval-augmented generation (RAG) systems by using retriever playground, reducing deployment risks, and verifying accurate AI outputs. Use AI Models (formerly Einstein Studio) retriever playground to configure pre-filters, select test data, and adjust result parameters to customize retrieval logic for domain-specific use cases, such as retrieving complaince documents or knowledge articles.
- **[Retriever Filters Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_retriever_filter_reference.htm&release=264.0.0&type=5)**
Configure filter conditions for retrieval accuracy when you create or test retrievers in AI Models (formerly Einstein Studio). Use filter conditions to filter records retrieved for search queries. You can configure up to ten filter conditions for an individual retriever.
- **[Retriever Support in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_data_cloud_one.htm&release=264.0.0&type=5)**
Learn about retriever capabilities and limitations when you work with Data Cloud One home and companion orgs.
#### See Also
- [_Salesforce Help_: Retrieval Augmented Generation (RAG)](https://help.salesforce.com/s/articleView?id=ai.generative_ai_rag.htm&type=5&language=en_US)
- [_Salesforce Help_:Ground with Knowledge Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&language=en_US)
- [_Salesforce Help_: Search for AI, Automation, and Analytics](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&type=5&language=en_US)
- [_Salesforce Help_: Retriever Support in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_data_cloud_one.htm&type=5&language=en_US)
- [_Trailhead_: Retrieval Augmented Generation: Quick Look](https://trailhead.salesforce.com/content/learn/modules/retrieval-augmented-generation-quick-look)
- [_Rag Best Practices White Paper_: Agentforce and RAG: Best Practices for Better Agents](https://view.salesforce.com/viewer/da54a79f51b5c2aa4002845258559687#1)
- [_Salesforce Developer:_ Salesforce Data 360 Connect REST API: Retrievers Reference](https://developer.salesforce.com/docs/data/connectapi/references/spec#tag/Machine-Learning)
# Retriever Filters Reference
Configure filter conditions for retrieval accuracy when you create or test retrievers in AI Models (formerly Einstein Studio). Use filter conditions to filter records retrieved for search queries. You can configure up to ten filter conditions for an individual retriever.
## Supported Operators in Filter Conditions
| Operator | Example \[Field\]{Operator}\[Value\] |
| --- | --- |
| Equal To | Make **Equal To** Honda |
| Not Equal To | Trim **Not Equal To** High-End |
| Greater Than | ModelYear **Greater Than** 2000 |
| Less Than | ModelYear **Less Than** 2025 |
| Like | ModelName **Like** Civic |

Note
When you define filter conditions for retrievers with the Like operator, don’t add a trailing % to match values. A trailing % is appended internally to match values. In other applications like Prompt Builder or Flow Builder, you have to append a trailing% to include partial matches. For example, a retriever with a dynamic filter condition that uses the Like operator requires the trailing % in a prompt template.
Review these guidelines for supported filter field datatypes.
- Text: Maximum 255 character and 254 characters with the Like operator.
- Boolean: Supports True or False values.
- Number: Maximum 255 Characters and 254 with the Like operator.
- Date: Enter date in the format, Dec 31, 2024.
- ArrayOfTexts: Not supported
Field values can't include single quotes.
## Filter Condition Logic
Combine filter conditions with conditional logic to filter records retrieved.
Use Filter When
Conditional Logic
Example
All Conditions Are Met
AND
ModelType Equal To Sedan AND ModelYear Greater Than 2000
Any Condition Is Met
OR
ModelType Equal To Sedan OR ModelType Equal To Hatchback
Custom Condition Is Met
The condition is built from the numbered filter conditions by using a custom
logic.
Custom conditions include all filter conditions defined with a valid
format. For example, when there are 3 filter conditions, a valid format can be 1
AND (2 OR 3) or (1 OR 2) AND (NOT 3).
ModelName Equal To Civic AND (ModelType Equal To Sedan OR
ModelType Equal To Hatchback)
(Model Equal To Civic OR Model
Equal To Odyssey) AND (NOT Trim Equal To A-Spec)
## Dynamic Filter Conditions
Dynamic filter conditions accept values at run time. Configure up to ten dynamic filter conditions and provide values at run time when you test a retriever in the retriever playground or in prompt templates.
You can enter a placeholder value, or AI Models includes a variable by default. For example, `Itemname Equal To {!$ItemName}`. Review these guidelines for valid placeholder values.
- Contain only alphanumeric characters and non-consecutive underscores
- Begin with a letter
- Don't include spaces
- Don't end with an underscore
- Have a maximum character length of 40
- Are unique across all pre-filter fields
# Retriever Metrics and Results
Review retriever metrics and the retrieved data chunks to understand the results of your test. Modify the retriever configuration to try different configurations and expected source data to get an optimal response. Save your configuration as a new version of the retriever.
## Retriever Metrics
You can test a retriever in a basic mode and an advanced mode. When you test a retriever in the advanced mode, the retriever playground generates a context recall score and a context precision score based on a reference answer. Testing retrievers in the advanced mode consumes flex credits.
**Retriever Playground in Basic Test Mode**
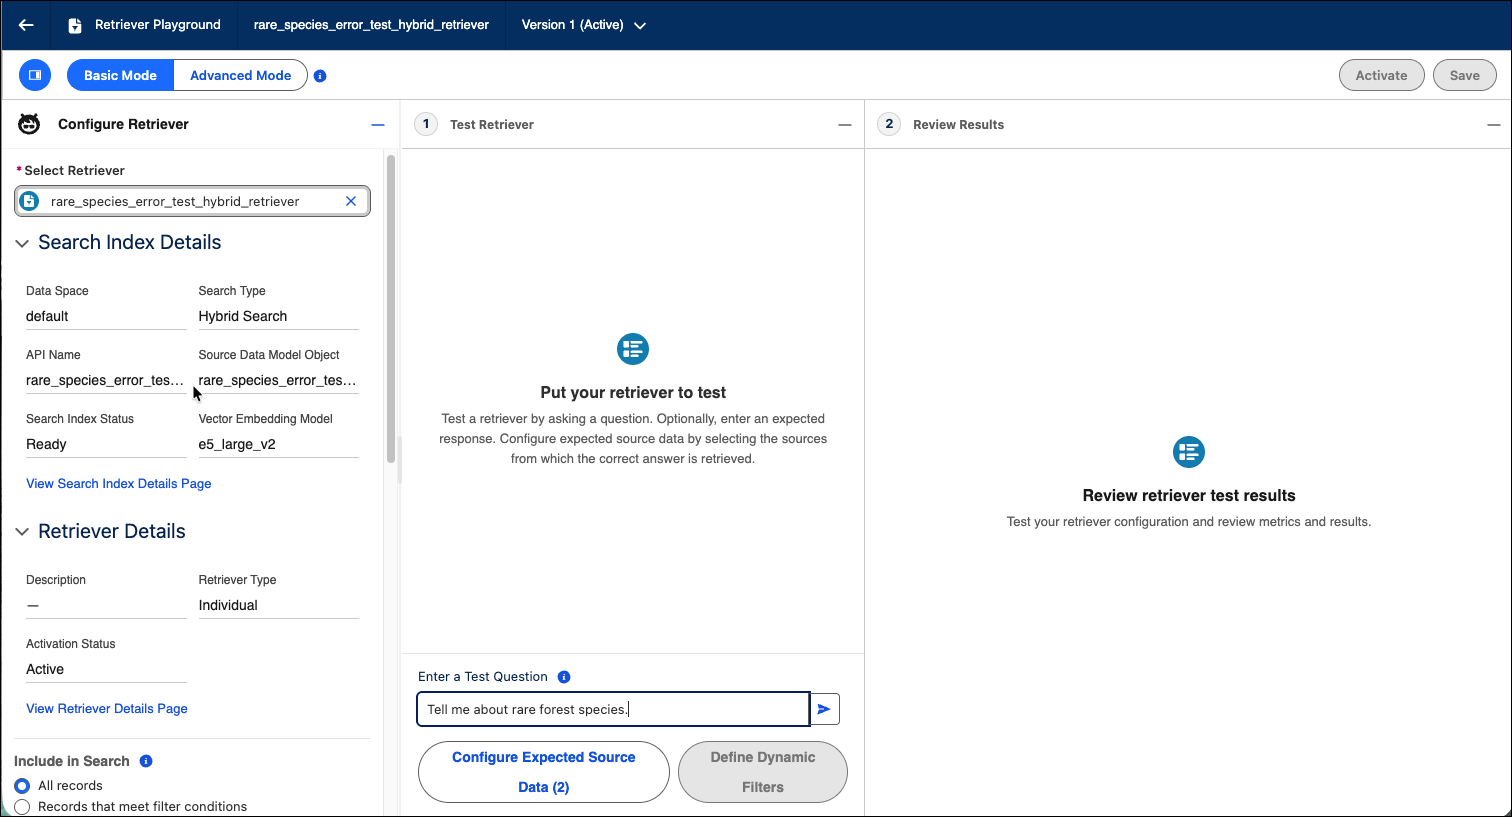
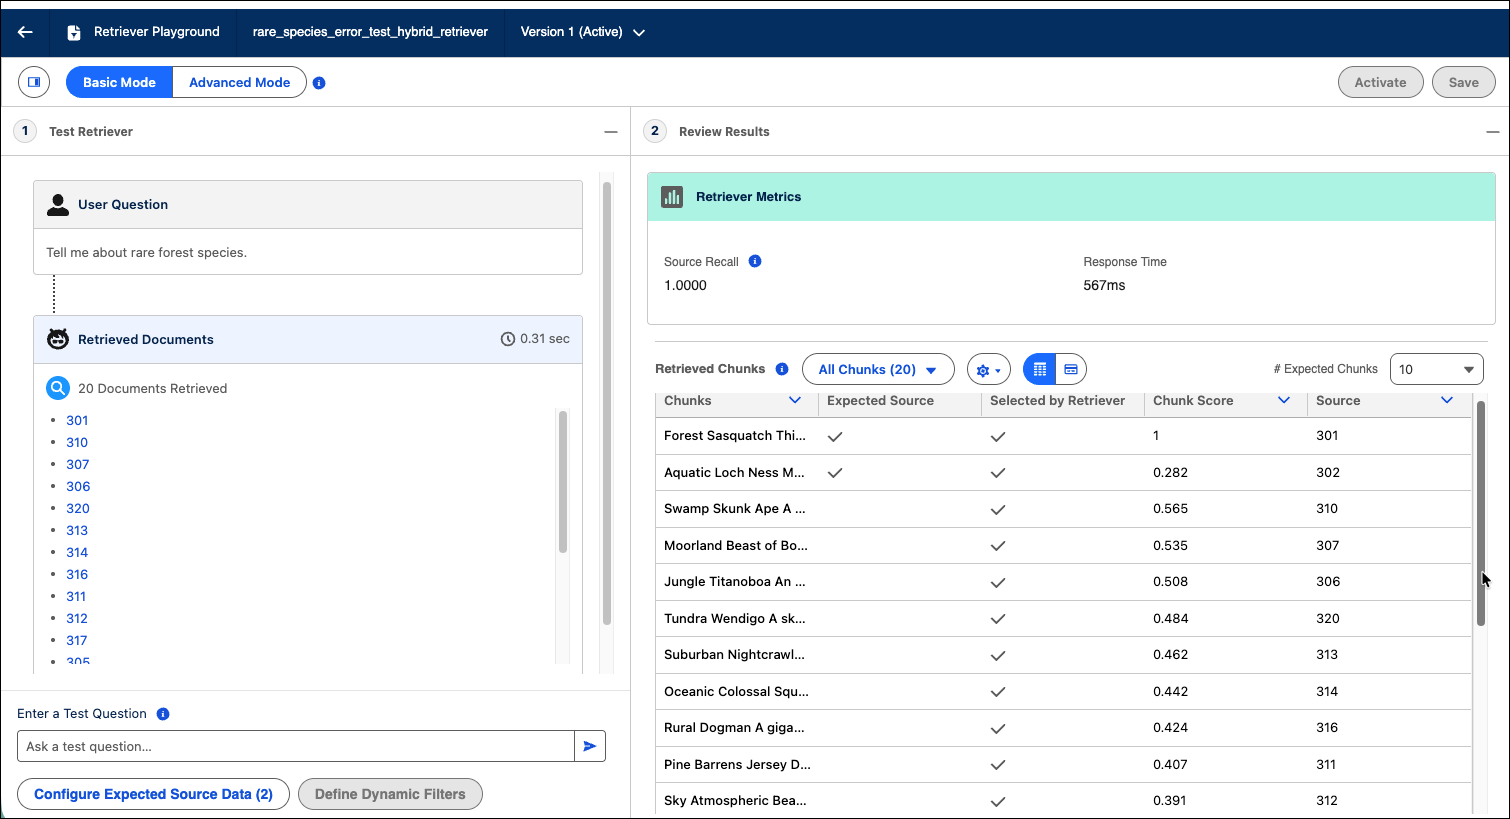
Metric
Description
More Details
Source Recall Score
Measures the percentage of expected source data chunks that are part of the top
retrieved chunks over the total number of chunks in the expected source
data.
If the Source Recall Score is zero, retrieved chunks don't include chunks from
the expected source data.
The score decreases when the number of expected source data chunks is high, even
when there are common chunks between retrieved chunks and the expected source data
chunks.
Response Time
The time in milliseconds for the retriever to respond with results.
-
Context Recall
Available only in Advanced mode. Measures how many of the relevant documents
were successfully retrieved based on a reference answer.
Higher recall means fewer relevant documents were missed. For more information
see, Ragas Context Recall
Context Precision
Available only in Advanced mode. Measures the retriever’s ability to rank
relevant chunks higher than irrelevant ones for a given query based on a reference
answer.
Higher precision score means the relevant chunks in the retrieved context are
placed at top of the ranking. For more information see, Ragas Context Precision
## Retrieved Chunks Metrics
Review the quality of your retriever response with the data in the Retrieved Chunks table or card view. Compare the overlap between the chunks selected by the retriever to the expected source data chunks to check if the top scoring chunks are from the expected source data.
| Metric | Description |
| --- | --- |
| \# Expected Chunks | Determines the maximum number of expected source data chunks to show in the tables. |
| All Chunks | The table shows data on all retrieved chunks - chunks in the expected source data, chunks selected by the retriever, chunk score, and source record for the chunk. Additionally, the table shows any fields the retriever returns. |
| Selected by Retriever | The table shows filtered column data on the chunks that the retriever selects. |
| Expected Source | The table shows filtered column data on chunks from the expected source. |
| Chunks | All retrieved chunks. |
| Chunk Score | Score value for the chunk that determines relevance ranking. There are many factors that affect chunk scores such as the query text, embedding model etc. |
| Citations | Links to the source content relevant to the retrieved chunk. Verify the validity of the source to ensure trusted responses when you deploy the retriever. |
# Retriever Support in Data Cloud One
Learn about retriever capabilities and limitations when you work with Data Cloud One home and companion orgs.
Understanding how retrievers work across Data Cloud One environments is based on two fundamental rules.
- You can edit or delete a retriever only in the org where you created it.
- Data Cloud One metadata synchronization happens in only one direction, from the home org to the companion org, not in reverse or between companion orgs.
## Constraints and Impacts
These constraints affect how you create and manage retrievers in Data Cloud One.
- Retrievers don't sync from Line of Business (LOB) orgs to home orgs or between LOB orgs. Each LOB org is isolated for locally created retrievers.
- Ensemble retrievers created in the home org are visible in companion orgs. When you create an ensemble retriever in the home org, it syncs to the companion orgs in the same way as an individual retriever. You can create an ensemble retriever in a local LOB org with retrievers in the same data space.
- Edit is possible only in the owning org. Switch between home and LOB orgs to tune and test retrievers.
- You can't test retrievers created in the home org in LOB orgs. You can edit, validate, and create new versions in the retriever playground only in the org that owns the retriever.
## Retrievers Created in the Home Org
This table shows what actions you can perform on retrievers created in the home org, depending on where you access them.
| Action | In Home Org | IN LOB OR Companion Org | In Other LOB Orgs |
| --- | --- | --- | --- |
| View (AI Models) | Yes | Yes | Yes |
| View (Prompt Builder / Flow picker) | Yes | Yes | Yes |
| Use at run time (Prompt Builder, Flow) | Yes | Yes | Yes |
| Edit | Yes | No | No |
| Delete | Yes, unless remote references exist in companion orgs. | No | No |
| Create new version | Yes | No | No |
## Retrievers Created Locally in a Line of Business or Companion Org
This table shows the actions you can perform on retrievers created in a LOB or companion org.
| Action | In that LOB Org (owner) | In Home Org | In Other LOB Orgs |
| --- | --- | --- | --- |
| View | Yes | No | No |
| Use at runtime | Yes | No | No |
| Edit | Depends on the creation method. | No | No |
| Delete | Yes | No | No |
If the retriever was created by Agentforce Data Library (ADL) in the LOB org, it isn’t editable in AI Models. Edit the ADL to change it. If a retriever was created using the retriever Connect API, you can edit it directly in AI Models.
## Ensemble Retrievers
This table shows the visibility and run-time capabilities for ensemble retrievers.
| Action | In Home Org | In LOB OR Companion Org |
| --- | --- | --- |
| Visibility | Yes | Yes |
| Run-time use | Yes | Yes |
| Managing Ensemble Retrievers | Create, Edit, and Delete: Yes for retreivers owned by the home org. | Create, Edit, and Delete: Yes for retrievers owned by the LOB or Companion org. |
# Retrieving Content with Vector Search
With vector search and AI agent queries, you can capture queries, search across structured and unstructured data sources, and receive summarized responses that improve efficiency and accuracy.
In these example workflows, a data aware specialist has knowledge articles stored in Salesforce and other PDF files stored externally in an Azure blob store. The data aware specialist wants Salesforce users to get summarized answers from the available content in AI agents using natural language search. The content has been chunked and vectorized in the Data Cloud search index.
## Workflow 1
This example demonstrates how an AI agent and vector search streamline the process of retrieving and summarizing relevant content based on a user query.
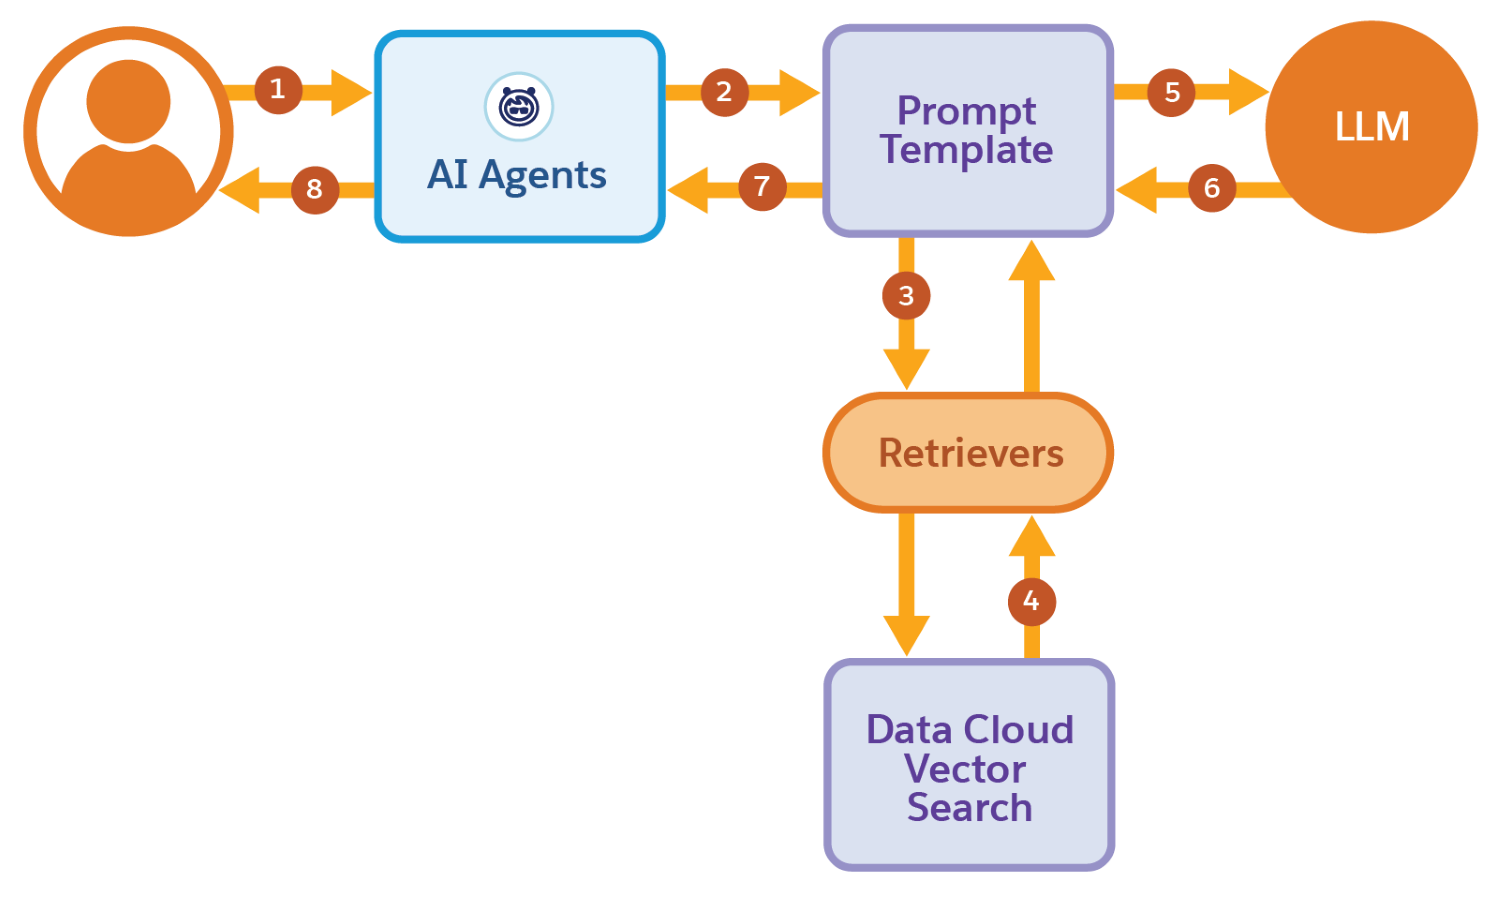
1. The user initiates a request through an AI agent.
2. The agent triggers a prompt template.
3. The prompt initiates a retriever, which is sent to Data 360 vector search.
4. Data 360 vector search retrieves matching excerpts from relevant documents sourced from Salesforce knowledge articles and PDFs stored in an Azure blob store.
5. The prompt template is populated and sent to a large language model (LLM) for summarization.
6. The LLM processes and returns a summarized response to the prompt template.
7. This response is then relayed back to the agent.
8. The response is displayed to the user.
## Workflow 2
This example demonstrates how AI agents, Apex invocable actions, Flows, and vector search streamline the process of retrieving and summarizing relevant content based on a user query.
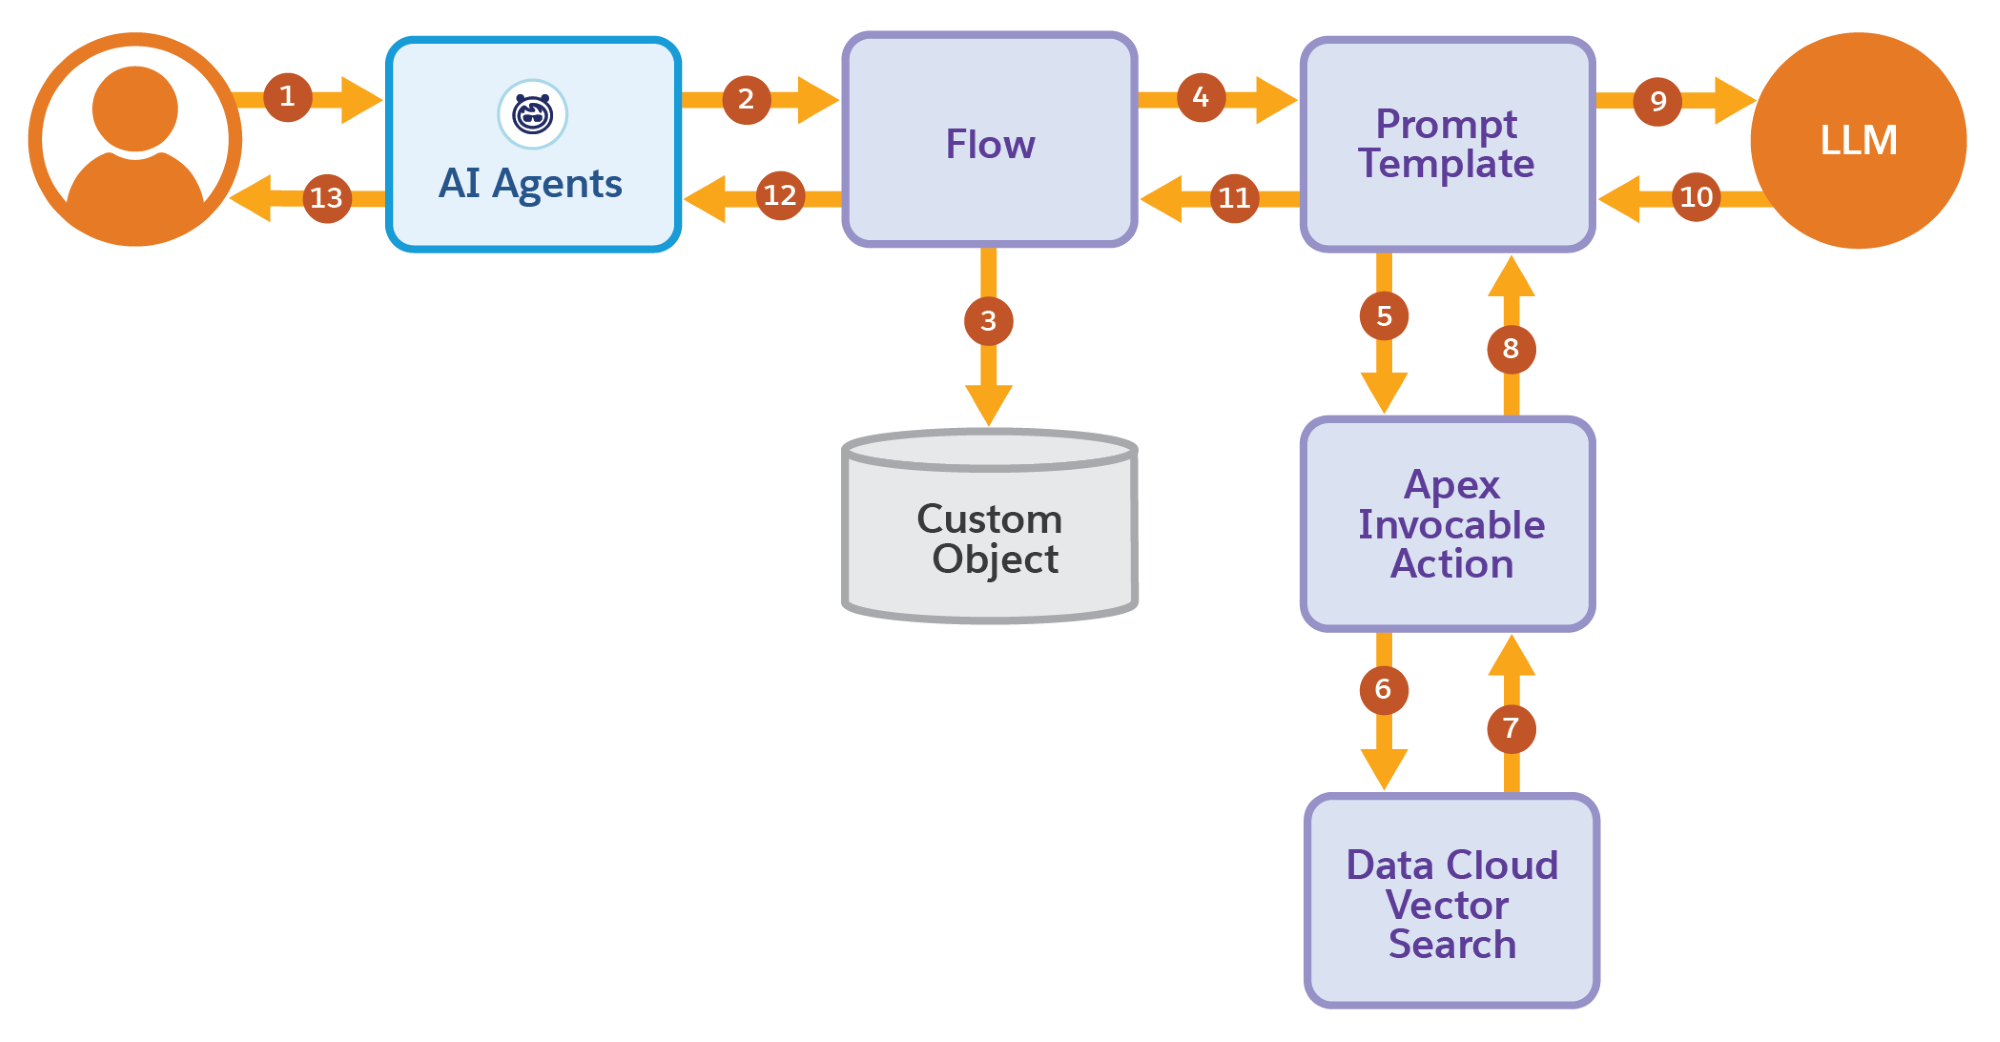
1. The user initiates a request through an AI agent.
2. The agent activates a flow.
3. Flow captures and stores the user’s input in a custom object.
4. Flow triggers a prompt template.
5. Prompt Builder retrieves data from the custom object and executes an Apex invocable action.
6. The Apex invocable action engages the Data 360 vector search.
7. Data 360 vector search retrieves matching excerpts from relevant documents sourced from Salesforce knowledge articles and PDFs stored in an Azure blob store.
8. The Apex invocable action receives the matching excerpts from Data 360 and populates the prompt template.
9. The prompt template is sent to a large language model (LLM) for summarization.
10. The LLM processes and returns a summarized response to the prompt template.
11. This response is then relayed back through Flow.
12. Flow sends the response back to the agent.
13. The response is displayed to the user.
#### See Also
- [_Salesforce Help_: Connect Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_overview.htm&release=264.0.0&type=5 "Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.")
- [_Salesforce Help_: Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_index.htm&release=264.0.0&type=5 "In Data 360, you can create searchable semantic vector embeddings from your unstructured and structured data. Vector search helps your generative AI, automation, and analytics applications understand semantic similarities and context between embeddings.")
- [_Salesforce Help_: Agentforce](https://help.salesforce.com/s/articleView?id=ai.copilot_intro.htm&language=en_US)
# Review Currencies Connection Status in Data Cloud
If your Data Cloud org uses multiple currencies from your Salesforce CRM org, you can review the associated connection’s status.
### Required Editions
User Permissions Needed
To disable a connection:
Permission set:
1. Go to **Data Cloud Setup**.
2. Under Admin Tools, click **Currency Connections**.
You can review the following information about each currencies connection: source type, status, exchange rates, available currencies, and the org id for the connection.
3. To review information about the currencies associated with the connection, from its dropdown menu, click **View Details**.

Note
If a connection isn’t enabled, from its dropdown menu, click **Retry**.
# Review Data in Marketing Cloud Engagement
After the segment is activated, a data extension is added to the Marketing Cloud Engagement business unit that you identified in the activation.
Here’s the data extension based on this activation use case.
SubscriberKey
Id
FirstName
Loyalty_Program_Member
Raja_Jones_Push_123
Raja_Jones_Push_123
Raja
JSON BLOCK
[{"program_name":
"Premiere Plus","Loyalty_Member_Tier":
[{"previous_loyalty_tier":"Silver",
"loyalty_tier":"Gold"}]}]
The first two columns are required based on the activation type (Push). The FirstName column is the selected direct attribute. The FirstName column is the selected direct attribute.
The last column contains the related attributes formatted as a JSON code block in one data extension field. The field is named after the API name of the related attribute's main DMO.
- Program Name
- Previous Loyalty Tier
- Loyalty Tier
These attributes are provided in the JSON code block.
```json
[
{
"program_name": "Premiere Plus",
"Loyalty_Member_Tier": [
{
"previous_loyalty_tier": "Silver",
"loyalty_tier": "Gold"
}
]
}
]
```
You can parse this data with either SSJS, AMPscript, or GTL. Here’s an example of parsing with SSJS.
```html
Congrats, %%=v(@First_Name)=%%!! You have recently reached %%=v(@loyalty_tier)=%% status
for %%=v(@program_name)=%%. To thank you for being such a loyal member with us,
we are giving you a $100 gift card for your favorite food delivery service!
```
Here’s an example of parsing with AMPscript.
```html
%%[
var @ProgramRowset, @ProgramRow, @ProgramName, @LoyaltyTierRowset, @LoyaltyTierRow, @LoyaltyTier
/* Query the first JSON object from the related attributes array. */
set @ProgramRowset=BuildRowsetFromJson(Loyalty_Program_Member,"$.[0]", false)
/* Get the program_name value. */
set @ProgramRow=row(@ProgramRowset, 1)
set @ProgramName=field(@ProgramRow, "program_name")
/* Query the first Loyalty_Member_Tier object inside of the first object. */
set @LoyaltyTierRowset=BuildRowsetFromJson(Loyalty_Program_Member,"$.[0]['Loyalty_Member_Tier'][0]", false)
/* Get the loyalty_tier value */
set @LoyaltyTierRow=row(@LoyaltyTierRowset, 1)
set @LoyaltyTier=field(@LoyaltyTierRow, "loyalty_tier")
/* Print the message */
OutputLine(concat("Congrats, ", FirstName, "!! You have recently reached ", @LoyaltyTier, " status
for ", @ProgramName, ". To thank you for being such a loyal member with us,
we are giving you a $100 gift card for your favorite food delivery service!"))
]%%
```
#### See Also
- [_Salesforce Developer_: Build Row Set From JSON](https://review-app-sdmarkdoc-pr-196.herokuapp.com/docs/marketing/marketing-cloud/guide/buildrowsetfromjson.html)
# Review the Data in Marketing Cloud Engagement
After the segment is activated, a data extension is added to the Marketing Cloud Engagement business unit that you identified in the activation.
Here’s the data extension based on this activation use case.

The first four columns are required based on the activation type (SMS). The FirstName column is the selected direct attribute. The last column contains the related attributes formatted as a JSON code block in one data extension field. The column name, Loyalty\_Program\_Member, is named after the API name of the related attribute’s main DMO.
- Program Name
- Previous Loyalty Tier
- Loyalty Tier
These attributes are provided in the JSON code block.
```json
[
{
"program_name": "Premiere Plus",
"Loyalty_Member_Tier": [
{
"previous_loyalty_tier": "Silver",
"loyalty_tier": "Gold"
}
]
}
]
```
You can parse this data with either SSJS, AMPscript, or GTL. Here’s an example of parsing with SSJS.
```html
Congrats, %%=v(@First_Name)=%%!! Your %%=v(@program_name)=%% loyalty status level has changed to
%%=v(@loyalty_tier)=%%!
```
Here’s an example of parsing with AMPscript.
```html
%%[
var @ProgramRowset, @ProgramRow, @ProgramName, @LoyaltyTierRowset, @LoyaltyTierRow, @LoyaltyTier
/* Query the first JSON object from the related attributes array. */
set @ProgramRowset=BuildRowsetFromJson(Loyalty_Program_Member,"$.[0]", false)
/* Get the program_name value. */
set @ProgramRow=row(@ProgramRowset, 1)
set @ProgramName=field(@ProgramRow, "program_name")
/* Query the first Loyalty_Member_Tier object inside of the first object. */
set @LoyaltyTierRowset=BuildRowsetFromJson(Loyalty_Program_Member,"$.[0]['Loyalty_Member_Tier'][0]", false)
/* Get the loyalty_tier value */
set @LoyaltyTierRow=row(@LoyaltyTierRowset, 1)
set @LoyaltyTier=field(@LoyaltyTierRow, "loyalty_tier")
/* Print the message */
OutputLine(concat("Congrats, ", FirstName, "!! Your ", @ProgramName, " loyalty status level has changed to ", @LoyaltyTier, "!"))
]%%
```
#### See Also
- [_Salesforce Developer_: Build Row Set From JSON](https://review-app-sdmarkdoc-pr-196.herokuapp.com/docs/marketing/marketing-cloud/guide/buildrowsetfromjson.html)
# Right Join
A right join includes all rows from the right and only matching rows from the left input data source objects. The join includes all matched rows in the data output when multiple rows match.

Example
Our company's marketing team captures demographic data in an external data source for opportunities stored in Salesforce. To help create more targeted campaigns, the team is segmenting our current opportunities by the Education Level demographic. Let’s use a right join to add the opportunity data to the demographic data.
To illustrate how this batch data transform handles unmatched rows and duplicate keys, we included them in both input data sources.
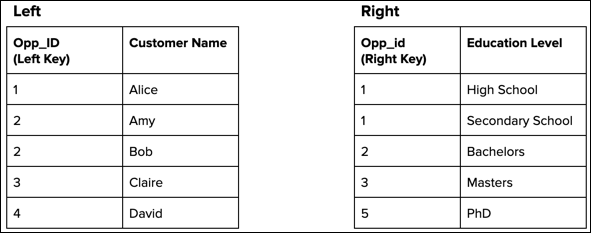
After performing the right join based on the matching keys, the data transform produces the following output data.
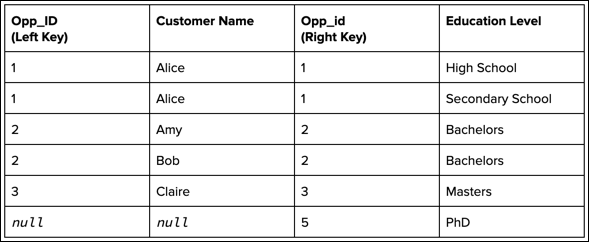
All rows from the right, including those without a match and those with multiple matches, are included in the output. Because `Opp_id` 2 has two matches on the left (Amy and Bob), the target contains a separate record for each of them. Also, because `Opp_id` 5 doesn’t have a match, the `Opp_ID` and `Customer Name` fields are null for that record.

Warning If duplicate records contain measures (as shown for `Opp_id` 1 in the following screenshot), don’t double count the measures when aggregating the records. To prevent duplicate records, use a lookup instead of a join.
# Root Key Lifecycle
Root key statuses in Platform Encryption define the usage of each key for data encryption and decryption.
### Required Editions
Available in: All Editions supported by Data 360. See Data 360 edition availability . Available with add-on license: Enterprise , Performance , Unlimited , and Developer Editions. Requires purchasing Salesforce Shield or Shield Platform Encryption, and Platform Encryption for Data Cloud. Also, to use the optional External Key Management, requires purchasing the Platform Encryption for Consumption license.
Each status impacts the key's availability and functionality within the encryption lifecycle.
- Active: The root key is visible in the Salesforce Platform Encryption UI and encrypts new data. All write options use this key to ingest new data from this point forward. Only one root key can be active at a time.
- Archived: When a new root key is generated, the previous key is archived. Archived keys remain available for decrypting existing data but aren't used for encryption of new data.
- Inactive: A root key becomes inactive when manually deactivated in the Salesforce Platform Encryption UI. In this state, the root key is no longer usable for encryption or decryption. Data encrypted with this key is inaccessible until the key is reactivated through the Salesforce UI.
- Unavailable (EKM only): This status applies only when using External Key Management (EKM). A root key becomes unavailable when it’s deactivated in the external key manager, such as AWS KMS. This status behaves similarly to Inactive. Before Data 360 processes start failing, customers get notified by email.
- Cancelled: Key is abandoned explicitly. This allows customer to generate a different key.
To reactivate the inactive or unavailable keys, see [Reactivate an EKM Key](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_ekm_reactivate_an_ekm_key.htm&language=en_US&type=5). Reactivate the key within 48 hours to avoid data loss in Data 360.
## Key States for BYOK
- Pending Setup completion: Salesforce has created the empty key wrapper in AWS KMS, and the system is waiting for you to upload the wrapped key material and token.
- Active: The key is active and its identifier appears in the UI.
- Archived: The key is archived after you generate a new root key. Archived keys can decrypt existing data but can’t encrypt new data. Decryption continues to work as soon as the key enters the archived state.
- Inactive: The key becomes inactive when you deactivate it in the Salesforce UI. Inactive keys can’t encrypt or decrypt data. Any data encrypted with this key becomes inaccessible until you reactivate it.
- Cancelled: You explicitly canceled the key. After cancellation, you can generate a new key.
#### See Also
- [_Salesforce Help_: Reactivate an EKM Key](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_ekm_reactivate_an_ekm_key.htm&language=en_US)
- [_Salesforce Help_: Check the Connection to Your EKM Key](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_ekm_check_connection.htm&language=en_US)
# Run a Batch Data Transform
Run a batch data transform for the first time to create the data. Run it again to update it with the latest data.
1. Click the **Data Transforms** tab. If the Data Transforms tab isn’t visible, click the **More** tab and select **Data Transforms**.
2. On the Recently Viewed screen, click the triangle to the right of the batch data transform name you want to run, and select **Run Now**.
- **[Schedule a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_schedule.htm&release=264.0.0&type=5)**
To ensure that the most up-to-date data is available by a particular time or to run a job during non-business hours, schedule a batch data transform.
- **[Batch Data Transform Run Types](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_run_types.htm&release=264.0.0&type=5)**
A batch data transform runs in either incremental or full mode. During an incremental run, the transform applies only to input data that has been added, updated, or deleted. These changes can occur through a data stream or from the target of another batch data transform that runs incrementally. A full run processes both new and existing data. You can’t configure the run type. The batch data transform selects the run type based on specific criteria.
# Run Hybrid Search Queries with Query API
Use Query API to run hybrid searches in Data 360. Use these examples as starting points.

Example
This syntax runs a hybrid search in the Query Editor.
```sql
select * from hybrid_search(
table(),
'',
'',
')';
```
Input Parameters
- is the API name of the index DMO.
- is the search text for the hybrid search.
- is the pre-filter condition.
- is the number of results to return.
Result Parameters
- RecordId\_\_c is a unique identifier for the result. This parameter has the same value as the SourceRecordId\_\_c field.
- SourceRecordId\_\_c is the identifier for the source (Chunk DMO) record associated with this result. You can use it in a join expression with the Chunk DMO table.
- vector\_score\_\_c is the similarity score returned by the underlying vector search index.
- keyword\_score\_\_c is the similarity score returned by the underlying keyword search index.
- hybrid\_score\_\_c is the derived score from combining the keyword and vector scores. This score takes ranking factors, such as popularity and recency, into account, which influences the rank of the results.
This syntax runs a hybrid search without pre-filter conditions.
```sql
select * from hybrid_search(
table(Knowledge_full_index__dlm),
'How to input special mark/character when using keyboard input data field','', 2)
```
Query Result
This syntax runs a hybrid search with pre-filter conditions.
```sql
select * from hybrid_search(
table(Knowledge_full_index__dlm),
'How to input special mark/character when using keyboard input data field',
'RecordId__c=''b7e66a34-15e3-43c6-8d84-9af80cd121d6''', 5);
```
Query Result
# Run Vector Searches Using Query API
Use the Query API to run vector searches in Data 360. Use these examples as starting points.
You can use Data 360 SQL to write custom vector search statements. With the Data 360 Query API you can use these SQL statements in your custom applications.
## Basic Vector Search
This syntax performs a vector search across an index data model object (DMO) to find the defined string.
```sql
SELECT *
FROM vector_search(TABLE(),
'',
'""',
''
)
```
Where:
The API name of the index DMO.
Search\_String
The search string for the vector search.
PrefilteringColumn
A boolean expression that filters the scalar fields of the primary key field to limit the search. For more information about pre-filtering, see [Vector Search Query Expressions and Pre-Filtering](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_query_prefilters.htm&release=264.0.0&type=5 "Enhance your vector search queries with pre-filtering fields. Use logical operators and manage case sensitivity for field names and values to ensure precise data retrieval.").
k=topK\_results
The number of the most similar results to return.
## Vector Search With Index and Chunk DMOs
This syntax performs a vector search across an index DMO and a chunk DMO.
```sql
SELECT
v.score__c AS Score__c,
c.chunk__c AS Chunk__c
FROM
vector_search(
TABLE(),
'',
'language = \'English\' AND status = \'active\'',
10
) v
JOIN
c ON v.RecordId__c = c.RecordId__c
AND c.KQ_RecordId__c IS NOT DISTINCT FROM v.KQ_RecordId__c
ORDER BY 1
LIMIT 10
```
Where:
Score\_\_c
The similarity score of each vector to the input search string.
Chunk\_\_c
The chunk that was used to generate the vector embedding.
language=\\'English\\' AND status=\\'active\\'
An example of prefiltering with two filters. These filters are combined using the logical `AND` operator.
10
Returns the top 10 results.
The API name of the chunk DMO.
RecordId\_\_c and KQ\_RecordId\_\_c
The join statement matches on both the RecordID and the key qualified record ID while avoiding NULL values. When joining DMOs and DLOs, use key qualifiers to avoid ID overlap.
## Vector Search with DMOs and Unstructured Data Model Objects (UDMO)
This example performs a vector search, retrieves the relevant text chunks and their scores, provides the file paths of the source documents for the chunks, and returns the top 10 results.
```sql
SELECT
v.score__c AS Score__c,
c.chunk__c AS Chunk__c,
u.FilePath__c AS FilePath__c
FROM
vector_search(TABLE(), '', '', 10) v
JOIN
c ON v.RecordId__c = c.RecordId__c
AND c.KQ_RecordId__c IS NOT DISTINCT FROM v.KQ_RecordId__c
JOIN
u ON c.SourceRecordId__c = u.FilePath__c
ORDER BY 1 DESC
LIMIT 10;
```
Where:
Your\_UDMO
The API name of the UDMO used to create the chunks.
FilePath\_\_c
The relative path of each file that was used to create the chunks and vector embeddings.
- **[Vector Search Query Expressions and Pre-Filtering](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_query_prefilters.htm&release=264.0.0&type=5)**
Enhance your vector search queries with pre-filtering fields. Use logical operators and manage case sensitivity for field names and values to ensure precise data retrieval.
#### See Also
- [_Salesforce Developer:_: Data 360 Query Guide](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/dc-sql-reference/data-cloud-sql-context.html)
- [_Salesforce Help_: Creating Search Index Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.")
# Sales and Order Filters
Here are some examples of common purchase order and service use cases.
## Find Loyal Customers Who Made a Recent Purchase and Without an Urgent Service Case
Filter for individuals in the Gold loyalty tier made a purchase greater than $50 in the last two days and don’t have an open urgent Service Cloud case.

Example
- Loyalty Program Member | Count | At Least | 1
- Loyalty Program Member Status | Is Equal To | Gold
AND
- Case | Count | At Most | 1
- Case Priority | Is Not Equal To | Urgent
AND
- Sales Order | Count | At Least | 1
- Grand Total Amount | Is Greater Than | 50
- Purchase Order Date | Last Number of Days | 2
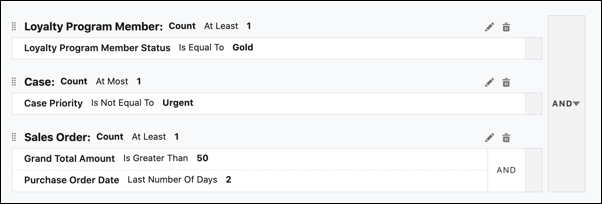
# Sales and Service Bundle Data Mappings
Use the Sales Cloud and Service Cloud datasets to manage leads, track progress, and automate sales processes. Sales Cloud data is extracted from Salesforce standard objects, such as Account, Contact, and Lead. The Service Cloud dataset lets you engage your customers at the right time as they go through the support process. These data mappings relate to the Sales Cloud and Service Cloud bundles available for the Salesforce CRM connector.
The Sales Cloud and Service Cloud bundles automatically map Salesforce standard objects to mappings to Data Cloud standard data model objects (DMOs). You can view all the mappings by reviewing your data streams after the bundle is deployed. You can add or customize the data mappings. Identity resolution uses the DMOs to link multiple records into a unified customer profile.
## Objects and Associated Bundles
When ingesting a bundle, these source objects are automatically mapped to DMOs. Find information about individual fields and specific relationships in the reference link related to that object.
## Sales Cloud Bundle
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| Account | Profile | [Account Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_account.htm) |
| Contact | Profile | [Contact Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_contact.htm) |
| Lead | Profile | [Lead Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_lead.htm) |
| Opportunity | Other | [Opportunity Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_opportunity.htm) |
| Opportunity Contact Role | Other | [Opportunity Contact Role Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_opportunity_contact_role.htm) |
| User | Profile | [User Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_user.htm) |
## Service Cloud Bundle
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| Account | Profile | [Account Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_account.htm) |
| Agent Work | Engagement | [Agent Work Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_agent_work.htm) |
| Agent Work Skill | Other | [Agent Work Skill Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_agent_work_skill.htm) |
| Business Hours | Other | [Business Hours Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_business_hours.htm) |
| Case | Engagement | [Case Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_case.htm) |
| Case History 2 | Other | [Case History 2 Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_case_history_2.htm) |
| Contact | Profile | [Contact Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_contact.htm) |
| Email Message | Engagement | [Email Message Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_email_message.htm) |
| Group | Profile | [Group Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_group.htm) |
| Group Member | Profile | [Group Member Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_group_member.htm) |
| Service Presence Status | Other | [Service Presence Status Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_service_presence_status.htm) |
| Skill | Other | [Skill Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_skill.htm) |
| Survey | Other | [Survey Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey.htm) |
| Survey Invitation | Other | [Survey Invitation Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_invitation.htm) |
| Survey Page | Other | [Survey Page Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_page.htm) |
| Survey Question | Other | [Survey Question Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_question.htm) |
| Survey Question Response | Other | [Survey Question Response Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_question_response.htm) |
| Survey Response | Other | [Survey Response Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_response.htm) |
| Survey Subject | Other | [Survey Subject Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_subject.htm) |
| Survey Version | Other | [Survey Version Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_survey_version.htm) |
| User | Profile | [User Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_user.htm) |
| User Role | Profile | [User Role Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_user_role.htm) |
| User Service Presence | Other | [User Service Presence Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_cloud_user_service_presence.htm) |
## Conversation Mining Bundle
This bundle is used for Service Intelligence visualizations of contact center performance metrics.
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| ConversationReason | Other | [ConversationReason Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_ai_ConversationReason.htm) |
| ConversationReasonExcerpt | Other | [ConversationReasonExcerpt Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_ai_ConversationReasonExcerpt.htm) |
| ConversationReasonGroup | Other | [ConversationReasonGroup Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_ai_ConversationReasonGroup.htm) |
| ConversationReasonReportDefinition | Other | [ConversationReasonReportDefinition Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_ai_ConversationReasonReportDefinition.htm) |
| ConvReasonReportSegmentDefinition | Other | [ConvReasonReportSegmentDefinition Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_ai_ConvReasonReportSegmentDefinition.htm) |
## Digital Engagement Bundle
This bundle is used to access Digital Engagement channel data for Service Cloud Voice, Enhanced Chat, and enhanced third-party channels, such as Facebook Messenger, Apple Messages for Business, WhatsApp, and SMS. The data can be used via reports, dashboards, and APIs for insightful conversation analytics.
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| Conversation | Engagement | [Conversation Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-ai-conversation.html) |
| ConversationParticipant | Engagement | [Conversation Participant Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-ai-conversationparticipant.html) |
| MessagingSession | Engagement | [Messaging Session Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-crm-messaging-session.html) |
| Participant | Other | [Participant Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-ai-participant.html) |
| VoiceCall | Engagement | [Voice Call Mapping](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-crm-voice-call.html) |
## Knowledge Bundle
This bundle is used for Service Intelligence visualizations of knowledge article metrics.
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| CaseArticle | Other | [Case Article Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_case_article.htm) |
| DataCategory | Other | [Data Category Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_data_cat.htm) |
| DataCategoryGroup | Other | [Data Category Group Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_data_cat_group.htm) |
| Knowledge\_DataCategorySelection | Other | [Knowledge Data Category Selection Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_knowledge_dc_selection.htm) |
| Knowledge\_ka | Other | [Knowledge Article Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_ka.htm) |
| Knowledge\_kav | Other | [Knowledge Article Version Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_kav.htm) |
| LinkedArticle | Other | [Linked Article Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_linked_article.htm) |
Related the Knowledge bundle, the Knowledge Article Views Ingestion API ingests other knowledge article data and automatically maps it DMOs.
| Source Object | Category | Mapping Reference |
| --- | --- | --- |
| KnowledgeArticleEngagement | Other | [Knowledge Article Engagement Mappings](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_crm_knowledge_article_engagement.htm) |
## Field Service Core Bundle
| Source Object | Category |
| --- | --- |
| Asset | Other |
| AssetWarranty | Other |
| AssignedResource | Other |
| ContractLineItem | Other |
| ProductConsumed | Other |
| ProductItem | Other |
| ProductRequest | Other |
| ProductRequestLineItem | Other |
| ProductRequired | Other |
| ProductServiceCampaign | Other |
| ProductServiceCampaignItem | Other |
| ProductTransfer | Other |
| ResourceAbsence | Other |
| ServiceAppointment | Other |
| ServiceContract | Other |
| ServiceResource | Other |
| ServiceTerritory | Other |
| ServiceTerritoryMember | Other |
| Shift | Other |
| WarrantyTerm | Other |
| WorkOrder | Other |
| WorkOrderLineItem | Other |
| WorkType | Other |
## Field Service Related Bundle
| Source Object | Category |
| --- | --- |
| Location | Other |
| Pricebook2 | Other |
| PriceBookEntry | Other |
| Product2 | Other |
# Sales Order Data Object
The Customer 360 Data Model sales order subject defines the future revenue or quantity for an opportunity by product family and rolls it up by territory, management (role), or hierarchy.
The sales data model includes the individual, account, sales order, and opportunity data model objects.
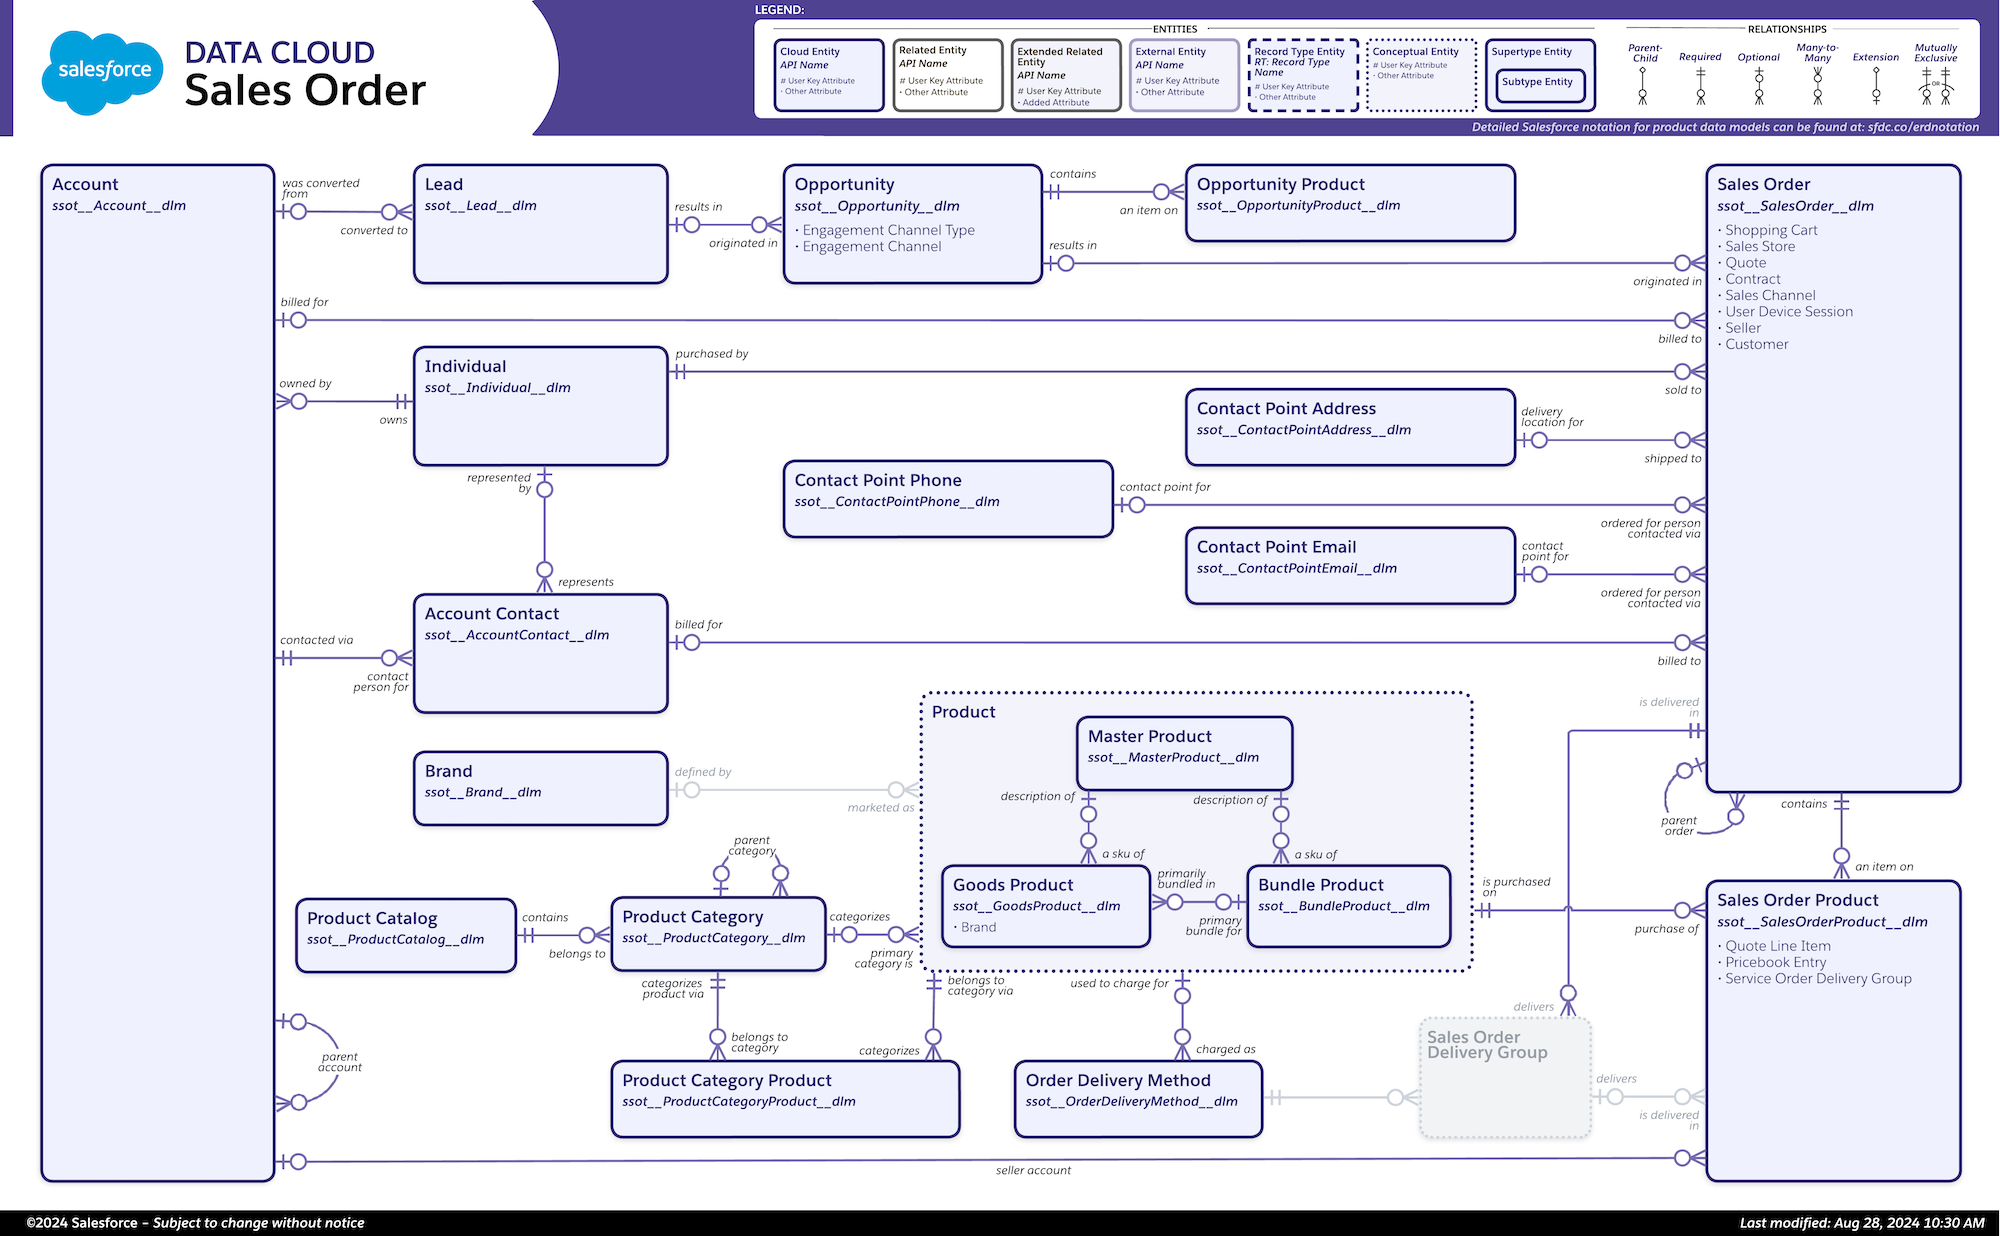
For more details and a larger image, visit the [Data Model Gallery](https://developer.salesforce.com/docs/platform/data-models/guide/sales-order.html).
These sales order subject objects are represented in Data 360.
| DMO | Description | Reference Doc Link |
| --- | --- | --- |
| Sales Order | A Data 360 DMO that provides information around current and pending sales orders. | [Sales Order DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_sales_order_dmo.htm) |
| Sales Order Product | A Data 360 DMO for a specific product, for example, a carton of milk, a pallet of coffee, or a mobile phone. | [Sales Order Product DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_sales_order_product_dmo.htm) |
| Sales Store | A Data 360 DMO that provides information regarding a retail establishment selling items to the public. | [Sales Store DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_sales_store_dmo.htm) |
| Order Delivery Method | A Data 360 DMO for the order and delivery methods for products or service fulfillment. | [Order Delivery Method DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_order_delivery_method_dmo.htm) |
| Opportunity | A Data 360 DMO for a deal or sale that is in progress and not yet completed. | [Opportunity DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_opportunity_dmo.htm) |
| Opportunity Product | A Data 360 DMO for an object connecting an opportunity to the product that it represents, allowing for a many-to-many relationship. | [Opportunity Product DMO Reference](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_opportunity_product_dmo.htm) |
# Salesforce Catalog
The Salesforce Catalog is a unified registry that discovers, indexes, and connects metadata across Salesforce and its ecosystem. This semantically rich foundation powers intelligent automation, agents, and high accuracy natural language queries at scale.
Fragmented data leaves AI agents with low context. The catalog grounds AI in your unique business semantics, reducing hallucinations, and turning cryptic technical fields into actionable intelligence for high accuracy, production-grade autonomous AI.
Data 360 powers the Salesforce Catalog. Built natively for real-time AI systems, Data 360 ingests, transforms, maps, and indexes metadata for natural language queries.
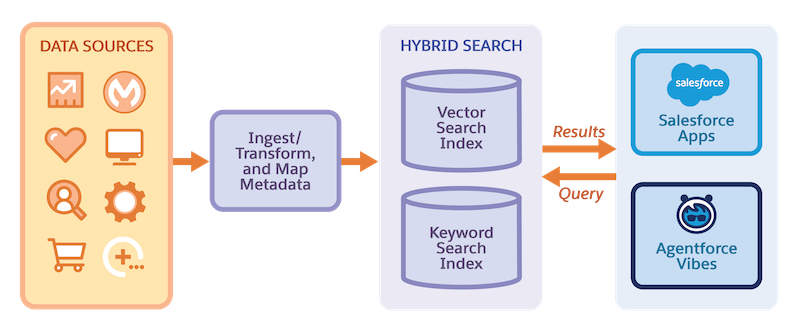
As part of the Salesforce Headless Toolkit initiative, the platform makes capabilities accessible through APIs, Model Context Protocol (MCP), or CLIs without a browser. Developers, admins, and agents use the catalog to access full org context, metadata, permissions, and business logic in one place.
By using the Salesforce hosted Metadata Grounding MCP server with AI agents, you can autonomously query, access, and interpret metadata in AI environments such as Agentforce Vibes. For more information on Metadata Grounding MCP Server, see [Metadata Grounding MCP Server (Beta)](https://developer.salesforce.com/docs/platform/hosted-mcp-servers/guide/metadata-grounding.html).
- **[Metadata Extraction and Refresh](https://help.salesforce.com/s/articleView?id=data.c360_a_metadata_ext_rfsh.htm&release=264.0.0&type=5)**
The metadata extraction framework extracts standard and custom metadata from a Salesforce org. Data 360 stores the metadata in a metadata data lake object (mDLO). A metadata extraction pipeline monitors the metadata's lifecycle, extraction, and ingestion into the catalog. The extraction pipeline handles bulk (Day 0), incremental metadata ingestion, and refresh between the Salesforce org and Data 360.
- **[Metadata Grounding Capabilities](https://help.salesforce.com/s/articleView?id=data.c360_a_metadata_grounding_capabilities.htm&release=264.0.0&type=5)**
With metadata grounding, you discover, understand, and reuse metadata through natural language interactions. Metadata grounding capabilities accelerate development and customization by making your Salesforce ecosystem accessible and actionable.
- **[Turn On Salesforce Catalog](https://help.salesforce.com/s/articleView?id=data.c360_a_sf_catalog_enable.htm&release=264.0.0&type=5)**
Make Your org's metadata available to AI agents with natural language queries by enabling Salesforce Catalog.
- **[Salesforce Catalog Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_catalog_considerations.htm&release=264.0.0&type=5)**
Note these considerations when you work with the Salesforce Catalog.
- **[Troubleshoot Salesforce Catalog Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_sf_catalog_troubleshooting.htm&release=264.0.0&type=5)**
Diagnose and fix the most common issues when setting up Salesforce Catalog.
- **[Billing Considerations for Salesforce Catalog](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_catalog_billing_considerations.htm&release=264.0.0&type=5)**
When you use Salesforce Catalog, you process unstructured data and search index configurations in Data 360. Use of Salesforce Catalog with Data 360 impacts the consumption of credits in these usage types.
#### See Also
- [_Salesforce Help_: Turn On Salesforce Catalog](https://help.salesforce.com/s/articleView?id=data.c360_a_sf_catalog_enable.htm&language=en_US)
- [_Salesforce Help_: Billing Considerations for Salesforce Catalog](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_catalog_billing_considerations.htm&language=en_US)
# Salesforce Catalog Considerations
Note these considerations when you work with the Salesforce Catalog.
- Salesforce Catalog is a Data 360 feature that can run on separate infrastructure, with different security protections and physical hosting locations than Agentforce Vibes. Review the [Salesforce Trust and Compliance Documentation](https://www.salesforce.com/company/legal/trust-and-compliance-documentation/).
- When you turn on Salesforce Catalog, Data 360 ingests your structural and operational metadata and generative AI enriches it.
- After you turn on Salesforce Catalog in a Data 360 sandbox, it applies to all associated sandboxes.
- To turn off and deprovision Salesforce Catalog after it's provisioned, contact Salesforce Customer Support.
- Salesforce Catalog isn't available in Developer Edition orgs if namespaces are enabled because search indexes aren't supported when namespaces are turned on.
- Salesforce Catalog isn't available in scratch orgs. Scratch org environments don’t support Data 360
- Salesforce Catalog doesn't support incremental metadata sync in Data Cloud One configurations. The catalog runs only daily full refresh cycles in Data Cloud One configurations.
# Salesforce Commerce Data Bundle Mappings
Salesforce Commerce standard bundles include Business-to-Business (B2B) Commerce, Direct-to-Consumer (D2C) Commerce, and Salesforce Order Management bundles. These bundles map the data source objects to the data model objects (DMO) and establish DMO relationships that enhance segmentation results.
## Salesforce Commerce B2B Data Bundle
Salesforce Commerce B2B data streams are created from the B2B Commerce data bundle. With the B2B data bundle, you can deploy relevant data streams and mappings for these objects.
| Source Object | Description | Category | Mapping Reference |
| --- | --- | --- | --- |
| Account | Data that indicates how a shopper interacts with a store. For example, billing and shipping information. | Profile | [Account Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_account.htm) |
| Coupon | A method for a buyer to compensate a seller for a purchased good or service. | Other | [Coupon Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_coupon.htm) |
| Order Adjustment Group Summary | A change to the price of a product that’s made before order fulfillment. | Engagement | [Order Adjustment Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_adgroupsum.htm) |
| Order Delivery Group Summary | The method that the buyer uses to compensate a seller for a service or product purchased. | Engagement | [Order Delivery Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdeliv_grsum.htm) |
| Order Delivery Method | A standardized method for transferring purchased products or services to the fulfillment destination. A delivery method characterized by the type of transportation used and by the delivering organization or group. | Engagement | [Order Delivery Method Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdelivery.htm) |
| Order Item Adjustment Line Summary | A change to the price of a sales order product that's made before order fulfillment. A sales order product price adjustment can be standalone, or it can relate to an adjustment defined at the overall sales order level. | Engagement | [Order Item Adjustment Line Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_ajdsum.htm) |
| Order Item Summary | A component of a sales order that identifies a product or service sold to the customer. | Engagement | [Order Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_itemsum.htm) |
| Order Item Summary Change | A change log for a sales order. | Engagement | [Order Item Summary Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderitemsum.htm) |
| Order Item Tax Line Item Summary | A charge imposed by a government entity. The tax types are aligned to phases of the process: SalesOrderTax, FulfillmentProductTax, and ShipmentProductTax. | Engagement | [Order Item Tax Line Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_tax.htm) |
| Order Payment Summary | One or more payments that have the same payment method applied to a single sales order. | Engagement | [Order Payment Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_pay.htm) |
| Order Summary | An internal document generated by the seller indicating that the customer is ready to purchase products and services. | Engagement | [Order Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_sum.htm) |
| Payment Method | A method for a buyer to compensate a seller for a purchased good or service. | Other | [Payment Method Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_paymentmethod.htm) |
| Product | A product that a company is selling. The Product object includes fields for quantity and revenue. | Other | [Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product.htm) |
| Product Attribute | An attribute of a product. For example, the type of material used for ShoeXYZ. | Other | [Product Attribute Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_process_att.htm) |
| Product Catalog | A catalog used for a business process. For example, inventory or merchandising. | Other | [Product Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_cat.htm) |
| Product Category | Categories and subcategories organize and group products in your catalog and on your storefront. For example, an outdoors outfitter site uses the Boots, Climbing Gear, and Outerwear categories to organize products on their storefront. | Other | [Product Category Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_category.htm) |
| Product Category Product | The assignment of a product to categories. For example, ShoeXYZ is assigned to the Shoes and Running categories. | Other | [Product Category Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_catprod.htm) |
| Promotion | Any type of marketing communication used to inform or persuade target audiences of the merits of a product, service, brand, or issue. | Other | [Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_promotion.htm) |
| Web Store | The Webstore object represents a Direct-to-Consumer (D2C) commerce store selling products to the public. | Other | [Web Store Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstore.htm) |
| Web Store Catalog | The products available at a store. Each record in a WebStoreCatalog data source object specifies a product catalog that organizes the products in a store. | Other | [Web Store Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorecatalog.htm) |
| Web Store Network | WebStoreNetwork data represents the relationship between a web store and an experience site. | Other | [Web Store Network Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorenetwork.htm) |
## Salesforce Commerce D2C Data Bundle
Salesforce Commerce D2C data streams are created from the D2C Commerce data bundle. With the D2C data bundle, you can deploy relevant data streams and mappings for these objects.
| Source Object | Description | Category | Mapping Reference |
| --- | --- | --- | --- |
| Account | Data that indicates how a shopper interacts with a store. For example, billing and shipping information. | Profile | [Account Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_account.htm) |
| Coupon | A method for a buyer to compensate a seller for a purchased good or service. | Other | [Coupon Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_coupon.htm) |
| Order Adjustment Group Summary | A change to the price of a product that’s made before order fulfillment. | Engagement | [Order Adjustment Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_adgroupsum.htm) |
| Order Delivery Method | A standardized method for transferring purchased products or services to the fulfillment destination. A delivery method characterized by the type of transportation used and by the delivering organization or group. | Engagement | [Order Delivery Method Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdelivery.htm) |
| Order Delivery Group Summary | The method that the buyer uses to compensate a seller for a service or product purchased. | Engagement | [Order Delivery Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdeliv_grsum.htm) |
| Order Item Adjustment Line Summary | A change to the price of a sales order product that's made before order fulfillment. A sales order product price adjustment can be standalone, or it can relate to an adjustment defined at the overall sales order level. | Engagement | [Order Item Adjustment Line Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_ajdsum.htm) |
| Order Item Summary | A component of a sales order that identifies a product or service sold to the customer. | Engagement | [Order Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_itemsum.htm) |
| Order Item Summary Change | A change log for a sales order. | Engagement | [Order Item Summary Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderitemsum.htm) |
| Order Item Tax Line Item Summary | A charge that imposed by a government entity. The tax types are aligned to phases of the process: SalesOrderTax, FulfillmentProductTax, and ShipmentProductTax. | Engagement | [Order Item Tax Line Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_tax.htm) |
| Order Payment Summary | One or more payments that have the same payment method applied to a single sales order. | Engagement | [Order Payment Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_pay.htm) |
| Order Summary | An internal document generated by the seller indicating that the customer is ready to purchase products and services. | Engagement | [Order Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_sum.htm) |
| Payment Method | A method for a buyer to compensate a seller for a purchased good or service. | Other | [Payment Method Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_paymentmethod.htm) |
| Product | A product that a company is selling. The Product object includes fields for quantity and revenue. | Other | [Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product.htm) |
| Product Attribute | An attribute of a product. For example, the type of material used for ShoeXYZ. | Other | [Product Attribute Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_process_att.htm) |
| Product Catalog | A catalog used for a business process. For example, inventory or merchandising. | Other | [Product Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_cat.htm) |
| Product Category | Categories and subcategories organize and group products in your catalog and on your storefront. For example, an outdoors outfitter site uses the Boots, Climbing Gear, and Outerwear categories to organize products on their storefront. | Other | [Product Category Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_category.htm) |
| Product Category Product | The assignment of a product to categories. For example, ShoeXYZ is assigned to the Shoes and Running categories. | Other | [Product Category Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_catprod.htm) |
| Promotion | Any type of marketing communication used to inform or persuade target audiences of the merits of a product, service, brand, or issue. | Other | [Promotion Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_promotion.htm) |
| Web Store | The Webstore object represents a Direct-to-Consumer (D2C) commerce store selling products to the public. | Other | [Web Store Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstore.htm) |
| Web Store Catalog | The products available at a store. Each record in a WebStoreCatalog data source object specifies a product catalog that organizes the products in a store. | Other | [Web Store Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorecatalog.htm) |
| Web Store Network | WebStoreNetwork data represents the relationship between a web store and an experience site. | Other | [Web Store Network Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorenetwork.htm) |
## Salesforce Order Management Data Bundle
Salesforce Order Management data streams are created from the Salesforce Order Management data bundle. With the Salesforce Order Management data bundle, you can deploy relevant data streams and mappings for these objects.
| Source Object | Description | Category | Mapping Reference |
| --- | --- | --- | --- |
| Fulfillment Order | Information about how a sales order is delivered to a customer and who delivers it. For example, the warehouse that fills an order and the required information about the process. | Engagement | [Fulfillment Order Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_fulfillmentorder.htm) |
| Fulfillment Order Line Item | A shippable product or service that is part of a fulfillment order. | Engagement | [Fulfillment Order Line Item Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_fulfillmentorder_lineitem.htm) |
| Fulfillment Order Item Adjustment | A price adjustment that is calculated at the level of a specific fulfillment order product. | Engagement | [Fulfillment Order Item Adjustment Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_fulfillmentorder_itemadj.htm) |
| Fulfillment Order Item Tax | A tax that is calculated on the base price of a fulfillment order product. | Engagement | [Fulfillment Order Item Tax Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_fulfillmentorder_itemtax.htm) |
| Location | The location that fulfills orders, such as a warehouse or a retail store. | Engagement | [Location Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_location.htm) |
| Order Adjustment Group Summary | A change to the price of a product that’s made before order fulfillment. | Engagement | [Order Adjustment Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_adgroupsum.htm) |
| Order Delivery Method | A standardized method for transferring purchased products or services to the fulfillment destination. A delivery method characterized by the type of transportation used and by the delivering organization or group. | Engagement | [Order Delivery Method Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdelivery.htm) |
| Order Delivery Group Summary | The method that the buyer uses to compensate a seller for a service or product purchased. | Engagement | [Order Delivery Group Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderdeliv_grsum.htm) |
| Order Item Adjustment Line Summary | A change to the price of a sales order product that's made before order fulfillment. A sales order product price adjustment can be standalone, or it can relate to an adjustment defined at the overall sales order level. | Engagement | [Order Item Adjustment Line Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_ajdsum.htm) |
| Order Item Summary | A component of a sales order that identifies a product or service sold to the customer. | Engagement | [Order Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_itemsum.htm) |
| Order Item Summary Change | A change log for a sales order. | Engagement | [Order Item Summary Change Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_orderitemsum.htm) |
| Order Item Tax Line Item Summary | A charge imposed by a government entity. The tax types are aligned to phases of the process: SalesOrderTax, FulfillmentProductTax, and ShipmentProductTax. | Engagement | [Order Item Tax Line Item Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_item_tax.htm) |
| Order Payment Summary | One or more payments that have the same payment method applied to a single sales order. | Engagement | [Order Payment Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_pay.htm) |
| Order Summary | An internal document generated by the seller indicating that the customer is ready to purchase products and services. | Engagement | [Order Summary Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_order_sum.htm) |
| Process Exception | An event related to a business process or data that affects normal order processing. Errors in programs or communication aren’t process exceptions, but they can cause process exceptions. | Engagement | [Process Exception Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_processexception.htm) |
| Product | A product that a company is selling. The Product object includes fields for quantity and revenue. | Other | [Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product.htm) |
| Product Attribute | An attribute of a product. For example, the type of material used for ShoeXYZ. | Other | [Product Attribute Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_process_att.htm) |
| Product Catalog | A catalog used for a business process. For example, inventory or merchandising. | Other | [Product Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_cat.htm) |
| Product Category | Categories and subcategories organize and group products in your catalog and on your storefront. For example, an outdoors outfitter site uses the Boots, Climbing Gear, and Outerwear categories to organize products on their storefront. | Other | [Product Category Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_category.htm) |
| Product Category Product | The assignment of a product to categories. For example, ShoeXYZ is assigned to the Shoes and Running categories. | Other | [Product Category Product Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_product_catprod.htm) |
| Return Order | The return of order products in Salesforce Order Management. | Engagement | [Return Order Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_returnorder.htm) |
| Return Order Item Adjustment | The change in price of the item in the return order product. | Engagement | [Return Order Item Adjustment Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_returnorder_itemadj.htm) |
| Return Order Item Tax | The tax amount adjustments made for the return order product. | Engagement | [Return Order Item Tax Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_returnorder_itemtax.htm) |
| Return Order Line Item | A product that a customer has returned to the seller. | Engagement | [Return Order Line Item Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_returnorder_line.htm) |
| Sales Channel | The channel used to sell goods. For example, a web store or a retail store. | Other | [Sales Channel Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_saleschannel.htm) |
| Web Store | The Webstore object represents a Direct-to-Consumer (D2C) commerce store selling products to the public. | Other | [Web Store Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstore.htm) |
| Web Store Catalog | The products available at a store. Each record in a WebStoreCatalog data source object specifies a product catalog that organizes the products in a store. | Other | [Web Store Catalog Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorecatalog.htm) |
| Web Store Network | WebStoreNetwork data represents the relationship between a web store and an experience site. | Other | [Web Store Network Mapping](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360dm_commerce_webstorenetwork.htm) |
# Salesforce Commerce Object Permissions
When you enable object and field permissions for Salesforce Commerce objects, object names can differ under the connector integration permission sets.
The table maps the Salesforce Commerce objects to the object name for permission sets. For objects that depend on another object, you can set only field-level permissions. For example, the ReturnOrderProductAdjustment object depends on ReturnOrder.
Salesforce Commerce object names are linked to data source object mappings.
| Salesforce Commerce Object Name | Permission Object Name | Only Field-level Permissions |
| --- | --- | --- |
| Account | Accounts | |
| Address | Addresses | |
| ContactPointAddress | Contact Point Addresses | |
| Coupon | Coupons | |
| FulfillmentOrder | Fulfillment Orders | |
| FulfillmentOrderProduct | Fulfillment Order Products |  |
| FulfillmentOrderProductPriceAdjustment | Fulfillment Order Item Adjustments |  |
| FulfillmentOrderProductTax | Fulfillment Order Item Taxes |  |
| Location | Locations | |
| OrderDeliveryMethod | Order Delivery Methods | |
| PaymentMethod | Card Payment Methods | |
| PriceBook2 | Price Books | |
| PriceBookEntry | Price Book Entries |  |
| ProcessException | Process Exceptions | |
| Product | Products | |
| ProductAttribute | Product Attributes |  |
| ProductCatalog | Catalogs | |
| ProductCategory | Categories | |
| ProductCategoryProduct | Product Category Products | |
| Promotion | Promotions | |
| ReturnOrder | Return Order | |
| ReturnOrderProductAdjustment | Return Order Item Adjustments |  |
| ReturnOrderProductTax | Return Order Item Taxes |  |
| ReturnOrderProduct | Return Order Line Items |  |
| SalesChannel | Sales channels | |
| SalesOrder | Order Summaries | |
| SalesOrderChangeLog | Order Product Summary Changes |  |
| SalesOrderDeliveryGroup | Order Delivery Group Summaries |  |
| SalesOrderPaymentSummary | Order Payment Summaries |  |
| SalesOrderPriceAdjustment | Order Product Adjustment Line Item Summaries |  |
| SalesOrderProduct | Order Products |  |
| SalesOrderProductPriceAdjustment | Order Product Adjustment Line Item Summaries |  |
| SalesOrderProductTax | Order Product Tax Line Item Summaries |  |
| WebStore | Stores | |
| WebStoreProductCatalog | Store Catalogs | |
# Salesforce Connectors for Data Cloud
In Data Cloud, you can connect to other Salesforce data sources. Many of the connectors for these data sources have a starter data bundle to help you quickly set up a data stream. A starter data bundle is a Salesforce-defined data stream definition that includes mapping to the Data Cloud DMO structure. You can also customize a bundle. Some connectors offer multiple data bundle options.
- **[B2C Commerce Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_commerce_cloud_connector.htm&release=264.0.0&type=5)**
Connect your B2C Commerce instance to a production site and create a B2C Commerce data stream. The data stream ingests all data from active production sites, both protected or unprotected. This connector is for production sites only. You can’t set up a B2C Commerce connector to test, sandbox, or non-live production site.
- **[Marketing Cloud Account Engagement Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_mcae_connector.htm&release=264.0.0&type=5)**
Ingest data from Account Engagement into Data 360 to drive calculated insights and build segments based on marketing asset engagement.
- **[Marketing Cloud Engagement Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_marketing_cloud_data_sources.htm&release=264.0.0&type=5)**
Connect Marketing Cloud Engagement to Data 360 using a starter data bundle or data extension.
- **[Marketing Cloud Personalization Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_interaction_studio_connector.htm&release=264.0.0&type=5)**
With Marketing Cloud Personalization (formerly Interaction Studio) data in Data 360, you can ingest user profiles and behavioral events to enrich the customer profile and increase personalization. The connector also lets you use Marketing Cloud Personalization as an activation target.
- **[Salesforce CRM Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_salesforce_crm_connector.htm&release=264.0.0&type=5)**
A standard Salesforce CRM connection establishes a connection between Data 360 and a Salesforce org, allowing Data 360 to ingest data from the connected org. Data 360 ingests data and sends back only data actions. This type of connection doesn’t share any data back to the connected org.
- **[Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one.htm&release=264.0.0&type=5)**
Streamline multi-org architecture and simplify Data 360 access with Data Cloud One. Data Cloud One allows users of connected companion orgs to access data and Data 360 features from one unified Data 360 home org.
- **[Omnichannel Inventory Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_oci_connector.htm&release=264.0.0&type=5)**
In Data Cloud, you can establish a connection to Omnichannel Inventory using the provided connector. The connection process creates the data streams and maps the data source objects to the data model objects (DMO) and establishes DMO relationships.
# Salesforce CRM Connection Considerations
Understand how the CRM connector maps and processes data, as well as its overall behavior.
- **[Data Refresh Process for Extraction](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5)**
Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge\_kav objects.
- **[Mapping for DateTime, Date, and Boolean Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_mapping_for_datetime_date_and_boolean_objects.htm&release=264.0.0&type=5)**
The Salesforce CRM connector maps the objects DateTime, Date, and Boolean based on the object and field type.
- **[CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5)**
Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.
- **[Object Support for CRM Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_unsupported_objects_types.htm&release=264.0.0&type=5)**
When you create a Salesforce CRM data stream, the CRM connector doesn’t support the ingestion of all objects or object types from the connected CRM orgs. Use only supported objects and object types for your data stream.
- **[Mapping Org IDs](https://help.salesforce.com/s/articleView?id=data.c360_a_mapping_org_ids.htm&release=264.0.0&type=5)**
The internal organization ID is commonly referred to as the Salesforce.com Organization ID or simply the Org ID. It’s a reference ID to the business unit or other internal organization that owns the data record and is a standard audit field for every standard DMO. However, this reference ID value is not populated by the CRM connector.
- **[CRM Connector Language Behavior](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_language_behavior.htm&release=264.0.0&type=5)**
Keep these considerations in mind when using the CRM connector.
- **[Use an Alias for a Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_alias.htm&release=264.0.0&type=5)**
As of July ‘24, an alias is required when setting up a Salesforce CRM connection. Existing connections aren't assigned an alias. The names of the data stream and data lake object are derived from the alias.
- **[CRM Connections in a Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connections_in_a_sandbox.htm&release=264.0.0&type=5)**
Connect your Salesforce org to a sandbox to ensure the safety and integrity of your production environment. When you set up CRM connections from your Salesforce org to a sandbox org, the connections are copied from the production org to the sandbox org.
- **[Sales and Service Bundle Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_sales_service_bundle_data_mappings.htm&release=264.0.0&type=5)**
Use the Sales Cloud and Service Cloud datasets to manage leads, track progress, and automate sales processes. Sales Cloud data is extracted from Salesforce standard objects, such as Account, Contact, and Lead. The Service Cloud dataset lets you engage your customers at the right time as they go through the support process. These data mappings relate to the Sales Cloud and Service Cloud bundles available for the Salesforce CRM connector.
- **[Loyalty Management Bundle Data Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_mappings_loyalty_management.htm&release=264.0.0&type=5)**
The Loyalty Management data lets you track and manage reward and recognition programs. Loyalty Management is a Salesforce Industry Cloud application. The data is available from Salesforce Platform objects, including Loyalty Program, Loyalty Tier, and Member Benefits. These data mappings relate to the Loyalty Management bundle available in Data 360. You can add more mappings by the bundle, and customize the data mappings. The Loyalty Management bundle is accessible only when object permissions have been set for your Loyalty Management objects.
- **[Salesforce Commerce Data Bundle Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_mappings_commerce_cloud.htm&release=264.0.0&type=5)**
Salesforce Commerce standard bundles include Business-to-Business (B2B) Commerce, Direct-to-Consumer (D2C) Commerce, and Salesforce Order Management bundles. These bundles map the data source objects to the data model objects (DMO) and establish DMO relationships that enhance segmentation results.
# Salesforce CRM Connector
A standard Salesforce CRM connection establishes a connection between Data 360 and a Salesforce org, allowing Data 360 to ingest data from the connected org. Data 360 ingests data and sends back only data actions. This type of connection doesn’t share any data back to the connected org.
You can also use a starter data bundle to create data streams in Data 360. The bundle maps the data source objects to the data model objects (DMOs) and establishes DMO relationships that improve your segmentation results.
Data 360 automatically connects to its home org. You can set up a standard CRM connection to orgs other than that home org. An org can be connected to multiple Data 360s via standard CRM connections, allowing multiple Data 360s to ingest the org's data.

Note The Salesforce CRM Connector doesn’t support ingestion of big objects from Salesforce CRM.
## Government Cloud Compliance
[FedRAMP High and DoD IL4/5](https://help.salesforce.com/s/articleView?id=ind.government_cloud_data_cloud.htm&language=en_US)
- **[Set Up a CRM Salesforce Org Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_crm_connection.htm&release=264.0.0&type=5)**
A data source and data action target are automatically created for the org where you set up Data 360. To connect other Salesforce orgs, manually set up a connection.
- **[Salesforce CRM Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5)**
When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.
- **[Salesforce CRM Connection Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_managing_crm_connections.htm&release=264.0.0&type=5)**
Understand how the CRM connector maps and processes data, as well as its overall behavior.
- **[Troubleshooting CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_refresh_history.htm&release=264.0.0&type=5)**
If you have trouble with creating, refreshing, or disconnecting a Salesforce CRM data stream, see these common issues.
#### See Also
- [_Salesforce Help_: Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.")
- [_Salesforce Help_: Manage Big Objects](https://help.salesforce.com/s/articleView?id=platform.custom_index.htm&type=5&language=en_US)
# Salesforce CRM Permissions
When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.
- View All Records, Modify All Records, and View All Fields permissions are object permissions. View All Records and View All Fields must be granted on objects and fields to ingest data. View All Fields is enabled by default. Users with the View All Fields user permission can view all fields and field data for all objects, regardless of assigned field permissions.
- View All Records isn't enabled by default. This permission is required to enable the Query All Fields permission, which grants users access to content files and objects.
- Users with the View All Data or Modify All Data user permission can view or modify all apps and data, even if the apps and data aren’t shared with them.
- Data 360 uses a system user called the Platform Integration User. Permissions granted through permission sets to this user determine the data you retrieve from Data 360.
- Grant permissions on related objects even if you don’t ingest the related objects into Data 360. Ingested objects that reference related objects need permissions to access the related object information and create a data stream.
- Starting In the Winter ’25 release:
- The Data Cloud Salesforce Connector permission set includes the View All Data permission enabled by default for new orgs. For existing Data Cloud Salesforce Connector permission sets, you can manually apply the View All Data permission or set the object permissions one at a time.
- The name of the `sfdc_c360a_sfdctrust_permSet` API has been changed to `sfdc_a360_sfcrm_data_extract`. This is an internal API, but it's displayed on the details page for the Data Cloud Salesforce Connector permission set. Any scripts that use the retired `sfdc_c360a_sfdctrust_permSet` API name will return 0 after you upgrade to Winter ’25.
- Access to the SurveyQuestionResponse object is controlled by the SurveyResponse object. To enable data ingestion for the Survey object, grant View All Records or Modify All Records permissions for the SurveyResponse object.
- Changes to permission sets in your Salesforce CRM org can impact the default behavior of your data bundles in Data 360.
- To allow users to access tasks and events, enable the Access Activities system permission in the Data Cloud Salesforce Connector permission set.
- **[Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&release=264.0.0&type=5)**
You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.
- **[Enable Permissions for CRM Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_permissions_for_crm_streaming.htm&release=264.0.0&type=5)**
For CRM streaming, set these system and user permissions.
- **[Enable Permissions to Ingest Salesforce Classic Encrypted Salesforce CRM Objects and Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org_encrypted.htm&release=264.0.0&type=5)**
Values in Salesforce Classic custom encrypted fields ingested from connected Salesforce CRM org are masked in Data 360 by default. You can opt to ingest them as unmasked values instead.
- **[Salesforce Commerce Object Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_salesforce_commerce_object_perms.htm&release=264.0.0&type=5)**
When you enable object and field permissions for Salesforce Commerce objects, object names can differ under the connector integration permission sets.
#### See Also
- [_Salesforce Help_: Ingest Classic Encrypted Salesforce CRM Objects and Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org_encrypted.htm&release=264.0.0&type=5 "Values in Salesforce Classic custom encrypted fields ingested from connected Salesforce CRM org are masked in Data 360 by default. You can opt to ingest them as unmasked values instead.")
- [_Salesforce Help_: Add a Source Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_new_source_fields.htm&release=264.0.0&type=5 "After your schema is created in Data 360, you can add source fields to the data stream as needed. When you add a field to an object in a connected Salesforce CRM org, make sure that the correct permissions are set for the field.")
# Salesforce-Enabled Large Language Models
Use a Salesforce-enabled foundation model to power your generative AI experiences with Prompt Builder. Some models use geo-aware request routing to accommodate data residency requirements. As a result, the provider can host their model in multiple regions while working within the boundaries of the Einstein Trust Layer.
### Required Editions
Einstein generative AI is available in Lightning Experience. Setup for Einstein generative AI is available in Lightning Experience. Available in: Enterprise , Performance , and Unlimited Editions with an Einstein for Sales, Einstein for Platform, or Einstein for Service add-on. To purchase the Einstein for Sales, Einstein for Platform, or Einstein for Service add-on, contact your Salesforce account executive.
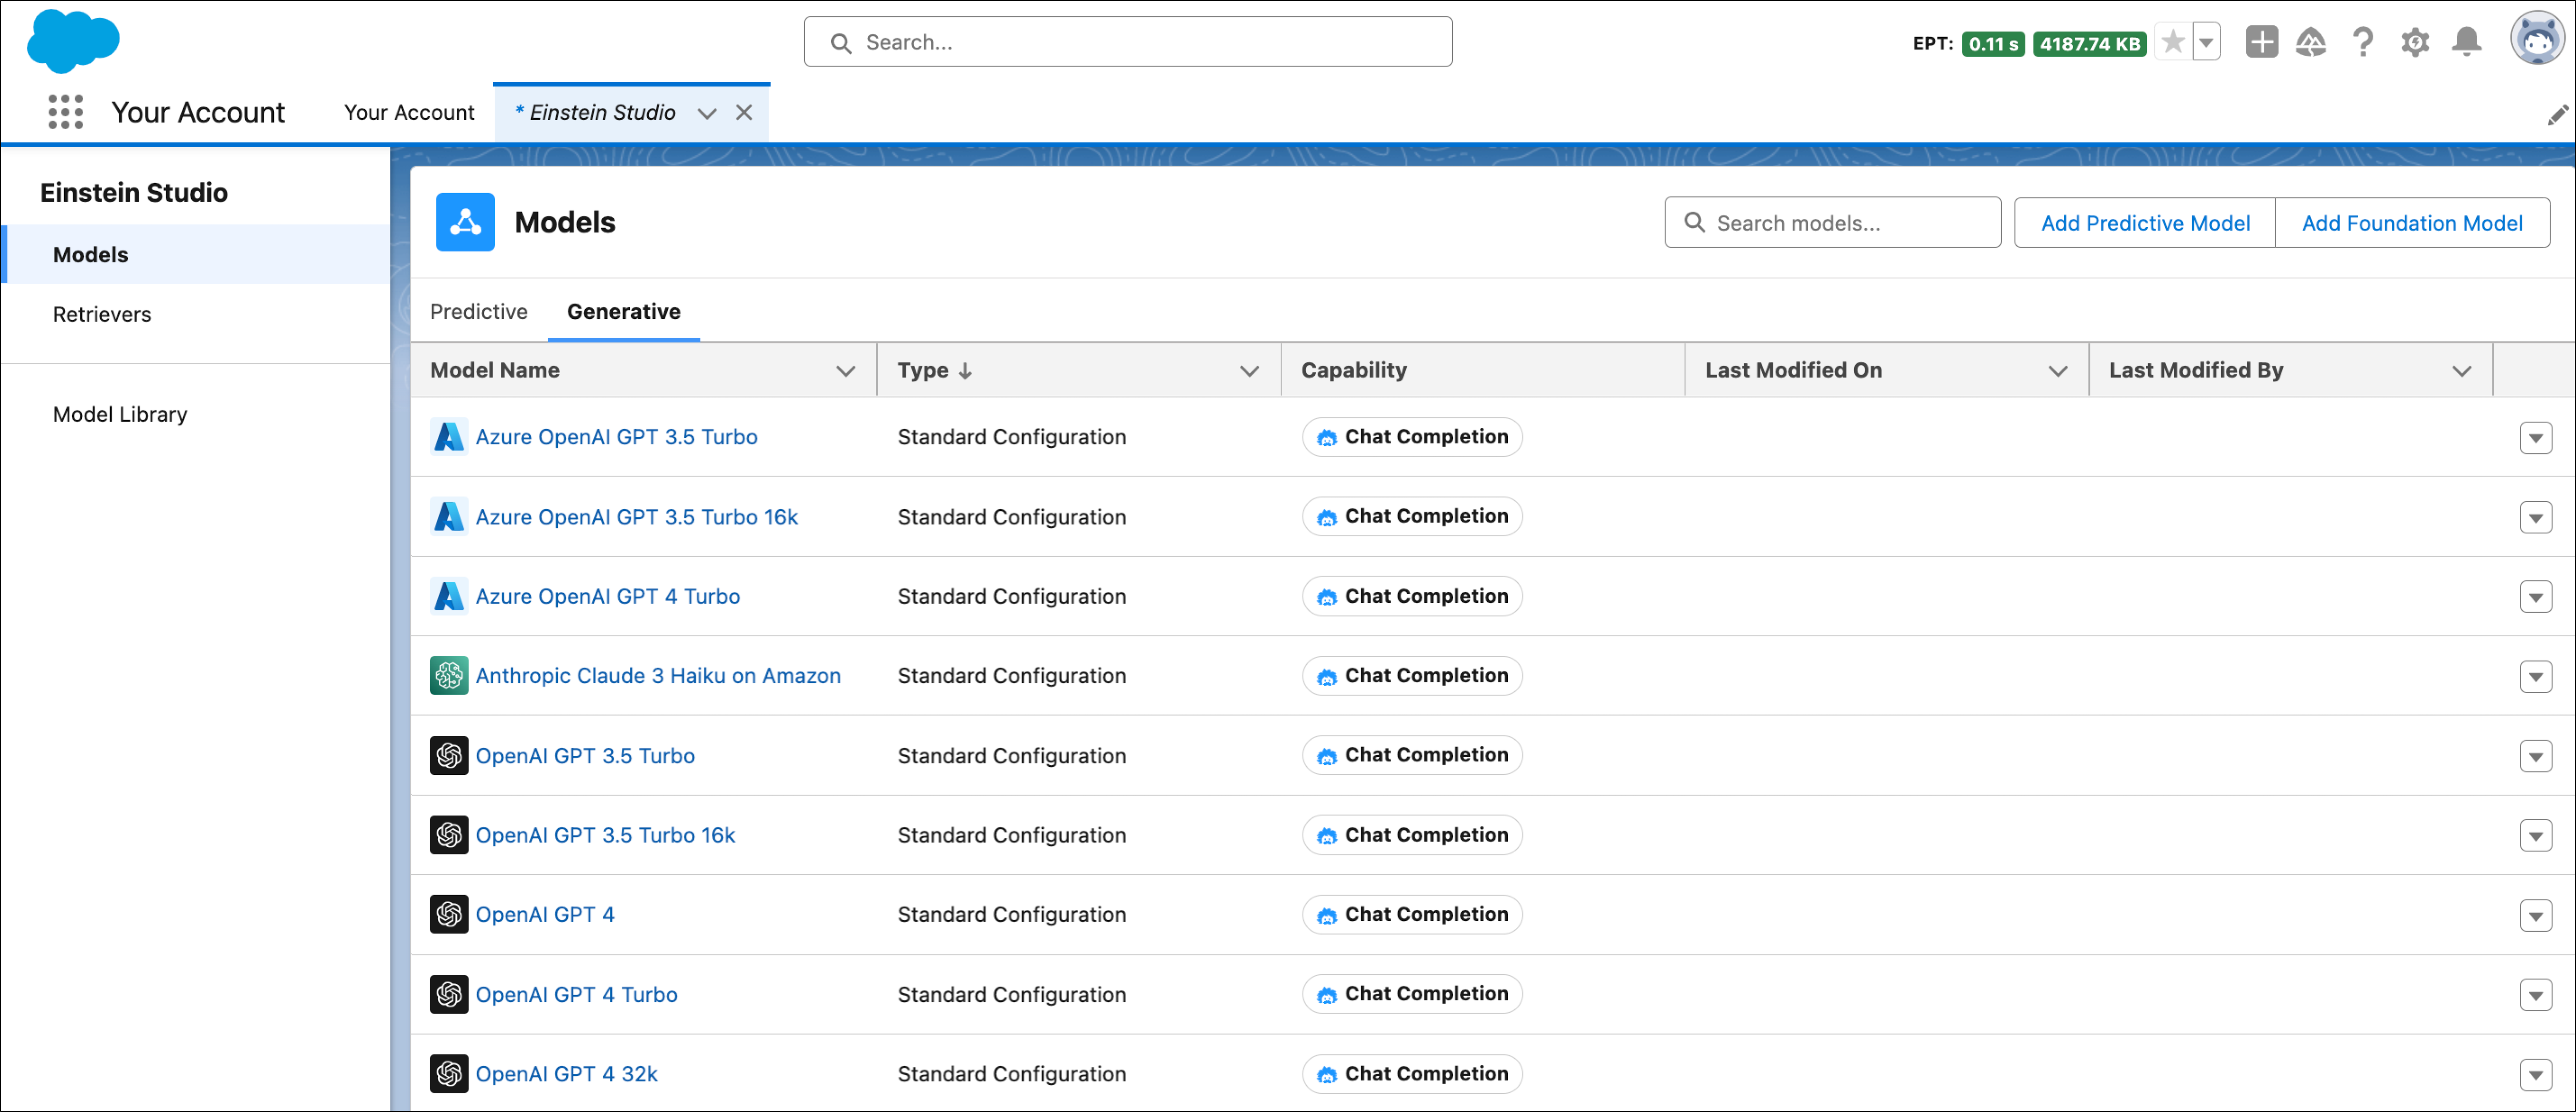
Edit a Salesforce-enabled model (standard configuration). You can then enter a test prompt, adjust one or more hyperparameters, and update the prompt settings based on the results you want to achieve.
#### See Also
- [_Salesforce Help_: Set Up Einstein Generative AI](https://help.salesforce.com/s/articleView?id=ai.generative_ai_enable.htm&type=5&language=en_US)
- [_Salesforce Help_: Large Language Model Support](https://help.salesforce.com/s/articleView?id=ai.generative_ai_large_language_model_support.htm&type=5&language=en_US)
- [_Salesforce Developers_: Supported Models](https://developer.salesforce.com/docs/einstein/genai/guide/supported-models.html)
- [_Salesforce Help_: Geo-Aware LLM Request Routing on the Einstein Generative AI Platform](https://help.salesforce.com/s/articleView?id=ai.generative_ai_platform_geo_aware_routing.htm&type=5&language=en_US)
- [_Salesforce Help_: Create a Prompt Template](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_build_template.htm&type=5&language=en_US)
# Salesforce-Provided Collaboration Templates
Data 360 provides a predefined template to identify segments that overlap. If you’re initiating a collaboration by allowlisting a trusted provider, use the Salesforce-provided collaboration template for the collaboration.
- **[Segment Overlap Use Case Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_segment_overlap_use_case.htm&release=264.0.0&type=5)**
The segment overlap use case helps providers and consumers understand shared audience segments. Consumers can identify overlaps with specific audience segments in the provider database. Providers can demonstrate the value of their audience data. Both parties can plan co-marketing efforts and refine their targeting strategies without exposing raw data.
- **[Activation Use Case Template](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_activation_use_case.htm&release=264.0.0&type=5)**
The activation use case provides consumers with a privacy-first method to activate their first-party audience data through a provider's media or advertising platform. Rather than transferring entire segment lists, consumers identify matched audiences within the clean room. Data 360 writes the matched records directly to the provider's Amazon S3 bucket for use in campaign activation.
# Save an Insight as a Draft
When creating a calculated insight using Insight Builder or SQL Expression Builder, you can save it as draft and continue to make updates until you publish it. You can then validate the calculated insight when you’re ready to deploy it. However, you can’t save an existing calculated insight as a draft while editing it.
### Required Editions
Available in: Lightning Experience
1. In Data 360, on the Calculated Insights tab, click **New**.
2. Select how you want to create the calculated insight.
- **Create with Builder**—If selected, select the required objects, and click **Next**.
- **Create with SQL**—If selected, enter the new insight SQL expression.
3. Save your changes as a draft.
# Schedule a Batch Data Transform
To ensure that the most up-to-date data is available by a particular time or to run a job during non-business hours, schedule a batch data transform.
1. In Data Transforms, from Recently Viewed, click  next to the data transform name, and select **Schedule**.
2. Under Run Mode, click **Scheduled**.
3. Select the frequency and time interval.
- Day Intervals—When you schedule a transform to run at an interval of days, the schedule is based on the first day of the month.
For example, on April 19, you schedule a batch data transform to run every 10 days. From the first day of the month, 10 days ahead is April 11, and 10 days after the 11th is April 21, the first date to occur after the schedule was set on April 19.
The transform runs on these dates: 4/21, 5/1, 5/11, 5/21, and 5/31. On 6/1, the schedule resets on the first day of the month and continues running every 10 days.
- Hourly Intervals—When you schedule a transform to run at an interval of hours, the schedule begins at the start time specified and runs until the end of the day.
For example, at 8 PM, you schedule a batch data transform to run every 4 hours, beginning at 6 PM on each day. The transform starts running on the day that the user creates the schedule at the first interval after 6 PM. The transform runs at these times: 10 PM, 6 PM, and 10 PM.
Even though you created the schedule at 8 PM, the batch data transform runs 4 hours after the defined start time of 6 PM, which is 10 PM. The next day, it runs at 6 PM, followed by a second run at 10 PM. Because the schedule completes at the end of the day, the transform doesn’t run again until the next day at 6 PM.
4. Select the start time and time zone.
If a scheduled run becomes due while the previous run of the same batch data transform is still in progress, that run is skipped, runs never overlap, and the next run proceeds as scheduled.
The scheduled time only determines when a run is queued, not when it starts; depending on concurrency limits and available capacity, the run may actually start slightly after the scheduled time.

Note When you deploy a batch data transform in a data kit, the schedule is included and transfers to the destination org automatically.
# Schedule a Calculated Insight in Data 360
Schedule runs of a calculated insight to keep it up to date with data and process new changes in Data 360.
### Required Editions
When you create a calculated insight, you can specify the schedule, start date and time, and end date. You can automatically process a calculated insight every 1, 6, 12, or 24 hours. To run a calculated insight manually, select the “Not Scheduled” option and publish the insight from the list view.

Tip If you created a calculated insight before the availability of the schedule feature, it runs on the previous system schedule of four times a day.
1. In Data Cloud, on the Calculated Insights tab, click **New**.
2. Select a data space. The data space defines the available objects. Only data spaces you have access to are visible in this list.
3. Select how you want to create the calculated insight.
- Create with Builder
1. Select the required objects.
2. Add the aggregate node and measure.
3. Apply the aggregate node.
4. Click Save and Run.
5. Enter the calculated insight name, and click Next.
Note: This doesn’t start a run of the calculated insight.
- Create with SQL
1. Enter the new insight SQL expression.
2. Click Activate.
4. In Schedule, select how often you want the insight to run.
Note: If a run doesn’t complete before the next scheduled run, the calculated insight skips the next scheduled run.
5. Select the start date and time of the schedule.
Note: If you select a 15-minute time increment, Data 360 updates it to the next 30-minute increment. For example, 4:15 becomes 4:30.
Note: The user's time zone determines the calculated insight schedule.
6. (Optional) Select an end time.
7. Click Enable.
- **[Edit a Calculated Insight Schedule](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_calculated_insight_schedule.htm&release=264.0.0&type=5)**
In Data 360, you can change the schedule of calculated insights that are created with a SQL and the builder.
# Schedule a Secondary Index Refresh
Set how often Data 360 refreshes a secondary index so that the index stays current with the underlying object. Choose a refresh frequency that keeps the index fresh enough for your queries without refreshing more often than your data changes.
Data 360 refreshes each secondary index on a schedule. Secondary index refreshes are incremental and only rebuild the portion of the index affected by changed data, which reduces refresh cost and data freshness lag.
You can set the refresh schedule when you create a secondary index, or update it later for an existing index. Because each refresh consumes credits, refreshing more frequently increases consumption. For more information, see [Billing Considerations for Secondary Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_secondary_index.htm&release=264.0.0&type=5 "Data 360 Secondary Indexes enable faster query performance and more efficient data retrieval with attributes other than the primary identifier. Use of secondary indexes impacts the consumption of credits used for billing in these usage types.").
1. To update the schedule for an existing secondary index, open the index record and choose **Update Schedule**.
2. For **Frequency**, choose how often the index refreshes: **Hourly**, **Daily**, or **Weekly**.
Secondary indexes work best on objects that update at most every 24 hours. For frequently updated objects, refreshing more often can increase cost without improving freshness. For best results, align your refresh schedule with your data update frequency.
3. If you chose **Hourly** or **Daily**, set **Run Every** to the number of hours or days between refreshes.
4. For **Daily Start Time** and **Time Zone**, choose when each refresh runs.
5. If you chose **Hourly** or **Weekly**, select one or more days under **Scheduled Day(s)**.
6. Choose **Save**.
You can change the refresh schedule at any time. Changing the schedule doesn't rebuild the index immediately. The new schedule applies to the next refresh.
# Scheduled and Real-Time Matching in Identity Resolution
Identity resolution can perform two types of ruleset runs: scheduled or real-time. They differ in how and when the two types of ruleset runs are performed, and how they interact with other features.
## Scheduled Matching
Scheduled matching reviews new and updated source data several times in a day using match methods you select. It stores updated unified profile information in the Unified Account or Unified Individual data model object.
Scheduled matching is used the first time your identity resolution ruleset runs. After the first successful run, your identity resolution ruleset is updated incrementally using scheduled matching when data in the primary data model object changes.
You can’t change or control the timing of scheduled matching, but you can turn it off by disabling scheduling.
More match methods are available when scheduled matches are run. Scheduled matching allows you to coordinate a thorough review of your data.
## Real-Time Matching
Real-time matching matches information about an active end user to a unified profile so that you can personalize your app or website within milliseconds. Real-time matching is used whenever customer identity information is received from the real-time personalization process.
Rulesets are run using real-time matching when the ruleset's output object is the primary object for a real-time data graph. In real-time matching, match methods are restricted to Exact or Exact Normalized matching only, regardless of the scheduled match selected for a given match rule. Email addresses and phone numbers can be matched using exact normalized matching, while all other fields are matched using exact matching only.
Once per day, the real-time data graph is updated with unified profiles generated by a scheduled ruleset run. To ensure real-time matching returns swift results, the number of source profiles and engagement events included in a unified profile are limited. Review the Data 360 limits and guidelines for details. Source profiles are prioritized for inclusion based on their value in real-time matching. For example, profiles with recent activity, frequent activity, and with user authentication are prioritized over less-used profiles.
Real-time matching is fast, allowing identity resolution to match your active customer to a unified profile in milliseconds. If the customer identity information isn’t an exact match for an existing unified profile, no matching profile is returned. Data that isn’t matched using real-time matching is reviewed during a scheduled match and could be matched at that time.
## Reconciliation Rules in Real-Time Matching
Identity resolution uses the same reconciliation rules in all modes, regardless of whether match rules are scheduled or real-time.
## Identity Resolution Output for Real-Time Matches
When you’re using real-time matching, identity resolution compares the input value to unified profile records in the ruleset’s related real-time data graph. If an existing customer is identified, these two actions are triggered:
- Real-time insights based on the unified profile are calculated. Results are saved to the real-time data graph record.
- Real-time segments based on the unified profile are built. Segmentation is saved to the real-time data graph record.
# Search Index Reference
Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.
### Required Editions
## Supported Embedding Models
Data 360 supports these embedding models.
| Model | Modality | Max Sequence/Input length |
| --- | --- | --- |
| [E5-large-v2](https://huggingface.co/intfloat/e5-large-v2) | Text | 512 tokens |
| [Multilingual-E5-large](https://huggingface.co/intfloat/multilingual-e5-large) | Text | 512 tokens |
| [SFR-v2-small](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_sfr_v2_small.htm&release=264.0.0&type=5 "The SFR-v2-small embedding model offers an enhanced context window of 8,000 tokens and significantly improves user experience and model capabilities.") | Text | 8,000 tokens |
## Supported Large Language Models
With LLM-based parsing and LLM-based Visual Data Preprocessing you can override the default GPT-4o model to use any supported LLM that best fits your business needs and your content. You can only select LLMs that are approved for use by your admin. If your admin turns off a model that is currently in use, your previously processed content remains accessible. Data 360 supports these Large Language Models (LLMs).
- Anthropic Claude Opus 4.6 Opus on Amazon
- Anthropic Claude Sonnect 4.6 on Amazon
- Google Gemini 3.5 Flash
- GPT 4.o Omni
- GPT 5.4
## Supported File Formats for Unstructured Data
Data 360 supports several file formats for unstructured data and search index configurations. See [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&type=5&language=en_US) for details.
## Supported Operators
Enhance your search queries with pre-filtering fields. Use logical operators and manage case sensitivity for field names and values to ensure precise data retrieval.
Data Type
Supported Operators
Number and Percent
< (Less than)
<= (Less than or equal to)
= (Equal to)
> (Greater than)
>= (Greater than or equal to)
Date and DateTime
< (Less than)
<= (Less than or equal to)
= (Equal to)
> (Greater than)
>= (Greater than or equal to)
Examples:
DateTimeField=''2024-05-21T00:00:00.000Z''
DateField=''2024-05-21''
Timezone can be any standard timezone, such as UTC, PST, or EST, or it can be an
offset, such as +05:30 or -08:00. If you specify no timezone, the system assumes
UTC.
Text, URL, Email, and Phone
= (Equal to)
!= (Not Equal to)
in (‘option1’, ‘option2’, ‘option3’) -> To match any of the listed options.
A maximum of 10 options can be provided.
not in (‘option1’, ‘option2’, ‘option3’) -> To match none of the listed
options. A maximum of 10 options can be provided.
LIKE (example: LIKE ‘d/%’)
Boolean
= (Equal to)
Example: <BooleanField>=true
## Search Index Considerations
Note these limitations when working with search indexes.
- Search index supports only UTF-8 encoding. Multilingual content must use UTF-8 encoding.
- Search indexes are not supported in Developer Edition orgs if namespaces are enabled in those orgs.
- If you’re creating a search index for unstructured data that you’ve connected from an external blob store to Data 360, ensure that you have set up a file notification pipeline on your blob store.
- A DMO that has mappings from one or more external DLOs can only be used as the data source if caching is enabled for all those external DLOs. For more information see, [Caching in Data Federation.](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&type=5&language=en_US)
- Search Indexes don't support date and datetime fields for chunking. Only Text data type fields are available for chunking data.
- Modifying data space filters on a Data Lake Object (DLO) after creating a search index on the associated Data Model Object (DMO) doesn't automatically update the search index. The index keeps data indexed under the old filter criteria, even if that data no longer qualifies. Only new or modified records that the system processes after the filter change reflect the updated criteria. To make sure that your search index accurately reflects the current data space filters, rebuild the index. To reprocess all records with the updated filter criteria, from the search index detail page, click Rebuild.
- Civilian Government Cloud environments support enriched indexes, but defense Government Cloud environments don't.
- **[Search Index Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_types.htm&release=264.0.0&type=5)**
Understand the differences in how search index types are managed in Data 360.
- **[SFR-v2-small Embedding Model Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_sfr_v2_small.htm&release=264.0.0&type=5)**
The SFR-v2-small embedding model offers an enhanced context window of 8,000 tokens and significantly improves user experience and model capabilities.
# Search Index Types in Data 360
Understand the differences in how search index types are managed in Data 360.
Search Index Type
Built In
Managed In
Supported Search Functionality
Documentation
Hybrid Search
Data 360 Data 360 Search Index tab
Directly query Chunk data model objects (DMOs) and Index DMOs.
Rebuild action is available.
Process history is available.
Salesforce Help: Create a Hybrid Search Index
with Advanced Setup
Vector Search
Data 360 Data 360 Search Index tab
Directly query Chunk DMOs and Index DMOs.
Rebuild action is available.
Process history is available.
Salesforce Help: Create a Vector Search Index
with Advanced Setup
Agentic Data Library (ADL) Index
Agentforce Data Library in Setup
Data 360 Search Index tab
With file-based search indexes created through ADL after August 2026:
Chunk/Index DMOs are no longer directly queryable (SELECT * query returns 0
rows). But a scoped search query is possible. See the troubleshooting guide next
for details.
Rebuild action isn't available.
The citation field is empty.
Process history is available.
No changes to the knowledge based ADL indexes.
No changes to ADL
indexes on Government Cloud and Data Cloud One configurations.
Existing
file-based ADL indexes aren’t automatically migrated to the new index
method.
## Troubleshooting Search Indexes Created Through ADL
There are three ways to make sure that files uploaded through ADL were successfully indexed:
- The file status column in ADL UI indicates successful upload and indexing.
- The Records Processed metric and Status label in the **Process History** tab for the search index in Data360.
- A search query scoped by SourceRecordId\_\_c. To get the SourceRecordId\_\_c for a given file, query the source unstructured data model object (UDMO) the SearchIndex was built on, filtered by its FilePath field.
```
SELECT Chunk__c
FROM vector_search(
TABLE(ADL__index__dlm),
'test something',
'SourceRecordId__c=''/''',
100
)
```
# Secure Your Data with Data Spaces
Logically segregate your data using Data Spaces so that different brands, regions, or business units can operate independently within the same Salesforce Data 360 instance. This segregation ensures that users access only the data that belongs to the Data Space they’re assigned to. Control access to data spaces with permission sets. By default, users with standard permission sets are granted access to the default data space. Create additional permission sets and customize which data spaces they’re associated with to change how users can view, update, or manipulate data in your org’s data spaces.
- **[Associate a Permission Set with a Data Space](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_associate_perm_sets.htm&release=264.0.0&type=5)**
When Data Cloud is enabled, the default data space is associated with standard Data Cloud permission sets, except the Data Cloud Architect. To give access to other data spaces, change the data space permission set that it’s associated with or create a permission set.
- **[Manage Feature Access for Data Space-Aware Data Cloud Features](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_feature_access.htm&release=264.0.0&type=5)**
By default, Data Cloud standard permission sets control access to Data Cloud features with preset object permissions. You can further restrict feature access within each data space assigned to a permission set by changing the data space’s feature permissions.
# Segment Activations to Ad Audiences Partner Platforms
Activate audience segments to Ad Audiences partner platforms for targeting advertising campaigns to known customers.
### Required Editions
Data 360 supports audience segment activations to these partner platforms.
- [Amazon Ads](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-amazonadsadaudiences-connector.html)
- [Google Ads](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-googleadsadaudiences-connector.html)
- [Google DV360](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-googledv360adaudiences-connector.html)
- Google Ads Manager
- [LinkedIn Campaign Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-linkedinadaudiences-connector.html)
- [Meta Ads Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-metaadaudiences-connector.html)
- [Pinterest Business Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-pinterestadaudiences-connector.html)
- [Snapchat Ads Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-snapchatadaudiences-connector.html)
- [TikTok Ads Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-tiktokadaudiences-connector.html)
- [LY Ads Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-lyadsadaudiences-connector.html)
- [Reddit Ads Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-redditadaudiences-connector.html)
After the initial activation, segment activations support incremental refresh.
**Considerations**
- Match rates on platforms depend on the quality and completeness of identity signals that you map during activation. Mapping extra attributes such as location, phone number, and device IDs increases match rates.
- Each platform enforces a minimum audience size for segments. This minimum limit applies to the matched audience count and not the segment size. If the matched audience is lower than the platform's requirement, Data 360 sends the segments to the platform, but the platform doesn't target that segment in campaigns. For example, TikTok requires a minimum of 1000 total matched users per segment. So, if you activate a segment with 5000 records to TikTok, TikTok targets the members of your segment only if they can match at least 1000 records from your segment to the users on their platform.
- After the initial activation, subsequent updates are activated incrementally by default. Incremental segment activations run on the segment's refresh schedule and include add, update, and delete signals. See [Activation Refresh Types](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_publish_types.htm&type=5&language=en_US).
- Full refresh resends the entire segment to prevent audience expiration on platforms that enforce time to live (TTL) restrictions. You can also use full refresh to handle major mapping changes or segment updates. In certain platforms, full refresh results in a delete-all-then-refill process, and in others it just resends the complete current segment membership without deleting anything.
- If you add activation filters after the initial publish, Data 360 applies the filter criteria to future incremental updates only. In other words, adding activation filters to an activated segment doesn't filter out profiles already sent to the platform. To update your segment after it's activated, edit the segment membership or create an activation to make sure that the audience segment reflects the updated filter.
- Activating to multiple platforms requires a separate activation per platform, even when you're activating the same segment.
- Creating and activating audiences consumes Segmentation and Activation credits.
- You can't duplicate an activation target in a data space. Choose a different data space or account ID.
## Company List Activation
Activate dynamic company-level audience lists to Ad Audiences partner platforms. Use this type of activation for B2B targeting by segmenting at the company level instead of individual users.
Data 360 currently supports [LinkedIn Campaign Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-linkedinadaudiences-connector.html#company-list-activation) only for company list activation.
**Considerations**
- Build your segments on account data. Segments built on individual data aren't compatible with company list activation.
- Use the same activation target for both user segment activation and company list activation.
- Map optional attributes such as city, state, and country to improve the accuracy of matches between your list and company records.
## Anonymous Audiences
Activate audience profiles based on pseudonymous identifiers rather than personally identifiable information (PII). Google Ads and Google DV360 support activating segments of website visitors by using first-party cookie IDs synced with their platforms. In Pinterest, you can activate audiences by using mobile advertising ID (MAID) only. If you select this option, you can target mobile device users without requiring other identifiers, such as email ID or phone number.
Use these activations to retarget both known and unknown users based on observed web browsing behavior.
# Segment Canvas
Use the segment canvas in Data 360 to select direct and related attributes to narrow down a created segment to your target audience.
## Steps
Drag Attributes from the library to your canvas to set filter criteria for your segment. You can drag attributes into their own container or combine them with other attributes in the same container to create an AND or an OR relationship between the attributes. From the Direct tab, you can select Data Model Objects (DMOs) that have a 1:1 or a N:1 relationship from the Segment On object (on some path). From the Related tab, you can select DMOs that have a 1:N relationship from the Segment On object (on some path). The library displays all object types including standard or custom objects as long as the objects are mapped.
## Relationships
Attributes in the library can have multiple relationships to other objects. When an object has multiple relationships to the same object, the library displays both the object name and the related field names for easier differentiation when building a segment.
If an object has multiple relationships to itself through nesting, the attribute library displays only the object nested beneath itself one time.
Match and reconciliation rules guide the DMO graph and determine the DMOs that are displayed in the attribute library. When match and reconciliation rules are configured for an individual DMO, derived relationships are generated between the target entity DMO and the unified individual DMO. These derived relationships are traversable, and individual DMOs along with paths with derived relationships appear in the attribute library.
Object relationships in a container path are applied in a case-sensitive manner. Data 360 supports one case-sensitive method of joining data tables that’s not configurable. The values of the linked records must match exactly. For example, if the value of SalesOrder.SoldToCustomer is c12d3, and the value of Individual.IndividualId is C12D3, the records don’t link up because the case of the two values doesn’t match.
## Direct Attributes
A direct attribute is a single data point or piece of information about the entity being segmented, such as a postal code, first name, or birthday. Direct attributes are often demographic attributes.

Example
1:1 Relationship
- First Name: Each customer has one first name.
- Birthday: Each customer has one birthday.
N:1 Relationship
- Employees to Department: Multiple employees can belong to one department.
- Orders to Customer: Multiple orders can be placed by one customer.
## Related Attributes
A related attribute is a collection of multiple data points or pieces of information associated with the entity being segmented, such as purchase history, product numbers, or email interactions. Related attributes are often behavioral or engagement events.
## Value Field
The value against which the attribute value is compared to determines whether it satisfies the condition. Queries honor exact matching on special characters and accents and aren’t case-sensitive. For example, querying on City | Is Equal To | Canon City doesn’t find the city Cañon City. A query on City | Is Equal To | Canon City finds canon city. Also, queries honor exact matching on types. For example, if the field type is a string for "Purchase Order Number", querying on Purchase order number | Is Equal To | 0852 finds a Purchase Order Number that’s equal to 0852. It doesn't find the purchase order number 852, which has no leading zero, or “0852” with quotation marks.
## Segment Count
The segment count indicates the number of entities based on the filters applied. When the segment target is Individual or Unified Individual, then the count also excludes any Individual profiles where a Data Deletion or Restrict Processing request has been submitted. For more information, see [Data Subject Rights](https://help.salesforce.com/s/articleView?id=data.c360_a_data_subject_rights.htm&release=264.0.0&type=5 "A customer’s data subject rights, such as those granted to them by the European Union’s General Data Protection Regulation (GDPR), relate to the storage and usage of their personal data. Data 360 offers tools to support your consumer’s data subject rights in alignment with various data protection and privacy regulations.").
Segment count isn’t applicable for dynamic segments if parameterized values are enabled. The segment population is empty for a dynamic segment with attributes where parameterized values are enabled.
Filter level count is available on direct attribute filters. It shows the segment population attributed to that filter (for example, for Segment On Individual, a filter Gender = Female shows the distinct count of individuals whose gender is female). No count is shown when you first add a filter; the ribbon shows **Calculate population**. Refresh to run the count. Counts are explicit and follow the same approximate population behavior as segment count when that option is enabled.
Container level count is available on related attribute filters (containers). It shows the segment population attributed to that container (for example, for Segment On Individual, a container with “at least one sales order has Product Line = Luxury watches AND Shipping City = California” shows the distinct count of individuals who have at least one such order). No count is shown when you first add a container; the ribbon shows **Calculate population**. Refresh to run the count. Counts are explicit and follow the same approximate population behavior as segment count when that option is enabled.
## Primary Key and Foreign Key
A primary key is an object’s unique identifier of a record, such as a customer email address or a product SKU. A foreign key is a field in a table that refers to the primary key of another table. The foreign key links two data tables based on a data point, for example, a customer ID.
Primary key and foreign key attributes don’t appear in the segment canvas. To make these attributes available in the attribute library, create a custom attribute without assigning it as the primary or foreign key. Use this custom attribute when building segments.
- **[Segment Your Data with Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_segmentation_interface.htm&release=264.0.0&type=5)**
After you create a segment, narrow your data based on related or direct attributes on the segment canvas interface. Narrow down a subset of the population from a filtered audience to see who’s included and excluded. Segment exclusion is optional.
- **[Filtering Using Containers and Attributes](https://help.salesforce.com/s/articleView?id=data.c360_a_container_basics.htm&release=264.0.0&type=5)**
On the segmentation canvas, you can define rules to filter your population to a targeted group. You can create and combine filters in different ways for different results. When you define a filter using a related attribute, a container is added to the canvas with applicable rule options. The related attribute’s data model object (DMO) becomes the container object.
- **[Approximate Segment Population](https://help.salesforce.com/s/articleView?id=data.c360_a_approximate_segment_population.htm&release=264.0.0&type=5)**
When building a segment in Data 360, use the Approximate Segment Population field to quickly check that the segment count meets your expectations. The approximate count provides an estimated segment population, represented as a range of possible values with 95% confidence. When the segment population is small, or when the record count for Segment On is low, the actual population can differ from the estimated range. You can then adjust your segment rules and save your segment to get the final segment population. To use this feature, enable Approximate Segment Population in Feature Manager.
- **[Segmentation Operators in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_datatype_expression_operators.htm&release=264.0.0&type=5)**
For each attribute dragged to the segment canvas from the attribute library, select an operator to modify it and limit records that are selected. The operators that are available depend on the data type of the attribute.
- **[Segment Time Zone](https://help.salesforce.com/s/articleView?id=data.c360_a_update_segment_time_zone.htm&release=264.0.0&type=5)**
Segment publish schedules are interpreted in the user's time zone. Your Data 360 org sets the publish time zones on the initial segment save and segment canvas. Segment and activation fields display the Publish Schedule Start Date and Time in the user's time zone.
- **[Use Value Suggestions in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_suggested_values_in_segments.htm&release=264.0.0&type=5)**
You can enable value suggestions for data model object (DMO) fields if the data type is Text. Enable or deactivate the feature in the DMO record home. You can enable value suggestions for up to 500 attributes for your entire org. It can take up to 24 hours for suggested values to appear.
- **[Multiple Identity Resolution Rulesets in Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_in_segments.htm&release=264.0.0&type=5)**
Compare the impact of different identity resolution rulesets for the same entity on segment population counts. After using identity resolution to create different rulesets for the same entity, entities and attributes created by both rulesets are available in segmentation. Use attributes from both rulesets to validate, or A/B test, different population counts. Entities and attributes names include the Ruleset ID at the end when you select what entity to Segment On or add attributes in the attribute library.
- **[Multiple Marketing Cloud Engagement Business Units in Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_business_units_in_segments.htm&release=264.0.0&type=5)**
Filter segments by business unit (BU) to determine the true size of segments for campaign planning. If segments aren’t filtered by business unit, the difference between a Data 360 segment population and Marketing Cloud Engagement data extension count can be significant.
#### See Also
- [_Salesforce Help_: Data Mapping](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping.htm&release=264.0.0&type=5 "Data ingested by all data streams is written to data lake objects (DLOs). After creating your data streams, you must associate your DLOs to data model objects (DMOs). Only mapped fields and objects with relationships can be used for Segmentation and Activation.")
- [_Salesforce Help_: Using Consent Preferences in Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_using_consent_preferences_in_segmentation.htm&release=264.0.0&type=5 "Learn more about how to use consent preferences in segmentation in Data 360.")
# Segment Membership Data Model Object
Each time you publish a segment, a data model object (DMO) is created or updated to store segment membership information. To identify who's included in a segment, use the Segment Membership DMO (type Segment\_Membership). If there are no dependencies on the DMO, you can delete segment membership DMOs manually.
Each object that you build a segment on has a set of membership DMOs across all segments using it. The latest segment membership shows the profile IDs included in the latest segment publish. The history segment membership shows the profile IDs included in the previous segment publish from the last 30 days. When a publish starts and a segment member no longer satisfies the segment criteria, the member is removed from the segment membership table.
Object Name
API Name
Category
Objectname - Latest
Objectname_SM__dlm
Example: Individual_SM__dlm
SEGMENT_MEMBERSHIP
Objectname - History
Objectname_SMH__dlm
Example: Individual_SMH__dlm
SEGMENT_MEMBERSHIP
You can interact with segment membership data in three ways.
- To verify the segmentation results, view the data in Data Explorer.
- To find insights in a business dashboard, interact with the data in Tableau.
- Query the segment membership DMO using SOQL, Query APIs, or the segmentation REST API.
- **[Segment Membership DMO Schema](https://help.salesforce.com/s/articleView?id=data.c360_a_segment_membership_dmo_schema.htm&release=264.0.0&type=5)**
The segment membership DMO has these object-level and field-level schema attributes. These fields are available in the latest and history segment membership DMOs.
- **[View Segment Members in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_membership_data_data_explorer.htm&release=264.0.0&type=5)**
After publishing your segment in Data 360, you can validate the segment membership in Data Explorer.
- **[Query Data in Data Model using Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_membership_data_data_model.htm&release=264.0.0&type=5)**
Download your segment membership data in Data 360 and then analyze in Tableau.
- **[Query Data using SOQL](https://help.salesforce.com/s/articleView?id=data.c360_a_membership_data_soql.htm&release=264.0.0&type=5)**
In Data 360, you can analyze segment membership data using SOQL in Data Explorer.
#### See Also
- [_Salesforce Help_: Manage Data 360 Objects and Field Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_model_object.htm&release=264.0.0&type=5 "Edit or remove objects and field mappings associated with a data model object (DMO) or data lake object (DLO). Manage mappings and objects to ensure data accuracy and maintain the integrity of your data model.")
# Segment Membership DMO Schema
The segment membership DMO has these object-level and field-level schema attributes. These fields are available in the latest and history segment membership DMOs.
Object Attribute
Value
Examples
Object Label
Dynamically generated
'[SegmentOnProfileDMOLabel] - [Member DMO Type]'
Individual - Latest
Unified Individual - History
API Name
Dynamically generated
'[SystemGeneratedDMOName]_[DMOType]__dlm'
Individual_Unified_SM_dlm
Individual_Unified_SMH__dlm
Category
SEGMENT_MEMBERSHIP
–
Type
Segment_Membership
–
Field Attribute
Field API Name
Data Type
Description
Id
Id__c
Text
Foreign key to the identifier of the segment-on profile DMO (for example,
Individual.Id__c)
Key Qualifier Id
KQ_Id__c
Text
Key qualifier of the Segment On target object
Segment Id
Segment_Id__c
Text
ID of the processed or published segment
Snapshot Type
Snapshot_Type__c
Text
Method used to evaluate membership (F = Full Snapshot)
Delta Type
Delta_Type__c
Text
The Delta Type is available only for the history segment membership DMO and compares
whether a member was added, removed, or persisted between the previous and most recent
publish events.
New–The profile wasn’t in the previous snapshot.
Existing–The profile was included in the previous snapshot.
Removed–The profile is no longer a member of the segment but was present in the
previous snapshot.
Timestamp
Timestamp__c
DateTime
Date and time when the segment was last run
Version Stamp
Version_Stamp__c
DataTime
Version of the segment definition at the time of the last run
# Segment On
Segment On defines the target object used to build your segment. You can choose an object marked as Profile or Engagement type during ingestion. For example, you can build a segment on Unified Individual, Unified Household, Account, Reservations, Sales Order, etc.
The target object chosen determines which attributes are available in the attribute library that you can use as segment filters.
## Unified Individual or Individual
To take advantage of Identity Resolution, use the Unified Individual as your segment target. With Identity Resolution, you can segment on profile, behavioral, and transactional data from disparate data sources as one Unified Individual.
If you have data from multiple data sources in Data 360, Identity Resolution and segmenting on the Unified Individual is recommended. If you aren’t using Identity Resolution, use Individual as your segment target.
You can consolidate Unified Individuals into groups of individuals called households. Segment on Unified Household to identify households with specific criteria.

Note Segmenting on the Individual instead of the Unified Individual can result in duplicate or skipped entities in your count.
#### See Also
- [_Salesforce Help_: Group Individuals into Households](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_households.htm&language=en_US)
- [_Salesforce Help_: Match Rules for Households](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_match_rules_households.htm&language=en_US)
- [_Salesforce Help_: Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.")
- [_Salesforce Help_: Unify Source Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_source_profiles.htm&release=264.0.0&type=5 "Use identity resolution in Data 360 to consolidate data from different sources into comprehensive views of your customers and accounts. Identity resolution uses matching and reconciliation rules to link data about people or accounts into unified profiles. Identity resolution creates complete, actionable views of your customers but doesn’t create golden records and isn’t a master data management (MDM) system. Each unified profile contains all the unique contact point values from all sources. You choose which view of your customers to use based on each business use case you want to solve.")
# Segment Overlap Use Case Template
The segment overlap use case helps providers and consumers understand shared audience segments. Consumers can identify overlaps with specific audience segments in the provider database. Providers can demonstrate the value of their audience data. Both parties can plan co-marketing efforts and refine their targeting strategies without exposing raw data.
The segment overlap use case template contains these parameters.
| Parameter | Value |
| --- | --- |
| Party Contributing Data | Both |
| Required Attributes | Segment Name, Individual ID, Hashed Email Address, or Contact Point |
| Optional Attributes | Segment Parent Category |
| Query Type | Count Overlap by Segment |
| Query Run By | Consumer |
| Result Type | Aggregated Counts |
| Aggregation Threshold | Minimum 100 matched individuals |
| Result Received By | Consumer |
| Results Stored In | Output DMO on the Consumer’s Side |
| Privacy Measures | Private Join, Query Limits, Aggregation Threshold |
For example, a sports gear company (Consumer A) is collaborating with a TV network (Provider B) to understand viewership data for certain sports tournaments. Consumer A wants to run the segment overlap query on these user segments.
- Football fans
- Basketball fans
- Cricket fans
For each segment, Consumer A brings these mandatory attributes into the clean room: segment ID, individual ID (member ID), and email address. The email address, which is hashed to protect privacy, is used as the primary key.
Provider B associates the same attributes for its user segments for the sporting events that it broadcasts. Consumer A runs the segment overlap query for each of its segments against the provider's segments to find out which audience has the most overlap.
Here are the results when Consumer A runs the query on the football fans segment. The report shows that Provider B’s “Behind-the-scenes followers’” segment has the highest overlap with Consumer A’s football fans segment.
| Parent Category | Provider Segment Name | Overlap Count | Provider Segment Size | Overlap Rate |
| --- | --- | --- | --- | --- |
| Viewer Behavior | Behind-the-scenes followers | 45,200 | 248,000 | 18.2% |
| Streaming Genre | Sports and action | 39,850 | 172,000 | 16.1% |
| Demographics | Adults 35–54 with kids | 33,300 | 198,000 | 13.4% |
| Purchase Intent | Sports merchandise buyers | 30,125 | 124,000 | 12.1% |
| Viewer Behavior | Morning news routine viewers | 28,770 | 102,000 | 11.6% |
| Platform Preference | Mobile app | 26,310 | 145,000 | 10.6% |
| Lifestyle | Upscale urban professionals | 24,480 | 85,000 | 9.8% |
The overlap scores are aggregated for each segment to preserve privacy. The generated reports are stored in an output DMO. If Consumer A collaborates with other providers on the same use case within the same data space, all the reports are stored in the same output DMO.

Note The Parent Category and Provider Segment Size columns are visible only if the provider includes the parent category and Segment Size fields.
# Segment Time Zone
Segment publish schedules are interpreted in the user's time zone. Your Data 360 org sets the publish time zones on the initial segment save and segment canvas. Segment and activation fields display the Publish Schedule Start Date and Time in the user's time zone.
The Salesforce org time zone still applies to other segmentation behavior, such as date-based operators like Last 'n' Days.
Updates made to your Salesforce org's time zone aren't reflected in existing segments.
## How Time Zone Changes Apply to Segments
Newly created segments follow the updated time zone. To update the time zone of an existing segment, resave the segment.

Note The save action is triggered only when specific payload fields change. A change to any one of these fields triggers a segment update request: Name, Description, Include Criteria, Exclude Criteria, Publish Schedule Start Date and Time, Publish Schedule Interval, Publish Schedule End Date, Publish Schedule Info, or Lookback Period. A change to the time zone alone doesn't trigger an update.
## How Daylight Saving Time Affects Publish Schedules
Scheduled segment publishes preserve the local wall-clock time that you chose, even when the clocks change for daylight saving time (DST). Your segment continues to publish at the same local time before, during, and after the clock change. You don't need to adjust your schedule when the clocks change. This behavior applies to any time zone that observes DST, including US, European, and Southern Hemisphere zones. If your time zone doesn't observe DST, your segment runs at the same time every day.
## Publish Behavior When Clocks Spring Forward
On the spring-forward day, one hour is skipped and doesn't exist in local time. If a scheduled run lands inside that missing hour, that single run is skipped and publishing resumes at the next scheduled time.
- Daily schedules: If your chosen time falls in the missing hour, that day's run is skipped and the next day's run occurs at your chosen time.
- Hourly or every-few-hours schedules: Only the run in the missing hour is skipped. Other runs that day aren't affected.
- Weekly and monthly schedules: A run that lands in the missing hour is skipped. The next scheduled run occurs in the following week or month at the same local time.
## Publish Behavior When Clocks Fall Back
On the fall-back day, one hour occurs twice in local time. To prevent duplicate publishes, a run that lands in the repeated hour runs only once.
- Hourly or every-few-hours schedules: The run in the repeated hour publishes once, not twice. Publishing continues normally afterward.
- Weekly and monthly schedules: A run that lands in the repeated hour publishes once.
## Daylight Saving Time Behavior by Schedule Type
| Schedule Type | Spring Forward | Fall Back |
| --- | --- | --- |
| Daily | Skips the run if the scheduled time is in the missing hour. | Runs once at the scheduled local time. |
| Every 12 hours | Skips a run in the missing hour. The interval continues. | Runs once for a run in the repeated hour. |
| Hourly or every few hours | Skips a run in the missing hour. The interval continues. | Runs once for a run in the repeated hour. |
| Weekly | Keeps the same day and local time each week. Skips a run in the missing hour. | Keeps the same day and local time each week. Runs once for a run in the repeated hour. |
| Monthly | Keeps the same local time each month. Skips a run in the missing hour. | Keeps the same local time each month. Runs once for a run in the repeated hour. |

Example
You schedule the segment publish start time for 1:00 PM EST (UTC-5) with a 24-hour interval. That same absolute time is 10:00 AM PST (UTC-8). If the Salesforce org time zone is later changed from EST to PST, the publish still occurs at the same absolute instant, so it appears as 10:00 AM PST, not 1:00 PM PST.
For a DST example, you schedule a daily publish for 3:00 AM in a time zone that observes DST. On the spring-forward day, 3:00 AM exists as normal because the missing hour is typically 2:00 AM to 3:00 AM, so the run happens at 3:00 AM. If you had instead scheduled the publish for 2:30 AM, that run is skipped on the spring-forward day because 2:30 AM doesn't exist that day. Publishing resumes at 2:30 AM the following day. On the fall-back day, your 3:00 AM run publishes once.
#### See Also
- [_Salesforce Help_: Change Time Zones](https://help.salesforce.com/s/articleView?id=data.c360_a_time_zones.htm&release=264.0.0&type=5 "Data 360 uses the time zone set in Salesforce when publishing and refreshing segments and activations. The dates and times added to a segment in the segment canvas also use the Salesforce time zone. To change the time zone for Data 360, change the time zone in Salesforce.")
# Segment Types and Statuses
Learn more about the values provided about each segment. View details in the Segments section of Data 360, or in Publish History for a specific segment. Depending on how you create the segment, the type can be UI (created via the Segment Builder) or DBT (created via the API).
## Segment Status
The Segment Status field provides details about your segment. If you don’t get an updated status and population count after saving the segment or after a couple of minutes, click the dropdown menu and select **Update Status**.
| Segment Status | Definition |
| --- | --- |
| Active | Segment created and all segment functionality available |
| Processing | Publishing segment in progress |
| Recounting | Recounting the segment population in progress |
| Error | Segment is active but can’t be manually published |
| Inactive | Segment can only be deleted |
## Publish Status
The Publish Status field provides details on the segment’s publishing status to the activation target.
| Publish Status | Definition |
| --- | --- |
| Success | Segment published successfully to the activation target |
| Error | Segment failed to publish, contact Salesforce Customer Support for help |
| Skipped | Publishing the segment is temporarily delayed for 30 minutes due to the maximum number of segments publishing simultaneously |
| Publishing | Publishing segment in progress, segment data from last publish is available until publishing is complete |
| Blank (No Status) | Segment was created but not published |
| Deferred | Segment publish time is pushed out due to exceeding the maximum number of simultaneous publishes |
## Publish Schedule
The Publish Schedule determines when and how often your segment publishes to an activation target.

Important Make sure all segments with a preset publish schedule also have an activation. Segments require a publish schedule and an activation to be sent to an activation target.
| Publish Schedule | Definition |
| --- | --- |
| Don’t refresh | Segment not published to activation targets |
| 1 hour | Segment published every hour (Marketing Cloud Engagement and file storage targets) |
| 4 hours | Segment published every 4 hours (Marketing Cloud Engagement and file storage targets) |
| 12 hours | Segment published every 12 hours |
| 24 hours | Segment published every 24 hours |
## Next Publish Date Time
The Next Publish Date Time for a segment is an estimate and can change depending upon concurrency limits and how many segments are in progress for publishing. A manual segment publish takes priority over a scheduled publish.
## Publish Type
Segments are either published on a schedule using the Publish Schedule or manually by clicking Publish Now for a segment.
Publish Type
Definition
Scheduled
Segment was published using a standard schedule of every 12 or 24 hours
Segment was published using a rapid segment schedule of every 1 or 4 hours (Marketing
Cloud Engagement only)
Manual
Segment was published on demand by clicking Publish Now for the segment
## Platform
The Platform column provides details about the activation target where the segment was published.
| Platform | Definition |
| --- | --- |
| CC | Segment published to a B2C Commerce activation target |
| Ecosystem | Segment published to an External Activation Platform activation target |
| Marketing Cloud Personalization | Segment published to a Marketing Cloud Personalization (formerly Interaction Studio) activation target |
| Loyalty | Segment published to a Data 360 activation target |
| SFMC | Segment published to a Marketing Cloud Engagement activation target |
| S3 | Segment published to a Cloud File Storage (Amazon S3) activation target |
#### See Also
- [_Salesforce Help_: Review Publish History of Your Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&release=264.0.0&type=5 "Activation record home in Data 360 shows activation outcomes in one place. The activation record home includes activation details, linked activation-triggered flows, and activation history. From this page, you can validate configuration, open related flows, and monitor publish results.")
- [_Salesforce Help_: Create Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_add_activation_target.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Segment Your Data with Attributes
After you create a segment, narrow your data based on related or direct attributes on the segment canvas interface. Narrow down a subset of the population from a filtered audience to see who’s included and excluded. Segment exclusion is optional.
### Required Editions
Permission Sets Needed
Add attributes to segments:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. Click the **Segments** tab, and select the segment from the list.
2. Click **Edit Rules**.
3. Click the **Include** or **Exclude** tab.
Each tab can have up to 50 filters.

Note Aggregations in general count toward the limit of 50 filters.
4. To see how each filter or container affects the segment, use the count in the ribbon below that filter or container. For more information, see [View Filter and Container Level Counts](https://help.salesforce.com/s/articleView?id=data.c360_a_view_filter_count.htm&release=264.0.0&type=5 "Use the population counts displayed in the ribbon under each filter or container to evaluate their impact on your segment. Filter-level counts apply to direct attributes; container-level counts apply to related attributes (containers). Counts are available on both the Include and Exclude tabs.").
5. To generate a filter population breakdown, click **Generate Population Breakdown**. For more information, see [Generate a Filter Population Breakdown for Your Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_generate_filter_population_breakdown.htm&release=264.0.0&type=5 "See the individual and cumulative impact of each Include and Exclude filter before you activate the segment."). To open the latest report, click **View Population Breakdown**.
6. From the attributes list, drag attributes to the segment canvas. If you don't find the attribute you're looking for, type the name of the attribute in the Search text box. Results appear as you enter the search terms. If the attribute you need is in more than one DMO, all the results show up. Choose the one you want to add to the segment filter. The left pane displays the path as you select attributes, ensuring you’re including attributes from the intended objects.
For dynamic segments, to provide values to an attribute during execution time, select Enable parameterized values.

Note When searching for attributes, only first-level attributes from related objects are visible by default. To access deeper-level DMO attributes, first find the main object in the DMO that contains the attributes you want. For example, in the Sales Order Product DMO, the main object is Product. If you need a deeper-level attribute such as Product Description, drag any attribute from that main object into the canvas to create a container (you can cancel without saving), then search again; the deeper-level attributes appear in the search results.
Each segment can have up to 100 attributes.
You can add criteria to these attributes.
- Direct Attributes—Each DMO being segmented on has only one data point such as postal code or first name.
- Related Attributes—Each DMO being segmented on has multiple data points such as purchases, product characteristics, or email events.
- Calculated Insights—Search for calculated insights by name or find them under the object referenced in the SQL. You can use only processed calculated insights in a segment.

Note Calculated insights with boolean measures are not currently supported in segmentation. Using a calculated insight with a boolean measure in your segment criteria causes a population error. This behavior is expected and affects all segment types. To ensure your segments show the correct population, use calculated insights with other supported data types.
7. To create more complex filters, add AND or OR nested operators.
You can nest up to three levels of attributes. For example, you want to run a promotion for customers who have purchased either $5000 or more on products or a total of 20 products over the last month. With nested operators, you can layer your filter logic to target both sets of customers over the specified time frame. You can nest filters up to three levels within a container. Across containers, you can nest filters up to ten levels.
8. (Optional) Click **Preview** to sample your segment results and verify your attribute rules before saving.
Segment preview uses random sampling, so you may see different results each time you click **Preview**. This is expected behavior. Preview results aren't deterministic. If you notice anomalies, review your segment rules and container configurations.

Note Segment preview is enabled by default. To use segment preview, you need segment view or edit rules permissions and access to Data Explorer.
9. After adding each attribute or calculated insight, click **Done**.
If Approximate Segment Population is enabled, you can get an estimate of the population count to validate your segment rules. The approximate segment population is calculated by using a sample of your profile dataset. Before saving your segment with the final segment population, ensure that the segment count meets your expectations. If necessary, update it by using the approximate count as a guideline.
10. To save your canvas and recount your population, click **Save**.
1. Total Population—Overall set of entities available in the segment.
2. Included Population—Total number of entities that qualified for your include criteria minus the entities that qualified for the exclude criteria.
3. Excluded Population—Total number of entities that qualified for your exclude criteria within the segment entities.

Note Use the Population Recount arrow to show the revised population count. This action uses Data Query type data service credits. Depending on the segment size, the count sometimes takes up to 15 minutes to refresh.
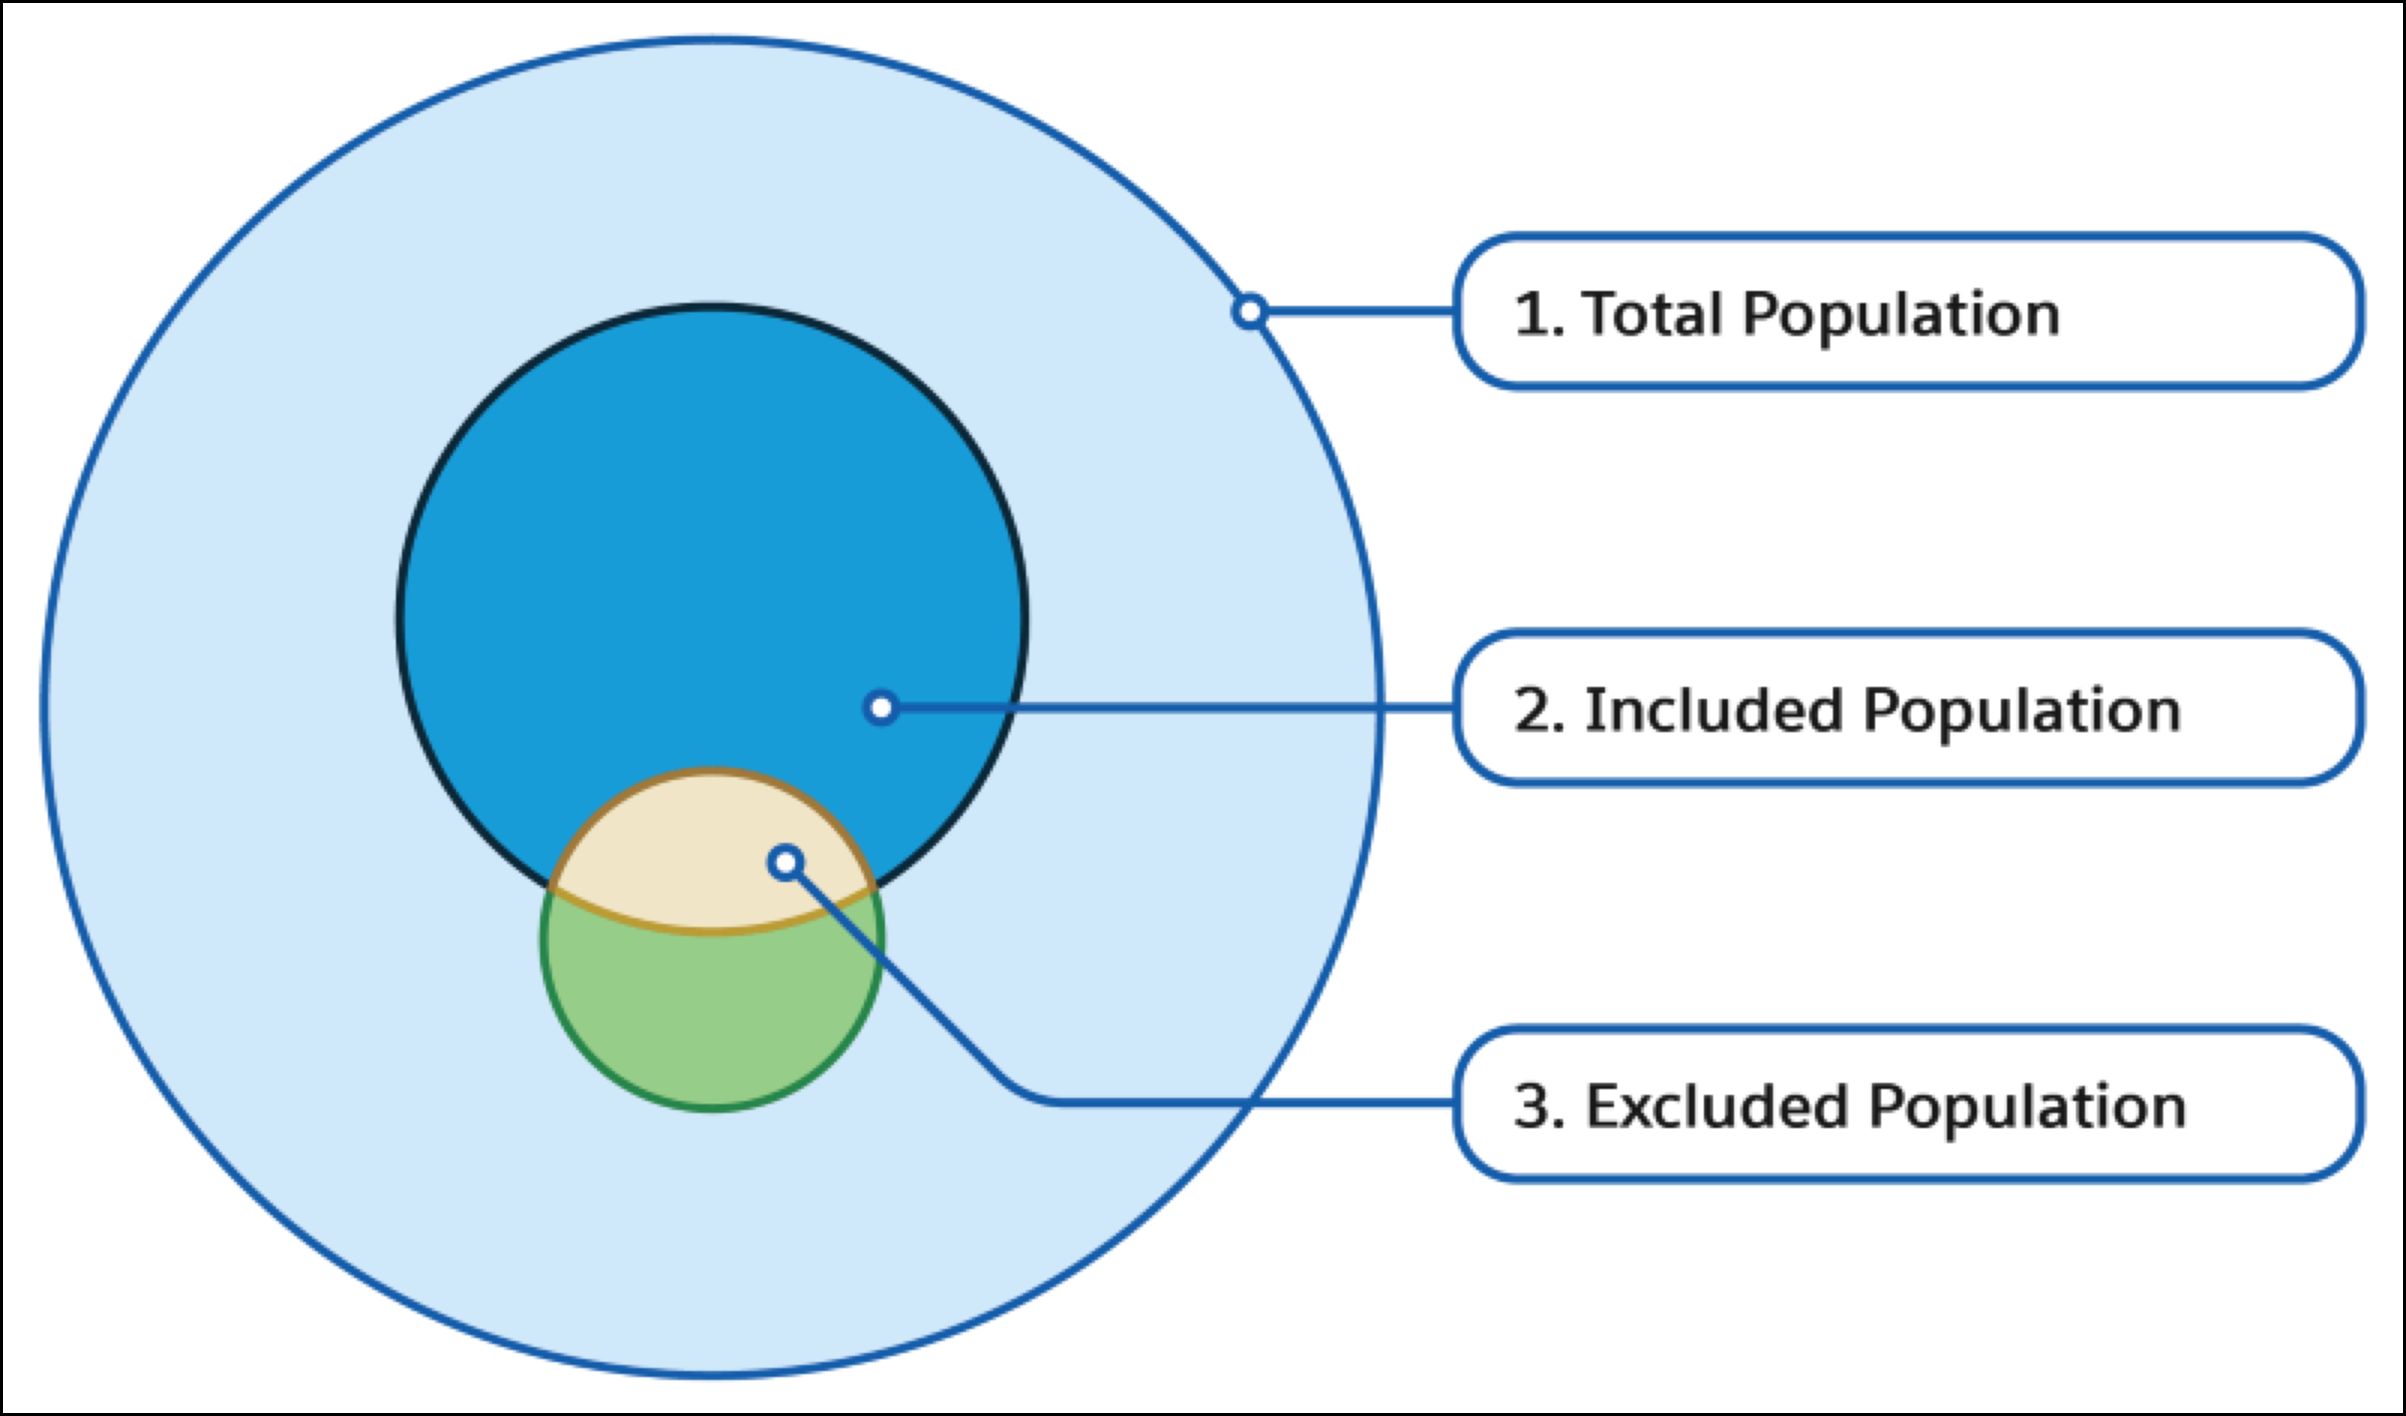
11. Click **Done**.
- **[Create a Nested Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_nested_segments.htm&release=264.0.0&type=5)**
Reuse filters and maintain consistency in your data by using an existing segment built on profile objects to build a new nested segment. A nested segment is a combination of an outer segment and inner segment. Each nested segment can have up to 50 filters in each tab.
- **[Generate a Filter Population Breakdown for Your Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_generate_filter_population_breakdown.htm&release=264.0.0&type=5)**
See the individual and cumulative impact of each Include and Exclude filter before you activate the segment.
#### See Also
- [_Salesforce Help_: Formulas, Operators, and Calculated Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_formulas__operators__and_calculated_insights.htm&release=264.0.0&type=5 "Create audiences in different ways and at different stages of your workflow using formulas, operators, and calculated insights in Data 360. During ingestion, you can use formulas to perform operations on row-based data used downstream. For segmentation, audiences are created with segment operators.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Enable Data 360 Features](https://help.salesforce.com/s/articleView?id=data.c360_a_feature_manager.htm&release=264.0.0&type=5 "You can enable Data 360 features using the Feature Manager. This screen is visible only when there are one or more features to enable or disable.")
- [_Salesforce Help_: Approximate Segment Population](https://help.salesforce.com/s/articleView?id=data.c360_a_approximate_segment_population.htm&release=264.0.0&type=5 "When building a segment in Data 360, use the Approximate Segment Population field to quickly check that the segment count meets your expectations. The approximate count provides an estimated segment population, represented as a range of possible values with 95% confidence. When the segment population is small, or when the record count for Segment On is low, the actual population can differ from the estimated range. You can then adjust your segment rules and save your segment to get the final segment population. To use this feature, enable Approximate Segment Population in Feature Manager.")
# Segmentation Filter Examples
Review examples of filters for various types of segmentation use cases. Use these examples as a starting point for your segments, which you can tailor by adding more filters to fit your campaigns.
- **[Sales and Order Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_b2c_commerce_engagement_filters.htm&release=264.0.0&type=5)**
Here are some examples of common purchase order and service use cases.
- **[Campaign Engagement Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_campaign_engagement_filters.htm&release=264.0.0&type=5)**
Here are some examples of common campaign engagement use cases.
- **[Einstein Engagement Score Filters in Data 360 Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_einstein_filters.htm&release=264.0.0&type=5)**
Here are some examples of common Einstein Engagement Score use cases.
- **[Email Engagement Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_email_engagement_filters.htm&release=264.0.0&type=5)**
Here are some examples of common email engagement use cases.
- **[Loyalty Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_miscellaneous_filters.htm&release=264.0.0&type=5)**
Here are some examples of common loyalty use cases.
- **[Purchases Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_purchases_filters.htm&release=264.0.0&type=5)**
Here are some examples of common purchases use cases.
- **[SMS Engagement Filters](https://help.salesforce.com/s/articleView?id=data.c360_a_sms_engagement_filters.htm&release=264.0.0&type=5)**
Here are some examples of common SMS engagement use cases.
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Marketing Cloud Engagement Data Bundle Information](https://help.salesforce.com/s/articleView?id=data.c360_a_mc_bundle_data_categories.htm&release=264.0.0&type=5 "When ingesting data from Marketing Cloud Engagement, Data 360 creates data streams and data lake objects (DLOs) for each starter bundle, along with schema and mappings to data model objects (DMOs).")
- [_Trailhead_: Data 360 and the Ethical Use of Data](https://trailhead.salesforce.com/users/mcguide2/trailmixes/customer-360-audiences-and-the-ethical-use-of-data)
# Segmentation Filters vs. Activation Filters
Segmentation and activation use different filters for different purposes. Apply filters to a segment to narrow your audience. Use activation filters to narrow down relevant values with related attributes that personalize messages.
For example, as an online retailer, you want to run an email campaign targeting your customers that have purchased video games in the past 2 months. You want to personalize the message by including the product name of the video game that the customer most recently purchased.
Begin the process in segmentation by applying filter criteria to narrow your audience to customers who have purchased video games in the past 2 months.
In activation, add the Product Name related attribute to include the product names of the items that the customers have purchased. However, during the past 2 months, customers could have made other purchases in addition to video games. To include only video game purchases in the email, apply a filter to the attribute, such as **Product Category is equal to Video Games**. If you don’t apply a filter to the attribute, other products that the customer has purchased are included in the email.
#### See Also
- [_Salesforce Help_: Segmentation Filter Examples](https://help.salesforce.com/s/articleView?id=c360_a_examples_of_segmentation_filters.htm&type=5&language=en_US)
# Segmentation Operators in Data 360
For each attribute dragged to the segment canvas from the attribute library, select an operator to modify it and limit records that are selected. The operators that are available depend on the data type of the attribute.
## Date
Date operators use your Salesforce org time zone.
Date Operator
Data Returned
Is Anniversary Of
Finds audience members for attributes where the day and month match today's
date and month.
Is Not Anniversary Of
Finds audience members for attributes where the day and month don’t match
today's date and month.
Is Today
Finds audience members for attributes where an event occurs between 00:00:00 AM
and 23:59:59 PM on today's date.
Is Yesterday
Finds audience members for attributes where an event occurred between 00:00:00
AM and 23:59:59 PM on yesterday's date.
Is Tomorrow
Finds audience members for attributes where an event occurs between 00:00:00 AM
and 23:59:59 PM on tomorrow's date.
Is Between
Finds audience members for attributes where an event occurred between 00:00:00
AM on the first date specified and 23:59:59 PM on the last date specified.
Is This Month
Finds audience members for attributes where an event occurs in the current
calendar month.
Is Next Month
Finds audience members for attributes where an event occurs in the next
calendar month.
Is Last Month
Finds audience members for attributes where an event occurred in the last
calendar month.
Is On
Finds audience members for attributes where an event occurs on a specified
date.
Is Before
Finds audience members for attributes where an event occurs before a specified
date.
Is After
Finds audience members for attributes where an event occurs after a specified
date.
Last Year
Finds audience members for attributes where an event occurred in the previous
calendar year.
This Year
Finds audience members for attributes where an event occurs in the current
calendar year.
Next Year
Finds audience members for attributes where an event occurs in the next
calendar year.
Last Number Of Days
Finds audience members for attributes where an event occurs in the last number of
days until the current day and time.
For example, a value of 2 returns events that occurred between February 5, 2020
at 00:00:00 AM and February 7, 2020 at 06:00:00 AM for a segment recounted on
February 7, 2020 at 06:00:00 AM. The filter finds all events for February 5,
February 6, and until the second that the segment population is recounted on
February 7.
Greater Than Last Number Of Days
Finds audience members for an attribute where an event occurs before the number
of days specified until the beginning of the current day.
For example, a value of 7 finds all events that occurred before February 1, 2020
at 00:00:00 AM for a segment recounted at any time on February 8, 2020.
Next Number Of Days
Finds audience members for an attribute where an event occurs from the current
day and time until the end of the next number of days.
For example, a value of 2 returns events that occurred between February 5, 2020
at 06:00:00 AM and February 7, 2020 at 11:59:59 PM for a segment recounted on
February 5, 2020 at 06:00:00 AM. The filter finds all events for February 6,
February 7, and starting from the second that the segment population is recounted
on February 5.
Last Number Of Months
Finds audience members for an attribute where an event occurs in the last number
of full months.
For example, a value of 2 for a segment recounted on March 15, 2020 at 06:00:00
AM returns all events that occurred between January 2020 and February 2020.
Next Number Of Months
Finds audience members for an attribute where an event occurs in the next number
of full months.
For example, a value of 2 for a segment recounted on March 15, 2020 at 06:00:00
AM returns all events from April 2020 and May 2020.
Last Number of Years
Finds audience members for an attribute where an event occurs in a calendar
year. Enter the number of years to go back to and search for segments for that
particular year. This date operator applies only to Calculated Insights.
For
example, a value of 5 for a segment recounted in 2025 returns all events that
occurred between January 2020 and December 2020.
Day Of Week
Finds audience members for attributes where an event occurs on the day of the
week specified in the filter.
Day Of Month
Finds audience members for attributes where an event occurs on the day of the
month specified in the filter.
Not Day Of Month
Finds audience members for attributes where an event didn’t occur on the day of
the month specified in the filter.
Month Of The Year
Finds audience members for attributes where an event occurs in the month of the
year specified in the filter.
Not Month Of The Year
Finds audience members for attributes where an event didn’t occur in the month
of the year specified in the filter.
Before Day Of Month
Finds audience members for attributes where an event occurs before the day of
the month specified in the filter.
After Day Of Month
Finds audience members for attributes where an event occurs after the day of
the month specified in the filter.
Has Value
Finds audience members for attributes where the value is not
Null .
Has No Value
Finds audience members for attributes where the value is
Null .

Note For dynamic segments, parameterized values aren’t supported for these Date operators: DAY\_OF\_WEEK, DAY\_OF\_MONTH, NOT\_DAY\_OF\_MONTH, BEFORE\_DAY\_OF\_MONTH, AFTER\_DAY\_OF\_MONTH, NOT\_MONTH\_OF\_YEAR, and MONTH\_OF\_YEAR
## Numeric
The percent data type is included within numeric operators. All numeric operators apply to percent.
| Numeric Operator | Data Returned |
| --- | --- |
| Has Value | Finds audience members for attributes where the value is not Null or Empty. |
| Has No Value | Finds audience members for attributes where the value is Null or Empty. |
| Is Equal To | Finds audience members for attributes with a value equal to a specified value. |
| Is Not Equal To | If a record containing a field with a `Null` value is referenced in an Is Not Equal To segment filter, the record isn’t included in the segment population. To include the record, configure a filter in the segment to check if the field Has No Value. Then add the Has No Value and Is Not Equal To filters within an Or block. |
| Is Less Than | Finds audience members for attributes less than the value specified. |
| Is Less Than or Equal To | Finds audience members for attributes that are less than or equal to the value specified. |
| Is Greater Than | Finds audience members for attributes that are greater than the value specified. |
| Is Greater Than or Equal To | Finds audience members for attributes that are greater than or equal to the value specified. |
| Is Between | Finds audience members for attributes that are between a start and end data. |
| Is Not Between | Finds audience members for attributes that are outside of the range between a start and end date. |
## Text
URL, phone, and email are data types included within text operators. All text operators apply to these data types.

Note Case sensitivity doesn't apply to the Has Value and Has No Value text operators. All other text operators are case-insensitive.
| Text Operator | Data Returned |
| --- | --- |
| Has Value | Finds audience members for attributes where the value is not Null or Empty. |
| Has No Value | Finds audience members for attributes where the value is Null or Empty. |
| Is Equal To | Finds audience members for attributes with a value equal to a specified value. |
| Is Not Equal To | If a record containing a field with a `Null` value is referenced in an Is Not Equal To segment filter, the record isn’t included in the segment population. To include the record, configure a filter in the segment to check if the field Has No Value. Then add the Has No Value and Is Not Equal To filters within an Or block. |
| Contains | Finds audience members for attributes that contain the value specified. This operator ignores null values. |
| Does Not Contain | Finds audience members for attributes that don't contain specified values. This operator ignores null values. |
| Matches | Finds audience members for attributes by using regular operator patterns to sift and match against data. For example, if your attribute contains TestSearch, then the operator matches any data that has the substring TestSearch in it, including TestSearch Results and TestingSearching. |
| Doesn’t Match | Finds audience members for attributes that don’t match a certain regular operator pattern. |
| Begins With | Finds audience members for attributes that begin with a specified value. |
| Exists As A Whole Word | Finds audience members for attributes if the provided parameter exists as a whole word in a statement. It checks whether the text exists as a word (group of chars delimited by word boundaries) in the target field. For example, hello exists as a whole word in hello world but not hel. |
| Is Not In | Finds audience members for attributes that don’t match a set of values. You can select up to 100 values for the Is Not In operator. You can enter comma-separated values such as Product1, Product2, Product3. If Value Suggestion is enabled, you can choose values from the dropdown list. |
| Is In | Finds audience members for attributes that match a set of values. For example, Gender Is In (F, Female). You can manually enter or paste up to 100 comma-separated values, such as Product1, Product2, Product3. If Value Suggestion is enabled, you can choose values from the dropdown list. You can also use the bulk import option to paste up to 10,000 comma-separated values. Value Suggestion isn’t available for the bulk import method. Segments can include only one `Is In` operator with up to 10,000 values. |
## Boolean
| Boolean Operator | Data Returned |
| --- | --- |
| Has Value | Finds audience members for attributes where the value is not Null or Empty. |
| Has No Value | Finds audience members for attributes where the value is Null or Empty. |
| Is True | Finds audience members for attributes where the value is not Null or Empty, and the value Is True. |
| Is False | Finds audience members for attributes where the value is not Null or Empty, and the value Is False. |
# Sensitive Data Classification in Data 360
Classifying data helps ensure it’s handled appropriately, securely, and in line with regulatory or internal standards. You can classify data by considering both its sensitivity (how confidential it is) and its usage (how and by whom it’s accessed or used).
## Classify Data Based on Sensitivity
To classify data by sensitivity, start by figuring out how much damage can happen if the data were shared, used incorrectly, or lost. You can group data into four sensitivity levels.
- **Public:** This data poses no risk if shared openly. Examples include product brochures and published reports.
- **Internal:** Company data that can include team lists or internal rules. It isn't harmful if it’s leaked, but it isn't meant for the public to see.
- **Confidential:** This data can include customer records or internal financials. If exposed, it causes significant harm and requires stronger controls.
- **Restricted or Highly Sensitive:** This data contains personal health information, credit card numbers, or trade secrets and demands the most stringent protections due to legal or business risk.
Refer to regulatory frameworks like General Data Protection Regulation (GDPR), Health Insurance Portability and Accountability Act (HIPAA), or (Payment Card Industry Data Security Standard) PCI-DSS to define and guide your sensitivity classifications.
## Classify Data Based on Usage
To classify data by usage, review who uses the data, how often, and why. For example, data for company-wide reports is different from data used in transactional systems or for customer service. Consider if the data is actively used, archived, or can be deleted. Organizing data helps you set the right security rules, like who can access it and for how long, ensuring it's managed properly based on its purpose.
- **[Classification Tags in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_assigning_classification_tags.htm&release=264.0.0&type=5)**
Classifications provide additional context and meaning within a taxonomy. They allow you to categorize data based on predefined criteria such as sensitivity or intended use, making it easier to manage, protect, and use data appropriately.
- **[Create a Classification in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_classification.htm&release=264.0.0&type=5)**
In Data 360, define sensitivity or usage levels to categorize data and drive governance policies such as masking and access control.
- **[Edit or Delete a Classification in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_classification.htm&release=264.0.0&type=5)**
Edit the name and description of a classification, manage its associated tags, or delete it if no longer needed. You can't delete classifications that are used in policies. This includes default classifications provided by Data 360.
# Sentiment Analysis
Use sentiment analysis in Data 360 to evaluate unstructured text and learn how customers feel about your brand, product, or service. For each record, such as a customer review or survey response, the model assigns a positive, negative, or neutral label and a confidence score. To filter audiences, build dashboards, and trigger automations, apply the model outputs.

Note
All sentiment analysis models and algorithms use the new runtime.
## Use Cases
Forecasting supports various use cases.
TYPE USE CASE WHAT DOES IT SOLVE Marketing Refine Campaigns To improve messaging, analyze sentiment in campaign responses. Segment Audiences Target promoters, neutrals, and detractors differently. Track Brand Perception Monitor how campaigns impact sentiment over time. Service Prioritize Cases Identify and escalate negative sentiment quickly. Improve Support Quality Analyze sentiment in interactions to coach reps. Reduce Churn Detect unhappy customers early and trigger recovery actions. Sales Deal Health Scoring To gauge deal momentum, analyze sentiment in emails, call transcripts, and meeting notes. Pipeline Prioritization Focus on opportunities with sentiment that improves or remains consistently positive. Upsell and Cross-Sell Identify satisfied customers with positive sentiment as strong expansion candidates.
## Considerations
Before you apply a sentiment analysis model, review these considerations.
- Use clean, relevant text data, such as customer reviews or case comments.
- Combine sentiment with other data, such as behavior or demographics, for better insights.
- Analyze trends over time rather than individual results.
## Limitations
Before you use sentiment analysis, review these limitations.
- Short, vague, or highly technical text is difficult to interpret.
- Sarcasm and nuanced language affect accuracy.
- Results depend on the quality and context of the input data.
# Session Extension in Real-Time Data Graphs
To maintain consistency between a real-time data graph and a standard data graph, session extension preserves your data for a longer period while the standard graph updates.
### Required Editions
Available in: Lightning Experience
This ensures you won't lose any valuable information at the end of a session. Session extension can sometimes delay the availability of lake house updates in your real-time data graph. Additionally, by keeping your data graph fresh, you can trust that the information you see is always up-to-date and accurately reflects the latest changes in your data sources. This is achieved through an automated update process that periodically refreshes the data graph. These updates occur in the background and minimize disruption to your ongoing sessions.
#### See Also
- [_Salesforce Help_: Record Caching and User Session Length in Real-Time Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_record_caching_in_rt_data_graphs.htm&release=264.0.0&type=5 "Configure your real-time data graph to manage the number of records held in the cache and user session length.")
# Set a Currency for a Batch Data Transform
To use currency values in a data transform, set a currency. Otherwise, data remains unchanged. This setting converts data with multiple currencies to a single value. For example, if your data includes GBP and USD and you set the currency to USD, then GBP values automatically convert to USD for use in the transform.
1. In a batch data transform that has at least one input node, from Settings, select **Set Currency**.
2. Select a currency from the dropdown of possible currencies.
Currency values from input nodes convert to the selected currency.
3. Click **Save**.
Data preview reflects the new currency setting.
# Set a Default Reconciliation Rule
Set a default reconciliation rule for each object in your identity resolution ruleset. The default reconciliation rule tells the identity resolution process how to select values for all fields in an object.
1. Navigate to the record home page of your identity resolution ruleset.
2. Select an object.
3. To edit the default reconciliation rule for the object, click .
4. Select a reconciliation rule from the dropdown menu.
5. Optionally, select **Ignore Empty Values**.
Identity resolution ignores the Ignore Empty Values selection for key fields.
6. If you're using Source Priority to select a value, order the data sources so that the highest priority source is at the top of the list. The value selected for the unified field is the value that appears in the highest priority data source.
7. Click **Save**.
#### See Also
- [_Salesforce Help_: Override an Object’s Default Reconciliation Rule](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules_setfieldspecific.htm&release=264.0.0&type=5 "Override an object’s default reconciliation behavior by applying a reconciliation rule to a specific field.")
# Set Actionable Variables
In Model Builder, actionable variables are fields that can you can change to influence a model's predicted outcome. Setting actionable variables enables the model to provide prescriptions (suggested actions that a user can take to improve an outcome).
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In AI Models (formerly Einstein Studio), go to the Predictive Models tab.
2. Click your model.
To get predictions and prescriptions, make sure that the model is activated.
3. From the model, click the Integrations tab to set variables for prescriptions.
4. Click the **+** icon to search for and select the fields you want to set as actionable variables.
5. Select variables that are likely to influence the predicted outcome. Model Builder suggests prescriptions based on the variables you set here.
Set at least one actionable variable to get prescriptions from the model.
6. Click **Apply**.
# Set Object Sharing Access for Salesforce CRM
Sharing access for certain objects, such as QuickTextUsage and MacroUsage, are set to Private by default. To ingest these objects into Data 360, change the organization-wide access to Public.
### Required Editions
User Permissions Needed
To set default sharing access
System admin profile OR
Data Cloud Architect permission set
1. From Setup, in the Quick Find box, enter Sharing Settings, and then select **Sharing Settings**.
2. Click **Edit** in the Organization-Wide Defaults area.
3. Set the Default Internal Access of the object to **Public Read Only**.
# Set Output Name for Activation Attributes
When you configure an activation in Data 360, you can customize the attribute names in your output file or stream. Custom attribute names help match the naming conventions required by your activation target. Use the output namefield ( preferred name) to define these values.
By default, the Output Name field shows the API name of the attribute with system prefixes and suffixes removed. To override the default API name, enter a custom preferred value in the Output Name field. Data 360 uses this value as the column header or field name in the activation output.
The output names must be unique across all attributes in the activation, including attributes from different data model objects (DMOs). Output names can contain only alphanumeric characters.
#### See Also
- [_Salesforce Help_: Create Activation for a Segment](https://help.salesforce.com/s/articleView?id=data.c360_a_add_activation_target.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
- [_Salesforce Help_: Create a Marketing Cloud Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation_target.htm&release=264.0.0&type=5 "To publish segments and batch data model objects (DMO) to Marketing Cloud Engagement business units, create an activation target in Data 360.")
# Set Up a B2C Commerce Connection
After you create your Data 360 instance, you can set up a B2C Commerce Connection. Then you can control the scope of data ingestion from B2C Commerce. The B2C Commerce connector only supports connections to production instances of B2C Commerce.
### Required Editions
User Permissions Needed
To create a connection
System admin profile OR
Data Cloud Architect permission set
Before beginning, log in to B2C Commerce and have the URL that you use to log in to Business Manager accessible.
1. From Data Cloud Setup, select **B2C Commerce** under Salesforce Integrations.
2. To import data from a B2C Commerce instance, click **New**.
3. Log out of all Business Manager instances that you’re logged in to.
4. In a new tab, log in to the Business Manager instance that you’re using for the B2C Commerce connection.
5. Return to the Data Cloud tab.
6. In the Sync With B2C Commerce Business Manager dialog, enter the URL that you use for Business Manager, without the trailing forward slash.
7. Click **Next**.
8. To allow Data 360 to connect to the B2C Commerce instance and access all its data, click **Allow**.
9. Select the sites that you want to ingest data from, and click the right arrow.
The selection appears under Selected Sites.
You can now create a data stream for the connected B2C Commerce instance.
- **[Add or Remove B2C Commerce Site Selections](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_site_selection_commerce_cloud_connector.htm&release=264.0.0&type=5)**
In Data 360, you can change which sites B2C Commerce ingests data from after you have set up a connection. Make sure that there’s a B2C Commerce connection before editing the sites.
- **[Disconnect a B2C Commerce Instance Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_cloud_instance_connection.htm&release=264.0.0&type=5)**
You can delete a connection to your B2C Commerce instance. Removing the connection stops data ingestion from your B2C Commerce instance to Data 360.
#### See Also
- [_Salesforce Help_: Disconnect a B2C Commerce Instance Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_cloud_instance_connection.htm&release=264.0.0&type=5 "You can delete a connection to your B2C Commerce instance. Removing the connection stops data ingestion from your B2C Commerce instance to Data 360.")
# Set Up a Connection to Marketing Cloud Personalization
After you create your Data 360 instance, connect to Marketing Cloud Personalization (formerly Interaction Studio) to enrich customer profiles with user profile data and events.
### Required Editions
User Permissions Needed
To connect to Marketing Cloud Personalization:
Admin permission in Marketing Cloud Personalization
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect
Set up Marketing Cloud Personalization before connecting with Data 360. After that's set up, follow these steps in Data 360 to connect the two.
1. From **Setup**, select Data 360 Setup.
2. From Salesforce Integrations under Marketing, select **Marketing Cloud Personalization**.
3. To connect to a new account, click **New** or **Connect**.
4. Enter your Marketing Cloud Personalization credentials and click **Log In**.
5. To grant access to your account for Data 360, click **OK**.
6. To select datasets for integration, click **Edit** next to your account name.
7. Select which datasets you want to integrate. These datasets are available for data modeling, segmentation, and activation.

Note Datasets can be used in only one Data 360 account. Datasets already connected don’t show on your available list. Also, unselected datasets aren't included in your Data 360 instance for ingestion or activation.
8. Click **Save**.
Your Marketing Cloud Personalization account is connected for use in Data 360.
#### See Also
- [_Salesforce Help_: Marketing Cloud Personalization Connector](https://help.salesforce.com/s/articleView?id=data.c360_a_interaction_studio_connector.htm&release=264.0.0&type=5 "With Marketing Cloud Personalization (formerly Interaction Studio) data in Data 360, you can ingest user profiles and behavioral events to enrich the customer profile and increase personalization. The connector also lets you use Marketing Cloud Personalization as an activation target.")
- [_Salesforce Help_: Integrate Personalization with Data 360](https://help.salesforce.com/s/articleView?id=mktg.mc_pers_salesforce_cdp.htm&type=5&language=en_US)
- [_Salesforce Help_: Create a Marketing Cloud Personalization Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_mc_personalization_activation_target.htm&release=264.0.0&type=5 "To publish segments to Marketing Cloud Personalization (formerly Interaction Studio), create an activation target in Data 360.")
# Set Up a CRM Salesforce Org Connection
A data source and data action target are automatically created for the org where you set up Data 360. To connect other Salesforce orgs, manually set up a connection.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect

Important Prevent users from logging in to your org via your instanced URL. On the My Domain page in Setup, select **Don’t redirect** for Instanced URL in the [redirections](https://help.salesforce.com/s/articleView?id=xcloud.domain_name_redirections_manage.htm&type=5&language=en_US) section.
- For a successful CRM connection, configure domain settings in both the source and target org.
- The Salesforce orgs that you connect must have API access and allow access for the Salesforce IP range. See [Salesforce IP Addresses and Domains to Allow](https://help.salesforce.com/s/articleView?id=000321501&type=1&language=en_US).
- See [Configure User Permissions for an External Salesforce Org Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setting_user_permissions_to_connect_external_org.htm&release=264.0.0&type=5 "For non-admin users to connect an external Salesforce org to Data 360, they must have the required user permissions assigned by the main Data 360 account.") and [Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.") .
1. From Data Cloud Setup, select **Salesforce CRM** under Salesforce Integrations.
2. Click **New**.
3. Click **Connect to a Salesforce org** or **Connect to a Sandbox org**.
4. Click **Next**.
5. Create an alias for your org by using up to 15 alphanumeric characters. Don't leave this space blank. Select a name carefully, because after the connection is established, the alias can't be changed. The alias is used for data stream and data lake object names. For example, if you use the alias "SourceOrg" and create an Account data stream, you get a corresponding data stream and data lake object named Account\_SourceOrg. If you use data kits, note that the alias must match across all orgs.
6. Click **Proceed**.
7. Log in to the org using your Salesforce credentials.
The login for a Salesforce production or developer org is https://salesforce.com. The login for a sandbox org is https://test.salesforce.com.
8. In the Allow Access menu, select **Allow**.
9. Confirm the connection by entering the Data 360 org identifier.
You can find this ID on the modal under **Data 360 Org Details**. This specifies which Data 360 org will retrieve data from your source org.
10. Check the checkbox to agree to create the connection and click **Connect**.
Your org is now available from the Salesforce CRM Connectors page.

Note After a home org connection is activated, the org can’t be disconnected due to associated system data streams.
- **[Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5)**
Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.
- **[Create a Salesforce CRM Starter Bundle](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_starter_bundle.htm&release=264.0.0&type=5)**
Create a data stream using a starter bundle to begin the flow of data from a Salesforce CRM source into Data 360.
- **[Create a CRM Data Stream from Financial Services Cloud (FSC) Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_stream_fsc_objects.htm&release=264.0.0&type=5)**
Add the permissions and license requirements in your Salesforce CRM org to ingest FSC objects.
- **[Install Standard Data Bundles Powered by Data Kits](https://help.salesforce.com/s/articleView?id=data.c360_a_install_standard_data_bundles_powered_by_data_kits.htm&release=264.0.0&type=5)**
After you create your Data 360 instance and set up your Salesforce CRM connection, you can install standard data bundles that are powered by data kits to deploy data within Data 360.
- **[Set Object Sharing Access for Salesforce CRM](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_object_sharing_and_access.htm&release=264.0.0&type=5)**
Sharing access for certain objects, such as QuickTextUsage and MacroUsage, are set to Private by default. To ingest these objects into Data 360, change the organization-wide access to Public.
- **[Disconnect a Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_salesforce_crm_connection.htm&release=264.0.0&type=5)**
When you no longer need a connection, you can delete it. After you remove a standard Salesforce CRM connection, Data 360 stops ingesting data from the connected org and deletes all the data it ingested from that org, except trust files. Data ingested from the org is removed from unified profiles the next time that identity resolution runs.
- **[Verify and Reauthenticate a Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_verify_and_reauthenticate_a_salesforce_crm_connection.htm&release=264.0.0&type=5)**
Verify your Salesforce CRM connection trust and re-authenticate if disruption was caused by a sandbox refresh, or if trust relationship between the home org CRM connection and Data 360 is broken. If your Salesforce org has a CRM connection to a sandbox org, and that sandbox has recently refreshed, the refresh process generates a new Org ID for the sandbox org that conflicts with the Org ID associated with the existing connection. Because Data 360 can’t establish trust with the refreshed sandbox, the connection to Data 360 is disrupted and requires reauthentication. When the connection is disrupted, data streams associated with it can encounter errors, including deployment failures for new streams and errors within the stream’s refresh history.
#### See Also
- [_Salesforce Help_: Use an Alias for a Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_alias.htm&release=264.0.0&type=5 "As of July ‘24, an alias is required when setting up a Salesforce CRM connection. Existing connections aren't assigned an alias. The names of the data stream and data lake object are derived from the alias.")
- [_Salesforce Help_: Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.")
- [_Salesforce Help_: Configure User Permissions for an External Salesforce Org Connection in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setting_user_permissions_to_connect_external_org.htm&release=264.0.0&type=5 "For non-admin users to connect an external Salesforce org to Data 360, they must have the required user permissions assigned by the main Data 360 account.")
- [_Salesforce Help_: Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
# Set Up a Data Cloud One Companion Connection
Establish a Data Cloud One Companion connection between the Data 360 org and another Salesforce org. You can't create a companion connection to a Salesforce org that's already connected to another Data 360 via a companion connection. You also can't connect a sandbox org to a production org.
### Required Editions
User Permissions Needed
Set up the connection from the home org
Standard System admin profile AND
Data Cloud Architect permission
set
Authorize the connection from the companion org
Standard System admin profile

Note
The connection must be initiated from the home org. When prompted during setup, log in to the companion org by using System Admin credentials.
Before you set up a companion connection:
- Plan your Data 360 architecture strategy.
- Review [Data 360 Architecture Strategy](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_architecture_strategy.htm&language=en_US&type=5) for architectural considerations.
- Choose a home org where Data 360 is provisioned.
- Choose a companion org. (A Salesforce org that already has Data 360 provisioned can't be connected as a companion org). If your intended companion org already has Data 360, deprovision Data 360 on that companion org first. See [Convert a Data 360 Home Org to a Data Cloud One Companion Org](https://help.salesforce.com/s/articleView?id=data.c360_a_prepare_home_org_for_dcone.htm&language=en_US&type=5).
- Verify that the companion org you're connecting has a Data Cloud One Companion license. If not, add one by using Your Account.
- Configure the domain settings in the home org and companion org to support the connection.
- Confirm that both orgs have API access and allow the Salesforce IP range. See [Salesforce IP addresses and domains to allow](https://help.salesforce.com/s/articleView?id=000384438&language=en_US&type=1).
If you don't want users to log in to your org through your instanced URL, go to the My Domain page in Setup and select Don't redirect for your instanced URL in the redirections section.
When you create a Data 360 companion connection, a standard Salesforce CRM org connection is also created. If you already have a Salesforce CRM connection to the org that you're connecting, the standard connection's name is updated to match the companion connection's name.
To initiate the connection, use the following steps.
1. From the Setup menu in the home org, select **Data Cloud Setup**.
2. Select **Data Cloud One**, and click **New**.
If you reached your org's maximum number of companion org connections, use Your Account in the home org to add a Data Cloud One Additional Connection license, and then try again.
3. When prompted during the connection process, log in to the companion org with System Admin credentials.
4. Review the org summary to confirm that you're connecting to the correct org, and click **Next**.
5. Select one or more data spaces to share with the companion org, and click **Next**. Metadata is synced only in data spaces that you share with this companion org. If no data spaces are shared, metadata isn't ingested or synced.

Note If you’re not sure which data space to use, or if you want to set up a new data space to share, you can skip this step and complete it later. However, your connection isn’t complete until you share at least one data space.
6. Review the access that the connection grants between orgs. To approve the connection, click **Connect**.
When you create a Data 360 companion connection, a standard Salesforce CRM org connection is also created. If a Salesforce CRM connection to the org already exists, it's upgraded to a Data Cloud One companion connection with the same name.
- **[Tagging, Policies, and Access in Data Cloud One](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_governance.htm&release=264.0.0&type=5)**
Data Cloud One uses the same tagging, policy creation, and access management as the rest of Data 360, with added specifications. For both tagging and policy creation in Data Cloud One, the home org functions as a standalone org that can perform further syncing.
- **[Objects Shared with Companion Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_companion_connection_shared_objects.htm&release=264.0.0&type=5)**
Data model objects (DMOs) and calculated insights objects (CIOs) in shared data spaces are shared with the companion org. You can reference data from these objects with Data 360 features and use the data with platform features, such as Flow and related list enrichments.
- **[Metadata Ownership in Connected Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_one_metadata_ownership.htm&release=264.0.0&type=5)**
An object is owned by the org in which it originated, even when it's shared with Data 360 or from Data 360 to other connected orgs. You can only edit or delete data in the org that owns it.
- **[Understand Data Spaces in Companion Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces_in_companion_orgs.htm&release=264.0.0&type=5)**
Metadata is synced only between a Data 360 home org and its connected companion org when the metadata is part of a data space that is shared with the companion org. Metadata syncing enables companion orgs to reference data in Data 360 objects in shared data spaces.
#### See Also
- [_Salesforce Help_: Manage Your Salesforce Account](https://help.salesforce.com/s/articleView?id=xcloud.users_checkout.htm&type=5&language=en_US)
- [_Salesforce Help_: Data 360 Standard Licenses and Editions](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&type=5&language=en_US)
# Set Up a Google Cloud Storage Target Connection
After you create your Data 360 instance, you can set up a Google Cloud Storage (GCS) connection.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
Prerequisites
- Complete the tasks in [Set Up Permissions for the Google Cloud Storage Connector](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-gcs-bucket-permission-setup.html)
- Review the [Data Cloud IP Allowlist](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_ip_address_allowlist.htm&release=264.0.0&type=5 "Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.") and make sure the GCS Connection has necessary access.
1. In Data 360, select **Data Cloud Setup**.
2. Under External Integrations, select **Other Connectors**.
3. Click **New**, and click **Target**.
4. Select **Google Cloud Storage**, and click **Next**.
5. Enter a connection name, connection API name, authentication details: access key, secret key, and connection details: bucket name and parent directory.
Access key The access key generated during creation of the key in Google Cloud Storage platform Secret key The secret key is generated during creation of the key in Google Cloud Storage platform. Bucket name The name of the bucket where you set up permissions in Google Cloud Storage platform. Parent directory The folder in the bucket where you want to transfer the data. It doesn’t include the bucket name.

Important It’s recommended to use a different parent directory for source and target connection.
6. To review your configuration, click **Test Connection**.
7. Click **Save**.
#### See Also
- [_External_: Protecting resources with VPC Service Controls](https://cloud.google.com/compute/docs/instances/protecting-resources-vpc-service-controls)
- [_Salesforce Help_: Create a File Storage Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_cloud_file_storage_activation_target.htm&release=264.0.0&type=5 "Create an activation target in Data 360 to publish segments and batch data model objects (DMOs) to external file storage activation platforms like Amazon S3, SFTP, Google Cloud Storage (GCS), or Microsoft Azure blob storage.")
# Set Up a Marketing Cloud Engagement Connection in Data 360
After you create your Data 360 instance, control the scope of data ingestion and activation from Marketing Cloud Engagement and other sources. Before integrating with Data 360, make sure that your Engagement user’s default business unit (BU) is set to the Enterprise ID (EID). Set up your data sources to tell Data 360 where to pull data from, also known as ingest, for data mapping and segments. You can connect multiple EIDs to a single Data 360 org, where each EID has its own connection to Data 360. For each of these connections, you can set up multiple data streams using data bundles or data extensions. Each connection also has its own business unit-to-data space mapping configuration. Data 360 supports only Engagement Enterprise 2.0 account connections.
### Required Editions

Note If you set up an Engagement connection before the Spring ‘22 release, skip to step 13 to enable the BU aware integration between Data 360 and Engagement.
User Permissions
Needed
To access Data Cloud Setup:
System admin profile OR
Data Cloud Architect
To connect to an Engagement account:
Administrator AND Marketing Cloud Administrator Roles must be assigned to the Engagement
account user.
1. From Setup, click **Data Cloud Setup**.
2. Under Salesforce Integrations and Marketing, select **Marketing Cloud Engagement**.
3. To create a new connection, click **New** and enter a name for the connection.
4. Click **Save**.
If you want to reconfigure an existing connection, select the connection from the list of connections, and select **Edit** from the menu.
5. To provide your Engagement credentials for authentication, click **Manage**.
During connection setup, if you are already logged in on a Marketing Cloud account, Data 360 assumes the credentials for that account and begins configuring a connection. If you intend to connect to a different Marketing Cloud account than the one that is currently logged in, you must log out of the account from the Marketing Cloud Engagement Authentication page.
6. Enter the Engagement username and password.

Important To prevent service disruptions, use a dedicated Marketing Cloud API user account for integration with Data 360. If your password expires, activations fail to publish new or updated segments to Engagement until the password is updated. A Marketing Cloud API user's password doesn’t expire.
7. To enable the channels so that Data 360 can pull in data, click **Manage** for Setup bundles to ingest into Data 360.

Note Make sure to enable the channels for the Data Extension Data Streams to be enabled. If the bundles aren't set up, Marketing Cloud Engagement won't be available as an option when creating a new Data Stream.
8. To enable the highlighted channels so that Data 360 can pull in data using the Data Cloud Starter Bundles, click **Start**.
9. Data bundle sources appear. Use data bundles to quickly and easily create multiple data streams to ingest system-owned data from Engagement. You can manually add more data extensions afterward.
Data 360 creates a set of automations and automation activities in Automation Studio to support data ingest. These automations transfer data between the two products. Don’t alter or edit these activities.
10. To select which business units to ingest data from, click **Manage**.

Note If you skip this step, Marketing Cloud Engagement will not be available as an option in the Data streams tab when creating a new Data Stream.
11. From Setup, use the arrows (1) to select the business unit name to add, remove, or move.
The top-level business unit is preselected and can’t be deselected because all subscriber data for the email channel is at that level.
When you select a new business unit, Data 360 ingests only 90 days of historical data for the business unit.
12. To enable business unit mapping, click **Save**.
13. To select which business units to activate segments to, click **Manage**.
If you don’t want to ingest any data from business units and only want to activate data to the Marketing Cloud Engagement account, click **Skip**.
14. Use the arrows to add or remove business units in Selected business units.
You can select any number or combination of business units independent of the BUs selected for ingest.
15. To automatically map Engagement subscriber data to the Affiliation Data Model Object (DMO), enable **Allow Profile Business Unit Mapping Data**.
Enabling **Allow Profile Business Unit Mapping Data** is permanent and can’t be undone. The new SFMC Subscriber BU Mapping Data Stream is created and mapped to the Affiliation DMO. Data can take up to 24 hours to appear in the Affiliation DMO. Until data is ingested into the Affiliation DMO, activations are sent to Engagement as shared data extensions. After successful ingestion, activations are sent as data extensions automatically. Because the SFMC Subscriber BU Mapping Data Stream gets a full refresh one time a day, view the refresh history for the latest status details.
16. Map other data to the Affiliation DMO.
1. Create a relationship between the Party field of the Affiliation DMO and the Individual Id field of the Individual DMO with the cardinality of ManyToOne.
2. Create a data stream and map data to the Affiliation DMO.
Affiliation DMO Fields
Field Label
Field API Label
Description
Mapping Requirements
Affiliation ID
ssot__Id__c
Unique value for each individual.
Required
Party
ssot__PartyId__c
Information about the individual.
The default mapping is to the Engagement Subscriber Key field.
Required
Affiliated To
ssot__AffiliatedTo__c
Information about the business unit. For example, brand or region.
Default mapping is to the Engagement MID.
This field ensures activations are sent to the right business unit in Engagement.
Required
Affiliation Type
ssot__AffiliationType__c
Type or category of the affiliation. For example, product category or
other granular details.
Optional
- **[Update your Connection’s Credentials After a Connection Failure](https://help.salesforce.com/s/articleView?id=data.c360_update_connection_after_failure.htm&release=264.0.0&type=5)**
If you receive a notification that one or more Marketing Cloud Engagement connections has failed, update your credentials to fit the issue.
#### See Also
- [_Salesforce Help_: Business Unit Aware Integration: Marketing Cloud and Data 360 (PDF)](https://resources.docs.salesforce.com/242/latest/en-us/sfdc/pdf/cdp_bu_aware_guide.pdf)
# Set Up a Microsoft Azure Target Connection
After you create your Data 360 instance, you can set up a Microsoft Azure Blob Storage Connection.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
Complete the prerequisites:
- Get a Microsoft Azure Storage account with these key settings.
- Public Access Level: Private
- Provision at least one Account key
- Get a container to which you want to transfer data
- Anonymous access level: Private
- Set up container SAS (Shared Access Signature) token. For more information, see [Create a Microsoft Azure Container SAS Token](https://help.salesforce.com/s/articleView?id=data.c360_a_create_an_azure_container_sas_token.htm&release=264.0.0&type=5 "Container Shared Access Signature (SAS) tokens give access to files in your Microsoft Azure Storage container.").
If you have restricted access to your storage service, make sure the Microsoft Azure Storage Service Connection has access to your storage service. Add the IP source addresses listed in the AWS ID IP Table section in [IP Addresses Used by Data Cloud Services](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_ip_address_allowlist.htm&release=264.0.0&type=5 "Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.") to the allowlist.
1. In Data 360, select **Data Cloud Setup**.
2. Under External Integrations, select **Other Connectors**.
3. Click **New**, and click **Target**.
4. Select **Microsoft Azure Storage**, and click **Next**.
5. Enter a connection name, connection API name, authentication details: SAS token and connection details: container URL and container path.
SAS token
Shared Access Signature (SAS) token that grants access to storage resources in a
storage account or container
Container URL
URL to access Azure storage container. You can get the container URL from the
container properties in your storage account.
Example: https://{storage account
name}.blob.core.windows.net/{container name}
Container Path
Container path refers to the directory in a file system and similar to the parent
directory in other connectors. The container path is where you want to activate files. The
container path must include only the directory name and not the container name.

Important It’s recommended to use a different container path for source and target connection.
6. To review your configuration, click **Test Connection**.
7. Click **Save**.
- **[Create a Microsoft Azure Container SAS Token](https://help.salesforce.com/s/articleView?id=data.c360_a_create_an_azure_container_sas_token.htm&release=264.0.0&type=5)**
Container Shared Access Signature (SAS) tokens give access to files in your Microsoft Azure Storage container.
#### See Also
- [_Salesforce Help_: Create a File Storage Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_cloud_file_storage_activation_target.htm&release=264.0.0&type=5 "Create an activation target in Data 360 to publish segments and batch data model objects (DMOs) to external file storage activation platforms like Amazon S3, SFTP, Google Cloud Storage (GCS), or Microsoft Azure blob storage.")
# Set Up a Redshift Federation Connection for Private Connect
Set up a connection between Redshift and Private Connect for Data Cloud to access the data.
### Required Editions
User Permissions
Needed
To create an Amazon Redshift Federation connection in Data Cloud:
System admin profile OR
Data Cloud Architect
Before you begin, verify that you have a configured Amazon Redshift or Redshift Serverless cluster and a private network route.
1. In Data Cloud, go to Data Cloud Setup.
2. Under External Integrations, select **Other Connectors**.
3. Click **New**.
4. Under Source, select **Amazon Redshift** and click **Next**.
5. Enter a connection name and connection API name.
6. Click **Use Private Network Route**.
7. Select the private network route that you created. The list of routes is specifically for private routes to Redshift.
8. To review your configuration, click **Test Connection**.
9. Click **Save**.
#### See Also
- [_Salesforce Help_: Add a Private Network Route for Redshift](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_redshift.htm&release=264.0.0&type=5 "To enable federation connections, connect your Redshift data source and your Data Cloud tenant with a dedicated network route using Private Connect for Data Cloud. Private Connect supports self-managed PrivateLink. Redshift-managed PrivateLink isn't currently supported.")
# Set Up a Snowflake Federation Connection for Private Connect
Set up a connection between Snowflake and Private Connect for Data Cloud to access the data.
### Required Editions
User Permissions
Needed
To create a Snowflake Data Federation connection in Data Cloud.
System admin profile OR
Data Cloud Architect
Before you begin, configure a network route to create a connection to Snowflake.
1. In Data Cloud, go to Data Cloud Setup.
2. Under External Integrations, select **Snowflake**.
3. Click **New**.
4. Enter a connection name and connection API name.
5. Click **Use Private Network Route**.
6. Select the private network route for the Snowflake instance. The list of routes are only for private network routes to Snowflake.
7. Enter the username for the Snowflake account.
8. Enter the private key details.
9. Click **Next**.
10. Select a database, and click **Save**.
# Set Up a Streaming Data Transform
When you set up a streaming data transform, it reads and processes all records in the source and writes the data to the target object. The source and target objects must be different objects.
1. In Data Cloud, on the Data Transforms tab, click **New**.
If the Data Transforms tab isn’t visible, click More and select Data Transforms. If your org has already used the maximum number of transforms allowed, the New button doesn’t appear.
2. Select **Streaming Data Transform**, then click **Next**.
3. Select **Data Model Object** or **Data Lake Object**, then click **Next**. If you select Data Model Object, choose a data space from the dropdown menu.
A data transform that runs on data model objects is restricted to read and write to the selected data space.
4. Enter a name for the data transform, and optionally, select a currency.
This setting converts data with multiple currencies to a single value. If you have multiple data transforms that write to the same target, make sure they all have the same currency.
5. For the Target Object field, choose a DLO or DMO from the list or select **Create New**. Only DLOs and DMOs created using Create New are displayed in this list.
6. Click **Next**.
7. In the Expression field, enter a SQL statement to tell the streaming data transform which records to process and how to map the transformed output to the target object.
If you chose to create a new DLO or DMO, the syntax will determine the columns and data type for the new DLO or DMO.
8. Verify your SQL statement’s syntax by clicking **Check Syntax**.
If a streaming data transform contains syntax errors or validation errors, such as incorrect API names for the source and target , you can’t save it. These errors appear on the left side. Fix them before saving.
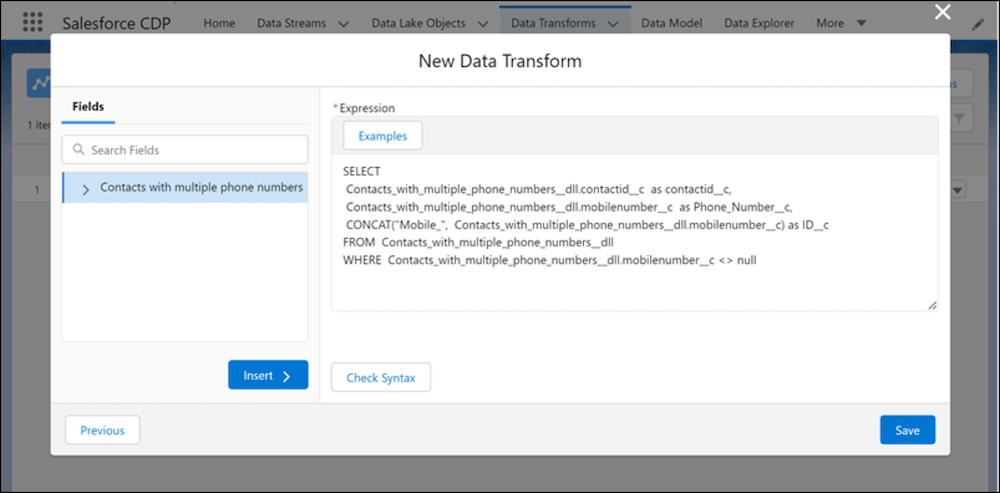
9. If you chose an existing target DLO or DMO, click **Save**.
Streaming data transforms are activated immediately when saved. You can’t change a streaming data transform after saving it. If you must change a streaming data transform, delete it and create another one.
10. If you are creating a new DLO or DMO, click **Next** and you are prompted to enter a name for the DLO or DMO and the category.
1. (Optional) Select a value from the **Enable Value Suggestion** field.
Value suggestions streamline the process by providing a list of valid values for fields.
2. Choose a key qualifier to create fully qualified keys (FQK) and select a primary key field.
3. Click **Save**.
After the DLO or DMO is created, a streaming data transform is created that uses it as target data source. Subsequently, this transform executes to populate the DLO or DMO with data.
# Set Up AI Models
To use AI Model Builder (formerly Einstein Studio Model Builder), your org must be provisioned with an applicable license, and users must be assigned the appropriate permission.
### Required Editions
Data 360 is available in several standard Salesforce editions and includes single-user access to Data 360. All licenses provide permission sets, which are automatically created when a license is provisioned in your org.
## Permissions
Users who manage their models in AI Models require the following permission:
| User Permission | What It Enables | Learn More |
| --- | --- | --- |
| Allow users to manage models in AI Models | Create, update, and delete predictive models in AI Models. | [Manage AI Models](https://help.salesforce.com/s/articleView?id=release-notes.rn_cdp_2024_summer_ai_model_permissions.htm&release=250&type=5&language=en_US) |
## Permission Sets
This permission is available in the following permission sets when a license is provisioned in your org.
| Permission Set | Provides |
| --- | --- |
| Data Cloud Architect | Admin-level access to all AI Models features, including the ability to create, update, delete, and activate models. |
| Data Cloud User | Restricted access to use a model, including getting predictions and improvements derived from a model. |
## Give Users Access to AI Models
To allow users to manage their models in AI Models, assign them the relevant Data Cloud permission sets and permissions. For more information on giving users access to AI Models, see [Data 360 Standard Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_userpermissions.htm&language=en_US).
#### See Also
- [_Salesforce Help_: Data 360 Standard Editions and Licenses](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_editions.htm&type=5&language=en_US)
- [_Salesforce Help_: Manage Access with Data 360 Permission Sets](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_walkthrough.htm&language=en_US)
- [_Salesforce Help_: Manage Permission Set Assignments](https://help.salesforce.com/s/articleView?id=platform.perm_sets_manage_assignments.htm&language=en_US)
# Set Up an Amazon Kinesis Target Connection
Send data action events from Data 360 to an Amazon Kinesis data stream. Use an access key or Salesforce as an OpenID Connect identity provider.
### Required Editions
User Permissions Needed
To create an Amazon Kinesis connection:
System Admin profile OR
Data Cloud Architect permission set
Before you begin, review [VPC Interface Endpoints for Amazon Kinesis Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_kinesis_vpc_endpoints.htm&release=264.0.0&type=5 "Data Cloud uses the VPC Endpoints listed here to communicate with Amazon Kinesis. If your security policy requires a strict network ACL (access control list), make sure to include these endpoints to your allowlists.") so the connection has the required network access.
Key-based authentication uses an IAM user's access key and secret. Identity-provider authentication configures Salesforce as an OpenID Connect identity provider in AWS and uses an IAM role.
1. In Data 360, click **Setup**, and select **Data Cloud Setup**.
2. Under External Integrations, select **Other Connectors**, and click **New**.
3. On the Target tab, select **Amazon Kinesis**, and click **Next**.
4. Enter a connection name and a connection API name.
5. Select an authentication method.
- To use key-based authentication, click **Access Key/Secret Based** and enter the information for the IAM user that connects to the Kinesis data stream. Then continue with the stream settings.
- To use identity-provider authentication, click **Identity Provider Based**, and complete the AWS identity provider and role setup in the next step.
6. If you clicked **Identity Provider Based**, add Salesforce as an identity provider in AWS IAM.
1. In the AWS IAM dashboard, select **Identity providers**, and click **Add provider**.
2. Enter the provider details, and click **Add provider**.
| Item | What to Enter | Example |
| --- | --- | --- |
| Provider type | OpenID Connect | None |
| Provider URL | My Domain URL with `/services/connectors` appended | https://yourcompany.my.salesforce.com/services/connectors |
| Audience | My Domain URL | https://yourcompany.my.salesforce.com |
3. Create an IAM role that provides access to the Kinesis data stream.
For Trusted Entity Type, select **Web identity**. Select the provider and audience that you created.
Add this JSON permission policy for the role.
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "AllowDataCloudKinesisEgressConnectionTestAndPublish",
"Effect": "Allow",
"Action": [
"kinesis:DescribeStreamSummary",
"kinesis:PutRecord",
"kinesis:PutRecords"
],
"Resource": "arn:aws:kinesis:::stream/"
}
]
}
```
If the stream uses a customer-managed KMS key, include this additional statement.
```
{
"Sid": "AllowKmsForEncryptedKinesisWrites",
"Effect": "Allow",
"Action": [
"kms:GenerateDataKey"
],
"Resource": "arn:aws:kms:::key/"
}
```
4. Enter a name for the role, and click **Create role**.
5. From Data 360, copy the External ID.
6. On the IAM role page, on the Trust relationships tab, click **Edit trust policy**.
7. In the trust policy, replace the external ID placeholder with the Data 360 External ID.
```
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"Federated": "arn:aws:iam:::oidc-provider//services/connectors"
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
"/services/connectors:aud": "https://",
"/services/connectors:sub": ""
}
}
}
]
}
```
8. From AWS IAM, copy the role's Amazon Resource Name (ARN).
9. In Data 360, enter the ARN in the IAM Role Name field.
7. Enter the Kinesis data stream's name.
8. Enter the name of the AWS region where the Kinesis data stream is hosted.
9. Enter the Kinesis data stream's endpoint. See [Amazon Kinesis endpoints and quotas](https://docs.aws.amazon.com/general/latest/gr/ak.html).
10. To review your configuration, click **Test Connection**.
11. When the connection succeeds, click **Save**.
The connection is created and listed under More Connectors. A Data Aware Specialist can create data streams that use this connection.

Note Create only one connection for each Kinesis data stream. A stream is identified by its name and region.
# Set Up an Amazon S3 Target Connection
After you create your Data 360 instance, you can set up an Amazon S3 target connection.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
Prerequisites
- [Prepare Your Amazon S3 Connection](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-prerequisites.html)
1. In Data Cloud, go to **Data Cloud Setup**.
2. Under External Integrations, select **More Connectors**.
3. Click **New**.
4. Under Target, select **Amazon S3**, and click **Next**.
5. Enter a connection name and connection API name.
6. Enter authentication details.
If you choose to use Access Key and Secret, click **Access Key/Secret Based**.
| Field Label | Description |
| --- | --- |
| AWS Access Key | Programmatic username for API access to AWS. |
| AWS Secret Access Key | Programmatic password for API access to AWS. |
If you choose to use IdP, click **Identity Provider Based**. For more details, see [Use Identity Provider-Based Authentication for S3 Connectors](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-connector-idp-settings.html), and enter the values.
| Field Label | Description |
| --- | --- |
| IAM Role Name | The Amazon Resource Name (ARN) specifying the role. |
| External ID | It’s auto-generated connection ID. Enter the External ID in the AWS trust policy for the role before testing the connection. |
7. Enter connection details.
| Field Label | Description |
| --- | --- |
| Bucket Name | Specific public cloud storage resource in AWS. |
| Parent Directory | Parent folder that corresponds to the S3 bucket. |
8. To review your configuration, click **Test Connection**.
9. Click **Save**.
Use this Amazon S3 connection to create an activation target and activate data from Data 360 to your Amazon S3 bucket.
#### See Also
- [_Salesforce Developers_: Configure Amazon S3 Bucket Policies and Permissions](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-bucket-policies.html)
- [_Salesforce Developers_: Configure Permissions for Activation](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-bucket-policies.html#configure-permissions-for-activation)
# Set Up an Endpoint in Databricks
Control the access to your data by setting up an endpoint connection between Databricks and Data 360.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. Before setup, confirm that your Databricks allowlist includes the IP addresses for your region.
2. Open the Databricks workspace.
3. In the Admin section, configure the service principal.
4. Configure the model serving endpoint.

Note Serverless compute is required for model serving and is available with the Premium tier.
5. Grant the service principal access to the warehouse and tables using roles and the unity catalog.
6. Generate an access token for the service principal.
#### See Also
- [_Salesforce Help_: IP Addresses Used by Data 360 Services](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_ip_address_allowlist.htm&release=264.0.0&type=5 "Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.")
- [_External_: Supported Regions List](https://learn.microsoft.com/en-us/azure/databricks/resources/supported-regions#--supported-regions-list)
- [_External_: IP Addresses and Domains](https://docs.databricks.com/en/resources/supported-regions.html#ip-domain-aws)
- [_External_: Grant Roles for a Service Principal](https://docs.databricks.com/en/resources/supported-regions.html#ip-domain-aws)
- [_External_: Manage Tokens for a Service Principal](https://docs.databricks.com/en/administration-guide/users-groups/service-principals.html#manage-tokens-for-a-service-principal)
- [_External_: What is Unity Catalog?](https://docs.databricks.com/en/data-governance/unity-catalog/index.html)
- [_External_: Manage Service Principals](https://docs.databricks.com/en/administration-guide/users-groups/service-principals.html)
- [_External_: Create and Configure Model Serving Endpoints](https://docs.databricks.com/en/machine-learning/model-serving/create-manage-serving-endpoints.html)
# Set Up an External Activation Platform
Reach more customers by connecting an external activation platform to Data 360. Install an external activation platform from AppExchange or a packaged URL.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
1. From Setup, select **Data Cloud Setup**.
2. Under External Integrations, select **External Activation Targets**.
3. Select the external activation platform.

Note Segment names are included in activations. To exclude segment names in the metadata file sent to the external activation platform, turn off **Include segment name in activations to this platform**.
4. To enable filtering by data privacy requirements, select the privacy type to indicate how your customers are impacted by the California Privacy Rights Act (CPRA).
If your customers aren’t impacted by CPRA (see [California Privacy Protection Agency](https://cppa.ca.gov/)), select **Not Applicable**.
5. For ISV-created JSON-based External Activation platforms, review the ID Type Mapping tab. If the ISV has configured supported IDs, update the ID Type field to map to the corresponding partner-supported identifiers. Mapping ID types normalizes the ID type, ensuring records are activated to the appropriate destination folder when the output is grouped by `PER_USER` (user identifier). The ID Type values are case-sensitive. For example, map Google to GAID, GoogleId, or GId as comma-separated values.
During activation, the final computation includes both the partner-supported ID type in the left column (for example, Google) and all mapped aliases in the right column (for example, GID, gid, and GAid). In this example, any record in the `ContactPointDigitalId` DMO with a `DigitalIdType` value of Google, GID, gid, or GAid is activated to the corresponding destination.
6. Save your changes.
7. Click **Enable** to use the platform for activations.
You can disable an external activation platform. However, activations associated with a disabled platform won’t be processed.
**Considerations for External Activation Platforms Created by ISV Partners Using JSON**
- After mapping the ID values and including them in the activation definition's Contact Point Digital ID filters, all records with these contact point filtering values are activated to the ISV partner’s S3 bucket when the activation runs.
- If an ISV partner discontinues support for an identifier during a package upgrade, you'll need to update the activations to reflect the changes made by the ISV partner during the upgrade.
- If you have mapped all possible values for the IDs supported by the ISV partner, and no additional contact point digital Id filters are applied, all records in the Contact Point Digital Id DMO linked to the supported identifiers are activated. However, applying filters allows for more control over which records are included in the activation.
- 
Note See [Ingest and Model Digital Identifiers for JSON-based External Activation Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_map_digital_identifiers_activation_toolkit.htm&release=264.0.0&type=5 "Ingest and model your digital identifier data by using the standard ContactPointDigitalId data model object (DMO). Independent Software Vendors (ISV) use the activation toolkit to build activations that query this DMO to resolve digital identities across digital media platforms.") to learn how to model and map digital identifiers to the ContactPointDigitalId DMO to successfully use the activation toolkit for external platforms.
#### See Also
- [_Salesforce Help_: Create an External Activation Target in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&language=en_US)
- [_Salesforce Help_: Create an Activation for an External Platform](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activations.htm&language=en_US)
# Set Up an Omnichannel Inventory Connection
Ingest your Omnichannel Inventory data into Data 360 using the Omnichannel Inventory connector.
### Required Editions
User Permissions
Needed
To connect to Omnichannel Inventory
Data Cloud Architect permission set OR Commerce Intelligence Admin permission
set

Important The Data 360 org and the Omnichannel Inventory (OCI) tenant must be on the same instance. Connect only one Data 360 org to one OCI tenant. Connecting more than one Data 360 org to a single OCI tenant results in unexpected behavior.
1. From Data Cloud Setup, in the Quick Find box, enter Omnichannel Inventory Connector, and then select **Omnichannel Inventory Connector**.
2. In the Omnichannel Inventory Connector setup screen, click **Connect**.
3. Next to the type of connection that you want to make, click **Connect**.
4. Log in to the Omnichannel Inventory instance.
5. Allow Data Clloud to connect to Omnichannel Inventory and access the data.
6. Review the connection details.
The connection process creates data streams and maps the data source objects to the data model objects (DMO) and establishes the DMO relationships. If the new connection is in an inactive status for longer than two minutes, navigate to the Data Streams workspace and check if the Omnichannel Inventory data streams are in an error state. If so, click **Retry** on those streams. If the retry fails, delete the data streams, navigate back to the Omnichannel Inventory Connector setup screen, and create a new connection.
#### See Also
- [Disconnect an Omnichannel Inventory Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_oci_connection.htm&release=264.0.0&type=5 "You can delete a connection to Omnichannel Inventory if you don't need it. Removing the connection stops Data 360 from using your inventory as a data source and data action target.")
- _Salesforce Help_: Disconnect an Omnichannel Inventory Connection
# Set Up an SFTP Target Connection
Create an SFTP connection in Data 360 using your own SFTP server that’s not provided or used by Marketing Cloud Engagement.
### Required Editions
User Permissions Needed
To access Data Cloud Setup
System admin profile OR
Data Cloud Architect permission set
1. In Data 360, select **Data Cloud Setup**.
2. Under External Integrations, select **Other Connectors**.
3. Click **New**, and click **Target**.
4. Select **Secure File Transfer (SFTP)**, and click **Next**.
5. Enter a connection name, connection API name, and enter the authentication details.
| Field | Description |
| --- | --- |
| Authentication Method | Select SSH Private Key or SSH Private Key & Password. |
| Username | The SFTP account used to authenticate the connection. |
| Password | The password to authenticate the user. |
| SSH Private Key | To secure access, create an SSH public and private key. The public key is used on the SFTP server to encrypt the data before sending it to Data Cloud. The private key is entered in your SFTP connection details and Data Cloud uses it to decrypt your data. |
| Passphrase (optional) | The passphrase to protect your private key. |
| Host Name | The SFTP server’s name or address. |
| Port: 22 (default) | The port that the SFTP server is running on. |
| PGP Encryption (optional) | The public key is in RSA format. PGP encryption is supported for CSV and JSON file formats, but not Parquet. |
| Parent Directory | The base directory where your activation target child folder resides. The directory you select must have Write permission. Also, file rename permission is required for activated files on the SFTP server. |
6. To review your configuration, click **Test Connection**.
7. Click **Save**.
After the connector details are accepted, the connection is created and ready to use in activation targets. Change the SFTP credentials and encryption keys periodically as per your security policy.
SSH keys consist of a Public Key and a Private Key (with an optional passphrase). SSH key pair generation can be done with multiple SSH key generator utilities. Use an SSH key generator utility such as PuTTY to generate the SSH key pair. The SFTP connector supports RSA-based keys up to 4096-bit encryption. For example, the command line entered in a terminal to create the key-pair using PuTTY is .
#### See Also
- [_Salesforce Help_: Allowlisting](https://help.salesforce.com/s/articleView?id=data.c360_a_allowlist.htm&release=264.0.0&type=5 "An allowlist defines things that a system trusts. It’s used to control allowed traffic and rejects undefined traffic and can be applied at different layers of the OSI Model. Here’s how the allowlist works at the application and network layers for Data 360.")
- [_Salesforce Knowledge_: IP Addresses and Domains to Allow](https://help.salesforce.com/s/articleView?id=000384438&type=1&language=en_US)
- [_Salesforce Help_: Create a File Storage Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_cloud_file_storage_activation_target.htm&release=264.0.0&type=5 "Create an activation target in Data 360 to publish segments and batch data model objects (DMOs) to external file storage activation platforms like Amazon S3, SFTP, Google Cloud Storage (GCS), or Microsoft Azure blob storage.")
# Set Up and Turn On Data 360
Capture, unify, segment, and activate your customer data with Data 360. Automatic provisioning occurs for most orgs that have a Data Cloud license. However, if auto provisioning isn't available or if you’re working in a Developer Edition or sandbox org, you must manually enable it.
### Required Editions
Available in: Developer Edition
User Permissions
Needed
To access Data Cloud Setup
System Admin profile AND
Data Cloud Architect permission
set
To provision Data 360 manually, follow these steps.

Note Enable Data 360 on a new or an existing Salesforce org.
1. From the standard Setup dropdown, go to **Data Cloud Setup**.
If you don’t see this option, refresh your page, or log out and then log back in with your admin user credentials.
2. To enable Data 360, click **Get Started**.
Setup can take a few minutes. After setup finishes, Data 360 admins can continue with the configuration and user setup.

Note
When a new org gets a Data 360 license, Salesforce sends an admin welcome email. If you didn’t receive an email, need Data 360 moved to a different org, or need a Data 360 license, contact your account executive.
# Set Up Clean Room Activation
After a clean room activation collaboration is active, the provider receives matched audience data directly in their Amazon S3 bucket. The provider can then use the data to run targeted campaigns in their advertising platform or downstream media system.
### Required Editions
Creating AppExchange clean room packages: Developer Edition (packaging org only) Deploying packages, creating collaborations, and accepting invitations: Enterprise Edition (home org)
User Permissions Needed
To set up clean room activation:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
The provider can use Data 360 or AWS as their clean room platform. Providers who are using Data 360 as the clean room platform can choose between a Salesforce-provided collaboration template or a custom one. Providers using AWS as the clean room platform must use a custom collaboration template.

Note Create clean room packages in a Developer Edition packaging org. Deploy packages, create collaborations, and accept invitations in an Enterprise Edition home org. You can’t receive or accept collaboration invitations in Developer Edition.
1. Provider: Create a clean room package that supports the activation use case in a Developer Edition packaging org.
See [Create a Clean Room Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_clean_room_package.htm&release=264.0.0&type=5 "Providers can offer clean room packages that contain collaboration templates on AppExchange. Consumers interested in collaborating on your data can download the clean room package and initiate a collaboration.").
2. Provider: Publish the clean room package on AppExchange.
3. Consumer: In an Enterprise Edition home org, deploy the package from AppExchange. If the provider is a trusted partner, you can allowlist the provider to access supported use cases without deploying a package.
See [Deploy a Clean Room from an AppExchange Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_deploy_cr_from_appexchange.htm&release=264.0.0&type=5 "To initiate a collaboration with a provider, install a clean room package from AppExchange and deploy it in Data 360 .") or [Allowlist a Clean Room Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_allowlist_clean_room_provider.htm&release=264.0.0&type=5 "To collaborate directly with a trusted provider, add them to your Data 360 org allowlist. When you add a collaborator to your allowlist, you don't need a clean room package to create a clean room collaboration with them.").
4. Consumer and provider: Create mapped templates to map each party's data to the required fields for the collaboration.
You can create mapped templates in advance or map data during the collaboration creation and invitation acceptance. Both parties must complete required mappings before the collaboration can become active. See [Map Data for a Clean Room Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_map_data_for_a_usecase.htm&release=264.0.0&type=5 "Create a mapped template to save your data mappings for a specific use case. You can create a template before a clean room collaboration is active. You can also map your data while creating a collaboration or accepting an invitation to collaborate.").
5. Consumer: Create the collaboration and send an invitation to the provider.
See [Create a Clean Room Collaboration and Invite a Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_collaboration.htm&release=264.0.0&type=5 "To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.").
6. Provider: In an Enterprise Edition home org, accept the collaboration invitation.
In the invitation acceptance wizard, configure the identity provider-based authentication to your AWS account so that Data 360 can write the collaboration results to your Amazon S3 bucket. You can use an existing bucket or create one.
See [Accept or Reject a Clean Room Invitation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_accept_reject_invitation.htm&release=264.0.0&type=5 "If you’re a provider, when you receive an invitation to a Data 360 clean room collaboration, you can accept or reject the request. If you accept, you can choose how to map your data for the collaboration.").
7. Consumer: After the provider accepts and the collaboration is active, run a query in the clean room.
For detailed instructions, see [Collaborate in a Clean Room](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_collaborate_in_clean_room.htm&release=264.0.0&type=5 "Set up a query in a Data 360 clean room collaboration to compare a consumer segment with the provider's data, without exposing raw records. Run a query manually for an immediate output, or schedule it to run each time the segment publishes.").
Data 360 writes the query results to the provider's S3 bucket as parquet files. Each query run creates a new timestamped folder at `s3://[your-bucket]/[Collaboration Name]/[Query Name]_[Timestamp]/`.
Providers can activate the output in their existing advertising platform or downstream media system. The S3 delivery format is designed to plug into activation pipelines they already have running.
# Set Up Clean Room Identity Boost
Setting up and using a clean room identity boost involves steps for both the provider and the consumer. The provider creates a package and sets up their Snowflake environment. The consumer installs the package, creates a collaboration, and maps their data. After the provider accepts the invitation and runs the enrichment job, Data 360 automatically refreshes the enriched data in the consumer's org.
### Required Editions
Creating AppExchange clean room packages: Developer Edition (packaging org only) Installing packages, creating collaborations, and accepting invitations: Enterprise Edition (home org) You can’t receive or accept collaboration invitations in Developer Edition.
User Permissions Needed
To set up a clean room identity boost:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist

Important Identity boost shares personally identifiable information (PII) in unhashed form with the identity provider. Before mapping your data, make sure that you have all required consumer consents and that you comply with applicable data usage agreements and privacy regulations. Data processing can occur outside your Salesforce region.
1. Provider: Create a clean room package that includes the identity boost use case, and publish it to AppExchange.
Creating an identity boost package requires a Developer Edition packaging org. Install the package, create the collaboration, and accept the invitation in an Enterprise Edition home org. See [Create a Clean Room Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_clean_room_package.htm&release=264.0.0&type=5 "Providers can offer clean room packages that contain collaboration templates on AppExchange. Consumers interested in collaborating on your data can download the clean room package and initiate a collaboration.").
2. Consumer: In an Enterprise Edition home org, install the package from AppExchange.
If the provider is a trusted partner, the consumer can allowlist the provider to access supported use cases without deploying a package. See [Deploy a Clean Room from an AppExchange Package](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_deploy_cr_from_appexchange.htm&release=264.0.0&type=5 "To initiate a collaboration with a provider, install a clean room package from AppExchange and deploy it in Data 360 .") or [Allowlist a Clean Room Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_allowlist_clean_room_provider.htm&release=264.0.0&type=5 "To collaborate directly with a trusted provider, add them to your Data 360 org allowlist. When you add a collaborator to your allowlist, you don't need a clean room package to create a clean room collaboration with them.").
3. Consumer and provider: Create mapped templates so that each party maps data to the required collaboration fields.
The consumer maps Data 360 DMO fields to the provider's required attributes. Review the data-sharing disclaimer carefully before proceeding because this use case shares PII with the provider in unhashed form. See [Map Data for a Clean Room Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_map_data_for_a_usecase.htm&release=264.0.0&type=5 "Create a mapped template to save your data mappings for a specific use case. You can create a template before a clean room collaboration is active. You can also map your data while creating a collaboration or accepting an invitation to collaborate.").
4. Consumer: Create a collaboration using the identity boost use case and send an invitation to the provider.
See [Create a Clean Room Collaboration and Invite a Provider](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_create_collaboration.htm&release=264.0.0&type=5 "To initiate a collaboration in a Data 360 clean room, you first create a collaboration. You can use an existing collaboration template to map your data or create one. When you save the collaboration, an invite is sent to the provider.").
5. Provider: In an Enterprise Edition home org, in the Invitation Acceptance wizard, set up the Snowflake environment and establish the trust relationship with Snowflake.
See [Accept or Reject a Clean Room Invitation](https://help.salesforce.com/s/articleView?id=data.c360_a_crc_accept_reject_invitation.htm&release=264.0.0&type=5 "If you’re a provider, when you receive an invitation to a Data 360 clean room collaboration, you can accept or reject the request. If you accept, you can choose how to map your data for the collaboration.").
After the provider accepts, Data 360 creates a clean room-aware Snowflake data share target and shares the consumer's mapped DMO data to the provider's Snowflake environment.
6. Provider: Run the enrichment job on the shared consumer data, then write enriched output tables to the consumer's Snowflake schema.
Data 360 automatically refreshes the enriched data in the consumer org. Data 360 reads enriched output tables from the provider's Snowflake schema through a (Bring Your Own Lake) BYOL connection, creates Data Lake Objects (DLOs) and enriched DMOs in the consumer org, and sets the collaboration status to Active.
7. Consumer: After refresh completes, use the enriched DMOs in the Data 360 org for activation use cases.
# Set Up Connectors with Google OAuth
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
### Required Editions
Follow these prerequisite steps before connecting to the data source in Data Cloud Setup. To complete these steps you must have admin access.
 Bookmark this page or keep it open to refer to this topic as you complete these tasks.

Note Steps and links outside of Salesforce content may not be updated or accurate.
## Create a Custom OAuth Application
Before you can define your authentication provider in Salesforce, you can optionally create a custom OAuth application on your provider's website. The process can vary depending on your provider.
1. According to your provider's documentation, create a private app on their website.
2. Write down these configuration values:
1. Client ID
2. Client Secret
## Configure an Authentication Provider
Create an authentication provider in Salesforce and then update your provider with the callback URL.
1. From Setup, in the Quick Find box, enter Auth. Providers, and then select it.
2. Click **New**.
3. Select **Google** from the provider type dropdown.
4. Fill out the required information (1).
1. Name—Enter a name for the Authentication provider.
2. URL Suffix—The URL automatically gets suffixxed with the name you have given to the Authentication provider.
5. Complete these fields.
1. Consumer Key—Add Google App's Application ID.
2. Consumer Secret—Add Google App's Client Secret Value.
6. (For structured and unstructured data ingestion) Set the Authorize Endpoint URL to `https://accounts.google.com/o/oauth2/v2/auth?access_type=offline&prompt=consent`.
7. Update the Scope (2) for the connector you’re using. All start with: https://www.googleapis.com/auth/\[VARIABLE\]. Find the variables listed for each connector.
1. Google Ad Manager: analytics.readonly
2. Google Analytics: analytics.readonly
3. Google Contacts: userinfo.email, userinfo.profile, or contacts
4. Google Campaign Manager: dfatrafficking, drareporting, or ddmconversions
5. Google Drive: userinfo.email, userinfo.profile, drive.readonly
6. Google Sheets: userinfo.email, userinfo.profile, drive.readonly
7. Google Spanner: spanner.data
8. Click **Save**.
Several client configuration URLs are generated after defining the authentication provider. Write down the callback URL from the Salesforce configuration after you save your work.
After defining the authentication provider in Salesforce, go back to your provider and update your app's callback URL.
# Set Up Connectors with LinkedIn OAuth
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using LinkedIn OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
### Required Editions
Follow these prerequisite steps before connecting to the data source in Data Cloud Setup. To complete these steps you must have admin access.
 Bookmark this page or keep it open to refer to this topic as you complete these tasks.

Note Steps and links outside of Salesforce content may not be updated or accurate.
## Create a Custom OAuth Application
Before you can define your authentication provider in Salesforce, you can optionally create a custom OAuth application on your provider's website. The process can vary depending on your provider.
1. Create a private app according to [LinkedIn's documentation](https://www.linkedin.com/help/linkedin/answer/a1667239).
2. Write down these configuration values:
1. Client ID
2. Client Secret
3. Authorization Endpoint URL (optional)
4. Token Enpoint URL (optional)
## Configure an Authentication Provider
Create an authentication provider in Salesforce and then update your provider with the callback URL.
1. From Setup, in the Quick Find box, enter Auth. Providers, and then select it.
2. Click **New** and select **LinkedIn** from the provider type dropdown.
3. Fill out the required information.
1. Name—Enter a name for the Authentication provider.
2. URL Suffix—The URL automatically gets suffixxed with the name you have given to the Authentication provider.
3. Consumer Key—Add the Client ID from LinkedIn.
4. Consumer Secret—Add LinkedIn's Client Secret Value.
4. Click **Save**.
Several client configuration URLs are generated after defining the authentication provider. Write down the callback URL from the Salesforce configuration after you save your work.
After defining the authentication provider in Salesforce, go back to your provider and update your app's callback URL.
# Set Up Connectors with Microsoft OAuth
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
### Required Editions
Follow these prerequisite steps before connecting to the data source in Data Cloud Setup. To complete these steps you must have admin access.
 Bookmark this page or keep it open to refer to this topic as you complete these tasks.

Note Steps and links outside of Salesforce content may not be updated or accurate.
## Optional: Create a Custom OAuth Application
Before you can define your authentication provider in Salesforce, you can optionally create a custom OAuth application on your provider's website. The process can vary depending on your provider.
1. According to your provider's documentation, create a private app on their website.
2. Write down these configuration values:
1. Client ID
2. Client Secret
3. Authorization Endpoint URL
4. Token Endpoint URL
## Configure an Authentication Provider
Create an authentication provider in Salesforce and then update your provider with the callback URL.
1. From Setup, in the Quick Find box, enter Auth. Provider, and then select it.
2. Click **New**.
3. Select **Microsoft** from the provider type dropdown.
4. Fill out the required information.
1. Name—Enter a name for the Authentication provider.
2. URL Suffix—The URL automatically gets suffixxed with the name you have given to the Authentication provider.
5. Complete optional fields.
1. Consumer Key—Add the Client ID from your provider.
2. Consumer Secret—Add the Client Secret from your provider.
3. Authorization Endpoint URL—Enter the Authorization Endpoint URL from your provider.
4. Token Endpoint URL—Enter the Token Endpoint URL from your provider.
6. Click **Save**.
Several client configuration URLs are generated after defining the authentication provider. Write down the callback URL from the Salesforce configuration after you save your work.
After defining the authentication provider in Salesforce, go back to your provider and update your app's callback URL.
# Set Up Connectors with OpenId Connect OAuth
To create a connection in Data Cloud securely without sharing passwords, some external connectors allow access using OAuth (Open Authorization). If using OAuth, there are several prerequisite implementation steps to complete before you connect the source to Data Cloud.
### Required Editions
Follow these prerequisite steps before connecting to the data source in Data Cloud Setup. To complete these steps you must have admin access.
 Bookmark this page or keep it open to refer to this topic as you complete these tasks.

Note Steps and links outside of Salesforce content may not be updated or accurate.
## Task 1: Create a Custom OAuth Application
Before you can define your authentication provider in Salesforce, you must create a custom OAuth application on your provider's website. The process can vary depending on your provider.
1. According to your provider's documentation, create a private app on their website.
2. Write down these configuration values:
1. Client ID
2. Client Secret
3. Authorization Endpoint URL
4. Token Endpoint URL
## Task 2: Configure an Authentication Provider
Create an authentication provider in Salesforce and then update your provider with the callback URL.
1. From Setup, in the Quick Find box, enter Auth. Provider, and then select it.
2. Click **New**.
3. Select **Open ID Connect** from the provider type dropdown.
4. Fill out the required information.
1. Name—Enter a name for the Authentication provider.
2. URL Suffix—The URL automatically gets suffixxed with the name you have given to the Authentication provider.
3. Consumer Key—Add the Client ID from your provider.
4. Consumer Secret—Add the Client Secret from your provider.
5. Authorization Endpoint URL—Enter the Authorization Endpoint URL from your provider.
6. Token Endpoint URL—Enter the Token Endpoint URL from your provider.
5. Complete optional fields.
See [Configure an Authentication Provider Using OpenID Connect](https://help.salesforce.com/s/articleView?id=xcloud.sso_provider_openid_connect.htm&type=5&language=en_US) for full details of the optional fields and steps.
6. Click **Save**.
Several client configuration URLs are generated after defining the authentication provider. Write down the callback URL from the Salesforce configuration after you save your work.
After defining the authentication provider in Salesforce, go back to your OpenID provider and update your app's callback URL.
# Set Up Platform Encryption for Data 360
When you enable Platform Encryption, your first Data 360 root key generates automatically. This key encrypts all previously ingested data in Data 360. After the initial setup, you can continue to use the generated root key or configure an external key using External Key Management (EKM), or leverage your own key material using Bring Your Own Key (BYOK) in the Salesforce UI to encrypt data in Data 360. You can rotate root keys periodically and view key metadata, such as creation time and creator, in Setup.
### Required Editions
Available in: All Editions supported by Data 360. See Data 360 edition availability . Available with add-on license: Enterprise , Performance , Unlimited , and Developer Editions. Requires purchasing Salesforce Shield or Shield Platform Encryption, and Platform Encryption for Data Cloud. Also, to use the optional External Key Management, requires purchasing the Platform Encryption for Consumption license.
Here are the key migration options.
- From Customer Managed Keys (CMK) to EKM: Existing CMK customers can configure a new EKM key from the Key Inventory and Management page in Setup. This change affects only the encryption of new data going forward. Previously encrypted data remains encrypted with the existing CMK key.
- From EKM to CMK: Existing EKM customers can switch to a CMK by generating a new key in the Key Inventory and Management page. This action reencrypts existing Data 360 data using the newly generated CMK key.
- From CMK or EKM to BYOK: Upload your own key material via the Bring Your Own Key option in Setup. Data encrypted with previous keys remains accessible. The new data is encrypted using the new BYOK root key.
- Customers can transition from CMK to BYOK and BYOK to CMK via the Salesforce UI. When this transition occurs we don’t reencrypt previously ingested data to the new key. It stays encrypted with the previous key.
- Customers can also transition from EKM to BYOK and BYOK to EKM.
- From EKM to BYOK: We reencrypt all previously ingested data to the new key.
- From BYOK to EKM: When this transition occurs we don’t reencrypt previously ingested data to the new key. It stays encrypted with the previous key.
# Set Up Your Data for Einstein Segments in Data 360
To get proper results when creating an Einstein segment, make sure that your data is prepared correctly.
### Required Editions
User Permissions
Needed
To set up data:
Permission set:
1. Run an identity resolution ruleset to create a Unified Individual data model object (DMO) prior to creating an Einstein segment.
2. Verify that your Unified Individual DMO contains at least 10 unified individual records.
3. If you want to include data in DMOs other than Unified Individual, the DMOs must be related to the Unified Individual DMO.
4. Make sure that your field names and DMO names are descriptive.
5. Refine your metadata with Metadata Studio.
Einstein Segment Creation results are optimized with Einstein Data Prism. To get the best results with Einstein Data Prism, review the generated descriptions for objects and fields, enter in missing descriptions, and omit objects from the data source. See [Einstein Data Prism](https://help.salesforce.com/s/articleView?id=ai.generative_ai_prism.htm&type=5&language=en_US).
#### See Also
- [_Salesforce Help_: Unify Source Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_source_profiles.htm&language=en_US)
# Set Up Your Data in Databricks
Access Salesforce data in your Databricks notebook using a Python connector. The user-friendly interface lets you quickly execute queries against data in Data 360 so that you can extract the data that you need into Python.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In your Databricks notebook, install the CDP Python Connector to access Data 360 objects and ingest Salesforce data into Databricks.
2. As part of the Python connector configuration, create an external client app or connected app.

Important Creating connected apps is restricted as of Spring ‘26. You can continue to use existing connected apps during and after Spring ‘26. However, we recommend using [external client apps](https://help.salesforce.com/s/articleView?id=xcloud.external_client_apps.htm&language=en_US) instead. If you must continue creating connected apps, contact Salesforce Support.
See [New connected apps can no longer be created in Spring ‘26](https://help.salesforce.com/s/articleView?id=005228017&type=1&language=en_US) for more details.
3. Restrict access to IP addresses to manage access to your data.
4. Use a key-based authentication to securely access your data.
5. In Data 360, connect to your data source to query the dataset in Databricks. For example, to get email engagement data, you need access to the Email Engagement object in Marketing Cloud Engagement.
6. To consume the inferences in Data 360, upload the Python file to your notebook.
7. To get your model endpoint, go to the Databricks dashboard in the Registered Models - Serving section. Note the URL as you need these details to connect your model with Salesforce.
#### See Also
- [_Salesforce Help_: Create a Connected App](https://help.salesforce.com/s/articleView?id=xcloud.connected_app_create.htm&type=5&language=en_US)
- [_Salesforce Developer_: CDP Python Connector](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_python_connector.htm)
- [_External_: Create and Configure Model Serving Endpoints](https://docs.databricks.com/en/machine-learning/model-serving/create-manage-serving-endpoints.html)
# Set Up Your Data in SageMaker
Access Salesforce data from an Amazon SageMaker notebook using the Data 360 Python connector. The intuitive interface lets you quickly execute run queries and extract the data that you need.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. 
Important Creating connected apps is restricted as of Spring ‘26. You can continue to use existing connected apps during and after Spring ‘26. However, we recommend using [external client apps](https://help.salesforce.com/s/articleView?id=xcloud.external_client_apps.htm&language=en_US) instead. If you must continue creating connected apps, contact Salesforce Support.
See [New connected apps can no longer be created in Spring ‘26](https://help.salesforce.com/s/articleView?id=005228017&type=1&language=en_US) for more details.
In your SageMaker notebook, install the Python connector. The connector enables you to access Data 360 objects and ingest Salesforce data into SageMaker.
2. As part of the Python connector configuration, create an external client app or connected app.
3. Authenticate to securely access data using one of these methods.
- Key-based
- JWT
4. In Data 360, connect to your Salesforce data source to query the dataset. For example, to get email engagement data, access the Email Engagement object in Marketing Cloud Engagement.
5. To use the inferences in Data 360, upload the Python file to your notebook.
6. To get the model endpoint, go to the SageMaker dashboard in the Inferences section, and go to Endpoints. Note the URL as you need these details to connect your model with Salesforce.
#### See Also
- [_Salesforce Developer_: Data 360 Python Connector](https://developer.salesforce.com/docs/data/data-cloud-query-guide/guide/get-started-dc-python.html)
- [_Salesforce Help_: Create a Connected App](https://help.salesforce.com/s/articleView?id=xcloud.connected_app_create.htm&type=5&language=en_US)
# Set Up Your Data in Vertex AI
Access Salesforce data in a Google Cloud Vertex AI notebook using a Python connector. The user-friendly interface lets you quickly query your data in Data 360 so you can extract the data that you need into Python.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In Vertex AI Workbench, install the CDP Python Connector to access Data 360 objects in and ingest Salesforce data into Vertex AI.
2. As part of the Python Connector configuration, create an external client app or connected app.

Important Creating connected apps is restricted as of Spring ‘26. You can continue to use existing connected apps during and after Spring ‘26. However, we recommend using [external client apps](https://help.salesforce.com/s/articleView?id=xcloud.external_client_apps.htm&language=en_US) instead. If you must continue creating connected apps, contact Salesforce Support.
See [New connected apps can no longer be created in Spring ‘26](https://help.salesforce.com/s/articleView?id=005228017&type=1&language=en_US) for more details.
3. Authenticate to securely access your data using one of these methods.
- Google Service Account Credential
- API Key
4. In Data 360, connect to your Salesforce data source in Vertex AI to query the dataset. For example, to get your email engagement data, access the Email Engagement object in Marketing Cloud Engagement.
5. To consume the inferences in Data 360, upload the Python file to your notebook.
6. To get your model endpoint, go to the Vertex AI dashboard in the Online Prediction section. Note the URL as you need these details to connect your model with Salesforce.
#### See Also
- [_Salesforce Developer_: CDP Python Connector](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_python_connector.htm)
- [_Salesforce Help_: Create a Connected App](https://help.salesforce.com/s/articleView?id=xcloud.connected_app_create.htm&type=5&language=en_US)
# SFR-v2-small Embedding Model Reference
The SFR-v2-small embedding model offers an enhanced context window of 8,000 tokens and significantly improves user experience and model capabilities.
### Required Editions
The following provides technical information about the SFR-v2-small embedding model.

Note If Salesforce removes this model due to regulatory changes affecting LLMs developed by Chinese entities, you'll receive the lesser of 90 days notice or the maximum time allowed by applicable law to rebuild your search index with an alternative model.
| MoDel Info | Details |
| --- | --- |
| Model type | Text embedding model that accepts text as input and generates 1024-dimensional continuous embedding vectors. It is trained with contrastive loss on query and document pairs. |
| Model architecture | 434M parameter language model |
| Context window | 8192 |
| Model lineage | No previous production models |
| Languages | English |
| Finetuned from model | gte-large-en-v1.5 |
| Quantized from model | N/A |
| Disclaimers and copyright attributions | Apache license 2.0 |
## Technical Specifications
- Number of layers: 24
- Embedding dimension: 1024
- Number of parameters: 434 million
- Model context size: 8,000
- Supported language: English
## Performance and Evaluation
The following captures public benchmarking scores and comparrisons to other embedding models.
- Improvement of +7.5% (15% relative) in retrieval performance over e5-large-v2
- Increased context length from 512 to 8,000 tokens, allowing more flexible knowledge processing
| MoDel Info | MTEB (56 tasks) | Retrieval (15 tasks) | Model Size | Embedding Dimension | Context Length |
| --- | --- | --- | --- | --- | --- |
| e5-large-v2 | 62.2 | 50.6 | 335 million | 1024 | 512 tokens |
| SFR-v2-small | 65.9 | 58.1 | 434 million | 1024 | 8192 tokens |
# Share Data Between Data 360 Orgs
Share Data 360 objects, such as data lake objects (DLOs), data model objects (DMOs), and calculated insights objects (CIOs), between Data 360 instances in different regions or with other Data 360 orgs using a data share.
### Required Editions
1. To receive data from a Data 360 org, add the org to allowlist. For more information, see [Add a Data 360 Org to Allowlist](https://help.salesforce.com/s/articleView?id=data.c360_a_add_dc_org_to_allowlist.htm&type=5&language=en_US).
2. Identify the Data 360 objects you want to share and create a data share in Data 360. For more information, see [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&type=5&language=en_US).
3. To establish connectivity with another Data 360 org, create a data share target in Data 360. For more information, see [Create Data Share Target to Connect with a Data 360 Org](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_datacloud.htm&type=5&language=en_US).
4. To make the Data 360 objects accessible in the other Data 360 org, link the data share with the data share target. For more information, see [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&type=5&language=en_US). Regardless of the type of Data 360 object shared by the source org, it is modelled as a DLO in the target Data Cloud org.
5. Accept the data share received from a Data 360 org, see [Accept Data Share Request in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_accept_data_share_request.htm&type=5&language=en_US).
- **[Add a Data 360 Org to Allowlist](https://help.salesforce.com/s/articleView?id=data.c360_a_add_dc_org_to_allowlist.htm&release=264.0.0&type=5)**
Add the Data 360 orgs that can send data sharing requests to your org.
- **[Create Data Share Target to Connect with a Data 360 Org](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_datacloud.htm&release=264.0.0&type=5)**
Create a data share target in Data 360 to establish connectivity with another Data 360 org.
- **[Accept Data Share Request in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_accept_data_share_request.htm&release=264.0.0&type=5)**
To share data between Data 360 orgs, target orgs must accept the share requests from the source org.
- **[Billing Considerations for Data Sharing Between Data 360 Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_sharing_with_data_cloud.htm&release=264.0.0&type=5)**
Data Sharing Between Data 360 Orgs impacts the consumption of credits used for billing on both the source and target orgs.
# Share Data with Amazon SageMaker
Amazon SageMaker includes AWS Glue Data Catalog Views, AWS Lake Formation, and AWS engines to run queries using Amazon Redshift, Athena, or Elastic MapReduce (EMR). Share Data 360 objects, such as data lake objects, data model objects, and calculated insights objects, with an Amazon Redshift account using a data share.
- Some of the required steps and links are external to Salesforce content. Salesforce doesn’t maintain these links.
- Review the prerequisites in [Harness Zero Copy Data Sharing from Salesforce Data Cloud to Amazon Redshift for Unified Analytics – Part 1](https://aws.amazon.com/blogs/big-data/harness-zero-copy-data-sharing-from-salesforce-data-cloud-to-amazon-redshift-for-unified-analytics-part-1/).
Sharing data with Amazon SageMaker allows you to access Salesforce Data 360 objects from Amazon Redshift, Athena, or EMR using Athena and Redshift SQL dialects. Link the data share to an Amazon SageMaker data share target to make the Data 360 objects available to the Amazon Redshift account. You can then query live, harmonized, and unified data from Amazon Redshift.
1. Identify the Data 360 objects that you want to access, and create a data share in Data 360. See [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&release=264.0.0&type=5 "Select the Data 360 objects that you want to include in a data share to share with an external system.").
2. Create a data share target in Data 360 to establish connectivity with an Amazon Redshift account. See [Create a Data Share Target to Connect with Amazon SageMaker](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_redshift.htm&release=264.0.0&type=5 "To establish connectivity with an Amazon Redshift account, create an Amazon SageMaker data share target in Data 360.").
3. Link the data share with the data share target to make Data 360 objects accessible in Amazon Redshift. See [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.").
Once you link the data share and the data share target, it is available in AWS.
4. In the customer AWS account, on the Lake Formation console, accept the data share, create the resource link to the target region, mount Salesforce Data 360 objects as data catalog views, and grant permissions to query the live and unified data in Amazon Redshift. See [Harness Zero Copy Data Sharing from Salesforce Data Cloud to Amazon Redshift for Unified Analytics – Part 1](https://aws.amazon.com/blogs/big-data/harness-zero-copy-data-sharing-from-salesforce-data-cloud-to-amazon-redshift-for-unified-analytics-part-1/).
Data 360 supports data sharing in the same region for both Amazon Redshift Serverless and provisioned RA3 clusters. To access shared objects across regions, provision Amazon Redshift Serverless in the same region as Data 360. Provisioned RA3 clusters don't support accessing shared objects across regions. See [Harness Zero Copy Data Sharing from Salesforce Data Cloud to Amazon Redshift for Unified Analytics – Part 2](https://aws.amazon.com/blogs/big-data/harness-zero-copy-data-sharing-from-salesforce-data-cloud-to-amazon-redshift-for-unified-analytics-part-2/).
- **[Create a Data Share Target to Connect with Amazon SageMaker](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_redshift.htm&release=264.0.0&type=5)**
To establish connectivity with an Amazon Redshift account, create an Amazon SageMaker data share target in Data 360.
- **[Supported Regions for Amazon Redshift Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_aws_supportability_redshift.htm&release=264.0.0&type=5)**
Data Cloud supports same-region and cross-region data sharing.
#### See Also
- [_Salesforce Help_: Private Connect for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_data_cloud.htm&release=264.0.0&type=5 "Private Connect uses Amazon Web Services (AWS) PrivateLink to establish a point-to-point network integration between your AWS virtual private cloud (VPC) and your Data 360 tenant. Private Connect provides a connection from Data 360 to your data source without exposing your network traffic to the public internet.")
# Share Data with Databricks
Share Data 360 objects with a Databricks account using a data share. Link the data share to a Databricks data share target to make the Data 360 objects available to the Databricks account.

Important
- Data shares don't honor the data governance policies enforced by Data 360. Apply those policies at the data share target.
- To comply with data policies and regulations, data sharing allows you to include the `IndividualGDPRState__dll` object, which provides individuals with consent information. You can create a join between Individual ID and other tables to honor the consent data for an individual at the data share target.
- Admins or privileged users in the receiving organization other than Salesforce Data 360 can view and query all records of the data lake objects (DLOs) mapped to data model objects (DMOs) in the data share. This depends on the security construct defined at the external system.
Before you begin, review [Supported Regions for Databricks Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_databricks_supportability.htm&release=264.0.0&type=5 "Data Cloud supports integration with the Databricks regions listed in Databricks clouds and regions.").
1. Identify the Data 360 objects you want to share and create a data share in Data 360. For more information, see [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&type=5&language=en_US).
2. To establish connectivity with a Databricks account, create a data share target in Data 360. For more information, see [Create Data Share Target to Connect with Databricks](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_databricks.htm&type=5&language=en_US)
3. To make the Data 360 objects accessible in Databricks, link the data share with the data share target. For more information, see [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&type=5&language=en_US).
You can view shared objects on the Databricks Catalog page.
- **[Create a Data Share Target to Connect with Databricks](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_databricks.htm&release=264.0.0&type=5)**
To establish connectivity with a Databricks account, create a data share target in Data 360.
- **[Supported Regions for Databricks Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_databricks_supportability.htm&release=264.0.0&type=5)**
Data Cloud supports integration with the Databricks regions listed in Databricks clouds and regions.
# Share Data with Databricks Using Query Federation
Securely share Data 360 data with Databricks without migrating your data from Data 360 to Databricks by running federated queries using Zero Copy Data Federation. You can access your data lake, data model, and calculated insight objects in your workspace using the Unity Catalog in Databricks.
For more information, see [Run Federated Queries on Salesforce Data Cloud](https://docs.databricks.com/en/query-federation/salesforce-data-cloud.html).
#### See Also
- [_External Site_: Run federated queries on Salesforce Data Cloud](https://docs.databricks.com/en/query-federation/salesforce-data-cloud.html)
# Share Data with Google BigQuery
You can access Data 360 objects as datasets in Google BigQuery by creating a data share. Zero copy integration allows data to be directly shared and queried without copying it into Google BigQuery. When data is accessible in Google BigQuery, you can work with harmonized and unified data from Data 360. Sharing data involves these high-level steps.
Before you begin:
- Review [Supported Regions for Google BigQuery Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_region_supportability_bq.htm&release=264.0.0&type=5 "Data Cloud supports cross-cloud data sharing with Google BigQuery. In cross-cloud data sharing, Google BigQuery can be in any location where data sharing is available.").
- If you use VPC Service Controls and if the Analytics Hub API is restricted, then create an egress rule in the VPC Service Controls Perimeter to include the Salesforce Analytics Hub Producer project. For more information, see [Analytics Hub VPC Service Controls rules](https://cloud.google.com/bigquery/docs/analytics-hub-vpc-sc-rules).
1. Identify the Data 360 objects that you want to access.
2. Create a data share in Data 360.
See [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&release=264.0.0&type=5 "Select the Data 360 objects that you want to include in a data share to share with an external system.").
3. Establish connectivity with Google BigQuery by creating a data share target in Data 360.
See [Create a Data Share Target to Connect with Google BigQuery](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_google_bq.htm&release=264.0.0&type=5 "To establish connectivity with a Google BigQuery account, create a data share target in Data 360.").
4. Link the data share with the data share target to make the Data 360 objects accessible in BigQuery.
See [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.").
5. In Google BigQuery [subscribe to the Data 360 data shares using the Analytics hub](https://help.salesforce.com/s/articleView?id=data.c360_a_subscribe_data_shares_bq_analytics_hub.htm&release=264.0.0&type=5 "The Google Cloud users can subscribe to the data using the Analytics Hub.").
- **[Create a Data Share Target to Connect with Google BigQuery](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_google_bq.htm&release=264.0.0&type=5)**
To establish connectivity with a Google BigQuery account, create a data share target in Data 360.
- **[Subscribe to Data Shares in Google Analytics Hub](https://help.salesforce.com/s/articleView?id=data.c360_a_subscribe_data_shares_bq_analytics_hub.htm&release=264.0.0&type=5)**
The Google Cloud users can subscribe to the data using the Analytics Hub.
- **[Supported Regions for Google BigQuery Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_region_supportability_bq.htm&release=264.0.0&type=5)**
Data Cloud supports cross-cloud data sharing with Google BigQuery. In cross-cloud data sharing, Google BigQuery can be in any location where data sharing is available.
# Share Data with Snowflake (Legacy)
To access Data 360 data, create a data share that contains Data 360 objects. You can access Data 360 objects as views in a Snowflake account. When data is available in Snowflake, you can work on harmonized and unified data.

Important You can’t create legacy Snowflake data share targets. [Create a Snowflake V2 data share target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflakev2.htm&type=5&language=en_US) instead, and link your existing and new data shares to it. Migrate existing data shares that are linked to a legacy Snowflake data share target to a Snowflake V2 data share target. See [Migrate Data Shares with Legacy Snowflake Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_migrate_data_shares_legacy_snowflake.htm&type=5&language=en_US). Don’t unlink an existing data share from its legacy target until you verify that the Snowflake V2 connection works. Downstream processes in Snowflake can refer to the database that was created using the legacy target.
Before you begin:
- Make sure that your Snowflake admin adds the [Data 360 IP Addresses](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_ip_address_allowlist.htm&release=264.0.0&type=5 "Data 360 uses these IP addresses to communicate with external services such as Amazon S3, Google Cloud Storage, Azure blob storage, Snowflake, or SFTP. If your security policy requires a strict network ACL (access control list), make sure to include these IP addresses to your allowlists.") to the allowlist.
- Verify [Supported Data 360 Regions for Snowflake Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_aws_supportability_snowflake.htm&release=264.0.0&type=5 "Data 360 supports integration with Snowflake in these regions.").
1. Identify the Data 360 objects you want to access and create a data share in Data 360.
For more information, see [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&release=264.0.0&type=5 "Select the Data 360 objects that you want to include in a data share to share with an external system.").
2. Create users in Snowflake and obtain the user credentials.
For more information, see [Get User Credentials from Snowflake](https://help.salesforce.com/s/articleView?id=data.c360_a_get_user_details_snowflake.htm&release=264.0.0&type=5 "Gather the user information and authentication details in Snowflake to create a data share target.").
3. To establish connectivity with a Snowflake account, create a data share target in Data 360.
For more information, see [Create Data Share Target and Connect with Snowflake](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflake.htm&release=264.0.0&type=5 "Create a data share target in Data 360 to establish connectivity with a Snowflake account.").
4. To make the Data 360 objects accessible in Snowflake, link the data share with the data share target.
For more information, see [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.").
5. View the data share in Snowflake.
1. Select the data share from private sharing in the Snowflake account.
2. Create a database on the data share.
To view the Data 360 objects in the database login as an ACCOUNTADMIN. You can query the data and create joins across Data 360 and Snowflake tables. If you’re using the classic console, the data shares are available on the Inbound tab.
- **[Get User Credentials from Snowflake](https://help.salesforce.com/s/articleView?id=data.c360_a_get_user_details_snowflake.htm&release=264.0.0&type=5)**
Gather the user information and authentication details in Snowflake to create a data share target.
- **[Create a Data Share Target to Connect with Snowflake](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflake.htm&release=264.0.0&type=5)**
Create a data share target in Data 360 to establish connectivity with a Snowflake account.
- **[Supported Data 360 Regions for Snowflake Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_aws_supportability_snowflake.htm&release=264.0.0&type=5)**
Data 360 supports integration with Snowflake in these regions.
- **[Supported Data 360 Government Cloud Regions for Snowflake Integration](https://help.salesforce.com/s/articleView?id=data.c360_a_data_shares_gov_cloud_aws_supportability_snowflake.htm&release=264.0.0&type=5)**
Data 360 in Government Cloud supports integration with these Snowflake regions.
#### See Also
- [_Salesforce Help_: Private Connect for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_private_connect_data_cloud.htm&release=264.0.0&type=5 "Private Connect uses Amazon Web Services (AWS) PrivateLink to establish a point-to-point network integration between your AWS virtual private cloud (VPC) and your Data 360 tenant. Private Connect provides a connection from Data 360 to your data source without exposing your network traffic to the public internet.")
# Share Data with Snowflake V2
Share Data 360 data with Snowflake using the Snowflake V2 connector. Create a data share target, link data shares, and migrate legacy targets.
### Required Editions

Note If you have an existing data share linked to a legacy Snowflake data share target, migrate it to a Snowflake V2 data share target. For more information, see [Migrate Data Shares with Legacy Snowflake Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_migrate_data_shares_legacy_snowflake.htm&type=5&language=en_US).
User Permissions Needed
To share data with Snowflake V2:
Data Cloud Architect permission set
1. Identify the Data 360 objects you want to access and create a data share in Data 360.
For more information, see [Create a Data Share](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_shares.htm&release=264.0.0&type=5 "Select the Data 360 objects that you want to include in a data share to share with an external system.").
2. To establish connectivity with a Snowflake account, create a data share target in Data 360.
For more information, see [Create a Snowflake V2 Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflakev2.htm&release=264.0.0&type=5 "Create a Snowflake V2 data share target in Data 360 to establish connectivity with a Snowflake account.").
3. To make the Data 360 objects accessible in Snowflake, link the data share with the data share target.
For more information, see [Link or Unlink Data Shares and Data Share Targets](https://help.salesforce.com/s/articleView?id=data.c360_a_link_data_shares_with_data_share_target.htm&release=264.0.0&type=5 "Link data shares with a data share target to make them available to an external system. You can also unlink a data share from a data share target.").
4. In Snowflake, accept the share and create a database to query shared views.
For more information, see [Snowflake documentation](https://docs.snowflake.com/en/user-guide/data-integration/zero-copy/salesforce/explore-data-products#list-shared-data-products).
- **[Create a Snowflake V2 Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_data_share_target_snowflakev2.htm&release=264.0.0&type=5)**
Create a Snowflake V2 data share target in Data 360 to establish connectivity with a Snowflake account.
- **[Migrate Data Shares with Legacy Snowflake Data Share Target](https://help.salesforce.com/s/articleView?id=data.c360_a_migrate_data_shares_legacy_snowflake.htm&release=264.0.0&type=5)**
Move data shares that are linked to a legacy Snowflake data share target to a Snowflake V2 data share target. Verify that data sharing works before you unlink the legacy target.
# Shopping Cart Insight Template
The Data 360 shopping cart insight template creates a calculated or real-time insight based on actions in your customer’s shopping cart. Analyze customer interactions with their shopping cart, from items added to purchases completed or abandoned. Shopping cart insights provide a view of the customer's current shopping cart state.
### Required Editions
Use this insight to:
- Identify popular product combinations.
- Reference cart contents to determine cart abandonment activity.
- Understand the impact of promotions or discounts on cart completion.
- Optimize the checkout flow to reduce friction.
- Improve product recommendations and merchandising strategies.
## Model Your Customer
The shopping cart insight is modeled on an Individual or Unified Individual data model. The model represents your customer and their shopping cart experience.
- Individual: Your customer’s shopping cart is unique to each device or browser that they use.
- Unified Individual: Your customer’s shopping cart is shared across all of their devices and browsers.
To use a Unified Individual, choose a related identity resolution ruleset. The ruleset defines how to identify a customer across multiple shopping sessions. See [Identity Resolution Rulesets](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_ruleset.htm&release=264.0.0&type=5 "Rulesets contain match and reconciliation rules that tell the customer data platform how to link multiple sources of data into a unified profile. Unified profile information is stored in data model objects created by the ruleset.") in _Salesforce Help_.
## Process Shopping Cart Data
To create a shopping cart insight, choose between calculated and real-time insights.
Calculated Insight
A calculated insight processes data in batches, typically on a schedule. This approach is suitable for analyses that don't require immediate updates. Use historical data for trend analysis and deeper analysis of customer behavior over time.
Real-time Insight
A real-time insight provides continuously updated data and reflects customer actions as they happen. Real-time insights require real-time data graphs and support immediate responses, such as triggering personalized offers based on current cart contents or identifying immediate abandonment risks. See [Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graphs.htm&release=264.0.0&type=5 "A data graph brings together structured data from your Data Model Objects (DMOs) in Data 360. It combines this data to create easy-to-use views of your information.") in _Salesforce Help_.
## Model Your Shopping Cart
Shopping cart insights map data model object (DMO) fields to events in your customer’s shopping carts. The insight uses the Shopping Cart Engagement DMO, Shopping Cart Product Engagement DMO, and Product Order Engagement DMO. Configure the required DMO fields.
DMO
FIELD NAME
Field API Name
Individual DMO
Individual ID
ssot__Id__c
Shopping Cart Engagement DMO
Individual
ssot__IndividualId__c
Shopping Cart Engagement ID
ssot__Id__c
Shopping Cart
ssot__ShoppingCartId__c
Created Date
ssot__CreatedDate__c
Shopping Cart Event Type
ssot__ShoppingCartEventTypeId__c
Shopping Cart Product Engagement DMO
Shopping Cart Engagement ID
ssot__ShoppingCartEngagementId__c
Product SKU
ssot__ProductSKUNumber__c
Product
ssot__ProductId__c
Product Quantity
ssot__ProductQuantity__c
Product Price
ssot__ProductPrice__c
Product Image URL
ssot__ProductImageURL__c
Product Order Engagement DMO
Individual
ssot__IndividualId__c
Shopping Cart
ssot__ShoppingCartId__c
Engagement Date Time
ssot__EngagementDateTm__c
Product Order Event Type
ssot__ProductOrderEventTypeId__c
## Track Shopping Cart Events
Event tracking captures the actions a customer takes related to their shopping cart, including adding items, removing items, and completing a purchase.
Your development team typically configures these events using your analytics platform's SDK or tag manager. Verify the event values by reviewing engagement events in [Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_data_explorer.htm&release=264.0.0&type=5 "With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.").
Shopping Cart Engagement DMO - Shopping Cart Event Type field
- Add to cart event: A product is added to the shopping cart.
- Remove from cart event: A product is removed from the shopping cart.
- Replace event: All products in the cart are replaced.
Product Order Engagement DMO - Product Order Event Type field
- Purchase event: An order is successfully completed.
## Insight Object Schema
The insight creates one output record for each product in a customer’s shopping cart. The individual, shopping cart, and product fields identify each record. Product quantity, product price, and last updated date come from shopping cart events. The insight derives the total amount by multiplying the product quantity by the product price.
Use this object for multiple business goals, such as cart analytics, website personalization, and abandoned cart workflows.
| Output Field | Role | Data Type | Description |
| --- | --- | --- | --- |
| Individual ID | Dimension, key | Text | Identifies the Individual or Unified Individual associated with the shopping cart. |
| Shopping Cart ID | Dimension, key | Text | Identifies the shopping cart associated with the product. |
| Product SKU | Dimension, key | Text | Identifies the product in the shopping cart. |
| Product Name | Dimension | Text | Specifies the name of the product. |
| Product Quantity | Measure | Number | Specifies the current quantity of the product in the shopping cart. |
| Product Price | Measure | Number | Specifies the price of one unit of the product. |
| Created Date | Dimension | Date and time | Specifies when the product record insight was created. |
| Total Amount | Measure | Number | Specifies the derived total for the product quantity multiplied by the product price. |
| Product Image URL | Dimension | Text | The URL of the image of the product involved in the shopping cart activity. |
| Product ID | Dimension | Text | Identifies the product involved in the shopping cart activity. |
## Get Started
# Simple Start in Data 360
Streamline your initial Data 360 setup with Simple Start. Bypass manual bundle configuration and field mapping by syncing metadata and creating standardized data structures for your Salesforce CRM data in minutes. Because the system initially syncs only metadata, you consume credits only after activating related data streams and downstream processes.
### Required Editions
## Key Benefits
- **Automated setup:** The platform automatically creates CRM data streams and data lake objects (DLOs) based on your connected home Salesforce org's metadata.
- **Review before ingestion:** Simple Start creates data streams in an inactive state, so you can review your schema before ingestion begins.
## Metadata Sync
Data 360 requires a home org connection to perform the metadata sync. This sync process automatically creates the necessary data streams, data lake objects (DLOs), and data model object (DMO) mappings. Data 360 adds the metadata directly to the schema, so you avoid installing standard bundles or packages.

Note Metadata syncing is available only for accounts and contact objects.
Simple Start automatically performs these actions:
- Creates data streams in an inactive status to prevent immediate credit consumption.
- Generates standard mappings for Salesforce standard objects. See [Data 360 DMO Mapping Guide](https://int-simplestart-1777c691e568.herokuapp.com/docs/data/data-cloud-dmo-mapping/guide/c360dm-model-data.html).
- **[Limitations and Key Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_limitations_considerations_for_simple_start.htm&release=264.0.0&type=5)**
Review these limitations before you use Simple Start:
- **[Activate Data Stream Sync for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_activate_data_stream_sync_for_data360.htm&release=264.0.0&type=5)**
After Simple Start adds your Salesforce CRM metadata to Data 360, you can activate the data stream to ingest data. Simple Start ingests streams in an inactive state to prevent immediate credit consumption.
- **[Troubleshoot Simple Start Errors](https://help.salesforce.com/s/articleView?id=data.c360_a_troubleshoot_simple_start.htm&release=264.0.0&type=5)**
Get tips for solving the most common Simple Start errors.
# Simplify Segment Filters with Shortcuts
Save commonly used segment filter attributes with their data model paths as shortcuts to reuse them across segments and activations. Instead of navigating the attribute library to find the right data model object (DMO), path, and attribute each time, you can select a saved shortcut that has the required configuration.
### Required Editions

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
When you build segments, finding the right attribute often requires knowledge of your organization's data model, including which DMOs to use and which paths connect them. Attribute shortcuts reduce that complexity by saving the segment-on object, path, and target attribute as a reusable filter. Create a shortcut one time, and any user with segment-building permissions can use it across segments. You can apply the same filter criteria consistently.
Attribute shortcuts appear in a dedicated Shortcuts tab in the attribute library panel alongside the existing data model tab. The Shortcuts tab appears only after you save your first shortcut.
## How Attribute Shortcuts Work
Each attribute shortcut stores these components.
- The segment-on object that segments are built on
- The object path from the segment-on object to the target DMO
- The target attribute on the final DMO in the path
When you add a shortcut to a segment, Data 360 applies the saved path and attribute configuration automatically. You then configure only the operator and values for your filter criteria.
Attribute shortcuts operate at the filter level, not the container level. A shortcut stores the attribute itself and its path but doesn't capture container-level context, such as aggregation settings or other filters in the same container.
## Considerations
Keep these points in mind when working with attribute shortcuts.
- Use a unique name for every shortcut. If you try to save a shortcut with a name that's in use, you're prompted to select a different name.
- Each attribute path can have only one shortcut. If a shortcut exists for a given path, you can use the existing shortcut or provide a unique path to create one.
- Shortcuts are scoped to the data space where they're created.
- Shortcuts are saved at the org level.
- Shortcuts are packageable through DataKits, making them deployable across orgs and sandbox-compatible.
- Attribute shortcuts are limited to 500 per tenant as a guardrail.

Example
A data specialist at a retail company frequently builds segments based on products that customers have purchased. The path from the Unified Individual profile through email to Product involves multiple DMOs. Instead of navigating this path each time, the specialist saves it as an attribute shortcut called "Product Drill Up" with the path Unified → Email → Product. Now, any team member building a segment can drag the "Product Drill Up" shortcut to the canvas and immediately start configuring filter values without knowing the underlying data model structure.
- **[Create an Attribute Shortcut](https://help.salesforce.com/s/articleView?id=data.c360_a_create_attribute_shortcut.htm&release=264.0.0&type=5)**
Save a frequently used attribute and its data model path as a shortcut so that you and other segment builders can reuse it without navigating the full attribute library each time.
- **[Build a Segment with Attribute Shortcuts](https://help.salesforce.com/s/articleView?id=data.c360_a_build_segment_attribute_shortcuts.htm&release=264.0.0&type=5)**
Speed up segment creation by using attribute shortcuts that store filter attributes with preconfigured data model paths. Instead of browsing the full attribute library, select from shortcuts that your team has set up.
# SMS Engagement Filters
Here are some examples of common SMS engagement use cases.
## SMS Engagement over a Period of Time
This filter looks for individuals who had at least two SMS engagements between May 1, 2020 and June 1, 2020.

Example
- SMS Engagement | Count | At Least | 2
- Engagement Date Time | Is Between | 2020-05-01 AND 2020-06-01

## Delivered SMS Messages
This filter looks for individuals who had an SMS delivered to their phone.

Example
- SMS Engagement | Count | At Least | 1
- Engagement Channel Action | Is Equal To | Delivered

## Keyword Text and Opt Ins
This filter finds individuals who opted in to the keyword text FreeGift in the next 30 days.

Example
- SMS Engagement | Count | At Least | 1
- Engagement Channel Action | Is Equal To | Opt In
- AND
- Engagement Date Time | Next Number Of Days | 30
- AND
- Keyword Text | Is Equal To | FreeGift
## Keyword Engagement in the Last 30 Days
This filter finds individuals who have engaged with the keyword EasterHunt! at least three times in the last 30 days.

Example
- SMS Engagement | Count | At Least | 3
- Keyword Test | Is Equal To | EasterHunt!
- AND
- Engagement Date Time | Last Number of Days | 30
## Keyword Engagement by Location
This filter finds individuals who have engaged with the keyword TreasureTruck!, have a postal code text of 734, and the city name of San Francisco or New York.

Example
- SMS Engagement | Count | At Least | 1
- Keyword Text | Is Equal To | TreasureTruck!
AND
- Contact Point Phone | Count | At Least | 1
- Postal Code Text | Begins With | 734
- AND
- City Name | Is In | San Francisco, New York
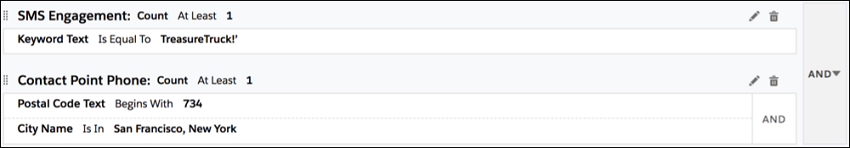
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
# Solution Workflow for Related Attributes
Review the solution workflow for the related attributes use cases.
Establish Campaign Requirements
Complete Steps in Data 360
Complete Steps in Marketing Cloud Engagement
Identify campaign goals
Identify personalization components
Identity audience and data sources
Gather campaign materials
Create an audience segment.
Activate the segment and add attributes
Filter attributes and publish to Marketing Cloud Engagement
Locate the audience segment stored in a data extension
Create campaign content
Create, test, and activate the journey
# Source Object Schema Modifications
You can modify Data 360 source object schema on the Data Stream details page. All changes are applied to future data imports. To apply logic retroactively, pull from the source and ingest into Data 360.
These actions are supported for each connector.
| Action Type | Field Type | CRM Connector | S3 Connector with Source Headers | S3 Connector Without Source Headers | Marketing Cloud Engagement Data Extension Connector | Web SDK |
| --- | --- | --- | --- | --- | --- | --- |
| Add | Source Field | X | X | X | X | X |
| Add | Formula Field | X | X | X | X | X |
| Update | Formula Field | X | X | X | X | |
| Disable | Source Field | X | X | | | |
| Disable | Formula Field | X | X | | | |
| Re-enable | Source Field | | X | | | |

Important When editing a source object schema in Data 360, consider these behaviors.
- If a source object doesn’t have a header, only Add and Update actions are supported. To maintain proper ordering based on column index, add new fields to the end of the file.
- Marketing Cloud Engagement data extensions don’t support the Remove Field action. Removing fields from the data extension in Engagement causes data to be inaccurate.
- After the Engagement data extension is configured in Data 360, don’t change the schema. Data 360 doesn’t support schema changes.
For more information on disabling data stream fields, refer [Disable a Data Stream Field](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_data_stream_fields.htm&release=264.0.0&type=5 "If a field is no longer required in a data stream, you can disable it. Disabling a field removes it from the data stream, and no new data is ingested. You can’t assign the name of a disabled field to a new field.").
- **[Add a Formula Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_action.htm&release=264.0.0&type=5)**
After you create your schema in Data 360, you can add formula fields.
- **[Add a Source Field](https://help.salesforce.com/s/articleView?id=data.c360_a_add_new_source_fields.htm&release=264.0.0&type=5)**
After your schema is created in Data 360, you can add source fields to the data stream as needed. When you add a field to an object in a connected Salesforce CRM org, make sure that the correct permissions are set for the field.
- **[Disable Source Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_disable_action.htm&release=264.0.0&type=5)**
After your schema is created you can disable source fields as needed.
- **[Update a Schema](https://help.salesforce.com/s/articleView?id=data.c360_a_update_action.htm&release=264.0.0&type=5)**
After your schema is created in Data 360, update formula fields or source fields as needed.
# Source, Object Name, and Object API Name
When ingesting a data set into Data 360, name the data set source.
The source corresponds to the technology-based tool that marketers use to execute marketing activities. These tools can include traditional software, social media tools, CRM, ecommerce, measurement, insight, customer service, SEO, and analytics. You can reuse a source definition as appropriate for each data set that you import.
You’re also prompted to name the object and the associated object API. This is similar to naming the data set associated with that source. In Data 360, this pair is referred to as the data lake object (DLO).
Object names must be unique and adhere to these guidelines:
- They can only contain underscores and alphanumeric characters.
- They must begin with a letter.
- They can't include spaces, end with an underscore, or contain two consecutive underscores.
For example, an ecommerce tool has two data sets: one contains order headers and the other order details. You can use the same source name across both data sets, but each object name and API name must be unique.
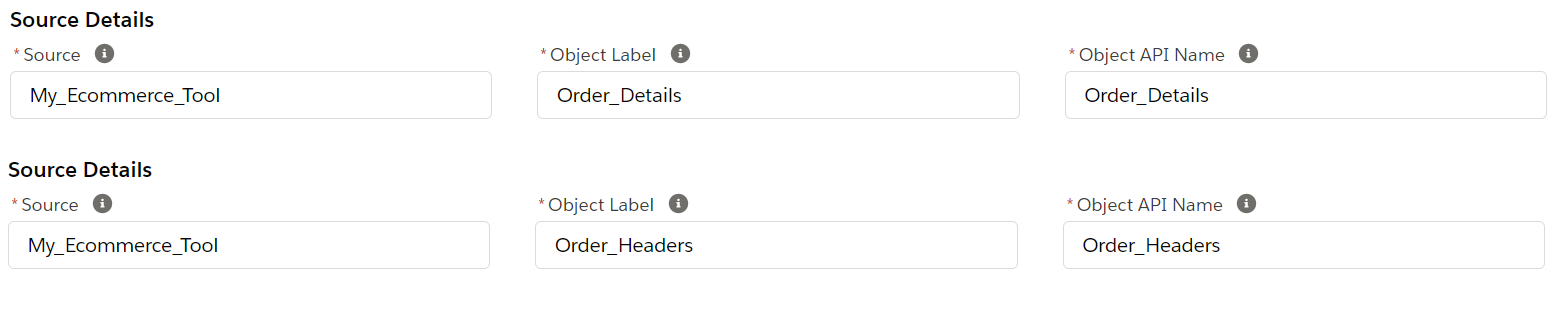
# Special Handling of DMO Relationships in Data Graphs
Data model object (DMO) relationships can affect how data is processed and reflected in data graphs, particularly in real-time data graphs. Review DMO relationship types when designing data graphs to make sure that processing behavior aligns with your expected update patterns.
### Required Editions
Real-time data graphs support 1:1 and 1:N DMO relationships. An N:1 relationship occurs when multiple child records reference a single parent record. For example, consider the relationship between sale order products and product categories. A sale order can contain multiple products, and each product in the order is represented as a sale order product record. Each sale order product is associated with a product category, such as Electronics or Fashion. A single order might include an iPhone and AirPods, which both belong to the Electronics category, and a T-Shirt, which belongs to the Fashion category.
In this scenario, multiple sale order product records reference the same product category record. For example, both the iPhone and AirPods sale order product records reference the Electronics product category. This relationship represents an N:1 relationship, where many child records map to one parent record. The child record’s foreign key (product category ID) points to the parent record’s primary key, allowing multiple child records to reference the same parent record.
Consider these two scenarios of N:1 relationship support based on when the real-time data graph was created.
- New real-time data graph behavior: Newly created or edited real-time data graphs don’t support N:1 relationships. If adding a DMO introduces an N:1 relationship, the system blocks the selection during creation or editing.
- Existing real-time data graph behavior: Real-time data graphs that were created before this restriction was introduced may already include N:1 relationships. These graphs continue to run for backward compatibility. However, changes to the parent DMO in an N:1 relationship aren’t immediately reflected in related records within the real-time data graph. Updated values become available only after the data graph is rebuilt or refreshed according to its configuration.
This restriction applies only to newly created real-time data graphs. Standard data graphs continue to support N:1 relationships.
#### See Also
- [_Salesforce Help_: Create a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_graph.htm&release=264.0.0&type=5 "Before creating a data graph in Data 360, decide which existing data model object (DMO) to use as the primary DMO. The primary DMO determines which related objects you can include in the data graph.")
- [_Salesforce Help_: Edit a Data Graph](https://help.salesforce.com/s/articleView?id=data.c360_a_edit_a_data_graph.htm&release=264.0.0&type=5 "You can change a data graph’s name and description, associate new data model objects (DMO), and make additive changes to the existing primary and associated DMOs.")
- [_Salesforce Help_: Data Graph Data Structures](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graph_data_structures.htm&language=en_US)
# Split a Data Stream Use Case
A data stream containing guest checkout information includes profile and engagement data. Split the data so that it can be mapped into separate data lake objects (DLOs), one for profile information and one for engagement.
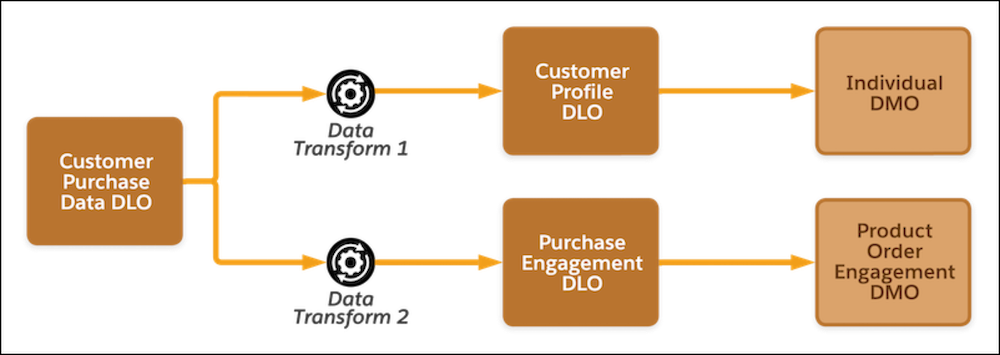
To split a single data stream into multiple objects, set up multiple data transforms that read from the same source DLO and write to different DLOs.
# Split Transformation: Break Up Column Values
Split a string in a text column into two values by specifying a delimiter. To split column values into more than two parts, add multiple instances of the split transformation. For instance, you can use three split transformations to split an address into street address, city, state, and ZIP code.
1. In a transform node, select the text column in the Preview tab.
2. In the transform toolbar, click the Split button ().
3. Select the delimiter.
4. Enter the column labels for both new columns.
5. Click **Apply**.

Tip To remove the original unsplit column, add the drop columns transformation after the split transformation.
6. To view the canvas, click the Collapse button ().
7. Save the data transform.
# SQL Functions for Insights
Use these aggregate, datetime, analytical, formatting, math and statistical, and boolean functions when you author calculated insights in Data 360. The Aggregatable column indicates whether a function's output can be rolled up across fewer dimensions when queried in segments or activations.
### Required Editions

Note Streaming and real-time insights support only the SUM and COUNT aggregate functions.
## Aggregatable and Non-Aggregatable Metrics
Some functions produce metrics that can be rolled up or collapsed across dimensions. These are called aggregatable metrics. Functions such as SUM, COUNT, and AVG are examples of aggregatable metrics. You can query the result for any subset of the dimensions you defined when you created the insight.
Other functions produce non-aggregatable metrics. Functions such as RANK, NTILE, and CASE are examples of non-aggregatable metrics. Because the result depends on all the dimensions at once, you can't reduce or collapse the metric to a smaller set of dimensions. When you query a non-aggregatable metric, you must provide values for all the dimensions that were defined when you created the insight.
For example, if you create a metric called "Rank customers by total spend by product category and location" using the RANK function, you can't later query that rank for product category alone. When querying the metric, you must always specify both "Product Category" and "Location."
```sql
SELECT
ssot__SalesOrder__dlm.ssot__SalesChannelId__c AS channel__c,
RANK() OVER (ORDER BY SUM(ssot__SalesOrder__dlm.ssot__GrandTotalAmount__c) ASC) AS spend_rank__c,
UnifiedIndividual__dlm.ssot__Id__c AS unified_individual__c
FROM
ssot__SalesOrder__dlm
JOIN IndividualIdentityLink__dlm
ON ssot__SalesOrder__dlm.ssot__SoldToCustomerId__c = IndividualIdentityLink__dlm.SourceRecordId__c
JOIN UnifiedIndividual__dlm
ON IndividualIdentityLink__dlm.UnifiedRecordId__c = UnifiedIndividual__dlm.ssot__Id__c
GROUP BY
unified_individual__c,
channel__c
```
You can see whether a function produces a non-aggregatable metric in the object home screen of the Calculated Insights.
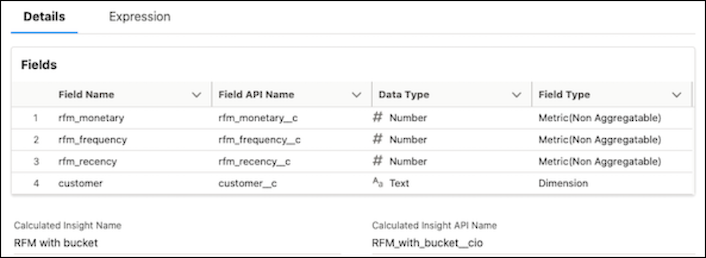
## Aggregate Functions

Important To compare the results of aggregate functions, use a CASE WHEN statement. Boolean comparison doesn't support aggregate functions.
Function
Aggregatable
Description
Example
SUMY
Calculates the total by adding all values in the selected field. Supports
numerical values.
SELECT ProductID, SUM(Quantity)
FROM OrderDetails
GROUP BY ProductID
COUNTY
Counts all values in the selected field. Supports date, text, and boolean
measures. COUNT(*) isn't supported.
SELECT
COUNT(EmailEngagement__dlm.Id__c) as email_engagement_count__c,
UnifiedIndividual__dlm.Id__c as customer_id__c
FROM EmailEngagement__dlm
AVGY
Calculates the average of all the values in the selected field. Supports
numerical values.
SELECT avg(SalesOrder__dlm.TotalAmount__c) as avg__c,
SubQuery1.Id as customer_id__c
FROM SalesOrder__dlm
MINY
Calculates the minimum value of the selected field. Supports numerical
values.
SELECT MIN(Price) FROM SalesOrder__dlm;
MAXY
Calculates the maximum value of the selected field. Supports numerical
values.
SELECT MAX(Price) FROM SalesOrder__dlm;
MEANY
Calculates the average of the given dataset by dividing the total sum by the
number of values in the dataset.
SELECT AVG(sale_amount) FROM sales;
FIRSTY
Returns the first value of the expression for a group of rows.
SELECT first(col)
FROM VALUES (10), (5), (20) AS tab(col); -- 10
LASTY
Returns the last value of the expression for a group of rows.
SELECT last(col)
FROM VALUES (10), (5), (20) AS tab(col); -- 20
APPROX_COUNT_DISTINCTN
Returns the estimated cardinality by using the HyperLogLog++ algorithm, similar
to COUNT DISTINCT. Use this function when you want to count unique occurrences of
dimensions in a calculated insight.
SELECT approx_count_distinct(col1)
FROM VALUES (1), (1), (2), (2), (3) tab(col1); -- 3
PERCENTILEN
Returns the exact percentile of the numeric column at the given percentage. The
percentage must be from 0.0 through 1.0.
SELECT percentile(col, array(0.25, 0.75))
FROM VALUES (0), (10) AS tab(col); -- [2.5, 7.5]
STDDEVN
Returns the statistical standard deviation of all values in the specified
expression.
SELECT stddev(col)
## DateTime Functions
Function
Aggregatable
Description
Example
HOUR(TIMESTAMP)N
Returns the hour component of the string or timestamp. Return type: integer
0–23.
SELECT hour('2009-07-30 12:58:59'); -- 12
DAY(DATE)N
Returns the day of the month of the date or timestamp. Return type: integer
1–31.
SELECT day('2009-07-30'); -- 30
MONTH(DATE)N
Returns the month component of the date or timestamp. Return type: integer
1–12.
SELECT month('2016-07-30'); -- 7
QUARTER(DATE)N
Returns the quarter of the year for the date. Return type: integer 1–4.
SELECT quarter('2016-08-31'); -- 3
YEAR(DATE)N
Returns the year component of the date or timestamp. Return type:
integer.
SELECT year('2016-07-30'); -- 2016
CDPHOUR(TIMESTAMP)N
Returns a timestamp representing the hour of the timestamp. Return type:
timestamp.
SELECT CdpHour('2009-07-30 01:10:05');
-- '2009-07-30 01:00:00'
CDPDAY(DATE)N
Returns a timestamp representing the 0th hour of the day. Return type:
timestamp.
SELECT CdpDay('2009-07-30 01:10:05');
-- '2009-07-30 00:00:00'
CDPMONTH(DATE)N
Returns a timestamp representing the month. Return type: timestamp.
SELECT CdpMonth('2009-07-30 01:10:05');
-- '2009-07-01 00:00:00'
CDPQUARTER(DATE)N
Returns a timestamp representing the first day of the quarter. Return type:
timestamp.
SELECT CdpQuarter('2009-07-30 01:10:05');
-- '2009-07-01 00:00:00'
CDPYEAR(DATE)N
Returns a timestamp representing the first day of the year. Return type:
timestamp.
SELECT CdpYear('2009-07-30 01:10:05');
-- '2009-01-01 00:00:00'
CURRENT_DATEN
Returns the current date at the start of query evaluation. All CURRENT_DATE
calls within the same query return the same value.
SELECT current_date(); -- 2020-04-25
DATE_SUBN
Subtracts a number of days from the date value and returns the earlier
date.
SELECT date_sub('2016-07-30', 1); -- 2016-07-29
DATE_ADDN
Adds a number of days to the date value and returns the later date.
SELECT date_add('2016-07-30', 1); -- 2016-07-31
DATEDIFFN
Returns the number of days from the start date to the end date.
SELECT datediff('2009-07-31', '2009-07-30'); -- 1
MONTHS_BETWEENN
Returns the number of months between two dates.
SELECT months_between('1997-02-28 10:30:00', '1996-10-30');
-- 3.94959677
DAYOFWEEKN
Returns the day of the week for a date or timestamp (1 = Sunday, 2 = Monday,
..., 7 = Saturday).
SELECT dayofweek('2009-07-30'); -- 5
DAYOFMONTHN
Returns the day of the month of the date or timestamp.
SELECT dayofmonth('2009-07-30'); -- 30
DAYOFYEARN
Returns the day of the year of the date or timestamp.
SELECT dayofyear('2009-07-30'); -- 211
TO_DATEN
Parses the date string with the format expression to a date. Returns null if
the input isn't valid.
SELECT to_date('2016-12-31', 'yyyy-MM-dd'); -- 2016-12-31
TO_TIMESTAMPN
Parses the timestamp string with the format expression to a timestamp. Returns
null if the input isn't valid.
SELECT to_timestamp('2016-12-31 00:12:00');
-- 2016-12-31 00:12:00
DATE_TRUNCN
Returns the timestamp truncated to the unit specified by the format
model.
SELECT date_trunc('YEAR', '2015-03-05T09:32:05.359');
-- 2015-01-01 00:00:00
HOUR_ADDN
Adds a number of hours to the datetime value and returns the later
datetime.
SELECT COUNT(SalesOrder__dlm.orderid__c) as orderid__c,
HOUR_ADD(SalesOrder__dlm.checkout_date__c, 2) as newDateHour__c
FROM SalesOrder__dlm GROUP BY newDateHour__c
HOUR_SUBN
Subtracts a number of hours from the datetime value and returns the earlier
datetime.
SELECT COUNT(SalesOrder__dlm.orderid__c) as orderid__c,
HOUR_SUB(SalesOrder__dlm.checkout_date__c, 2) as newDateHour__c
FROM SalesOrder__dlm GROUP BY newDateHour__c
NOWN
Returns the current date and time aligned to when the insight is processed. All
NOW calls within the same query return the same value. Time is calculated at
millisecond precision in UTC for your instance's region.
SELECT NOW(); -- 2020-04-25T13:00:00.000Z
SECOND_ADDN
Adds a number of seconds to a datetime value and returns the later
datetime.
SELECT SECOND_ADD('2020-04-25T13:00:00.000Z', 305);
-- 2020-04-25T13:05:05.000Z
SECOND_SUBN
Subtracts a number of seconds from a datetime value and returns the earlier
datetime. For example, use this function to include records from the last 5 minutes
at the time of batch processing.
SELECT SECOND_SUB('2020-04-25T13:00:00.000Z', 305);
-- 2020-04-25T12:54:55.000Z
## Analytical Functions
Function
Aggregatable
Description
Example
LAGN
Returns the input value at the offset row before the current row in the window.
The default offset is 1. Returns null if the input value at the offset row is
null.
SELECT a, b, lag(b)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 NULL A1 1 1 A1 2 1 A2 3 NULL
LEADN
Returns the value at the offset row after the current row in the window. The
default offset is 1. Returns null if there's no offset row.
SELECT a, b, lead(b)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 1 A1 1 2 A1 2 NULL A2 3 NULL
NTILEN
Divides the rows for each window partition into n buckets ranging from 1 to at
most n .
SELECT a, b, ntile(2)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 1 A1 1 1 A1 2 2 A2 3 1
RANKN
Computes the rank of a value in a group of values. The result is 1 plus the
number of rows preceding the current row in the ordering of the partition. Produces
gaps in the sequence.
SELECT a, b, rank(b)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 1 A1 1 1 A1 2 3 A2 3 1
PERCENT_RANKN
Computes the percentage ranking of a value in a group of values.
SELECT a, b, percent_rank(b)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 0.0 A1 1 0.0 A1 2 1.0 A2 3 0.0
DENSE_RANKN
Computes the rank of a value in a group of values. Unlike RANK, doesn't produce
gaps in the ranking sequence.
SELECT a, b, dense_rank(b)
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 1 A1 1 1 A1 2 2 A2 3 1
ROW_NUMBERN
Assigns a unique, sequential number to each row starting with 1, based on the
ordering of rows within the window partition.
SELECT a, b, row_number()
OVER (PARTITION BY a ORDER BY b)
FROM VALUES ('A1', 2), ('A1', 1), ('A2', 3), ('A1', 1) tab(a, b);
-- A1 1 1 A1 1 2 A1 2 3 A2 3 1
FIRST_VALUEN
Returns the first value of the expression for each row in the window.
SELECT first_value(col)
FROM VALUES (10), (5), (20) AS tab(col); -- 10
LAST_VALUEN
Returns the last value of the expression for each row in the window.
SELECT last_value(col)
FROM VALUES (10), (5), (20) AS tab(col); -- 20
REGEXPN
Searches strings for patterns in text.
SELECT * FROM Customers
WHERE name REGEXP '^[A-Z][a-z]+'
REGEXP_EXTRACTN
Creates dimension values by extracting them from a source dimension using
Google RE2 regular expressions.
SELECT regexp_extract('100-200', '(\\d+)-(\\d+)', 1); -- 100
REGEXP_REPLACEN
Extends REPLACE by letting you search a string for a regular expression
pattern.
SELECT regexp_replace('100-200', '(\\d+)', 'num'); -- num-num
ISNULLN
Returns true if the expression is null; otherwise, returns false.
SELECT isnull(1); -- false
ISNOTNULLN
Returns true if the expression isn't null; otherwise, returns false.
SELECT isnotnull(1); -- true
IFNULLN
Returns the second argument if the first argument is null; otherwise, returns
the first argument.
SELECT ifnull(null, 'default'); -- default
NULLIFN
Returns null if the two expressions are equal; otherwise, returns the first
expression.
SELECT nullif(2, 2); -- NULL
CONTAINSN
Searches for a word or phrase in one or more text columns using precise or
fuzzy matching.
SELECT * FROM COMPANY
WHERE CONTAINS(products, "product1")
LIKEN
Searches for a specific pattern in a string value.
SELECT * FROM Customers
WHERE last_name LIKE 'R%';
RLIKEN
Searches a string for a regular expression pattern.
SELECT id, text_field, text_field RLIKE '..number'
FROM SalesOrder__dlm ORDER BY id;
NOTLIKEN
Ignores values that match the specified pattern in the column.
SELECT * FROM Customers
WHERE last_name NOTLIKE 'R%'
NOTRLIKEN
Ignores values that match a regular expression pattern in the column.
SELECT * FROM SalesOrder__dlm
WHERE description__c NOTRLIKE '[0-9]+'
CASEN
Evaluates conditions and returns a value when the first condition is met. If no
conditions are true, the ELSE value is returned (or null if there's no ELSE
clause).
SELECT
CASE
WHEN SUM(ssot__Order__dlm.ssot__TotalAmount__c) > 500
THEN 'high spender'
ELSE 'low spender'
END AS spend_label__c,
Individual__dlm.ssot__Id__c AS customer_id__c
FROM ssot__Order__dlm
JOIN IdLink__dlm ON ssot__Order__dlm.ssot__SoldId__c = IdLink__dlm.RecId__c
JOIN UnifiedIndividual__dlm ON IdLink__dlm.UnifiedRecId__c = Individual__dlm.ssot__Id__c
GROUP BY customer_id__c
## Formatting Functions
Function
Aggregatable
Description
Example
SUBSTRINGN
Extracts a substring from a string. Accepts a start index and a length.
SELECT COUNT(SUBSTRING(ssot__Acct__dlm.ssot__AcctTypeId__c, 1, 9))
AS count_of_acct_type__c,
ssot__Acct__dlm.ssot__Id__c AS account_id__c
FROM ssot__Acct__dlm
GROUP BY account_id__c
SUBSTRN
Extracts a substring from a string. Accepts a start position and a character
count.
substr(Account_Id, 13, 3)
RTRIMN
Removes trailing space characters from a string.
rtrim('2 Spaces After ')
UPPERN
Converts lowercase characters to uppercase.
upper("Account.Industry")
LOWERN
Converts uppercase characters to lowercase.
lower("Account.Industry")
CONCATN
Returns a string by merging the values of specified fields and input
strings.
concat("OwnerId.FirstName", ' ', "OwnerId.LastName")
## Math and Statistical Functions
Function
Aggregatable
Description
Example
MODN
Returns the remainder after expr1 / expr2.
SELECT MOD(3, 1.8);
ABSN
Calculates the absolute value of a number (the value without its sign).
abs(number)
RANDN
Returns a random decimal number in [0, 1). Non-deterministic in the general
case. Specify a seed to return a repeatable sequence.
SELECT rand(); -- random
SELECT rand(0); -- repeatable sequence
ROUNDN
Rounds a number to the specified number of decimal places.
SELECT round(2.5, 0)
GREATESTN
Returns the greatest value in the argument list, skipping null values.
SELECT greatest(10, 9, 2, 4, 3);
LEASTN
Returns the smallest value in the argument list, skipping null values.
SELECT least(10, 9, 2, 4, 3);
LOGN
Returns the logarithm of a number in a specified base. Arguments:
base (the base of the logarithm) and number (the
value to take the logarithm of).
log(base, number)
EXPN
Returns e raised to the power of the specified number.
SELECT EXP(2);
BETWEENN
Selects values within a given range (inclusive). Values can be numbers, text,
or dates.
SELECT * FROM table
WHERE price BETWEEN 50 AND 100;
## Boolean Functions
Function
Aggregatable
Description
Example
IS_TRUEN
Returns true if the value is true.
SELECT count(Id) FROM Table
WHERE Is_True(Boolean_Column);
IS_FALSEN
Returns true if the value is false.
SELECT count(Id) FROM Table
WHERE Is_False(Boolean_Column);
HAS_BOOLEAN_VALUEN
Returns true if the field contains a value; returns false if it's null or
blank.
SELECT count(Id) FROM Table
WHERE Has_Boolean_Value(Boolean_Column);
HAS_NO_BOOLEAN_VALUEN
Returns true if the field's value is null or blank; returns false if it
contains a value.
SELECT count(Id) FROM Table
WHERE Has_No_Boolean_Value(Boolean_Column);
# SQL Operators for Insights
Use these arithmetic, currency, and logical operators in SQL expressions when you author calculated insights in Data 360.
### Required Editions
## Arithmetic Operators
Use these operators to perform arithmetic operations on numeric operands.
| Operator | Description | Supported Data Types |
| --- | --- | --- |
| `*` | Multiply | Number, Integer, Percent, Currency |
| `+` | Add | Number, Integer, Percent, Currency |
| `-` | Subtract | Number, Integer, Percent, Currency |
| `/` | Divide | Number, Integer, Percent, Currency |
## Currency Operator
| Operator | Description | Supported Data Types |
| --- | --- | --- |
| `TRY_CONVERT_CURRENCY` | Converts aggregate currency values into a single currency value. | Currency |
## Logical Operators
Use these logical operators to combine one or more true or false values. Each operator returns a true or false value.
| Operation | Operator | Supported Data Types |
| --- | --- | --- |
| Not equal to | `!= , <>` | Text, URL, Email, Phone, Number, Percent, Date, DateTime |
| Less than | `<` | Number, Percent, Date, DateTime |
| Less than or equal to | `<=` | Number, Percent, Date, DateTime |
| Equal to | `=` | Text, URL, Email, Phone, Number, Percent, Date, DateTime |
| Greater than | `>` | Number, Percent, Date, DateTime |
| Greater than or equal to | `>=` | Number, Percent, Date, DateTime |
| And | `and` | Text, URL, Email, Phone, Number, Percent, Date, DateTime, Boolean |
| Pattern match | `LIKE; %` | Text, URL, Email, Phone |
| Regular expression match | `RLIKE` | Text, URL, Email, Phone |
| Boolean evaluation | `Is_True, Is_False, Has_Boolean_Value, Has_No_Boolean_Value` | Boolean |

Example
This example uses logical operators to find individuals who spent more than $5, have a tax rate of 9 or less, an adjusted tax amount of 0, and have orders with a list price other than $100.
```sql
SELECT
SUM(SALESORDER__dlm.grand_total_amount__c) as TotalOrderAmount__c,
Individual__dlm.Id__c as CustomerId__c
FROM SALESORDER__dlm
LEFT JOIN Individual__dlm ON SALESORDER__dlm.partyid__c = Individual__dlm.Id__c
WHERE SALESORDER__dlm.grand_total_amount__c > 5
and SALESORDER__dlm.tax_rate__c <= 9
and SALESORDER__dlm.total_adjustment_tax_amount__c = 0
and SALESORDER__dlm.list_price__c != 100
GROUP BY CustomerId__c
```
# SQL Rules for Insights
When you write SQL for calculated or streaming insights in Data 360, rules govern how each clause is interpreted and what constraints apply. You can also embed a nested subquery in a WHERE or JOIN clause to restrict which rows the outer query returns.
### Required Editions
## Query Rules by Clause
Clause
Rule
General
DMO names are case-sensitive. Verify that DMO references in your SQL match
the casing shown in the Object API Name column on the Data Model tab.
A query must contain at least one measure. A measure is any field wrapped
in an aggregation function.
Any attribute in the SELECT clause that isn't inside an aggregation
function is treated as a dimension and must appear in the GROUP BY
clause.
You can't aggregate within an aggregation.
You can't use DISTINCT in a top-level query.
You can use multiline comments (/* */).
SELECTThe alias for a dimension can't match the field's original name. For
example, UnifiedIndividual__dlm.Id__c as customer_id__c is
valid, but UnifiedIndividual__dlm.Id__c as Id__c causes an
error.
You must use TRY_CONVERT_CURRENCY in the SELECT clause
when your insight includes a currency field.
WHEREThe WHERE clause can't contain an aggregate expression.
The WHERE clause can't reference a dimension or measure alias.
GROUP BYThe GROUP BY clause must be a non-aggregate expression that uses
non-aliases.
The GROUP BY clause can reference a dimension alias, but the alias can't be
part of an expression.
The GROUP BY clause can't include a measure alias or an aggregate
function.
ORDER BYORDER BY isn't allowed in a top-level SELECT statement.
RANKPARTITION BY and ORDER BY inside a RANK function can be aggregate or
non-aggregate expressions.
A RANK clause that contains an aggregate expression is treated as a
measure.
Measures produced by RANK are non-aggregatable. You must provide all defined
dimensions when querying them.
CASEA CASE expression that contains an aggregate function is treated as a
measure.
Measures produced by CASE(WHEN <aggregate>) are
non-aggregatable. You must provide all defined dimensions when querying
them.
To compare the results of aggregate functions, use a CASE WHEN statement.
Boolean comparison doesn't support aggregate functions. For example, instead of
WHEN SUM(amount) > 100, use CASE WHEN SUM(amount) >
100 THEN ... END.
Date fields
When filtering for an empty string in a date field, use a null value
instead.
## Nested Subqueries
A subquery is a query embedded inside another query, typically in a WHERE or JOIN clause. Use a subquery to return data that restricts which rows the outer query retrieves.
For example, this query averages sales order totals for customers who were born after 1980.
```sql
SELECT
avg(SalesOrder__dlm.GrandTotalAmount__c) as avg__c,
SubQuery1.Id as customer_id__c
FROM SalesOrder__dlm
JOIN (
SELECT Individual__dlm.Id__c as Id
FROM Individual__dlm
WHERE year(Individual__dlm.BirthDate__c) > 1980
) as SubQuery1
ON SalesOrder__dlm.SoldToCustomerId__c = SubQuery1.Id
GROUP BY customer_id__c;
```
# SQL Use Cases for Insights Data 360
There are several useful code blocks when creating insights in Data 360.
### Required Editions
Use these code block examples to successfully create your Calculated Insights.

Using UnifiedIndividalID as a Dimension
```sql
SELECT
COUNT(EmailEngagement__dlm.Id__c) as email_engagement_count__c,
UnifiedIndividual__dlm.Id__c as customer_id__c
FROM
EmailEngagement__dlm
JOIN
IndividualIdentityLink__dlm
ON
EmailEngagement__dlm.IndividualId__c = IndividualIdentityLink__dlm.SourceRecordId__c
JOIN
UnifiedIndividual__dlm
ON
UnifiedIndividual__dlm.Id__c = IndividualIdentityLink__dlm.UnifiedRecordId__c
GROUP BY
customer_id__c
```

Group customers based on Recency, Frequency, and Monetary \[RFM\] Score
```sql
SELECT sub2.cust_id__c as id__c,
FIRST(sub2.rfm_recency__c*100 + sub2.rfm_frequency__c*10 +sub2.rfm_monetary__c) as rfm_combined__c,
FIRST(sub2.rfm_recency__c) as Recency__c,
FIRST(sub2.rfm_frequency__c) as Frequency__c,
FIRST(sub2.rfm_monetary__c) as Monetary__c
From (
select UnifiedIndividual__dlm.Id__c as cust_id__c,
ntile(4) over (order by MAX(SALESORDER__dlm.checkout_date__c)) as rfm_recency__c,
ntile(4) over (order by SUM(SALESORDER__dlm.orderid__c)) as rfm_frequency__c,
ntile(4) over (order by avg(SALESORDER__dlm.grand_total_amount__c)) as rfm_monetary__c
FROM SALESORDER__dlm
LEFT JOIN
IndividualIdentityLink__dlm
on
SALESORDER__dlm.partyid__c=IndividualIdentityLink__dlm.SourceRecordId__c
LEFT Join
UnifiedIndividual__dlm
on
UnifiedIndividual__dlm.Id__c=IndividualIdentityLink__dlm.UnifiedRecordId__c
group by cust_id__c
) as sub2
group by sub2.cust_id__c
```

Count of email opened by Unified Individual
```sql
SELECT COUNT( EmailEngagement__dlm.Id__c ) as email_count__c,
UnifiedIndividual__dlm.Id__c as customer_id__c
FROM
EmailEngagement__dlm
LEFT JOIN
IndividualIdentityLink__dlm
ON
IndividualIdentityLink__dlm.SourceRecordId__c = EmailEngagement__dlm.IndividualId__c
and EmailEngagement__dlm.EngagementChannelActionId__c = 'Open'
JOIN
UnifiedIndividual__dlm
ON
UnifiedIndividual__dlm.Id__c = IndividualIdentityLink__dlm.UnifiedRecordId__c
GROUP BY
customer_id__c
```

Rank customers by repeat purchase by product category
```sql
SELECT
FIRST(SubQuery2.highest_purcahased_rank__c) as purchase_rank__c,
SubQuery2.CustomerId__c as UnifiedCustomerID__c,
SubQuery2.product_category__c as ProdSubCategory__c
FROM
(
SELECT
RANK() OVER ( PARTITION BY SubQuery1.id__c
order by (SubQuery1.product_purchase_count__c) desc )
as highest_purcahased_rank__c,
SubQuery1.id__c as CustomerId__c,
SubQuery1.product_category__c as product_category__c
FROM
(
SELECT
UnifiedIndividual__dlm.Id__c as id__c,
PRODUCT__dlm.product_subcategory__c as product_category__c,
COUNT(PRODUCT__dlm.product_sk_u__c ) as product_purchase_count__c
FROM
PRODUCT__dlm
JOIN
SALESORDERPRODUCT__dlm
ON PRODUCT__dlm.productid__c=SALESORDERPRODUCT__dlm.productid__c
JOIN
SALESORDER__dlm
ON SALESORDER__dlm.orderid__c=SALESORDERPRODUCT__dlm.orderid__c
LEFT JOIN
IndividualIdentityLink__dlm
on
SALESORDER__dlm.partyid__c=IndividualIdentityLink__dlm.SourceRecordId__c
LEFT Join
UnifiedIndividual__dlm
on
UnifiedIndividual__dlm.Id__c=IndividualIdentityLink__dlm.UnifiedRecordId__c
group by
id__c, product_category__c
) as SubQuery1
) as SubQuery2
group by
UnifiedCustomerID__c, ProdSubCategory__c
```
# Stage Your Data in Data 360
Customers commonly implement Marketing Cloud Engagement to create many different SubscriberKeys (Individuals) that represent the same person. Such SubscriberKeys are often channel-specific and, as a result, can’t natively execute omnichannel journeys. To build an omnichannel journey, use Data 360 and build a Unified Individual that represents a single person consisting of separate Marketing Cloud Engagement channel-specific SubscriberKeys (Individuals) and contact points.
# Standardize Activations by Using Activation Templates
Use activation templates to define and save reusable activation configurations. These configurations include settings for contact point selection, source priority, filters, enrichment data, and membership filtering. Use these templates to create activations with consistent, predefined settings across all supported activation platforms.
### Required Editions
Activation features such as contact point and membership filtering, source priority, and enrichment data have made creating activations more complex. Teams often reuse the same filtering, priority, and enrichment logic across many campaigns, especially for consent compliance and contact point selection.
Activation templates solve this problem by letting you save common activation configurations once and then apply them when creating activations. Instead of configuring the activation logic from scratch each time, you select a template, and Data 360 prefills your activation with the template's stored settings.

Note Segment-triggered flows also use activation templates. The flow engine reads the template's stored logic to select the correct contact points for each individual in the segment.
## Benefits of Activation Templates
- Define contact-point-selection logic, enrichment data, and filters one time and reuse them across multiple activations.
- Apply source priority rules, contact point filters, and membership filters consistently without manual reconfiguration.
- Standardize consent and contact-point-filter configurations to meet regulatory requirements, such as GDPR.
- Use templates across diverse platforms, including Amazon S3, Marketing Cloud, AppExchange, and Ad Audiences partner destinations.
- Segment-triggered flows can use contact-point-selection logic, a feature that was exclusive to the activation UI.
## How Activation Templates Work
Activation templates are reusable configurations that store metadata such as contact point channels, source priority, enrichment data, and membership filtering logic.
Each template is associated with a specific data space and data model object (DMO), such as Individual or Unified Individual. The DMO and platform association determines which activations and flows can reference the template.
When you create an activation and select a template, Data 360 uses the template as a blueprint to prefill the activation's configuration. You can then review and edit the prefilled fields before saving. After you create an activation from a template, Data 360 removes the link. Subsequent changes to the template don't affect existing activations.
## Template Components
An activation template can include these configurations.
- Contact point channels: Preselected channels such as email, phone (SMS), or WhatsApp.
- Source priority: The evaluation order for contact point values when multiple values exist for the same channel. Each row in the source priority table represents a combination of source, source object, contact point type, and active status. Rows higher in the table take priority.
- Contact point filters: Filter criteria applied to contact point DMOs or consent DMOs to ensure only compliant, valid contact points are selected.
- Enrichment data: Direct attributes and related attributes to include in the activation output.
- Activation membership filtering: Criteria to filter which segment members are included in the activation.
## Supported Platforms
Activation templates support these activation platforms:
- Salesforce Marketing Cloud
- Data Cloud
- Cloud storage platforms such as Amazon S3, Microsoft Azure, Google Cloud Platform (GCP), and SFTP
- External platforms such as Meta, Google Ads, LinkedIn, and DV360

Example
To comply with GDPR consent regulations, a global company operating in Europe needs to ensure proper compliance across multiple activations to different platforms. The marketing operations manager creates an activation template named "GDPR Email Compliance" that includes:
- Email as the contact point channel
- A source priority configuration where a primary email from the Marketing Cloud source with a Lead source object is priority, followed by a primary email from Marketing Cloud with a Prospect source object, and then a business email from Amazon S3 as the lowest priority
- Contact point filters requiring explicit email opt-in consent
- Enrichment attributes for personalization
When a marketer creates a new activation to Marketing Cloud, they select the "GDPR Email Compliance" template. Data 360 prefills the activation with the template's contact point, source priority, filter, and enrichment configurations. The marketer reviews the prefilled settings, makes any campaign-specific adjustments, and saves the activation without manually re-creating the GDPR compliance logic.
- **[Create an Activation Template](https://help.salesforce.com/s/articleView?id=data.c360_a_create_activation_template.htm&release=264.0.0&type=5)**
Create an activation template to define reusable activation configuration logic, including channel selections, source priority, contact point filters, enrichment data, and membership filtering. Apply this configuration when creating new activations or reference it in segment-triggered flows. Templates are created based on the combination of DMO and the activation destination, which allows you to reuse the same template across all activation targets for a given destination.
- **[Use an Activation Template When Creating an Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_use_activation_template.htm&release=264.0.0&type=5)**
Use an activation template when creating an activation to automatically fill in settings like contact points, source priority, filters, and enrichment data. You can then review and adjust these settings before saving your activation.
#### See Also
- [_Salesforce Help_: Create a Segment-Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.automate_flow_build_create_segment_triggered.htm&language=en_US)
# Stop Engagement Data Collection
User engagement data is collected by default to generate valuable insights, but you can choose to stop data collection for a specific engagement data stream by deleting the engagement data stream and associated Data Lake Object (DLO).
### Required Editions
User Permissions Needed
To stop engagement data collection
System admin profile OR
Data 360 Architect permission set
1. Open the **Data Streams** tab, and locate the engagement data stream associated with the harmonized Unstructured Data Model Object (UDMO). Engagement data streams have the label “Engagements” indicated in their name. Open the Data Lake Object tab, and locate the telemetry DLO.
2. From the dropdown menu on the relevant data stream row, select **Delete Data Stream**.
3. Open the **Data Lake Object** tab, and locate the telemetry DLO.
Data 360 immidiately stops Content Viewer engagement data.
#### See Also
- [_Salesforce Help_: Remove Data Lake Objects from Data Spaces](https://help.salesforce.com/s/articleView?id=data.c360_a_remove_data_lake_objects_from_data_spaces.htm&release=264.0.0&type=5 "Before deleting a data lake object (DLO) from a data space, remove all the dependencies like mappings from the DLO.")
# Store or Remove Deleted CRM Connector Data Stream Records
Store soft deleted data stream records that have been in the Salesforce Recycle Bin for up to 15 days. To store deleted data stream records, create a Deleted Record data lake object (DLO). You can use this DLO to view your stored records and use them in Data 360. For example, you can use the Deleted Record DLO to store deleted contacts outside of your Recycle Bin. You can only store deleted records of structured data streams.
### Required Editions
User Permissions Needed
To create and delete a Deleted Record DLO
System admin profile OR
Data 360 Architect permission
set
## Store Deleted CRM Connector Data Stream Records
To store soft deleted records, create a Deleted Record DLO from the **Data Streams** tab.
You can only store soft deleted data stream records that have been in the Salesforce Recycle Bin for up to 15 days.
[Learn more about the rules and guidelines for deleted records](https://developer.salesforce.com/docs/atlas.en-us.api.meta/api/sforce_api_calls_getdeleted.htm).
[Learn more about the Salesforce data deletion mechanism.](https://developer.salesforce.com/docs/data/data-cloud-dmo-mapping/guide/c360a-starter-data-bundles.html)
You can't store deleted [Knowledge\_\_kav data stream records](https://developer.salesforce.com/docs/atlas.en-us.sfFieldRef.meta/sfFieldRef/salesforce_field_reference_Knowledge__kav.html).
1. In the Data 360 app, go to the **Data Streams** tab and select a data stream associated with the Salesforce CRM connector.
2. Make sure that that the data stream has a “IsDeleted” field by reviewing the Field Name column. This field indicates that a record is in the Salesforce Recycle Bin, and is normally needed to create the Deleted Record DLO.
1. If your data stream doesn’t have a “IsDeleted” field, click **Add Source Fields** and add the field API name “IsDeleted\_\_C”.
3. From the dropdown menu on the top-right, select **Store Deleted Records**.
You can view your data stream’s new Deleted Record DLO and check its status under the **Data Lake Objects** tab. If you delete a data stream, its associated Deleted Record DLO is also deleted.
## Remove Stored Deleted Records
You can remove stored deleted records by removing the Deleted Record DLO through the **Data Streams** tab. Upon deletion, the DLO and all its associated data are removed permanently. You can’t remove this DLO directly from the Data Lake Objects tab.
1. In the Data 360 app go to the **Data Streams** tab.
2. Select the data stream whose stored records you want to delete.
3. From the dropdown menu on the top-right, select **Remove Stored Deleted Records**.
4. Confirm deletion, or if prompted, follow the instructions on screen to delete any dependencies that prevent the Deleted Record DLO from being removed.
The stored records are now deleted, including all the data assigned to them. You can’t access the permanently deleted records.

Note When you delete a data stream that has stored records, the stored records are also deleted.
# Streaming Audit Data Model Object
Use the streaming audit data model object (DMO) to track and audit the data sent from your real-time streaming activations.
### Required Editions
Unlike standard audience DMOs, the streaming audit DMO is a single, append-only object. It serves as a continuous historical log of everything sent via a streaming DMO activation. Use it to view the exact data payload, precise commit and processing timestamps, and metadata about the streaming job itself.
An audit DMO is automatically created when you configure a streaming activation for the first time for an activation target. For example, if you create a streaming DMO activation, a corresponding streaming Audit DMO is created to log all its activity. The lifecycle of the DMO is tied to its activation target. You can't manually delete the DMO while the activation target exists, regardless of whether it has active activations or not. The audit DMO is deleted only when the activation target is deleted.
## Audit DMO Schema Attributes
| Field Name | API Name | Data Type | Description |
| --- | --- | --- | --- |
| Commit Timestamp (Truncated) | commit\_timestamp\_truncated | DateTime | The commit timestamp from the source data, truncated to a 30-minute interval. Used for efficient data partitioning. Format: ISO 8601. For example: 2024-03-20 14:30:00. |
| Commit Timestamp (Exact) | commit\_timestamp\_exact | DateTime | Exact Change Data Feed (CDF) commit timestamp when the activation event occurred. |
| Activation ID | activation\_id | Text | Unique identifier for the activation that triggered the streaming event. |
| Activation Record | activation\_record | Text (JSON) | The full activation payload in JSON format. |
| Activated Entity Name | activated\_entity\_name | Text | Name of the activated entity associated with the record. For example, Unified Individual. |
| Additional Properties | additional\_properties | Text (JSON) | JSON blob containing metadata about the streaming job. For example, streaming\_job\_id. Designed for future extensibility. |
| Process Timestamp | process\_timestamp | DateTime | Timestamp when the streaming job was executed. |
| Uploaded Timestamp | uploaded\_timestamp | DateTime | Timestamp when the audit data was uploaded. |
# Streaming Data Graphs
Use streaming data graphs to automatically refresh your data when underlying data changes. Streaming refresh reduces latency, removes the need for scheduling, and provides more predictable refresh behavior.
### Required Editions
Unlike scheduled refreshes that rely on defined intervals, streaming data graphs run automatically when source data changes. Streaming updates only the affected data, which improves efficiency, helps maintain consistent performance, and ensures metadata and data remain in sync.
Streaming data graphs reflect updates to your data graph within minutes, not in real time. If your use case requires lower latency than this, use a real-time data graph instead, which is built to serve requests with sub-second latency for supported data sources.
Streaming data graphs are billed only for the volume of updates processed, not for a full daily refresh. This differs from standard data graphs, which incur a daily full-refresh cost regardless of how much data actually changed. As a result, Streaming Data Graphs can reduce costs specifically when the volume of incoming updates is small relative to the total number of records in the data graph. When you create a streaming data graph, it automatically goes through a full refresh to populate the data.
You can edit a streaming data graph after it's created and apply incremental changes without a full rebuild. When you make an edit, only the affected records and relationships that come in the stream henceforth are processed. Use the Refresh Now option for a full rebuild of the data graph.

Note Streaming refresh isn’t supported for data graphs that include N:1 relationships between participating data model objects (DMOs) or filter conditions. After a data graph is created, you can’t change the refresh type between streaming and scheduled. To use a different refresh type, create a new data graph with the required configuration.
#### See Also
- [_Salesforce Help_: Billing Considerations for Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_graphs.htm&release=264.0.0&type=5 "Use of data graphs impacts the consumption of credits in these usage types. A data graph creates a transform at the backend and hence reflects under the respective usage type in Digital Wallet.")
# Streaming Data Transform Functions and Operators
You can use these functions and operators in a streaming data transform SQL statement.
Category
Function Name
Description
Table
JSON_TABLE(field ,
rootPath COLUMNS (list )
alias )
Extracts values from a JSON string value into a table with specified columns. Can
be used to create more than one table.
Use these values inside the function.
Field (string)—The name of the field in the
input object where the JSON values are stored. It can be any expression that
results in a JSON string value.rootPath (path)—The JSON path expression
that locates properties in a JSON object.List (ColumnName Type PATH Path)—A
comma-separated list of columns that is within the table.
ColumnName (string)—The name of the
column in the table returned from the JSON_TABLE invocation.Type—The type of data being outputted.
Valid values are TEXT or NUMBER.Path (path)—The JSON path expression
that locates properties in a JSON object in relation to the root path.
Alias (string)—The name of the table being
created.
Examples
SELECT
customers_with_orders__dll.order_id__c as order_id__c,
customers.customer as customer__c
FROM customers_with_orders__dll, JSON_TABLE(
customers_with_orders__dll.json_data__c, '
#### See Also
- [Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5 "Data 360 supports these data types.")
- [Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.")
- [Normalize Data with UNION Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_normalization.htm&release=264.0.0&type=5 "Normalize data ingested into Data 360 with streaming data transforms.") COLUMNS (
customer TEXT PATH '$.customer'
)
) customersSELECT
customers_with_orders__dll.order_id__c as order_id__c,
items.item_name as item_name__c,
items.item_price as item_price__c
FROM customers_with_orders__dll, JSON_TABLE(
customers_with_orders__dll.json_data__c, '$.items[*]' COLUMNS (
item_name TEXT PATH '$.name',
item_price NUMBER PATH '$.price'
)
) items
Text
CONCAT()
Returns a concatenated string of the provided values. Accepts two or more strings
or field API names.
Text
COALESCE
Returns the first value from the list that isn’t empty.
Text
TRIM(text )
Removes all spaces from the text except for single spaces between words.
Text
RTRIM(text )
Removes all spaces from the end.
Text
LOWER(text )
Converts all uppercase letters in a text string to lowercase.
Text
UPPER(text )
Converts all lowercase letters in a text string to uppercase.
Text
TO_TEXT(expr )
Returns the UTF-8 value for a text, number, boolean, date, or datetime
expression.
Text
REGEXP(text, pattern )
Returns true if the text matches the regular expression pattern, and false
otherwise.Use these values with the operator.
text (string): The text to search.
pattern (string): A regular expression.
Example
REGEXP(order_id__c,
'^[A-Z]{3}-[0-9]+
#### See Also
- [Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5 "Data 360 supports these data types.")
- [Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.")
- [Normalize Data with UNION Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_normalization.htm&release=264.0.0&type=5 "Normalize data ingested into Data 360 with streaming data transforms."))
Text
REGEXP_EXTRACT(text, pattern, index )
Returns the matching group at the specified index from the text. Index 0 returns
the entire match. Index 1 and higher return capturing groups, which are the parts of
the pattern enclosed in parentheses.
Use these values inside the function.
text (string): The text to search.
pattern (string): A regular expression.
index (number): The zero-based index of the group to return.
Example
REGEXP_EXTRACT(order_id__c, '([A-Z]+)-([0-9]+)', 1)For
an order_id__c value of ORD-1042, this example returns ORD.
Datetime
TO_DATETIME(expr )
Returns the datetime value for a date, date time, or epoch
expression.
Examples
Date
TO_DATETIME(2023-05-15) returns 2023-05-15
00:00:00
Epoch
TO_DATETIME(1700127401) returns 2023-11-16 09:36:41
Datetime
HOUR_ADDAdds a number of hours to the datetime value based on the integer value of the
second function parameter. Returns the datetime that is the number of hours after the
start datetime.
Datetime
HOUR_SUBSubtracts a number of hours from the datetime value based on the integer value of
the second function parameter. Returns the date that is the number of hours before the
start datetime.
Boolean
TO_BOOLEAN(expr )
Returns a boolean value. Accepts boolean values or the text values “True” and
“False.”
Number
TO_NUMBER(expr )
Returns a number value for a given expression. Returns null for text, date,
datetime, and boolean values.
Date
TO_DATE(expr )
Returns a date value for a date, datetime, or epoch
expression.
Examples
Datetime
TO_DATE(2023-11-16 09:36:41) returns
2023-11-16
Epoch
TO_DATE(1700127401) returns 2023-11-16
Logic
ISNULL()
IFNULL()
NULLIF()
ISNOTNULL()
Don’t compare a field to null using =,!=, or <>. These
comparisons don’t match null values, so rows with a null in that field will be
silently excluded or included when you don’t expect it. Always use field
ISNULL(field) or field ISNOTNULL(field)
instead.
These functions test for null values.
For number and datetime data types:
To check for a non-null value, use ISNOTNULL(field).
To check for a null value, use ISNULL(field).
Logic
CASE WHEN
statement
Returns a value when the first condition is met, such as if-then-else.
Example
SELECT
SourceObject.Id as id__c,
CASE
WHEN upper(SourceObject.Type) LIKE '%CAT%' THEN 'pet'
WHEN lower(SourceObject.Description) LIKE '%donut%' THEN 'food'
ELSE 'Unknown'
END AS newProduct__c
FROM SourceObject
Logic
AND(condition1 ,
condition2 )
Logical AND checks to see that both conditions
are true.
Example
SELECT *
FROM SourceObject
WHERE (Type <> "" AND Comment == "")
Logic
OR(condition1 ,
condition2 )
Logical OR checks to see if either one of the
conditions is true.
Example
SELECT *
FROM SourceObject
WHERE (Type <> "" AND Comment == "")
OR (FirstName == "Alice" AND LastName == "Bob")
Operators
Logical operators
Greater than (>)
Greater than or equal to (>=)
Less than (<)
Less than or equal to (<=)
Equal to (==)
Logical AND (&&)
Logical OR (||)
Logical NOT (!=, <>)
Operators
UNION
Combine up to five SELECT statements. Each SELECT
statement must use the same source data lake object.
Example
SELECT Name, City
FROM AccountObject
UNION
SELECT Name, City
FROM AccountObject;
To ensure records are properly updated, validate that none of the following
conditions are present at the same time.
Date & Datetime
CURRENT_DATE()
Returns the current UTC date as a value of the date data type.
#### See Also
- [Data Types in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types.htm&release=264.0.0&type=5 "Data 360 supports these data types.")
- [Date and Datetime Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_data_types_and_date_formats.htm&release=264.0.0&type=5 "Data 360 supports date and datetime data types.")
- [Normalize Data with UNION Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_normalization.htm&release=264.0.0&type=5 "Normalize data ingested into Data 360 with streaming data transforms.")
# Streaming Data Transform Use Cases
These use cases show how you can use streaming data transforms to normalize your data, filter it, and better align it with the Data Cloud data model.
- **[Normalize Data with UNION Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_normalization.htm&release=264.0.0&type=5)**
Normalize data ingested into Data 360 with streaming data transforms.
- **[Merge Multiple Data Streams Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_merge.htm&release=264.0.0&type=5)**
The Marketing Cloud Engagement connector in Data 360 uses two profile data streams to ingest data from Marketing Cloud Engagement. Both data streams include the same set of primary keys. When these data streams are mapped directly to the Individual data model object (DMO), duplicate records appear in the DMO. To solve this problem, merge the data streams into one data lake object (DLO) before mapping to the Data 360 data model.
- **[Split a Data Stream Use Case](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_split.htm&release=264.0.0&type=5)**
A data stream containing guest checkout information includes profile and engagement data. Split the data so that it can be mapped into separate data lake objects (DLOs), one for profile information and one for engagement.
# Streaming Data Transforms
A streaming data transform reads one record in a source object, reshapes the record data, and writes one or more records to a target object. The source and target objects must be different objects. A streaming data transform runs continuously as a streaming process, picking up new or changed data.
Use a streaming data transform to clean ingested data. Then, map the improved data to the data model.
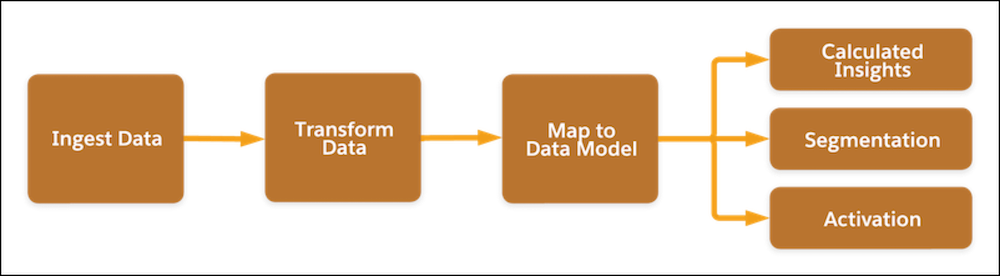
- **[Streaming Data Transform Use Cases](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_use_cases.htm&release=264.0.0&type=5)**
These use cases show how you can use streaming data transforms to normalize your data, filter it, and better align it with the Data Cloud data model.
- **[Set Up a Streaming Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_setup.htm&release=264.0.0&type=5)**
When you set up a streaming data transform, it reads and processes all records in the source and writes the data to the target object. The source and target objects must be different objects.
- **[Join Data in a Streaming Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_join_data_streaming_transform.htm&release=264.0.0&type=5)**
Joins enable data augmentation by combining data from two separate streams based on a primary key. In streaming data transformations, \`INNER JOIN\` and \`LEFT JOIN\` clauses in SQL statements are used to combine data from two distinct streams. A join expression consists of two objects: one identifies the object that triggers the streaming transform on update, and the other specifies the object used to evaluate the join.
- **[Create a Target DLO from the Data Lake Objects Tab](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_create_dlo.htm&release=264.0.0&type=5)**
One way to create a new Target Data Lake Object (DLO) is via the Data Lake Objects tab.
- **[Check the Status of a Streaming Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_check_data_transform_status.htm&release=264.0.0&type=5)**
To monitor the status of a streaming data transform, review its processing metrics.
- **[Filter Streaming Data Transform Records](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_use_where_filter_records.htm&release=264.0.0&type=5)**
Use the `WHERE` clause in the streaming data transform SQL statement to limit which source object records the streaming data transform reads and processes.
- **[Rebuild Streaming Transform Target Objects](https://help.salesforce.com/s/articleView?id=data.c350_a_rebuild_streaming_transform_target_objects.htm&release=264.0.0&type=5)**
Rebuild a streaming transform target object to ensure data consistency.
- **[Considerations for Working with Streaming Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_considerations.htm&release=264.0.0&type=5)**
Considerations for working with streaming data transforms can significantly affect the performance, reliability, and success of your data processing pipeline.
- **[Considerations for Deleting Data](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_delete_data_considerations.htm&release=264.0.0&type=5)**
Keep the following in mind when you delete data in Data 360.
- **[Customer Data Subject Rights in Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_data_subject_rights.htm&release=264.0.0&type=5)**
A customer’s Data Subject Rights relate to the storage and use of their personal data. Data 360 offers tools to support Data Subject Rights in alignment with various data protection and privacy regulations.
- **[Streaming Data Transform Functions and Operators](https://help.salesforce.com/s/articleView?id=data.c360_a_streaming_transform_supported_functions.htm&release=264.0.0&type=5)**
You can use these functions and operators in a streaming data transform SQL statement.
# String Functions for Formulas
Use a string function to manipulate the text data type, including email, phone, time, and date values. For example, change text from uppercase to lowercase, concatenate values from multiple fields, and replace values.
When you enter a formula, use the API name of the field in the expression, not the label. Enclose text in single straight quotes (`'This is a string.'`) and parameters in parentheses.
Formula expressions support these string functions.
String Function
Description
Syntax
char_length
Returns the number of characters in the specified string. Length includes leading and
trailing spaces.
char_length(field )
field is the text
field to
measure.
Example
char_length(product_name)
concat
Returns a string by merging the values of the specified fields and input
strings.
concat(field1 ,field2 ,...fieldN )
field1
is the first text field to include in the concatenated
value.
field2 is the second text field to
include.
fieldN is any number of additional text fields to
include.
Example
concat("OwnerId.FirstName",' ',"OwnerId.LastName")
endsWith
Returns True if the specified string is found at the end of the field value. You can
use this function only in case functions.
ends_with(fieldName ,literal )
fieldName
is the text field to search.
literal is the value to search for at
the end of the field.
instr
Returns the first location of the text in the specified field. You can specify a
different position to start the search or find the location of a different search
string.
instr(field ,
searchString , [position ,
[occurrence ]])
field is the text field
evaluated to find the searchString .
searchString
is the text field searched for in the
field .
position is the location in
field where to start the search. If you don't specify a position, the
search begins at position 1.
occurrence is the
searchString instance to return. If you don’t specify a position with
the occurrence, the search begins at position 1.
Example: Evaluate text for an
exclamation point
instr('123!456!78!', !)
--The result is 4
instr('123!456!8!', !, [4])
--The result is 7
instr('123!456!8!', !, [4, [2]])
--The result is 9
lower
Returns the string with all characters in lowercase. If the input string is null, the
result is null.
lower(field )
field is the text field to
convert to
lowercase.
Example
lower("Account.Industry")
ltrim
Removes the specified characters from the beginning of a string in a field. If you
don’t specify characters, it removes the string’s leading spaces.
ltrim(field ,[valueToBeRemoved ])
field
is the text field to remove the leading spaces or specified characters
from.
valueToBeRemoved is the value to remove from the string. If
unspecified, the transformation removes the leading spaces.
Example: Trim the leading
space characters from a
string
ltrim(' 5 Spaces Before')
md5Returns a 32-character string that is a text representation of the hexadecimal
value of a 128-bit checksum.
md5(field )
field
(Required) is the text for which you want to calculate the
checksum.
Example
md5("Account_Name")
replace
Replaces a string with another string. If any argument is null, the function returns
null. This function is case-sensitive.
replace(field ,searchString ,replacementString )
string is the text field that contains the string to
replace.
searchString is the string to replace.
replacementString is the value to replace the string.
Example
replace(Account_Name,'salesforce.com','Salesforce')
rtrim
Removes the specified characters from the end of a string in a field. If you don’t
specify characters, it removes the string’s trailing spaces.
rtrim(field ,
[valueToBeRemoved ])
field is the text
field to remove the trailing spaces or specified substring
from.
valueToBeRemoved is the value to remove from the string. If
unspecified, the transformation removes the trailing spaces.
Example: Trim the two
trailing space characters from a
string
rtrim('2 Spaces After ')
sha2Converts a variable-length string of characters into a fixed-length string of
characters. The character string is a text representation of the hexadecimal value of
the checksum with the specified number of bits. SHA-224, SHA-256, SHA-384, and SHA-512
are supported. Bit length of 0 is equivalent to 256.
sha2(field , bitLength
field (Required) is the text to convert into a into a
character string.
bitLength (Required) is an integer that
defines the number of bits in the hash function. Valid values are 0, 224, 256, 384,
and 512.
Example
sha2('account_name', 224);
startsWith
Returns True if the specified string is found at the beginning of the field value. You
can use this function only in case functions.
startsWith(fieldName ,literal )
fieldName
is the text field to search.
literal is the value to search for at
the beginning of the field.
string
Converts the date or number value to a string data type.
string(expression )
expression is the date
or number field to convert.
substr
Returns the specified number of characters from the string, starting at the specified
position. Also called substring.
substr(field ,position ,len )
field
is the text field to extract the substring from.
position is the
starting character position of the substring. The first character in a string is position 1.
If the position is negative, the position is relative to the end of the string. A position
of -1 is the last character.
len is the number of characters to
return. If the length is 0, the output is an empty string. If the length is negative, the
function returns null. This parameter is
optional.
Example
substr(Account_Id,13,3)
title
Returns the string with the first character of every word in uppercase and the other
characters in lowercase.
title(field )
field is the text field to
apply title case
to.
Example
title(Opp_Name)
trim
Removes the specified characters from the beginning and end of a field value. If no
string is specified, it removes the spaces from the beginning and end of a string.
trim(field ,
[valueToBeRemoved )]
field is the text
field to remove the specified substring from.
valueToBeRemoved is
the value removed from the string. This parameter is optional. If unspecified, the
transformation removes the trailing
spaces.
Example
trim(' Spaces Before and After ')
upper
Returns the string with all characters in uppercase. If the string is null, the result
is null.
upper(field )
field is the text field to
convert to
uppercase.
Example
upper(First_Name)
- **[Notation for String Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_string_notation.htm&release=264.0.0&type=5)**
If you manually type your formulas, use single quotes `‘` for string literals and double quotes `“` for joined fields with dot notation or reserved keywords.
- **[Reserved Keywords in Formulas](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_string_keywords.htm&release=264.0.0&type=5)**
Batch data transforms have reserved keywords that need special handling when manually writing formulas. Use double quotes “ when referencing fields that share a name with reserved keywords. To avoid cross-referencing your field names with this list, the best practice is to use double quotes around all field names.
# Subscribe to Data Shares in Google Analytics Hub
The Google Cloud users can subscribe to the data using the Analytics Hub.
Before you begin complete these prerequisites.
- Get familiar with [Viewing and subscribing to listings in Google Analytics Hub](https://cloud.google.com/bigquery/docs/analytics-hub-view-subscribe-listings#view_listings).
1. In the Google Cloud console, go to the **BigQuery** page.
2. In the Explorer panel, click **\+ Add data** and select **Sharing (Analytics Hub)**.
3. Type Salesforce in the **Search for listings** bar. A page that contains the listing of the Salesforce data appears.
4. Select a listing and click **Subscribe**.
5. Select a project, enter a name for your dataset, and click **Save**.
A new linked dataset is created in your project and appears in the Explorer panel. The linked dataset shows all the Data 360 objects shared from the Salesforce Data 360 listing. Salesforce Data 360 data objects are shared as views. As a subscriber, you can't access the underlying tables that the views reference.
# Supported Data 360 Government Cloud Regions for Snowflake Integration
Data 360 in Government Cloud supports integration with these Snowflake regions.

Note This content applies only to data shares with the legacy Snowflake data share target.
## United States and Canada
| **Data 360 GOVERNMENT CLOUD Region** | **Snowflake Cloud Region** |
| --- | --- |
| **Amazon Web Services (AWS)** | **Amazon Web Services (AWS)** |
| us-goveast-1 (FedRAMP High Plus) | us-gov-east-1: US Gov East 1 (FedRAMP High Plus) |
To enable data sharing for a specific cloud or region, contact Salesforce Support.
# Supported Data 360 Regions for Snowflake Integration
Data 360 supports integration with Snowflake in these regions.

Note This content applies only to data shares with the legacy Snowflake data share target.
## United States and Canada
Data 360 Region Snowflake Cloud and Region
Amazon Web Services (AWS)
Amazon Web Services (AWS)
Google Cloud Platform (GCP)
Microsoft Azure
us-east-1 (Virginia)
us-east-1: US East (Virginia)
us-central1: US Central1 (Iowa)
westus2: West US 2 (Washington)
us-east-2: US East (Ohio)
us-east4: US East4 (N. Virginia)
eastus2: East US 2 (Virginia)
us-west-2: US West (Oregon)
centralus: Central US (Iowa)
ca-central-1: Canada (Central)
southcentralus: South Central US (Texas)
ap-southeast-2: Asia Pacific (Sydney)
canadacentral: Canada Central (Toronto)
eu-west-1: Europe (Ireland)
westeurope: West Europe (Netherlands)
centralindia: Central India (Pune)
us-west-2 (Oregon)
us-west-2: US West (Oregon)
us-central1: US Central1 (Iowa)
westus2: West US 2 (Washington)
us-east-1: US East (Virginia)
us-east4: US East4 (N. Virginia)
eastus2: East US 2 (Virginia)
us-east-2: US East (Ohio)
centralus: Central US (Iowa)
ca-central-1: Canada (Central)
southcentralus: South Central US (Texas)
eu-west-1: Europe (Ireland)
canadacentral: Canada Central (Toronto)
sa-east-1 (Sao Paulo)
sa-east-1: South America (Sao Paulo)
Not available
eastus2: East US 2 (Virginia)
us-east-1: US East (Virginia)
ca-central-1: Canada (Central) ca-central-1: Canada (Central)
Not available
canadacentral: Canada Central (Toronto)
eu-west-1: Europe (Ireland)
ap-south-1: Asia Pacific (Mumbai)
us-east-1: US East (Virginia)
us-east-2 (Ohio) us-east-2: US East (Ohio)
Not available
eastus2: East US 2 (Virginia)
us-east-1: US East (Virginia)
us-west-2: US West (Oregon)
## Europe
Data Cloud Region Snowflake Cloud and Region
AWS
AWS
GCP
Microsoft Azure
eu-central-1 (Frankfurt)
eu-west-1: Europe (Ireland)
europe-west2: Europe West2 (London)
uksouth: UK South (London)
eu-west-2: Europe (London)
europe-west4: Europe West4 (Netherlands)
northeurope: North Europe (Ireland)
eu-west-3: Europe (Paris)
westeurope: West Europe (Netherlands)
eu-central-1: Europe (Frankfurt)
switzerlandnorth: Switzerland North (Zurich)
eu-north-1: Europe (Stockholm)
centralus: Central US (Iowa)
ap-south-1: Asia Pacific (Mumbai)
us-west-2: US West (Oregon)
us-east-1: US East (Virginia)
ca-central-1: Canada (Central)
eu-west-2 (London)
eu-west-2: Europe (London)
Not available
uksouth: UK South (London)
eu-west-1: Europe (Ireland)
northeurope: North Europe (Ireland)
westeurope: West Europe (Netherlands)
eu-central-2 (Zurich) eu-central-2: Europe (Zurich)
Not available
switzerlandnorth: Switzerland North (Zurich)
eu-west-1: Europe (Ireland)
ap-south-1: Asia Pacific (Mumbai)
eu-west-3 (Paris) eu-west-3: Europe (Paris)
Not available
Not available
eu-west-1: Europe (Ireland)
eu-north-1: Europe (Stockholm) eu-north-1: Europe (Stockholm)
Not available
Not available
eu-west-1: Europe (Ireland)
## Asia Pacific
Data Cloud Region Snowflake Cloud and Region
AWS
AWS
GCP
Microsoft Azure
ap-northeast-1 (Tokyo)
ap-northeast-1: Asia Pacific (Tokyo)
Not available
japaneast: Japan East (Tokyo)
southeastasia: Southeast Asia (Singapore)
ap-northeast-3: Asia Pacific (Osaka)
ap-southeast-1: Asia Pacific (Singapore)
ap-northeast-3 (Osaka) ap-northeast-3: Asia Pacific (Osaka)
Not available
Not available
ap-southeast-3: Asia Pacific (Jakarta)
ap-northeast-1: Asia Pacific (Tokyo)
ap-southeast-2 (Sydney)
ap-southeast-2: Asia Pacific (Sydney)
us-central1: US Central1 (Iowa)
australiaeast: Australia East (New South Wales)
eastus2: East US 2 (Virginia)
ap-south-1 (Mumbai)
ap-south-1: Asia Pacific (Mumbai)
Not available
Not available
ap-southeast-1 (Singapore) ap-southeast-1: Asia Pacific (Singapore)
Not available
southeastasia: Southeast Asia (Singapore)
ap-southeast-3 (Jakarta) ap-southeast-3: Asia Pacific (Jakarta)
Not available
Not available
ap-northeast-2 (Seoul) ap-northeast-2: Asia Pacific (Seoul)
Not available
Not available
ap-southeast-1: Asia Pacific (Singapore)
To enable data sharing for a specific cloud or region, contact Salesforce Support.
# Supported Data Types for Custom Templates
The data types supported in custom templates vary based on the clean rooms platform. Adhere to supported data types for successful query execution.
If you’re a provider who's offering custom templates, follow the specifications for your clean room platform. There are minor differences between AWS and Data 360 that affect the success of your custom template. One notable difference is quoting identifiers.
- In Data 360, to quote an identifier, enclose table names and field names in double quotes (").
- In AWS, to quote an identifier, enclose table names and field names in backticks ( \`).
## Data Types for Data 360 Clean Rooms
For providers that use Data 360 clean rooms, see [Data 360 Data Types](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/dc-sql-reference/datatypes.html) for table configurations and [Data 360 SQL Syntax](https://developer.salesforce.com/docs/data/data-cloud-query-guide/references/dc-sql-reference/sql-commands-context.html) for SQL syntax. Data 360 clean rooms use the Hyper query engine for query execution. Hyper supports these data types for query parameters in custom templates.
| Name | Aliases | Description |
| --- | --- | --- |
| boolean | bool | Boolean value with ternary logic (true/false/unknown) |
| numeric | decimal | Exact numeric of selectable precision |
| smallint | int2 | Signed two-byte integer |
| integer | int, int4 | Signed four-byte integer |
| bigint | int8 | Signed eight-byte integer |
| real | float4 | Single-precision floating-point number (4 bytes) |
| double precision | float, float8 | Double-precision floating-point number (8 bytes) |
| character varying | varchar | Variable-length character string with limit |
| character | char | Fixed-length character string |
| date | (None) | Calendar date (year, month, day) |
| time | (None) | Time of day (no time zone) |
| timestamp | (None) | Date and time (no time zone) |
| TIMESTAMP WITH TIME ZONE | timestampTZ | Date and time, including time zone |
| oid | (None) | Object Identifier; a numeric system-assigned unique ID used internally. |
| bytes | byte, blob, varbinary | Sequence of bytes (octets); used for raw byte data and binary strings. |
## Data types for AWS Clean Rooms
If you’re a provider using AWS clean rooms, see [AWS data types](https://docs.aws.amazon.com/clean-rooms/latest/sql-reference/s_Supported_data_types.html) for table configurations and [Overview of SQL in AWS clean rooms](https://docs.aws.amazon.com/clean-rooms/latest/sql-reference/sql-reference.html) for AWS clean room SQL syntax. Here are the supported data types for query parameters in AWS clean rooms.
| Name | Alias | Description |
| --- | --- | --- |
| BIGINT | LONG | Signed eight-byte integer |
| BINARY | | Byte sequence values |
| BOOLEAN | | Logical Boolean (true/false) |
| BYTE | | 1-byte signed integer numbers, from -128 to 127 |
| CHAR | CHARACTER | Fixed-length character string |
| DATE | | Calendar date (year, month, day) |
| DECIMAL | NUMERIC | Exact numeric of selectable precision |
| DOUBLE | | Double precision floating-point number |
| FLOAT | REAL | Single precision floating-point number |
| INTEGER | INT | Signed four-byte integer |
| LONG | | 8-byte signed integer numbers |
| SMALLINT | SHORT | Signed two-byte integer |
| TIMESTAMP | | A calendar date and time of day with millisecond precision. |
| TIMESTAMP\_LTZ | | Time of day with local time zone |
| TIMESTAMP\_NTZ | | Time of day without time zone |
| TINYINT | BYTE | 1-byte signed integer numbers, from -128 to 127 |
| VARCHAR | STRING | Variable-length character string with a user-defined limit |
# Supported File Formats in Data 360
Data 360 supports various files and compression formats for your data stream sources.
## Supported File Formats

Important We recommend you refer [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.") to know the applicable file limitations.
Data 360 supports these file formats:
- Delimited text files such as CSV files.
- Parquet files when data is ingested from Amazon S3, Google Cloud Storage, Microsoft Azure Storage, SFTP.

Note You must use ASCII characters in text fields such as file name, wildcard, directory name, or formula syntax editor. UTF-8 sometimes contains non-ASCII characters that aren’t guaranteed to work properly. Also, don't use `:`(colon) and `'` (single quote) in file names and formulas.

Note Files containing newline characters and multiline text columns are not supported.
## Supported File Formats for Unstructured Data
Data 360 supports several file formats for unstructured data and search index configurations. For a complete list, see [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&release=264.0.0&type=5 "Data 360 supports multiple file formats and connector types for unstructured data.").
## Supported Delimiters
Data 360 supports these content delimiters for text files:
- `,` (comma)
- \\t (tab)
- `|` (pipe)
- `;` (semicolon)
- `^` (caret)
- `¦` (broken pipe)
- \\u0001

Note Data 360 automatically evaluates the ingested files and determines the delimiter. We recommend using double quotes around values in a file to ensure the system detects the correct file delimiter.
## Supported File Compression Formats
Data 360 supports these compression formats for CSV files:
- GZ
- ZIP
Data 360 supports these compression formats for the data in the Parquet files:
- GZ
- ZIP
- NONE
- SNAPPY
- ZSTD
## Ingestion of Parquet Files
Data 360 supports these parquet data types and they’re converted to the corresponding Data 360 data types. If a parquet file contains a data type that's not supported in Data 360, the column is ignored and not ingested. You can view the unsupported fields when configuring the data stream in the New Data Stream page. You can also see the unsupported data types in the New Source Fields page when adding a source field. To ingest an unsupported data type. convert it to a Data 360 supported datatype in the source parquet file.

Note \* Indicates a primitive data type in Parquet files.
Parquet Data Type
Data 360 Data Type
STRING
Text
ENUM
UUID
BOOLEAN*
Boolean
DATE
Date
TIMESTAMP
Datetime
INT96*
DECIMAL with 38 precision, 18 scale
Number
DOUBLE*
FLOAT
INT
INT32*
INT64*
Data 360 supports the following encoding formats for parquet files:
- Run-length encoding (RLE) Dictionary
- Plain Dictionary
# Supported Library Functions
In the Data 360 data library, you can choose functions and operators. You can nest functions.
Functions are case-sensitive, and the convention is uppercase letters. For example, enter IF( ), not if( ).
You can reference these functions in the syntax editor.
## Conversion Functions
Function Name
What It Does
ABS(number)
Returns the absolute value of a number.
Example:
ABS(sourceField['quantity']) with a quantity of -48 returns 48.0.
COMPRESS(value1)
Compresses a string using gzip and returns it in base64.
Example:
COMPRESS(sourceField['name']), where name is Andrew Lawrence, returns COMPRESSED~H4sIAAAAAAAAAHPMSylKLVfwSSwvSs1LTlUAAOpHEAwQAAAA
.
DECODE_BASE64(value1)
Decodes a string from base64.
ENCODE_BASE64(value1)
Encodes a string to base64.
FORMATDATE(date, pattern)
Returns the string representation of the given date according to the supplied
pattern.
Example: FORMATDATE(sourceField['createdDate'],'yyyy-MM-dd') for a date
created as Oct 16, 2024 returns 2024-10-16.
MD5(stringToHash)
Returns an MD5 hash of the given string.
Example: MD5(sourceField['name']),
where name is Andrew Lawrence, returns b5101112a252d5a1f7e8af8ea893901e.
NUMBER(value1)
Converts a string to a number.
PARSEDATE(dateString, pattern)
Returns the date object specified by the given dateString using the given
pattern.
Example: PARSEDATE(sourceField['createdDate'], 'yyyy-MM-dd'), where
createdDate is 2014-02-25, returns the date object 2014-02-25.
ROUND(number)
Rounds a number to the nearest integer.
Example: ROUND(sourceField['cost']),
where cost is 45454.9, returns 45455. If cost is 45454.1, it returns
45454.
SHA256(stringToHash)
Returns an SHA256 hash of the given string.
Example:
SHA256(sourceField['name']), where name is Andrew Lawrence, returns cc0b796c0ebea8fb21abca58deed9e7adbaee88f607037c9dc98d344b7809ac5.
UNCOMPRESS(value1)
Uncompresses a base64 string using gzip.
Example:
UNCOMPRESS(sourceField['name']), where name is
COMPRESSED~H4sIAAAAAAAAAHPMSylKLVfwSSwvSs1LTlUAAOpHEAwQAAAA , returns
Andrew Lawrence.
UUID()
Returns a 36-character UUID number.
## Date Functions
Function Name
What It Does
DATE(year, month, day)
Returns the date representing the given arguments.
DATEDIFF(interval, startDate, endDate)
Returns the number of time units specified by interval between the startDate
and endDate. The startDate and endDate arguments must be date objects or date
strings in standard form. The interval must be one of the following: yyyy (year), q
(quarter), m (month), d (day), ww (week), h (hour), n (minute), s (second).
DATEADD(interval, number, date)
Returns the date after which a certain time or date interval is added. The
interval must be one of the following: 'yyyy' (year), 'q' (quarter), 'm' (month),
'd' (day), 'ww' (week), 'h' (hour), 'n' (minute), 's' (second).
DAYSBETWEEN(startDate, endDate)
Returns the number of days between the given startDate and endDate. The
arguments must be date objects or date strings in standard form.
DAYS_IN_MONTH(date)
Returns the number of days in a specified month.
Example:
DAYS_IN_MONTH(sourceField['createdDate']), where createdDate is Oct 16, 2024,
returns 31.
DAYPRECISION(date)
Returns the given date with day precision, meaning that the hours, minutes, and
seconds fields are all set to 0.
Example:
DAYPRECISION(sourceField['createdDate']), where createdDate is Oct 16, 2024 11:45
AM, returns 2024-10-16 00:00:00.
NETWORKDAYS(startDate, endDate)
Returns the number of workdays between two dates, excluding weekends. The
arguments must be date objects or date strings in standard form.
NOW()
Returns the current system date and time.
SETHOUR(date, hour)
Returns the given date set with the given hours. Hour must be a numeric value
between 0 and 23.
Example: SETHOUR(sourceField['createdDate'], 17), where
createdDate is Oct 16, 2024, returns Wed Oct 16 17:00:00 GMT 2024.
TODAY()
Returns the current system date in UTC.
TOSECONDS(duration)
Returns the number of seconds represented by the given duration string in the
format HH:mm:ss/HH:mm:ss.SSS.
## Logical Functions
| Function Name | What It Does |
| --- | --- |
| IF(condition,resultIfTrue, resultIfFalse) | Returns the second argument if the first argument is true, and third argument if otherwise |
| AND(condition1, condition2) | Logical AND, checks to see that both conditions are true |
| OR(condition1, condition2) | Logical OR, Checks to see if either one of the conditions is true |
| NOT(condition) | Logical NOT, reverses the logic of its argument, true becomes false and vice versa |
## Text Functions
Function Name
What It Does
CHAR()
Returns the ASCII character specified by a number.
Example: CHAR(61) returns
=.
CONCAT(text1, text2, ...)
Joins two or more text strings into one string.
COALESCE([value1, value2, ...])
Returns the first value from the list that isn’t empty.
COUNT_CHAR(text, charToCount)
Returns the count of a specific character in a text.
Example:
COUNT_CHAR('Tokyo', 'o') returns 2.
EXTRACT(text, delimiter, position)
Extracts from the given text the substring at the given position, after
splitting by the given delimiter.
Example: EXTRACT('a_b_c', '_', 1) returns b.
FIND(findText, withinText)
Returns the starting position of findText in withinText. Returns -1 if
withinText doesn’t contain findText.
Example: FIND('l', 'Tokyo is a metropolis')
returns 18.
FUZZYMATCH(valueToMatch, array, threshold)
Searches for a string in an array of values that match using
duplicate-detecting algorithms that calculate the similarity of two streams of data.
Returns the matched string from the array if there’s a match, and returns an empty
string if there’s no match.
Example: FUZZYMATCH('ABC Company',['ABC Company
Inc','Apple Inc','IBM Company'],0.8) returns ABC Company Inc.
The threshold
parameter must be a value from 0 through 1. A threshold of 1 means an exact
match.
ISEMPTY(value)
Indicates whether the value is empty.
LEFT(text, numOfChars)
Returns the requested number of characters starting from the left.
Example:
LEFT(sourceField['name'], 3), where name is Andrew Lawrence, returns
And.
LEN(text)
Returns the number of characters in the given text.
LOWER(text)
Converts all uppercase letters in a text string to lowercase.
PROPER()
Capitalizes the first letter of each word in a text string.
Example:
PROPER('Oh! An octave is a music series of 8 notes.') returns Oh! An Octave Is A
Music Series Of 8 Notes.
REPLACE(sourceStr, pattern, targetStr)
Replaces every match of pattern (a regex expression) in sourceStr to targetStr.
Example: REPLACE('All-The-Best', '-', ' ') returns All The Best.
Example: REPLACE('Let It Be',' ','-') returns Let-It-Be.
RIGHT(text, numOfChars)
Returns the requested number of characters starting from the right.
Example:
RIGHT(sourceField['name'], 9), where name is Andrew Lawrence, returns
Lawrence.
SELECT(sourceStr, pattern)
Selects the first match of the pattern (a regex expression) in sourceStr.
Example: SELECT('Hello B wow E Goodbye', 'B(.*?)E') returns B wow
E.
SPLIT(text, delimiter)
Splits a text string into an array based on the delimiter character. It returns
a zero-based, one-dimensional array that includes the parts of the original text
string.
Example: SPLIT('a,b,c', ',') returns an array with three
items.
SUBSTRING(text, beginIndex, endIndex)
Returns the substring of the text begining at beginIndex (inclusive) and ending
at endIndex (exclusive).
SUBSTITUTE(text, oldText, newText)
Substitutes newText for oldText in a text string. Use SUBSTITUTE to replace
specific text in a text string.
TRIM(text)
Removes all spaces from the text except for single spaces between
words.
UPPER(text)
Converts all lowercase letters in a text string to uppercase.
# Supported Library Operators
Learn more about the supported library operators in the Data 360 syntax editor.
Only specific operators can be referenced in the Data 360 syntax editor.
| Operator Name | What It Does |
| --- | --- |
| a != b | Not Equals Check. Checks to see if the values on both sides of the operator are not equal. |
| a % b | Modulus. Divides the number on the left by the number on the right and returns the remainder. |
| a && b | Logical AND. Checks to see that the values on both sides of the operator are true. |
| a \* b | Multiplication. Multiples the number on the left by the number on the right. |
| a + b | Addition. Adds the value on the left to the value on the right. Use the NUMBER() function to ensure the left and right are treated as numbers. |
| a - b | Subtraction. Subtracts the value on the right from the value on the left. |
| a / b | Division. Divides the number on the left by the number on the right. |
| a < b | Less Than Check. Checks to see if the value on the left side of the operator is less than the value on the right. |
| a <= b | Less Than or Equal. Checks to see if the value on the left-hand side is less than or equal to the value on the right. |
| a == b | Equality Check. Checks to see if the values on both sides of the operator are equal. |
| a > b | Greater Than Check. Checks to see if the value on the left side of the operator is greater than value on the right. |
| a >= b | Greater Than or Equal. Checks to see if the value on the left-hand side is greater than or equal to the value on the right. |
| a || b | Logical OR. Checks to see if either the value on the left or the right is true. |
# Supported Operators for Event and Action Rule Conditions
To trigger a data action, you can select one or more event rules based on the record actions and specify when to publish data using OR and AND conditions.
### Required Editions
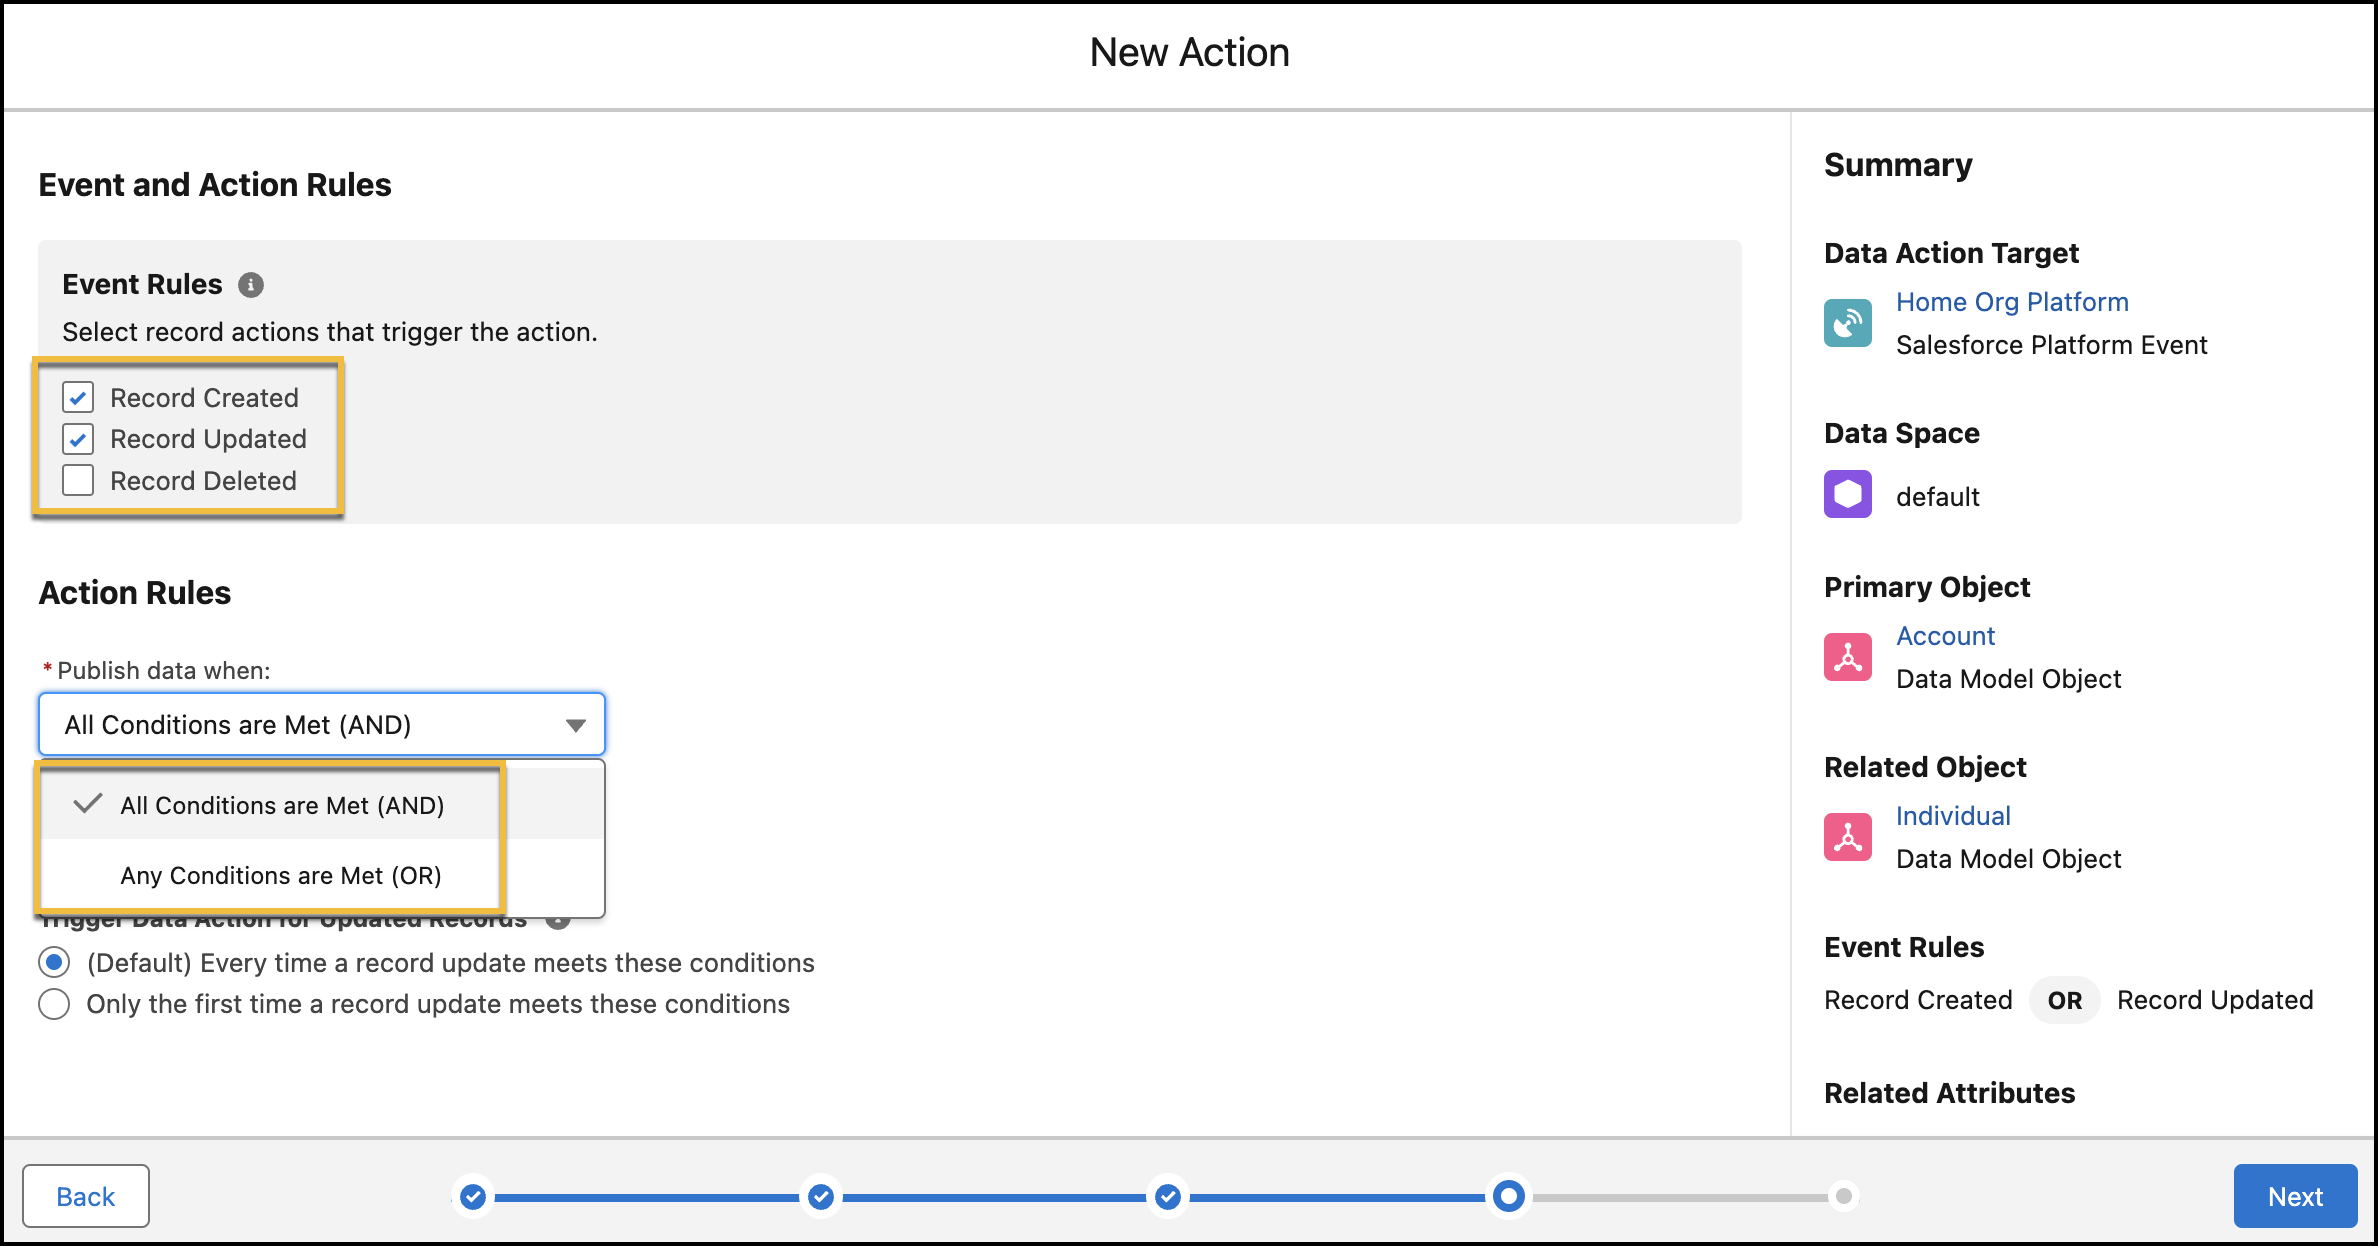
When adding conditions, you can use these operators for objects to evaluate a data action.
| Operator | Description |
| --- | --- |
| Is Equal To | The attribute value is the same as the specified value. For example, to select records where the product category is Clothing, use this operator and enter Clothing as the input value. |
| Is Not Equal To | The attribute value doesn’t match the specified value. For example, to select records where the product category isn’t equal to Clothing, use this operator and enter Clothing as the input value. |
| Is In | The attribute value must be in a multivalue, comma-separated list. For example, to select records from certain countries in the APAC region, use this operator and specify the list of countries to include such as Japan, Malaysia, Singapore. |
| Is Not In | The attribute value isn’t in a multivalue, comma-separated list. For example, to omit records from certain countries in the APAC region, use this operator and specify the list of countries to exclude such as Japan, Malaysia, Singapore. |
| Does Not Contain | The attribute value doesn't contain the specified value. For example, to select records from a subscription list that doesn’t contain website, phone, and email, use this operator and specify website, phone, email as input values. |
| Contains | The attribute value contains the specified value. For example, to select records from a subscription list that contains website, phone, and email, use this operator and specify website, phone, email as input values. |
| Contains Regular Expression | The attribute value contains or matches the regular expression in the specified value. For example, to select records from cities that contain specific characters, such as San in San Francisco, San Jose, or San Antonio, use this operator and specify the expression San as the input value. |
| Does Not Contain Regular Expression | The attribute value doesn’t contain or match the regular expression in the specified value. For example, to select records from cities that don’t include a specific character, use this operator and specify the expression as the input value. |
| Begins With | The attribute value begins with the specified value. For example, to select records for movies with titles beginning with specific characters such as Life in Life Is Beautiful or Life Is Good, use this operator and specify the expression Life as the input value. |
| Ends With | The attribute value ends with the specified value. |
| Exists As A Whole Word | The attribute value matches the entire word in the specified value. For example, if your subscription ID is Smith, Z07257, use this operator and enter Smith or Z07257 as the input value. |
| Has No Value | Evaluates if the value is null or empty. |
| Is True | Evaluates if the attribute value is present and if it’s true. For example, use this operator to check if an individual user profile is anonymous. |
| Is False | Evaluates if the attribute value is present and if it’s false. For example, use this operator to check whether a user’s subscription is current. |
| Is Null | Evaluates if the attribute value isn’t defined. For example, use this operator to check whether the consent status of a user isn’t defined. |
| Is Not Null | Evaluates if the attribute value is defined. For example, use this operator to check whether the consent status of a user is defined. |
The Record Updated event rule supports these change operators. These change operators aren’t available for related objects.
Operator
Description
Changed From
Evaluates whether the attribute value has changed from the previous value. For
example, use this operator to check whether the user has changed their consent
status from Yes.
Changed To
Evaluates whether the attribute value has changed to a specific value. For
example, use this operator to check whether the user has changed their consent
status to “opt out.”
Is Changed
Evaluates whether the attribute value has changed. For example, use this
operator to check whether the user’s subscription status has changed.
Is Not Changed
Evaluates whether the attribute value is the same as the previous value.
For
example, use this operator to check whether the user’s subscription status hasn’t
changed.
Is Empty String
Checks whether a text field value is an empty string. For example, use this
operator to check whether the user’s name is empty.
Operator
representation:
Is Empty String(null) = false
Is Empty String(“”) = true
Is Empty String(“Matt”) = false
Is Empty String(” Matt “) = false
Is Not Empty String
Checks whether a text field value isn’t an empty string. For example, use this
operator to check whether the user’s name isn’t empty.
Operator
representation:
Is Not Empty String(null) = true
Is Not Empty String(“”) = false
Is Not Empty String(“Matt”) = true
Has Increased
The attribute value has increased from the previous value.
Has Decreased
The attribute value has decreased from the previous value.
# Supported Predictive Model Types
Predictive models address common business use cases.
- **[Regression for Numbers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_use_cases.htm&release=264.0.0&type=5)**
Numeric (regression) use cases target numeric outcomes represented as quantitative data (measures), such as currency, counts, or percentages.
- **[Binary Classification for Text](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_use_cases.htm&release=264.0.0&type=5)**
Binary classification solutions target business outcomes with only two possible results, which are represented as text data.
- **[Multiclass Classification](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_use_cases.htm&release=264.0.0&type=5)**
Multiclass classification solutions provide detailed predictions, closer alignment with real-world situations, and the ability to take targeted actions.
## Regression for Numbers
Numeric (regression) use cases target numeric outcomes represented as quantitative data (measures), such as currency, counts, or percentages.
### Example of Regressions
Here are just a few examples of how models created in AI Models (formerly Einstein Studio) can help you improve numeric outcomes in your organization:
- Predicted Amount of an opportunity
- Predicted Time-to-Close of an opportunity
- Predicted Customer Lifetime Value of an account
- Predicted Customer Satisfaction of a case
### Supported Algorithms for Regression
- Generalized Linear Model (GLM) - Linear Regression
- XGBoost
- Gradient Boost Machine (GBM)
## Binary Classification for Text
Binary classification solutions target business outcomes with only two possible results, which are represented as text data.
### Binary Outcomes
These outcomes are typically yes/no questions that are expressed in business terms, such as churned or not churned, opportunity won or lost, employee retained or not retained, and so on. For analysis purposes, AI Models (formerly Einstein Studio) converts the two values into boolean true and false.
### Example Binary Classification Solutions
Here are just a few examples of how models created in AI Models can help you improve binary classification outcomes in your organization:
- Predict the probability to win an Opportunity
- Predict the probability for an Account to buy a specific product
- Predict the probability that a Lead will convert
- Predict the probability that an Account will churn
### Supported Algorithms for Binary Classification
- Generalized Linear Model (GLM) - Logistic Regression
- XGBoost
- Gradient Boost Machine (GBM)
## Multiclass Classification
Multiclass classification solutions provide detailed predictions, closer alignment with real-world situations, and the ability to take targeted actions.
### Multiclass Outcomes
With AI Models (formerly Einstein Studio), you can use multiclass classification to predict the likelihood that records fall into one of 3 and up to 50 buckets. In contrast with binary classification, which provides two outcomes, yes or no, multiclass models can handle multiple possible outcomes.
### Example Multiclass Classification Solutions
Improve outcomes in your organization with these multiclass use cases.
- Predict the most likely product from multiple up-sell or cross-sell options
- Predict the most likely product category from a catalog of offerings
- Predict the most likely next sales stage in the opportunity lifecycle
- Classify support cases into one of several case reason categories
- Classify accounts into one of several predefined customer segments
For example, a marketing team uses multiclass classification to predict the most effective communication channel for a specific customer. To target the campaign for a specific product, the model evaluates the probability that a record belongs to various categories. When customers use touchpoints, such as phone, email, or chat, the model analyzes their demographics and past interactions to recommend the appropriate channel. Precise targeting ensures that the optimal marketing channel reaches customers to drive a purchase, an upsell, or increased brand loyalty.
# Supported Regions for Amazon Redshift Integration
Data Cloud supports same-region and cross-region data sharing.
In same-region data sharing, both Data Cloud and Amazon Redshift are in the same region. In cross-region data sharing, Amazon Redshift can be in any region where data sharing is available. See [Regions where data sharing is available](https://docs.aws.amazon.com/redshift/latest/dg/datashare-overview.html#limitations-datashare). To share data across regions, a resource link is created in one region that points to a database in another Redshift region.
# Supported Regions for Databricks Integration
Data Cloud supports integration with the Databricks regions listed in Databricks clouds and regions.
See [Databricks clouds and regions](https://docs.databricks.com/en/resources/supported-regions.html).
# Supported Regions for Google BigQuery Integration
Data Cloud supports cross-cloud data sharing with Google BigQuery. In cross-cloud data sharing, Google BigQuery can be in any location where data sharing is available.
See Google’s documentation for [locations where data sharing is available](https://cloud.google.com/bigquery/docs/omni-introduction#locations).
#### See Also
- [_External Site_: Cross-cloud join limitations](https://cloud.google.com/bigquery/docs/biglake-intro#cross-cloud_join_limitations)
# Supported Regions for Private Connect Multicloud
Private Connect Multicloud isn’t available in all regions. Use this list to understand which regions are supported.
### Required Editions
Private Connect Multicloud is available on:
- us-east-1
- us-east-2
- us-west-2
- ca-central-1
- sa-east-1
- eu-central-1
- eu-central-2
- eu-north-1
- eu-south-1
- eu-west-2
- eu-west-3
- ap-northeast-1
- ap-northeast-2
- ap-south-1
- ap-southeast-1
- ap-southeast-2
#### See Also
- [_Salesforce Help_: Add a Salesforce-Managed Private Network Route for Databricks on Azure](https://help.salesforce.com/s/articleView?id=data.c360_a_add_a_salesforce_managed_private_network_route_for_databricks_on_azure.htm&release=264.0.0&type=5 "Connect Data 360 to your Azure Databricks workspace by using Private Connect Multicloud for a Salesforce-managed private network connection. Salesforce provisions and maintains the cross-cloud connection on your behalf, without needing you to configure Azure. In general, you authorize Salesforce private endpoints from your Azure environment as follows: two endpoints for a private workspace storage and one endpoint for public workspace storage.")
# Syncing Copy Field Enrichments
Learn how data is copied and synced between Data 360 and your org for copy field enrichments. Get tips for troubleshooting data syncing and changing enrichments.
The last step in creating a copy field enrichment is to start a data sync. The first sync is always a full sync.
## Full Sync And Incremental Sync
Copy field enrichments use two types of sync.
- Full Sync is a series of bulk jobs that started when you create the enrichment. The bulk jobs copy records in batches. It can take hours for all of the jobs to be complete. A full sync job can run for a maximum of 24 hours. It can process 60–100 million records, depending on the environment. Each job must be completed before the data is fully available. The log for each job is available separately in the Sync History tab for the enrichment.
- Incremental Sync uses batched events to keep your field data up to date. Incremental sync is triggered by any change in Data 360 data for the fields you're copying.

Note If more than 250,000 data changes occur in a transaction after any filter conditions are applied for copy field enrichment, the incremental sync is replaced by a full sync. A full sync reduces latency in data syncs for large volumes of changes. After the full sync completes, the system switches to incremental sync again. To learn about the cost of copy field enrichment for each sync method, see [Considerations for Enrichment Cost Impact](https://help.salesforce.com/s/articleView?id=data.c360_a_enrichment_considerations_cost.htm&type=5&language=en_US).
## Stopping and Restarting Syncs
If you stop syncing your enrichment, no more data is copied into your org, but no data or fields are removed. If you restart your sync, it performs a full sync again and copies all of the data from Data 360, which can take days. However, Salesforce recommends periodically restarting the sync, because incremental syncs behave like events and can occasionally have incomplete data for transactions with over 100,000 changes.
## Troubleshooting Sync
The Sync History tab shows every sync that changes a record in your org. It lists the type of sync and indicates its status. To see the Sync History tab, click the name of an enrichment in the list screen.
For full syncs, the Sync History tab Details column shows links to logs for each batch of changes. The logs expire after 7 days and are no longer accessible.
In some cases, a sync job succeeds as a whole, but specific records fail to be copied over. To see if individual records are failing to sync, check the Sync History tab Records Excluded column.
For incremental syncs, any errors that are encountered are shown in the Sync History tab Details column. If no records are changed in an incremental sync, the sync doesn’t appear in the Sync History tab.
If you have a key qualifier specified and the sync seems to be copying over the wrong data, check to make sure that the key qualifer is correct. If it’s incorrect, stop the sync, specify the correct key qualifier, and restart the sync.
## Record Exclusions and Errors
Records are excluded from sync for several reasons.
- Locked data—data locked by another user at the time of sync is excluded from the sync
- Orphaned data—records that don't have a corresponding user in the org are excluded from the sync. For example, assume that org A and org B have records ingested into Data 360 and you're syncing records from org A. Some amount of the records to sync are customers that only exist in org B and those records are excluded. You only sync records that are relevant for your customers. These records are orphaned records because they don't have a parent object in your org.
- Mismatched Data—data that contains characters or other issues that can’t be included in the org. These records fail validation and can’t be synced.
# Tableau Accelerators for Data 360
A Tableau accelerator provides ready-to-use dashboards and workbooks geared for a particular industry or business use case. All Tableau accelerators use the Salesforce Data Cloud connector to connect Tableau and Data 360.
## Data 360 Identity Resolution Accelerator
Explore how identity resolution in Data 360 is working for your business. In Tableau, view your ingested sources, how they contribute to unified individuals, and their composition. See how matching rules and data quality affect your identity resolution results.
See Data 360 Identity Resolution on [Tableau Exchange](https://exchange.tableau.com/products/624) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=998f2129-6168-4193-8cac-248a49ece04a).
## Data 360 Email Marketing Campaign Accelerator
Get a jump-start to data-driven insights in Tableau for monitoring the efficiency of your email campaigns. Explore campaigns that have the highest conversion, check email trends over time, and more.
See Data 360 Email Marketing Campaign on [Tableau Exchange](https://exchange.tableau.com/products/688) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=2f6f8c71-8b74-4580-87f5-613f44003225).
## Data 360 Customer Engagement Accelerator
Provide an exploratory Tableau dashboard to give marketing and sales teams with a comprehensive view of the engagement levels of customers across these channels:Select the best channels to interact with a customer, develop relevant messaging, and create positive experiences to increase loyalty and retention.
- Sales
- Email
- Messages (SMS)
- Website
- Push Notifications
See Data 360 Customer Engagement on [Tableau Exchange](https://exchange.tableau.com/products/727) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=8d11d702-b904-45d7-a780-afb599c02a94).
## Data 360 Sales Accelerator
Assess and improve your sales performance by combining sales and customer data together in a single view with data from multiple Salesforce orgs or business units. The data is ingested and harmonized into Data 360, which unifies sales data to analyze in Tableau.
See Data 360 Sales on [Tableau Exchange](https://exchange.tableau.com/products/901) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=33e3f152-7451-4e34-9c28-36e9aa4ce875).
## Data 360 Sales Pipeline Accelerator
Analyze your business in a single view using opportunity data from multiple Salesforce orgs or business units. The data is ingested and harmonized into Data 360, which unifies opportunities pipeline data and the overall sales pipeline to analyze in Tableau.
See Data 360 Sales Pipeline on [Tableau Exchange](https://exchange.tableau.com/products/896) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=b94f084d-9ae5-431a-9b72-b4b66d105b02).
## Data 360 Weighted Sales Pipeline Accelerator
Get a more accurate and realistic analysis of pipeline opportunity data based on the probability of closing. This accelerator brings opportunity data from multiple Salesforce orgs or business units into a single view. Compared to standard Pipeline, the Weighted Pipeline introduces the concept of "Probability of Closing" (expressed in %) for each opportunity, which provides a more accurate and realistic analysis of the pipeline to explore in Tableau.
See Data 360 Weighted Sales Pipeline on [Tableau Exchange](https://exchange.tableau.com/products/898) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=20d86c23-6626-41e9-9eb9-e9afcc3b1204).
## Data 360 Service Desk Accelerator
Make better business decisions, influence Key Performance Indicators (KPI), and improve overall customer service by bringing in data from multiple Salesforce orgs or business units. The data is ingested and harmonized into Data 360. View data across your entire business, including across individual Service Cloud instances in Tableau. From there, you can drill down to individual business units, all the way down to individual service agents.
See Data 360 Service Desk Accelerator on [Tableau Exchange](https://exchange.tableau.com/products/899) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=df871afe-9b11-4593-8f3a-2a6c9efc0101).
## Data 360 Retail Sales Accelerator
Unlock sales and product performance across different store locations by bringing in data from multiple Salesforce orgs or business units. The data is ingested and harmonized into Data 360 and represented in a single view in Tableau. You can analyze overall sales across all your orgs or business units as well as drill down to the lowest level of detail: Store Location, Product Line, and Product.
See Data 360 Retail Sales on [Tableau Exchange](https://exchange.tableau.com/products/897) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=64ca5a70-f1b8-4a24-a19d-5a48b88117bb).
## Data 360 Sales vs Quota Accelerator
Explore your sales performance results versus quota across your sales teams and products or services by bringing in data from multiple Salesforce orgs or business units. The data is ingested and harmonized into Data 360, which is then assessed in Tableau to effectively appraise your sales performance from different perspectives: Month-to-Date, Year-to-Date, and Actual vs Quota vs LY.
See Data 360 Sales vs Quota on [Tableau Exchange](https://exchange.tableau.com/products/900) and on [Salesforce AppExchange](https://appexchange.salesforce.com/appxListingDetail?listingId=c56b4da2-cbca-47bf-bb43-e88d28144009).

Note If you experience an issue when using an accelerator, share the details with your Tableau Account Team and ask them to contact the Tableau Accelerator Team to review the issue. Salesforce Support doesn't support the Tableau accelerators for Data 360 available on [Tableau Exchange](https://exchange.tableau.com/accelerators) and [Salesforce AppExchange](https://appexchange.salesforce.com/mktcollections/curated/tableau-accelerators?_ga=2.121680143.505645265.1694449023-1607241779.1694449023).
#### See Also
- [_Tableau Help_: Use Accelerators to Quickly Visualize Data](https://help.tableau.com/current/online/en-us/accelerators.htm)
# Tag Propagation in Data 360
Tag propagation helps maintain consistent data classification by extending tags from a primary data object to related or downstream objects and fields. This ensures that related objects in your data model carry the same metadata labels and reduces the need for repetitive tagging.
There are two types of tag propagation in Data 360.
## Manual Propagation
Propagate tags manually from a primary data object, such as a data model object (DMO), to its downstream DMOs. This method is useful when you add new tags to the source after the related objects are created.
## Automatic Propagation
Data 360 automatically propagates tags to DMOs that are generated from defined process definitions such as segments, calculated insights, data streams, and identity resolution. It applies tags from the source object to these generated DMOs. For example, when identity resolution runs, it generates a unified individual DMO by merging multiple records into a single profile. It can also create engagement DMOs, such as Email Engagement, which show calculated metrics such as open rates or visit counts. In these cases, Data 360 automatically applies tags from the source individual DMO to the generated DMOs.
- **[Propagate Tags to Downstream Objects and Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_apply_tags_to_downstream_objects_fields.htm&release=264.0.0&type=5)**
In Data 360, apply tags automatically from primary data objects to their related downstream objects to ensure consistent policy enforcement.
#### See Also
- [_Salesforce Help_: Propagate Tags to Downstream Objects and Fields in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_apply_tags_to_downstream_objects_fields.htm&release=264.0.0&type=5 "In Data 360, apply tags automatically from primary data objects to their related downstream objects to ensure consistent policy enforcement.")
# Tagging, Policies, and Access in Data Cloud One
Data Cloud One uses the same tagging, policy creation, and access management as the rest of Data 360, with added specifications. For both tagging and policy creation in Data Cloud One, the home org functions as a standalone org that can perform further syncing.
## Tag Management
In Data Cloud One, you can create tags, taxonomy, and classification only in the home org. During the initial Data Cloud One setup, a “day zero” sync transfers all existing governance artifacts from the home to the companion org. After the initial sync, automatic, incremental updates keep both orgs aligned. These syncs can occur before or after you enable Data Cloud One features, and regardless of when the tags were first created.
## Tag Assignment
Tag assignment in companion orgs has these restrictions.
- Users can assign tags within the companion org, but only to objects that were created locally within that specific companion org.
- Object tags for objects created in home orgs automatically sync to companion orgs. These objects’ tag assignments can’t be changed in the companion org.
## Tag Propagation
In a home org, tags can propagate between parent and child objects created in the org.
In a companion org, updates to home org objects automatically sync to the objects’ synced counterparts. The changes don’t automatically propagate to locally-created objects built on top of them. To propagate them, manually sync the home org-synced object to the local object.
Tags can’t be propagated between synced objects.
This table displays how the tag and taxonomy capabilities between home and companion orgs.
| Task | Home Org | Companion Org |
| --- | --- | --- |
| Tag and Taxonomy Creation | Yes | Home org admins can create new tags and taxonomies and make them available to companion orgs. You can only assign tags in companion orgs to the objects that were created there. |
| Taxonomy sync | Standard and Custom taxonomies are available for all companion orgs. | Users with permissions can view taxonomies shared by the home org. |
| Tag Assignment: Home org objects | Yes | Admins can’t change home org objects’ tag assignments. |
| Tag Assignment: Companion org objects | No | Admins can assign tags to any objects or process definitions created locally in the org. |
| Tag Propagation | Tags propagate from parent to child objects. These tags automatically propagate to synced home org objects in the companion org. | Tags can be manually propagated from synced home org objects to child objects locally-created in the companion org. They can also be propagated between parent local objects and their children. |
## Policy Management
Policies aren’t automatically synced from the home org to companion orgs. Instead, companion orgs can create their own policies and apply them to the tags and classifications synced from the home org. This includes both tag-based and non-tag based policies such as row-level security policies.
| Task | Home Org | Companion Org |
| --- | --- | --- |
| Policy Creation | Yes | Yes |
| Policy sync | Policies don’t sync to companion orgs. | Policies don’t sync to other companion orgs. |
| Policy Application: Tags | Can apply policies to locally-created tags and classifications. | Can apply policies to synced tags and classifications from the home org. |
| Policy Application: Non-Tags | Can create and apply. | Can create and apply. |
| Policy Scope | Applies to all home org content. | Applies only to local content and synced metadata. |
## Licensing and Access
Licensing control resides in the home org. Companion orgs gain access to features only when the corresponding add-ons are purchased through the home org.
#### See Also
- [_Salesforce Help_: Data Governance](https://help.salesforce.com/s/articleView?id=data.c360_a_data_gov_capabilities.htm&release=264.0.0&type=5 "Data governance provides a robust framework for securing and managing data through the combined use of tags, classifications, user attributes, and policy-based governance. Enabling policies and other governance features improves control and ensures users have access to the right data at scale.")
# Test an Ensemble Retriever
Test an ensemble retriever configuration in the AI Models retriever playground before you use it in prompt templates or AI agents. Add or remove retrievers to an ensemble, configure test data, and result parameters to verify the retrieval logic.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, test, and
delete)
Allow users to manage models in AI Models AND Access to Field Relationship Path
object
OR
Data Cloud Architect permission set
To access data with retrievers
For the Knowledge object, make sure that the user has read access to the object
and has the app permission: Allow View Knowledge
For all other standard objects,
make sure that the user has read access to the object and appropriate sharing
rules. For more information see, Set Your Internal Organization-Wide Sharing
Defaults
#### See Also
- [Create an Ensemble Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_ensemble_create.htm&release=264.0.0&type=5 "Use ensemble retrievers to get the most relevant information from multiple searches or data sources. In AI Models (formerly Einstein Studio), an ensemble retriever is a collection of individual retrievers. When you run an ensemble retriever, it runs all the individual retrievers, combines their results into a single list, reranks the list according to relevance to the search request, and returns just the most relevant information to the prompt or agent.")
## Customize an Ensemble Retriever in the Playground
1. In AI Models on the Retrieve tab, select **Test Retriever**. Alternatively, select **Test Retriever** for an ensemble retriever from the drop-down action menu.
Ensemble retrievers that contain Agentforce Data Library (ADL) retrievers can't be tested in the playground.
2. Select a mode for testing the retriever. In the basic mode, the retriever playground returns a source recall score and a response time. In the advanced mode, the playground returns an AI-generated context recall score and a context precision score based on an expected answer to a test question. For more information on metrics and costs, see, [Retriever Metrics and Results](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_metrics.htm&type=5&language=en_US) and [Billing Considerations for Testing Retrievers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_billing.htm&type=5&language=en_US).
3. Select an ensemble retriever that you want to test and validate.
When you search for retrievers, only active retrievers are listed. The retriever configuration panel shows the individual retrievers that are part of the ensemble retriever.
4. To customize or reconfigure the ensemble retriever, select **Edit**.
5. Select or deselect retrievers by data space.
An ensemble retriever can contain a maximum of 10 individual retrievers. The **Select Retriever** tab shows the retrievers that are part of the ensemble.
6. Modify the number of results that you want the retriever to return.
If the results to a user's question don't include the expected response, increase the number of results returned.
7. Customize the fields returned by the retriever by adding or removing existing fields.

Note The retriever returns these new fields when you save the configuration and use it with agents.
8. (Optional) Turn on **Citations Settings** to preview and validate citations from individual retrievers.
## Test Your Retriever
Configure expected source data and enter a natural language query to test your retriever. Expected source data is the desired source from where the correct answer is expected. With ensemble retrievers, the desired source records can be part of different retrievers. In the playground, you can select test data from each individual retriever that is part of the ensemble.
1. To test your retriever responses from expected sources, select **Configure Expected Source Data**.
2. In the **Configure Expected Source Data** window, select a retriever.
3. Select data model object if you know which records contain the response or select keyword search.
For hybrid search retrievers with keyword matches, select test data by keyword search or data model object records. Otherwise, you can only select by data model object records. Select data model object records if you know which records contain the response to your test question. Select records based on a keyword search if you know what your response should include, such as, for a question related to paid time-off, you can enter “PTO or Time-off.”
4. Repeat steps two and three for each retriever that is part of the ensemble.
You can select up to five test data records for each individual retriever in the ensemble.
5. Ask a test question. In the advanced mode, you can test your retriever responses based on an expected answer to the test question.
After you run your test, the Test Retriever panel shows the number of documents retrieved by the retriever.
In the Results panel, review the overlap between the top chunks returned by the retriever and the expected source data chunks. Verify validity of sources with links to citations for the retrieved chunks. Customize retriever configuration with your test data to get the optimal response. Save tested configurations as new versions.
# Test an Individual Retriever
Test a retriever configuration to ensure accurate responses from your AI agents. Save retriever configurations as new versions of the retriever in AI Models (formerly Einstein Studio). Activate them for use in agents with prompt templates, Flow, and apps.
### Required Editions
User Permissions
Needed
To manage retrievers or versions in AI Models (create, edit, test, and
delete)
Allow users to manage models in AI Models AND Access to Field Relationship
Path object
OR
Data Cloud Architect permission set
To access data with retrievers
For the Knowledge object, make sure that the user has read access to the object
and has the app permission: Allow View Knowledge
For all other standard objects,
make sure that the user has read access to the object and appropriate sharing
rules. For more information see, Set Your Internal Organization-Wide Sharing
Defaults
## Configure Retriever
Customize your retriever configuration with filter conditions, expected source data, and expected results.
1. In AI Models on the Retrieve tab, select **Test Retriever**. Alternatively, select **Test Retriever** for an individual retriever from the drop-down action menu.
You can't test default retrievers that were automatically created.
2. Select a mode for testing the retriever. In the basic mode, the retriever playground returns a source recall score and a response time. In the advanced mode, the playground returns an AI-generated context recall score and a context precision score based on an expected answer to a test question. For more information on metrics and costs, see, [Retriever Metrics and Results](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_metrics.htm&type=5&language=en_US) and [Billing Considerations for Testing Retrievers](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_test_billing.htm&type=5&language=en_US).
3. Select a retriever that you want to test and validate.
The retriever configuration panel shows the search index and retriever details for review.
4. Include all records or filter records that meet the conditions to customize retriever configuration. Configure up to ten filter conditions for retrieval of records based on filter conditions.
For example, define simple filter conditions such as "document published date is after 2022" or " Company name is equal to Salesforce."
To select field values at run time, define dynamic filter conditions. For example, to select a car make and model at run time for questions about car mileage, define filter conditions such as, 1. Make Equal to {!$Make} and 2. Model Equal To {!$Model}.
Select the conditional logic to use filters when all conditions are met, any condition is met, or custom conditional logic is met. For example, with the test question about car mileage, add a third condition, 3. ModelYear greater than 2000. You can configure a custom condition where conditions 1 AND (2 OR 3) are met.
5. Modify the number of results that you want the retriever to return.
If the results to a question don’t include the expected response, increase the number of results returned.
6. Customize the fields returned by the retriever by adding or removing existing fields.

Note The retriever returns these new fields when you save the configuration and use it with agents.
7. (Optional) Preview and validate citations for a retriever by configuring citations.
1. To automatically generate citations that include the source URL, and a heading text, select **Standard Citations**.
2. To customize the citation, select **Custom Citations**. Optionally, enter a base URL, source DMO field that contains the full link or a URL path that can be combined with the base URL, and the source DMO field to use for the citation heading. For example, if the source DMO contains a citation to a specific help page such as [Retrieve Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever.htm&language=en_US&type=5). Enter a base URL of [https://help.salesforce.com/s/articleView?id=&language=en\_US](https://help.salesforce.com/s/articleView?id=&language=en_US) and the URL path would be the source DMO field that contains the document ID, data.c360\_a\_ai\_retriever.htm. If the source DMO has a field with the entire URL path, then don’t enter a base URL path. Set the URL path to the source DMO field that contains the entire URL path.
3. Click **Save**.
## Test Your Retriever
Enter a natural language query and set expected source data to evaluate how accurately your retriever returns content. Expected source data is the content you expect for a correct response.
1. In the Test Retriever panel, ask a test question. In the advanced mode, you can also test your retriever responses based on an expected answer to the test question.
2. Optionally, define dynamic filter values.
3. To test your retriever responses from expected sources, select **Configure Expected Source Data**.
4. Select data model object records if you know which records contain the response or select keyword search.
For hybrid search retrievers with keyword matches, select expected source data by keyword search or data model object records. Otherwise, you can only select by data model object records. Select data model object records if you know which records contain the response to your test question. Select records based on a keyword search if you know what your response should include, such as, for a question related to paid time-off, you can enter “PTO or Time-off”.
**Configure Expected Source Data**
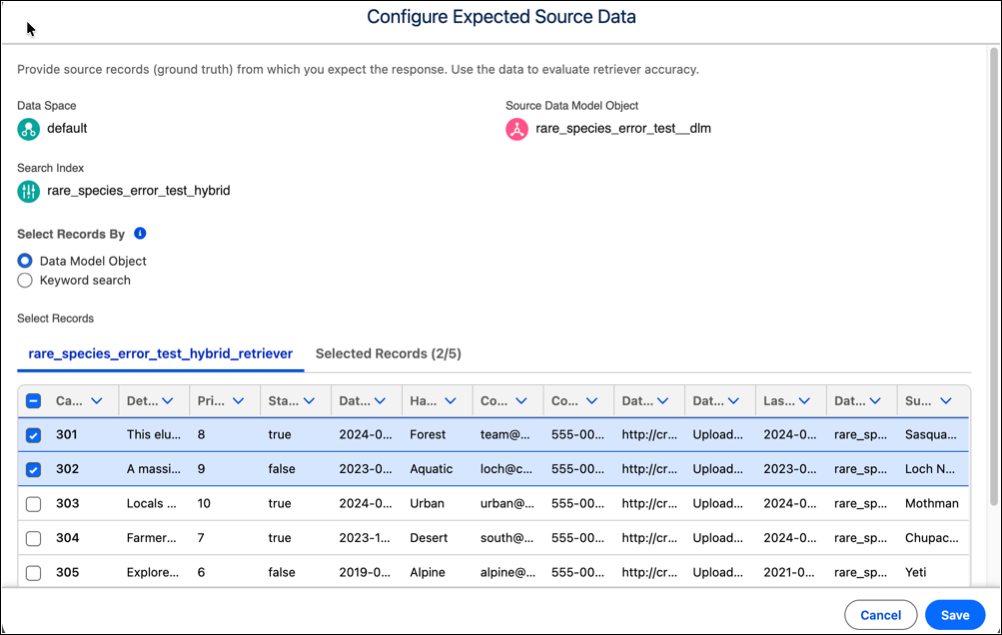
After you run your test, the Test Retriever panel shows the number of documents retrieved by the retriever. In the Review Results panel, review the overlap between the top chunks returned by the retriever and the expected source data chunks. Verify validity of sources with links to citations for the retrieved chunks. Optionally, customize retriever configuration to get an optimal response. Save tested configurations as new versions.
#### See Also
- [Retriever Filters Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_retriever_filter_reference.htm&release=264.0.0&type=5 "Configure filter conditions for retrieval accuracy when you create or test retrievers in AI Models (formerly Einstein Studio). Use filter conditions to filter records retrieved for search queries. You can configure up to ten filter conditions for an individual retriever.")
- [Create an Individual Retriever](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever_create.htm&release=264.0.0&type=5 "To improve the relevancy of the content returned to a prompt for a particular use case, create a custom individual retriever in AI Models (formerly Einstein Studio). To customize the retriever, select its search index, define filters, and specify what information it returns.")
# Test Your Prompt
Before you put a model into production, test it using prompts in Model Playground to evaluate the generated responses based on your model’s hyperparameter settings.
1. In Model Playground, enter a prompt, such as a question or task.
For example, enter a prompt to create an email to offer a new customer an online deal.
2. Click **Settings**.
3. Enter the number of responses for each prompt and the stop sequence.
4. Enable data masking to mask sensitive information during testing. If you don’t enable masking in Model Playground, org-level data masking settings are applied.
These prompt settings are used only during testing. They aren’t saved with your model configuration.
5. To get a prompt response, click **Generate**.
6. To evaluate your prompt, click **Debug**.
7. If you’re satisfied with the quality of your test prompt, save your work and exit Model Playground.
# Testing an Activation Platform Package
Test an activation platform package by installing it either in an Enterprise or Developer Edition org that has a provisioned Data 360 license. For more rapid testing and inspection of file outputs as you develop your app, use a Dev org to trigger manual activation publish. When testing your activation platform app in an Enterprise org, activation files are published every 24 hours if the activation output is grouped by user identifiers (PER\_USER). If the activation output is grouped by segments (PER\_SEGMENT), the refresh schedule is tied to the segment publish schedule.
### Required Editions
Available in: Lightning Experience
- **[Use a Package Subscriber Org for Testing](https://help.salesforce.com/s/articleView?id=data.c360_a_use_package_subscriber_for_testing.htm&release=264.0.0&type=5)**
When using a Developer edition org in the context of a packaged app, Salesforce uses the terms Packaging org and Package Subscriber org. The Packaging org is where the package is created. The Package Subscriber org is an org that has installed a package from a Packaging org. To speed up testing, developers can now install their package in another Dev org and manually trigger an activation publish.
- **[Use a Package Subscriber Org to Trigger a Publish](https://help.salesforce.com/s/articleView?id=data.c360_a_trigger_a_manual_publish.htm&release=264.0.0&type=5)**
To speed up testing, use the package subscriber org and manually trigger an activation publish to inspect and validate the output files.
# Text a Policy Change SMS Notification (B2C) Use Case
Cumulus Bank wants to send a SMS message to notify their customers living in California to check their account about upcoming policy changes. They want to ensure they’re including all phone contact points available for their customers that have provided consent.
## Identify Requirements
- **Goals**
- Send an SMS notification to all customers living in California about their upcoming policy changes.
- **Personalization components**
- The SMS message includes the customer’s first name and last name.
- **Audience and data sources**
- Customers living in California who provided consent and their phone number.
- DMOs involved: Unified Individual, Individual, Contact Point Phone, Contact Point Subscription Consent, Communications Subscription Consent
- **[Create the Audience Segment in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc3_policy_create_segment.htm&release=264.0.0&type=5)**
To create an SMS message to notify California-based customers about their upcoming policy changes, follow these steps in Data Cloud to create an audience segment.
- **[Filter the Segment and Publish to Marketing Cloud Engagement](https://help.salesforce.com/s/articleView?id=data.c360_a_activation_filtering_uc3_policy_filter_segment.htm&release=264.0.0&type=5)**
After you create a segment, you can narrow the audience by adding filters. For this use case, you filter by consent status and whether the person has provided their phone number.
# Text to Date Transformation: Convert the Column Type
A date column is sometimes tagged as text if it contains unexpected string values or dates in different formats. To use date functionality, such as grouping by month, use the Text To Date transformation to change the Text column type to Date.
1. In the Transform node, select the text column that you want to convert to the Date column type. For example, you standardized the dates in a text column and now want to convert the column type to Date.
2. In the Transform toolbar, select **Text to** | **Date**.
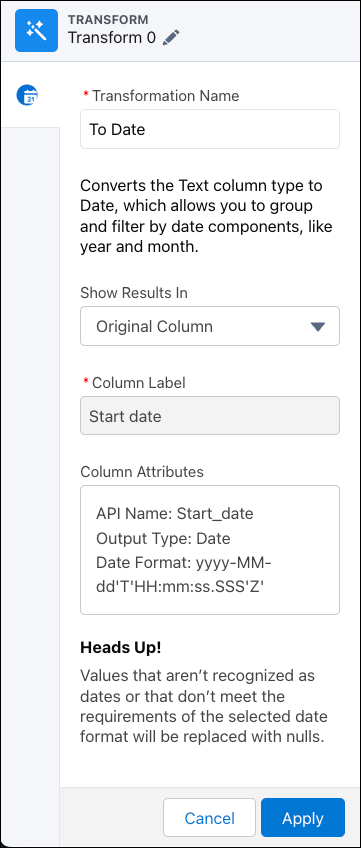
3. In the Date Format field, select the date format to display the dates.
4. Under Show Results In, select whether the new values appear in a new column and whether to keep the original column.
5. If you elect to create a column, set the label under Column Label.
6. To add the transformation to the Transform node, click **Apply**. The Preview tab shows the new date component column.
7. To view the canvas area, click the **Collapse** button ().
Run the data transform to convert the column type to Date and the date values to the specified format. If the transformation can’t parse a date value, it replaces the value with null.
# Text to Number Transformation: Convert the Column Type
To perform a mathematical calculation on the column, such as calculating the average, use the Text To Number transformation to change the Text column type to Number. You can perform mathematical calculations on numeric columns only. Numeric types include the percent data type.
During the column type conversion, the Dimension to Measure transformation rounds decimals to the nearest whole number. For example, 300.2939 becomes 300.
1. In the Transform node, select the dimension column that you want to convert to the Measure column type.
2. In the Transform toolbar, select **Dimension to** | **Measure**.
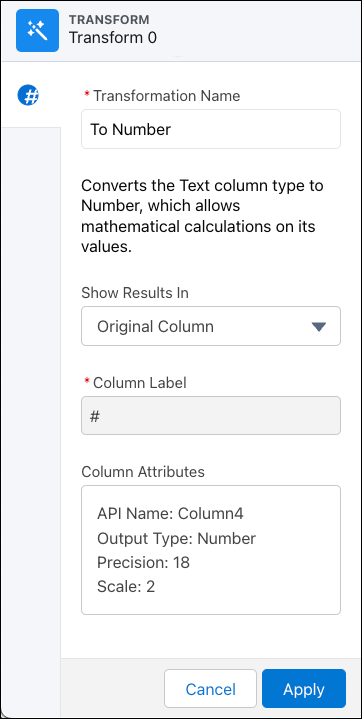
3. Under Show Results In, select whether the new values appear in a new column and whether to keep the original column.
4. If you elect to create a column, set the label under Column Label.
5. To change more column attributes, click the **Column Attributes** box, change them, and click **Apply**.
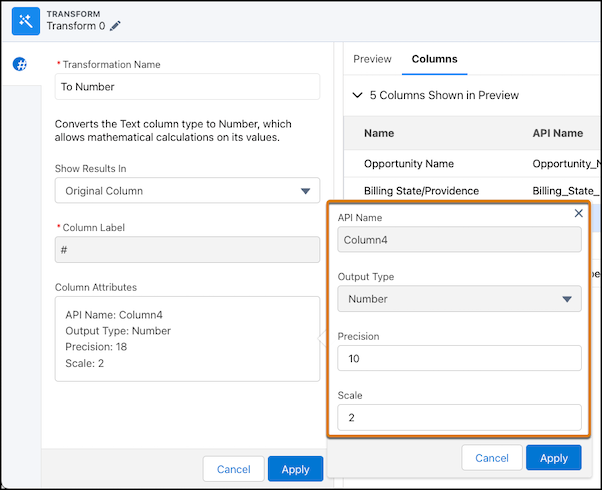
6. Based on the output column’s data type, you can set these attributes.
Attribute
Description
API Name
The API name of the column. The column API name can each be up to 255 characters.
The API name must also be unique within the batch data transform.
Precision
The maximum number of digits in a numeric column. Includes all numbers to the left and
to the right of the decimal point (but excludes the decimal point character). Enter an
integer from 1 through 18, inclusive.
If a numeric value exceeds the specified precision, the value is set to 0 or null,
depending on whether null measure handling is enabled. For example, if precision is set
to 5 and null measure handling is enabled, the numeric value 123456.78 is replaced with
null.
Scale
The number of digits to the right of the decimal point in a numeric column. Enter an
integer from 0 through 17, inclusive. The scale must be less than the precision. For
example, if the numeric value is 123456.789 and you set the scale to 2, the number appears
as 123456.78.
Length
The maximum number of characters in a text column. Enter an integer from 1 through
32000, inclusive. The default length is 255 characters.
Date Format
The date format of a date column.
For more guidelines, see Field Name Restrictions in [Analytics External Data Format Developer Guide: External Data Metadata Format Reference](https://developer.salesforce.com/docs/atlas.en-us.bi_dev_guide_ext_data_format.meta/bi_dev_guide_ext_data_format/bi_ext_data_schema_reference.htm).
7. To add the transformation to the Transform node, click **Apply**. The Preview tab shows the measure column.
8. To view the canvas area, click the **Collapse** button ().
Run the data transform to convert the column type to measure.
# Tips for Improving Account Matching
Creating rules with overly broad criteria can result in poor account matching. Consider these guidelines when setting up identity resolution match rules for unifying accounts.
## Limit Geographical Location
For example, a match rule with these criteria is unlikely to result in good matches.
- (Fuzzy Match - High Precision) Account Name
- (Normalized) State
- (Normalized) Country
Overly broad criteria can cause two seemingly conflicting problems.
- **Too Many False Positives**\--In large datasets, overly broad matches with these criteria can try to evaluate every account in a particular state and country. This can lead to too many accounts being matched into a single group.
- **Missed Matches**\--When too many source profiles match, some records can be skipped during processing. The records skipped can be different each time identity resolution runs because records are reviewed in arbitrary order. This can lead to matching records being missed.
You can reduce the number of records considered for matching by defining more specific geographic areas. For example, include city or postal code as match criteria rather than allowing matching across an entire state, province, or country. Reducing the geographical area leads to more reliable and precise matching.
## Combine Multiple Match Rules
Each match rule you add to a ruleset provides an opportunity to match accounts in a different way. Allow for multiple sets of match criteria and match methods by setting up multiple match rules within a ruleset.
This set of five match rules allows for a variety of match options within a ruleset.
- Fuzzy Account Name and Normalized Address
- Fuzzy Account Name and Normalized Phone Number
- Account Identifier -- D-U-N-S Number
- Account Identifier -- External MDM Id
- Account Identifier -- Demandbase
# Topic Classification
Use topic classification in Data 360 to organize unstructured text such as reviews, case comments, or survey responses, into meaningful categories. To evaluate records for classification, the model applies a trained language model to a selected field. For each record, the model assigns a topic label and a confidence score. Data 360 adds these outputs to your dataset. Apply topic classification in reporting and queries.

Note
All topic classification models and algorithms use the new runtime.
Review these topic classification goals.
- Classify text into categories—for example, billing, product issues, or feature requests.
- Standardize how text data is organized across datasets.
- Identify trends and patterns by topic.
- Segment data based on topics for targeted engagement.
- Enrich datasets with topic labels and confidence scores.
## Use Cases
Forecasting supports various use cases.
TYPE USE CASE WHAT DOES IT SOLVE Marketing Segment Audiences To create more targeted campaigns, group customers by interests or topics. Analyze Campaigns To understand what messaging resonates, classify responses and engagement by topic. Strategize Content Identify themes across emails, web, and social channels. Service Track Issues To speed up resolution, automatically categorize support cases, such as billing or technical issues. Route Cases To speed up resolution, automatically categorize support cases, such as billing or technical issues. Manage Escalations To handle cases faster, flag sensitive or high-priority topics, such as complaints or disruptions. Sales Analyze Deal Insights To identify key topics, such as pricing, objections, or competitors, analyze emails, and call transcripts. Route Leads To assign leads to the right team, classify inbound inquiries by product, industry, or use case. Upsell and Cross-Sell Surface high-intent topics, such as demo requests or pricing discussions.
## Considerations
Before you apply a topic classification model, review these considerations.
- Overlapping or ambiguous categories reduce accuracy.
- Very short or unclear text is harder to classify.
- Model performance depends on the quality and relevance of input data.
- The model is multilingual and supports text in multiple languages.
## Limitations
Before you use topic classification, review these limitations.
- Define clear and distinct topic categories for better accuracy.
- Use text data that reflects actual customer language.
- Review and refine categories periodically as business needs evolve.
- Combine topic classification with sentiment analysis for richer insights.
- Chunk the long text before you pass it through the model. Topic classification works best on short, intent-rich text up to 512 tokens
# Track Calculated Insight History
When you start history tracking on a calculated insight, Data 360 creates a calculated history insight.
### Required Editions
1. Go to the **Calculated Insights** list view.
2. Choose an active calculated insight:
1. From the drop-down arrow, select **Track History**.
2. Click the calculated insight to go to the record page, and from the drop-down arrow, select **Track History**.
3. Select the **Track history** checkbox.
4. Choose the **Schedule** and **Time** for the calculated insight.
5. Click **Save**.
The list view displays the new calculated history insight with the original source name appended with `History`.
The output for history tracking insights include the `history_capture_ts` timestamp field.
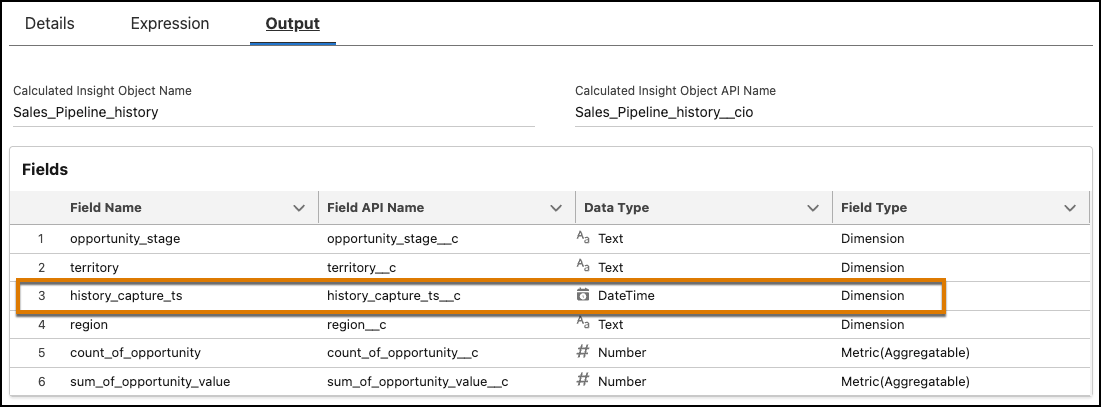
# Track Metrics with Calculated History Insights
Track how your metrics evolve over time to make data-driven decisions.
### Required Editions
Business metrics are essential for measuring success. However, important metrics like Sales Pipeline, Service Call Stats, or Brand Awareness Scores can be difficult to track over long periods of time. With calculated insight history in Data 360, you can see how these metrics and dimensions change over time..
Here's an example of how storing metric and dimensions using history tracking leads to more informed decisions. In this example, the source definition for Sales Pipeline is:
```
SELECT Region, Territory, Deal Stage, SUM(Opp Value) AS Pipeline Value
FROM Opportunity
GROUP BY Region, Territory, Deal Stage
```
When you turn on history tracking on a calculated insight, Data 360 creates a new calculated history insight. The calculated history insight captures data at a specific time and appends the calculated insight object values to the calculated history insight object.
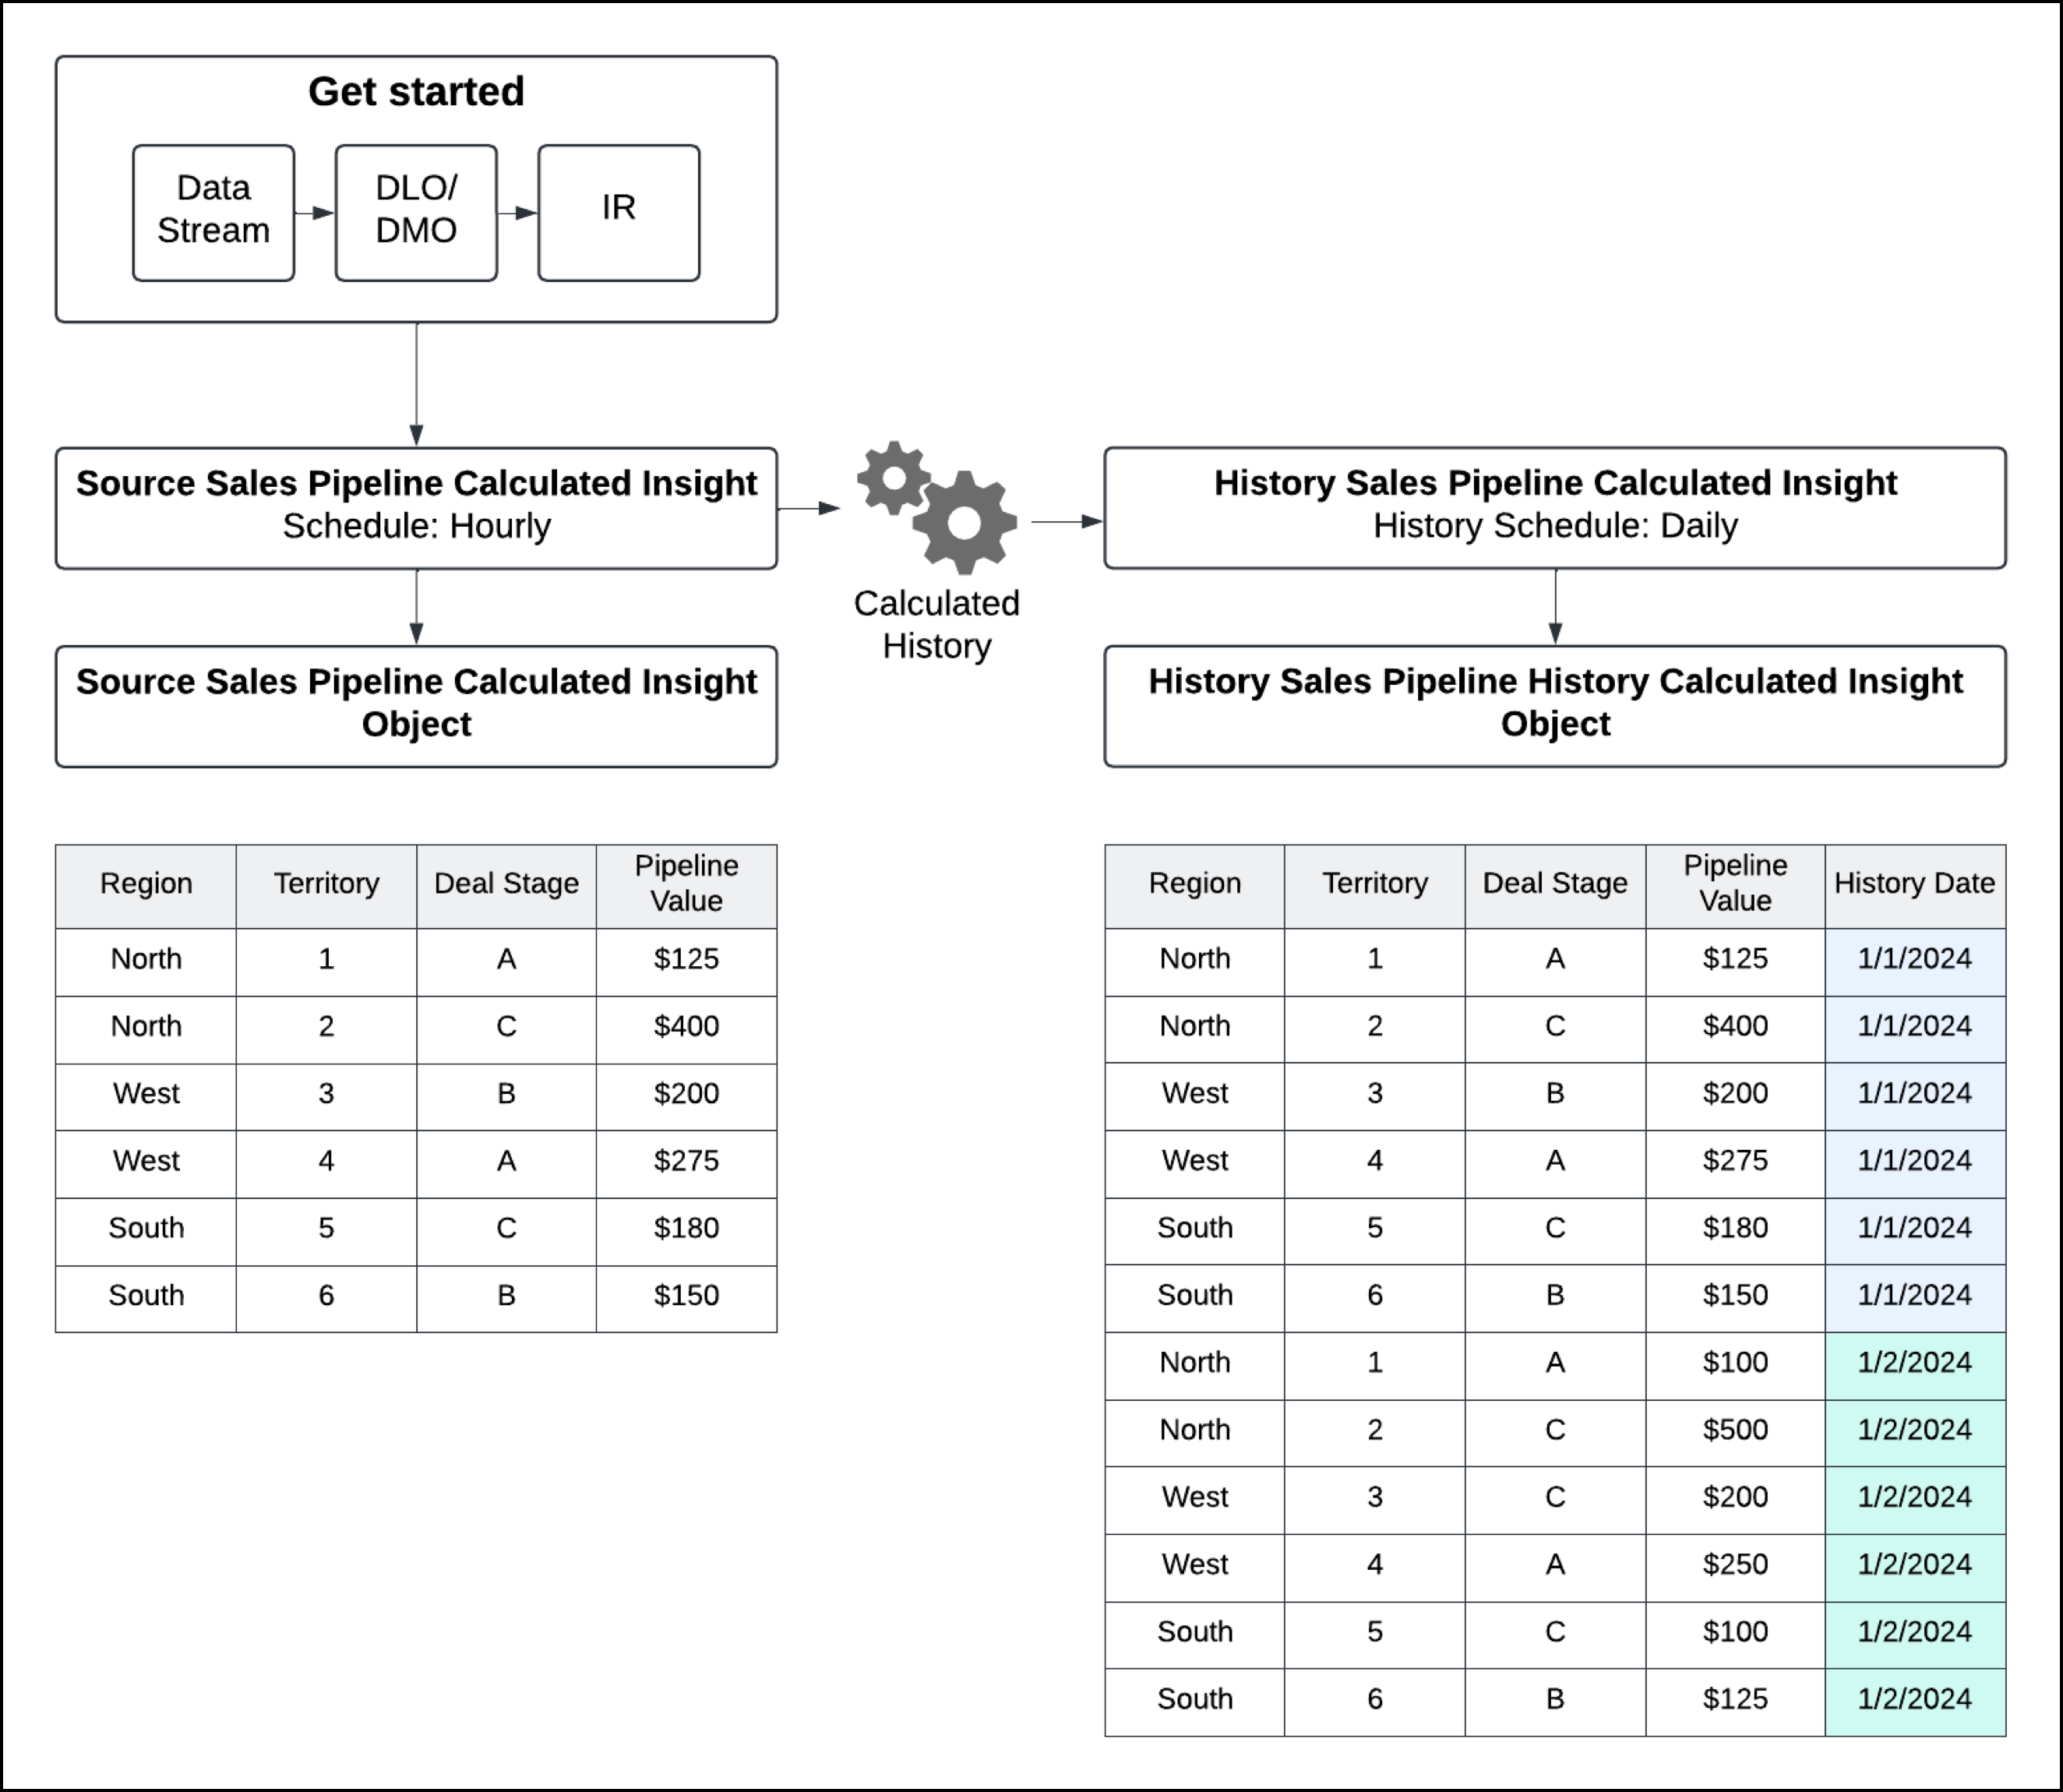
As data in the source calculated insight changes, the calculated history insight tracks and records these changes. You can use Data Explorer to see your Calculated History Insights and how your company's data evolves over time. Use history tracking for use cases like these:
- Review which deal stage progression loses the most pipeline value
- Split or combine territories based on value trends
- Trend future value based on MoM, QoQ, YoY
- Compare Sales forecast to actual sales
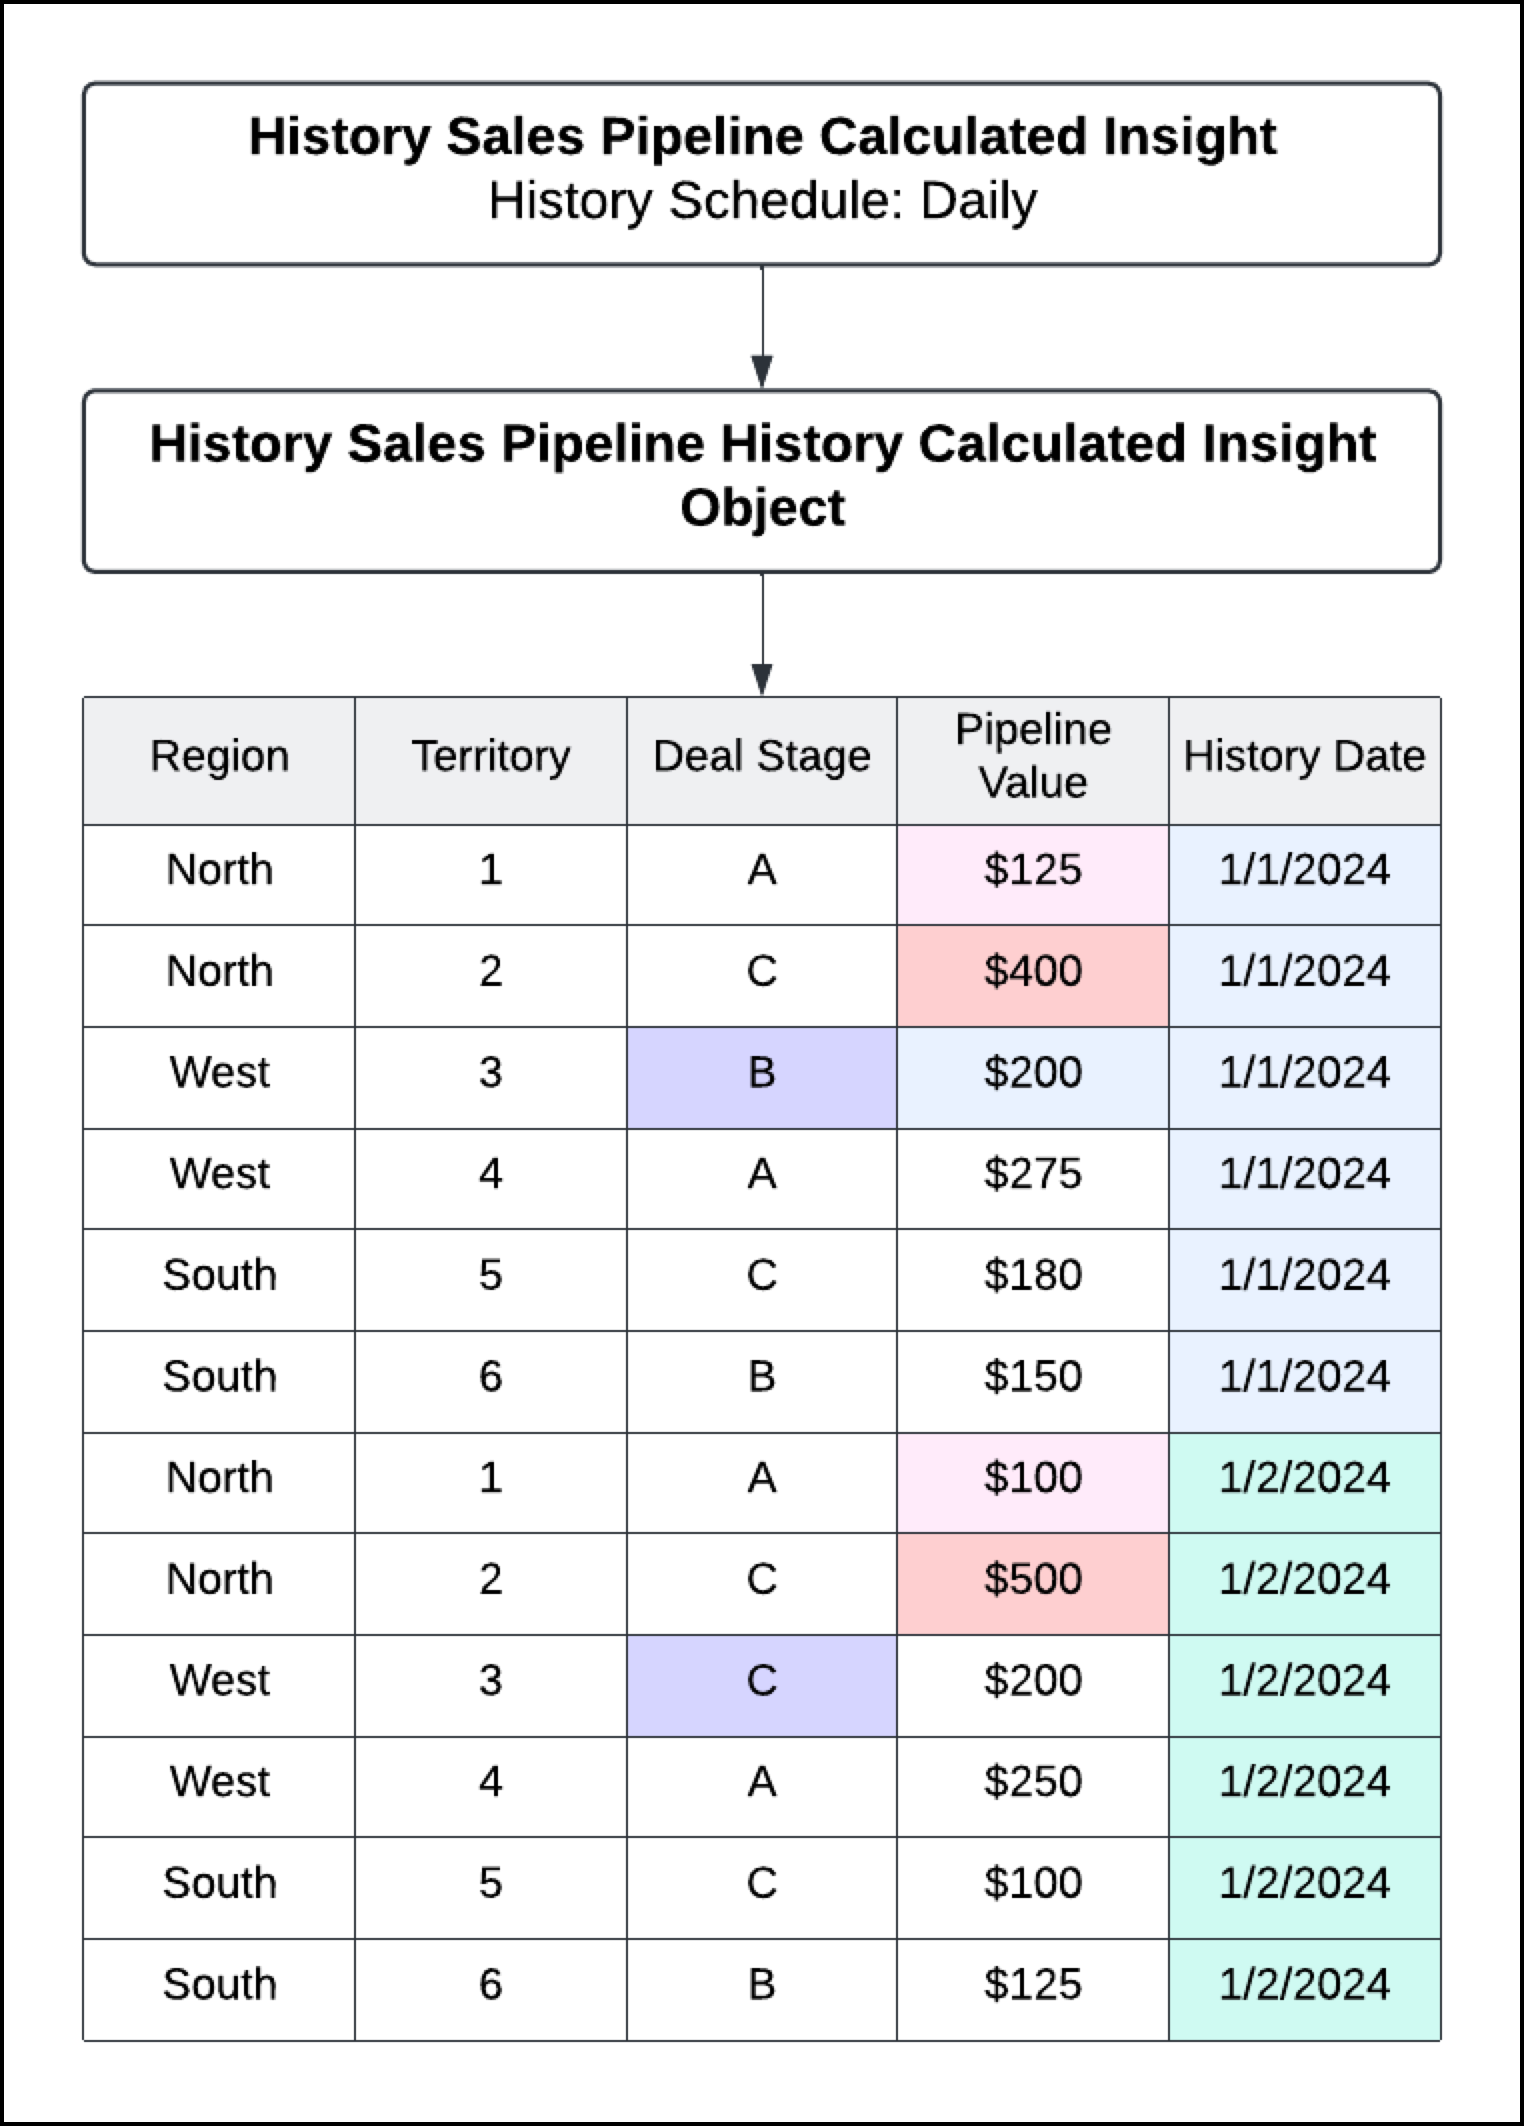
## Get Started With History Tracking
- **[History Tracking Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_history_tracking_considerations.htm&release=264.0.0&type=5)**
Keep these considerations in mind when using history tracking.
- **[Track Calculated Insight History](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_apply_history_tracking.htm&release=264.0.0&type=5)**
When you start history tracking on a calculated insight, Data 360 creates a calculated history insight.
- **[Delete a History Tracking Calculated Insight](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_delete_history_tracking.htm&release=264.0.0&type=5)**
If it’s no longer needed, you can delete a history tracking insight.
- **[Edit a History Tracking Calculated Insight](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_history_track_edit.htm&release=264.0.0&type=5)**
You can modify the frequency, duration, and activation status of history tracking insights.
# Transform Data with Predictions and Prescriptions
Enrich a data model object (DMO) with outputs. Use a data transform to add predictive and prescriptive intelligence to your data. Run data transformations and save the outputs, such as prediction scores, on a DMO. Use each row of the output to create derived columns and run calculations. You can also build data visualizations using output data saved on the DMO in other Salesforce applications, such as in Tableau, CRM Analytics, and app templates.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. In Data Transforms, click **New**.
2. Select **Batch Data Transform**.
3. Click **Data Model Objects** and select the data space where you want to store the output.
4. Select the DMO that you want to add the input data to and the fields that you want to use.
If you change the DMO during the transformation, your data will reset and you must start over.
5. To add a transform node, click **+** on the DMO.
6. To initiate the data transform node, click **AI Model**.
7. Select the AI model, and click **Next** to launch the model in the transform editor.
8. On the Map Fields tab, map your model schema fields with your input fields.
9. On the Modify Output tab, to include factors with the highest impact on each prediction, click **Top Predictors**. This setting appends a description and an impact column on your dataset.
This tab appears only for Salesforce-created models.
10. Select up to three predictors.
11. Preview your data and check the columns in your output DMO.
12. To save your prediction outputs in the DMO, click **Apply**.
To visualize your data inputs, upload your DMO to other applications in Salesforce, such as CRM Analytics.
#### See Also
- [_Salesforce Help_: Batch Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_overview.htm&release=264.0.0&type=5 "To transform your data for further usage, such as identity resolution, segmentation, or calculated insights, or to derive insights in Salesforce reports, use a batch data transform. A batch transform is a repeatable series of operations that you can run when data updates. The first time you run a batch data transform, it pulls in data and defines it according to your steps. You can then run a transform manually or set it up to run at scheduled intervals.")
- [_Salesforce Help_: Create a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_create.htm&release=264.0.0&type=5 "Create a batch data transform with data lake objects or data model objects by using the in-app builder.")
# Transform Node: Transform the Data Before Loading It Into an Output
Use a Transform node to manipulate data based on the transformations added to the node. You can add one or more transformations to each Transform node. For example, you can add transformations to concatenate two columns, standardize the formats in a date column, and detect the sentiments of comments in a feedback column. Each transformation modifies the data in a unique way. To manipulate data at multiple stages of a data transform, add a separate Transform node at each stage.
1. In the batch data transform, select the **Add Node** button () between two nodes or at the end of the batch data transform. To show the Add Node button between two nodes, hover the cursor on the connecting line.
2. In the Add Node dialog box, select **Transform**.
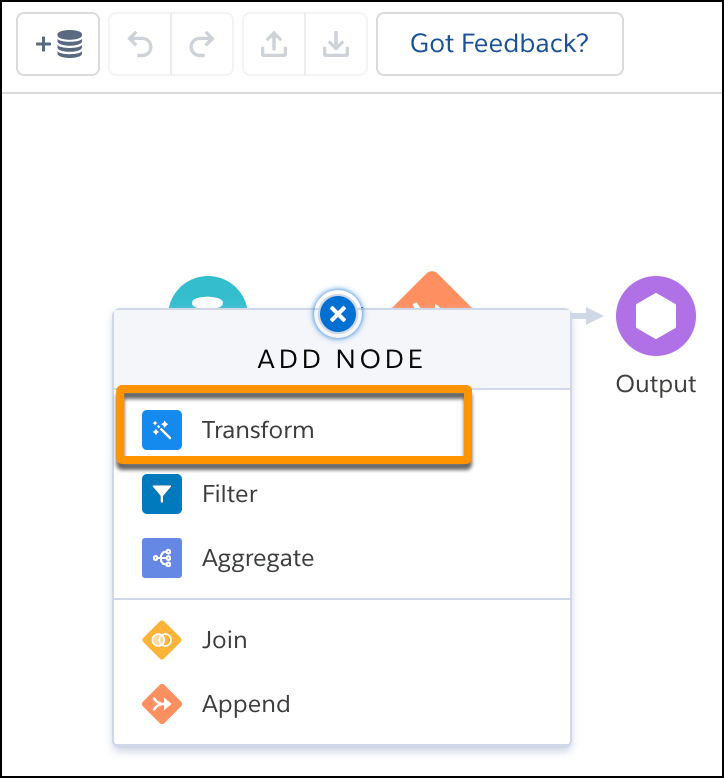
3. In the Preview tab of the details section, select one or more columns for which you want to transform their data.
4. Use the Transform toolbar (1) to add a transformation based on the selected column(s). Each time you add a transformation to the Transform node, it appears in the left panel (2). We refer to each card in the left panel as a step.
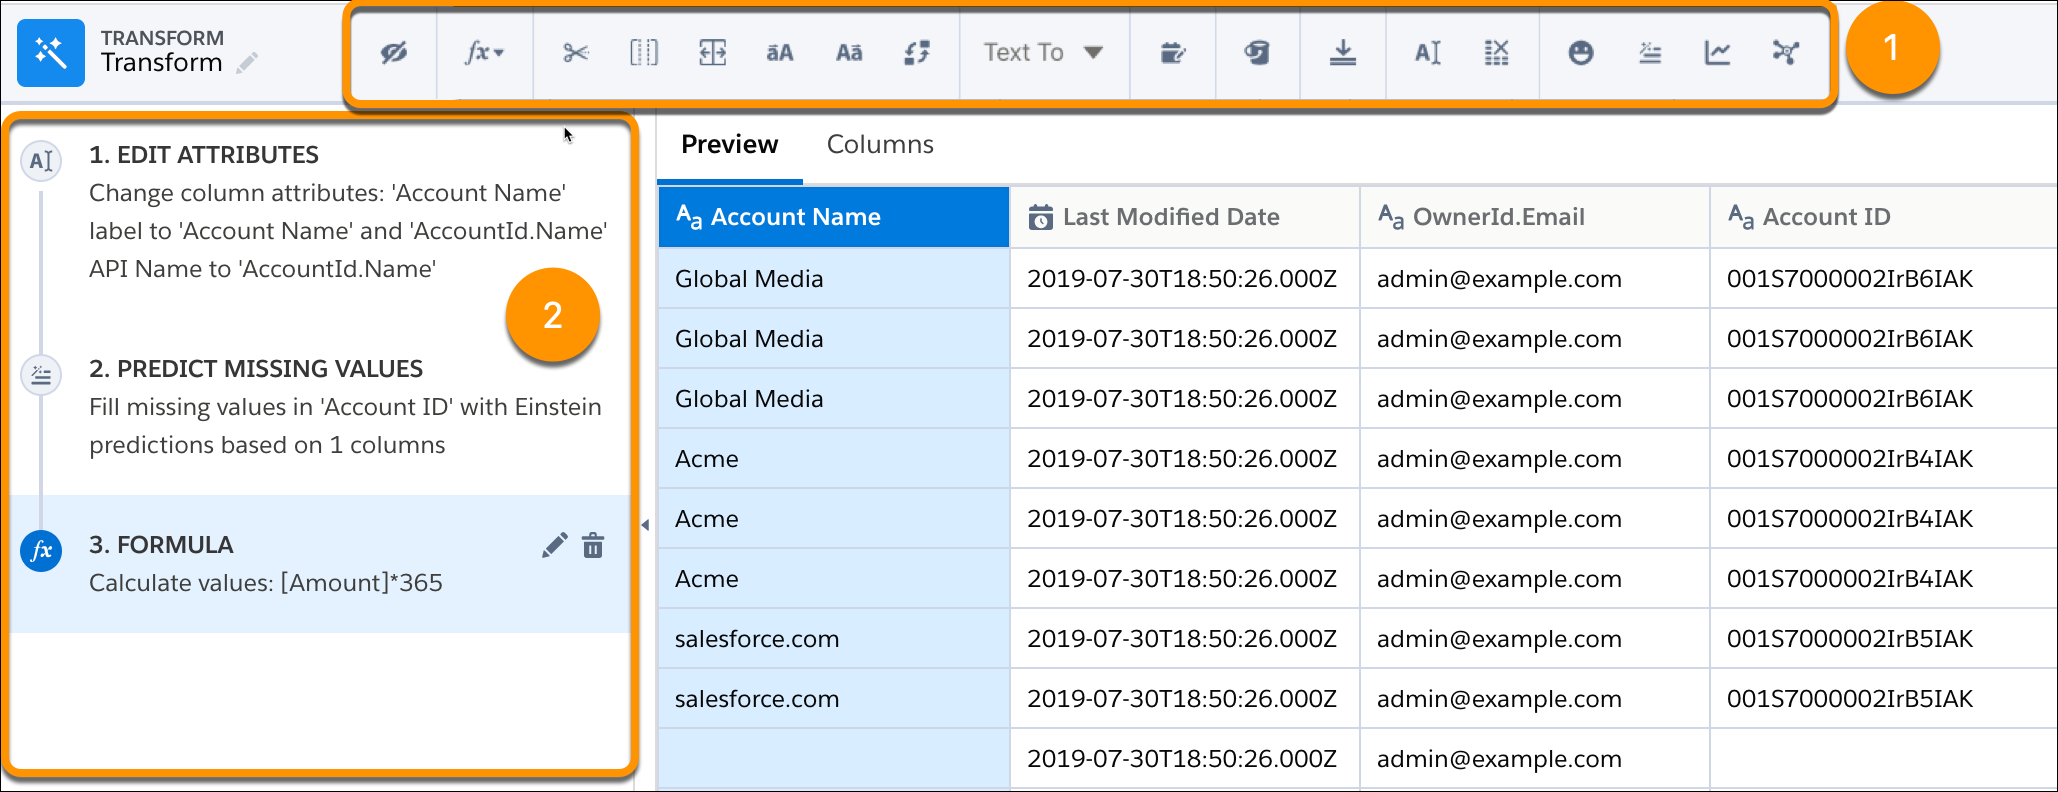
5. To preview the results of a transformation in the Preview tab, select the step in the left panel.
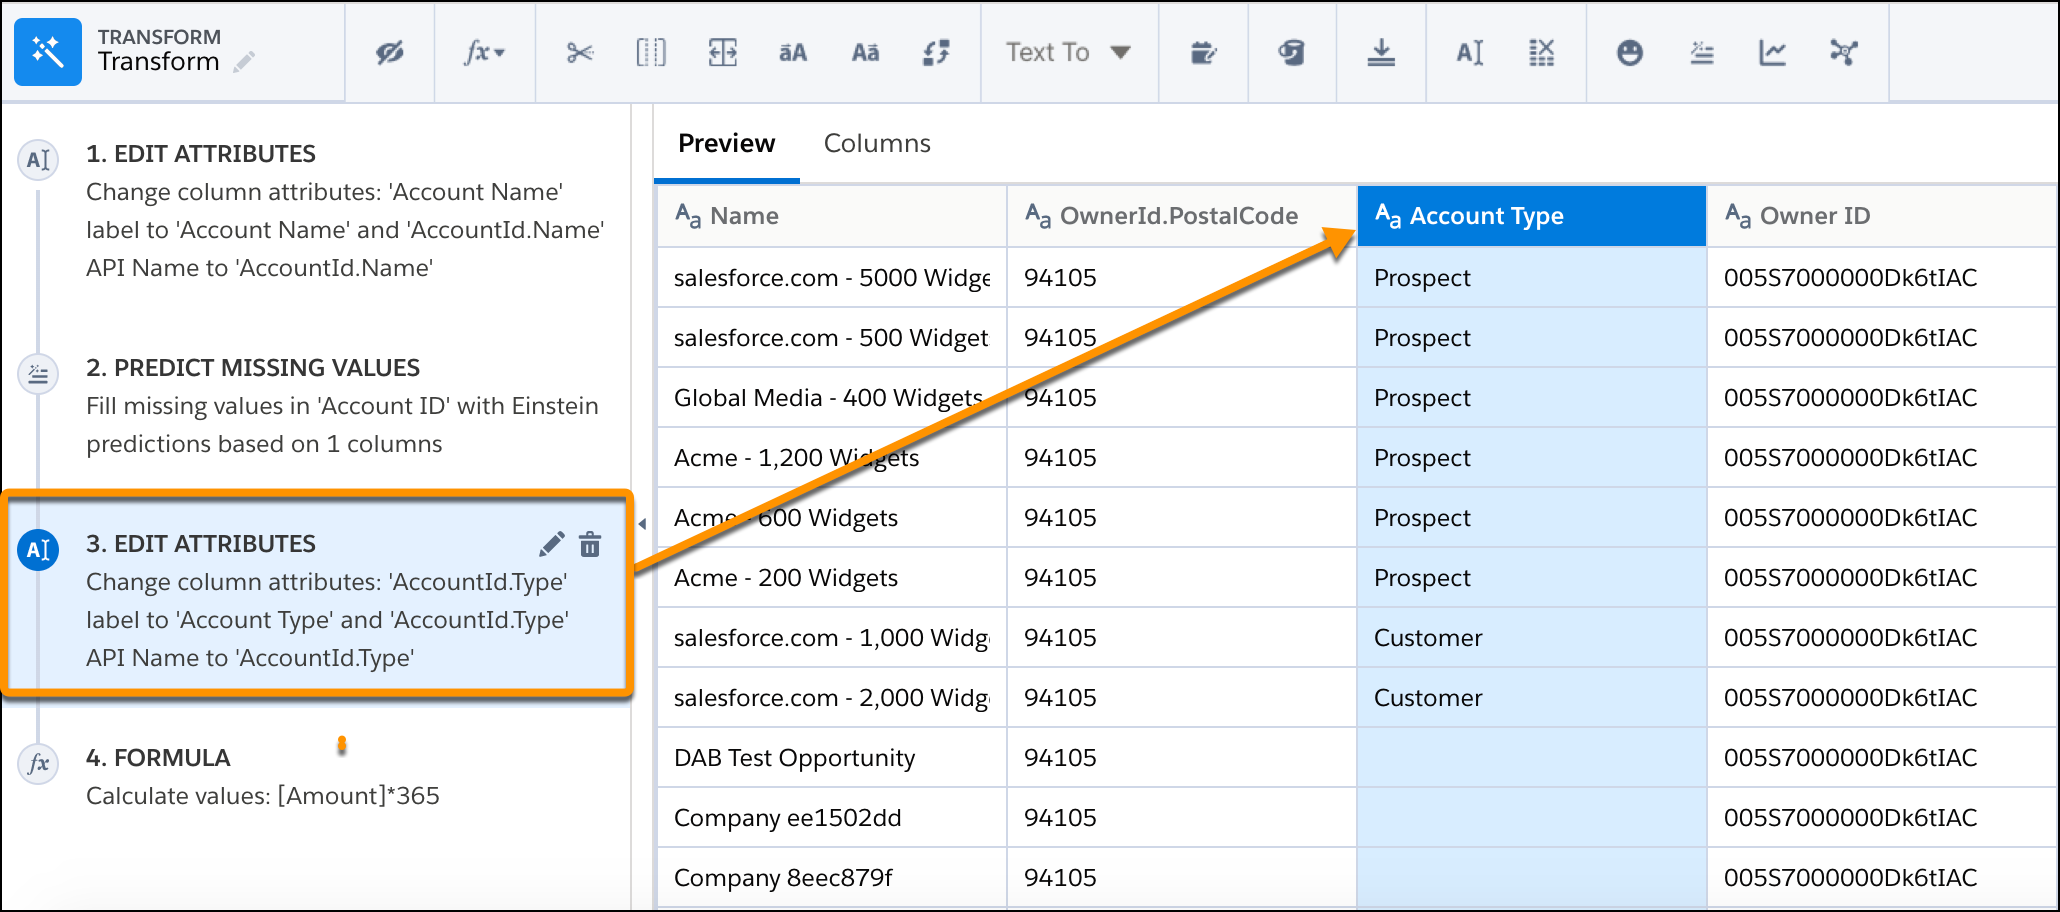
6. To view the canvas, click the **Collapse** button ().
7. If needed, select a node in the canvas to preview the results of the node. It’s always a great idea to preview results to ensure that each node and transformation returns expected results.
8. If needed, add more transformations to the Transform node.
9. Save the batch data transform.
# Transformations for Batch Data Transforms
Use transformations to perform calculations on and manipulate your data. For example, you can use a transformation to create a calculated field based on a formula. You add transformations inside a Transform node. You can string together multiple transformations to manipulate data sequentially.
- **[Bucket Transformations: Categorize Field Values](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_bucket.htm&release=264.0.0&type=5)**
Bucket your number, text, and boolean fields to group and organize data.
- **[Data Type Conversion Transformations: Convert Column Types](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_convert_column_types.htm&release=264.0.0&type=5)**
The data type of a column determines how you can query that column’s data. For example, you can filter and group by a text or date column, or perform math calculations on a number column. Sometimes, fields are tagged incorrectly. If needed, use the column-type conversion transformations to convert columns to the correct types.
- **[Date and Time Transformations: Calculate on Date Fields](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_date_and_time.htm&release=264.0.0&type=5)**
Date fields are key to understanding trends over time or keeping teams aware of upcoming milestones and deadlines. To calculate based on dates or make them more helpful to your analysis, use date and time transformations. Insert a column with the current date and time in a specified format with the Now option. Calculate the duration between two selected date columns as days, months, or years using Date Difference. And add or subtract days or months from a date column with the Add or Subtract Days or Months function.
- **[Drop Columns Transformation](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_drop_fields.htm&release=264.0.0&type=5)**
Drop unwanted columns from a batch data transform. For example, you can add a Drop Columns transformation after a Formula transformation to drop input columns used for a calculated column.
- **[Extract Transformation: Get a Date Component](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_dateextract.htm&release=264.0.0&type=5)**
Use the Extract transformation to pull a selected component from a date field into a new field. For example, extract the hour component from the Case Created Date field to analyze case creation by hour of the day.
- **[Edit Attributes Transformation: Change the Column Names and Value Formats](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_edit_attributes.htm&release=264.0.0&type=5)**
Use the Edit Attributes transformation to make column names more descriptive and apply consistent formats to column values. You can set the labels and API names of all columns. You can also set the precision and scale for numeric columns, character length for text columns, and date formats for date columns.
- **[Flatten JSON Data](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_flatten_json.htm&release=264.0.0&type=5)**
Turn data ingested as a JSON string into tabular data in a batch transform. To use data in downstream features, such as identity resolution and segmentation, the data must be stored as rows and columns in a data lake object or data model object. You can flatten JSON data that’s stored as a single object, an array of objects, or an array of literals (scalar values).
- **[Flatten Hierarchical Data](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_flatten.htm&release=264.0.0&type=5)**
Use the flatten transformation to simplify nested, hierarchical data by converting it to a list. The list tracks where each node and the ones preceding it (referred to as its ancestors) appear within the hierarchy. To flatten data, specify the field that contains every node in the hierarchy and the field that contains their corresponding parent. After you run the transform, each record contains the list of ancestors.
- **[Format Dates Transformation: Standardize the Date Format in a Column](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_format_dates.htm&release=264.0.0&type=5)**
Standardize the format for all dates in a text column with the Format Dates transformation. With a consistent format, you can correctly filter and group records by date, including filtering by date component, such as month. A consistent format also ensures that you can successfully convert the column type from Text to Date.
- **[Formula Transformation: Create a Calculated Column Based on an Expression](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_formula.htm&release=264.0.0&type=5)**
Create a column that displays values based on a formula calculation. The calculation can include input from other columns in the same row or across rows. For example, you can create a Profit column based on input from Revenue and Cost columns. Enter formulas in SQL. SQL in Data 360 is a collection of standard and custom functions for numeric, string, and date data.
- **[Split Transformation: Break Up Column Values](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_split.htm&release=264.0.0&type=5)**
Split a string in a text column into two values by specifying a delimiter. To split column values into more than two parts, add multiple instances of the split transformation. For instance, you can use three split transformations to split an address into street address, city, state, and ZIP code.
# Troubleshoot Activation Errors
Get tips for solving common activation errors in Data 360.
Error
Troubleshooting Suggestions
Required fields don't have a value
Complete the required fields
Invalid email address
Use an email address with an @ and .
Use an email address that's fewer than 254 characters
Invalid date
Use a date as MM/DD/YYYY or DD/MM/YYYY
Invalid locale
Use a locale to define the country of the subscriber. For example: A resident of the
U.S. who speaks English would receive the en-US locale value
Invalid phone
Use a phone number as ###-###-####
Use a phone number with the correct country code number
Field not found
Determine if the field still exists in the data extension. Modify the field mapping if
the data extension schema changes
Bucket or directory not found
Confirm that the bucket name (GCS) or container name (Azure) is present and
spelled right in the target region.
Provide a valid and accessible directory path with necessary permissions.
Ensure that the request parameters in your configuration match the requirements
of the destination storage account.
Invalid field count
When you import a data extension, make sure the number of fields is correct
Invalid decimal
Use a value within the length range. For example: The length is 3 and the value is XXX
or XX.X
Connectivity issue at the SFTP server
Check that the SFTP server is online and has a stable network connection.
Verify that the server is scaled to handle new connection requests.
Confirm that your firewall or security rules aren't blocking Salesforce IP
addresses.
Retry after some time.
Connectivity issue with cloud storage service
Check that the cloud storage service (Google Cloud Storage or Azure Blob
Storage) is online and has a stable network connection.
Confirm that your cloud provider's firewall or virtual network (VNet) rules
aren't blocking Salesforce IP addresses.
Ensure the GCS or Azure activation target is enabled and connected, and the
activation definition is active.
Retry after some time.
SFTP permission or protocol issue
Check that the SFTP username and password/SSH keys are accurate and
up-to-date.
Ensure the SFTP user has the necessary permissions for the target directory on
the SFTP server.
Confirm that the SFTP server is running a compatible SSH/SFTP protocol
version.
Investigate any network interruptions or unstable connections between the
application and the SFTP server.
Authentication or permission issue
Check that the access key, shared access signature (SAS), or service account
credentials are accurate and up-to-date.
Ensure the authenticated user/principal has the necessary write/edit permissions
for the target container or bucket.
Confirm that the credentials are valid.
Investigate if specific IP restrictions on the cloud account are rejecting the
connection.
File or data format issue
Ensure that the file isn't modified, moved, or deleted while the activation is
in progress. Check the activation status via the UI or Connect API.
Verify that the file compression format (for example, .GZIP) is supported by
your configuration and the destination.
## Activation and Segment Count Differences
Due to various factors, there can be differences between your activation and segment count.
- Segmenting and activating on different objects: To avoid different counts, activate on the same object.
- Data is coming from two or more data streams: Check your data mapping from the DLO and DMO.
If the Individual ID comes from two data streams but has attributes mapped to different fields in the DMO, it can lead to duplicate records.
Segmentation does a distinct count on Individual IDs. If there are duplicate IDs, segmentation counts that ID one time. In activation, if there are multiple records of the same ID and the same values in the attributes, it's deduped.
- Multiple records from activating on Unified data model object (DMO): Activate on a non-Unified DMO or don’t select an attribute with an N:1 relationship.
If you’re activating on a Unified DMO and selecting direct attributes, check the relationship between the Activate on object and the activated DMOs. If any DMOs have an N:1 relationship, there may be multiple records.
#### See Also
- [_Salesforce Help_: Review Publish History of Your Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_activations_publish_history.htm&release=264.0.0&type=5 "Activation record home in Data 360 shows activation outcomes in one place. The activation record home includes activation details, linked activation-triggered flows, and activation history. From this page, you can validate configuration, open related flows, and monitor publish results.")
# Troubleshoot Data 360 Governance Mergeback Deployments
When you migrate your data governance metadata, you can sometimes encounter deployment errors. Review the symptoms and solutions for common mergeback issues so that you can successfully complete your deployment across environments.
| Issue | Recommended Fix |
| --- | --- |
| Deployment fails because a record-level security (RLS) policy with joins references a data model object (DMO) or data lake object (DLO) that doesn't exist in the target environment. | Deploy the referenced object first, or include it in the same or an earlier DevOps data kit deployment. |
| Deployment fails because a custom tag assignment is included in the deployment. | Remove the custom tag assignment from the source org, or redesign the policy to use standard tags only. |
| Deployment succeeds, but a policy doesn't appear in the target environment. | Verify that the policy was associated with an object included in the DevOps data kit. Policies aren't deployed independently. |
| Permission error during deployment. | Verify that the deploying user has the Data Cloud Architect permission set in the target environment. |
# Troubleshoot Data Action Errors
Get tips for solving the most common data action and data action target errors.
Error
Troubleshooting Suggestions
Events aren’t coming through the webhook data action target.
Confirm that the webhook data action target has a secret key.
If there’s no secret key, generate one for signature validation.
Events aren’t being generated in the Marketing Cloud Engagement data action
target.
Check whether the data extension attribute name in Journey Builder uses the correct
naming format. The name must start with the object API name of the data model object
selected in Data Cloud, followed by an underscore and the attribute API name. For example,
Shopping_Events__dlm_deviceId__c.
Make sure that the required field is present in the event payload.
Check if the subscriber key value that you selected when creating the data action isn’t
null during event payload ingestion.
The datatypes of the fields configured in Engagement and Data Cloud must match.
The length of the attribute can’t exceed the value that you’ve defined in the data
extension in Journey Builder.
#### See Also
- [_Salesforce Help_: Create a Webhook Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_data_action_target_of_webhook_type.htm&release=264.0.0&type=5 "Send a data action event to a webhook target and protect the message integrity with a Salesforce-generated secret key. A webhook is a type of API that’s event driven rather than request driven. The secret key validates the payload requests sent from Salesforce. The webhook transports the HTTP payload with events in the format of DataObjectDataChgEvent.")
- [_Salesforce Help_: Create a Marketing Cloud Data Action Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_marketing_cloud_data_action_target.htm&release=264.0.0&type=5 "Send automated emails and journeys to customers based on behavioral or transactional event data routed from Data 360. Trigger emails and journeys to customers from data model objects (DMOs) and calculated insights. For example, a customer purchases an item and searches for “installation manual” on your website. You trigger an event that sends the customer an email with a how-to video or installation instructions.")
# Troubleshoot Data Share Errors
Get tips for solving the most common data share and data share target errors.
Error
Troubleshooting Suggestions
Authentication error when setting up a Snowflake data share target.
Confirm that Data Cloud IP addresses are included in the Snowflake list of allowed IP
addresses. Learn how to add an IP
networking policy to Snowflake .
Confirm that your local machine’s IP address is added to the Snowflake list of allowed
IP addresses. To add your IP address to this list, contact your Snowflake account
admin.
Internal server error while data sharing. The Salesforce support team is notified of
the problem. Contact Salesforce Support, and provide contextual information, such as the URL
of the page requested and the error ID shown on the page.
In your browser, switch to Incognito mode and try again.
- **[Add an IP Networking Policy](https://help.salesforce.com/s/articleView?id=data.c360_a_add_ip_networking_policy.htm&release=264.0.0&type=5)**
If you encounter an authentication error when setting up a Snowflake data share target, make sure to include Data Cloud IP addresses in Snowflake. Create an IP networking policy in Snowflake that lists the allowed Data Cloud IP addresses.
# Troubleshoot Data Stream Errors
Data streams can encounter various issues when importing data into Data 360. Use this troubleshooting section to identify and resolve common data streaming errors.
## Common Zero Copy Data Stream Errors
ERROR: `Time out in polling job.Try increasing the timeout value`.
ERROR: `EXEC_JOB_EXEC_ERR`
Time out errors and job execution errors occur when you exceed optimal data volume in zero copy connectors. To fix time out errors, make sure your data volume is within:
- 234 GB or 1 billion rows for Amazon Redshift
- 20GB or 750 million rows for Snowflake
- 23 GB or 500 million rows for Databricks
- 10 GB or 100 million rows for Google BigQuery
## Common CRM Data Stream Errors
ERROR: `Invalid extractor job query found."errorCode":"INVALID_TYPE"`
ERROR: `Invalid extractor job query found."errorCode":"INVALID_FIELD"`
An `INVALID_TYPE` error indicates an issue accessing the CRM object. An `INVALID_FIELD` error indicates the deletion of a field on the object or a loss of access to a field due to permission changes. To troubleshoot such errors,
- Confirm that the objects and fields are not deleted.
- Confirm that the[Salesforce CRM Permissions](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&type=5&language=en_US) still has Read, View All Records, and View All Fields permissions for the object listed in the exception.
ERROR: `OPERATION_TOO_LARGE`
An `OPERATION_TOO_LARGE` error indicates that one of the fields is referencing an entity that the CRM connector lacks access to. When an entity is related to another entity, Data 360 checks if the related record also has granted permissions before returning a row. This additional query can overload the operation, as the original query expands for each related entity. To resolve this, verify that Read and View All access is granted to all the related objects.
## Common SFTP Data Stream Errors
ERROR: `STREAM_JOB_STATUS_FAILURE`
A `STREAM_JOB_STATUS_FAILURE` error can be due to the file size being too large. For Secure File Transfer Protocol (SFTP), the total limit in a run is 4.5 GB and each individual file is 500 MB. To fix file size issues, make sure the file sizes on the SFTP are within the limits as outlined in the [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&type=5&language=en_US).
ERROR: `STREAM_JOB_STATUS_CANCELLED`
A `STREAM_JOB_STATUS_CANCELLED` error occurs when two consecutive jobs are run for the same data stream. Make sure you are running one job only at any given time in a data stream.
ERROR: `STREAM_JOB_STATUS_FAILURE` - Log shows "Data read has a different length than expected"
This error is because SFTP connectors does not support multiple files in a zip file. To fix this, merge all the files together or ingest the unzipped folder using a wildcard.
ERROR: `Unknown Error`
An `Unknown Error` usually occurs when the file you are trying to use is corrupted. Try again with with another file.
ERROR: `Job Aborted Due to Stage Failure`
A `Job Aborted Due to Stage Failure` error occurs when the source file is missing.
ERROR: `Unable to position the current position from -1 to 0`
This error occurs due to concurrent connection limits on your SFTP server. If multiple data streams are scheduled simultaneously, they can all attempt to connect at the same time, causing a failure. To resolve this:
- Check the concurrent connection limit on the SFTP server.
- Make sure the number of data streams using the same connection does not exceed the concurrent connection limit. Stagger the scheduling of data streams by approximately 30 minutes to prevent conflicts.
# Troubleshoot External User Access Errors
Resolve common issues with authenticated external user and unidentified external user access to Data 360.
Issue
Resolution
An authenticated external user sees 0 accessible records.
In the Data Governance tab, confirm that the data model object (DMO) has the
correct access level tag (ExternalData.Visibility.Portal or a
custom tag).
If no tag exists, add one and save.
Wait a few minutes and retest access.
Verify that an Allow policy exists for authenticated external users.
Verify that the policy restricts access based on the custom permission assigned to
the authenticated external user profile.
An unidentified external user accesses data without a policy.
Confirm that the DMO doesn't have the
ExternalData.Visibility.Public tag.
Remove any ExternalData.Visibility.Public tags from internal
objects.
An agent action fails for an authenticated external user.
Verify that the Agent Service Account uses external org-wide default access (not
internal).
Check that the DMO has the correct authenticated external user tag
(ExternalData.Visibility.Portal or custom).
Confirm that an Allow policy exists for authenticated external users with the
custom permission assigned to the authenticated external user profile.
If the AI agent is configured as Digital Agent External User in Summer '26 or
later releases, verify that the DMO has the
ExternalData.Visibility.Public tag. Also verify that an
Unidentified External User policy exists.
An agent action succeeds in the sandbox but fails in production.
Confirm the Agent Service Account org-wide default setting matches across
environments.
Verify that tags exist on the same DMOs in both environments.
Check that Allow policies exist with identical custom permission restrictions in
both environments.
Policies work in the home org but not in the companion org.
Confirm multi-org policies are enabled in the home org and synced to the companion
org.
Verify that the companion org admin has mapped attribute placeholders to local
values.
Check that custom permissions referenced in policies exist in the companion
org.
Contact Salesforce Support to verify the companion org policy sync status.
# Troubleshoot Identity Resolution Results with Calculated Insights
Build calculated insights to investigate the quality of your unified profile data and profile consolidation rates.
- **[Data Quality Calculated Insight: Summary by Source](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ci_summary_by_source.htm&release=264.0.0&type=5)**
Review the number of unique contact points per data source. The number of unique contact points is the number of source records consolidated in identity resolution. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.
- **[Data Quality Calculated Insight: Contact Points Per Individual](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ci_contact_points_for_individuals.htm&release=264.0.0&type=5)**
Review the number of contact points for each source record to find outliers. Outliers can help you identify issues with your source data or data mappings. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.
- **[Data Quality Calculated Insights: Contributing Contact Points](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ci_contact_points_overgrouping.htm&release=264.0.0&type=5)**
Review occurrences of repeat values for Contact Point Address, Contact Point Email, Contact Point Phone, and Party Identification objects. Use this calculated insight after data ingestion, but before creating an identity resolution ruleset.
- **[Identity Resolution Calculated Insight: Consolidation Rates for Unified Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ci_consolidation_rate.htm&release=264.0.0&type=5)**
Review the consolidation rate of matched profiles for each data source. Data sources with duplicate profiles are expected to have higher consolidation rates than data sources with many unique profiles. Use this calculated insight after creating unified profiles with an identity resolution ruleset.
- **[Identity Resolution Calculated Insight: Outlier Unified Profiles](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_troubleshooting_ci_outlier_unified_profiles.htm&release=264.0.0&type=5)**
Review the number of matched contact points for each unified profile. A high number of matches per contact point, like profiles with hundreds of source records matched with the same email address, could indicate issues with data quality or source data. Use this calculated insight after creating unified profiles with an identity resolution ruleset.
#### See Also
- [_Salesforce Help_: Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_data_explorer.htm&release=264.0.0&type=5 "With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.")
- [_Salesforce Help_: Profile Explorer in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer.htm&release=264.0.0&type=5 "Get a complete view of a unified profile for an account or individual for purposes such as validating unified profile data and checking for discrepancies. Customers can deploy a set of Lightning apps to customize and expand the experience.")
- [_Salesforce Help_: Data Mapping](https://help.salesforce.com/s/articleView?id=data.c360_a_data_mapping.htm&release=264.0.0&type=5 "Data ingested by all data streams is written to data lake objects (DLOs). After creating your data streams, you must associate your DLOs to data model objects (DMOs). Only mapped fields and objects with relationships can be used for Segmentation and Activation.")
# Troubleshoot Identity Resolution Ruleset Processing Errors
Understand what ruleset processing errors mean and how to resolve them.
Error
Tips for Resolving It
Some contact point records were skipped because they contained the same ID, data source
ID, data source object ID, and key qualifier.
During the match and merge process, identity resolution expects every contact point
record to have a unique combination of record ID, data source ID, data source object ID, and
key qualifier. When the process runs into records with the same combination of these four
fields, it only considers the first contact point record it finds during matching. Other
contact point records with matching attributes are skipped. The record used for matching is
selected arbitrarily, which can impact matching.
To resolve this error, groom your data at
the data source or using data transforms to eliminate or repair poor quality
data.
Some match or reconciliation rules include external data lake objects that aren't
accessible.
The external data lake object wasn't accessible when the ruleset tried to run.
If
the external data lake object isn't accessible because of an authentication error or other
problem, try fixing it. Otherwise, edit the ruleset's match rules and reconciliation rules
to remove references to the external data lake object.
Some contact point records aren’t linked to a primary data model object.
A contact point record exists without a corresponding record in the primary data model
object. Identity resolution can't use orphaned contact point records in matching and
reconciliation, so the record was dropped during matching. The orphaned contact point record
isn't included in any unified profiles created from the ruleset.
Some records were skipped because the record size was greater than 15 KB.
An input record is defined as a combination of a primary data model object record and
all the corresponding contact point data model object records. The maximum allowable size of
an input record is 15 KB. Any input records exceeding this size aren't considered for
unification during matching.
Some records were altered during matching because the combined length of values being
matched was greater than 500 characters.
During matching, the combined character limit of all values in all fields included in a
match rule can't be greater than 500 characters. During the matching process, if the combined
vales of fields being matched exceeds 500 characters, some values or parts of values are
truncated. Mismatches can result because matching is based on truncated values.
For
example, supposed a match rule uses the Exact Phone, Exact First Name, and Normalized Email
Address fields, the combination length of the record's phone number, first name, and email
address can't be greater than 500 characters.
Long values are commonly caused by
formatting errors in source data. If you imported data from a CSV file, long streams can be
created when incorrect formatting makes several records run together.
Some source profiles weren’t unified because they matched 50,000 or more other
profiles. To reduce the number of matching records, clean your data or refine your match
rules.
Identity resolution can't combine more than 50,000 records into a single unified
profile. Any clusters with more than 50,000 records are split into multiple unified profile
records. To determine why large profiles are being created, consider these things:
Are any match rule criteria allowing matches on blank fields? If so, consider changing
your match rule criteria to disallow matching on blank values. Or, groom your data at the
data source or using data transforms to eliminate or repair poor quality data.
Are default values being entered into fields in your data source? For example, if a
phone number is missing, are users or processes entering a placeholder value such as
000-0000 ?
Are your match rules too broad? Match rules can be narrowed by adding more criteria or
using more strict match methods.
One or more source data lake objects is in an error state.
Check the status of data lake objects that are mapped to the data model objects used by
the identity resolution ruleset. Repair your data model objects or reconfigure your
ruleset.
Some contact points were skipped during matching because they didn’t contain a value.
If the string "null" is present in any of the following contact point record fields,
the contact point is skipped during matching.
The ssot__EmailAddress__c field on the ssot__ContactPointEmail__dlm object
The ssot__FormattedE164PhoneNumber__c on the ssot__ContactPointPhone__dlm object
The ssot__AddressLine1__c, ssot__CityId__c and ssot__CountryId__c fields on the
ssot__ContactPointAddress__dlm object
The ssot__AdvertiserId__c field on the ssot__Device__dlm object
The ssot__IdentificationNumber__c field on the ssot__PartyIdentification__dlm
object
The ssot__Id__c field on the ssot__ContactPointApp__dlm object
The ssot__SocialHandleId__c field on the ssot__ContactPointSocial__dlm object
If the string "null" is entered into a custom field that's used by match or
reconciliation rules, or if "null" is entered into any field in the ruleset's primary data
model object, it's converted to an empty string.
To avoid triggering this error, groom
your data at the data source or using data transforms to eliminate or repair poor quality
data.
# Troubleshoot Notebook AI Errors
Diagnose and fix the most common issues when setting up Notebook AI.
Error
Troubleshooting Suggestions
Notebook AI enablement fails with the log error "Unable to create a
data-stream. Insufficient Permissions "
Ensure that the Data Cloud Salesforce Connector permission set includes
these permissions.
Customize Application
Manage Custom Permissions
Modify Metadata Through Metadata API Functions
View All Data
View All Fields (Global)
Ensure that the Platform Integration User is assigned the Data Cloud Salesforce
Connector permission set.
Notebook AI tab is not visible in the Salesforce org.
In Setup , navigate to the user's profile and object
settings, and enable Notebook AI.
Custom data spaces don't show up in the Notebook AI admin screen
In Setup , go to Permission Sets
and select Data Cloud Architect permission set.
Choose Data Cloud Data Space Management.
Add the custom data space you where want to enable Notebook AI.
Datakit deployment fails with SFDC_PERMISSION_ERROR
In Setup , go to Permission Sets
and select Data Cloud Salesforce Connector permission set.
Select Object Settings, and choose Data Knowledge Space Definitions.
Edit Object Permissions and enable Read, Create, View All Records, View All
Fields and save the updates.
# Troubleshoot Salesforce Catalog Errors
Diagnose and fix the most common issues when setting up Salesforce Catalog.
Salesforce Catalog automatically creates and manages a set of underlying objects to build and maintain your data catalog—including connectors, data streams, data lake objects, data model objects, and their field mappings. To maintain the integrity of your catalog, don't directly modify these system-managed objects.
Error
Troubleshooting Suggestions
Failure during metadata ingestion and processing.
Wait for Data 360 to automatically refresh.
Contact Salesforce Customer Support for a reset if the failure persists.
Catalog refresh error.
Wait for Data 360 to run an automatic refresh. In the case of
a refresh failure, Data 360 retries an automatic refresh.
Contact Salesforce Customer Support for a reset if the failure persists.
Metadata Grounding Model Context Protocol (MCP) queries don't return any
results.
After you enable Salesforce Catalog, Data 360 runs a full
metadata extraction and ingestion. After which a search index is built. This
process can take time to complete depending on the size of the data.
Contact Salesforce Customer Support for a reset if the failure persists.
# Troubleshoot Segment Errors
Get tips for solving the most common segment errors in Data 360.
Error
Troubleshooting Suggestions
Segment references too many data lake objects (DLOs).
Use a Calculated Insight (CI) to reduce the number of DLOs referenced by your
segment.
Split a segment into multiple smaller segments.
Segment is too complex.
Use a CI instead of many attributes and nested operators.
Use a CI instead of an attribute (data model object) with many relationships.
Combine text values into one Is In text operator.
Segment returns skewed data.
Remove placeholder values like 0 or
Unknown from source data before ingesting data into Data 360 .
Segment is inactive.
Copy the inactive segment to create a segment with the same population.
Too many segments are trying to publish at the same time.
Wait for some segments to finish publishing and try again.
Change the publish schedule for some of your segments.
Segment population recount in progress.
Wait for the recount to finish and try publishing the segment again.
Segment wasn’t processed.
Contact Salesforce Customer Support for help.
Multiple population counts are in progress.
Wait for the counts to complete and try again.
Improve the segment by making it simpler, using nested segments, or merging the
containers, if possible.
Segment population count failed.
Identify containers with the same join paths and merge them using nested operators, if
possible.
Avoid long paths and use the shortest join path to reach the needed attribute.
Avoid cyclic paths in segments. Cyclic paths are relationships that use cyclic behavior
(a→b→a). While segment counts can fail, segment jobs can run successfully.
Segment can’t be published.
Simplify your segment by merging containers when possible. Use nested operators to merge
the containers.
Ensure the DMO types are correct, especially for Engagement Type data. Incorrect DMO
types can cause timeouts and failures.
Segment count/population mismatch.
Segmentation applies a filter on the engagement date (24 months for standard segments
and 7 days for rapid segments). In Data Explorer, make sure to apply the filter on the
engagement event date.
Ensure date operators match with tenant timezones.
Check if the source data has drastically changed (significant additions, updates, or
deletions).
If you use Calculated Insights in your segments and notice an unexpected increase or
decrease in segment count or segment population, check if any Identity Resolution rules
were processed between the CI and segment run.
Segmentation in Data 360 generates a list of unique profile IDs as output. But
Marketing Cloud uses the Subscriber Key attribute for segmentation; hence, the
population counts in Data 360 and Marketing Cloud can differ.
Unable to edit segment, or segment editor UI times out.
Remove unnecessary relationships defined at Segment On at the DMO level. If the issue
persists, contact Salesforce Customer Support for help.
#### See Also
- [_Salesforce Help_: Calculated Insights in Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_in_segments.htm&release=264.0.0&type=5 "Use a calculated insight to control data-driven insights in segmentation. You can also describe the calculated insight’s metrics and dimensions in a segmentation filter.")
- [_Salesforce Help_: Data Objects in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lake_objects.htm&release=264.0.0&type=5 "When working with Data 360, it’s helpful to know about Data 360 data objects including data lake objects (DLO) and data model objects (DMO).")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Publish a Segment in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_segment.htm&release=264.0.0&type=5 "After defining your segment in Data 360, you can publish it to your activation targets whenever you want or based on a schedule when the segment was created. The standard publish schedule is 12 or 24 hours. You can also change the segment schedule by editing its properties. When you’ve reached the segment publish concurrency limit, Data 360 defers the publish of other segments. This deferral continues until the number of simultaneously running segments falls below the limit. This means that a segment scheduled at a specific time sometimes doesn’t start publishing at its scheduled time.")
# Troubleshoot Simple Start Errors
Get tips for solving the most common Simple Start errors.
| Error | Troubleshooting Suggestions |
| --- | --- |
| Data doesn’t appear in your data lake objects (DLOs) for Simple Start enabled orgs. | To prevent credit consumption, Simple Start creates data streams in an inactive state. You must manually activate the data streams to begin data ingestion. |
| An error occurs during the metadata sync process. | Confirm that your home org connection remains active. Verify that you have the required permissions in the source Salesforce CRM org to access the Metadata API, including the global "View All" access for objects and fields. |
# Troubleshooting CRM Connections
If you have trouble with creating, refreshing, or disconnecting a Salesforce CRM data stream, see these common issues.
## Refresh History Object Permission Errors
The data stream **Refresh History** tab summarizes each data stream’s last 50 refresh operations including errors that occurred. Use this tab to troubleshoot errors.
A refresh can fail for these reasons:
- If you don’t enable object and field permissions during Data 360 setup, a data stream refresh can fail. Enable object and field permissions to access Salesforce CRM.
- If you delete a custom field and then add it back, a scheduled or manual data stream refresh can fail to update records or status. When you add back a field, re-enable Read access for the field.
- If you exceed the DLO to DMO mapping limit, a data stream refresh can fail to complete. Review the DMO relationship limits.
- When an incremental update or full refresh is running, adding a formula field to trigger a full refresh cancels the initial update. The update then appears as failed.
- When the following error message appears, it indicates improper permission settings.
`The following fields are missing in the CRM object or you do not have permissions to read from these fields.`
See [Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&release=264.0.0&type=5 "You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.").
## Streaming Errors
For a data stream to use streaming mode, grant the required permissions and satisfy all validation requirements
A data stream uses batch mode instead of streaming mode in these situations:
- The object, object type, or derived field don't support streaming. See [Object Support for CRM Data Streams](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_unsupported_objects_types.htm&release=264.0.0&type=5 "When you create a Salesforce CRM data stream, the CRM connector doesn’t support the ingestion of all objects or object types from the connected CRM orgs. Use only supported objects and object types for your data stream.").
- You include batch ingested standard or custom fields in your data stream.
- You participate in the Filtering for Salesforce CRM Connector pilot and have defined a filter on a stream.
- You modified the Data Cloud Salesforce Connector permission set by adding users. When you connect to an org, the Data Cloud Salesforce Connector permission set is created and allows access to Data 360 objects and fields. This permission set is intended for the [Platform Integration User](https://help.salesforce.com/articleView?id=security_platform_integration_user.htm&language=en_US). Adding other users to this permission set prevents Data 360 from assigning the necessary permissions that are needed for streaming.
- You include custom entities in your data stream where the deployment status is **In Development** instead of **Deployed**. We recommend creating data streams only after their deployment status is **Deployed**. If you include in your data stream an entity whose status is **In Development**, the data stream automatically switches to streaming mode, but it doesn’t receive updates. To enable data ingestion, change the entity status to **Deployed** in the object manager. Note that because records that were updated while the entity was **In Development** may not sync properly, the data can be inaccurate. To avoid this inaccuracy, delete the data stream and then recreate it.
See [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.") and [Create a Salesforce CRM Data Stream](https://help.salesforce.com/s/articleView?id=data.c360_a_create_crm_data_stream.htm&release=264.0.0&type=5 "Create a data stream to begin the flow of data from a Salesforce CRM data source to Data 360 for processing and unification.")
## SurveyQuestionResponse Object Ingestion Failed
Access to the `SurveyQuestionResponse` object is controlled by the `SurveyResponse` object. To ensure data ingestion for the Survey object, grant View All Records or Modify All Records permissions for the `SurveyResponse` object.
See [Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&release=264.0.0&type=5 "You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.").
## Related Object Ingestion Failures
Grant permissions on objects and related objects even if you don’t ingest the related objects into Data 360. Ingested objects that reference related objects need permissions to access the related object information and create a data stream.
See [Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&release=264.0.0&type=5 "You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.").
## Error OPERATION\_TOO\_LARGE
When the following error message appears, it indicates that one of the fields references an entity that the CRM connector can't access. To resolve this, verify that Read and View All access is granted to all the related objects.
`"[{"message":"exceeded 100000 distinct ids","errorCode":"OPERATION_TOO_LARGE"}]"`
When an entity has more than 100,000 records with granted permissions, all records can be retrieved without issue. However, if the entity is related to another entity, the system checks if the related record also has granted permissions before returning a row. This additional query can overload the operation, as the original query expands for each related entity. To maintain performance, a hard limit is set.
For Data 360 data streams, this query always runs as the Platform Integration User. Logging in as any other user in the system can present you with a non-failing result, the problem is still permission related however and needs to be addressed in the Data Cloud Salesforce Connector permission set to proceed.
See [Enable Object and Field Permissions for CRM Connections](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_enable_object_and_field_permissions.htm&release=264.0.0&type=5 "You can edit the Data Cloud Salesforce Connector permission set to allow ingestions of objects and fields into Data 360.")
## Data Stream Fails on Extraction
Extraction must succeed before ingestion begins. The data stream history panel shows when there are extraction and ingestion errors, or when there’s a successful ingestion.
See [Data Refresh Process for Extraction](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5 "Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge_kav objects.").
## Data Stream Deployment Fails with a “Data Lake Object ID Cannot Be Empty” Error
When you deploy an unsupported Data 360 setup object by using [file-based metadata deployment](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/file_based.htm), the deployment leaves incomplete or orphaned records, and fails with the “Data Lake Object ID cannot be empty” error. To avoid this error, don’t include these unsupported setup objects in package.xml, destructiveChanges.xml, or change sets.
- [DataStreamDefinition](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/meta_datastreamdefinition.htm)
- [DataSourceObject](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/meta_datasourceobject.htm) or DataSourceObject fields
- MktDataLakeObject ([Data Lake Object](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion_and_modeling.htm&language=en_US))
- [ObjectSourceTargetMap](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/meta_objectsourcetargetmap.htm)
- [MktDataTranObject](https://developer.salesforce.com/docs/atlas.en-us.api_meta.meta/api_meta/meta_mktdatatranobject.htm)
## Salesforce CRM to Data 360 Data Mismatches
When integrating Salesforce CRM with Data 360, data mismatches can occur if access permissions aren't set correctly.
See [Addressing Salesforce CRM to Data 360 Data Mismatches](https://help.salesforce.com/s/articleView?id=002467417&type=1&language=en_US).
If the record count in your Salesforce CRM source doesn't match the count in your Data 360 data stream, or recently modified records aren't reflected in Data 360, this can be because you configured a periodic full refresh interval for a streaming mode data stream. In streaming mode, you can't configure the periodic full refresh interval. To sync your data, you can set a full refresh on demand by clicking the **Refresh Now** button for that stream on the **Data Streams** tab.
See [Configure Periodic Full Refresh Interval](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5 "Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge_kav objects.") and [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.")
## Salesforce CRM Connection Doesn't Disconnect
If you can’t remove a Salesforce CRM connection, check for system data streams. You can't edit or delete Salesforce system data streams that other applications use, such as these Digital Wallet system data streams: PF (ProvisionedFeature), TET (TenantEntitlementTransaction), or TUTM (TenantUsageTypeMultiplier). You also can't remove a connection that includes them. To remove the connection, contact Salesforce Customer Support.
See [Disconnect a Salesforce CRM Connection](https://help.salesforce.com/s/articleView?id=data.c360_a_disconnect_a_salesforce_crm_connection.htm&release=264.0.0&type=5 "When you no longer need a connection, you can delete it. After you remove a standard Salesforce CRM connection, Data 360 stops ingesting data from the connected org and deletes all the data it ingested from that org, except trust files. Data ingested from the org is removed from unified profiles the next time that identity resolution runs.").
If the record count in your Salesforce CRM source doesn't match the count in your Data 360 data stream, or recently modified records aren't reflected in Data 360, this can be because you configured a periodic full refresh interval for a streaming mode data stream. In streaming mode, you can't configure the periodic full refresh interval. To sync your data, you can set a full refresh on demand by clicking the **Refresh Now** button for that stream on the **Data Streams** tab.
See [Configure Periodic Full Refresh Interval](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_data_refresh_process_for_extraction.htm&release=264.0.0&type=5 "Data refreshes have two phases: full refresh, which replaces all destination data, and incremental refresh, which updates data between full refresh runs. You can perform both full and incremental refresh on demand. Learn about the different refresh scenarios, and the special behavior of ContentVersion and Knowledge_kav objects.") and [CRM Connector Streaming](https://help.salesforce.com/s/articleView?id=data.c360_a_crm_connector_streaming.htm&release=264.0.0&type=5 "Batch and stream processing handle data differently. Batch mode checks the data once at scheduled intervals of 10-15 minutes, and then processes and stores it in a Data Lake Object (DLO) that you can access. Streaming mode processes data with minimal latency, and reflects changes as soon as they're made in the org.")
## General Considerations
Keep these considerations in mind when creating a Salesforce CRM data stream.
- The Salesforce CRM Connector doesn’t support ingestion of Big Objects from Salesforce CRM.
- The Salesforce CRM connector streaming process doesn't support data encryption with Bring Your Own Key (BYOK).
- Salesforce archives Tasks and Events that are over a year old. When ingesting data, these archived records aren’t included.
- Salesforce CRM data streams can fail due to missing field and object permissions. To download errors, go to the **Refresh History** tab of a data stream, click the error, and download the error message file.
- The number of fields and values can have an impact on refresh time and can result in timeouts.
- Enable Read permissions on related objects even if you don’t ingest the related objects into Data 360. Ingested objects that reference related objects need permissions to access the related object information and create a data stream.
- To delete a field from your connected CRM, first disable that field from Data 360 to avoid ingestion errors in data streams. See [Considerations for Data Stream Field Disablement](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_field_deletion_settings.htm&release=264.0.0&type=5 "There are few restrictions to consider when planning to disable a data stream field.").
- You can delete the DMO only if it’s a custom object. See [Manage Data 360 Objects and Field Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_delete_data_model_object.htm&release=264.0.0&type=5 "Edit or remove objects and field mappings associated with a data model object (DMO) or data lake object (DLO). Manage mappings and objects to ensure data accuracy and maintain the integrity of your data model.")
#### See Also
- [_Salesforce Help_: Enable Object and Field Permissions to Access Salesforce CRM in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_user_permissions_external_salesforce_org.htm&release=264.0.0&type=5 "When you connect to an org, the Data Cloud Salesforce Connector permission set is created to allow access to Data 360 objects and fields. You can edit the Data Cloud Salesforce Connector permission set to meet your organization’s needs.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- [_Salesforce Help_: Data Stream Schedule in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_stream_schedule.htm&release=264.0.0&type=5 "Data streams can operate on different refresh schedules. Learn more about how and when these data streams update.")
# Turn On Salesforce Catalog
Make Your org's metadata available to AI agents with natural language queries by enabling Salesforce Catalog.
### Required Editions
User Permissions
Needed
To access Data Cloud Setup
Data Cloud Architect permission set
Before you begin, [Set Up and Turn On Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_setup_provision.htm&type=5&language=en_US) in your org, and review Salesforce Catalog considerations.
1. From **Data Cloud Setup**, under Feature Management, select **Feature Manager**.
2. To turn on Salesforce Catalog, next to the feature name, click **Enable**.
3. Agree to the terms and service, and confirm that you want to turn on the catalog.
After you turn on Salesforce Catalog, an initial full sync runs to completely extract and ingest your org's metadata. This process can take time depending on the size of your org. After the initial sync completes, Salesforce Catalog keeps your metadata current through incremental metadata sync for supported metadata types and daily full refresh. For more information see, [Metadata Extraction and Refresh](https://help.salesforce.com/s/articleView?id=data.c360_a_sf_metadata_ext_rfsh.htm&type=5&language=en_US).
4. Next, enable the Metadata Grounding Model Context Protocol (MCP) server in your org by following the steps in [Activate MCP Servers](https://developer.salesforce.com/docs/platform/hosted-mcp-servers/guide/activate-mcp-servers.html).
To connect to the Metadata Grounding MCP server from other AI clients such as Claude, ChatGPT, or Cursor, follow the steps in [Connecting an MCP Client](https://developer.salesforce.com/docs/platform/hosted-mcp-servers/guide/client-connection-overview.html). After you enable the MCP server, your AI client can connect to a Salesforce org and act on behalf of authorized users.
For more information on Metadata Grounding MCP server capabilities see, [Metadata Grounding MCP Server (Beta)](https://developer.salesforce.com/docs/platform/hosted-mcp-servers/guide/metadata-grounding.html).
# Understand Data Spaces in Companion Orgs
Metadata is synced only between a Data 360 home org and its connected companion org when the metadata is part of a data space that is shared with the companion org. Metadata syncing enables companion orgs to reference data in Data 360 objects in shared data spaces.
## What happens when I share a data space?
A data space with the same name is created on your companion org. Your companion org can access Data 360 metadata, objects, and records associated with the data space for use in Data 360-powered features.
## Which data spaces can I share with the companion org?
Select only the data spaces that you need to ingest data into or that contain metadata, objects, and records that you want to share with the companion org. To avoid unnecessary processing costs, don’t select data spaces that you don’t need.
## What happens if I don't share any data spaces with a companion org?
If you don't share any spaces with a companion org, the companion org's connection isn't active and doesn't sync metadata with Data 360. If you aren't sharing data spaces, the connection status shows Incomplete.
## What happens when I unshare a data space?
When you unshare a data space that was synced with a companion org, your Data 360 home org doesn't ingest metadata that was stored in that data space, the metadata is deleted from the companion org, and the data space is deleted from the companion org. If you unshare all the data spaces, the companion connection is no longer active.
# Understanding the Ad Activation Report
Here are descriptions for the fields of the report.
### Required Editions
| Field Name | Description |
| --- | --- |
| AudienceName | The name of the audience. |
| AudienceEID | The Enterprise ID associated with the audience. |
| AudienceMID | The Member ID associated with the audience. |
| AudienceCreatedBy | The ID of the user who created the audience. |
| AudienceAdAccountId | The ad account ID linked to the audience. |
| AudienceNetwork | The advertising network where the audience is used (for example, Facebook or LinkedIn). |
| AudienceSize | The total size of the audience on the advertising network. |
| AudienceMatchCount | The number of matched individuals in the audience. |
| DataExtensionName | The name of the source Data Extension used for the audience. |
| DataExtensionIsShared | Indicates whether the source Data Extension is shared. |
| MatchingOnEmail | Indicates whether the audience is matching based on Email. |
| MatchingOnPhone | Indicates whether the audience is matching based on Phone Number. |
| MatchingOnMAID | Indicates whether the audience is matching based on Mobile Ad ID. |
| MatchingOnGoogleUID | Indicates whether the audience is matching based on Google User ID. |
| MatchingOnFirst | Indicates whether the audience is matching based on First Name. |
| MatchingOnLast | Indicates whether the audience is matching based on Last Name. |
| MatchingOnStreet | Indicates whether the audience is matching based on Street Address. |
| MatchingOnCity | Indicates whether the audience is matching based on City. |
| MatchingOnState | Indicates whether the audience is matching based on State. |
| MatchingOnZip | Indicates whether the audience is matching based on Zip Code. |
| MatchingOnCountryCode | Indicates whether the audience is matching based on Country Code. |
| MatchingOnDOB | Indicates whether the audience is matching based on Date of Birth. |
| MatchingOnGender | Indicates whether the audience is matching based on Gender. |
| MatchingOnOther | Indicates whether the audience is mapped using other, non-standard identifiers. |

Note If the MatchingOnOther field is true, the audience uses one or more of these user types for matching:
- Facebook User ID
- App User ID
- Twitter ID or Handle
- Contact Key
- LinkedIn Company Name, Website, Email Domain, Page URL, or Stock Symbol
- SnapChat Mobile ID
# Unified Individual for Activation Membership
To take advantage of identity resolution, use the Unified Individual data model object (DMO) as the Activation Membership. With identity resolution, you combine data from disparate data sources to create one Unified Individual. When selecting Unified Individual as the DMO, the Individual ID attribute is included and not the Unified Individual ID.
## Contact Points for a Unified Individual
If you have data from multiple data sources in Data 360, use Unified Individual as the Activation Membership. Selecting Individual instead of Unified Individual as the Activation Membership can result in duplicate entries in your count. When any DMO besides Unified Individual is selected as the Activation Membership, Data 360 includes all contact points associated with the object.
Data 360 activates one row for a Unified Individual. Unified Individual includes different fields depending on which contact point channel you select.
Contact Point
Field
Email Address
Subscriber key
Contact email address
Phone Number
Subscriber key
Contact phone number
Phone country code
MobilePush
WhatsApp
If contact points come from multiple sources, Data 360 selects the contact points you prioritized in source selection. If there are multiple contact points for a single source, the contact point with the highest Einstein engagement score is selected. If the score isn't available or has the same score, the lowest alphanumeric ID is selected.
#### See Also
- [_Salesforce Help_: Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules.htm&release=264.0.0&type=5 "Match rules tell Data 360 which profiles to unify during the identity resolution process. Each match rule contains one or more criteria. Profiles are matched when all criteria within a match rule are satisfied.")
# Unified Lineage Limitations
Unified lineage has the following limitations.
### Required Editions
Some legacy components have limited field-level visibility.
- Batch transforms created before December 2025 don’t support field-level lineage. In the Unified Lineage interface and API responses, these transforms won’t display field-level mappings between source and target DMOs or DLOs.
- Calculated insights created before December 2025 don’t support field-level lineage. In the Unified Lineage interface and API responses, these calculated insights won’t display field-level mappings between source DMOs or DLOs and target calculated insight objects (CIOs).
# Unified Link Objects and Relationships to Unified Objects
Identity resolution creates the following link tables as a bridge between source objects and unified profile objects.
The unified objects and link objects created by your ruleset are based on your data mappings. These objects automatically have a 1:1 relationship. If any of your data sources have key qualifier fields added, these additional fields are visible on all Unified Link Account, Unified Link Individual, and Unified Link Contact Point objects.
Object Name
Object API Name
Fields
Field API Names
Unified Link Individual
IndividualIdentityLink__dlm
CreatedDate
Data Source
Data Source Object
Individual Id
Internal Organization Id
Unified Individual Id
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
SourceRecordId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Account
UnifiedLinkssotAccount__dlm
Account Id
CreatedDate
Data Source
Data Source Object
Internal Organization Id
Unified Account Id
SourceRecordId__c
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Contact Point Address
ContactPointAddressIdentityLink__dlm
Contact Point Address Id
CreatedDate
Data Source
Data Source Object
InternalOrganizationId
Unified Contact Point Address Id
SourceRecordId__c
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Contact Point App
ContactPointAppIdentityLink__dlm
Contact Point App Id
CreatedDate
Data Source
Data Source Object
InternalOrganizationId
Unified Contact Point App Id
SourceRecordId__c
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Contact Point Email
ContactPointEmailIdentityLink__dlm
Contact Point Email Id
CreatedDate
Data Source
Data Source Object
InternalOrganizationId
Unified Contact Point Email Id
SourceRecordId__c
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Contact Point Phone
ContactPointPhoneIdentityLink__dlm
Contact Point Phone Id
CreatedDate
Data Source
Data Source Object
InternalOrganizationId
Unified Contact Point Phone Id
SourceRecordId__c
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
Unified Link Party Identification
PartyIdentificationIdentityLink__dlm
CreatedDate
Data Source
Data Source Object
InternalOrganizationId
Party Identification Id
Unified Party Identification Id
CreatedDate__c
ssot__DataSourceId__c
ssot__DataSourceObjectId__c
SourceRecordId__c
ssot__InternalOrganizationId__c
UnifiedRecordId__c
## Unified Objects and Unified Link Objects with Multiple Rulesets
When a ruleset ID is used, the ruleset ID is appended to the names and API names of objects created during identity resolution.

Example
These are the object names and API names for two sample rulesets based on the Individual entity.
Ruleset ID
Object Type
Object Names
Object API Names
Blank (No Ruleset ID)
Unified
Unified Individual
Unified Contact Point Address
Unified Contact Point App
Unified Contact Point Email
Unified Contact Point Phone
Unified Party Identification
UnifiedIndividual__dlm
UnifiedContactPointAddress__dlm
UnifiedContactPointApp__dlm
UnifiedContactPointEmail__dlm
UnifiedContactPointPhone__dlm
UnifiedPartyIdentification__dlm
Blank (No Ruleset ID)
Link
Unified Link Individual
Unified Link Contact Point Address
Unified Link Contact Point App
Unified Link Contact Point Email
Unified Link Contact Point Phone
Unified Link Party Identification
IndividualIdentityLink__dlm
ContactPointAddressIdentityLink__dlm
ContactPointAppIdentityLink__dlm
ContactPointEmailIdentityLink__dlm
ContactPointPhoneIdentityLink__dlm
PartyIdentificationIdentityLink__dlm
Test
Unified
Unified Individual Test
Unified Contact Point Address Test
Unified Contact Point App Test
Unified Contact Point Email Test
Unified Contact Point Phone Test
Unified Party Identification Test
UnifiedssotIndividualTest__dlm
UnifiedssotContactPointAddressTest__dlm
UnifiedssotContactPointAppTest__dlm
UnifiedContactPointEmailTest__dlm
UnifiedssotContactPointPhoneTest__dlm
UnifiedssotPartyIdentificationTest__dlm
Test
Link
Unified Link Individual Test
Unified Link Contact Point Address Test
Unified Link Contact Point App Test
Unified Link Contact Point Email Test
Unified Link Contact Point Phone Test
Unified Link Party Identification Test
UnifiedLinkIndividualTest__dlm
UnifiedLinkContactPointAddressTest__dlm
UnifiedLinkContactPointAppTest__dlm
UnifiedLinkContactPointEmailTest__dlm
UnifiedLinkContactPointPhoneTest__dlm
UnifiedLinkPartyIdentificationFzzy__dlm
#### See Also
- [_Salesforce Help_: Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_fully_qualified_keys.htm&release=264.0.0&type=5 "Use Fully Qualified Keys (FQK) to avoid key conflicts when data from different sources are harmonized in the Data 360 data model.")
# Unify Anonymous and Known Individual Profiles Example
This example shows how known and anonymous individual profiles are unified.

Example
These profile and engagement data lake objects (DLOs) combine to create three unified individual profiles. After unifying the data with a match rule, the first unified profile is anonymous, and the other two are known.
**DLO 1: Marketing Cloud Engagement Source Individuals Data Stream**
| Subscriber Id | Data Source | Is Anonymous | First Name | Last Name | Email | Registration Id |
| --- | --- | --- | --- | --- | --- | --- |
| SUB-6014 | SFMC\_1487860 | 0 | Howard | Davis | hdavis@gmail.com | 9091-7065 |
| SUB-4161 | SFMC\_1487860 | 0 | Lisa | Jones | L.Jones@yahoo.com | 5751-8359 |
The Engagement Mobile SDK Registration Id is a shared identity across Data 360 and MobilePush (in Marketing Cloud Engagement). The Registration Id is a unique identifier generated when a mobile app is installed.
**DLO 2: Mobile Identity Data Stream**
| Individual Id | Data Source | Is Anonymous | First Name | Last Name | Email | Registration Id | Timestamp |
| --- | --- | --- | --- | --- | --- | --- | --- |
| 18123-1001 | My\_Mobile\_App | 1 | | | | 6571-8001 | 2021-12-16 12:00:00 |
| 18123-1002 | My\_Mobile\_App | 1 | | | | 9091-7065 | 2021-12-16 12:00:00 |
| 18123-1005 | My\_Mobile\_App | 1 | | | | 5751-8359 | 2021-12-16 12:00:00 |
| 18123-1005 | My\_Mobile\_App | 0 | Lisa | Jones | L.Jones@yahoo.com | 5751-8359 | 2021-12-16 12:10:00 |
**DLO 3: Mobile Engagement Clicks Data Stream**
| Event Id | Data Source | Device Id | URL | Timestamp |
| --- | --- | --- | --- | --- |
| 88111-3001 | My\_Mobile\_App | 18123-1001 | https://www.northerntrailoutfitters.com/default/homepage | 2021-12-16 12:00:00 |
| 88111-4001 | My\_Mobile\_App | 18123-1002 | https://www.northerntrailoutfitters.com/default/homepage | 2021-12-16 12:00:00 |
| 88111-5001 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/homepage | 2021-12-16 12:00:00 |
| 88111-5002 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/kids | 2021-12-16 12:00:01 |
| 88111-5003 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/kids-toddlers | 2021-12-16 12:00:03 |
| 88111-5004 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/toddler-zipline-rain-pant-3010742AZ1.html | 2021-12-16 12:00:07 |
| 88111-5005 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/checkout-login | 2021-12-16 12:00:10 |
| 88111-5006 | My\_Mobile\_App | 18123-1005 | https://www.northerntrailoutfitters.com/default/checkout?stage=shipping#shipping | 2021-12-16 12:00:11 |
Identity Resolution Match Rule: Party Identification Identification Number (Exact); Additional Information: Party Identification Type (App Identifier) and Party Identification Name (Mobile SDK Shared Identifier)
**Unified Profiles**
| Unified Individual Id | Is Anonymous | First Name | Last Name | Email | Registration Id | Unified Profile Category | Profile Explanation |
| --- | --- | --- | --- | --- | --- | --- | --- |
| UUID-1 (18123-1001) | 1 | | | | 6571-8001 | Anonymous | This unified profile contains only anonymous source data from the Mobile Identity Data Stream (DLO 2) and the Mobile Engagement Clicks Data Stream (DLO 3). |
| UUID-2 (18123-1002, SUB-6014) | 0 | Howard | Davis | hdavis@gmail.com | 9091-7065 | Known | This unified profile contains anonymous source data from the Mobile Identity Data Stream (DLO 2) and known source data from the Engagement Source Individuals Data Stream (DLO 1). Profiles with both source data types are categorized as known. |
| UUID-3 (18123-1005, SUB-4161) | 0 | Lisa | Jones | L.Jones@yahoo.com | 5751-8359 | Known | This unified profile contains known source data from the Mobile Identity Data Stream (DLO 2) and known source data from the Engagement Source Individuals Data Stream (DLO 1). |
# Unify Individual Profiles in Real Time
Real-time profile unification reviews profile information immediately and completes real-time profile matching in milliseconds. Real-time matching matches information about an active end user to a unified profile so that you can personalize your app or website within milliseconds.
Real-time unification is only available when these criteria are met.
- The identity resolution ruleset is based on the Individual object.
- The ruleset’s output Unified Individual object is used as the basis for a real-time data graph.
Single individual profiles are matched at real-time speeds immediately when the customer identity information is received from the real-time personalization process.
When you’re using real-time matching, identity resolution compares the input value to unified profile records in the ruleset’s related real-time data graph. If an existing customer is identified, these two actions are triggered.
- Real-time insights based on the unified profile are calculated. Results are saved to the real-time data graph record.
- Real-time segments based on the unified profile are built. Segment data is saved to the real-time data graph record.
The same ruleset is also used to process profiles received from the real-time personalization process incrementally, along with other profiles ingested or federated from other data sources.
#### See Also
- [_Salesforce Help_: Configure Real-Time Matching](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_configure_real_time_matching.htm&release=264.0.0&type=5 "You can configure any ruleset for real-time matching after its first ruleset run is completed by creating a real-time data graph based on the ruleset’s output unified profile data model object.")
# Unify Individuals or Accounts
Identity resolution in Data 360 offers several different ways to unify your records. The unification type you select determines what types of objects you can base your unified profiles on, the output objects created by the ruleset, and the speed at which records can be unified.
- **[Individual Object Data Modeling Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_individual.htm&release=264.0.0&type=5)**
Map the following fields during data modeling to prepare data about individuals for the identity resolution process.
- **[Account Object Data Modeling Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_account.htm&release=264.0.0&type=5)**
Map the following fields during data modeling to prepare data about your accounts for the identity resolution process.
- **[Unify Individuals or Accounts Based on Party Identifier](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_partyidentifier.htm&release=264.0.0&type=5)**
Party identifier refers to the exact match of the Identification Number, Identification Name, and Party Identification Type fields in the Party Identification object. This type of match is useful for matching unique identifiers, such as government ID, first-party cookies, external MDM systems, and vendor-specific IDs.
- **[Unify Individuals or Accounts with an External Link](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_externallink.htm&release=264.0.0&type=5)**
Matching on an external link lets you unify profiles that have been identified as matching in an external data source. Your source data must include an ID that identifies the matched records.
- **[Unify Individual Profiles in Real Time](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unify_realtime.htm&release=264.0.0&type=5)**
Real-time profile unification reviews profile information immediately and completes real-time profile matching in milliseconds. Real-time matching matches information about an active end user to a unified profile so that you can personalize your app or website within milliseconds.
#### See Also
- [_Salesforce Help_: Individual Object Data Modeling Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_individual.htm&release=264.0.0&type=5 "Map the following fields during data modeling to prepare data about individuals for the identity resolution process.")
- [_Salesforce Help_: Account Object Data Modeling Requirements](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_data_modeling_account.htm&release=264.0.0&type=5 "Map the following fields during data modeling to prepare data about your accounts for the identity resolution process.")
# Unify Individuals or Accounts Based on Party Identifier
Party identifier refers to the exact match of the Identification Number, Identification Name, and Party Identification Type fields in the Party Identification object. This type of match is useful for matching unique identifiers, such as government ID, first-party cookies, external MDM systems, and vendor-specific IDs.
When integrating Salesforce CRM and Marketing Cloud Engagement, use the MC Subscriber Key as a party identifier. When using MobilePush, create an additional custom match rule to match the Mobile SDK Shared Identifier.
You can't use the Match on Blank matching option in match rules based on party identifier.
These fields must be mapped before you can use the party identification object in identity resolution.
Party Identification ID
The party identification ID is the primary key or the primary identifier from your customer data. It can be any unique ID.
Party
This ID field is a foreign key to an account or individual. A relationship must exist between account ID or individual ID and this field.
Party Identification Type
This field provides additional information about the identifier, for example, Social or Account Identifier. Be descriptive because it’s used to set up your match rules.
Identification Number
The ID used for identity resolution comparison. For example, a driver’s license number, subscriber ID number or external MDM ID number. You can't match identification numbers on blanks.
Identification Name
Similar to party identification type, this field specifies the name of the ID space. For example, Mobile ID, D-U-N-S number, or LinkedIn ID. This name is also used in match rule setup.

Example
Suppose you ingest data from multiple sources that all contain driver license information. In this example, three data sources contain information about an individual with the California driver’s license ID number D1469256. If you set up matching on party identifier, these three individual records (10016-00001, 10017-00001, and 10018-00001) are resolved into a single unified individual.
| Identification Number | Identification Name | Party Identification Type | Party | Party Identification ID |
| --- | --- | --- | --- | --- |
| D1469256 | CA License Number | CA Driver License | 10016-00001 | 100 |
| D1469256 | CA License Number | CA Driver License | 10017-00001 | 101 |
| D1469256 | CA License Number | CA Driver License | 10018-00001 | 102 |

Example
Identifiers can be an effective match method for accounts. To ensure that these records are appropriately joined in Data 360 as a single, unified account, add these custom match rules based on the Party Identification object. If your data includes more than one type of account identifier, set up separate match rules for each identifier.
Match on D-U-N-S Number
To match accounts from any data sources that include the D-U-N-S number, create a custom match rule with this criteria.
- Object—Party Identification
- Field—Identification Number
- Match Method—Exact
- Party Identification Type—Account Identifier
- Party Identification Name—D-U-N-S Number

Example
Engagement data bundles represent subscriber data across Email Studio, MobileConnect, and MobilePush. To ensure that these records are appropriately joined in the Data 360 as a single, unified individual, add these custom match rules based on the Party Identification object.
Match on MC Subscriber Key
To match to any other existing data sources that share the MC subscriber key, create a custom match rule with this criteria.
- Object—Party Identification
- Field—Identification Number
- Match Method—Exact
- Party Identification Name—MC Subscriber Key
- Party Identification Type—Person Identifier
Match on Mobile SDK Shared Identifier
Engagement data can include both known and unknown records with different subscriber keys for the same individual. In orgs using Mobile SDK to track app usage, unify known and unknown records with a custom match rule based on the Mobile SDK Shared Identifier.
- Object—Party Identification
- Field—Identification Number
- Match Method—Exact
- Party Identification Number—Mobile SDK Shared Identifier
- Party Identification Type—App Identifier
#### See Also
- [_Salesforce Help_: Marketing Cloud Engagement Data Bundle Information](https://help.salesforce.com/s/articleView?id=data.c360_a_mc_bundle_data_categories.htm&release=264.0.0&type=5 "When ingesting data from Marketing Cloud Engagement, Data 360 creates data streams and data lake objects (DLOs) for each starter bundle, along with schema and mappings to data model objects (DMOs).")
- [_Salesforce Help_: Configure Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5 "Specify how identity resolution identifies matching records in Data 360.")
# Unify Individuals or Accounts with an External Link
Matching on an external link lets you unify profiles that have been identified as matching in an external data source. Your source data must include an ID that identifies the matched records.
Matching based on external links improves profile matching in complex situations by ensuring that records stay linked even if attribute data changes. For example, match an anonymous user profile to a logged in user profile by contributing the link during the browser session. Or, add identifiers to source profiles to unify profiles that wouldn’t normally match based on regular rules.
#### See Also
- [_Salesforce Help_: Configure Identity Resolution Match Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_match_rules_configure.htm&release=264.0.0&type=5 "Specify how identity resolution identifies matching records in Data 360.")
# Unify Leads for Targeted Selling
Improve sales experiences by unifying data with Data Cloud. Use that data to unlock insights to enhance Sales Cloud. Combine your Sales Cloud data to identify opportunities with priority customers to sell products and services.
## About this Guide
This multi-step solution requires various users to complete steps in Data Cloud and Sales Cloud. This solution helps you ingest data, unify that data, and create an insight, and view unified profiles.
To complete this use case, review the features used, permissions required, and associated skills.
Products or Features
Roles and Permissions
Data Cloud Architect permission set
Associated Skills
Let's review the high-level steps we cover in this guide.
## Configure Users and Install Data Bundles
Set up Data Cloud users, add the appropriate permission sets, and then install data bundles.
## Ingest and Map Data
Use a starter data bundle to create a data stream for Leads. Then map required fields for Identity Resolution.
## Unify Sales Data with Identity Resolution
Link multiple sources of data into a unified profile using an identity resolution ruleset that contains match and reconciliation rules based on the Individual data model object. Then view the profile in Profile Explorer.
## Analyze Sales Data with Calculated Insights
Create a calculated insight, Unified Individual Counts by Sales Object, and then view it in Data Explorer.

[ About Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud.htm&type=5&language=en_US)
[ Sales Cloud Enhancements with Data Cloud: Quick Look](https://trailhead.salesforce.com/content/learn/modules/sales-cloud-enhancements-with-data-cloud-quick-look)
[ Data Cloud Glossary](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&type=5&language=en_US)
- **[Configure Users and Install the Sales Cloud Data Bundle](https://help.salesforce.com/s/articleView?id=data.c360_a_conf_connect_dc4sales.htm&release=264.0.0&type=5)**
Set up Data Cloud users, add the appropriate permission sets, and then install the Sales Cloud data bundle. These steps are all done within Data Cloud Setup.
- **[Ingest and Map Data from Sales Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_ingest_map_dc4sales.htm&release=264.0.0&type=5)**
In Data Cloud, you can connect to many data sources. Many of the Salesforce connectors have a starter data bundle to help you quickly set up a data streams, create data lake objects, and map to the data model automatically. However, you must map custom objects and some required fields to the Customer 360 Data Model to use Identity Resolution.
- **[Unify Sales Data with Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_unify_data_dc4sales.htm&release=264.0.0&type=5)**
Link multiple sources of data into a unified profile using an identity resolution ruleset. A ruleset contains match and reconciliation rules based on the Account data model object or the Individual data model object.
- **[Analyze Sales Data with Calculated Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_analyze_ci_dc4sales.htm&release=264.0.0&type=5)**
Calculate multidimensional metrics on your data within Data Cloud. You can create metrics at the profile, segment, and population levels. For example, evaluate performance at the channel level or use product metrics to understand purchasing and browsing behavior.
# Unify Sales Data with Identity Resolution
Link multiple sources of data into a unified profile using an identity resolution ruleset. A ruleset contains match and reconciliation rules based on the Account data model object or the Individual data model object.
## Create an Identity Resolution Ruleset
Configure a ruleset to create a unified profile based on multiple sources of data. First you create your ruleset.
1. In Data Cloud on the Identity Resolutions tab, click **New**.
2. For the primary data object, select **Individual**.
If you don’t see any objects available to select, make sure your data is modeled properly.
3. Leave the ruleset ID blank and click **Next**.
4. Name your ruleset and add an optional description.
5. Disable **Run jobs automatically**.
6. Click **Save**.
## Add Match Rules
Match rules identify what data is reviewed and used for matching. For this guide, we select all the default matching rules.
1. In the Match Rules section of the ruleset’s home page, click **Configure**.
2. Select **Fuzzy Name and Normalized Email** and click **Next**.
3. Keep the settings and click **Next**.
4. Click **Add Match Rule**.
5. Select **Fuzzy Name and Normalized Phone** and click **Next**.
6. Keep the settings and click **Next**.
7. Click **Save**.
## Set Reconciliation Rules
While match rules are used to link together data into a unified customer profile, reconciliation rules determine the logic for data selection. Let's set the default reconciliation rules.
1. In the Reconciliation Rules section, select the **Individual** object.
2. Set the default rule (1) to **Most Frequent**.
3. Click **Save**.
4. To run the ruleset manually, on the ruleset’s record page go to the **Processing History** tab.
5. Verify that **Automatic Runs** are disabled. If automatic runs aren’t disabled, click **Edit** and disable.
6. Click **Run Ruleset**.

Note Read more about the [Identity Resolution Summary](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_summary.htm&type=5&language=en_US) and [Identity Resolution Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&type=5&language=en_US). You can also take the [Data and Identity Trailhead Module](https://trailhead.salesforce.com/content/learn/modules/data-and-identity-in-salesforce-cdp?trail_id=explore-customer-360-audiences) for a deeper dive.
When the run finishes, review the Resolution Summary to determine how successfully profiles were unified. The higher the consolidation percentage, the more successful your ruleset was at combining individual records into unified individual profiles based on the ruleset’s match and reconciliation rules.
## View Unified Profiles in Profile Explorer
User Profile Explorer to validate and see a complete view of a unified profile for an account or individual.
1. In Data Cloud, click **Profile Explorer**.
2. To search for a profile, select an attribute and enter an exact phrase.
3. From the search results, select a profile to explore.

Note You can’t configure the Unified Profile Insights app until after you’ve created at least one calculated insight. Learn more about [Profile Explorer in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer.htm&type=5&language=en_US).
# Unify Service Data with Identity Resolution
Link multiple sources of data into a unified profile using an identity resolution ruleset. A ruleset contains match and reconciliation rules based on the Account data model object or the Individual data model object.
## Create an Identity Resolution Ruleset
Configure a ruleset to create a unified profile based on multiple sources of data. First you create your ruleset.
1. In Data Cloud on the Identity Resolutions tab, click **New**.
2. For the primary data object, select **Individual**.
If you don’t see any objects available to select, make sure your data is modeled properly.
3. Leave the ruleset ID blank and click **Next**.
4. Name your ruleset and add an optional description.
5. Disable **Run jobs automatically**.
6. Click **Save**.
## Add Match Rules
Match rules identify what data is reviewed and used for matching. For this guide, we select all the default matching rules.
1. In the Match Rules section of the ruleset’s home page, click **Configure**.
2. Select **Fuzzy Name and Normalized Email** and click **Next**.
3. Keep the settings and click **Next**.
4. Click **Add Match Rule**.
5. Select **Fuzzy Name and Normalized Phone** and click **Next**.
6. Keep the settings and click **Next**.
7. Click **Save**.
## Set Reconciliation Rules
While match rules are used to link together data into a unified customer profile, reconciliation rules determine the logic for data selection. Let's set the default reconciliation rules.
1. In the Reconciliation Rules section, select the **Individual** object.
2. Set the default rule (1) to **Most Frequent**.
3. Click **Save**.
4. To run the ruleset manually, on the ruleset’s record page go to the **Processing History** tab.
5. Verify that **Automatic Runs** are disabled. If automatic runs aren’t disabled, click **Edit** and disable.
6. Click **Run Ruleset**.

Note Read more about the [Identity Resolution Summary](https://help.salesforce.com/s/articleView?id=data.c360_a_resolution_summary.htm&type=5&language=en_US) and [Identity Resolution Reconciliation Rules](https://help.salesforce.com/s/articleView?id=data.c360_a_reconciliation_rules.htm&type=5&language=en_US). You can also take the [Data and Identity Trailhead Module](https://trailhead.salesforce.com/content/learn/modules/data-and-identity-in-salesforce-cdp?trail_id=explore-customer-360-audiences) for a deeper dive.
When the run finishes, review the Resolution Summary to determine how successfully profiles were unified. The higher the consolidation percentage, the more successful your ruleset was at combining individual records into unified individual profiles based on the ruleset’s match and reconciliation rules.
## View Unified Profiles in Profile Explorer
User Profile Explorer to validate and see a complete view of a unified profile for an account or individual.
1. In Data Cloud, click **Profile Explorer**.
2. To search for a profile, select an attribute and enter an exact phrase.
3. From the search results, select a profile to explore.

Note You can’t configure the Unified Profile Insights app until after you’ve created at least one calculated insight. Learn more about [Profile Explorer in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_profile_explorer.htm&type=5&language=en_US).
# Unify Source Profiles
Use identity resolution in Data 360 to consolidate data from different sources into comprehensive views of your customers and accounts. Identity resolution uses matching and reconciliation rules to link data about people or accounts into unified profiles. Identity resolution creates complete, actionable views of your customers but doesn’t create golden records and isn’t a master data management (MDM) system. Each unified profile contains all the unique contact point values from all sources. You choose which view of your customers to use based on each business use case you want to solve.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
Unified profile data empowers your reps to sell, service, and market more effectively with 360-degree views of each customer.
- Prioritize high-value leads from existing or key accounts.
- Boost sales effectiveness with personalized, relevant marketing across channels.
- Enable seamless information sharing across departments.
- Equip reps with full account history for contextual conversations and cross-channel consistency.
- Empower sales and service to identify cross-sell and upsell opportunities.
Set up identity resolution rulesets after transforming and mapping source data to data model objects (DMOs). Mapping must be completed before creating rulesets.
- **[About Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution.htm&release=264.0.0&type=5)**
Identity resolution is the processing engine that generates unified profiles from source profile data stored in Data 360. Unified profiles act as a system of reference to unlock our source data. Understand how and when source profiles are processed and what you can do with unified profile output.
- **[Profile Unification Types](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_unification_types.htm&release=264.0.0&type=5)**
Identity resolution in Data 360 offers several different ways to unify your records. The unification type you select determines what types of objects you can base your unified profiles on, the output objects created by the ruleset, and the speed at which records can be unified.
- **[Identity Resolution Rulesets](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_ruleset.htm&release=264.0.0&type=5)**
Rulesets contain match and reconciliation rules that tell the customer data platform how to link multiple sources of data into a unified profile. Unified profile information is stored in data model objects created by the ruleset.
- **[Optimize Identity Resolution](https://help.salesforce.com/s/articleView?id=data.c360_a_identity_resolution_optimize.htm&release=264.0.0&type=5)**
Consider these best practices and troubleshooting tips for the data you bring in and send out of Data 360 to get the most of your unified profiles.
#### See Also
- [_Trailhead_: Data and Identity in Data 360](https://trailhead.salesforce.com/en/content/learn/modules/data-and-identity-in-salesforce-cdp)
# Uninstall a Deployed Data Kit in Data 360
Removing unused or outdated data kits keeps your org organized and efficient. To uninstall a data kit deployed from a managed package, first undeploy the deployed data kit components and their dependencies from all data spaces. Then, uninstall the managed package.
### Required Editions
User Permission Set
Needed
To uninstall a data kit:
Permission set:
1. In your target org, go to Data 360 Setup.
2. Under Developer Tools, click **Data Kits**.
3. Open your data kit, and click **Un-deploy**.
Managed package data kits lock deployed components by design. To remove these components, undeploy the data kit.
4. Select the data space to remove the deployed components, and click **Un-deploy**.
Repeat these steps to remove the deployed components from all the data spaces.
5. After you remove all the components, uninstall the managed package with the data kit. See [Uninstall a Managed Package.](https://help.salesforce.com/s/articleView?id=xcloud.distribution_uninstalling_packages.htm&type=5&language=en_US)
# Unlock Hidden Insights with Tableau
After you've combined, unified, and harmonized your data in Data 360, it's now ready for you to analyze. Use Tableau to find useful and actionable insights that can drive business success and create a personalized experience for your customers. Data 360, Tableau, and Salesforce 360 apps work together to consolidate your data and create a single customer record. Unlock hidden insights, and make decisions based on all your customer data.
With Data 360 and Tableau, you can:
- Connect Tableau to Data 360 data model objects using the built-in Salesforce Data Cloud connector in Tableau.
- Analyze your data in near real time with a live connection to Data 360.
- Quickly analyze your data with the Salesforce purpose-built Accelerator dashboards.
- Create key metrics that drive your business decisions.
- Publish the metrics to Tableau Cloud or Tableau Server to share with your colleagues.
- Make the metrics available to your decision-makers in their workflow, and embed your metrics and dashboards in your Salesforce instance.
## What You Need
- Data 360 Starter pack
- Tableau Creator license to connect to Data 360 and author views and dashboards and embed them in your Salesforce instance
- Tableau explorer or viewer licenses for accessing the views and dashboards in Tableau
To learn more about Tableau licenses, see [Understanding Role-Based License Model](https://help.tableau.com/current/online/en-us/license_product_keys.htm#rolebased-license-modelcense_product_keys.htm%23rolebased-license-model).

- **[Connect Tableau in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_tableau_connected_app.htm&release=264.0.0&type=5)**
Set up a connection to Data 360 from Tableau. Different steps are required depending on which Tableau product and version you use.
- **[Enable Data 360 in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_enable_tableau_connector.htm&release=264.0.0&type=5)**
Using the Data 360 connector, you can discover and analyze unified profiles and other customer insights.
- **[Use Data 360 Data in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_using_customer_360_aud_data_in_tableau.htm&release=264.0.0&type=5)**
Tableau enables metadata and data discovery of all objects in your Data 360 instance with Salesforce security mode.
- **[Use Data 360 Data Spaces to Organize Data in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_dataspaces_tableau.htm&release=264.0.0&type=5)**
Use data spaces to segregate your data, metadata, and processes into categories, such as brand, region, or department. Set up permissions so that users can see and work on data only in the context of their brand or region.
- **[View Tableau Dashboards](https://help.salesforce.com/s/articleView?id=data.c360_a_view_tableau_data.htm&release=264.0.0&type=5)**
After defining visualizations on your Data 360 data in Tableau, you can view these dashboards by embedding or publishing them.
- **[Visual Segment Creation to Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_create_segments_to_data_cloud.htm&release=264.0.0&type=5)**
Segmentation enables data analysts to curate relevant portions of data from their analyses in Tableau and seamlessly transfer them as segments to Data 360.
- **[Tableau Accelerators for Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_tableau_accelerators.htm&release=264.0.0&type=5)**
A Tableau accelerator provides ready-to-use dashboards and workbooks geared for a particular industry or business use case. All Tableau accelerators use the Salesforce Data Cloud connector to connect Tableau and Data 360.
- **[Data 360 and Tableau Use Cases](https://help.salesforce.com/s/articleView?id=data.c360_a_dc_for_tableau_use_cases.htm&release=264.0.0&type=5)**
Tableau helps you explore, analyze, and find hidden insights in your data. The Tableau to Data Cloud connectors use the Hyper query engine to provide fast processing. You can explore your Data 360data in near real time enabling quick and accurate decision-making. These example use cases illustrate how Data 360and Tableau work together to help you achieve your business goals and deliver a personalized experience for your customers.
# Unstructured Data
Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.
Data 360 supports several connectors and file formats for unstructured data. Learn more about unstructured data.
- [Using Unstructured Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_overview.htm&type=5&language=en_US)
- [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&type=5&language=en_US)
- [Billing Considerations for Unstructured Data and Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&type=5&language=en_US)
# Unstructured Data File Formats and Connectors
Data 360 supports multiple file formats and connector types for unstructured data.
## Supported File Formats for Unstructured Data
Data 360 supports these file formats for unstructured data and search index configurations.
Text-Based Files
FILE Format
File Extension
Search indexing notes
harmonization notes
PDF
.pdf
Limited support for content formatted as tables.
These elements are supported:
Tables: Plain text only
Text: Plain text, icons, images, links, lists, and headers
Lists: Simple lists and single indentation lists
Orientation: Left to right, top down, and up to two-columned text
(partially)
These elements are not supported:
Tables: Icons, images, inner tables, lists in cells, multiple tables, merged
cells, and deep indentations beyond a single level
Text: Code blocks, ligatures (two or more letters joined together as a
single symbol), and non-Latin letters
Lists: Deep nested lists beyond a single level
Orientation: Right to left, rotated documents (non vertical), and text with
more than two columns.
Text
.txt
HTML
.html
Limited support for content formatted as tables.
Supported
CSV
.csv
Each row is a chunk.
Log
.log
Each row is a chunk.
Excel
.xlsx
Limited support for content formatted as tables.
PowerPoint
.pptx
Chunked by heading. Limited support for content formatted as tables.
Rich text format
.rtf
Chunked by heading or paragraph. Limited support for content formatted as
tables.
Word
.docx
Chunked by heading or paragraph. Limited support for content formatted as
tables.
Supported
Messages
.msg
Chunked by body and attachments.
Email
.eml
Chunked by body, headers, and attachments.
XML
.xml
Chunked by XML element tag.
Markdown
.md
Chunked by heading or paragraph. Tables are flattened to text.
Supported

Note Data 360 content harmonization supports Word, PDF, HTML, and Markdown file formats only from unstructured data model objects (UDMOs), not from standard data model objects (DMOs), including those that have a file attachment UDMO. Other ingested file types are not harmonized and can be viewed in their source platform linked from the Content Viewer.
Audio, Video, and Image Files
FILE Format
File Extension
SEARCH INDEXING Notes
MPEG
.mpg
Audio only
MPEG-3
.mp3
Audio only
MPEG-4
.mp4
Audio only
MPGA
.mpga
Audio only
Ogg
.ogg
Audio only
Wav
.wav
Audio only
FLAC
.flac
Audio only
WebM
.webm
Audio only
JPEG (Beta)
.jpg
Image-based files. Embeddings include extracted text and captions
The maximum
size of an image that can be processed is 20 MB.
PNG (Beta)
.png
Image-based files. Embeddings include extracted text and captions.
The
maximum size of an image that can be processed is 20 MB.
PDF (Beta)
.pdf
PDFs with Images.
Maximum size of a PDF that can be processed is 100
MB
## Unstructured Data Connectors
Data 360 has several connectors built for ingesting unstructured data from third-party applications or sources. You can also create a data lake object to ingest unstructured data through an existing connector.
- [Adobe Experience Manager](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-aem-connector.html)
- [Amazon S3 Storage](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-awss3-connector.html)
- [Azure Storage](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-azure-udlo.html)
- [Box](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-box-connector.html)
- [Confluence](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-confluence-unstructured-connector.html)
- [GitHub](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-github-connector.html)
- [Google Cloud Storage](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-gcs-udlo.html)
- [Google Drive](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-googledrive-unstructured-connector.html)
- [Guru](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-guru-connector.html)
- [Helpjuice](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-helpjuice-connector.html)
- [Jira](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-jira-unstructured-connector.html)
- [Microsoft SharePoint (Documents)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-microsoftsharepoint-unstructured-connector.html)
- [Microsoft SharePoint (Site Pages and Site Assets)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-microsoftsharepoint-unstructured-spsa-connector.html)
- [MuleSoft Direct](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-mulesoft-direct.html)
- [Web Content (Crawler)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-web-content-crawler-connector.html)
- [Web Content (Sitemap)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-web-content-sitemap-connector.html)
- [YouTube](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-youtube-connector.html)
- [Zendesk](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-create-zendesk-udlo.html)
Additionally, you can ingest ingest unstructured data from [file attachments on Salesforce objects](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_content_document.htm&release=264.0.0&type=5 "Use the Salesforce CRM connector to ingest into Data 360 content files such as documentation or customer support files. You can ingest content files attached to standard and custom CRM objects, including 100K of the most recently uploaded historical files and all new files going forward. Data 360 converts the content into searchable vectors for generative AI, analytics, and automation while preserving search context.") or upload files directly into [Agentforce Data Libraries](https://help.salesforce.com/s/articleView?id=ai.data_library_parent.htm&type=5&language=en_US).
## Unstructured Data Limits and Guidelines
For limits and guidelines related to supported file types, see [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.").
For billing info, see [Billing Considerations for Unstructured Data and Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&release=264.0.0&type=5 "When you use unstructured data and search index configurations, your data is stored and processed in Data 360. Use of unstructured data and search index in Data 360 impacts the consumption of credits in the following usage types.").
## Monitor Unstructured Data Connectors
For methods of monitoring your unstructured data streams and ingestion progress, see [Monitor the Status of Unstructured Connectors Data Ingestion](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_the_status_of_unstructured_connectors_data_ingestion.htm&release=264.0.0&type=5 "You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.").
#### See Also
- [_Salesforce Help_: Monitor the Status of Data Ingestion for Unstructured Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_the_status_of_unstructured_connectors_data_ingestion.htm&release=264.0.0&type=5 "You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.")
# Unstructured Data in Data 360
By bringing unstructured data in Data 360, you can ground your Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.
### Required Editions
Unstructured data is data that doesn’t have a specific, consistent format and can’t be easily stored in a typical relational database. Its lack of structure makes it particularly challenging to search or analyze. However, AI technologies, such as large language models, can process unstructured data effectively. Common forms of unstructured data include chat transcripts, PDFs, audio and video files, legal documents, and other large texts, such as books. In Salesforce, unstructured data can come from Knowledge Articles or sales call transcripts. To learn more about unstructured data, see these resources.
- [Using Unstructured Data in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_overview.htm&release=264.0.0&type=5 "Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.")
- [Unstructured Data File Formats and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&release=264.0.0&type=5 "Data 360 supports multiple file formats and connector types for unstructured data.")
- [Unstructured Data Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_workflow.htm&release=264.0.0&type=5 "Regardless of your use case for unstructured data, there's a general workflow to ingest and process it in Data 360.")
## Unstructured Data Lake Objects
For typical structured data, a data lake object (DLO) is a storage container for the data ingested using a data stream in Data Cloud. Unstructured data is referenced directly by an unstructured data lake object (UDLO) that can also be ingested by data stream.
A single UDLO contains metadata for a collection of unstructured data files.
A UDLO has these key pieces of metadata at the table level.
- Content Type: For a UDLO, contains a metadata attribute value of `Content`
- Total Records: Indicates the number of records in the UDLO. Because each record in the UDLO corresponds to a file on the blob store, the number of records in a UDLO represents the number of unstructured data files that are represented in the UDLO.
- Last Updated On: The timestamp for when the file metadata stored in the UDLO was most recently modified.
## UDLO Schema Attributes
The UDLO schema has these attributes.
| Field Label | Field API Name | Data Type | Description |
| --- | --- | --- | --- |
| `File Path` | `FilePath__c` | Text | Primary Key: Contains the relative path of the source file |
| `Resolved FilePath` | `ResolvedFilePath__c` | Text | Fully resolved path of the file, for internal use |
| `Content Type` | `ContentType__c` | Text | The file MIME type, such as text/csv or text/html |
| `Parent Id` | `ParentId__c` | Text | Used to set up a foreign key to a related object |
| `Size` | `Size__c` | Number | File size, in bytes |
| `Col1…Col5` | `Col1__c…Col5__c` | Text | Currently unused |
| `Data Source` | `Data Source__c` | Text | |
| `Data Source Object` | `DataSourceObject__c` | Text | |
| `Internal Organization` | `InternalOrganization__c` | Text | |
| `ETag` | `ETag__c` | Text | Currently unused |
| `KQ_FilePath` | `KQ_FilePath__c` | Text | Key Qualifier for "FilePath\_\_c" |
| `URL` | `URL__c` | Text | URL in source. |
| `Type` | `Type__c` | Text | File types such as .html, .pdf |
| `Title` | `Title__c` | Text | Title of the document |
| `Metadata` | `Metadata__c` | Text | Extra metadata (currently only used in the Youtube connector) |
| `Last Modified` | `LastModified__c` | Date/Time | The data's latest update time |
| `Labels` | `Labels__c` | Text | Labels, tags etc. Defined per connector type |
## UDMO Schema Attributes
Unstructured data model objects (UDMOs) are groups of data created from unstructured data sources. The UDMO schema has these attributes.
| Field Label | Field API Name | Data Type | Description |
| --- | --- | --- | --- |
| `File Path` | `FilePath__c` | Text | Primary Key: Contains the relative path of the source file |
| `Resolved FilePath` | `ResolvedFilePath__c` | Text | Fully resolved path of the file, for internal use |
| `Content Type` | `ContentType__c` | Text | The file MIME type, such as text/csv or text/html |
| `Parent Id` | `ParentId__c` | Text | Used to set up a foreign key to a related object |
| `Size` | `Size__c` | Number | File size, in bytes |
| `Col1…Col5` | `Col1__c…Col5__c` | Text | Currently unused |
| `Data Source` | `Data Source__c` | Text | |
| `Data Source Object` | `DataSourceObject__c` | Text | |
| `Internal Organization` | `InternalOrganization__c` | Text | |
| `ETag` | `ETag__c` | Text | Currently unused |
| `KQ_FilePath` | `KQ_FilePath__c` | Text | Key Qualifier for "FilePath\_\_c" |
| `URL` | `URL__c` | Text | URL in source. |
| `Type` | `Type__c` | Text | File types such as .html, .pdf |
| `Title` | `Title__c` | Text | Title of the document |
| `Metadata` | `Metadata__c` | Text | Extra metadata (currently only used in the Youtube connector) |
| `Last Modified` | `LastModified__c` | Date/Time | The data's latest update time |
| `Labels` | `Labels__c` | Text | Labels, tags etc. Defined per connector type |
## Fully Qualified Keys for UDLOs and UDMOs
Fully Qualified Keys Data 360 adds key qualifier fields to UDLOs and UDMOs, which behave the same as in standard DLOs and DMOs. Key qualifier fields can be added when you create object relationships between DMOs and UDMOs. [See Fully Qualified Keys in Data Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_dlo_dmo_key_qualifiers.htm&type=5&language=en_US).
#### See Also
- [_Salesforce Help_: Connect Unstructured Data to Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect_overview.htm&release=264.0.0&type=5 "Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.")
# Unstructured Data Workflow
Regardless of your use case for unstructured data, there's a general workflow to ingest and process it in Data 360.
### Required Editions
User Permissions
Needed
To set up Data 360
System admin profile OR
Data Cloud Architect
To ingest unstructured data and create search indexes
One of these permission sets:
#### See Also
- [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&release=264.0.0&type=5 "Document AI in Data 360 uses large language models (LLMs) to extract structured data from unstructured documents such as invoices, resumes, lab reports, and purchase orders.")
## Step 1: Set up Data 360 In Your Org
Before you can connect unstructured data, verify that Data 360 is provisioned and enabled in your org.
See [Get Started with Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_product_considerations.htm&release=264.0.0&type=5 "Before you begin with Data 360, review the checklist, considerations, and product navigation.").
## Step 2: Ingest Unstructured Data
Depending on your use case, Data 360 has connectors purpose built for ingesting unstructured data from third-party applications or sources. You can also use the Salesforce CRM connector to ingest knowledge article data.
Some connectors, such as those for Amazon S3, Azure, or Google Cloud Storage, require file notification pipelines. Review the documentation for each connector.
Refer to the Unstructured Data Reference for more information.
## Step 3: Process Data
Use Document AI in Data 360 to read and import unstructured or semi-structured data from documents like invoices, resumes, lab reports, and purchase orders. Using AI, Data 360 extracts data from those documents into Data Lake Objects (DLO), which represent schemas for the extracted data. From this point, your data is available for search index processing and retrieval from automation flows or AI agent actions.
See [Document AI](https://help.salesforce.com/s/articleView?id=data.c360_a_document_ai.htm&type=5&language=en_US).
## Step 4: Create a Search Index
After setting up an unstructured data connection, you create a vector search index or a hybrid search index using either Data 360 defaults or the advanced builder. The search index helps validate that outputs are finely tuned to your users' intents and contexts.
See [Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.") or [Create a Hybrid Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_create.htm&release=264.0.0&type=5 "Configure a hybrid search index for a data model object (DMO) or an unstructured data model object (UDMO) to provide relevant information to generative AI applications. Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors, and then generates a vector index and a keyword index.").
## Step 5: Use Unstructured Data in a Workflow
Using unstructured data in Salesforce improves your AI agent, automation, and analytics workflows, improving customer experiences and operational efficiency. Based on your use case, consider these resources.
- Use Query API to [Run Vector Search Queries](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_query.htm&release=264.0.0&type=5 "Use the Query API to run vector searches in Data 360. Use these examples as starting points.") or to [Run Hybrid Search Queries](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index_query.htm&release=264.0.0&type=5 "Use Query API to run hybrid searches in Data 360. Use these examples as starting points.").
- Retrieval Augmented Generation (RAG) in Data 360 is a framework for grounding large language model (LLM) prompts. By augmenting prompts with accurate, current, and pertinent information, RAG improves the relevance and value of LLM responses for users. See [Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=data.c360_a_rag_overview.htm&release=264.0.0&type=5 "Retrieval Augmented Generation (RAG) in Data 360 is a framework for grounding large language model (LLM) prompts. By augmenting the prompt with accurate, current, and pertinent information, RAG improves the relevance and value of LLM responses for users.").
- Bring the power of conversational AI to your business with Agentforce. Build intelligent, trusted, and customizable AI agents and empower your users to get more done with Salesforce. See [Agentforce Agents](https://help.salesforce.com/s/articleView?https://help.salesforce.com/s/articleView?id=ai.copilot_intro.htm&type=5id=ai.data_library_parent.htm&type=5&language=en_US).
# Update a Data Kit in Data 360
You can update an existing data kit when you modify Salesforce CRM and B2C Commerce data streams, data models, mappings, and relationships. You can also retrieve and deploy the updated data kit from Data 360 with Package Manager in your Salesforce org.
### Required Editions
User Permission Set
Needed
To update a data kit:
Permission set:
1. In your Data Cloud publisher org, click **Setup**, and select **Data Cloud Setup**.
2. Make necessary changes to your Data 360 features that are packaged in a data kit.
For example, you can add new mappings or modify fields for data streams.
3. Under Developer Tools, click **Data Kits**.
4. Select your data kit, verify the changes made, and click **Update**.
5. Create and publish the updated package.
1. In your publisher org, create a new package version.
2. To publish the updated package, click **Publish**.
Your data kit is updated. Install the package in your subscriber org and deploy the components from the updated package.
#### See Also
- [_Salesforce Help_: Publish a Data Kit](https://help.salesforce.com/s/articleView?id=data.c360_a_publish_package_kit.htm&release=264.0.0&type=5 "After creating and publishing your data kit in Data 360 source org, add the data kit to a package and upload it using Package Manager in your Salesforce org.")
# Update a Schema
After your schema is created in Data 360, update formula fields or source fields as needed.
### Required Editions
User Permissions
Needed
To update a schema
Data Cloud Architect permission set OR
Manage External Connections or
Customize Application permissions
1. To modify a formula, navigate to the field list on the data streams details page.
2. Find the specific formula field you wish to modify and select **Edit Formula** from the dropdown.
3. To overwrite the formula, update the formula syntax and click **Save**

Note Changes to formula logic are applied on a go-forward basis, not retroactively. To keep logic consistent across all data imports, import historical data into Data 360 after the change has been applied.

Note Formula fields that are designated as the Primary Key or Event Date Time field can’t be modified.

Note Any changes you make to fields or objects that have already been activated aren’t applied to existing fields. Instead, these changes create new fields in the data extension. New fields are updated on the data extension upon the next refresh after field creation.
# Update Database Configuration for Zero Copy Data Streams
When deploying a data kit that contains zero copy data streams, you can update the target database, schema, or table after deployment to match your target environment.
### Required Editions
This allows you to promote configurations across environments (sandbox to production) where each environment points to different schemas or tables without recreating the data stream.
User
Permissions Needed
To update database configurations
Permission set:
1. In Data 360, go to the **Data Streams** tab.
2. Next to the deployed zero copy data stream, from the dropdown, select **Edit Data Stream**.
3. In the Database Configuration section, update the Target Database, Schema, and Table to match your environment.
4. Click **Save**.
Data 360 validates that the new target has the same schema definition as the original. If the schema differs, the operation fails.
# Update Node: Swap Column Values
You can swap column values with data from another data source when key pairs match with the update node. For example, to update selected account names after a series of recent acquisitions and mergers, replace the name from an uploaded spreadsheet based on matching account IDs. To minimize processing time, change column values with matching key pairs instead of every value in the column.
1. In a batch data transform that already has at least one input node, select **Add Node**  between two nodes or at the end of the data transform. To show the Add Node button between two nodes, hover the cursor on the connecting line.
2. In the Add Node dialog, select **Update**.
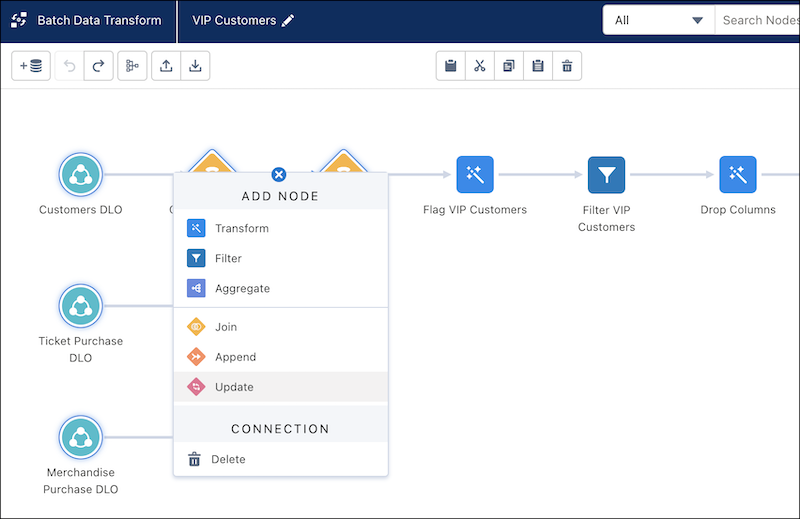
3. Choose the data source containing the update data. Alternatively, if the original and update data are already added as input nodes, drag **Add Node** () from one to the other and click **Update**. The two inputs are used as the source and update location.
4. Choose which key pair values must match between the original and update data.
5. Choose the columns to update. If all key pairs match for a row, the column value is updated.
6. Click **Apply**. When the batch data transform runs, the update node contains the original data with updated column values.
7. Save the data transform.
# Update the Send Relationship in the Activated Data Extension
Cumulus updates the send relationship in the activated data extension.
1. In Marketing Cloud Engagement, navigate to Audience Builder.
2. From the dropdown, select **Contact Builder**.
3. Click the **Data Extensions** tab.
4. Open the **Shared Items** folder.
5. Open the **Shared Data Extensions** folder, and then select the Data 360Segments folder.
6. Locate the **Omnichannel Credit Limit Alert** data extension, and click into it.
7. In the Type section on the left side, click **Edit**.
8. Update the default send relationship set by Data 360. Relate MobilePush Key to Subscriber Key.
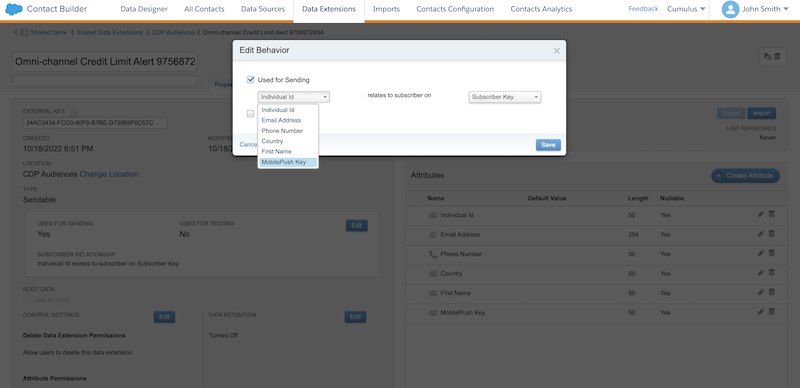
# Update your Connection’s Credentials After a Connection Failure
If you receive a notification that one or more Marketing Cloud Engagement connections has failed, update your credentials to fit the issue.
1. From Setup, in the Quick Find box, search for Marketing Cloud Engagement, and select **Marketing Cloud Engagement**.
2. To the right of your connection, click the down arrow and select **Edit**.
3. To the right of your credentials, click **Manage**.
4. Update your credentials.
# Update Your Snowflake Network Policy
To ensure access, modify your Snowflake network policy to include the Data Cloud virtual private cloud (VPC) endpoint ID.
### Required Editions
User Permissions
Needed
To create a Snowflake network route
Data Cloud Architect permission set OR
Manage External Connections or
Customize Application permission
To administer a Snowflake environment
Snowflake account administrator
1. To find your Data Cloud VPC Endpoint ID and Data Cloud DNS Name, go to the details page of the network route after it's provisioned.
2. (Data Federation) Create network rules based on their purpose and type of network identifier. Use `MODE=INGRESS TYPE=AWSVPCEID VALUE_LIST=('')`. See [Create network rules](https://docs.snowflake.com/en/user-guide/network-policies#label-network-policy-network-rules) and [Incoming requests](https://docs.snowflake.com/en/user-guide/network-rules#incoming-requests).
3. (Data Federation) Create a network policy that contain the identifiers including the rule: `CREATE NETWORK POLICY policy_salesforce_vpce_only ALLOWED_NETWORK_RULE_LIST = ('allow_salesforce_vpce');`. See [Create a network policy](https://docs.snowflake.com/en/user-guide/network-policies#label-network-policy-create-policy) and [Interaction between allowed lists and blocked lists](https://docs.snowflake.com/en/user-guide/network-policies#interaction-between-allowed-lists-and-blocked-lists).
4. (Data Federation) Apply the policy to the user connecting from Salesforce for a Java Database Connectivity (JDBC) based connection using the private network route: `ALTER USER SET NETWORK_POLICY policy_salesforce_vpce_only;`
5. (Data Share) Apply the policy to the Security Integration for Data Share Target (DST) using the PrivateLink URL: `ALTER SECURITY INTEGRATION SET NETWORK_POLICY = ;`. See [Create Security Integration](https://docs.snowflake.com/en/sql-reference/sql/create-security-integration).
# Use a Package Subscriber Org for Testing
When using a Developer edition org in the context of a packaged app, Salesforce uses the terms Packaging org and Package Subscriber org. The Packaging org is where the package is created. The Package Subscriber org is an org that has installed a package from a Packaging org. To speed up testing, developers can now install their package in another Dev org and manually trigger an activation publish.
### Required Editions
Available in: Lightning Experience
You need access to another Dev org that has Data 360 enabled and fully deployed.
1. Locate the installation URL of the package that you created.
After a successful package upload, the installation URL is displayed on the upload confirmation screen. Alternatively, to find it later, go to **Setup** > **Package Manager**, open your package, click the **Versions** tab, and then click the version number to view the installation URL.
2. Open the installation URL in a browser.
3. Enter the login credentials for the Dev org that you want to install this package in.
Select an org that is different from the one used to create the package, which becomes your Package Subscriber org.
4. Choose **Install for Admins Only**, select the check box for acknowledgment, and click **Install**.
5. After the package is installed, navigate to the Data 360 app in your Package Subscriber org.
6. Go to Data 360 Setup, under **External Integrations**, select **External Activation Platforms**.
7. Select the external activation platform and click **Enable** to use the platform for activations.
8. To test sending segments to your installed platform, create segments, activations, and targets.
9. Trigger an activation publish to inspect and validate the output files.
#### See Also
- [_Salesforce Help_: Create and Activate Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&release=264.0.0&type=5 "Use segmentation in Data 360 to break down your data into useful segments to understand, target, and analyze your customers. After you create a segment, you can publish it to an activation target.")
# Use a Package Subscriber Org to Trigger a Publish
To speed up testing, use the package subscriber org and manually trigger an activation publish to inspect and validate the output files.
### Required Editions
Available in: Lightning Experience
1. In Data 360, select Data 360 Setup.
2. Click **External Activation Platform**.
3. To view the package that you’ve installed from another packaging org, select the **Subscriber**.
To create an external activation platform entity to package and distribute your app, select **Developer**.
4. Select the external activation platform that you want to test.
5. In the details screen, click **Enable**.
6. Navigate back to the list of External Activation Platforms.
7. To trigger the activation, in the external activation platform’s dropdown menu, select **Publish Now**.
When a publish is triggered you must wait until the activation run completes before triggering another publish. You can publish up to 2 requests per hour and a total of 24 requests per day.
#### See Also
- [_Salesforce Help_: Create and Activate Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&release=264.0.0&type=5 "Use segmentation in Data 360 to break down your data into useful segments to understand, target, and analyze your customers. After you create a segment, you can publish it to an activation target.")
# Use a Record-Triggered Flow to Automate Actions when a Prediction Changes
Automatically perform actions when a record is created, updated, or deleted. Let's look at how to use a flow to create actions when a prediction score on a case updates and it exceeds the threshold, indicating a case escalation.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. From Setup, in the Quick Find box, enter Flows, and then select it.
2. Create a flow from scratch. Flow Builder launches.
3. Create a record-triggered flow.
4. Define the flow's object, trigger, and conditions. To queue records for processing even if there are system delays, choose an asynchronous path.
For example, you initiate the flow only for cases that are eligible for platinum support.
5. To assign values to variables in the flow, add the **Assignment** element.
For example, to update values for a case record, specify the case record variable.
6. To get data from an object and the inputs required to run the model, add the **Get Records** element.
For example, get account records associated with a case using the Account ID.
7. Add the **Action** element, and choose the predictive model that you want to use. Search for your model by its name or location in the Data Cloud action category.
For example, "Predicted Case Escalation" to predict the likelihood of a case escalation.
8. In the model inspector, get your model’s prediction threshold from AI Models.
9. Use the **Decision** element to add possible outcomes.
For example, if a case is likely to escalate, specify a Predict Case Escalation and the prediction score threshold. A record must exceed this value to initiate possible actions.
10. To receive notifications, add the **Notify** element.
For example, email the account team handling the case on what measures to take to resolve the escalation.
11. Save the flow.
12. After you test the flow, activate it.
You can now automatically initiate actions when a prediction score changes on your case record.
#### See Also
- [_Salesforce Help_: Provided Flow Core Actions](https://help.salesforce.com/s/articleView?id=platform.flow_ref_elements_actions_list.htm&type=5&language=en_US)
- [_Salesforce Help_: Data-Cloud Triggered Flow](https://help.salesforce.com/s/articleView?id=platform.flow_concepts_trigger_data_cloud.htm&type=5&language=en_US)
- [_Salesforce Help_: Flow Types](https://help.salesforce.com/s/articleView?id=platform.flow_concepts_type.htm&type=5&language=en_US)
- [_Trailhead_: Flow Builder Basics](https://trailhead.salesforce.com/content/learn/modules/flow-basics?trail_id=build-flows-with-flow-builder)
- [_Trailhead_: Record Triggered Flows](https://trailhead.salesforce.com/content/learn/modules/record-triggered-flows)
# Use a Screen Flow to Enrich Records with Predictions
Create a screen flow to get records from Salesforce objects and add a prediction to a Lightning page. For example, you can add a lead conversion prediction score to a lead record.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
Before you create a flow, ensure that your predictive model is activated in AI Models (formerly Einstein Studio).
1. From Setup, in the Quick Find box, enter Flows, and then select it.
2. Create a flow from scratch. Flow Builder launches.
3. Create a screen flow.
4. To get the inputs required to run the model, add the **Get Records** element.
For example, to get leads records.
5. For the data source, add a Salesforce or Data 360 object. Enter a label, API name.
In this case, select the Lead object.
6. (Optional) Filter records based on a condition, field, operator, and value.
For example, to predict leads by record ID, filter your data by selecting All Conditions Are Met (AND), Field=Id, Operator=Equals, and Value=Resource (a variable named recordid).
7. To use data that resides elsewhere, add another **Get Records** element, and enter the information.
8. Add the **Action** element, and choose the predictive model that you want to use.
For example, "Predicted Lead Conversion."You can search for your model by its name or location in the Data Cloud action category.
9. Because your model needs inputs to generate predictions, map the relevant fields.
For example, use the fields from the lead object that match your model inputs.
10. After you configure an action, a resource {ActionName.Prediction} is available to use in the flow.
11. To append a prediction score to your record page, add a screen interaction to the flow, and enter a label, API name, and resource.
For example, {!Predicted\_Lead\_Conversion\_Action\_1.Prediction}.
12. Save the flow.
13. Test the flow, and then activate it.
14. To view leads in your org, go to the App Launcher and enter Marketing CRM Classic.
15. Add the screen flow to a record page to show prediction scores on all leads records.
1. Go to Setup, and edit the object in Object Manager.
2. Use the Lightning Record pages to create a record page.
3. On the Components tab, search for Flow, and drag the component to your preferred location on the object.
4. Add the flow that you want to use on your object, and save to display the output from your flow.
#### See Also
- [_Salesforce Help_: Provided Flow Core Actions](https://help.salesforce.com/s/articleView?id=platform.flow_ref_elements_actions_list.htm&type=5&language=en_US)
- [_Salesforce Help_: Flow Types](https://help.salesforce.com/s/articleView?id=platform.flow_concepts_type.htm&type=5&language=en_US)
- [_Trailhead_: Flow Builder Basics](https://trailhead.salesforce.com/content/learn/modules/flow-basics?trail_id=build-flows-with-flow-builder)
# Use AI Models
AI Models is your home base for AI in Data 360. Augment your business intelligence with AI to identify, surface, and visualize inferences in yourData 360 data. AI is integrated into your Data 360 environment so that you can quickly operationalize generative models, predictions, and improvements with clicks, not code.

Note As of April 2026, Einstein Studio is now called AI Models. Learn more in the [release note](https://help.salesforce.com/s/articleView?language=en_US&id=release-notes.rn_cdp_2026_spring_predictive_ai_models_update.htm&release=260&type=5).
## Blogs, Videos, and Webinars
Hear directly from our product team and see features in action.
- Webinar: [Elevate Your AI Strategy with Google Vertex AI and Salesforce Data Cloud](https://events.actualtechmedia.com/on-demand/1869/elevate-your-ai-strategy-with-google-vertex-ai-and-salesforce-data-cloud/?pr=18)
- AWS re:Invent: [Unlocking the power of AWS AI and data with Salesforce](https://www.youtube.com/watch?v=E4FL67NMqjU)
## Additional Resources
- Learn more about AI model usage that impacts cost: [Billing Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_usage_inference.htm&language=en_US)
- Trailhead: [Machine Learning Predictions: Quick Look](https://trailhead.salesforce.com/content/learn/modules/machine-learning-predictions-quick-look)
- **[Set Up AI Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_license_perms.htm&release=264.0.0&type=5)**
To use AI Model Builder (formerly Einstein Studio Model Builder), your org must be provisioned with an applicable license, and users must be assigned the appropriate permission.
- **[Predictive AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive.htm&release=264.0.0&type=5)**
Predictive AI uses models built with machine learning (ML) and your historical data to predict business outcomes and recommend ways to improve predicted outcomes.
- **[Create, Connect, and Activate Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_create_connect_activate_models.htm&release=264.0.0&type=5)**
Create your own predictive models with clicks, not code. Establish connections to bring in generative and predictive AI from models outside of Salesforce. Then, activate models to use the inferences and insights revealed in your data.
- **[Manage Models](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_mm_manage_models.htm&release=264.0.0&type=5)**
After creating a predictive model, you can edit to update your settings or delete it if it’s no longer needed.
- **[Get Predictions, Prescriptions, and Top Predictors](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_utilize.htm&release=264.0.0&type=5)**
Put your predictive AI models into action. After a model is activated, use it to get inferences—predictions, prescriptions, and top predictors—from your Salesforce workflows. Get inferences on demand, in batches, and in streams. Use them in flows, prediction jobs, batch data transforms, agents, and prompt templates. Get them programmatically in Apex and REST applications.
- **[Retrieve Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever.htm&release=264.0.0&type=5)**
Use a retriever to search and return relevant data from a search index. Create and customize retrievers in AI Models (formerly Einstein Studio) for Retrieval Augmented Generation (RAG) in Data 360. Retrievers augment prompt templates by providing relevant, specialized grounding information for prompts.
# Use Amazon SageMaker Models
You can build, train, and deploy custom machine learning (ML) models with Amazon SageMaker and data in Salesforce. After registering a model in SageMaker, define your prediction criteria and connect the model with Data 360 to get predictions and insights for your use case. Use the insights to enrich customer profiles, create segments, and personalize experiences across various channels.
### Required Editions
Available in: Developer, Enterprise, Performance, and Unlimited editions.
Here are some benefits of using SageMaker models with Salesforce data.
- Access highly curated, harmonized, and near real-time data across Customer 360. This capability leads to expert models that deliver more intelligent predictions.
- Build models in SageMaker and easily connect them with Data 360 to consume predictive insights for business process optimization. Use cases include email engagement, propensity to buy, lead conversion, propensity to churn, and more.
- Operationalize models and inferences easily in Salesforce.Data 360 simplifies the consumption of results from business processes and drives value.
- Eliminate tedious, costly, and error-prone Extract, Transform, and Load (ETL) jobs from Amazon S3 using a zero-copy approach to data. This approach reduces costs and improves efficiencies for business.
- Integrate SageMaker models and get predictions in Salesforce. Use Flow, a workflow automation suite, to enable AI-driven decision-making that can evolve based on real-time updates to data.
To use a SageMaker model with Salesforce:
- Access your Data 360 data in SageMaker to build, train, and deploy a model.
- Connect your SageMaker model with Data 360 to consume the inferences for predictions and insights in various workflows across Salesforce.
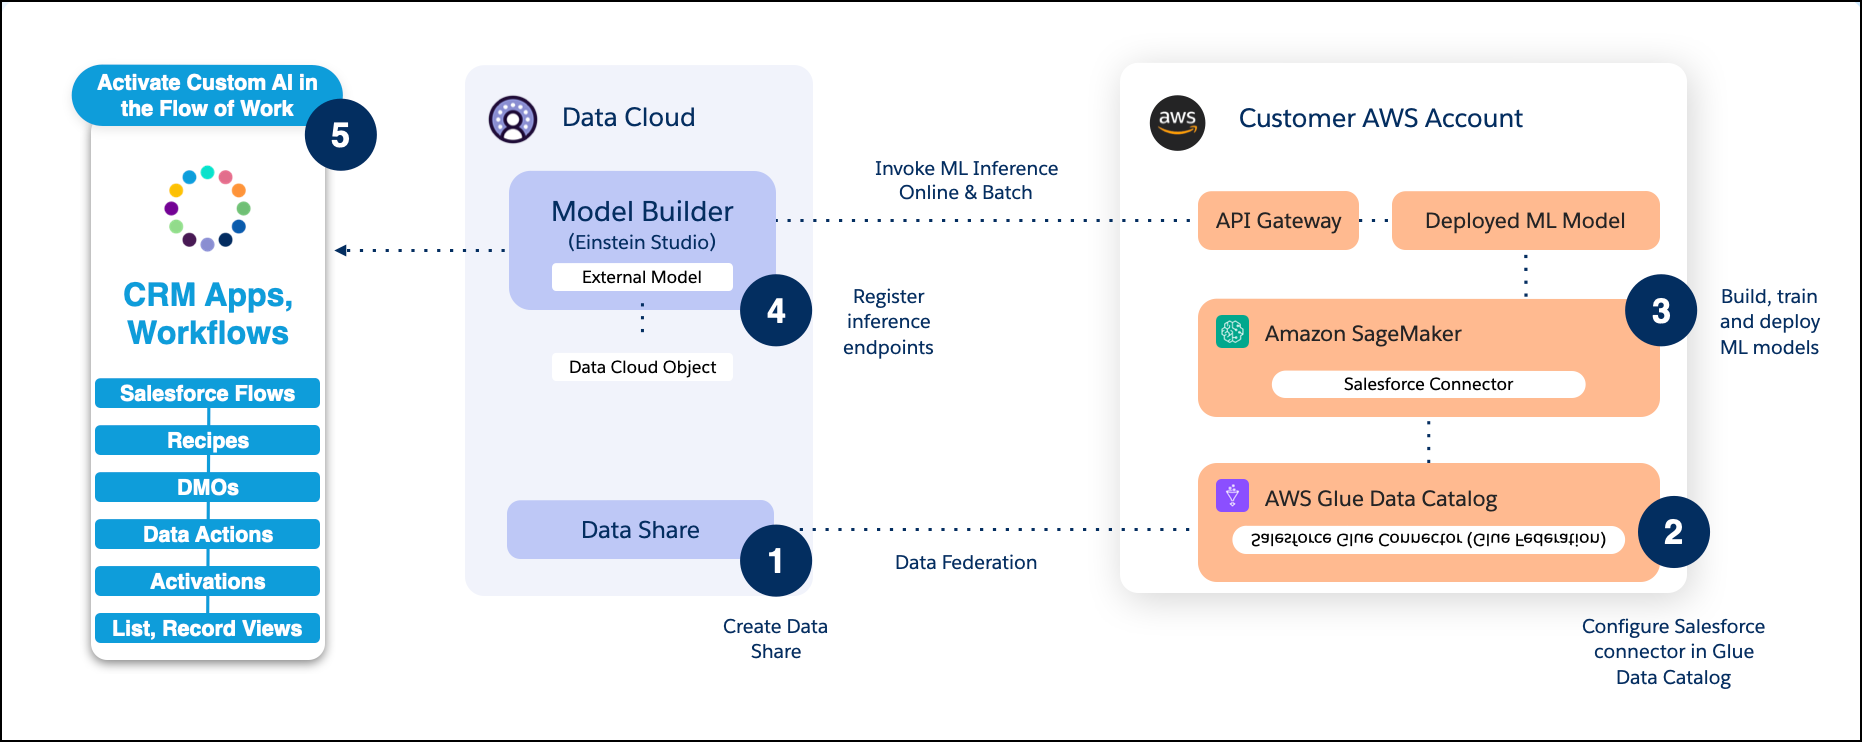
- **[Set Up Your Data in SageMaker](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_your_data.htm&release=264.0.0&type=5)**
Access Salesforce data from an Amazon SageMaker notebook using the Data 360 Python connector. The intuitive interface lets you quickly execute run queries and extract the data that you need.
- **[Connect a SageMaker Model](https://help.salesforce.com/s/articleView?id=data.c360_a_connect_your_external_model.htm&release=264.0.0&type=5)**
To consume your predictions in Salesforce, connect your SageMaker model with Data 360 and define the prediction criteria for your use case.
#### See Also
- [_External_: Bring your own AI using Amazon SageMaker with Salesforce Data Cloud](https://aws.amazon.com/blogs/machine-learning/bring-your-own-ai-using-amazon-sagemaker-with-salesforce-data-cloud/)
# Use an Activation Template When Creating an Activation
Use an activation template when creating an activation to automatically fill in settings like contact points, source priority, filters, and enrichment data. You can then review and adjust these settings before saving your activation.
### Required Editions
User Permissions Needed
To use an activation template:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
Before you use a template during activation creation, at least one activation template must exist that matches the target platform and DMO for your activation.
When you create a new activation, select an existing activation template to use as a starting point. The template prefills the activation's configuration with the stored contact point selection, source priority, filters, and enrichment settings. You can then review, adjust, and save the activation. The template acts as a one-time blueprint. After you save the activation, changes to the template don't affect the activation.
1. In Data 360, go to **Activations** and click **New**.
2. Select **Segment** or **data model object (DMO)**and click **Continue**.
3. In the New Activation dialog, complete these fields.
- **Data Space**: Select the data space for this activation.
- **Segment or DMO**: Select the entity to activate.
- **Activation Target**: Select the destination platform.
- **Activation Membership**: Select the entity to use as the basis for activation.
- (Optional) **Activation Template**: Search for and select a template.

Note Only templates with the same DMO and activation platform appear in the list.
4. Click **Continue**.
5. Review the activation configuration prefilled from the template and adjust any settings as needed, including contact points, source priority, and enrichment attributes.
6. Add a name and an optional description.
7. Click **Save**.
The activation is created with the configuration from the selected template. After saving, the activation operates independently. Future changes to the template don't affect this activation.
# Use an Alias for a Salesforce CRM Connection
As of July ‘24, an alias is required when setting up a Salesforce CRM connection. Existing connections aren't assigned an alias. The names of the data stream and data lake object are derived from the alias.
When you create an alias for the Salesforce CRM connection, the default data stream name and data lake object name are appended with the alias that you create. For example, if the connection is to the org MyCompany and the alias is SourceOrg, the data steam name and data lake object label for the Account are Account\_SourceOrg.
For connections that were created before the alias feature was available, no alias is assigned and the default data stream name and data lake object API name are appended with the org ID of the data source. For example, if the connection is to the org MyCompany and the org ID is 00DOK00129XWZ, the data stream name and data lake object name for the Account are Account\_00DOK00129XWZ.
By default, your home org connection is given the alias Home when the org is provisioned with Data Cloud.
You define the alias during the connection creation process. Select a name carefully, because after the connection is established, the alias can't be changed.
# Use Automatic Tag Suggestions in Data 360
Data 360 suggests tags by analyzing the metadata of objects and fields, such as their names and types. This helps streamline tagging by providing intelligent, context-aware suggestions without scanning the actual data.
### Required Editions
| User permission needed | |
| --- | --- |
| To suggest tags: | Data Cloud Architect permission set |
1. In Data Cloud, go to the Data Governance tab.
2. Click **Suggest Tags**.
3. To suggest tags, select the object type.
4. If you select a data model object or a calculated insight object, select a data space.
5. Search for the object, and click **Next**.
6. Review the selected objects, and click **Suggest Tags**.
While tag suggestion is in progress, you can’t add or delete tags to the selected objects or their fields.
# Use Case 1: Create a State-Specific Primary Address Flag
This use case creates a flag for customers who live in a specific state.
| Raw Data | Goal |
| --- | --- |
| The field City State in the format: City, State Abbreviation. For example, San Francisco, CA, or New York, NY. | Create the formula field “Is California” with {TRUE, FALSE} values. Return TRUE if the State Abbreviation is “CA”. |
1. For Field Label, enter Is California.
2. For Formula Return Type, select **Text**.
3. In the syntax editor, enter the formula: IF(EXTRACT(sourceField\['City State'\], ",", 1) == "CA", "TRUE", "FALSE").
Use the == operator to check the equality or difference between values on both sides of the operator.
4. In the test input box, validate the formula using these combinations.
- “City State” with the value of “San Diego, CA” returns “TRUE”.
- “City State” with the value of “Los Angeles, CA” returns “TRUE”.
- “City State” with the value of “New York, NY” returns “FALSE”.
5. Click **Save**.
6. Verify that “Is California” is added as a field.
#### See Also
- [_Salesforce Help_: Supported Library Functions](https://help.salesforce.com/s/articleView?id=data.c360_a_supported_library_functions.htm&release=264.0.0&type=5 "In the Data 360 data library, you can choose functions and operators. You can nest functions.")
# Use Case 1: Loyalty Status SMS Notification
Cumulus Bank and Financial Services want to send an SMS message to customers who have earned a new loyalty status.
Let's review the solution steps for this campaign.
## Establish Campaign Requirements
- **Identify campaign goals**
- Send an SMS notification when a customer’s reward status has changed.
- The campaign is ongoing, regularly adding customers who meet the criteria.
- **Identify personalization components**
- SMS includes the customer’s first name and their previous and new loyalty status.
- **Identity audience and data sources**
- Active customers whose loyalty level has changed in the past 7 days.
- Unified Individual, Loyalty Program Member, and Loyalty Member Tier data sources.
- **Gather campaign materials**
- Compose the copy for the SMS message in Marketing Cloud Engagement.
# Use Case 2: Create a Primary Key Using a Composite Key
This use case creates a composite key and sets a formula field as the primary object.
An order can have several products, and the same product can exist in multiple orders. Order Confirmation Number and Product ID can also have a many-to-many relationship.
| Raw Data | Goal |
| --- | --- |
| The fields Order Confirmation Number and Product ID. The combination of these two fields uniquely identifies a row. | Create the formula field “Unique ID” that concatenates Order Confirmation Number with Product ID. Set the Unique ID as the Primary Key in Object Details. |
1. For Field Label, enter Unique ID.
2. For Formula Return Type, select **Text**.
3. In the syntax editor, enter the formula: CONCAT(sourceField\[‘Order Confirmation Number’\], "\_", sourceField\[‘Product ID’\]).
4. In the test input box, validate the formula using these combinations.
- “Order Confirmation Number” with value of “A43JCT” and “Product ID” with value of “soap” returns “A43JCT\_soap”.
- “Order Confirmation Number” with value of “A43JCT” and “Product ID” with value of “cookie” returns “A43JCT\_cookie”.
- “Order Confirmation Number” with value of “PT56CG” and “Product ID” with value of “soap” returns “PT56CG\_soap”.
5. Click **Save**.
6. Verify that “Unique ID” is added as a field.
7. In the Primary Key dropdown, select **Unique ID**.
# Use Case 2: Loyalty Status App Push Notification
Cumulus Bank and Financial Services wants to use MobilePush to send an app notification to customers who have reached Gold loyalty status, and they're eligible to redeem a $100 gift card from their favorite food delivery service.
Let's review the solution steps for this campaign.
## Establish Campaign Requirements
- **Identify campaign goals**
- Send an app notification when a customer's reward status changes to Gold.
- As a reward for becoming a Gold member, inform customers of the redeemable gift card.
- The campaign is ongoing, regularly adding customers who meet the criteria.
- **Identify personalization components**
- The app message includes the customer's first name, previous loyalty status, new loyalty status, and the gift card reward bonus.
- **Identity audience and data sources**
- Active customers whose loyalty level has changed in the past 7 days.
- Unified Individual, Loyalty Program Member, and Loyalty Member Tier data sources.
- **Gather campaign materials**
- Compose the copy for the app message in Marketing Cloud Engagement.
# Use Case 3: New Auto Policy Welcome Series
Cumulus Bank and Financial Services wants to create a three part journey to welcome new auto policy holders that introduces them to their policy and benefits.
Let's review the solution steps for this campaign.
## Establish Campaign Requirements
- **Identify campaign goals**
- After a customer is added to the journey, send a welcome email to the new auto policy holder. Send a follow-up email 3 days later, and then a final email 5 days later.
- The campaign is ongoing, regularly adding new customers.
- **Identify personalization components**
- The first email includes the customer’s first name, auto policy number, and start date.
- The second and third emails include the customer’s first name.
- **Identity audience and data sources**
- Customers with an active auto policy created in the past 30 days.
- Unified Individual, RA\_PolicyInformation\_02, RA\_PolicyProducts, and RA\_Account02 data sources.
- **Gather campaign materials**
- Create the design for the three auto policy emails in Marketing Cloud Engagement.
# Use Case 3: Set a Hard-Coded Value for the Organization Unit Identifier
This use case sets a hard-coded value for the Organization Unit Identifier in Object Details and allows you to specify a business unit in your Data 360 data.
| Raw Data | Goal |
| --- | --- |
| Raw data doesn’t have any reference to the business unit, but every row of data comes from the Finance Department. | Create the formula field “Business Unit” with the hard-coded value “Finance Department”. Set the Business Unit as the Organization Unit Identifier in Object Details. |
1. For Field Label, enter Business Unit.
2. Select Text for the Formula Return Type.
3. In Tranformation Formula, enter “Finance Department” or ’Finance Department'.
4. Click **Save**.
5. Verify that “Business Unit” is added as a formula field.
6. In the Organization Unit Identifier dropdown, select **Business Unit**.
# Use Case 4: Convert Hours in the Day to Day Parts
This use case converts hours in the day into day parts; for example, morning or afternoon.
| Raw Data | Goal |
| --- | --- |
| Column named Hour of Day. | Create the formula field “Day part” that assesses the hour of the day and determines if the value is Morning, Midday, Afternoon, Evening, or Overnight. |
1. For Field Label, enter Day part.
2. For Formula Return type, select Text.
3. In the syntax editor, enter the formula: IF(sourceField\['Hour of Day'\] >= 6 && sourceField\['Hour of Day'\] < 10, 'Morning', IF(sourceField\['Hour of Day'\] >= 10 && sourceField\['Hour of Day'\] < 15, 'Midday', IF(sourceField\['Hour of Day'\] >= 15 && sourceField\['Hour of Day'\] < 19, 'Evening', IF((sourceField\['Hour of Day'\] >= 19 && sourceField\['Hour of Day'\] < 24) || (sourceField\['Hour of Day'\] >= 0 && sourceField\['Hour of Day'\] < 6), 'Overnight', "Unclassified")))).
If the raw data doesn’t have a separate column for Hour of Day, you can use the same formula by reading in a Date with Timestamp and parse out the timestamp.
4. In the test input box, validate the formula using these combinations.
- “Hour of Day” with the value of “6” returns “Morning”.
- “Hour of Day” with the value of “12” returns “Midday”.
- “Hour of Day” with the value of “18” returns “Evening”.
- “Hour of Day” with the value of “19” returns “Overnight”.
- “Hour of Day” with the value of “23” returns “Overnight”.
- “Hour of Day” with the value of “0” returns “Overnight”.
- “Hour of Day” with the value of “5” returns “Overnight”.
5. Click **Save**.
6. Verify that “Day part” is added as a new field.
# Use Case 5: Calculate Revenue
This use case calculates revenue by a defined margin.
| Raw Data | Goal |
| --- | --- |
| Column named Revenue. | Create the formula field “Revenue Plus Margin” and add a 5% margin to the revenue. |
1. For Field Label, enter Revenue Plus Margin.
2. For Formula Return Type, select Number.
3. In the syntax editor, enter the formula: sourceField\[‘Revenue’\]\*1.05.
4. In the test input box, validate the formula using this combination.
- “Revenue” with the value of “10” returns “10.5”.
5. Click **Save**.
6. Verify that “Revenue Plus Margin” is added as a field.
# Use Case 6: Add the Date and Time Field to Engagement Streams
This use case locates engagement streams that have no set date and updates them since a date is required.
| Raw Data | Goal |
| --- | --- |
| Raw data has no date, but you want to set the data as Category = “Engagement”. | Create the formula field “Today’s Date” and set the formula to the “Event Date & Time” on Object Details. |
1. For Field Label, enter Today’s Date.
2. For Formula Return Type, select Date.
3. In the syntax editor, enter the formula: TODAY().
4. Click **Save**.
5. Verify that “Today’s Date” is added as a field.
6. In Object Details, select the new field for Event Date & Time.
# Use Case 7: Create Required Party Identifier Formula Fields for Mobile
This use case creates required party identifier formula fields to match on the Identity data stream.
Mobile App has implemented both Data 360 and MobilePush (in Marketing Cloud Engagement) modules of the Engagement Mobile SDK. This use case demonstrates a match based on mobile registration ID.
| Raw Data | Goal |
| --- | --- |
| deviceId | Create formula fields to match anonymous mobile users based on a shared registration ID across Data 360 and MobilePush and to enable anonymous user activation to Marketing Cloud Engagement. |
1. Create the Party Identification Type field on the Identity data stream.
1. For Field Label, enter Party Identification Type.
2. For Formula Return Type, select Text.
3. For Value, select App Identifier.
2. Create the Party Identification Name field on the Identity data stream.
1. For Field Label, enter Party Identification Name.
2. For Formula Return Type, select Text.
3. For Value, select Mobile SDK Shared Identifier.
3. Create the Party Identification ID field on the Identity data stream.
1. For Field Label, enter Party Identification ID.
2. For Formula Return Type, select Text.
3. For Value, select CONCAT(sourceField\['deviceId'\], "\_","Mobile SDK Shared Identifier", "\_","Person identifier").
# Use Case: Cumulus Bank and Financial Services Event-Triggered Journeys
Cumulus Bank and Financial Services want to integrate Data 360 with Marketing Cloud Engagement. They’re using Data 360 to establish a data foundation in Marketing Cloud Engagement. They then want to use the data foundation as part of their campaigns, including their initial customer campaign: a 30-day journey to welcome new auto policy holders and to introduce them to their policy and benefits.
# Use Case: Enhance Paid Media Campaigns with First-Party Data
A marketing team wants to activate their existing MCE Data Extensions to paid media channels for more targeted advertising campaigns. They need to ingest their MCE data into Data Cloud, create audience segments in Data Cloud, and activate the segments to platforms such as Google Ads and Meta.
### Required Editions
## (Optional) Step 1: Generate the Ad Activation Report
The Ad Activation report provides a comprehensive overview of your active Marketing Cloud Advertising audiences. Use this report to simplify your migration from Marketing Cloud Ads to Data Cloud Ads. The report is generated as a Data Extension, so you can ingest it into Data Cloud.
1. In Ad Studio, select **Ad Activation Report** in the Administration tab.
If a report was generated in the past, the new report indicates the date when the previous report was generated. You can access the new report under the Data Extensions tab in Email Studio or Contact Builder. The format of the report name is AdvertisingAudiences-ReportKit-{EID}-{MID}.
2. For enterprise accounts, if you want to include data from all business units in a single report, select the **Include all Business Units** option.
3. Click **Generate Report**. The report can take 30 minutes to be generated. When the report is complete, its status changes from “In Progress” to “Done”.
4. After the report is generated, you can download the report or ingest it in Data Cloud.
- Click **Export** to export the report.
- [Create a data stream by using the Marketing Cloud connector](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_data_extension.htm&type=5&language=en_US) to ingest the report in Data Cloud.
After creating the data stream, map it to a custom Data Model Object (DMO). You can then view your Advertising Audiences data as a Data Cloud report or create an AI agent to analyze the data and optimize the transfer.
## Step 2: Ingest and Map Marketing Cloud Data to Data Cloud
Start by connecting MCE to Data Cloud and then create a data stream to ingest data into Data Cloud.
1. [Set Up a Marketing Cloud Engagement Connection in Data Cloud.](https://help.salesforce.com/s/articleView?id=data.c360_a_set_up_marketing_cloud_connection.htm&type=5&language=en_US)
2. [Create a Data Stream from a Marketing Cloud Engagement Data Extension.](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_data_extension.htm&type=5&language=en_US)
3. [Map your Data Lake Objects (DLOs) to Data Model Objects (DMOs)](https://help.salesforce.com/s/articleView?id=data.c360_a_map_custom_data_model_objects.htm&type=5&language=en_US) to enable segmentation and activation.
You can use only mapped fields and objects with established relationships for segmentation and activation.
## Step 3: Create Activation Targets and Activate Segments
An activation target stores authentication and authorization information for the platform on which you want to activate your audience segments.
Here are the platforms supported for activation.
- Google Ads
- Meta (Facebook)
- LinkedIn
- Amazon Ads
- SnapChat
1. [Create an External Activation Target](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activation_target.htm&type=5&language=en_US) for your paid media platforms.
See [Platform-Specific Requirements for External Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_requirements_for_external_activation_targets.htm&type=5&language=en_US) for setup details on each supported platform.
2. [Create Standard Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_segment.htm&type=5&language=en_US) to break down your data. Consider your campaign goals and how you want to group your audiences before creating segments.
3. [Create an Activation](https://help.salesforce.com/s/articleView?id=data.c360_a_create_external_activation_platform_activations.htm&type=5&language=en_US) for an External Platform to activate segments to paid media platforms.
## Step 4: Access Your Audiences on Paid Media Platforms
Add the target user segment to your advertising campaigns.
1. Log in to the account for your paid media platform (for example, Google Ads or Meta).
2. Navigate to your audience or customer lists section.
3. Locate your audience by using the name you assigned during activation.
4. Add your audience to your advertising campaigns.
For segments activated to Google Ads or Amazon Ads, access audience insights directly within Data Cloud:
- [Google Ads Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_google_insights.htm&type=5&language=en_US)

Note Google Ads insights are typically available 5 to 7 days after activation.
- [Amazon Ads Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_google_insights.htm&type=5&language=en_US)
- LinkedIn Insights
# Use Cases for Predictive AI Solutions
Here are some functional and industry use cases to consider for predictive AI solutions.
## Functional Solutions
Function
Candidate Use Cases
Sales
Increase conversion
Improve win probability
Decrease time to close
Predict expected revenue
Decrease churn probability
Improve sales rep performance
Increase contract renewals
Increase quote acceptance
Increase repeat business
Increase lifetime value
Read more at Sales Use Cases for Predictive AI Solutions .
Marketing
Most likely to purchase
Email campaign target
Improve media spend
Increase advertising ROI
Increase conversion
Read more at Marketing Use Cases for Predictive AI Solutions
Service
Likelihood of escalation
Increase compliance with SLA
Minimize risk of churn
Increase CSAT/NPS
Decrease TTR
Reduce handle time
Improve agent performance
Finance
Forecast revenue
Decrease late payments
Increase invoice fulfillment
Decrease returns
Maximize margin
Maximize cost reduction
Reduce attrition
Reduce compliance risk
Improve margin
Human Resources
Improve employee productivity
Reduce employee attrition
Maximize lead scoring
Likelihood to secure a hire
Improve candidate targeting
Identify top performers
Operations
Improve inventory management
Improve network utilization
Increase on-time delivery
Maximize cost reduction
Maximize resource optimization
## Industry Solutions
Industry
Candidate Use Cases
Consumer Goods
Increase expected revenue by store location/promotion/brand
Likelihood of stock-out
Likelihood of cross-sell/upsell
Increase field rep productivity
Increase average order value
Intelligent markdowns
Improve utilization
Maximize loyalty score
Financial Services
Likelihood to grow
Likelihood to increase AUM
Improve operational costs
Reduce insurance agent attrition
Reduce compliance risk
Reduce credit risk
Manufacturing
Improve inventory management
Improve network utilization
Increase on-time delivery
Maximize cost reduction
Resource optimization
Health Care and Life Sciences
Reduce readmission risk
Reduce canceled visit rate
Increase referral conversion
Reduce wait/cancellation
Improve claims routing
Improve utilization
Improve program completion
Improve inventory management
Improve network utilization
Increase on-time delivery
Maximize cost reduction
# Use Clustering on Structured Data
Use clustering models in Data 360 to automatically group data model object (DMO) records by shared characteristics. Run a predict job or batch data transform to assign new records to saved clusters, and use the results across Salesforce.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
Before you begin:
- Build and activate a clustering model in the AI Models tab in Data 360.
- Make sure that you use a DMO with structured data.
Tips:
- Use scores to rank or filter records by confidence. If a record has a low cluster score, it can be a poor fit for its assigned cluster.
- Cluster label names reflect what you set during model setup. To change labels, edit the clustering model and rerun the transform.
## Map Records to Clusters with a Predict Job
Use a predict job to run inference and map new records to clusters in a DMO.
1. From Data 360, go to the AI Models tab, and click the activated clustering model.
2. On the Integrations tab, select **Add Job**. Predict Job Builder opens.
3. Set the model inputs using a DMO, and map its fields to the model’s variables.
4. Define the output DMO. Optionally, specify how many top contributors to include.
5. Schedule a streaming or batch job.
6. Save the job.
7. Activate and run the predict job.
## Run Clustering with a Data Transform
Use a batch data transform to apply cluster labels to new data in a DMO.

Important
Deleting the clustering model removes all downstream transform jobs. Before you delete the model, delete all associated transforms.
1. From Data 360, go to the AI Models tab, and click the activated clustering model.
2. On the Integrations tab, select **Add Transform**.
3. In the transform setup, select the structured DMO that contains the records you want to assign to clusters.
4. Map the DMO fields to the corresponding fields used during model training.
5. Configure the output DMO settings.
- DMO name: The name of the output DMO.
- Cluster ID: The name for the cluster ID field (the API name is set automatically and you can't change it).
- Cluster Label: A descriptive label that summarizes the records in the cluster.
6. Configure up to 3 top contributors to include in the output.
7. Activate and run the predict job.
8. Save and run the transform.
# Use Data 360 Data in Tableau
Tableau enables metadata and data discovery of all objects in your Data 360 instance with Salesforce security mode.
### Required Editions
Available in: Lightning Experience
The Data 360 Tableau connector provides two modes for interacting between products: live and extract. You can select your mode in Tableau when setting up your connection by choosing the Live or Extract radio buttons available for selection after a table has been dragged into the “Need More data?” section. It’s suggested that you determine your desired connection and don’t change your mode after you have begun initial execution of your queries.
Live mode is the default, but each mode and we strongly recommend using a live connection when querying data from Tableau.
## Data 360 Objects in Tableau
All Data 360 objects are accessible in Tableau by querying the authorized tenant and exposing the objects to Tableau after authentication is complete. Data from Data 360 includes data model objects (DMO), data lake objects (DLO), and calculated insights (CIO). All end-user modeled data is suffixed with dlm. System-created data like calculated insights objects are suffixed with a cio. Match and merge tables are suffixed with \_\_dlm. Tables that include identity link in the name are exposed to Tableau.
To build Tableau visualizations from unified data, identity link files are required to be included in the mapping in Tableau. Drag your objects from the sidebar to the Tableau canvas to map them.
In the above image, numerous tables are being joined to visualize several data points in Data 360, starting with the Unified Individual Table. In order to understand the Calculated Insights called purchase insights that were defined on the unified individual, it’s mapped to the unified individual table. However, Tableau must traverse the graph to get to a place where it can handle the relationships across all the tables. For cases where you have a unified individual and you want to map it to an individual, you must map the individual identity link, which is a system-created bridge table that comes from the match and merge process and maps the individual ids to the unified individual ids. After the individual table has been mapped, all tables that map to it can be mapped. In this case, contactpointaddress, deviceapplication, SalesOrder\_\_dlm, segment\_membership, and websiteengagement. These are all \_dlms that can be mapped to the individual\_\_dlm.
Finally, salesorderproduct can be mapped to SalesOrder\_\_dlm. These joins are all loosely defined as joins, not unions. However, Tableau doesn’t determine how the joins occur under the defined visualization. Tableau sends a query to Data 360 to get the data in a defined fashion relative to the mapped tables.

Note The Data 360 query engine supports consumer rights at query execution time. When dashboards are published, ensure that any changes made to your Data 360 data as a result of consumer rights requests, such as Right to be Forgotten or Restriction of Processing, are reflected in Tableau.
## Mapping Unified Individual Data Model Objects
Use a Tableau relationship when you define a relationship between a Unified Individual Data Model Object (DMO) and DMOs that represent performance and interaction data from Marketing Cloud Engagement or cases from Service Cloud. You must also map the individual identity link using Tableau join for every engagement entity as shown in the screenshots here. It makes sure your queries fetch data from all objects that are mapped to the Unified Individual. For more information, see [Tableau Relationships vs Joins](https://help.tableau.com/current/online/en-us/datasource_relationships_learnmorepage.htm).

## Downloading Tableau Data Source File
You can download already modeled relationships for your selected data object from Data 360. You can download the data models in the form of a Tableau data source file and import it for data exploration.
- - Click **Data Model** tab in Data 360.
- Select one object at a time and click **Download Tableau Data Source File** button.
- Download the file on your local machine as a .tds file.
- Import the file in Tableau Desktop or Tableau Server for further data explorations.
## Fully Qualified Keys in Tableau
Fully Qualified Keys (FQKs) are composite keys that are used as the primary keys in Data 360. FQKs help resolve key conflicts that arise when data from different source systems is brought into Data 360. Keys can conflict when data is harmonized into one data model object.
All keys include two components.
- The primary key provided by the data source.
- The key qualifier that’s configured within Data 360.
When you build your own data model in Tableau using data from Data 360 check if the data has key qualifiers enabled. For adhoc table joins, you must include the key qualifier field to use a composite key. Add `IFNULL()` function in joins if the key qualifiers aren’t configured in Data 360.
The Tableau Data Source file contains all the relationships that are defined in Data 360 data model. If key qualifiers are enabled in your Salesforce org then they're automatically included in the relationships for the data model. Null values in key qualifiers are also handled with `IFNULL()` function.
For more information, see [Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_fully_qualified_keys.htm&release=264.0.0&type=5 "Use Fully Qualified Keys (FQK) to avoid key conflicts when data from different sources are harmonized in the Data 360 data model.")
#### See Also
- [_Salesforce Help_: Data Model Concepts](https://help.salesforce.com/s/articleView?id=data.c360_a_understanding_and_using_the_data_model.htm&release=264.0.0&type=5 "Improve the interoperability of data across applications, and map data between your connected data sources and the Data 360 Customer 360 Data Model.")
- [_Tableau Help_: Get Started](https://help.tableau.com/current/pro/desktop/en-us/gettingstarted_overview.htm)
# Use Data 360 Data Spaces to Organize Data in Tableau
Use data spaces to segregate your data, metadata, and processes into categories, such as brand, region, or department. Set up permissions so that users can see and work on data only in the context of their brand or region.
### Required Editions
Available in: Tableau Desktop, Tableau Prep, and Tableau Cloud
To access data spaces requires:
- The Salesforce Data Cloud connector to connect Tableau and Data 360
- Tableau version 2023.2 or Tableau Cloud
The Data Spaces available in Tableau are based on the OAuth login that is used to connect to the Data 360. For example, if a user John Doe is assigned to data space AMER in Data 360, then John Doe would see only Data Space AMER in the dropdown in Tableau UI. If you're using the Customer Data Platform connector to connect Tableau and Data 360 you see a default data space. A default data space includes all the data lake objects, data model objects, and calculated insights available in Data 360.
1. Log in to Tableau.
2. Select the Salesforce Data Cloud connector.
3. Authenticate with Data 360.
4. If you’re already logged in to Data 360, you’re automatically authenticated using the browser mode.
5. From the Data Space dropdown, select the applicable data space or choose the default data space.
A list of tables that use the selected data space appears.
#### See Also
- [_Salesforce Help_: Data Spaces in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_spaces.htm&release=264.0.0&type=5 "A data space is a logical partition to organize your data for profile unification, insights, and marketing in Data 360. You can segregate your data, metadata, and processes into categories, such as brand, region, or department, and then enable users to see and work on data only in the context of their category. You can also merge and analyze data in data spaces.")
# Use Data 360 Data Throughout Marketing Cloud Engagement
It’s important for Marketers to understand that their interaction with the data foundation varies based on the type of campaign that they’re activating. These recommendations maximize system performance.

Note See [Audience-Based Journeys](https://help.salesforce.com/s/articleView?id=data.c360_a_create_marketing_cloud_activation.htm&release=264.0.0&type=5 "After you create a segment in Data 360, you can publish it to an activation target.")
Using Data Extensions for Journey Entry
_Content Personalization_
When activating audiences from Data 360, we recommend including all attributes that are required to personalize the content throughout the targeted journey.
_Journey Decisioning_
When activating audiences from Data 360, we don’t recommend including attributes for journey decisioning. Instead, use the commonly shared attributes that have been established as part of the data foundation (the core Individual or Unified Individual data extensions) for the journey’s decisions and exit activities.
In an ad hoc journey scenario that requires decisioning attributes that aren’t already included in the data foundation, consider either:
- Updating the existing data foundation by including the required decisioning attributes in an existing activation used as part of the data foundation.
- Activating the audience with all attributes required for the journey for personalization and decisioning. Then temporarily connect the resulting data extension to the data foundation via the SF CDP Ad Hoc attribute group in the Engagement Contact Model.
Event-Triggered Journeys Using Data Actions or API for Journey Entry
_Content Personalization_
By default, event-triggered journeys use static [journey data](https://help.salesforce.com/s/articleView?id=mktg.mc_jb_journey_contact_data.htm&type=5&language=en_US) for content personalization. To use refreshed Contact Data for these journeys, use the personalization feature in Journey Builder or [AMPscript](https://trailhead.salesforce.com/content/learn/modules/marketing-cloud-programmatic-languages/explore-ampscript) to reference the personalization attributes established in the data foundation you already created.
_Journey Decisioning_
When activating audiences from Data 360, we don’t recommend including attributes for journey decisioning. Instead, use the commonly shared attributes that have already been established as part of the data foundation for the journey’s decisions and wait and exit activities.
In an ad hoc journey scenario that requires decisioning attributes that aren’t already included in the data foundation, consider either:
- Updating the existing data foundation by including the required decisioning attributes in an existing activation used as part of the data foundation.
- Activating the audience with all attributes required for the journey for personalization and decisioning. Then, temporarily connect the resulting data extension to the data foundation via the SF CDP Ad Hoc Attribute Group in the Engagement Contact Model.
# Use Data Cloud APIs with Data Spaces
To use Salesforce Data Cloud APIs, you must be authenticated. Create an external client app to authenticate and request access to the Data 360 APIs.
### Required Editions
User Permissions
Needed
To use data cloud APIs:
System admin profile OR
Data Cloud Architect permission set
With data spaces, while using any of the Data 360 APIs, follow these additional steps as needed:
- Exchange Salesforce access token for Data 360 token: In the exchange token, specify the body parameter “dataspace” and provide the data space name as the value. Use this Data Cloud token to invoke any Data 360 API.
- Configure an SQL client and Python Connector.
- For an SQL client to run with the data space;
1. Right-click a connection and select **Edit Connection**.
2. For Driver properties, specify a user property “dataspace” and enter the data space name that you want to query.
- For [Python Connector](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_api_python_connector.htm), while creating a connection object provide the additional parameter “dataspace” and enter the data space name that you want to query.
- For any Data Cloud Connect APIs, provide the data space name as the extra parameter in the request.
ConnectApi.CdpQueryOutputV2 cdpOut = ConnectApi.CdpQuery.queryAnsiSqlV2(input, "dataspace\_name");
#### See Also
- [_Salesforce Developer_: Create a Connected App](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_getting_started_with_cdp.htm)
- [_Salesforce Developer_: Acquire and Exchange Your Access Token](https://developer.salesforce.com/docs/atlas.en-us.c360a_api.meta/c360a_api/c360a_getting_started_with_cdp.htm)
# Use Databricks Models
You can build, train, and deploy custom machine learning models with Databricks and data in Salesforce. After registering a model in Databricks, define your prediction criteria and connect the model with Data 360 to get predictions and insights for your use case. Use the insights to enrich customer profiles, create segments, and personalize experiences across various channels.
### Required Editions
Available in: Developer , Enterprise , Performance , and Unlimited editions
Here are some benefits of using a Databricks model with Salesforce data.
- Access highly curated, harmonized, and near real-time data across Customer 360. This capability leads to expert models that deliver more intelligent predictions.
- Build models in Databricks and easily connect them with Data 360 to consume predictive insights for business process optimization and drive value. Use cases include propensity to buy, lead conversion, propensity to churn, and more.
- Operationalize models and inferences easily in Salesforce.Data 360 simplifies the consumption of results from business processes and drives value.
- Eliminate tedious, costly, and error-prone Extract, Transform, and Load (ETL) jobs from Databricks using a zero-copy approach to data. This approach reduces costs and improves efficiencies.
- Integrate Vertex AI models and get predictions in Salesforce. Use Flow, a workflow automation suite, to enable AI-driven decision-making that can evolve based on real-time updates to data.
To use a Databricks model with Salesforce:
- Access your Data 360 data in Databricks to build, train, and deploy a model.
- Connect your Databricks model with Data 360 to consume the inferences for predictions and insights in various workflows across Salesforce.
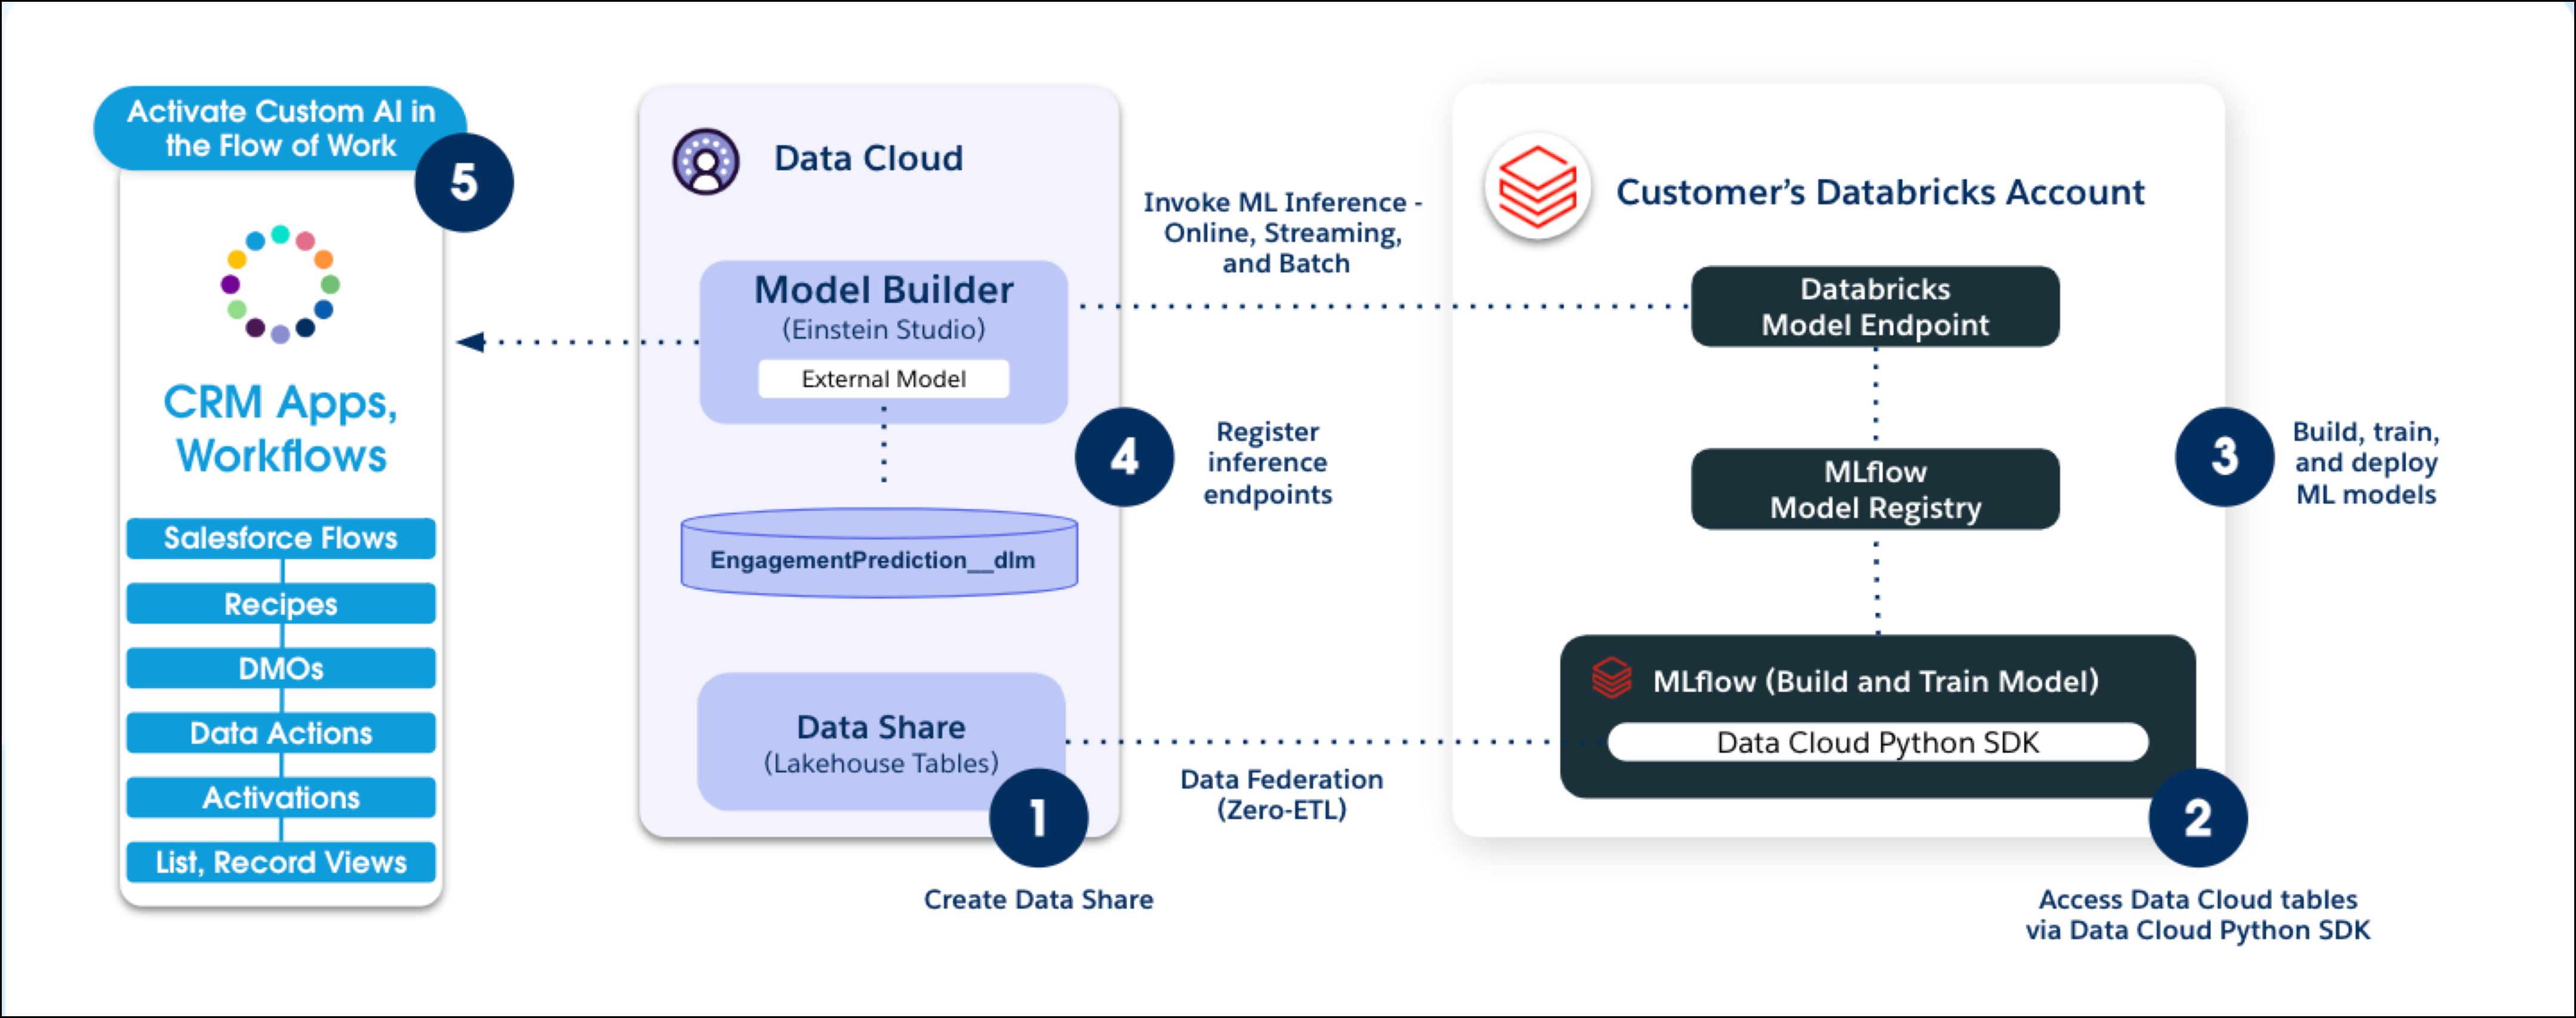
- **[Set Up Your Data in Databricks](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_set_up_your_data_databricks.htm&release=264.0.0&type=5)**
Access Salesforce data in your Databricks notebook using a Python connector. The user-friendly interface lets you quickly execute queries against data in Data 360 so that you can extract the data that you need into Python.
- **[Set Up an Endpoint in Databricks](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_set_up_your_endpoint_databricks.htm&release=264.0.0&type=5)**
Control the access to your data by setting up an endpoint connection between Databricks and Data 360.
- **[Connect a Databricks Model](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_connect_your_external_model_databricks.htm&release=264.0.0&type=5)**
To consume predictions in Salesforce, connect your Databricks model with Data 360 and define the prediction criteria for your use case.
# Use Google Cloud Vertex AI Models
You can build, train, and deploy sophisticated custom machine learning (ML) models with Google Cloud Vertex AI and data in Salesforce. After registering a model in Vertex AI, define your prediction criteria and connect the model with Data 360 to get predictions and insights for your use case. Use the insights to enrich customer profiles, create segments, and customize experiences across various channels.
### Required Editions
Available in: Developer, Enterprise, Performance, and Unlimited editions.
Here are some benefits of using Vertex AI models with Salesforce data.
- Access highly curated, harmonized, and near real-time data across Customer 360. This capability leads to expert models that deliver more intelligent predictions.
- Build models in Vertex AI and easily connect them with Data 360 to consume predictive insights for business process optimization. Use cases include propensity to buy, lead conversion, product interest, and more.
- Operationalize models and inferences easily in Salesforce.Data 360 simplifies the consumption of results from business processes and drives value.
- Eliminate tedious, costly, and error-prone Extract, Transform, and Load (ETL) jobs from Google Cloud because of the zero-copy approach to data. This approach also improves efficiencies for businesses.
- Integrate Vertex AI models and get predictions in Salesforce. Use Flow, a workflow automation suite, to enable AI-driven decision-making that can evolve based on real-time updates to data.
To use a Vertex AI model with Salesforce:
- Access your Data 360 data in Vertex AI to build, train, and deploy a model.
- Connect your Vertex AI model in Data 360 to consume the inferences for predictions and insights in various workflows across Salesforce.
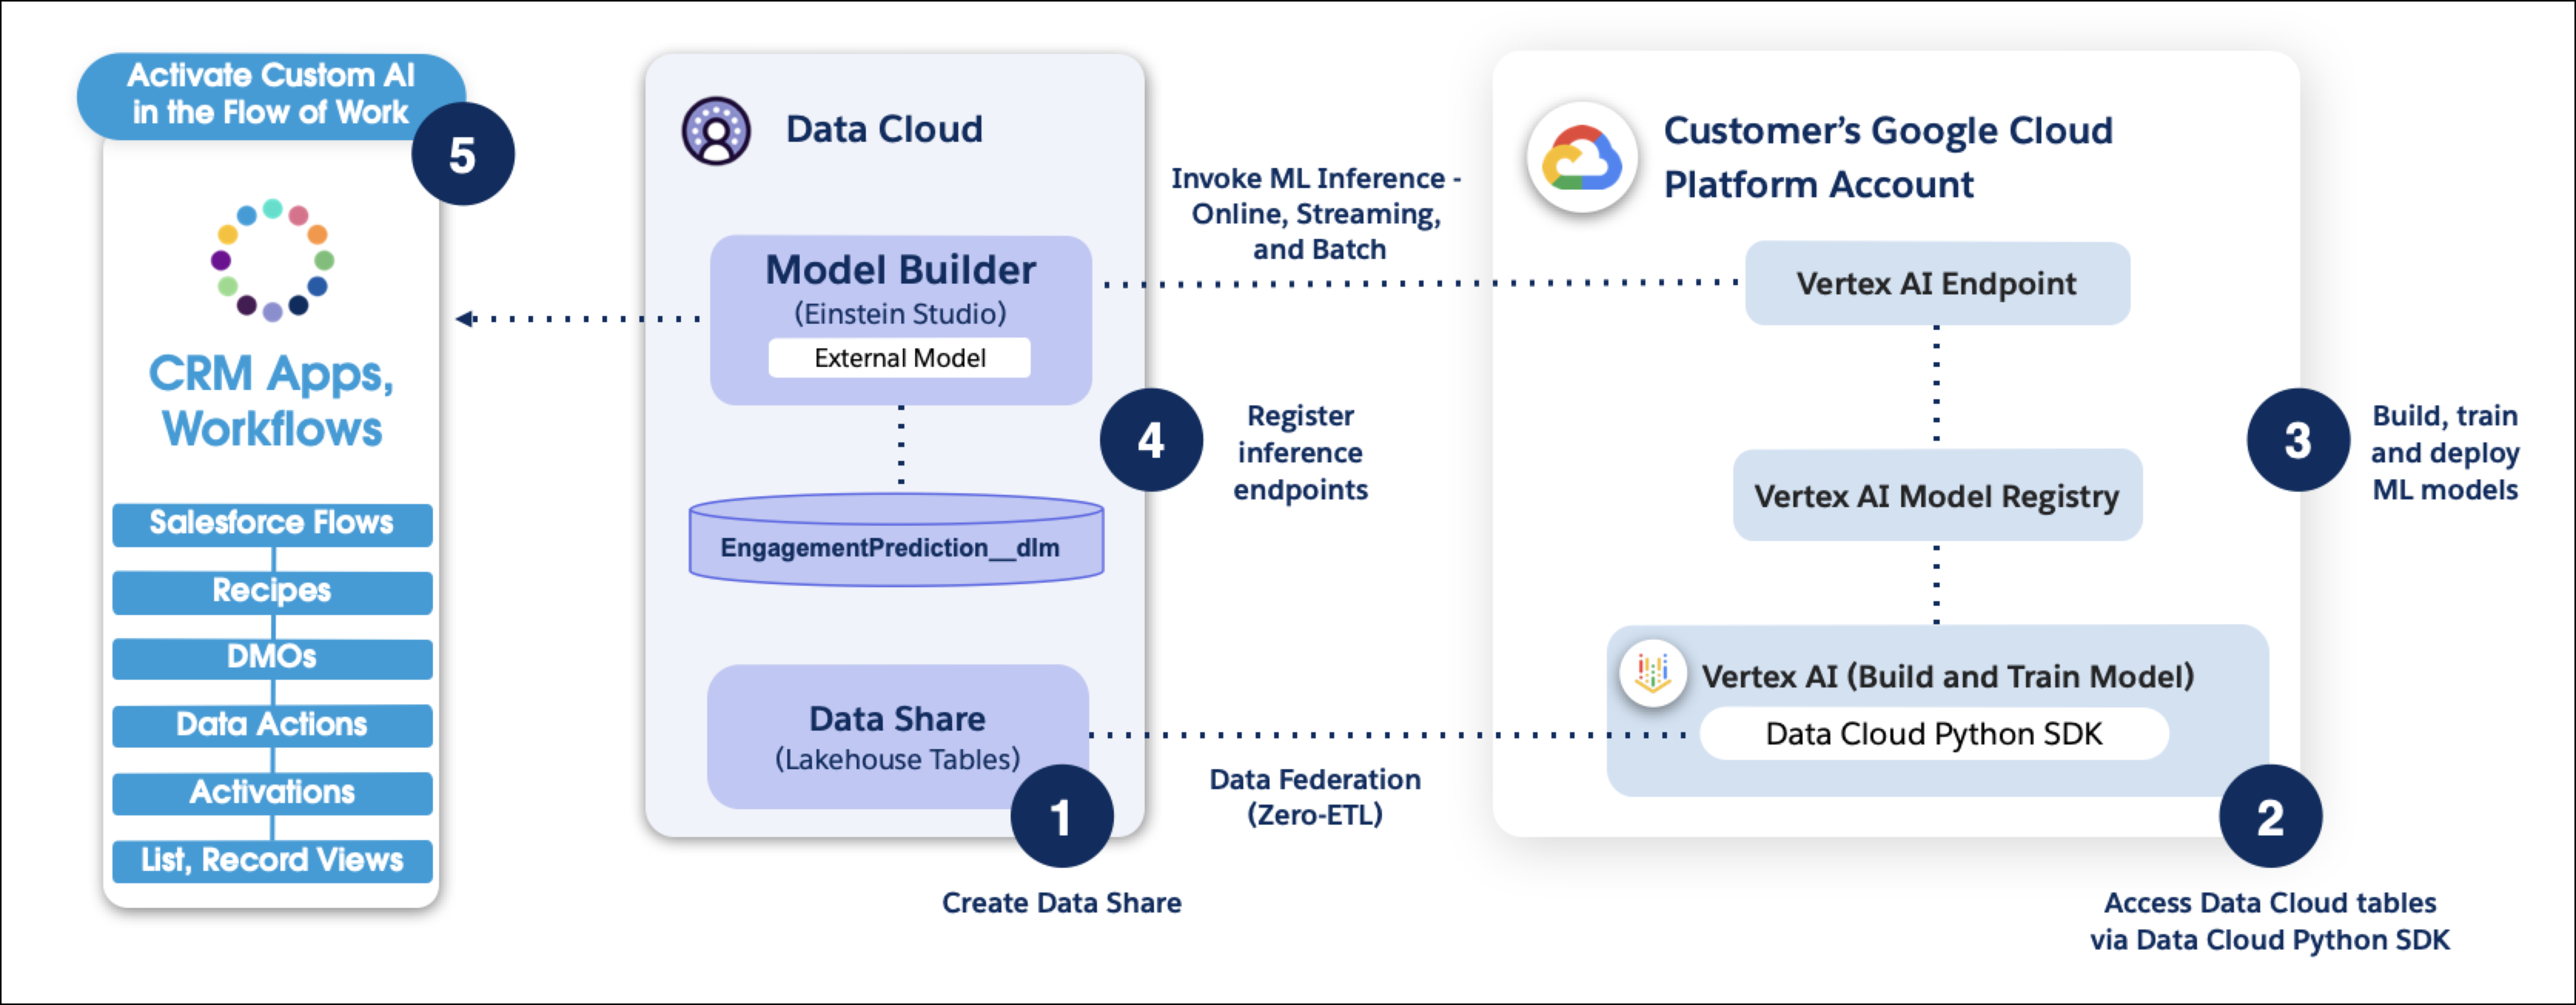
- **[Set Up Your Data in Vertex AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_set_up_your_data_google_vertex.htm&release=264.0.0&type=5)**
Access Salesforce data in a Google Cloud Vertex AI notebook using a Python connector. The user-friendly interface lets you quickly query your data in Data 360 so you can extract the data that you need into Python.
- **[Connect a Vertex AI Model](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_byom_connect_your_external_model_google_vertex.htm&release=264.0.0&type=5)**
To consume predictions from a Vertex AI model in Salesforce, connect it with Data 360 and define the prediction criteria for your use case.
#### See Also
- [_External_: Bring your own Google Vertex AI Models to Data Cloud](https://developer.salesforce.com/blogs/2023/11/bring-your-google-vertex-ai-models-to-data-cloud)
# Use Outputs from Predictive Models
There are many ways in which you can consume predictions, prescriptions, and top factors returned from predictive models.
### Required Editions
## Consumption Patterns
PATTERN
DESCRIPTION
OPTIONS
on demand
Generate predictions dynamically within the flow of work. Map the input fields to the
model. The model generates a prediction which can be actioned within any automated or manual
business process. On-demand predictions aren’t persisted anywhere unless done so
manually
batch
Use batch predictions when analyzing large sets of data. Ideal for comparing models on
various sets of data, performing predictive analytics, or for creating audience segments
when the most up-to-date prediction value isn’t business critical. Batch predictions can be
written back to Data Lake Objects (DLOs) or special Data Model Objects (DMOs) that don’t
have mapped DLOs (Transform DMOs or ML Prediction DMOs)
batch data transforms
batch predict jobs
streaming
When the most up-to-date prediction is critical to an automated or manual business
process across a large set of data, streaming predictions stay up to date in near real time
as input data changes. Streaming predictions are persisted in a special Data Model Object
(DMO) of type ML Prediction that doesn’t have a mapped Data Lake Object (DLO). Streaming
predictions are great for kicking off Data Cloud Triggered flows when a prediction value
changes.
## Consumers
Consumer
Description
More Information
Flows
Connect any data that’s accessible within a flow to a predictive model and generate
on-demand predictions and prescriptions.
Use Predictions in Flow Builder
Prediction Jobs
Map a DMO and related DMOs to a single model. Generated predictions are persisted in a
newly created DMO (of type ML Prediction) that is automatically related back to the base
DMO.
Use Predict Jobs
Batch Data Transforms
Generate predictions, top factors, and prescriptions from one or more models. Perform
additional transformations and choose where all the transformed results are written
back.
Transform Data with Predictions and Prescriptions
Agents
Create a flow that generates predictions and/or prescriptions and turn that into an
agent action. Agents can use the results to make further decisions and generate even better
responses.
Agentforce Agents
Prompt Templates
Predictions, top factors, and prescriptions generated from a model can be hard for a
human to decipher. Prompts can help to generate a more human-readable view of the prediction
and guide a user on what they possibly want to do next. Create a flow that generates
predictions, top factors and/or prescriptions as outputs. Then use a prompt to read the
information and generate the most relevant content to users.
Prompt Builder
REST Applications
Integrate on-demand predictions into any experience inside or outside Salesforce using
the public REST API to generate predictions. Use this API to build custom Lightning Web
Components or embed predictions into an external system.
Get Predictions in REST APIs
Apex
When activating a predictive model, a custom invocable action is automatically created
for that model so it can be used in flow. The same custom invocable action can also be
executed within Apex using the Invocable namespace.
Get Predictions in Apex
Invocable Namespace
## Tips for Interacting With Predictive Models
To produce predictions, a predictive AI model requires input variables with values that you supply at run time.
- During setup for batch data transforms, flows, and prediction jobs, you map each model input variable to the data source that supplies the value.
- For REST and Apex code, you programmatically supply the input data in the request to the predictive model.
- For on-demand predictions, these values can come from anywhere, including CRM data, user input, Data 360, and other sources. For example, in a flow, a user can provide one of the input values.
- Your training data is not the source for input variables.
After processing the request, the predictive model returns a prediction and, optionally, prescriptions and top predictors.
- For prediction jobs and batch data transforms, the model output is automatically saved in the associated DMO.
- For flows, you must configure in Flow Builder where you want the output returned from the predictive model.
- For REST and Apex code, you must programmatically handle the output returned from the predictive model.
#### See Also
- [_Salesforce Help:_ About Predictive AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_about.htm&release=264.0.0&type=5 "Learn key concepts for working with predictive models in AI solutions.")
# Use Predict Jobs
A predict job enables an active model to write predictive outputs to a data model object (DMO). Create a streaming or batch job in Model Builder and use the model's outputs in Salesforce workflows.
1. In AI Models (formerly Einstein Studio), click a model to view its details.
2. From the Integrations tab, create a new predict job.
3. In Predict Job Builder, select the data space and DMO where you want to store the outputs. Then click **Next**.
4. Map the model schema fields to your variables. Then click **Next**.

Note The inputs defined here initiate updates to your prediction when data on these fields change. To activate a predict job, you must also map all fields.
1. To add a DMO for your inputs, click the object field and select **Add an object**.
2. On Available Objects, select the object and its associated direct attributes.
3. To add related attributes, select a default path to begin mapping your fields. Then click **Select {"default path name"}**.
4. On Added Objects, review your objects.
5. To remove an object that you added, click **Remove**.
6. To see your mapped fields, click **Back to Mapping**.
5. To choose the predict job update type, select a streaming or batch job. Then click **Next**.

Note
Streaming jobs don't support externally stored data sources such as zero copy or Bring Your Own Lake (BYOL). Only batch jobs are supported for these object types. You must keep this in mind when choosing a data source.

Note Streaming predictions automatically update when input data changes. This keeps your predictions up to date. Batch predictions must be manually refreshed.
6. Define which fields initiate prediction updates, and click **Next**.
7. Review your predict job settings.
8. If you make changes, update your settings. Then click **Next**.
9. Add a job name and description, and then click **Create**.
After the job is created, you can find it in Model Details.

Note
A new DMO is created to store predictions for streaming jobs.
# Use Predictions in Flow Builder
Create automation using outputs from an activated model for decision-making. Predictive models that are activated in AI Models (formerly Einstein Studio) are surfaced in Flow as actions. You can use all flow types and choose a flow based on your goal. For example, if a business process requires user input or you want to display specific data to users, use a screen flow. If you want to automate possible actions to take after a record is created, updated, or deleted, use a record-triggered flow.
- **[Use a Screen Flow to Enrich Records with Predictions](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_screen_flow_predictions.htm&release=264.0.0&type=5)**
Create a screen flow to get records from Salesforce objects and add a prediction to a Lightning page. For example, you can add a lead conversion prediction score to a lead record.
- **[Use a Record-Triggered Flow to Automate Actions when a Prediction Changes](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_record_triggered_flow_predictions.htm&release=264.0.0&type=5)**
Automatically perform actions when a record is created, updated, or deleted. Let's look at how to use a flow to create actions when a prediction score on a case updates and it exceeds the threshold, indicating a case escalation.
#### See Also
- [_Salesforce Help_: Provided Flow Core Actions](https://help.salesforce.com/s/articleView?id=platform.flow_ref_elements_actions_list.htm&type=5&language=en_US)
# Use Predictive AI with Agents and Prompt Templates
Use predictive intelligence to power agents and prompt templates in Agentforce solutions.
## Use Predictive AI with Agents
You can augment agents with predictions, prescriptions, and top factors generated from predictive models, as shown in this video.
## Use Predictive AI with Prompt Templates
You can augment prompt templates with predictions, prescriptions, and top factors generated from predictive models. To learn more, see [Ground with Predictive AI](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_predictive.htm&language=en_US).
Use prompt templates to enhance the interpretability of predictive intelligence. For example, a flow can invoke a prompt template to generate a more human-readable view of predictive intelligence to guide users on what to do next.
Agentforce solutions can use predictive intelligence to conditionally invoke prompt templates based on current business conditions, as shown in this video.
- **[Drive Better Decisions with Predictive and Generative AI](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_predictive_and_generative_decisions.htm&release=264.0.0&type=5)**
The Predictive Model reference action in Agentforce enables an AI agent to invoke a predictive model created in AI Models (formerly Einstein Studio). Use the action to generate on-demand, data-driven predictions, interpret the results, and provide recommendations for how to improve an outcome. The integration of predictive and generative AI improves the interpretability of results for taking the best actions.
# Use Query Editor in a Data Cloud One Companion Org
Query Editor has the same features in the Data Cloud One app as it does in Data 360. However, its settings and data access capabilities vary depending on the companion org.
- Within a companion org, Query Editor can only access Data 360 data in data spaces shared with that companion org. This limitation maintains data isolation and security protocols between organizations.
- Query workspaces aren't synchronized with companion organizations. Create query workspaces specific to the org you use.
- You can only create new query workspaces in data spaces that are synchronized with that companion org. You can't create a workspace in a data space that hasn't been shared.
# Use Real-Time Predictions to Drive Personalized Recommendations
Predictive models in AI Models (formerly Einstein Studio) can generate real-time predictions to inform personalized recommendations in Salesforce Personalization. The integration enables the delivery of customized experiences, which can boost engagement. Predict the customer lifetime value annual spend, or likeliood to purchase and use your model's predictions in a Personalization Decision targeting rule to serve up different content recommendation strategies.
### Required Editions
For editions and permissions needed to use Salesforce Personalization targeting rules, see [Create a Targeting Rules](https://help.salesforce.com/s/articleView?id=mktg.persnl_personalization_point_targeting_rules_create.htm&type=5&language=en_US)
USER PERMISSIONS NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create, update,
delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and improvements
derived from a model.
When using a predictive model in AI Models in Salesforce Personalization, consider the following:
- Personalization maps are only supported for models created from scratch. Connected models aren’t supported.
- You can map models built from scratch to a real-time profile data graph.
- You can map direct attributes and calculated insights without dimensions to a model created from scratch. Calculated insights must have a number data type.
To set up a model to provide personalized recommendations in Salesforce Personalization, follow these steps.
Before you begin, you must first [create a model from scratch](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_ec_create_model.htm&type=5&language=en_US) in AI Models.
1. In AI Models, from the predictive models tab, click your model. The model must be activated so it can provide predictions.
2. From the model details, click the Integrations tab.
3. To create a new personalization map, click **New**.
4. Select a data space and profile data graph.
5. Identify the fields in the data graph map you want to use to generate the personalized prediction.
6. Click **Next**.
7. Review the mapping.
8. Save your settings.
After linking your model with a real-time profile data graph, you can use the model in Salesforce Personalization targeting rules to get personalized recommendations.
#### See Also
- [_Salesforce Help:_ Einstein Studio Model Predictions for Personalization](https://help.salesforce.com/s/articleView?id=mktg.persnl_esi_realtime_prediction_for_persnl.htm&language=en_US)
# Use Search for AI, Automation, and Analytics
Grounding Data 360 search on unstructured and structured data enhances your use of generative AI, analytics, and automation tools across Salesforce. Grounding brings customer-specific data, including diverse forms of unstructured data (such as text documents, multimedia files, social media content, web content, chat logs, sensor data, and customer feedback), into applications like Agentforce, Tableau, and Flow Builder. This alignment results in more accurate and relevant AI-generated content, deeper insights from analytics, and more efficient automation workflows for your teams and customers.

Note
As of October 14, 2025, Data Cloud has been rebranded to Data 360. During this transition, you may see references to Data Cloud in our application and documentation. While the name is new, the functionality and content remains unchanged.
In Data 360, you can create vector or hybrid search indexes depending on data and query needs.
## Vector Search
In Data 360, you can create searchable vector embeddings from your unstructured and structured data. A vector embedding is a numerical representation of a unit of text (an article or a passage from a larger document) that captures its semantic meaning. Large language models (LLMs) group embeddings with similar semantic meanings so that generative AI applications can effectively interpret their relationships and contextual relevance.
Use vector search when your data source and search queries benefit more from semantically aware matches within a large dataset. For example, if you send a query such as “What is Acme famous for?”, the LLM retrieves chunks that have the highest vector search score that relates to the closest semantic match with the search query.
Before you create a vector search index, unstructured data stored in data model objects (DMOs) or unstructured data model objects (UDMOs) are chunked into manageable, semantically meaningful units. These units are stored in [two objects](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_chunk_index_dmo.htm&type=5&language=en_US): a chunk data model object (CDMO) and an index data model object (IDMO). The CDMO is a Data 360 object that stores the actual content chunks, and the IDMO stores the vector embedding.
You can perform vector searches on that data from apps such as Prompt Builder, AI agents, or Tableau.
## Hybrid Search
To deliver relevant and accurate responses in generative AI applications, Large Language Models (LLMs) often require both vector and keyword search. While vector search excels at grasping semantic similarities, it can lack precision with specific domain vocabulary. Conversely, keyword search is excellent for lexical matches but doesn't understand semantic similarity. In Data 360, hybrid search combines these methods, using semantically aware vector search for contextual understanding and keyword search for precise lexical matching.
When your data source and search queries benefit from both semantically aware vector search and the precision of a keyword search, use hybrid search. For example, in the query “Does Acme motor XYZ123 use hydraulic pumps?” the addition of keyword search promotes higher-ranking positions for more relevant content, thus providing the results with better grounding.
After you create a hybrid search index on your DMOs or UDMOs, Data 360 generates content chunks and vector embeddings for a vector search index and a keyword search index. Hybrid search queries the vector search index to retrieve information based on semantic similarity, and it queries the keyword search index to retrieve information based on lexical similarity. Hybrid search then merges and ranks the results provided by both types of searches to generate the best response. You can also configure additional ranking factors, such as recency or popularity of records, to influence the search results returned.
## Key Use Cases for Data 360 Search
Key use cases for Data 360 search include:
- In Retrieval Augmented Generation (RAG): Data 360 search is fundamental to RAG, grounding AI responses in relevant unstructured data. This directly leads to more accurate and contextually appropriate AI outputs that are based on your specific knowledge base.
- In Service Cloud: AI agents use search to query for precise information within knowledge articles, emails, support tickets, and chat logs. This enables them to provide more accurate answers, craft better responses, and even proactively suggest solutions to customer issues.
- In Sales Cloud: AI agents can query unstructured sales data—like emails, call transcripts, and notes—to generate highly relevant meeting briefings and summaries. This insight also fuels personalized content and customer-specific recommendations for new emails, significantly boosting customer engagement and sales team productivity.
- In automation flows: AI agents can automatically identify semantically similar records, such as Cases, based on their descriptions. This capability is crucial for flagging duplicates, accelerating resolution times, and accurately classifying records by finding similar historical examples.
- In analytics: Within Tableau, Data 360 search facilitates gaining deeper insights from unstructured data, notably through advanced topic classification. This enhances data analysis by revealing patterns and themes that traditional methods sometimes miss.
- **[Chunk Data](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_grounding.htm&release=264.0.0&type=5)**
To add your data to Data 360’s search index, you must first chunk it. Chunking break your data into meaningful chunks, and Data 360 turns those chunks into machine-readable vector embeddings.
- **[Vector Search](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_index.htm&release=264.0.0&type=5)**
In Data 360, you can create searchable semantic vector embeddings from your unstructured and structured data. Vector search helps your generative AI, automation, and analytics applications understand semantic similarities and context between embeddings.
- **[Hybrid Search](https://help.salesforce.com/s/articleView?id=data.c360_a_hybridsearch_index.htm&release=264.0.0&type=5)**
To provide relevant information to an LLM with gen AI applications and generate the correct response, requires both vector search and keyword search. Vector search understands semantic similarities and context, but lacks specific domain vocabulary. Keyword search excels at lexical similarity but not at semantic similarity. In Data 360, hybrid search combines the strengths of semantically aware vector search with the precision and speed of keyword search.
- **[Manage Search Indexes](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_manage.htm&release=264.0.0&type=5)**
Create, view, edit, and delete search index configurations.
- **[Optimizing Search Indexes: Field Selection and Chunking](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_optimize.htm&release=264.0.0&type=5)**
When you create a search index in the advanced builder, you can optimize your search index to deliver more accurate results by paying attention to the field selection and chunking strategies you use.
- **[Search Index Reference](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5)**
Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.
- **[Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=data.c360_a_rag_overview.htm&release=264.0.0&type=5)**
Retrieval Augmented Generation (RAG) in Data 360 is a framework for grounding large language model (LLM) prompts. By augmenting the prompt with accurate, current, and pertinent information, RAG improves the relevance and value of LLM responses for users.
- **[Billing Considerations for Unstructured Data and Search Index](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_billing_considerations.htm&release=264.0.0&type=5)**
When you use unstructured data and search index configurations, your data is stored and processed in Data 360. Use of unstructured data and search index in Data 360 impacts the consumption of credits in the following usage types.
#### See Also
- [_Salesforce Help_: About Unstructured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_about.htm&release=264.0.0&type=5 "By bringing unstructured data in Data 360, you can ground your Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.")
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
- [_Salesforce Help_: Encrypt Data 360 with Customer-Managed Root Keys](https://help.salesforce.com/s/articleView?id=xcloud.security_pe_enable_pe_for_data_cloud.htm&type=5&language=en_US)
- [_Trailhead_: Get to Know Search Index Types in Data 360](https://trailhead.salesforce.com/content/learn/modules/search-index-types-data-cloud-quick-look)
# Use Single Variate Forecasting
Predict future values based on historical patterns in a single variable by using the Holt-Winters algorithm. For example, use a data transform to forecast sales by account based on opportunity data.
### Required Editions
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
## Run a Forecast Model with a Batch Data Transform
Use a batch data transform to apply forecasting across large datasets.
1. From Data 360, go to Data Transforms, and click go to Data Transforms, and click **New**.
2. Select **Batch Data Transform**.
3. Select **Data Model Objects** and the data space.
4. To add your input data, select a data model object. For this example, use Opportunity.
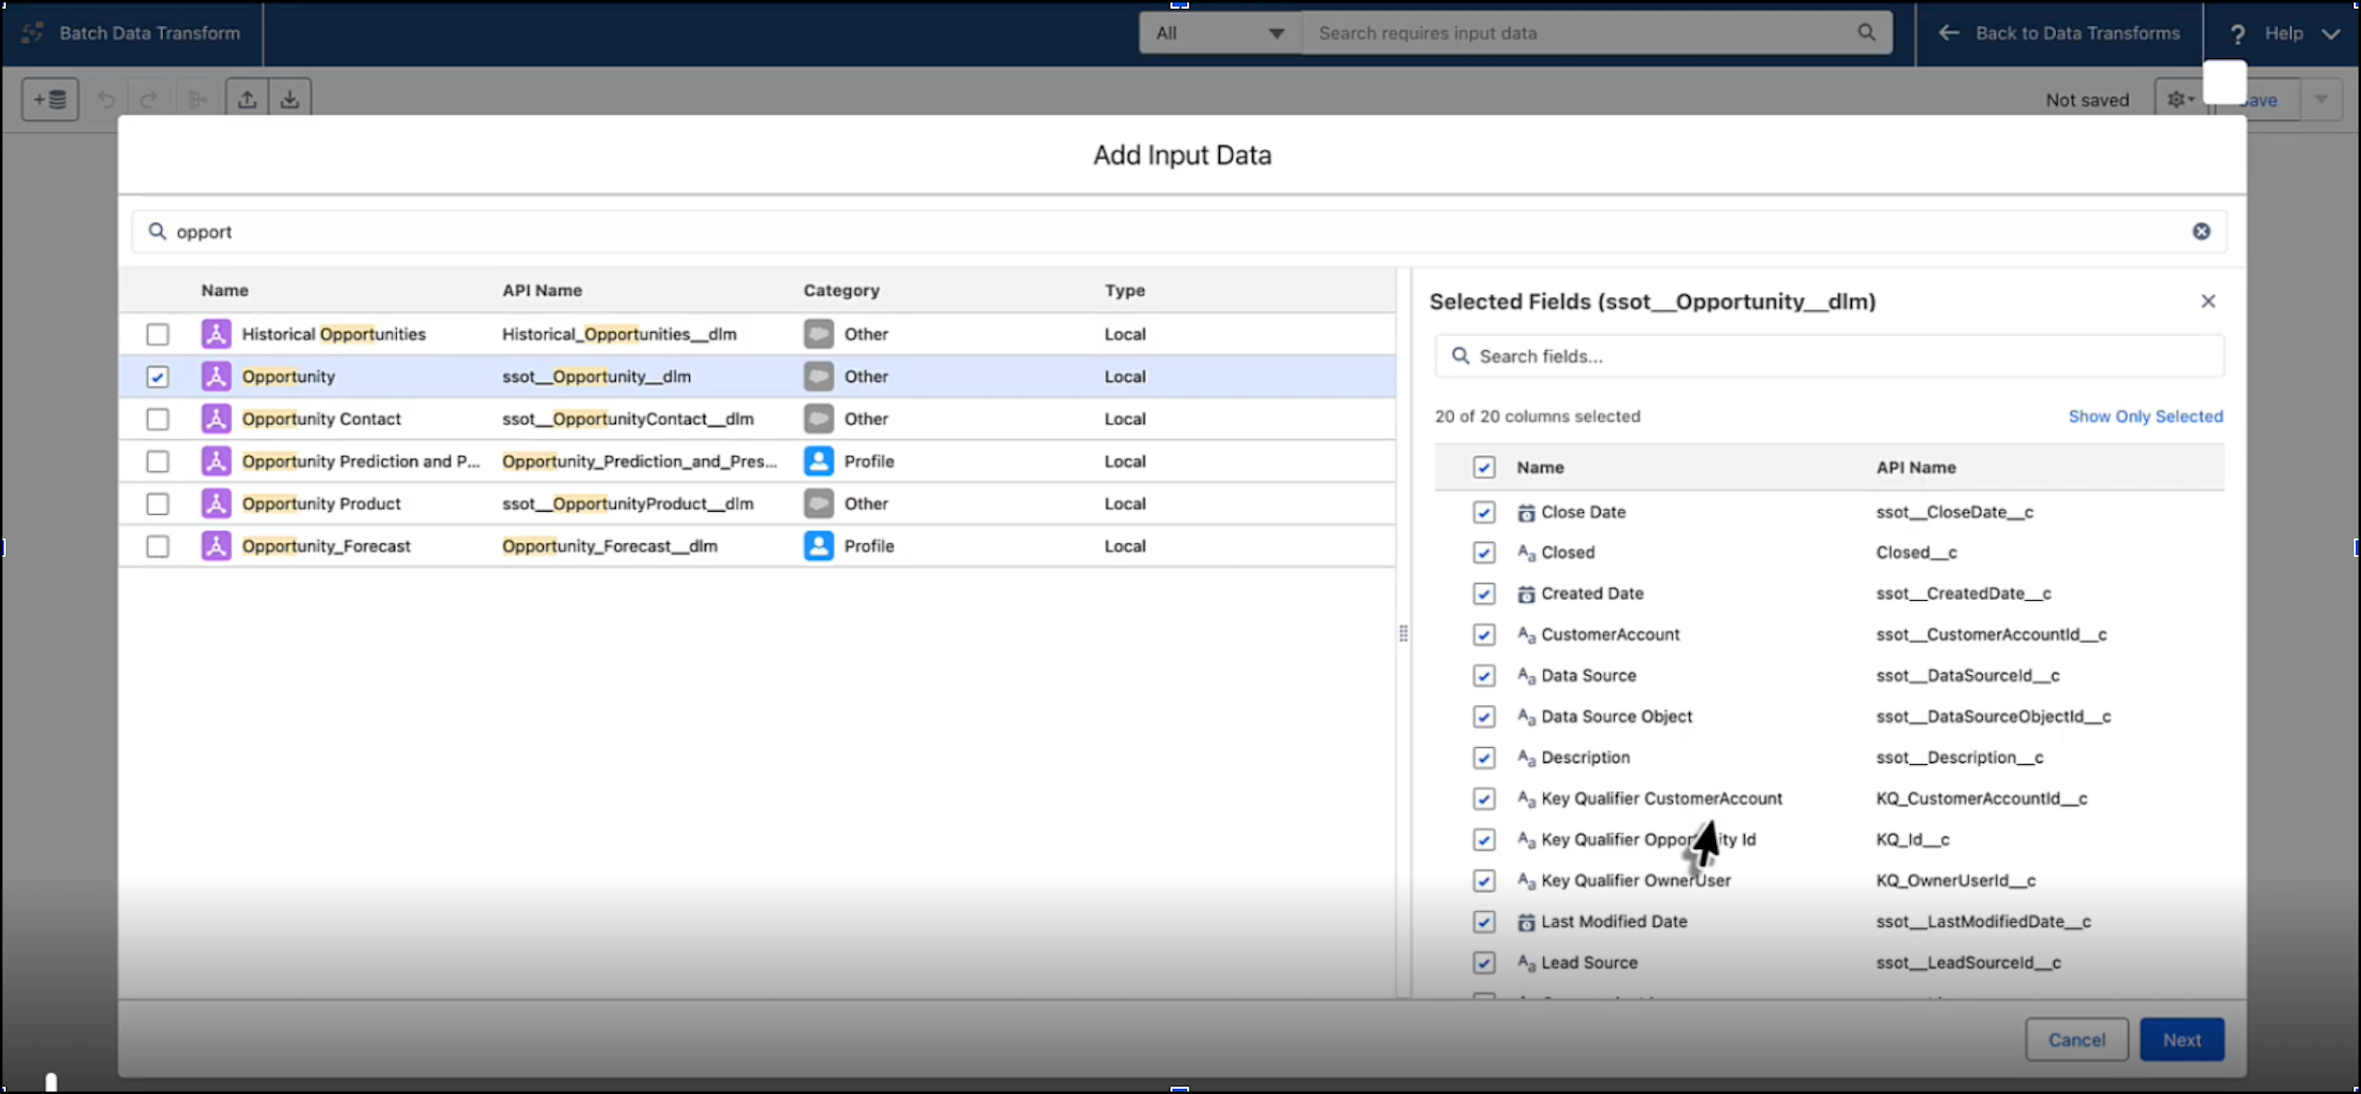
5. Add a node to select an AI function.
6. Select **Forecast**.
7. Select the Holt-Winters forecasting model.
8. Configure these details and input fields.
1. Specify a forecast horizon, such as 3 (months).
2. Keep the auto seasonality selected.
3. Select the Sum of Total Amount as the aggregate metric to forecast.
4. Group data by customer account ID, and configure the close date field by year/month to ensure monthly granularity.
5. Specify the time series, such as the Close Date field, and select **Year-Month** to forecast out by month.
6. Map the output field (forecasted value, upper bound, and lower bound). This action saves the transformed data to a new DMO.
7. Save your settings. A preview shows data in three forecasted fields based on your horizon of 3.
8. Run the transform to incorporate historical data with the future forecasted rows in the output DMO.
9. To append the transformed data back to the Account DMO, use the Join node.
10. Select the forecast fields to add to the Join.
11. In the data transform, connect the Join node to Output to append forecasted values to the output object.
# Use SQL to Create Insights
Write SQL to define calculated and streaming insights in Data 360. Each query must follow a specific structure and use supported functions, operators, and data types.
### Required Editions
A calculated insight query follows this structure:
```sql
SELECT ,
FROM
JOIN [INNER | LEFT | RIGHT | FULL] -- optional
WHERE -- optional
GROUP BY
```
Measure
A quantitative value produced by an aggregation function, such as a total amount or record count. Every query must include at least one measure.
Dimension
A qualitative field used to categorize and group measures, such as a product name, date, or profile ID. Any field in the `SELECT` clause that isn't inside an aggregation function is treated as a dimension and must also appear in the `GROUP BY` clause.

Note To include a calculated insight in a segment, add the segmented table as a `JOIN` and include its primary key as a dimension in your query.
For the full list of supported syntax rules, functions, and operators, see the reference topics in this section.
- **[Create a Calculated Insight Using SQL](https://help.salesforce.com/s/articleView?id=data.c360_a_get_started_with_calculated_insights.htm&release=264.0.0&type=5)**
Write SQL expressions to create your metrics and dimensions from mapped objects and fields. You can create a calculated insight in Data 360 using SQL.
- **[Create a Streaming Insight Using SQL](https://help.salesforce.com/s/articleView?id=data.c360_a_create_a_streaming_insight_using_sql.htm&release=264.0.0&type=5)**
Write SQL expressions to compute streaming metrics across dimensions from your near real-time data sources. A streaming insight analyzes data at specific points in time. Streaming insights help build time series aggregations in near real time to orchestrate and optimize your data within Data 360.
- **[SQL Rules for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_general_sql_rules.htm&release=264.0.0&type=5)**
When you write SQL for calculated or streaming insights in Data 360, rules govern how each clause is interpreted and what constraints apply. You can also embed a nested subquery in a WHERE or JOIN clause to restrict which rows the outer query returns.
- **[Data Types for Insights SQL](https://help.salesforce.com/s/articleView?id=data.c360_a_insight_sql_data_types.htm&release=264.0.0&type=5)**
When you define a calculated or streaming insight with SQL in Data 360, use the supported data types for your measures and dimensions. Measures are the numerical values you aggregate; dimensions are the qualitative fields you group by.
- **[SQL Functions for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_aggregates.htm&release=264.0.0&type=5)**
Use these aggregate, datetime, analytical, formatting, math and statistical, and boolean functions when you author calculated insights in Data 360. The Aggregatable column indicates whether a function's output can be rolled up across fewer dimensions when queried in segments or activations.
- **[SQL Operators for Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_operators.htm&release=264.0.0&type=5)**
Use these arithmetic, currency, and logical operators in SQL expressions when you author calculated insights in Data 360.
- **[Formulas, Operators, and Calculated Insights](https://help.salesforce.com/s/articleView?id=data.c360_a_formulas__operators__and_calculated_insights.htm&release=264.0.0&type=5)**
Create audiences in different ways and at different stages of your workflow using formulas, operators, and calculated insights in Data 360. During ingestion, you can use formulas to perform operations on row-based data used downstream. For segmentation, audiences are created with segment operators.
- **[SQL Use Cases for Insights Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_calculated_insights_use_cases.htm&release=264.0.0&type=5)**
There are several useful code blocks when creating insights in Data 360.
# Use the Data Q&A Agent
Ask the Data 360 Data Q&A Agent questions in natural language to explore your data, review the responses and generated queries, and refine your analysis with follow-up questions.
### Required Editions
## Ask Questions
1. In Data 360, open the Data 360 Data Q&A Agent chat panel.
2. In the chat input field, type your question or request in natural language. Examples:
- What are the top 10 best performing products in Q3 in terms of revenue?
- Show me customer engagement trends by segment over the last 6 months.
- Generate a chart comparing deal sizes by region.
3. Press Enter or click **Send**.
The agent processes your question, generates a SQL query, executes it, and returns a response with explanations, data tables, and charts as appropriate.
## Review Responses
The response can include:
- An explanation of the findings
- Data table with query results
- Charts or visualizations
- Notes about how the agent interpreted your question
Click **View More Details** to see how the agent processed your question. The details section shows:
- **Objects Used:** Which data objects the query accessed
- **Steps Performed:** How the agent broke down and processed your request
- **Assumptions:** Any assumptions the agent made about your question
- **Generated Query:** The actual SQL query that was executed
- **Confidence Score:** How confident the agent is in its response
## Refine Your Analysis
Ask follow-up questions to refine, modify, or get more detail about the results. Examples:
- Show me the same data for Q4.
- Filter that to only include active accounts.
- Explain how you calculated that metric.
- Fix the query to use amount\_usd instead.
Provide feedback using the thumbs up or thumbs down buttons to help improve the agent's responses.
## Example Conversation Flow
**You:** Show me the top 3 opportunities by deal size.
**Agent:** The top 3 opportunities are all clustered just under $200K, led by Perez Homes - Q1 Renewal at $199.7K.
\[Agent displays a data table with the 3 opportunities and a bar chart\]
**Note from Agent:** I interpreted deal size as amount\_usd\_\_c. This ranking was across all opportunities in the dataset, with no extra filters for stage, owner, or date.
**You:** Filter that to only show closed-won opportunities.
**Agent:** \[Generates new query with stage filter and returns updated results\]
# Use the Predictive Model Agent Reference Action to Enhance Predictions
For an AI agent to provide and interpret outputs from a predictive model, you must create a custom agent action in your org. Let's look at how Agentforce can enhance predictions from a Predicted Attrition model that was created in Model Builder.
### Required Editions
For editions and permissions needed to create a custom agent action, see [Agent Actions](https://help.salesforce.com/s/articleView?id=ai.copilot_actions.htm&language=en_US).
USER PERMISSIONS
NEEDED
Allow users to manage models in AI Models
Enables you to create, update, and delete models in AI Models.
PERMISSION SETS
Data Cloud Architect
Admin-level access to all AI Models features, including the ability to create,
update, delete, and activate models.
Data Cloud User
Restricted access to use a model, including getting predictions and
improvements derived from a model.
1. From Setup, search for and select **Agentforce Assets**.
2. Go to the Actions tab and click **New Agent Action**.
3. Select the Predictive Model reference action type.
4. For the reference action, select the model (Predicted Attrition) that you want the agent to provide predictions for. The agent action label and API name is autopopulated.

Important Only models that are activated in AI Models are displayed.
5. Click **Next**.
6. Review and update the Predicted Attrition agent action. If needed, you can customize the pre-populated text.
1. Agent Action Instructions (pre-populated text):
Requests a predictive model to return outputs based on the run-time values of input variables. These values originate from the agent's context, such as from records or user inputs. For a regression model, this action returns a numeric value for a predicted outcome, such as expected deal revenue. For a binary classification model, this action returns a numeric score indicating the likelihood of an outcome, such as lead conversion. No-code models built with Model Builder also provide top predictive factors and prescriptions to optimize the predicted outcome.
2. Inputs: Each field in the model schema is displayed as an input, and some fields are model variables.
Autopopulated text is used for these model inputs.

Note
The _Require Input_ option is selected for all inputs except for Recommendations.
i. **Top Predictors** — specify the number of outputs. If no value is specified, the default is 3.
ii. **Recommendations** — specify the number of outputs. If no value is specified, the default is 3.
iii. **Department** — the model requires a value for Department. Get the value at run time from a record, a user conversation, or some other source.
iv. **Daily Rate** — the model requires a value for Daily Rate. Get the value at run time from a record, a user conversation, or some other source.
v. **Age** — the model requires a value for Age. Get the value at run time from a record, a user conversation, or some other source.
vi. **Total Working Years** — the model requires a value for Total Working Years. Get the value at run time from a record, a user conversation, or some other source.
vii. **Years at Company** — the model requires a value for Years At Company. Get the value at run time from a record, a user conversation, or some other source.
3. Outputs: Results provided by the predictive model.
Autopopulated text is used for these model outputs.
i. **Top Predictors** — represents the most important variables that influence a predictive outcome. The Output Rendering option is an Apex class type.
ii. **Recommendations** — represents actions that can improve a predicted outcome. The Output Rendering option is an Apex class type.
iii. **Prediction** — represents a prediction. The meaning of the value depends on the model type. The Output Rendering option is a decimal.
4. When your agent action settings are complete, click **Finish**. The Predicted Attrition action must be assigned to an active agent such as Predictive Assistant.

Note
You must select the _Show In Conversation_ option for at least one output.
7. In Agentforce Builder, create a new topic to assign to an agent action based on the model's outcome, and click **Next**.
You can ask a question based on the model outcome, such as: what’s the likelihood that customers will switch brands?
8. Review the autopopulated topic fields. Update the information as needed, and if you're satisfied, click **Next**.
9. Click **Finish** to assign your agent action to the topic. Now you can use the action so the agent can provide responses from the model.
10. Click the topic and use the conversation preview to post questions related to the model outcome.
11. Activate the topic you’re satisfied with the responses provided by your agent.
# Use Unified Lineage
Explore and interact with the lineage graph to view how your data objects connect. Search for objects, trace upstream and downstream dependencies, and use side-panel details, field-level views, and tag overlays to understand your data flow and governance context.
### Required Editions
| User permission needed | |
| --- | --- |
| To use unified lineage: | Data Cloud Architect permission set |

Note You can view lineage only for objects within data spaces where you have permission to view metadata. If you don’t have View access on an object, that part of the lineage graph stays hidden, which can result in an incomplete graph. To see the full graph, make sure you have the View All Records permission.
Make sure you:
- Have the View Metadata permission for the data space you’re exploring.
- Understand the Data 360 object model. For example, how data streams, data lake objects, data model objects, calculated insights, and activations relate.
- Review your governance tags so you can interpret tag propagation accurately when viewing tag overlays.
1. In Data Cloud, go to **Data Governance** > **Lineage**.
2. Select a data space and object type, then search for an object by name or browse the list.
The graph initializes with the selected object and shows three upstream and three downstream dependency levels.
- Upstream objects represent ingestion or source connections.
- Downstream objects represent harmonization or activation flows.
3. In the graph, boxes represent data objects and ovals represent processes such as transforms or activations.
- To view the fields in the object, expand it.
- To trace dependencies, go to **Actions** > **Highlight Path**.
- To reveal more upstream or downstream objects, click **+** to expand the dependencies.
- To re-render the graph, go to **Actions** > **Re-render Graph** to focus on the selected object.
4. To view object details, click on the object to open the side panel.
- **Details** - Shows the name, type, category, and operational information such as last run status, record count, and schedule of the object.
- **Tags** - Lists applied governance tags.
- **Fields** - Lists fields and their tags.
- **View Record Page** - Opens the object record in a new tab.
5. To view field-level lineage, open a data object node such as a DLO, DMO, or CIO, expand the field list, and select a field to trace its lineage.
6. To overlay governance tags on the graph, select **Show Tags**. This action is useful to confirm how tags propagate across dependencies and detect gaps in policy enforcement.
# Use Value Suggestions in Segmentation
You can enable value suggestions for data model object (DMO) fields if the data type is Text. Enable or deactivate the feature in the DMO record home. You can enable value suggestions for up to 500 attributes for your entire org. It can take up to 24 hours for suggested values to appear.
1. In Data 360, click the Segments tab.
2. Select a segment.
3. To use value suggestion when creating segment filters, drag the attribute onto the canvas.
4. Start typing in the Value field for an attribute.
If you don’t see the values in your list yet, start typing the values you’ve already ingested or type values exactly as they appear in your dataset.
Suggested values are retained for 30 days in the suggested values dataset. For attributes with more than 1,000 values, the most frequently occurring 1,000 values in the dataset are displayed alphabetically. This includes both new and old suggested values. Some operators allow you to select multiple values for an attribute. Values with more than 255 characters aren’t available as suggested values, but you can still type them in to filter on them.

Note When suggested values are enabled on fields mapped to external objects (See [BYOL](https://help.salesforce.com/s/articleView?id=data.c360_a_data_ingestion_and_modeling.htm&type=5&language=en_US)), charges apply per field every 24 hours.

Note
- When the DMO's category is Other, value suggestion is available when the relationships from the Segment On entity to the DMO are one-to-one (1:1) and many-to-one (N:1). Value suggestions aren’t available when the relationships are one-to-many (1:N). The DMO category and relationships are determined while ingesting and mapping your data.
- Use data newer than 30 days. If the data has been inactive for 30 days, the values don’t appear.
#### See Also
- [_Salesforce Help_: Edit Data Model Object Properties](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_properties.htm&release=264.0.0&type=5 "You can edit Data Model Object (DMO) properties either on the Data Model tab or on the data mapping page.")
- [_Salesforce Help_: Category](https://help.salesforce.com/s/articleView?id=data.c360_a_category.htm&release=264.0.0&type=5 "When creating a data stream, select a category or type of data found in that data stream.")
# Use Vector Filters in Data 360 Segments (Beta)
Vector filters reduce reliance on exact keyword matches and manual data organization, allowing you to create accurate segments efficiently. This feature uses NLP algorithms to sort through unstructured data in segment creation. It supports filtering both structured and unstructured data within a single interface and a segment.
### Required Editions

Note Vector filters in Segments is a beta service that is subject to the Beta Services Terms at Agreements - Salesforce.com or a written Unified Pilot Agreement if executed by Customer, and applicable terms in the Product Terms Directory. Use of this beta service is at the Customer's sole discretion.
Permission Sets Needed
To use vector filters:
Any one of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, click **Segments**.
2. Select the segment from the list.
3. Click **Edit Rules**.
4. Click the **Include** or **Exclude** tab. You can have up to 50 filters in each tab.
5. You can add criteria to:
- Direct Attributes — a single data point or piece of information about the entity being segmented, such as a postal code, first name, or birthday. Direct attributes are often demographic attributes.
- Related Attributes — a collection of multiple data points or pieces of information associated with the entity being segmented, such as purchase history, product numbers, or email interactions. Related attributes are often behavioral or engagement events.
- Calculated Insights — search for calculated insights by name or find them under the object referenced in the SQL. You can only use processed calculated insights in a segment.
6. Select the **Is Similar To** operator.
7. Enter the required value. For example, backpacks.
8. Select the similarity level using the slider. By default, it’s set to 100.
9. Click **Compute Results**.
10. Click **View Results**. You'll see these details:
- The number of similar terms returned based on the search term and the selected similarity level.
- A sample of the five most similar terms.
- A sample of the five least similar terms.
You can compute results with different similarity levels and different values as needed.
11. Click **Done** to save the filter.
The filter operates within its defined scope, making sure the data it collects is relevant and fits the context you're looking for, thus improving the accuracy of your segment data.
# Use Your Customer ID as a Party Identifier
By default, the Marketing Cloud Personalization bundle maps the Profile ID to the Data 360 Individual ID. Personalization also connects the Salesforce Marketing Cloud contact key to the party identification number. To unify profiles for identity resolution, use your own Customer ID as the party identifier in Marketing Cloud Personalization and Data 360.
### Required Editions
User Permissions Needed
To map data
Permission set:
1. Select the mapping between Salesforce Marketing Cloud Contact Key and Party Identification.IdentificationNumber, and click **Delete**.
2. Map your party identifier (for example, External User ID) to Party Identification.IdentificationNumber. Ensure that the External User ID contains the customer’s unique party identifiers.
#### See Also
- [_Salesforce Help_: Marketing Cloud Personalization Bundle Mappings](https://help.salesforce.com/s/articleView?id=data.c360_a_interaction_studio_bundle_mappings.htm&release=264.0.0&type=5 "When creating a data stream in Data Cloud using a Marketing Cloud Personalization (formerly Interaction Studio) starter bundle, the system creates standard mappings for you.")
# Using an Existing Data Lake Object to Create a Data Stream
You can use an existing data lake object (DLO) when creating an S3, Google Cloud Storage, or SFTP data stream. The data stream that initially created the DLO defines the characteristics, such as the primary key, event date time, and record modified field. You can convey how the new data stream’s fields conform to the existing DLO fields.
Keep these considerations in mind when using an existing DLO to create a data stream.
- You can’t use a DLO that’s already being used by another source.
- Bring in all data stream fields. If the DLO doesn’t have a field that corresponds to your data stream field, you can extend the DLO on the Data Lake Object tab.
- A data stream field must have the same data type as its intended DLO target field. If you can’t locate the DLO field in the dropdown, it’s because of a data type mismatch or another data stream field is using the DLO field.
- Assign a data stream field to the DLO’s primary key.
- If the DLO is in the Engagement category, assign a data stream field to the DLO’s Event Date Time.
- If the DLO is of category Profile and the Record Modified field was previously declared on the DLO, assign a data stream field to it. If the Record Modified field hasn’t been previously assigned, you can configure it during data stream setup.
- If the Organization Unit Identifier was previously declared on the DLO, assign a data stream field to it. If it hasn’t been previously assigned, you can configure it during data stream setup.
# Using Consent Preferences in Segmentation
Learn more about how to use consent preferences in segmentation in Data 360.
If you’re using custom DMOs or attributes to store consumer consent preferences in Data 360, use them as filter criteria when creating a segment.

Tip We recommend that consent preferences be mapped to objects from the [Privacy Data Model](https://help.salesforce.com/s/articleView?id=data.c360_a_privacy_data_model.htm&type=5&language=en_US) but they can be mapped to custom objects as well.
For example, Northern Trail Outfitters created a segment of individuals who opted into email communication and haven’t opted out of promotions. They use the Consent Status attributes as filter criteria to ensure their segment honors individuals' consent preferences.
#### See Also
- [_Salesforce Help_: Create and Activate Segments](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&release=264.0.0&type=5 "Use segmentation in Data 360 to break down your data into useful segments to understand, target, and analyze your customers. After you create a segment, you can publish it to an activation target.")
# Using Currencies in Data Cloud
Data Cloud uses the currencies and static exchange rates configured in your Salesforce CRM org and applies them to data transforms, calculated insights, segmentations, reports, and other processes.
In a single-currency organization, Data Cloud syncs its currency data from your Salesforce org using this process.
- After the Salesforce CRM connector to Data Cloud is automatically set up, Salesforce creates a static rate data lake object (DLO) named `Static_Currency_Rates_` and a static rate conversion data model object (DMO) named `Static_Currency_Rates_` for the currency data. If the CRM connector has an alias, then the alias replaces `` in the name.
- The Salesforce CRM connector syncs active and inactive currencies and static conversion rates to the associated currencies connection in Data Cloud.
- When the Salesforce admin adds currencies or updates the conversion rate in a Salesforce CRM org, Data Cloud syncs these changes, and the static rate conversion DMO is updated within a few minutes.
In a multiple-currency organization, Data Cloud uses the same process to sync its currency data from each connected Salesforce org and follows a similar naming convention for the DLO and DMOs it creates. In addition to the DLO and DMOs, Salesforce creates a data stream named `Static_CurrencyType_`. Each CRM org manages its own currencies and conversion rates.

Note We recommend not adding formula fields to the data stream.
- If an org context is present for the Data Cloud query, Data Cloud uses the conversion rate from the org. For example, Data Cloud applies the currency conversion rates from a logged-in user’s org when:
- The user’s actions trigger queries on Data Explorer or Data Cloud reports
- The user executes SQL or SOQL queries using an API
- If an org context isn’t present for the Data Cloud query, Data Cloud applies the default conversion rates. Examples include background and service processes such as data pipelines running data transforms, segmentation, and activation.
- Data Cloud applies these conversion rates.
| Data Cloud Process | Org Used for Conversion Rate |
| --- | --- |
| Data transforms, data actions, insights, segmentation, and activation | Default CRM org. The first CRM org connected to Data Cloud is the default org unless the admin changes it. |
| Data Cloud query services | User’s logged-in org. A user can override these rates using SQL statements. |
| SOQL queries on Data Cloud objects | User’s logged-in org. A user can’t override these rates using SOQL statements. |
- **[Considerations for Using Multiple Currencies in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_multi_currency_considerations.htm&release=264.0.0&type=5)**
Keep these considerations in mind when using multiple currencies in Data Cloud.
- **[Billing Considerations for Multi-Currency Usage](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_multi_currency.htm&release=264.0.0&type=5)**
Use of multiple currencies in Data 360 impacts the consumption of credits in these usage types. Credits are consumed for setting up currencies and maintaining them over time.
- **[Review Currencies Connection Status in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_multi_currency_view_status.htm&release=264.0.0&type=5)**
If your Data Cloud org uses multiple currencies from your Salesforce CRM org, you can review the associated connection’s status.
- **[Disable a Currency Connection in Data Cloud](https://help.salesforce.com/s/articleView?id=data.c360_a_multi_currency_disable.htm&release=264.0.0&type=5)**
While we recommend keeping the currency connection in Data Cloud enabled, if you plan to disconnect a standard Salesforce CRM connection from Data Cloud, disable the currency connection to Data Cloud first.
# Using Retrieval Augmented Generation
Retrieval Augmented Generation (RAG) in Data 360 is a framework for grounding large language model (LLM) prompts. By augmenting the prompt with accurate, current, and pertinent information, RAG improves the relevance and value of LLM responses for users.
When you submit an LLM prompt, RAG in Data 360:
1. Retrieves relevant information from structured and unstructured data indexed in Data Cloud’s vector database
2. Augments the prompt by combining this information with the original prompt
3. Generates a prompt response
It’s helpful to think of RAG in two main parts: offline preparation and online usage.
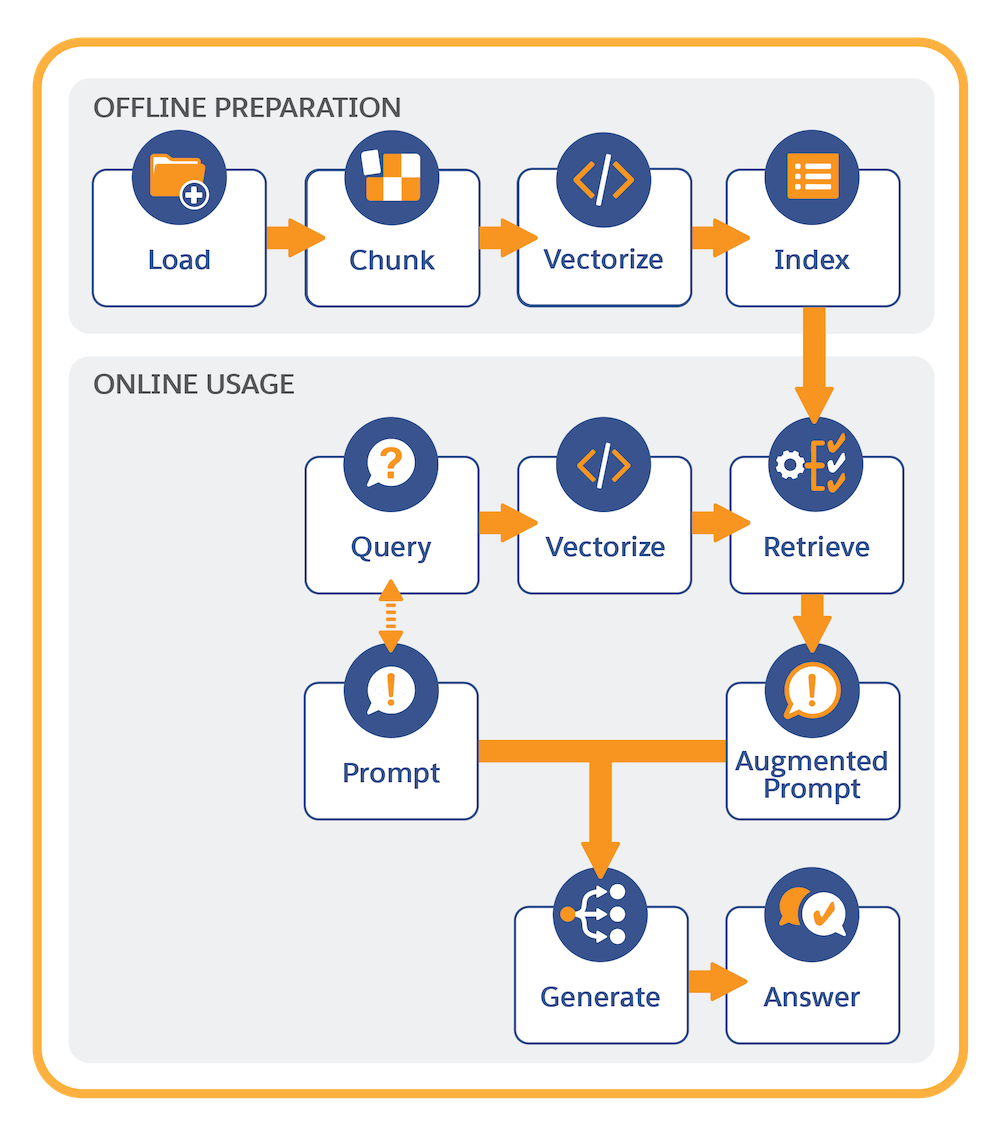
## Offline Preparation
To implement RAG, start by connecting structured and unstructured data that RAG uses to ground LLM prompts.
Data 360 uses a vector database to manage unstructured data. The vector database contains a collection of structured and unstructured content (a search index) that is indexed in a search-optimized way. Content can be ingested from a variety of sources and file types. Some examples of unstructured content used with RAG include service replies, cases, RFP responses, knowledge articles, emails, and meeting notes.
Offline preparation involves these steps:
1. Connect your unstructured data.
2. Create a search index configuration to chunk and vectorize the content.
Chunking breaks the text into smaller, semantically meaningful units, and vectorization converts chunks into numeric representations of the text that capture semantic similarities.
3. Store and manage the search index in Data 360.
Retrievers serve as the bridge between search indexes and prompt templates. Retrievers further refine the search criteria and retrieve the most relevant information used to augment prompts. To support a variety of use cases, you create custom retrievers in AI Models (formerly Einstein Studio). To learn more, see [Retrieve Data](https://help.salesforce.com/s/articleView?id=data.c360_a_ai_retriever.htm&language=en_US).
## Online Usage
The final piece of the RAG implementation is to call a retriever in a prompt template. For a given prompt template, the prompt designer can customize retriever query and result settings to populate a prompt with the most relevant information.
Online usage involves these steps:
1. The retriever is invoked with a dynamic query initiated from the prompt template.
2. The query is vectorized (converted to numeric representations). Vectorization enables search to find semantic matches in the search index.
3. The query retrieves the relevant context from Data 360’s vector database.
4. The original prompt is populated with the information retrieved from the search index.
5. The prompt is submitted to the LLM, which generates and returns the prompt response.
Many LLMs were trained generally across the Internet on older content. With RAG, prompt template users can provide the LLM with the most accurate, up-to-date information, as well as bring proprietary data to the LLM without retraining and fine-tuning the model, creating generated responses that are more pertinent to their context and use case.
#### See Also
- [_Salesforce Help_: Manage Retrievers in Einstein Studio](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&release=264.0.0&type=5 "Grounding Data 360 search on unstructured and structured data enhances your use of generative AI, analytics, and automation tools across Salesforce. Grounding brings customer-specific data, including diverse forms of unstructured data (such as text documents, multimedia files, social media content, web content, chat logs, sensor data, and customer feedback), into applications like Agentforce, Tableau, and Flow Builder. This alignment results in more accurate and relevant AI-generated content, deeper insights from analytics, and more efficient automation workflows for your teams and customers.")
- [_Salesforce Help_: Ground with Retriever Augmented Generation (RAG) in Data 360](https://help.salesforce.com/s/articleView?id=ai.prompt_builder_ground_rag.htm&type=5&language=en_US)
- [_Trailhead_: Retrieval Augmented Generation: Quick Look](https://trailhead.salesforce.com/content/learn/modules/retrieval-augmented-generation-quick-look)
# Using the Aggregate Node
The aggregate node performs a calculation on a set of values and returns a single value. For example, Average returns the average value of a numerical column. You can use dimensions to roll up the records to a higher granularity. Dimensions, which are typically textual, categorize and describe data by supplying qualitative data points. They are commonly used to filter and segment data based on specific characteristics, such as customer ID, product type, location, or date. Dimensions provide context for measurements, which allows for analysis across different aspects of a dataset.

Note For real-time insights, aggregate nodes must use fields with a real-time source. Otherwise, the result is blank.
Approximate Count Distinct
Calculates the relative rank of a row within a group of rows.
Average
Calculates the average of all the values in the selected field.
Supports numerical values.
Count
Counts all values in the selected field.
Supports date, text, and boolean measures.
Dense Rank
Returns the rank of each row within a result set partition, with no gaps in the
ranking values.
First Value
Returns the first value from the unsorted data records. The results may change in
a future insight processing job. For a consistent result use the Min or Max.
Last Value
Returns the first value from the unsorted data records. The results may change in
a future insight processing job. For a consistent result use the Min or Max.
Lead
Returns the value from the preceding row.
Maximum
Calculates the maximum value of the selected field.
Supports numerical values.
Minimum
Calculates the minimum value of the selected field.
Supports numerical values.
NTile
Distributes the rows in an ordered partition into a specified number of groups.
The groups are numbered, starting at one. For each row, NTILE returns the number of
the group to which the row belongs.
Percent Rank
Calculates the relative rank of a row within a group of rows.
Rank
Returns the rank of each row within the partition of a result set. The rank of a
row is one plus the number of ranks that come before the row in question.
Row Number
Returns the sequential number of a row within a partition of a result
set.
Sum
Calculates the total by adding all values in the selected field. Supports
numerical values.
# Using the Case Node
The case node, similar to the CASE statement in SQL, analyzes data by comparing the attributes of conditions. The WHEN/THEN statements determine the outcome based on whether all or any of the specified conditions are true. If none of the WHEN conditions are met, the ELSE statement provides an alternative action. The Case node statement must be followed by at least one WHEN/THEN pair, which applies a designated function when the associated condition is true.
equal Returns values that are equal to the specified value. not Returns values that are not equal to the specified value. is null Returns a null value when conditions are met. is not null Returns a not null value when conditions are met. For example, filtering a field to ensure that the value exists. less than Returns values that are less than the specified value. less than or equal to Returns values that are less than or equal to the specified value. greater than Returns values that are greater than the specified value. greater than or equal to Returns values that are greater than or equal to the specified value. is empty Returns empty values. For example, an empty string is a string with zero length. contains Checks if the given value can be found in the results. does not contain Checks whether the specified value is not present in the results. contains regular expression Checks whether the specified matching string is present in the results. does not contain regular expression Checks whether the specified matching string is not present in the results.
# Using the Filter Node
The filter node uses the selected operator and value to keep or remove data based on whether any or all of the specified conditions are met.
equal
Returns values that are equal to the specified value.
not
Returns values that are not equal to the specified value.
is null
Returns a null value when conditions are met.
is not null
Returns a not null value when conditions are met. For example, filtering a field
to ensure that the value exists.
less than
Returns values that are less than the specified value.
less than or equal to
Returns values that are less than or equal to the specified value.
greater than
Returns values that are greater than the specified value.
greater than or equal to
Returns values that are greater than or equal to the specified value.
is empty
Returns empty values. For example, an empty string is a string with zero length.
contains
Checks if the given value can be found in the results.
does not contain
Checks whether the specified value is not present in the results.
contains regular expression
Checks whether the specified matching string is present in the results.
does not contain regular expression
Checks whether the specified matching string is not present in the
results.
Relative DateTime
Expresses a date and/or time value that changes based on the current date and
time. Intervals include:
Last N Days, Hours, Minutes, and Seconds
Next N
Days, Hours, Minutes, and Seconds
# Using the Join Clause for Insights
A calculated insight can simultaneously access multiple data model objects (DMOs). A calculated insight query that accesses multiple rows of the different DMOs at one time is called a join query. Data 360 supports four types of joins in a calculated insight: inner, left, right, and full.
### Required Editions
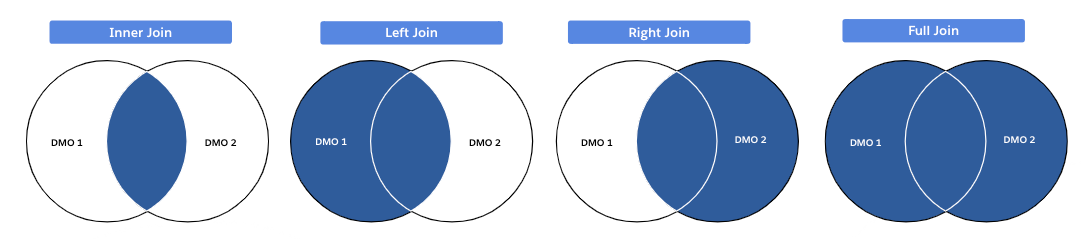
## Inner Join
An inner join returns all records that have matching values in two DMOs.

Example
```sql
SELECT
SUM(SALESORDER__dlm.grand_total_amount__c) as TotalOrderAmount__c,
Individual__dlm.Id__c as CustomerId__c
FROM SALESORDER__dlm
INNER JOIN Individual__dlm ON SALESORDER__dlm.partyid__c = Individual__dlm.Id__c
GROUP BY CustomerId__c
```
## Left Join
A left join returns all records from the left table and the matched records from the right DMO.

Example
```sql
SELECT
SUM(SALESORDER__dlm.grand_total_amount__c) as TotalOrderAmount__c,
Individual__dlm.Id__c as CustomerId__c
FROM SALESORDER__dlm
LEFT JOIN Individual__dlm ON SALESORDER__dlm.partyid__c = Individual__dlm.Id__c
GROUP BY CustomerId__c
```
## Right Join
A right join returns all records from the right table and the matched records from the left DMO.

Example
```sql
SELECT
SUM(SALESORDER__dlm.grand_total_amount__c) as TotalOrderAmount__c,
Individual__dlm.Id__c as CustomerId__c
FROM SALESORDER__dlm
RIGHT JOIN Individual__dlm ON SALESORDER__dlm.partyid__c = Individual__dlm.Id__c
GROUP BY CustomerId__c
```
## Full Join
A full join returns all records when there’s a match in either the left or right DMO.

Example
```sql
SELECT
SUM(SALESORDER__dlm.grand_total_amount__c) as TotalOrderAmount__c,
Individual__dlm.Id__c as CustomerId__c
FROM SALESORDER__dlm
FULL JOIN Individual__dlm ON SALESORDER__dlm.partyid__c = Individual__dlm.Id__c
GROUP BY CustomerId__c
```
- **[Autopopulated Join Keys in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_auto_populate_join_keys_in_customer_data_platform.htm&release=264.0.0&type=5)**
When you join two or more objects in Insight Builder, the join nodes and join keys are autopopulated based on their relationships in Data 360. A key join is a simple way to join link tables. Autopopulated join nodes make it easy to connect engagement data with a unified profile and override autosuggested joins.
# Using the Join Node
The Join node combines data from multiple sources based on shared values. A column represents a category of information, such as an opportunity source or account name.
Inner join Returns matching field values from the two selected columns. Left join Returns matching field values from the left column and the matched records from the right column. Right join Returns matching field values from the right column and the matched fields from the left column. Full join Returns matching field values when there’s a match in either the left or right column.
# Using the Transform Node
Use a Transform node to manipulate data based on the transformations added to the node. To manipulate data at multiple stages of a data transform, add a separate Transform node at each stage.
Absolute Value
Takes the value from the field and returns its absolute value.
CDP Hour
CDP Day
CDP Month
CDP
Quarter
CDP Year
Returns the a timestamp value truncated at the Year, Quarter, Month,
Day, or Hour precision.
When using the CDP time functions, Metrics will be
aggregated at different granularities. See Calculated Insights Processing and Retention
Times for more details.
Current Date
Returns the current date at the start of the query evaluation. All current_date
calls within the same query return the same value.
Date Addition
Adds a number of days to the date value based on the integer value of the second
function parameter. Returns the date that is the number of days after the start
date.
Date Difference
Returns the number of days from start date to end date.
Date Subtraction
Subtracts a number of days from the date value based on the integer value of the
second function parameter. Returns the date that is the number of days before the
start date.
Date Truncation
Returns the timestamp expression truncated to the unit specified by the format
model.
Day
Returns day component of the string or timestamp.
Day of Week
Day of Month
Day of Year
Returns the day of the week, month, or year for a date or timestamp.
Hour
Returns the hour component of the string or timestamp.
Left Trim
Removes leading spaces from strings.
Lowercase
Returns the input as an all-lowercase string.
Mod
Returns the remainder of a number divided by another number.
Month
Returns the month component of the string or timestamp.
Quarter
Returns the quarter component of the string or timestamp.
Random
Returns a random number between 0 (inclusive) and 1 (exclusive).
Regular Expression
Defines a sequence of characters, used to search and locate specific sequences of
characters that match a pattern.
Regular Expression Extract
Creates dimension values by extracting them from a source dimension using Google
RE2 regular expressions.
Regular Expression Replace
Extends the functionality of the REPLACE function by letting you search a string
for a regular expression pattern.
Null If
Compares two expressions. If the values are equal, it returns NULL. If they are not
equal, it returns the first expression.
Right Trim
Removes trailing spaces from strings.
Round
Rounds a number to the specified decimal place.
Substring
Returns a portion of the string beginning at a specified position and having a
specified length. Alternatively, get a slice of the byte array starting at a specified
position and having a specified length.
Trim
Removes leading and trailing spaces from strings.
To Date
Parses the date string expression with the format expression to a date. Returns
null if the input isn’t valid.
To Timestamp
Parses the timestamp string expression with the format expression to a timestamp.
Returns null if the input isn’t valid.
Uppercase
Returns the input as an all-uppercase string.
Year
Returns the year component of the string or timestamp.
# Using Unstructured Data in Data 360
Use unstructured data in Data 360 to ground Agentforce agents, generative AI, analytics, and automation use cases with business-specific data that delivers deeper insights for your users and customers.
Unstructured data comes in many forms. Consider these common examples.
| Type of Data | Examples |
| --- | --- |
| Text documents | Case notes, reports, internal memos, handwritten notes, invoices, business cards, and emails that contain detailed descriptions or conversations |
| Multimedia files | Audio files from customer service calls, podcasts, video recordings from training sessions, tutorials, meetings, images from product reviews, infographics, scanned documents, and medical imaging |
| Social media content | Comments, posts, or messages containing customer feedback, opinions, or sentiments |
| Web content | Blogs, articles, and forum posts that discuss products, services, or customer experiences |
| Chat logs | Conversations from live chat support, often containing nuanced questions, complaints, and preferences |
| Sensor and IoT data | Data from wearable devices or machinery that doesn't follow a standard format, such as raw accelerometer data |
| Customer feedback | Survey responses, feedback forms, or reviews written in free text |
Data 360 supports several connectors and file formats for unstructured data. See [Unstructured Data Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_data_connect.htm&release=264.0.0&type=5) and [Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.").
Using unstructured data in your AI, automation, and analytics workflows can help you make informed decisions and improve customer experiences.
## Agentforce Agents
Data 360 provides customer data to make agents more contextually aware and knowledgeable. For example, when a customer contacts an Agentforce Service Agent, Data 360 can add unstructured data, such as information from past emails, support tickets, product photos, or voicemails, to help the agent to better understand the customer's perspective. Data 360 hybrid search can then find the appropriate knowledge articles to resolve the issue. When a service case is resolved, Data 360 can guide the agent with next steps, such as automating follow-up emails or preparing detailed chat summaries.
Here's an example of an agent in action.
## Generative AI
Retrieval augmented generation (RAG) improves AI responses by grounding them in unstructured data, making them more relevant and accurate. To learn more, see [Using Retrieval Augmented Generation](https://help.salesforce.com/s/articleView?id=data.c360_a_rag_overview.htm&release=264.0.0&type=5 "Retrieval Augmented Generation (RAG) in Data 360 is a framework for grounding large language model (LLM) prompts. By augmenting the prompt with accurate, current, and pertinent information, RAG improves the relevance and value of LLM responses for users.") and [Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5 "When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.").
In Service Cloud, agents can use hidden data in knowledge articles to answer customer questions more accurately. By working with Data 360, agents can look at unstructured data, like emails, support tickets, and chat logs, to get more information and write better responses, including suggestions for fixing problems before they happen.
In Sales Cloud, agents can use unstructured data, including emails, call transcripts, and notes, to generate detailed and contextually relevant meeting briefings and summaries. These insights improve new emails with personalized content and customer-specific recommendations, improving the customer experience and sales team effectiveness.
## Automation
Agents can automate the identification of similar records, such as Cases, based on their descriptions to flag duplicates and speed up resolution. Additionally, agents can classify records by finding and using semantically similar ones, improving efficiency and accuracy.
## Analytics
Agents can use Tableau to gain insights from unstructured data, such as topic classification. Check out the example in [Enhancing Data Analysis with Vector Search in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_search_analytics.htm&release=264.0.0&type=5 "Find and analyze data based on meanings, not just keywords, by using vector search in a Tableau query. Vector search broadens the scope of data exploration as well as enhances the accuracy and relevance of the insights by identifying semantic similarities rather than relying solely on exact keyword matches.").
## Team-based Examples
Consider these use cases for how to use unstructured data across the various functions.
| Team | AI | Automation | Analytics | Search |
| --- | --- | --- | --- | --- |
| Sales | Draft responses to RFPs using previous proposals, contracts, and documentation. | Analyze email conversations to automate lead scoring. | Analyze recorded sales calls to spot patterns in competitive insights or feature interests. | Prep sales calls with insights from thousands of PDFs and emails. |
| Service | Estimate repairs through photo analysis. | Proactively send repair recommendations by identifying patterns in agent assets. | Analyze chat and product logs to identify common recurring service problems. | Get context-based knowledge article recommendations. |
| Marketing | Find subject lines that have worked on similar email templates. | Automate campaign follow-up based on specific product interests found in support chats. | Spot trends based on customer feedback on websites. | Search feedback from surveys to create more responsive campaigns. |
#### See Also
- [_Trailhead_: Unstructured Data in Data 360](https://trailhead.salesforce.com/content/learn/projects/unstructured-data-in-data-cloud.html)
- [_Salesforce Help_: Use Search for AI, Automation, and Analytics](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_ground_ai.htm&release=264.0.0&type=5 "Grounding Data 360 search on unstructured and structured data enhances your use of generative AI, analytics, and automation tools across Salesforce. Grounding brings customer-specific data, including diverse forms of unstructured data (such as text documents, multimedia files, social media content, web content, chat logs, sensor data, and customer feedback), into applications like Agentforce, Tableau, and Flow Builder. This alignment results in more accurate and relevant AI-generated content, deeper insights from analytics, and more efficient automation workflows for your teams and customers.")
- [_Salesforce Help_: Design and Implement Agents](https://help.salesforce.com/s/articleView?id=ai.copilot_intro.htm&language=en_US)
# Validate an Insight in Data 360
After creation, validate your calculated or streaming insight in Data Explorer to ensure that your data and formulas are accurate. You must validate an insight before you use it in a segment.
### Required Editions
1. In Data Cloud, go to the Data Explorer tab.
2. From the Data Space dropdown, select a data space.
3. From the Object dropdown, select **Calculated Insights**, and then select a calculated or streaming insight.
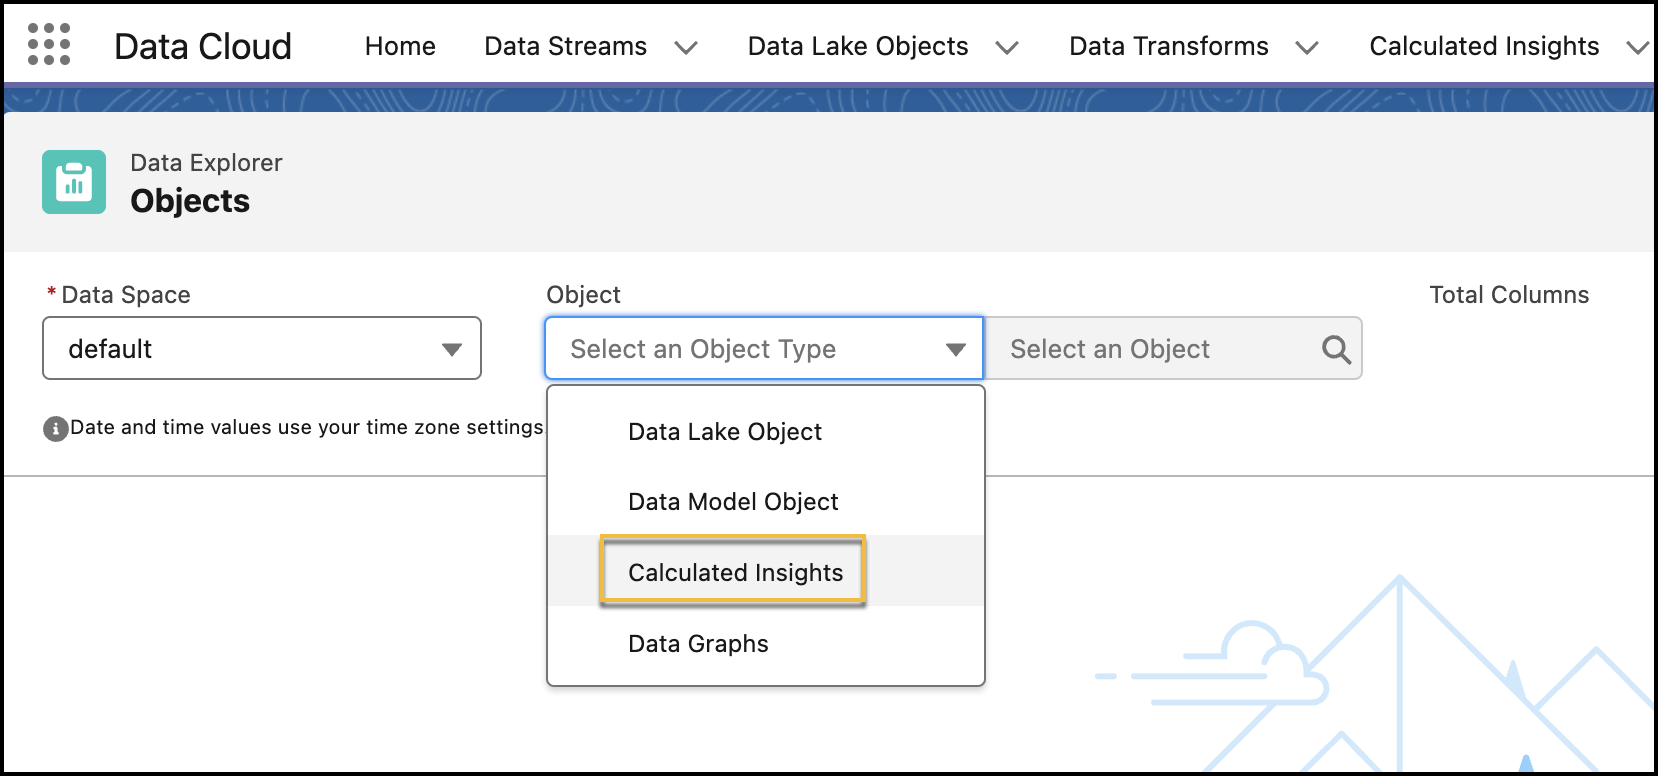
4. Review the data and results of your selected insight.
You can personalize your view by editing the columns and use filters to show only the most relevant data for your selected insight. You can sort the data in descending or ascending orders by clicking a data column.
For streaming insights, if there isn’t any new streaming data ingested, no data is displayed in any of the columns. To process a streaming insight, data must be ingested continuously during a specified time interval. You can check the status of a streaming data transform from the **Refresh History** of a data stream. For calculated insights, you must wait until your insight is processed to validate it in Data Explorer. You can check the status of a calculated insight on its record home page.
#### See Also
- [_Salesforce Help_: Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_data_explorer.htm&release=264.0.0&type=5 "With Data Explorer, you can validate data lake objects, data model objects, calculated insights, and data graphs to ensure that your data and formulas are accurate.")
# Validating Clean Rooms in a Sandbox Org
To verify query results, test your clean room packages, configurations, and data mappings in a Developer or Developer Pro Data 360 sandbox. When the query run yields expected results, deploy the mapped templates from a sandbox org to a production org.
### Required Editions
Available in: Enterprise Edition sandboxes (Developer or Developer Pro Data 360 sandbox types) Developer or Developer Pro sandbox is different from a Salesforce Developer Edition org. Create and distribute clean room packages from a Developer Edition org. Manage collaborations and accept invitations from an Enterprise Edition home org or its sandbox.
If you create a Data 360 sandbox after clean rooms are set up in production, the clean room packages and mapped templates are replicated in the sandbox. However, clean room collaborations aren’t replicated in the sandbox.
To initiate your clean room configuration in the sandbox, deploy a clean room package.

Note If you're installing a Clean Room package in a sandbox org, replacelogin.salesforce.com with test.salesforce.comin the package install link to avoid authentication failures.
If you’re collaborating with a known partner, allowlist their sandbox org ID. You can collaborate with allowlisted orgs without a clean room package. You can't initiate a collaboration to a production org from a sandbox and vice versa. Ensure both orgs are of the same type (both sandbox or both production) before setting up a collaboration. If you’re a provider, use two sandbox orgs to validate your clean room configuration.
#### See Also
- [_Salesforce Help_: Create a Data 360 Sandbox](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_create.htm&language=en_US)
- [_Salesforce Help_: Deploy Data 360 Changes Across Orgs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_cloud_sandbox_deploy.htm&language=en_US)
# Vector Search
In Data 360, you can create searchable semantic vector embeddings from your unstructured and structured data. Vector search helps your generative AI, automation, and analytics applications understand semantic similarities and context between embeddings.
### Required Editions
Vectorization is the process of embedding your unstructured data into numerical representations of data that machines can read. Vector embeddings are used to measure the semantic closeness of different pieces of text to create accurate and relevant results in your RAG and agent queries.
Data 360 indexes this data. When you create a vector search index using the Data 360 search index UI or Connect API, you first chunk the unstructured data stored in DMOs and UDMOs. Chunking breaks the data into manageable, semantically meaningful units. Next Data Cloud generates vector embeddings from those chunks. Chunks are stored in chunk data model objects (CDMOs) and vector embeddings are stored in index daa model objects (IDMOs).
After the vector embeddings are added to the search index, you can perform vector searches on that data from apps such as Prompt Builder, AI agents, or Tableau.
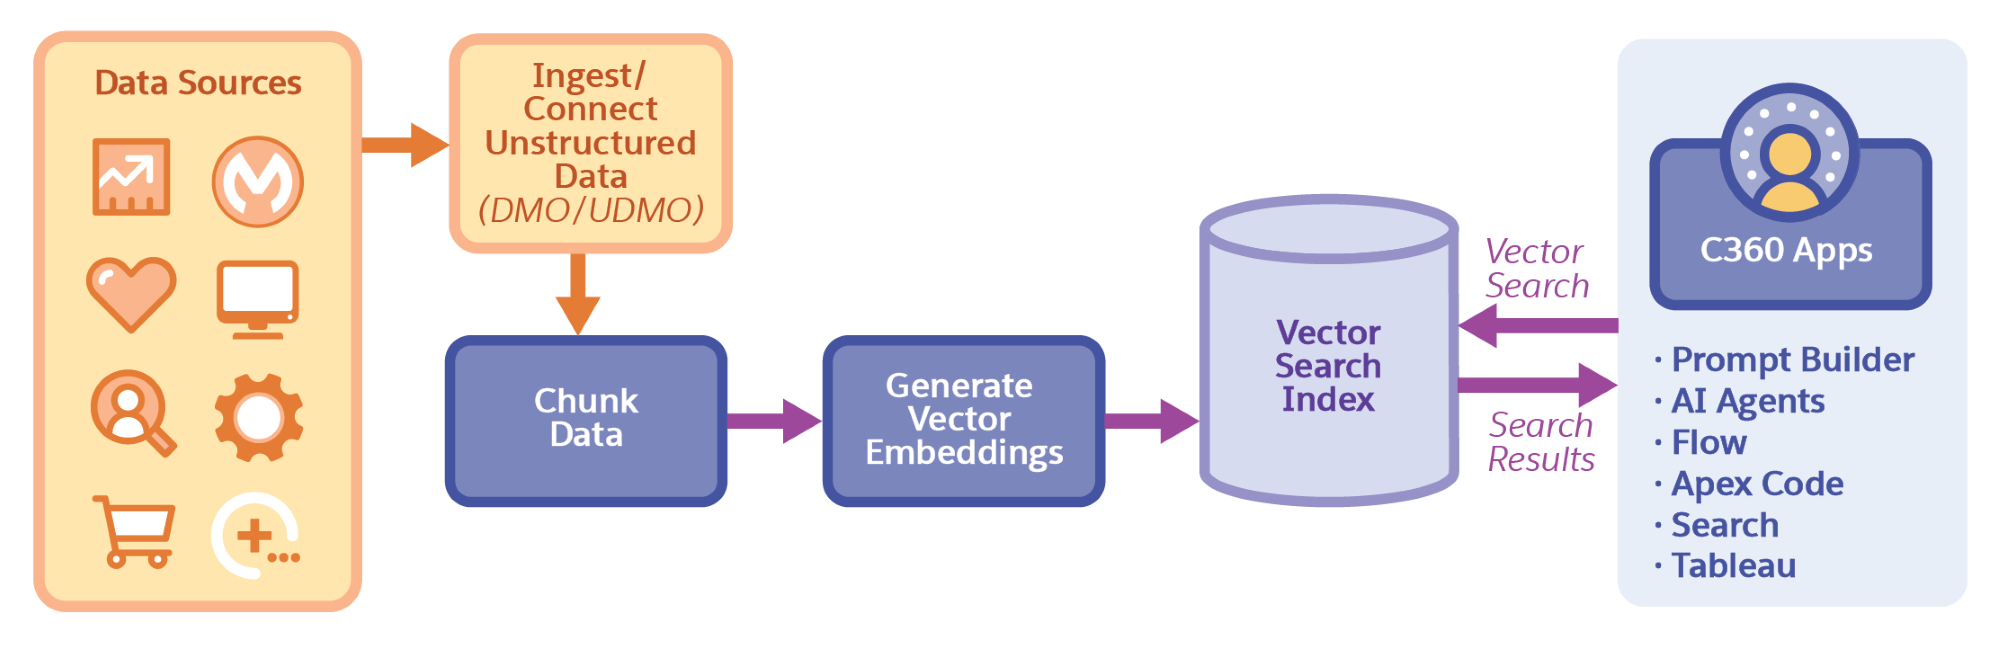
- **[Create a Vector Search Index with Advanced Setup](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_create_vector_index_config.htm&release=264.0.0&type=5)**
When you create a vector search index configuration for a data model object, Data 360 breaks up the referenced data into semantically related chunks and generates searchable vectors. Your RAG and agent workflows use these vectors to find and return semantically similar items when they run queries. To get more granular control over your search index configuration, use the advanced setup, which guides you through each step of the process.
- **[Run Vector Searches Using Query API](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_query.htm&release=264.0.0&type=5)**
Use the Query API to run vector searches in Data 360. Use these examples as starting points.
- **[Retrieving Content with Vector Search](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_retrieve_content.htm&release=264.0.0&type=5)**
With vector search and AI agent queries, you can capture queries, search across structured and unstructured data sources, and receive summarized responses that improve efficiency and accuracy.
- **[Enhancing Data Analysis with Vector Search in Tableau](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_vector_search_analytics.htm&release=264.0.0&type=5)**
Find and analyze data based on meanings, not just keywords, by using vector search in a Tableau query. Vector search broadens the scope of data exploration as well as enhances the accuracy and relevance of the insights by identifying semantic similarities rather than relying solely on exact keyword matches.
#### See Also
- [_Salesforce Help_: Search Index Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5 "Data 360 search supports many different file formats with unstructured data, embedding models, and pre-filter operations on search results.")
# Vector Search Query Expressions and Pre-Filtering
Enhance your vector search queries with pre-filtering fields. Use logical operators and manage case sensitivity for field names and values to ensure precise data retrieval.
## Supported Operators
Use logical operators to test the values in each pre-filtering field. To learn more, see [Supported Operators](https://help.salesforce.com/s/articleView?id=data.c360_a_search_index_reference.htm&release=264.0.0&type=5).
## Filter Expressions in Vector Search
Expressions Types
Examples
Notes
Expressions with NOT, IN, AND, OR operators
strField1 != 'v1' and
strField2 = 'v2' and
(strField3 = 'v3' or
strField4 not in ('a', 'b', 'c') or
strField5 in ('a', 'b', 'c')
) and
strField6='v6'
You can combine individual filters using the logical and and
or operators.
Simple pre-filter expression in a SQL expression
select * from
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'RecordId__c=''1c1c533c-1bc0-40cb-8bd8-f4b6e6e101b7''',
10)
)
When the pre-filter condition is part of the SQL expression the quotes in the
filter expression have to be escaped by doubling them.
Complex pre-filter expression in a SQL expression
select * from
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'strField1 != ''v1'' and
strField2 = ''v2'' and
(strField3 = ''v3'' or
strField4 not in (''a'', ''b'', ''c'') or
strField5 in (''a'', ''b'', ''c'')) and
strField6=''v6''', 10)
When the pre-filter condition is part of the SQL expression the quotes in the
filter expression have to be escaped by doubling them.
Pre-filtering on a field which is of date/datetime data type with standard (Z)
offset.
select * from
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'DateTimeTypeWithTimezone=''2024-05-08T15:28:07.000Z''',
10)
Pre-filtering on a field which is of date/datetime data type with custom
offset.
select * from (
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'DateTimeTypeWithTimezone=''2024-05-08T15:28:07.000-08:30''',
10)
Pre-filtering on a field with date only.
select * from
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'DateType=''2024-05-08''',
10)
Pre-filtering on a field which is of string data type with the LIKE
operator.
select * from
vector_search(
TABLE('some_VDMO'),
'some_search_text',
'StrField LIKE ''prefix%''',
10)
The LIKE operator must be used with a value with a single trailing wildcard
character (%). The following are examples of invalid LIKE
filters.
'StrField LIKE ''%prefix%'''
'StrField LIKE ''%prefix'''
'StrField LIKE ''prefix%suffix'''
## Case Sensitivity on Pre-filtering Fields
Names of pre-filtering fields are case insensitive. For example, if the name of a field is `My_Column_c` , a filter expression with `my_column_c` correctly references that field. However, case matters for values used within filters. If the field has a value `SomeValue,` the filter expression `My_Column_c='somevalue'` or `My_Column_c='SOMEVALUE'` results in a no-match—only the expression `My_Column_c='SomeValue'` matches that record.
## Default Pre-filtering Fields
The field `DataSource__c` from the chunk data model object (CDMO) is a default pre-filtering field. It is always available in pre-filtering queries.
## Pre-filtering Values for Objects in 1:N Relationships
When creating a search index, you can index only one pre-filtering value.
Consider this example. You create a search index in which the indexed chunk data model object (CDMO) is in a 1:N relationship with related records from which a pre-filtering value is extracted. In the relationship, the CDMO `{"chunkId":"1"}` matches both `{"filterRecordId"="123": "filterValue": "tag1"}` and `{"filterRecordId"="123": "filterValue": "tag2”}`.
Data 360 indexes only one of these filtered values for retrieval, and there’s no guarantee which one is indexed. For example, Data 360 may index`{"chunkId":"1", "filterValue":"tag1"}` or `{"chunkId":"1", "filterValue":"tag2"}` but not `{"chunkId":"1", "filterValue":["tag1", "tag2”]}`.
# Verify and Reauthenticate a Salesforce CRM Connection
Verify your Salesforce CRM connection trust and re-authenticate if disruption was caused by a sandbox refresh, or if trust relationship between the home org CRM connection and Data 360 is broken. If your Salesforce org has a CRM connection to a sandbox org, and that sandbox has recently refreshed, the refresh process generates a new Org ID for the sandbox org that conflicts with the Org ID associated with the existing connection. Because Data 360 can’t establish trust with the refreshed sandbox, the connection to Data 360 is disrupted and requires reauthentication. When the connection is disrupted, data streams associated with it can encounter errors, including deployment failures for new streams and errors within the stream’s refresh history.
### Required Editions
User Permissions Needed
To reauthenticate a connection
System admin profile OR
Data 360 Architect permission
set
- To verify the connection’s trust, you can initiate a row-level action on the connection record on the Salesforce CRM page and follow Data 360’s on-screen instructions if reauthentication is needed. Reauthenticating the connection updates the connection record’s Org ID to match the refreshed sandbox’s Org ID and restores full connection functionality. After reauthenticating, you can create new data streams and data action targets as normal.
- Reauthentication also automatically connects existing data action targets to the refreshed sandbox and enables existing data streams to resume data ingestion from the refreshed sandbox.
- Authenticating a Salesforce CRM connection associated with a Data 360 One companion connection requires assistance from Support.
1. In Data 360, select **Setup** and select **Data 360 Setup**.
2. Under **Salesforce Integrations**, select **Salesforce CRM**.
3. Go to the connection for which you want to verify trust, and click the row-level action **Verify Connection**.
4. Follow the on-screen instructions to perform an action, depending on the status of the org associated with this connection, and whether it’s a sandbox org.
connection status
action
The connection is verified and doesn’t have trust issues.
Continue to use it.
The connection is associated with a Salesforce CRM production or development org, and
has trust issues. Its status updates to Needs Reauthentication .
The connection is associated with a Salesforce CRM home org and has trust issues. Its
status updates to Needs Reauthentication .
On the connection record, click the row-level action Reauthenticate Connection .
Data 360 reauthenticates the connection and updates its status to
Active .
The connection is associated with a Salesforce CRM sandbox org and has trust issues.
This indicates that the sandbox has been refreshed. The connection status updates to
Needs Reauthentication and a modal opens, indicating that the connection to the
sandbox needs to be reauthenticated.
Locate the newly refreshed sandbox's credentials (see tip below).
Click Reauthenticate on the modal to get redirected to the login
screen, or return to the Salesforce CRM Connection page and use the row-level action
Reauthenticate Connection on the connection record.
Log in using the credentials of the newly refreshed sandbox.
Confirm reauthentication by entering the Data 360 org identifier. You can find this ID
on the modal under Data 360 Org Details . This specifies which Data
360 org retrieves data from your source org. After confirming, check the checkbox to agree
to reauthenticate the connection and click Reautheticate
Connection .
Note that if the refreshed sandbox connection doesn’t have an alias, to maintain
consistent stream naming following the sandbox refresh, this connection's alias is set to
the original Org ID. When you reauthenticate, the connection is assigned the refreshed
sandbox's new Org ID, while the alias remains as the original Org ID.
The connection is associated with a Data 360 One companion
org.
Ask your Salesforce Account Representative to disconnect the associated Data 360 One org.
After Data 360 One is disconnected, return to the Salesforce CRM
Connection page and reauthenticate this sandbox connection using the
Reauthenticate Connection row-level action.
After the CRM connection to the newly refreshed sandbox is reaauthenticated, Set up a new Data 360 companion
connection for the refreshed sandbox on the Data 360 One page.
After you perform the required steps, your Salesforce CRM connection is verified and authenticated, and you can proceed to use it.

Tip
**How to find your sandbox’s credentials**
In the org where your sandbox was created, go to **Setup** > **Sandboxes**.
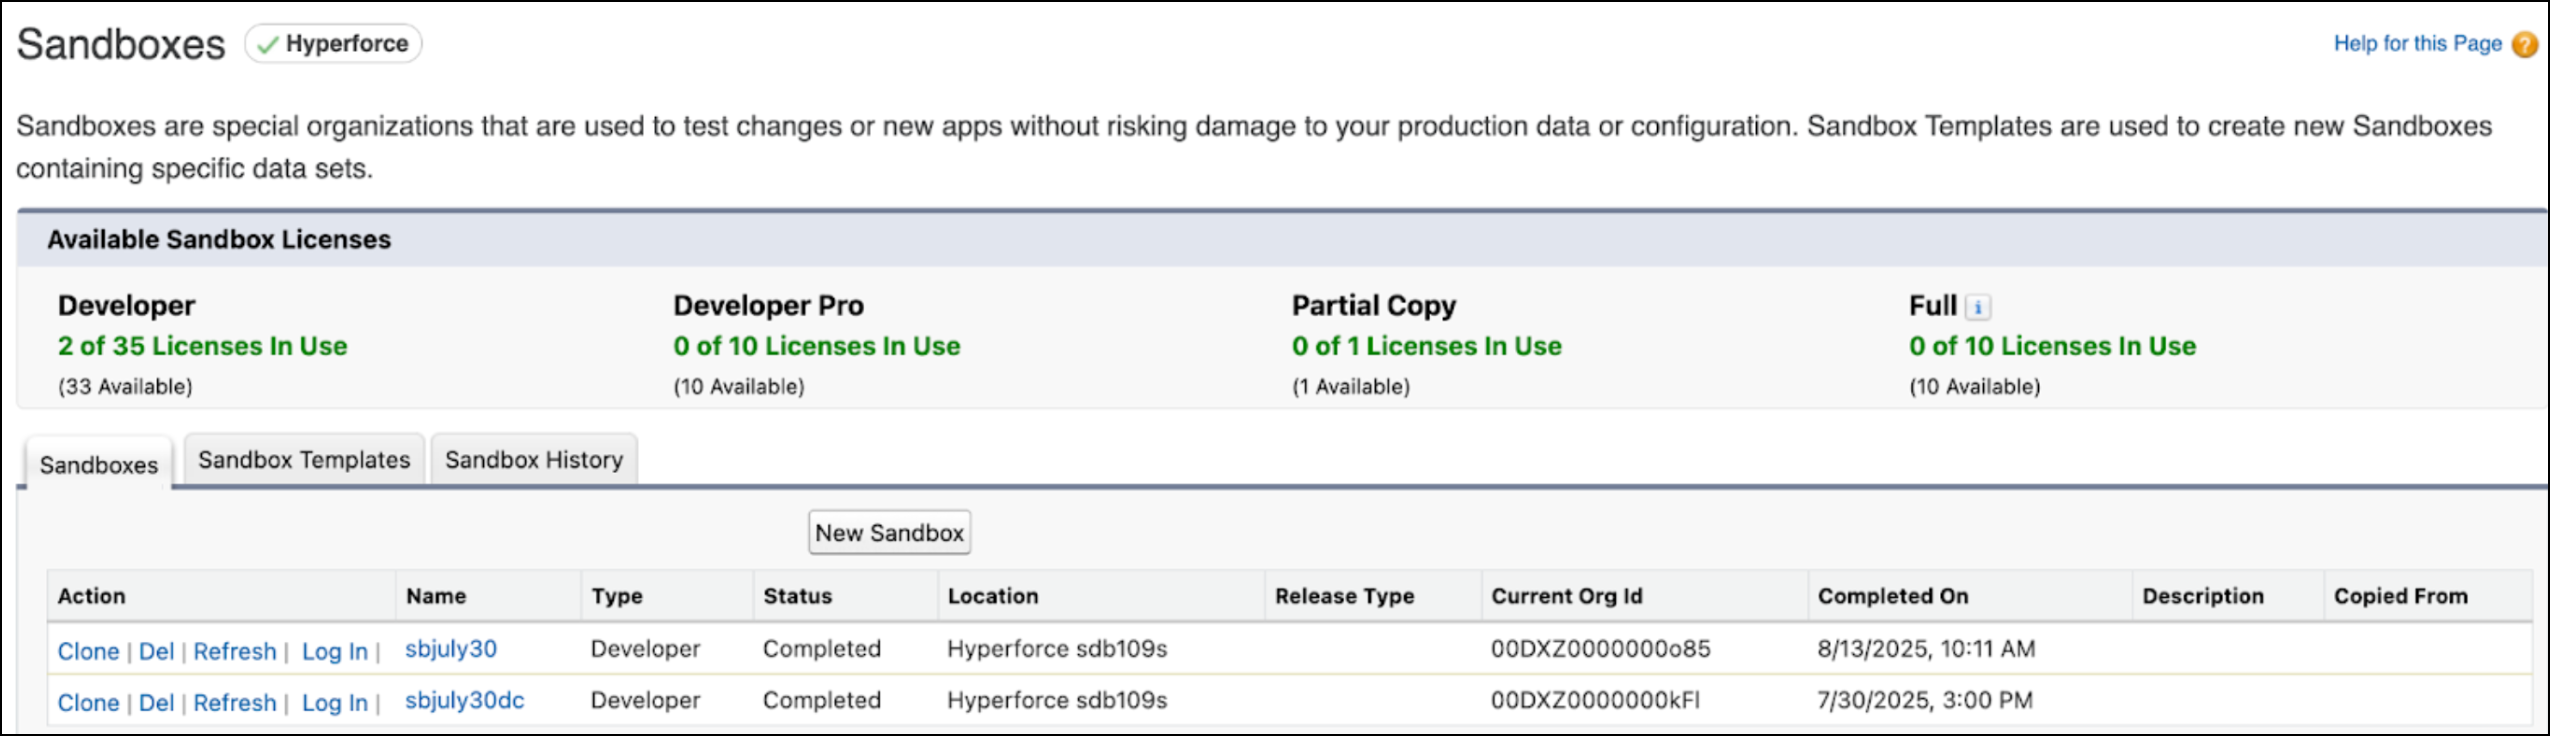
Find the username of the newly refreshed sandbox, which consists of the parent org’s username and the appended sandbox org name. For example, if the parent org’s username is epic.out.a865f8b0263c@orgfarm.salesforce.com, and the sandbox name is sbjuly30, then the username of the sandbox is epic.out.a865f8b0263c@orgfarm.salesforce.com.sbjuly30. The password is the same as the parent org’s.
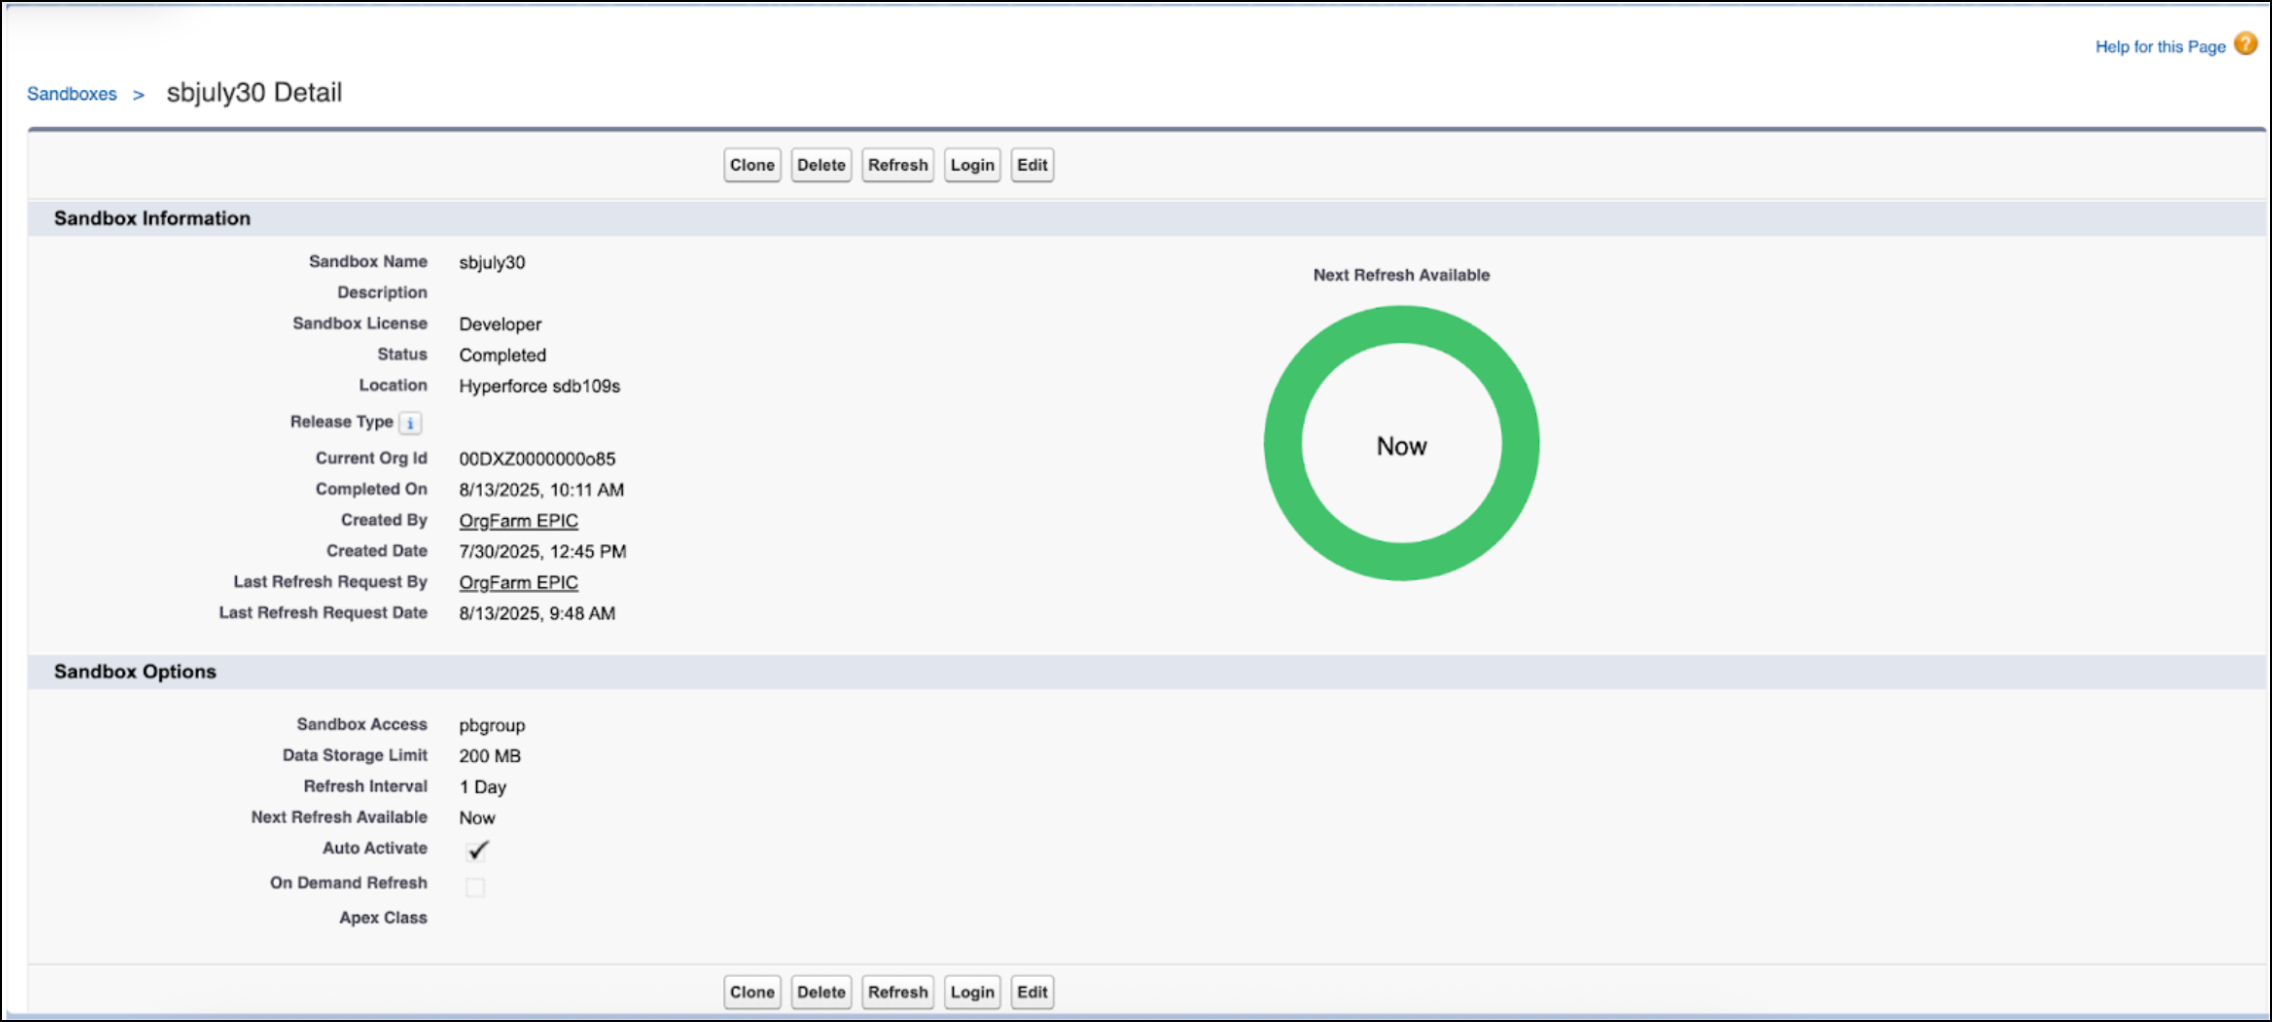
# Version Mismatch Errors in Data Cloud One Orgs
Data Cloud One supports mixed versions between home and companion orgs, but version mismatches can cause temporary metadata syncing delays in some circumstances. Metadata syncing between a home org and its companion org can be delayed when an object's schema changes between minor Salesforce versions. You can continue using all previously synced metadata even when syncing is in a temporary error state. Version mismatch errors resolve themselves as soon as both orgs upgrade to the same version.

Important You can continue using all previously synced metadata even when syncing is delayed or in an error state due to a version mismatch. Check your orgs’ versions to confirm the mismatch, then wait 24-72 hours for the syncing error to resolve automatically.
Version mismatches between Data Cloud One home and companion orgs can happen during minor upgrades, which happen as often as every two weeks. Although updates during major releases are typically backwards-compatible, some minor versions introduce schema changes that aren’t. New Salesforce versions roll out to different data centers at different times over a period of 24 to 72 hours. If your home org and companion org are provisioned at different data centers, especially if they’re in different regions, their versions can mismatch during the rollout period.
## Impacts of Version Mismatches
- You can establish new companion connections, but your initial metadata sync can show a pending or error status until your home org and companion org versions match.
- Syncing pauses if a version mismatch causes an object's schema to be different between the two orgs and if that particular object is being used. For example, if a Salesforce release introduces a new property in a data model object (DMO) and you are using that DMO, new metadata won’t sync until the home and companion orgs are on the same version.
- All previously synced Data 360 metadata remains usable in the mismatched companion org. However, new or changed metadata isn’t available until syncing resumes.
## Checking for Version Mismatches
We recommend checking what release version each org in your Data Cloud One org cluster is using before establishing new companion connections or if you notice delays in metadata syncing. You can’t change the timing of Salesforce updates, but knowing the current versions of each org helps you plan ahead.
To check versions, log into each Salesforce org. Append `/releaseVersion.jsp` to your domain URL. For example, `https://yourdomain.lightning.force.com/releaseVersion.jsp`. The page displays `ReleaseName=[Your Precise Version]`. For example, `ReleaseName=[111.22.33]`.
Compare the version for both the home and companion orgs. An org's minor version number is indicated by the second set of numbers. For example, if the version number is `111.22.33`, the number `22` indicates the minor version. Metadata syncing errors are usually caused by minor version mismatches.
## Handle Version Matches
You don’t have to take any action to resolve version mismatches. Version mismatches resolve within 24 to 72 hours. Metadata syncing automatically resumes when your home org and companion org versions match and schema mismatches resolve.
# View Activations in Data Explorer
View your activation data for a specific activation target in Data 360. You can view results up to the past 30 days.
### Required Editions
User Permissions
Needed
To view Data Explorer
Permission set:
1. In Data Cloud, click **Data Explorer**.
2. Select a data space.
3. From the Object dropdown list, select **Data Model Object**.
4. Select the DMO (for example, Activation Audience - Activation Target Name), and view the results.
- **[Find Segments in Data Model Objects (DMOs)](https://help.salesforce.com/s/articleView?id=data.c360_a_segments_in_audiences.htm&release=264.0.0&type=5)**
After you create and activate segments to Data 360, you can find segments via the Query API or in Data 360.
#### See Also
- [_Salesforce Help_: View Your Data in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_your_data.htm&release=264.0.0&type=5 "In Data Explorer, you can view Data 360 data from your data lake objects (DLOs), data model objects (DMOs), calculated insight objects (CIOs), or data graphs. You can personalize your view by editing the columns and use filters to show only the most relevant data for the selected object.")
# View Audience Insights in Data Explorer
View audience insights across different activations for a given target in Data 360. You can view results up to the past 90 days.
### Required Editions
User Permissions Needed
To view a DMO in Data Explorer:
One of these permission sets:
Data Cloud Architect
Data Cloud User
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, click **Data Explorer**.
2. Select a data space.
3. From the Object dropdown list, select **Data Model Object**.
4. Select the DMO (for example, Audience Insights - Activation Target Name), and view the results.
#### See Also
- [_Salesforce Help_: View Your Data in Data Explorer](https://help.salesforce.com/s/articleView?id=data.c360_a_view_your_data.htm&release=264.0.0&type=5 "In Data Explorer, you can view Data 360 data from your data lake objects (DLOs), data model objects (DMOs), calculated insight objects (CIOs), or data graphs. You can personalize your view by editing the columns and use filters to show only the most relevant data for the selected object.")
# View Clean Room Query Results
Check the latest output for a clean room query whenever a manual or scheduled run completes.
### Required Editions
Available in: Enterprise Editions
User Permissions Needed
To view clean room query results:
Data Cloud Architect OR Data Cloud Activation Manager OR Data Cloud Activation Specialist
1. In Data 360, go to the **Clean Rooms** tab.
2. Under **Collaborations**, open the collaboration to view results for.
3. Click the **Collaboration Results** tab. If the collaboration supports multiple queries, the results of each query are under separate tabs.
4. Select a query tab to view the results of that query.
5. Select a result from the query history to review its output. To find a result, use the search bar or filter options.
If a query uses parameters, the parameter values for each query result are also shown.
Run details for every query, including status and timing, write to the Clean\_Room\_Audit\_Log DMO. A successful query run writes its output to a data model object (DMO) that you explore in Data Explorer.
- For the Salesforce-provided segment overlap use case, results write to the Clean\_Room\_Overlap\_Output DMO.
- For the Salesforce-provided activation use case, results write to the provider's Amazon S3 bucket.
- For custom collaboration templates, the template defines the results storage location.
For the Salesforce-provided segment overlap use case, Data 360 generates an overlap-percentage report and stores it in the Results section. Open the report, or work with the output DMO directly.
For a custom template, Data 360 generates the report automatically only when you keep the template's default query. If you run a different query, build the report yourself from the output DMO. See [Create a Standard Report on Data 360 Objects](https://help.salesforce.com/s/articleView?id=analytics.rd_dc_reports_dashboards_create_standard_reports.htm&type=5&language=en_US).
# View Content Viewer User Engagement Insights in Data Explorer
Data 360 automatically creates an engagement telemetry data stream and a data lake object (DLO) to track user engagement with the Content Viewer. The Content Viewer is available only for harmonized content. You can view engagement data from the **Data Explorer** tab.
### Required Editions
User Permissions Needed
To view engagement insights
System admin profile OR
Data 360 Architect permission set
1. In Data 360, go to the **Data Explorer** tab.
2. Select a data space.
3. Select **Data Lake Object** as object type.
4. Search and select the relevant DLO associated with your harmonized Unstructured Data Model Object (UDMO) and engagement data stream. Engagement DLOs have the label “Engagements” indicated in their name.
5. The list of telemetry events that have been fired for the harmonized UDMO opens in a table view.
- You can configure the columns of this table to view file attributes you’re interested in. To add or remove columns from your table view, click **Edit Columns** on the top right. Move any column from the left to the right to add it to your view, or from the right to the left to remove it from your view. For example, to include events from a specific time in your table view, make sure the **DateTime** column is included in your view.
- You can filter the columns you’re interested in. Click the filtering icon on the top right, and click **Add Filter** to select from the **Field** list the event attribute you’re interested in. For example, to get a filtered view of user engagement with content coming from a specific source, select the **Data Source** filter under **Field**, select equals as the **Operator**, and enter the content source (for example, Google Drive) under **Value**.
With the engagement data displayed, you can analyze how your users interact with your harmonized content. For example, you can find the content source that users engage with most.
# View Data Graph Properties and JSON Structure
Use a list view to see data graph properties, including the primary data model object (DMO), data graph status, and structure. Additionally, you can copy a data graph’s JSON structure from its record home page.
### Required Editions
User Permission Set
Needed
To add calculated insights to a data graph
Permission set:
1. In Data Cloud, go to the Data Graphs tab.
2. From a list view, click the name of a data graph to open the data graph editor and see the structure in read-only mode.
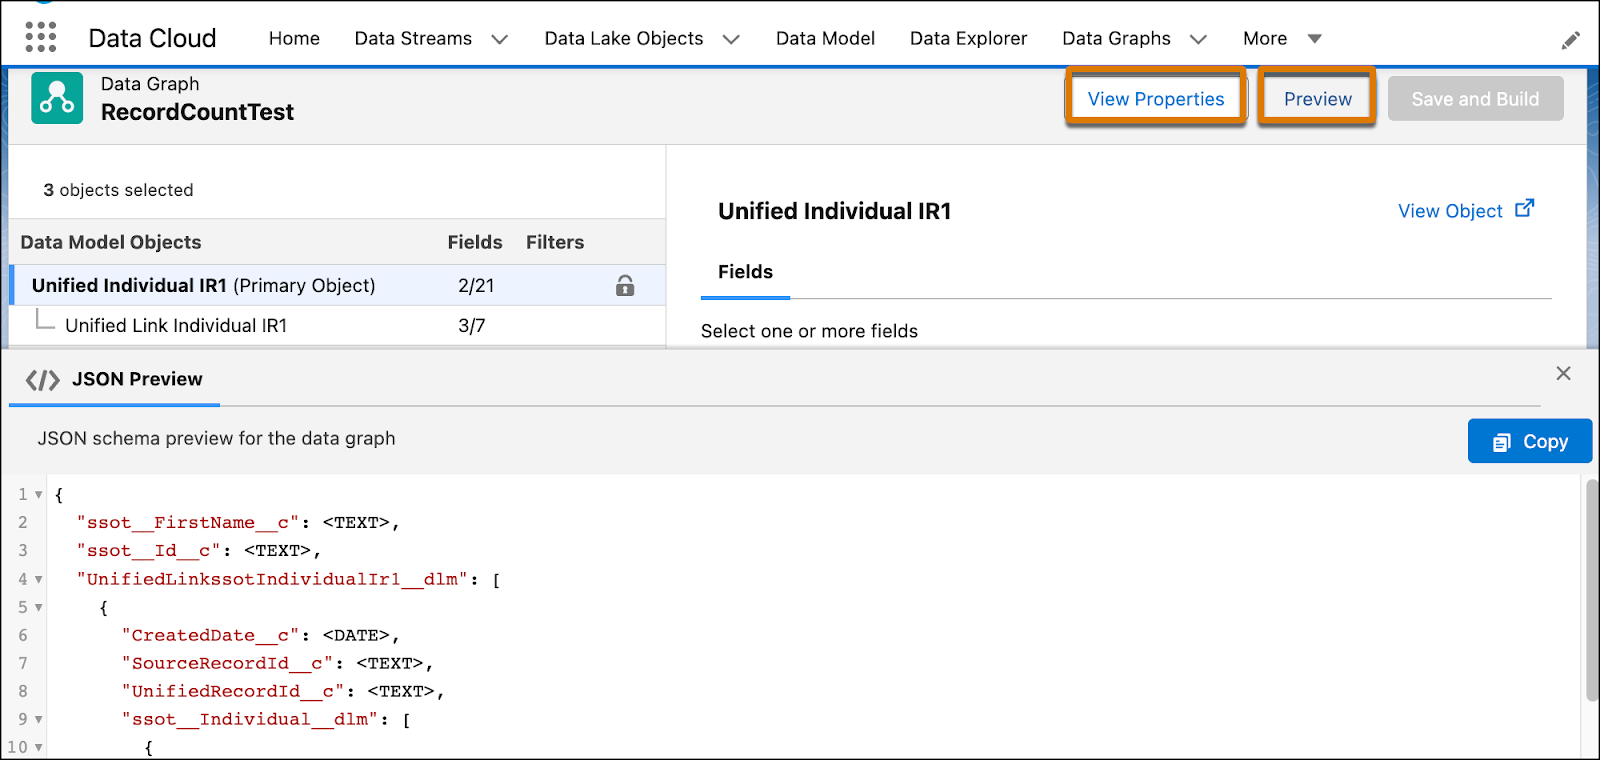
3. In the data graph editor, click **Preview** to review the JSON structure.
4. Click Copy to add the JSON to your clipboard so that you can paste it into a file or a JSON editor.
# View Filter and Container Level Counts
Use the population counts displayed in the ribbon under each filter or container to evaluate their impact on your segment. Filter-level counts apply to direct attributes; container-level counts apply to related attributes (containers). Counts are available on both the Include and Exclude tabs.
### Required Editions
Permission Sets Needed
To create a container:
One of these permission sets:
Data Cloud Architect
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. Go to the Segments tab, select the segment, then click **Edit Rules**.
2. Click **Include** or **Exclude**. Each tab can have up to 50 filters.
3. Each filter (direct attribute) or container (related attributes) shows a population count in a ribbon below it. Initially, the ribbon displays Calculate population. Click the refresh icon to run and view the count.
While the count runs, the ribbon shows **Calculating population….** . When it finishes, the ribbon shows **Population** (the number of records that match the criteria in that block). Click the refresh icon to update. If you use approximate count, the ribbon shows approximate population.
If the count fails, the ribbon shows **Population count failed**. Use the error icon to view details and retry. A failed filter or container count doesn’t block saving, publishing, or segment counting.
Counts return to **Calculate population** if you refresh the segment, edit that filter or container, or leave the segment builder.
You can see the impact of each filter and container on the segment and adjust rules as needed.
# View Filter Population Breakdown
After you start a report, open it to see how each Include and Exclude filter changes the audience, from the first filter through the final count.
### Required Editions
After you start a report generation, click **View Population Breakdown**. A report opens in a new browser page.
The report shows the status and has a table with three columns that explain your segment step by step.
**Attributes and Filters**
Shows each container (for example, Individual or Campaign Member) and its filters.
**Individual Filter Population**
Shows how many people match that filter by itself.
**Cumulative Filter Population**
Shows the running audience count as filters are applied from top to bottom.
The rows are grouped into two sections. **Include** filters build your audience. **Exclude** filters remove people from that audience.
**Final Count** shows the segment population after all Include and Exclude filters are applied. This count matches the final population in Segment Builder.
# View Harmonized Content Consistently in Data Explorer
The harmonized Unstructured Data Model Object (UDMO) record page, available through the Content Viewer in Data 360’s Data Explorer tab or in Service Cloud's Enterprise Knowledge component, provides you with a unified, in-app experience od all data interactions (structured knowledge and unstructured content). Through the Content Viewer, your harmonized content is presented in a standard, consistent format, regardless of its source.
### Required Editions
User Permissions Needed
To view harmonized content
System admin profile OR
Data 360 Architect permission
set
Before you begin verify that you have created a Harmonization configuration for either [Structrured Data](https://help.salesforce.com/s/articleView?id=data.c360_a_configure_harmonization_for_structured_data.htm&release=264.0.0&type=5 "Use this workflow to configure harmonization for structured data such as Salesforce Knowledge.") or [Unstructured](https://help.salesforce.com/s/articleView?id=data.c360_a_unstructured_content_harmonization.htm&release=264.0.0&type=5 "Use this workflow to create an unstructured content harmonization configuration for Data 360 content. The content must be ingested with a supported connector.") Content.
1. In Data 360, go to the **Data Explorer** tab.
2. Select a data space.
3. Select **Data Lake Object** as object type.
4. Search and select the relevant harmonized Data Model Object (DMO) associated with the UDMO you created when you set up your unstructured data connector. Harmonized UDMO names start with **harmonized**.
5. The list of files comprising the harmonized DMO that you select opens in a table view.
1. Configure the columns of this table to view file attributes you're interested in as needed. To add or remove columns from your table view, click **Edit Columns** on the top right. Move any column from the left to the right to add it to your view, or from the right to the left to remove it from your view. For example, to include in your table view files in a specific language, make sure the **Language** clumn is on the right side, then find files in this language in the Language columns of the table.
2. Filter the columns you’re interested in as needed. Click the filtering icon on the top right, and click **Add Filter** to select from the Field list the file attribute you’re interested in. For example, to get a filtered view of files authored by a specific user, select the Author filter under **Field**, select equals as the Operator, and enter the author’s username under Value.
6. Click **View** on the left side of any file row of the UDMO. You can now view and interact with the unstructured data directly within your application, in the Content Viewer. The Content Viewer presents content in a standard, consistent format regardless of its source, including images, tables, videos, and other elements. It is structured with several key sections to enhance user interaction and navigation.
1. **Table of Contents (1)**: Indicates the location and hierarchy of the document or document section in its source system. Use the TOC to browse additional documents or sections in the current context.
2. **Title (2)**: Indicates the title of the document or relevant section.
3. **Document Headings – Hierarchy (3)**: Displays the content in a structured, clear format.
4. **Metadata (4)**: Includes the date when the document was last updated.
5. **View in Source (5)**: Allows you to view the full context of the current document in its source platform, for example, in the harmonized Google Drive.
# View Search Index Status and Process History
View details of search index configurations from the Search Index list view and the object record view to monitor the indexing process.
### Required Editions
User Permissions
Needed
To view a search index configuration:
Permission set:
**Search Index Processing:** Create search indexes on data model objects (DMOs) or unstructured data model objects (UDMOs) by using the easy setup or advanced setup. Data 360 automatically processes changes in the source DMO or UDMO and incrementally updates the search index. The data stream settings and refresh modes determine the schedule of updates to the source DMO or UDMO. With all refresh modes, including the full refresh mode, the search index processes only changed records. When you delete a record from the source object, incremental processing deletes all information derived from that record, such as transcripts, chunks, and vector embeddings.
## Search Index Status States
During creation and processing, a search index has these statuses.
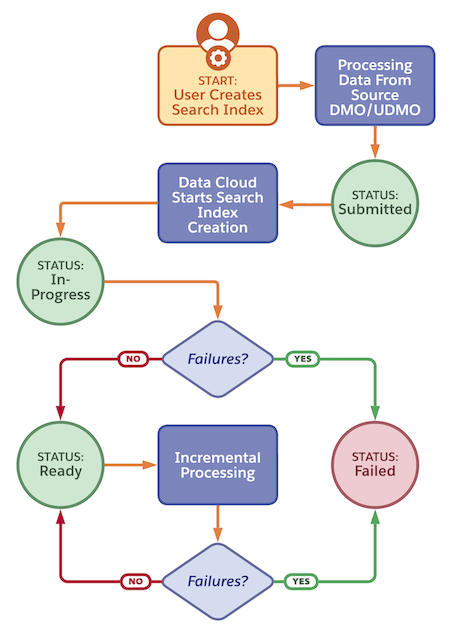
| Status | Definition |
| --- | --- |
| Submitted | A user created a search index via the UI or API. |
| In-progress | Data 360 is running an indexing job to process data from the source DMO/UDMO. |
| Ready | The search index is ready to use. The indexing job runs incrementally to process any changes in data from the source DMO/UDMO. |
| Failed | Data 360 encountered failures while processing data from the source DMO/UDMO. |
## Search Index Process History
The Process History tab tracks metrics for search index jobs. Data 360 retains metrics for up to 1,000 recent jobs. Metrics become available only after a job completes.
For large datasets, Data 360 splits the work into multiple concurrent jobs for faster processing. As each job completes, it progressively populates the search index. The **Process History** tab shows metrics separately for each individual job. The **Process History** tab captures these metrics.
Detail
Description
Start Time
The timestamp when the job started.
End Time
The timestamp when the job ended.
Records Processed
The number of records processed from a DMO, or number of files processed from
a UDMO. For search indexes that reference a file attachment UDMO, each file
attachment is treated as a separate record.
Records Skipped
The number of files skipped. For example, files are skipped for these
reasons:
the file type doesn't match the file type you configure in the search
index
authentication errors occur in the data source
the file size exceeds the limit
you try to process an unsupported file format
All files that are skipped are reported both as processed records and
skipped records.
Size Processed
The size, in bytes, of the content processed by the index refresh job.
This metric doesn't report: 1) files that are skipped if you don’t select the
file type in the search index or 2) files that are skipped due to a system
error.
Note: This metric doesn't always match what is reported to Digital Wallet for
billing. For the size to be reported to Digital Wallet, records and files must
be successfully processed.
Chunks Created
The number of chunks created. If the job fails, this metric reports
0.
Chunks Deleted
The number of chunks removed. If the job fails, this metric reports
0.
Job Status
The status of the job run, either Succeeded or Failed.
## View a Search Index
1. From App Launcher, select **Data Cloud**.
2. Click **Search Index**.
3. From the list of search index configurations, click a search index and select **Process History**.
View details to understand the search index processing history.
# View Segment Members in Data Explorer
After publishing your segment in Data 360, you can validate the segment membership in Data Explorer.
### Required Editions
Permission Sets Needed
To view data in Data Explorer:
One of these permission sets:
Data Cloud Architect
Data Cloud User
Data Cloud Activation Manager
Data Cloud Activation Specialist
1. In Data Cloud, click **Data Explorer**.
2. From the Object dropdown list, select **Data Model Object**.
3. Select the DMO that you’re segmenting on (for example, Individual - Latest), and view your results.
The segment membership doesn’t contain data until you publish the segment.
4. To view results for a specific segment, click the Filter icon and use the 15-character Segment Id.
# View Tableau Dashboards
After defining visualizations on your Data 360 data in Tableau, you can view these dashboards by embedding or publishing them.
### Required Editions
Available in: Lightning Experience
## Embed Your Data
Embed Tableau views into Salesforce Lightning pages using the [Tableau View Lightning web component](https://help.tableau.com/current/pro/desktop/en-us/embed_ex_lwc.htm) in Lightning Experience. When editing a Lightning page, drag the Tableau View Lightning web component onto the page and then provide the URL for the Tableau view.
## Publish Your Data
You can publish your data sources and workbooks to the Tableau server. You can share your work with the rest of your team by publishing it to Tableau Server or Tableau Online. After it’s published, you and your team can access it through your web browser or the Tableau mobile app. Publishing data sources can also help you to centralize data management.

Note The Data 360 query engine supports consumer rights at query execution time. When dashboards are published, you must perform a full refresh to ensure that any changes between queries adhere to the latest assertion of consumer rights.
#### See Also
- [_Tableau Help_: Publish Data Sources and Workbooks](https://help.tableau.com/current/pro/desktop/en-us/publish_overview.htm)
- [_Tableau Help_: Embed Tableau Views into Salesforce](https://help.tableau.com/current/pro/desktop/en-us/embed_ex_lwc.htm)
# View the Number of Successfully Synced Pages per Connector Run
Determine the total number of records ingested during each Web Content (Crawler or Sitemap) connector run.
Use this procedure to check each job your connector completes in order to find trends in ingestion rates and track possible issues.
1. From App Launcher, select **Data Cloud**.
2. Open the **Data Streams** tab and select the relevant data stream name (DLO name).
3. Open the **Refresh History** tab to view the number of ingested records for each connector run.
#### See Also
- [_Salesforce Help_: Monitor the Status of Data Ingestion for Unstructured Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_monitor_the_status_of_unstructured_connectors_data_ingestion.htm&release=264.0.0&type=5 "You can monitor the status of data ingested by the Web Contnet (Crawler and Sitemap) connectors, using the Data Cloud’s Data Streams tab and Query Editor.")
# View Unified Profiles in Profile Explorer
Unified Account and Unified Individual profiles are shown in Profile Explorer. You can search for them by attributes or related attributes.
1. In Data 360, click **Profile Explorer**.
2. To search for a profile, select an attribute and enter an exact phrase.
You must search with an exact phrase to get results.
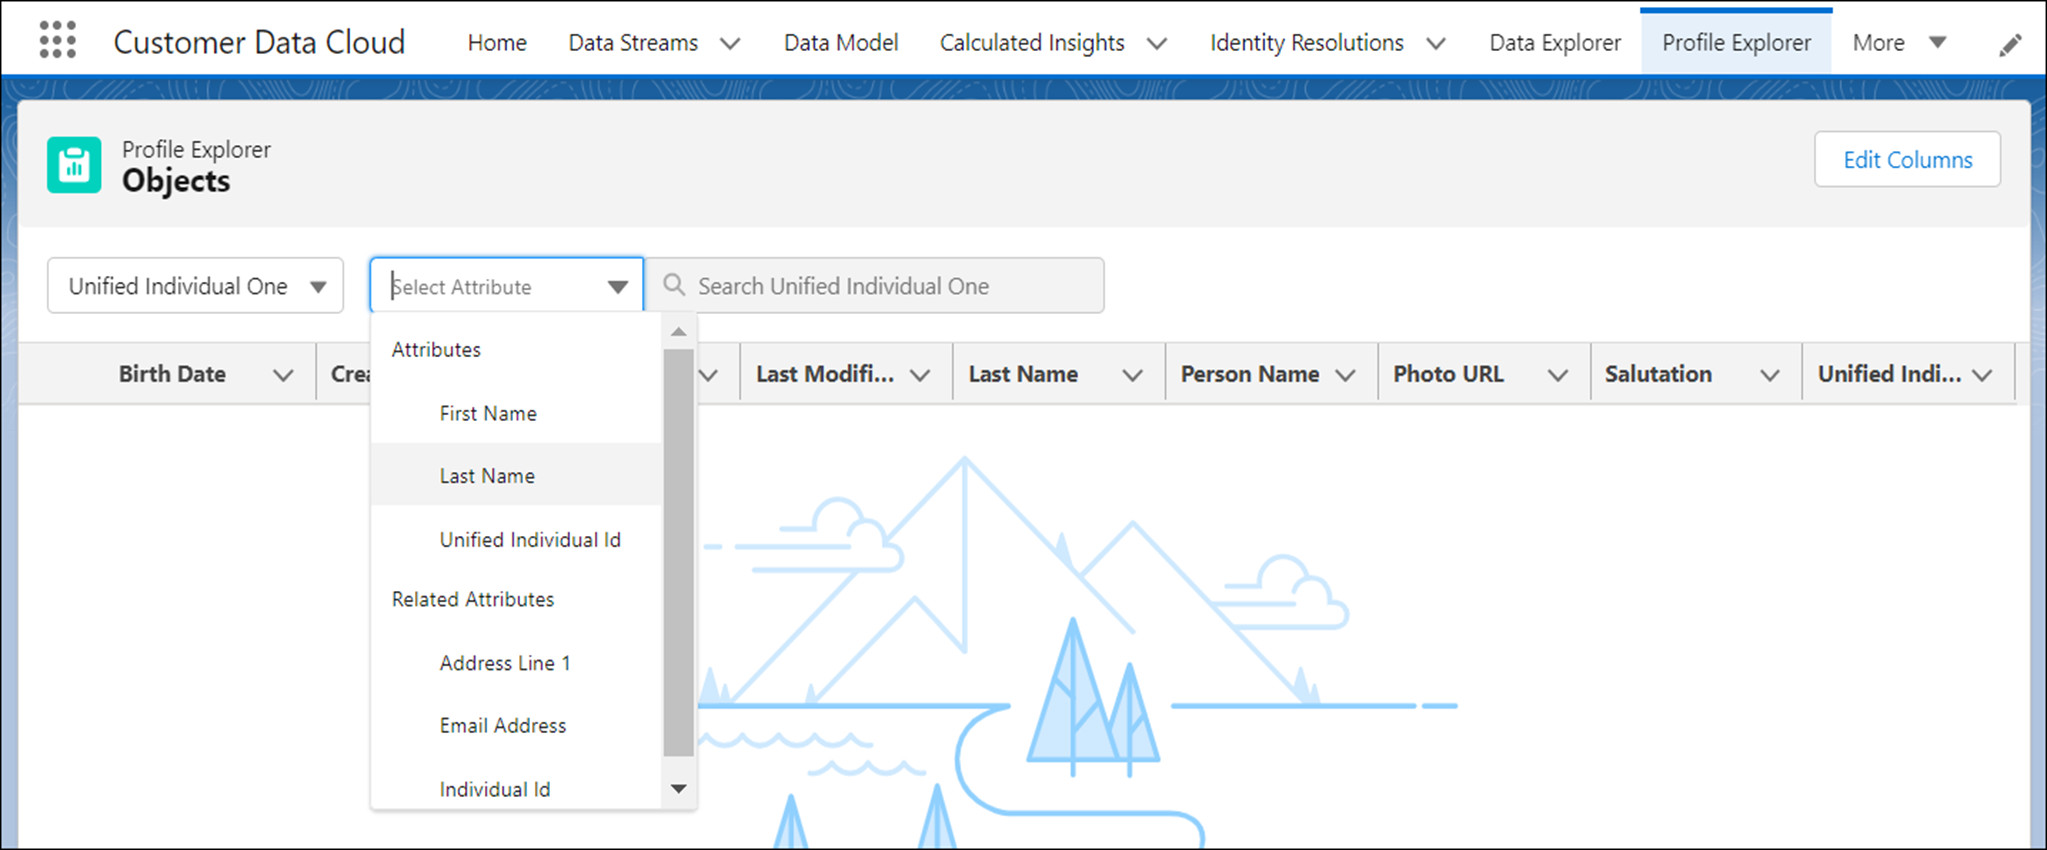
# View Your Data in Data Explorer
In Data Explorer, you can view Data 360 data from your data lake objects (DLOs), data model objects (DMOs), calculated insight objects (CIOs), or data graphs. You can personalize your view by editing the columns and use filters to show only the most relevant data for the selected object.
### Required Editions
## View Object Data
To view your data in Data Explorer:
1. Select a data space, an object type (DLO, DMO, CIO, or Data Graph), and then the specific object you want to view.
2. (Optional) Select any data column to sort the data based on that selection.
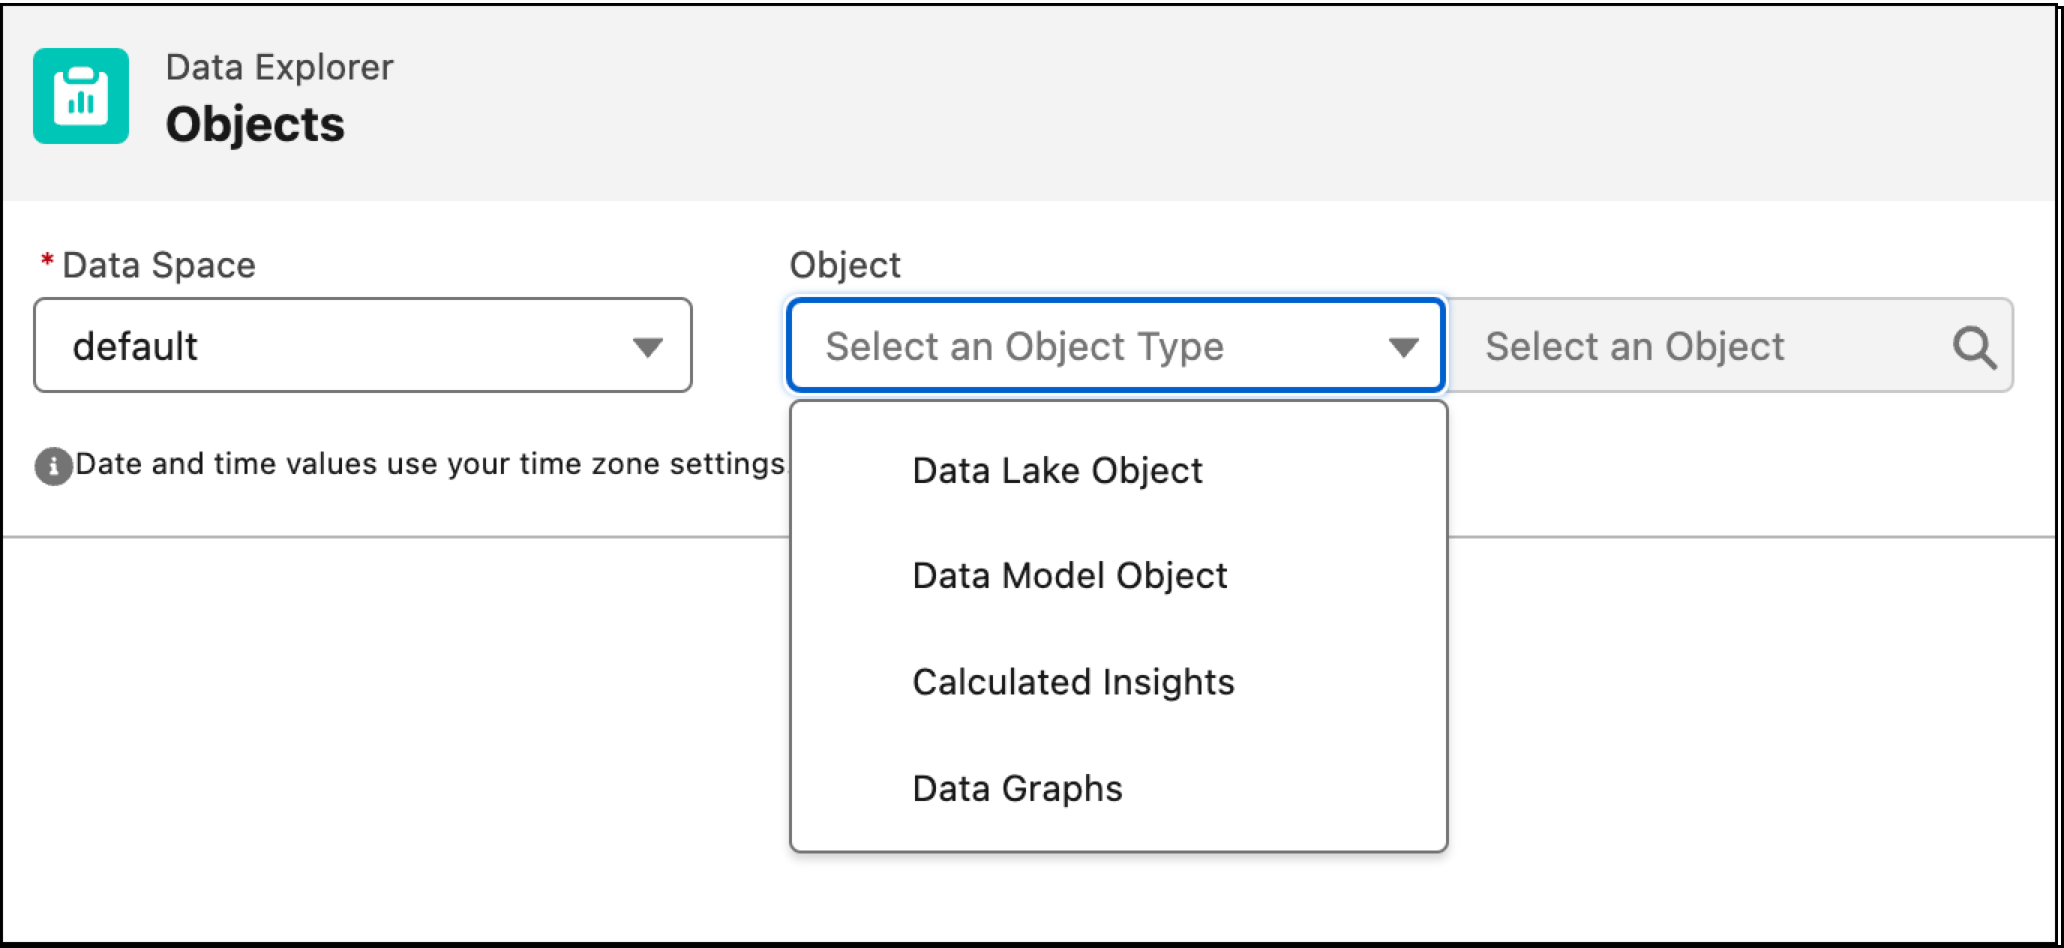
Some notes on Data Explorer limitations:
- Boolean fields store two possible values, ‘true’ or ‘false’. If a selected boolean field has null or empty values, it always defaults to ‘false’.
- The dates and times displayed in Data Explorer are based on the time zone configured in your Salesforce org. When an ingested date value in a column is 01/01/0001, it's rendered as 01/01/1901.
- For numbers, the digits are truncated to two places to the right of the decimal point.
- The maximum display is 100 rows per view.
## Copy SOQL Queries
Use the \*\*Copy SOQL\*\* button to copy the SOQL query that populates the current table. If a table has more than 10 columns, Data 360 copies only the SOQL for the 10 visible columns.
To run the query:
1. Select **Copy SOQL**.
2. Go to the Data 360 Query Editor.
3. Use the SOQL you copied to create a new query.
4. (Optional) Remove the '`LIMIT 100`' condition from the query.
5. Run the modified query.
For more information, see [Query Editor](https://help.salesforce.com/s/articleView?id=data.c360_a_query_editor.htm&release=264.0.0&type=5 "With the Data 360 Query Editor, you can directly query harmonized customer data using Data 360 SQL (Structured Query Language). You can build queries on Data Lake Objects (DLOs), Data Model Objects (DMOs), Calculated Insights Objects (CIOs), and data graphs.").
## View a Calculated Insights Chart
After choosing a CIO, you can view your calculated insight objects in Chart view by selecting the **pie icon**.
With this view you can visualize and further analyze your CIOs in a graph.
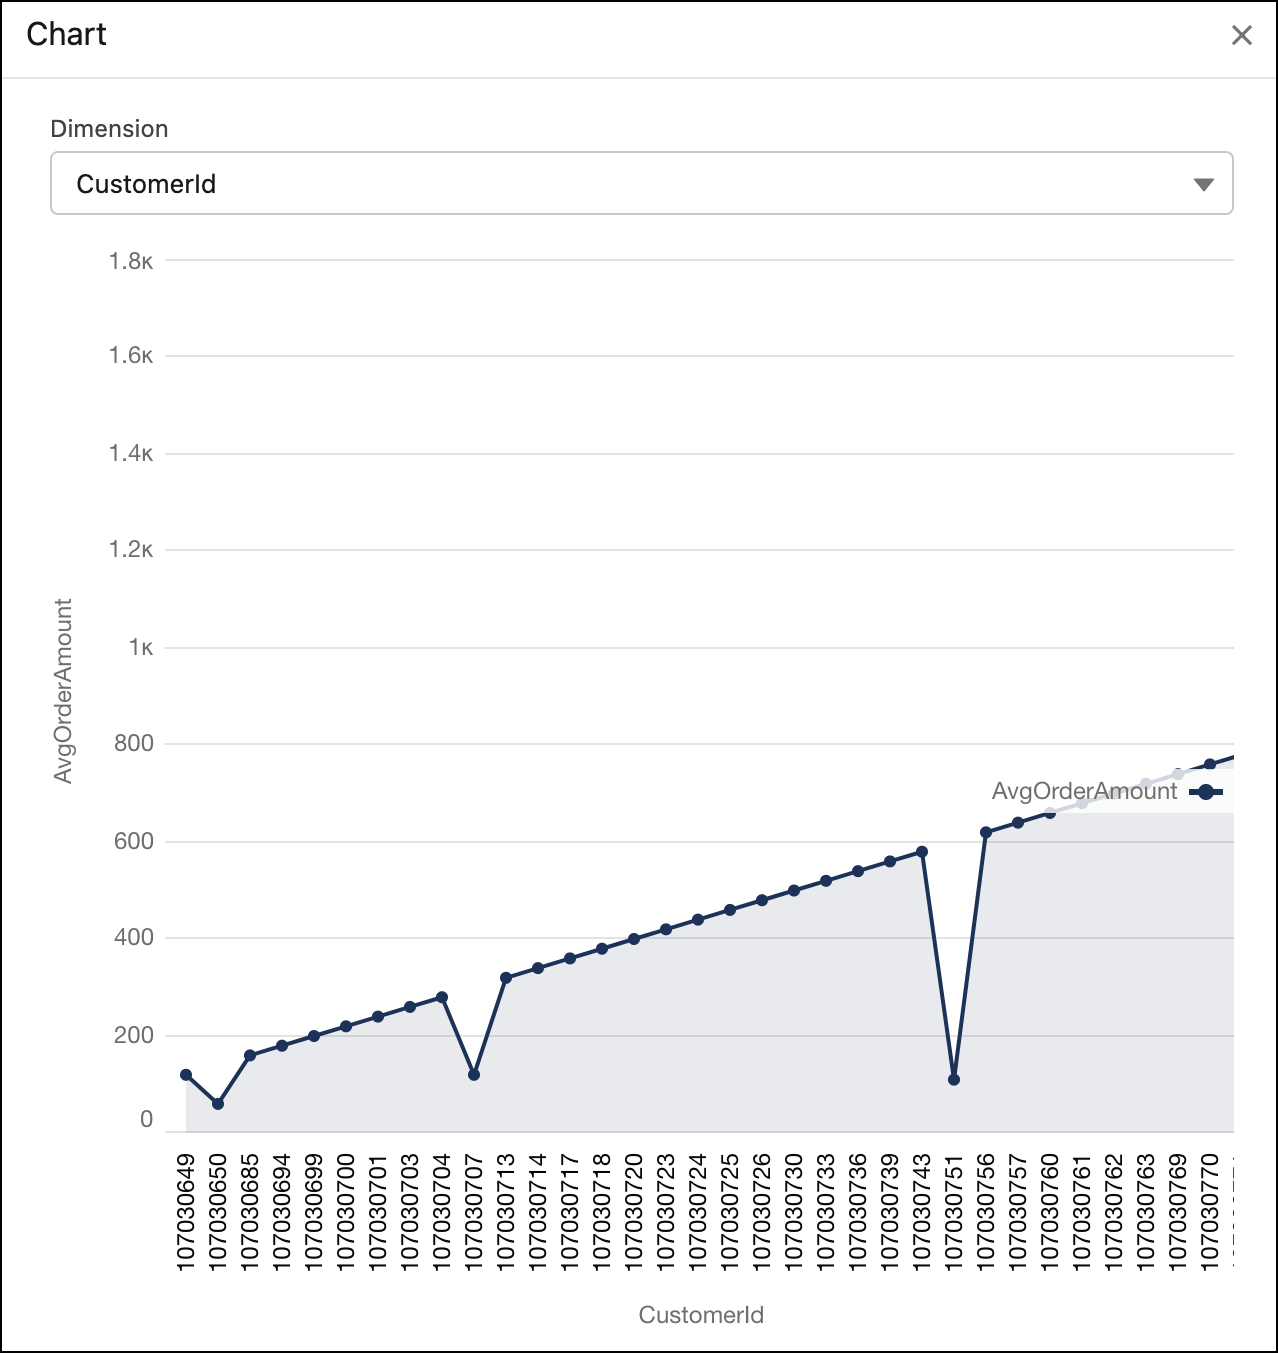
## View Data Graph Records
To view a data graph's records, select Data Graphs as the object type, then select the data graph. With Data Explorer, you can view and copy the Data Graph data in JSON block format from cached or real-time data. To view real-time data, select **Real-time View: On** in the JSON preview. For more information, see [Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graphs.htm&release=264.0.0&type=5 "A data graph brings together structured data from your Data Model Objects (DMOs) in Data 360. It combines this data to create easy-to-use views of your information.").
#### See Also
- [_Salesforce Help_: Change Time Zones](https://help.salesforce.com/s/articleView?id=data.c360_a_time_zones.htm&release=264.0.0&type=5 "Data 360 uses the time zone set in Salesforce when publishing and refreshing segments and activations. The dates and times added to a segment in the segment canvas also use the Salesforce time zone. To change the time zone for Data 360, change the time zone in Salesforce.")
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Data Graphs](https://help.salesforce.com/s/articleView?id=data.c360_a_data_graphs.htm&release=264.0.0&type=5 "A data graph brings together structured data from your Data Model Objects (DMOs) in Data 360. It combines this data to create easy-to-use views of your information.")
# View Your Data Model Objects
You can view your Data 360 data model objects in either list or graph view.
### Required Editions
You can alternate between a list view and a graph view in the Data Model tab. The graph view shows an Entity Relationship Diagram of the mapped data model objects within Data 360 and their relationships.
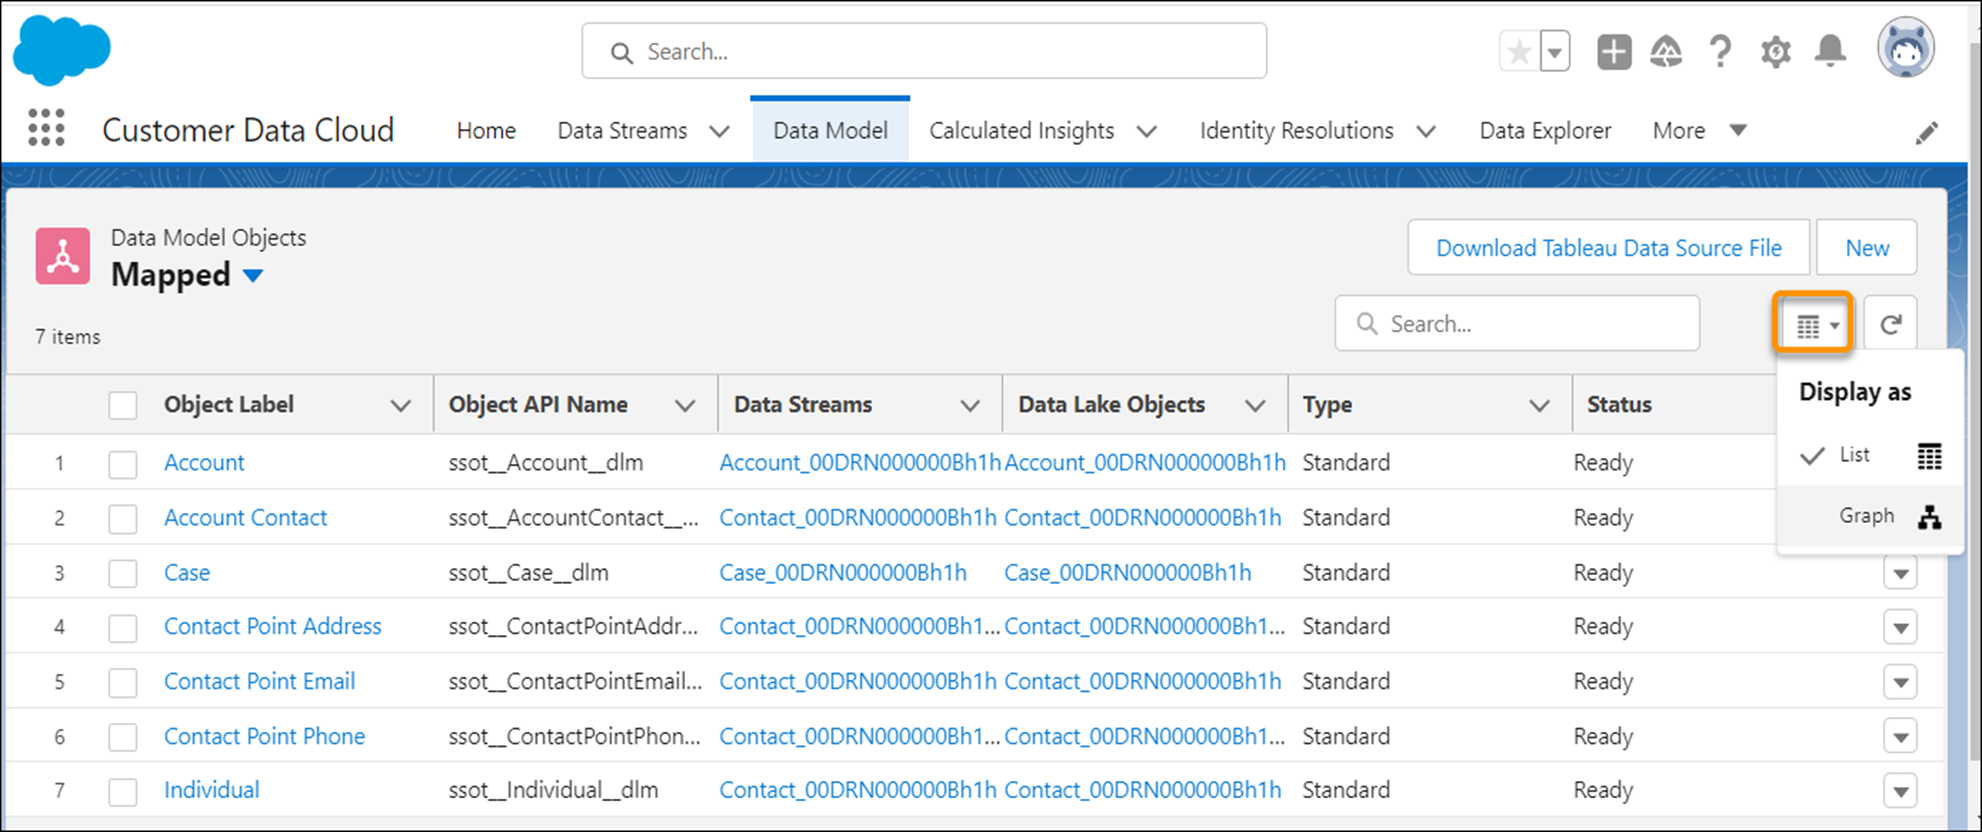
List view allows you to view your data model objects (DMOs) and any related details in a list. You can see object label, object API name, which data streams that object is mapped to, the type, and status all in one view. There are two list views: All and Mapped. All shows all DMOs, and Mapped shows only the DMOs that have mappings.
Graph view lets you view your data in image form to easily visualize how all data in your instance is connected. The color of each data model object node represents the category Profile, Engagement, or Other. You can click each node to view details and make edits, just like in the list view. You can drag and zoom in and out using either the canvas or mini-map. Only mapped DMOs show in this view.
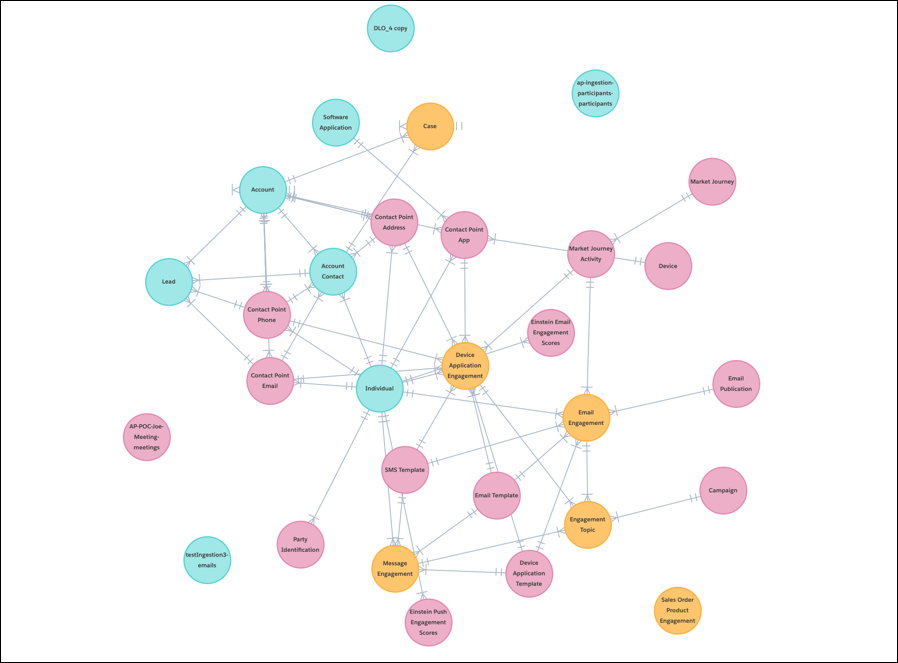
To view, edit, or deactivate relationships, select a DMO from either the list view or graph view. Navigate to Relationships and click **Edit** or **New**. Create relationships between objects and fields.
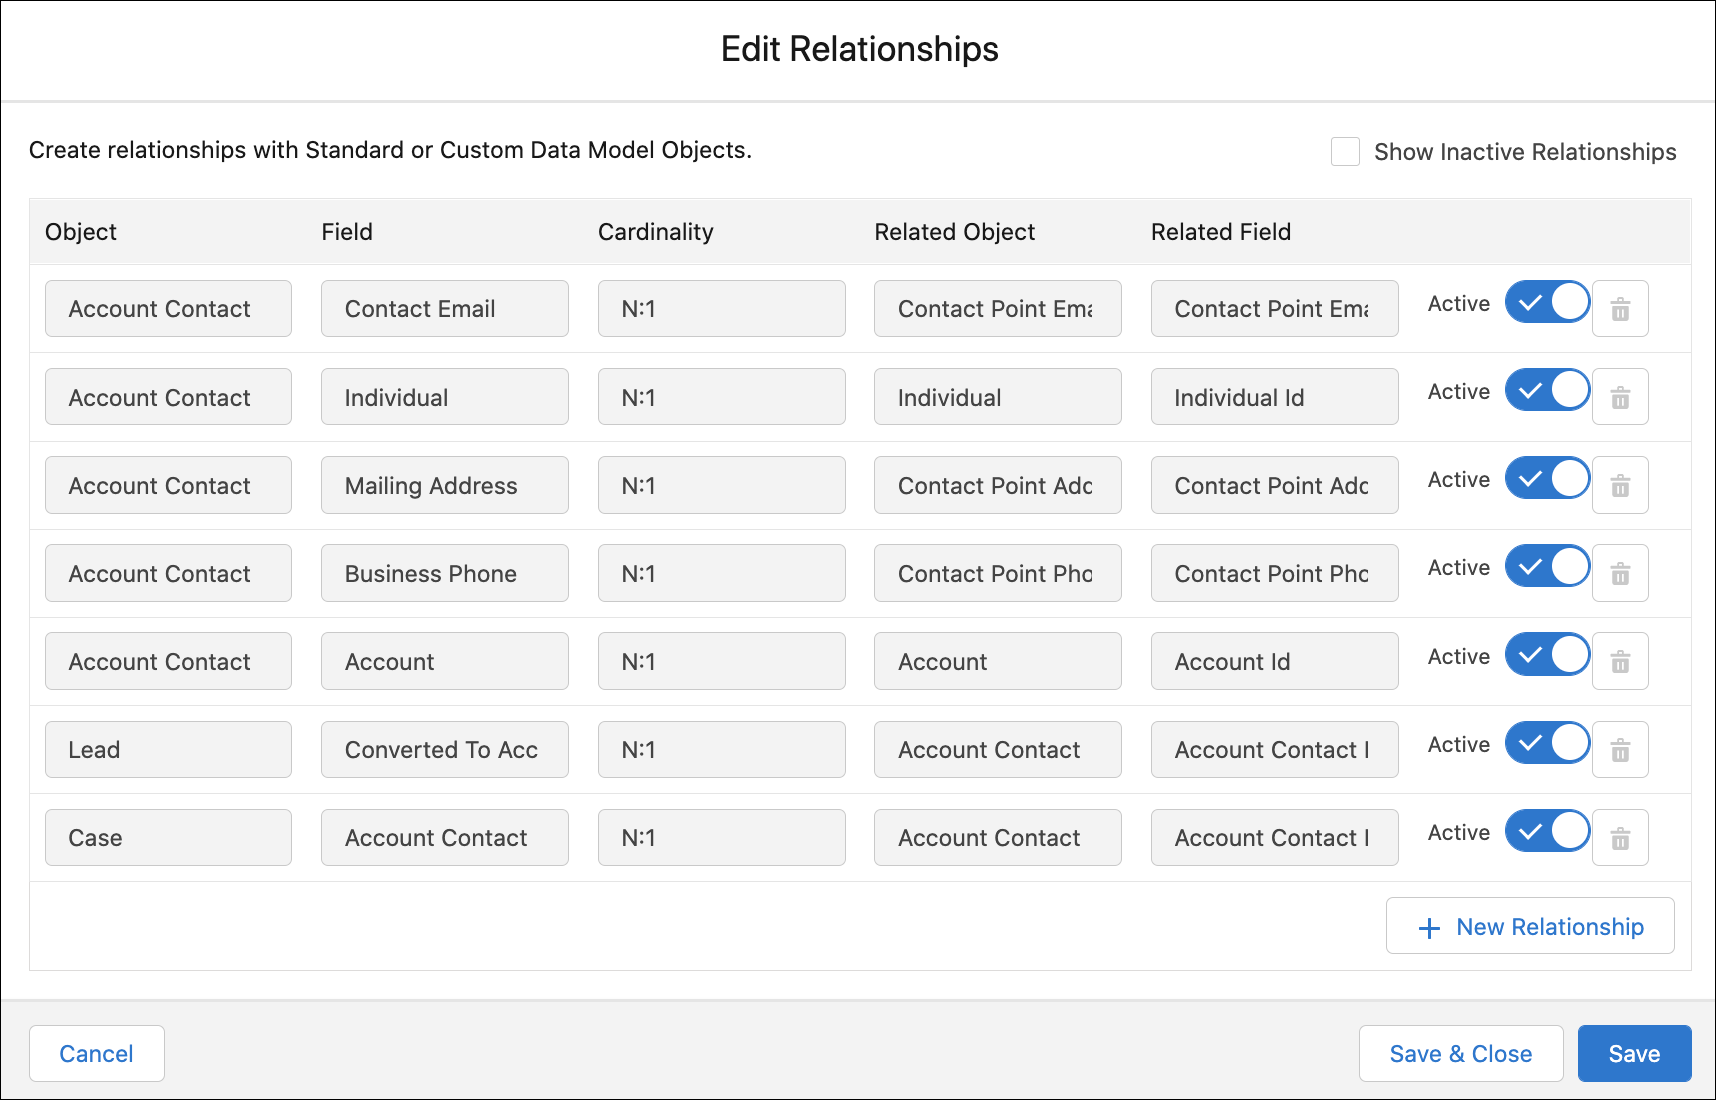
#### See Also
- [_Salesforce Help_: Data Model Object Relationships](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_object_relationships.htm&release=264.0.0&type=5 "A Data 360 data model object (DMO) can have a standard or custom relationship with other DMOs. The relationship can be structured as a one-to-one or many-to-one relationship. You can view the relationships and their statuses on a DMO record’s Relationships tab.")
# Viewing Data Relationships with Unified Lineage
Unified lineage gives you a complete view of how your data objects are connected. Use it to understand data journeys, dependencies, and the downstream impact of changes such as applying tags or updating objects
### Required Editions
Unified lineage is a visual relationship graph that shows how your data objects are connected. It provides visibility into how data moves across sources, transformations, and activations so you can trace dependencies, audit governance, and assess impact before making changes.
Unified lineage is automatically available in all customer orgs and no setup is required. When enabled, a background job collects lineage for all existing objects. Subsequent updates are captured incrementally as new objects are created or modified.
## Supported Object Types
Object-level lineage is available for:
- Data streams and their connection info
- Data lake objects and unstructured data lake objects
- Data transforms
- Data model objects and unstructured data model objects
- Calculated Insights
- Segments
- Activations
- Identity Resolutions
- Semantic Data Models
- Data Graphs
- Data Shares
Field-level lineage is available for a subset of these objects:
- Data Lake Objects
- Data Transforms
- Data Model Objects
- Calculated Insights
- Segments
- Activations
- Data Graphs
- Identity Resolutions
- Data Shares
- **[Data Lineage Best Practices](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lineage_best_practices.htm&release=264.0.0&type=5)**
Applying these best practices helps maintain consistent data visibility and governance alignment across your organization.
- **[Use Unified Lineage](https://help.salesforce.com/s/articleView?id=data.c360_a_use_unified_lineage.htm&release=264.0.0&type=5)**
Explore and interact with the lineage graph to view how your data objects connect. Search for objects, trace upstream and downstream dependencies, and use side-panel details, field-level views, and tag overlays to understand your data flow and governance context.
- **[Unified Lineage Limitations](https://help.salesforce.com/s/articleView?id=data.c360_a_lineage_limitations.htm&release=264.0.0&type=5)**
Unified lineage has the following limitations.
#### See Also
- [_Salesforce Help_: Unified Lineage Limitations](https://help.salesforce.com/s/articleView?id=data.c360_a_lineage_limitations.htm&release=264.0.0&type=5 "Unified lineage has the following limitations.")
# Visual Segment Creation to Data 360
Segmentation enables data analysts to curate relevant portions of data from their analyses in Tableau and seamlessly transfer them as segments to Data 360.
### Required Editions
Available in: Tableau Cloud
Combine the robust analysis capabilities in Tableau with Data 360 marketing using the Salesforce Data 360 connector. A data analyst can explore Data 360 data to create visually rich segments in Tableau and then send the segments to Data 360. In Data 360, a marketer can publish the segments to other Salesforce clouds or platforms for further analysis and action by sending out targeted marketing campaigns to customers.
#### See Also
- [_Tableau Help_: Visual Segment Creation to Data 360](https://help.tableau.com/current/online/en-us/segments.htm)
- [_Salesforce Help_: Segmentation](https://help.salesforce.com/s/articleView?id=data.c360_a_segments.htm&type=5&language=en_US)
# Visualize Your Data with Data Lens
Data Lens provides you with an intuitive and interactive environment for in-depth data exploration and visualization. Moving beyond static reports, you can directly interact with your data to reveal hidden, valuable insights and patterns.
With Data Lens, you can:
- Analyze Distributions: Understand the spread of values to identify patterns and outliers.
- Explore Relationships: Discover connections between related data points.
- Examine Row Details: Validate summarized data by reviewing individual rows.
- Pinpoint Nulls: Identify missing values within your datasets.
- Categorize Unique Values: Classify data by recognizing distinct entries.
- Understand Data Types: Determine the assigned data type for each field.
- Streamline Your View: Hide or show fields to optimize your data perspective.
Data Lens provides these user interface features within Segments, Data Lake Objects, and Data Model Objects tabs.
- Profile View: Shows data columns as colored bars, summarizing data distributions, values, and nulls. You can click values to include/exclude or highlight relationships.
- Data Grid View: A spreadsheet-like view for viewing row-level details. Synchronized with the profile pane for consistency.
- List View: Show or hide fields to streamline your view.
## Data Governance
Data Lens operates by leveraging the existing query layer to preview data, ensuring adherence to established security protocols. Data Lens respects policies such as dynamic PII masking, which is applied at the time of the query. This means only the masked version of the data is displayed in the Data Lens preview, while the raw, unmasked data remains secure in its original location. This approach ensures sensitive information is protected from unauthorized viewing during data exploration and preview, aligning with strict data governance and compliance requirements.
- **[Billing Considerations for Data Lens](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_lens.htm&release=264.0.0&type=5)**
Data Lens uses the Data 360 query layer to fetch and display live data previews, which consumes credits from your Data Services or Flex Credits consumption card.
# VPC Interface Endpoints for Amazon Kinesis Connection
Data Cloud uses the VPC Endpoints listed here to communicate with Amazon Kinesis. If your security policy requires a strict network ACL (access control list), make sure to include these endpoints to your allowlists.
## AWS Kinesis VPC Endpoints Table
| SF Region Name | FD | AWS REGION | VPC ENDPOINT |
| --- | --- | --- | --- |
| prod20 | cdp1 | ilcentral1 | **vpce-0363080487845dc24** |
| prod3 | cdp1 | eucentral1 | **vpce-028d0b6b1ffc5afdc** |
| prod15 | cdp2 | eucentral2 | **vpce-0b946d9cfe96d0ba3** |
| prod16 | cdp1 | eunorth1 | **vpce-08f810630cdf8e278** |
| prod14 | cdp1 | apnortheast2 | **vpce-048a6da18d4771e0f** |
| prod1 | cdp5 | useast1 | **vpce-0e8ecaecae1eb95fa** |
| prod4 | cdp1 | apsoutheast2 | **vpce-0aca3c68eb174290c** |
| prod2 | cdp1 | apsouth1 | **vpce-0116b150bc9ad799c** |
| prod19 | cdp2 | eusouth1 | Not Available |
| prod14 | cdp2 | apnortheast2 | Not Available |
| prod2 | cdp2 | apsouth1 | **vpce-0f3bc6d2528fb158c** |
| prod1 | cdp2 | useast1 | **vpce-048ab13be9be19fb9** |
| prod17 | cdp1 | apsoutheast3 | **vpce-0f138258096605652** |
| prod13 | cdp2 | euwest2 | **vpce-069b10ec226d56124** |
| prod9 | cdp2 | apnortheast1 | **vpce-0339d3839e0e517dd** |
| prod22 | cdp1 | apnortheast3 | **vpce-06a6b108713ebd135** |
| prod1 | cdp1 | useast1 | **vpce-0e17b5a726bc27d8e** |
| prod11 | cdp2 | saeast1 | **vpce-07b9d6320fc857587** |
| prod12 | cdp1 | euwest3 | **vpce-02ee0bb3fd078596f** |
| prod15 | cdp1 | eucentral2 | **vpce-00c22c21987f12aa7** |
| prod1 | cdp3 | useast1 | **vpce-0c64c6cf6df7b1f31** |
| prod21 | cdp1 | useast2 | **vpce-04ceb94a5972ec782** |
| prod5 | cdp2 | uswest2 | **vpce-058614420bc1d542c** |
| prod10 | cdp1 | apsoutheast1 | **vpce-0f4101a1dbcc24fb3** |
| prod18 | cdp1 | mecentral1 | **vpce-0b3dcccf3a33ed1f2** |
| prod3 | cdp2 | eucentral1 | **vpce-08022f23639518c86** |
| prod4 | cdp2 | apsoutheast2 | **vpce-04f0a32c607ce6d41** |
| prod1 | cdp4 | useast1 | **vpce-051fac77d2db8550e** |
| prod5 | cdp3 | uswest2 | **vpce-0e5d2597fc8bcf078** |
| prod18 | cdp2 | mecentral1 | Not Available |
| prod9 | cdp1 | apnortheast1 | **vpce-0854197fe1b75462b** |
| prod5 | cdp1 | uswest2 | **vpce-0c467c13a3829c5ff /** |
| prod8 | cdp1 | cacentral1 | **vpce-0bd37a47de107a22a** |
| prod11 | cdp1 | saeast1 | **vpce-03f7de330163c66d6** |
| prod13 | cdp1 | euwest2 | **vpce-050dac8f371ff2a8a** |
| prod12 | cdp2 | euwest3 | Not Available |
| prod8 | cdp2 | cacentral1 | **vpce-0893ce41f87cf8441** |
| prod19 | cdp1 | eusouth1 | **vpce-0ba24ac6c79bdb9f9 /** |
| prod16 | cdp2 | eunorth1 | Not Available |
# Web and Mobile App Connector
Connect your web and mobile apps to Data Cloud to collect customer engagement data. This data helps you customize messages, create automations, or support AI projects. After it’s connected, set up data streams to ingest your data into Data Cloud, allowing you to access and query this data for various uses.
### Required Editions
User Permissions
Needed
To view Data Cloud Setup and connect your website
System admin profile OR
Data Cloud Architect
To create a data stream
Permission set:

Note These instructions apply to mobile apps and websites that don't use Google Analytics 4 (GA4). To ingest GA4 data from your sites into Data Cloud, see [Connect a Website with Google Analytics 4 (Beta)](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-web-connector-ga4.html).
#### See Also
- [Trailhead: Web Engagement Data in Data 360](https://trailhead.salesforce.com/content/learn/modules/web-engagement-data-in-data-cloud)
- [_Salesforce Help_: Data 360 Limits and Guidelines](https://help.salesforce.com/s/articleView?id=data.c360_a_limits_and_guidelines.htm&release=264.0.0&type=5 "Guidelines define best practice recommendations to optimize your adoption of Data 360 for best performance. Limits are boundaries beyond which features are unavailable, performance is throttled, or usage billing charges are applied. Since Data 360 is built to scale, some limits can be adjusted to meet your business needs. Work with your account executive to find a solution that meets your goals.")
## Step 1: Connect a Website or Mobile App to Data Cloud
First connect your mobile applications and website source. By connecting your mobile applications and website sources, you can capture online data and control the scope of data ingestion and activation.
1. Create a connection in Data Cloud Setup (System Admin Profile).
2. Build data capture rules (or sitemap).
3. Create event definitions (also called a schema).
To connect mobile apps and websites, review these steps in the Salesforce Developer documentation, [Web and Mobile App Connector.](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-mobile-web-app-connector.html) To connect sites with GA4, see the note at the top of this page.
### Step 2: Capture Engagement Data
To capture engagement data, add a JavaScript beacon script (or CDN script) to your website or app code.
1. Copy the provided beacon.
2. Add the beacon to your website (Web Developer).
### Step 3: Create a Data Stream
Create a data stream to initiate the flow of data from a website or mobile app.
[Create a web or mobile data stream](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-mobile-web-datastream.html) (Data Cloud Admin).
# Welcome New Loyalty Members to Your Program
Send personalized messages to new loyalty members to educate them on program benefits.
## Get Started
This solution kit helps you:
- Increase loyalty program engagement
- Engage new loyalty members
- Increase loyalty program member LTV
## Required Products
- Commerce and Order Management Solutions (OMS)
- Loyalty Management
- Marketing Cloud Connect
- Marketing Cloud Engagement
## Other Recommended Technology
- B2C Commerce
- Salesforce OMS
- Service Cloud
1. **[Workflow](https://help.salesforce.com/s/articleView?id=data.c360_a_loy_mgmt_workflow.htm&release=264.0.0&type=5)**
Learn how data flows through the configurations when you welcome new loyalty members to your program.
2. **[Design Considerations](https://help.salesforce.com/s/articleView?id=data.c360_a_loy_mgmt_considerations.htm&release=264.0.0&type=5)**
Keep these design considerations in mind when you welcome new loyalty members to your program.
3. **[Configurations](https://help.salesforce.com/s/articleView?id=data.c360_a_loy_mgmt_conf.htm&release=264.0.0&type=5)**
Use these configuration steps to welcome new loyalty members to your program.
#### See Also
- [_Salesforce Help_: Configure Marketing Cloud Connect](https://help.salesforce.com/s/articleView?id=mktg.mc_co_configure_the_marketing_cloud.htm&type=5&language=en_US)
# White-label and Distribute a Connector
Use the metadata-based Data Cloud Connector Framework to package and white-label an existing connector, improving the discoverability of your product. To white-label a connector and distribute it, you configure a Salesforce project before publishing the managed package to AppExchange.
### Required Editions
User Permissions Needed
To white-label and package a connector:
Permission set:
1. Create a DevHub or configure an existing org to be your Dev Hub. See [Select and Enable a Dev Hub Org](https://developer.salesforce.com/docs/atlas.en-us.sfdx_dev.meta/sfdx_dev/sfdx_setup_enable_devhub.htm).
2. Create a developer edition org to own your new package. See [Create a Developer Edition org](https://www.salesforce.com/form/developer-signup/?d=pb).
3. Create a namespace and register it with your Dev Hub. See [Create and Register a Namespace](https://developer.salesforce.com/docs/atlas.en-us.sfdx_dev.meta/sfdx_dev/sfdx_dev_unlocked_pkg_create_namespace.htm).
4. Install the Salesforce CLI.
5. Authorize access to your Dev Hub.
```
sf org login web --set-default-dev-hub --alias {devHubAlias} --instance-url {devHubInstanceURL}
```
6. Create a Salesforce project.
```
sf project generate --name {name} --template empty
```
7. In the `{name}/config/project-scratch-def.json` file, replace the `features` field with this.
```
{
"orgName": "{your_org_name}",
"edition": "Developer",
"features": ["EnableSetPasswordInApi","CustomerDataPlatform","MarketingUser"],
"settings": {
"lightningExperienceSettings": {
"enableS1DesktopEnabled": true
},
"mobileSettings": {
"enableS1EncryptedStoragePref2": false
}
}
}
```
8. In the `{name}/sfdx-project.json` file, replace the value of the `namespace` field with the name of the namespace that you created.
9. Navigate to `{name}/force-app/main/default` and create two folders — `staticresources` and `dataconnectors`.
10. Open the `staticresources` folder and create a new `StaticResource` for each connector you want to white-label.
```
sf static-resource generate --name {name} --type image/svg+xml
```
11. Replace the contents of `{name}.resource` with the logo's SVG XML. Ignore the other generated file. This is an example XML to replace the logo.
```
Override
```

Note
Name the XML as file as `{name}.dataconnector-meta.xml`.
13. Make a GET request to `GetConnectors` endpoint.
14. Copy the value in the `name` field of the connector you want to white-label, and enter it in the `parentConnector` field in the XML file that you created.
15. Create a manifest file that describes the metadata entities that you created.
```
sf project generate manifest --metadata DataConnector --metadata StaticResource
```
16. Create a scratch org.
```
sf org create scratch --definition-file config/project-scratch-def.json --alias {scratchOrgAlias} --set-default --target-dev-hub {devHubAlias}
```
17. Deploy your connector.
```
sf project deploy start --manifest package.xml --target-org {scratchOrgAlias}
```
18. Generate user credentials, and login to your scratch org.
```
sf org generate password --target-org {scratchOrgAlias}
```
19. When your scratch org is set up, you can create a package, promote it, and submit it for AppExchange Security review. See [Workflow for Second-Generation Managed Packages](https://developer.salesforce.com/docs/atlas.en-us.sfdx_dev.meta/sfdx_dev/sfdx_setup_enable_devhub.htm).
# Window Functions for Formulas
Use window functions to perform calculations across rows. For each row of input data, perform a calculation on a selection—or window—of related rows. Unlike aggregation functions that group rows, window functions return a result for each row. For example, you can calculate the changes to the opportunity amount throughout the stages of each opportunity to see if you can hit your sales target.
When entering a formula, use the API name of the field in the expression, not the label. Surround the parameters with parentheses.
You can use the following window functions in a formula expression.
String Function
Description
Syntax
collect_list
Returns a array type containing duplicates.
collect_list(field )
field is the field for which you want all the values for.
Example: Return all the values from the Owner ID column.
Owner Id
--------
A
B
C
array_join(collect_list(OwnerId), ',') -> A,B,C
collect_set
Returns an array type without duplicates.
collect_set(field )
field is the field for which you want remove duplicate values
from.
Example: Return only the unique values from the Owner ID
column.
Owner Id
--------
A
B
C
array_join(collect_set(OwnerId), ',') -> A,B,C
current
Returns the value from the current record in the partition.
current(field )
field is the field that you want to get the current value
from.
Example: Get the value of the Amount field for the current
row.
current(Amount)
dense_rank
Returns the rank of each record in the partition based on order. Ranks are
consecutive—they don’t repeat when the values match. For example, if the first three rows
have the same value, then the first four ranks are 1, 1, 1, and 2.
dense_rank()
Example: Calculate the dense rank
for rows within each
partition.
dense_rank()
first_value
Returns the value from the first record in the partition.
first_value(field )
field is the field
that you want to get the first value from.
Example: Get the original quote value for
the Quote field.
first_value(Quote)
lag
Returns the value from the previous record in the partition.
lag(field )
field is the field for which
you want to obtain the previous value.
Example: Calculate the percentage change in
profit between the current and previous
records.
(((current(Profit)-lag(Profit)))/current(Profit))*100
last_value
Returns the value from the last record in the partition.
last_value(field )
field is the field that
you want to get the last value from.
Example: Calculate the difference between the
original quote and final
quote.
first_value(Quote)-last_value(Quote)
lead
Returns the value from the next record in the partition.
lead(field )
field is the field for which
you want to obtain the next value.
Example: Get the next value for the Stage
field.
lead(Stage)
rank
Returns the rank of each record in the partition based on order. Repeats the rank when
the values are the same, and skips as many on the next non-match. For example, if the first
three rows have the same value, then the first four ranks are 1, 1, 1, and 4.
rank()
Example: Rank the records in each
partition.
rank()
row_number
Returns the row number in the partition. Increments by 1 for every row in the
partition. For example, if the first three rows have the same value, then the first four
ranks are 1, 2, 3, and 4.
row_number()
Example: Assign a row number to
each record in each
partition.
row_number()
sum
Returns the cumulative sum from groups of values.
sum()
Example: Track the cumulative number of
monthly units shipped tied to a specific sales
agreement.
sum()
# Work with Nodes in Batch Data Transforms
Batch data transforms provide nodes that allow you to bring in data, transform it, and write the results to a target. You add nodes in the canvas. String together multiple nodes to sequentially change the flow of the data. A batch data transform can have multiple Input and Output nodes along with multiple Append, Join, Aggregate, Filter, Transform, and Update nodes.
- **[Input and Output Nodes: Add Data and Write to a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_input_and_output_nodes.htm&release=264.0.0&type=5)**
Add data to a batch data transform with an input node. To save batch data transform output, write your data to one or more output nodes. Input and output nodes can be either data lake objects or data model objects of type Profile or Other. You can’t have a data lake object input node and a data model object output node, and vice versa. Typically data aware specialists and engineers have access to data lake objects and data model objects, whereas marketers and analysts have access only to data model objects.
- **[Combine Rows from Different Data Sources Using the Append Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_append_node.htm&release=264.0.0&type=5)**
Use an append node to combine rows from multiple input data sources into a single result.
- **[Aggregate Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_aggregate.htm&release=264.0.0&type=5)**
Use an Aggregate node to roll up data. You can aggregate to a higher level of granularity or roll up hierarchical data.
- **[Filter Node](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_filter.htm&release=264.0.0&type=5)**
Use a Filter node to remove rows that you don’t need in your target. For example, you can filter case records to focus on escalated cases only. Filter values are case-sensitive.
- **[Join Objects in a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join.htm&release=264.0.0&type=5)**
On the batch data transform canvas, use a node to create a join between data objects. To make sure that data from multiple data objects is combined accurately and not duplicated, always add a key qualifier field to create a fully qualified key (FQK) in a join. To ensure that null values in a key qualifier field are matched correctly, use a null-safe join by replacing null values with null strings or empty strings.
- **[Join Operations](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_join_operations.htm&release=264.0.0&type=5)**
Batch data transforms support these join operations.
- **[Transform Node: Transform the Data Before Loading It Into an Output](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_transform_node.htm&release=264.0.0&type=5)**
Use a Transform node to manipulate data based on the transformations added to the node. You can add one or more transformations to each Transform node. For example, you can add transformations to concatenate two columns, standardize the formats in a date column, and detect the sentiments of comments in a feedback column. Each transformation modifies the data in a unique way. To manipulate data at multiple stages of a data transform, add a separate Transform node at each stage.
- **[Transformations for Batch Data Transforms](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_transformation_overview.htm&release=264.0.0&type=5)**
Use transformations to perform calculations on and manipulate your data. For example, you can use a transformation to create a calculated field based on a formula. You add transformations inside a Transform node. You can string together multiple transformations to manipulate data sequentially.
- **[Update Node: Swap Column Values](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_update.htm&release=264.0.0&type=5)**
You can swap column values with data from another data source when key pairs match with the update node. For example, to update selected account names after a series of recent acquisitions and mergers, replace the name from an uploaded spreadsheet based on matching account IDs. To minimize processing time, change column values with matching key pairs instead of every value in the column.
- **[Copy and Paste a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_copy_paste.htm&release=264.0.0&type=5)**
Use the toolbar or keyboard shortcuts to copy and paste nodes within a single batch data transform or across multiple ones. To use this feature, enable clipboard access permissions in your browser.
- **[Connect and Reorganize Nodes or Branches in a Batch Data Transform](https://help.salesforce.com/s/articleView?id=data.c360_a_batch_transform_connect_nodes_and_branches.htm&release=264.0.0&type=5)**
Connect disconnected nodes or branches to append data from any node to any other node in a batch data transform. You can also create a branch at an intermediate node, and append it to another path in the batch data transform.
# Workflow
Learn how data flows through the configurations when you welcome new loyalty members to your program.
## Workflow for the Loyalty Welcome Journey
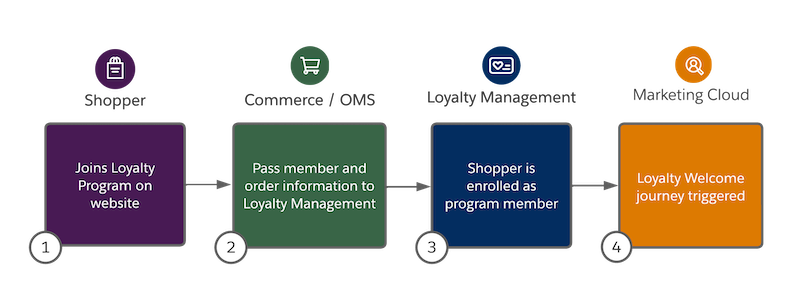
- Shopper joins the Loyalty Program by signing up online or in-store. (1)
- The Commerce and OMS systems send the member and order information to Loyalty Management using the API. (2)
- Loyalty Management receives member enrollment and updates membership tiers and points based on the defined loyalty programs. (3)
- A Salesforce data entry event identifies the new loyalty program member and triggers a Marketing Cloud Engagement Loyalty Welcome journey. (4)
## Understanding the Flow of Data
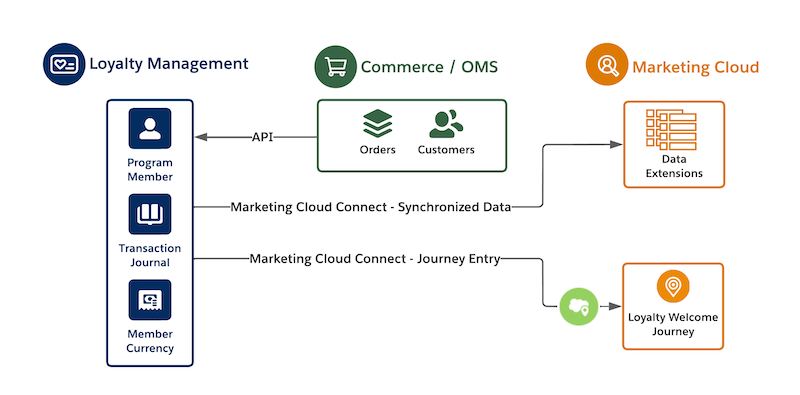
- To send member information and reward transactions to Loyalty Management from Commerce, OMS, and POS systems, implement API processes.
- To replicate loyalty data in Marketing Cloud Engagement, [implement Marketing Cloud Connect](https://help.salesforce.com/s/articleView?id=mktg.mc_co_connect_the_clouds.htm&type=5&language=en_US) and [synchronize Loyalty Management data extensions](https://help.salesforce.com/s/articleView?id=xcloud.content_block.htm&type=5&language=en_US).
- To enter subscribed loyalty members into a Loyalty Welcome Journey, use a Salesforce Data Entry Event.
#### See Also
- [_Salesforce Help_: Synchronized Data Sources Best Practices](https://help.salesforce.com/s/articleView?id=mktg.mc_co_implement_synchronized_data_sources_best_practices.htm&type=5&language=en_US)
# Working with Nodes in Visual Insight Builder
Visual Insight Builder uses a low-code, drag-and-drop interface to simplify the creation of streaming, calculated, and real-time insights. Visual components replace complex code, allowing you to develop metrics and expressions, regardless of technical expertise.
## Supported Nodes for Visual Insight Builder
Nodes are the key components of a workflow, enabling the execution of a series of operations by connecting nodes with different functionalities.
Node
Function
Calculated Insights Streaming Insights Real Time Insights
Using the Join Node Left Join
Yes
Yes
No
Right Join
Yes
Yes
No
Inner
Yes
Yes
No
Full
Yes
Yes
No
Using the Aggregate Node Count
Yes
Yes
Yes
Sum
Yes
Yes
Yes
Average
Yes
No
No
Maximum
Yes
No
Yes
Minimum
Yes
No
Yes
Lead
Yes
No
No
Lag
Yes
No
No
Rank
Yes
No
No
Dense Rank
Yes
No
No
Percent Rank
Yes
No
No
Approximate Count Distinct
Yes
No
No
First Value
Yes
No
No
Last Value
Yes
No
No
Row Number
Yes
No
No
NTile
Yes
No
No
Using the Case Node equal
Yes
No
Yes
not
Yes
No
Yes
is null
Yes
No
Yes
is not null
Yes
No
Yes
less than
Yes
No
Yes
less than or equal to
Yes
No
Yes
greater than
Yes
No
Yes
greater than or equal to
Yes
No
Yes
is empty
Yes
No
Yes
contains
Yes
No
Yes
does not contain
Yes
No
Yes
contains regular expression
Yes
No
Yes
does not contain regular expression
Yes
No
Yes
Using the Filter Node equal
Yes
Yes
Yes
not
Yes
Yes
Yes
is null
Yes
Yes
Yes
is not null
Yes
Yes
Yes
less than
Yes
Yes
Yes
less than or equal to
Yes
Yes
Yes
greater than
Yes
Yes
Yes
greater than or equal to
Yes
Yes
Yes
is empty
Yes
Yes
Yes
contains
Yes
Yes
Yes
does not contain
Yes
Yes
Yes
contains regular expression
Yes
Yes
Yes
does not contain regular expression
Yes
Yes
Yes
Relative DateTime
Yes
No
Yes
Using the Transform Node Absolute Value
Yes
No
No
Mod
Yes
No
No
Random
Yes
No
No
Round
Yes
No
No
Regular Expression
Yes
No
No
Regular Expression Extract
Yes
No
No
egular Expression Replace
Yes
No
No
Null If
Yes
No
Yes
Right Trim
Yes
No
Yes
Left Trim
Yes
No
Yes
Trim
Yes
No
Yes
Substring
Yes
No
No
Lowercase
Yes
No
Yes
Uppercase
Yes
No
Yes
Hour
Yes
No
No
Day
Yes
No
No
Month
Yes
No
No
Quarter
Yes
No
No
Year
Yes
No
No
CDP Hour
Yes
No
No
CDP Day
Yes
No
No
CDP Month
Yes
No
No
CDP Quarter
Yes
No
No
CDP Year
Yes
No
No
Day of Week
Yes
No
No
Day of Month
Yes
No
No
Day of Year
Yes
No
No
Current Date
Yes
No
No
Date Addition
Yes
No
No
Date Subtraction
Yes
No
No
Date Difference
Yes
No
No
Date Truncation
Yes
No
No
To Date
Yes
No
No
To Timestamp
Yes
No
No
- **[Using the Join Node](https://help.salesforce.com/s/articleView?id=data.c360_a_using_the_join_node.htm&release=264.0.0&type=5)**
The Join node combines data from multiple sources based on shared values. A column represents a category of information, such as an opportunity source or account name.
- **[Using the Aggregate Node](https://help.salesforce.com/s/articleView?id=data.c360_a_using_the_aggregate_node.htm&release=264.0.0&type=5)**
The aggregate node performs a calculation on a set of values and returns a single value. For example, Average returns the average value of a numerical column. You can use dimensions to roll up the records to a higher granularity. Dimensions, which are typically textual, categorize and describe data by supplying qualitative data points. They are commonly used to filter and segment data based on specific characteristics, such as customer ID, product type, location, or date. Dimensions provide context for measurements, which allows for analysis across different aspects of a dataset.
- **[Using the Case Node](https://help.salesforce.com/s/articleView?id=data.c360_a_using_the_case_node.htm&release=264.0.0&type=5)**
The case node, similar to the CASE statement in SQL, analyzes data by comparing the attributes of conditions. The WHEN/THEN statements determine the outcome based on whether all or any of the specified conditions are true. If none of the WHEN conditions are met, the ELSE statement provides an alternative action. The Case node statement must be followed by at least one WHEN/THEN pair, which applies a designated function when the associated condition is true.
- **[Using the Filter Node](https://help.salesforce.com/s/articleView?id=data.c360_a_using_the_filter_node.htm&release=264.0.0&type=5)**
The filter node uses the selected operator and value to keep or remove data based on whether any or all of the specified conditions are met.
- **[Using the Transform Node](https://help.salesforce.com/s/articleView?id=data.c360_a_using_the_transform_node.htm&release=264.0.0&type=5)**
Use a Transform node to manipulate data based on the transformations added to the node. To manipulate data at multiple stages of a data transform, add a separate Transform node at each stage.
# Write the Batch Data Transform Results to a Data Lake Object Output Node
To use your batch data transform as input to identity resolution, calculated insights, or segmentation, you write the results to a new or existing data lake object (DLO) in an output node. The object that holds the output is called a target data lake object. You can’t save a batch data transform without an output node.
1. At the end of your batch data transform, click the Add Node button () and select **Output**.
- To use an existing DLO, select **Use Existing**. Select the object to write the results to, and then click **Apply**.
- To create a new DLO, select **Create New**.
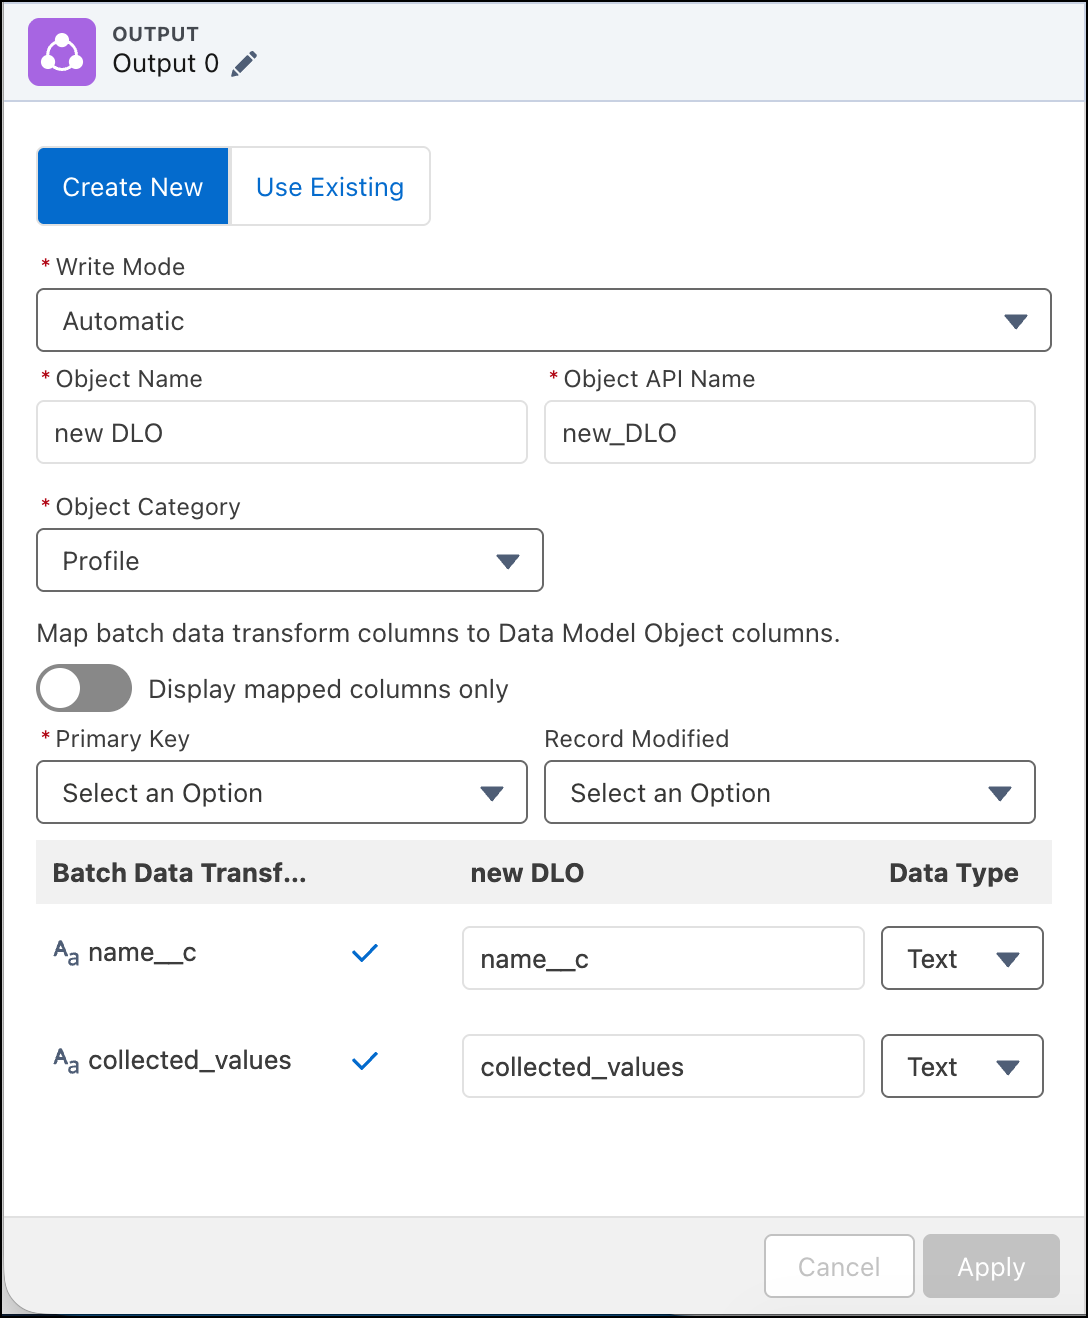
2. For the output Write Mode, select either **Replace** or **Upsert**.
- Replace mode:
- Loads all input data in every run.
- Merges input data into the output by replacing all columns in the record during the upsert operation.
- Requires all columns in the output object to be mapped.
- Doesn't allow carrying over values from the existing record.
- Upsert mode:
- Replace attempts incremental transforms, loading only changes from previous runs into the output.
- Allows unmapped columns in the output object.
- When the transform runs, unmapped columns will contain null values.
3. Choose which data lake object fields to map to the batch data transform’s fields. You can only map fields that have the same data type. Fields that share the same name are automatically selected.

Note You can't map the system fields, Data Source and Data Source Object. If you edit a transform that has these fields manually mapped, remove them from the output node and save your changes.
1. When you map transform results to an output node, the transform’s currency (ex. USD, INR, GBP) is written to the output’s currency field. The currency field can't be used as a primary key.
#### See Also
- [_Salesforce Help_: Data Objects in Data 360](https://help.salesforce.com/s/articleView?id=data.c360_a_data_lake_objects.htm&release=264.0.0&type=5 "When working with Data 360, it’s helpful to know about Data 360 data objects including data lake objects (DLO) and data model objects (DMO).")
# Write the Batch Data Transform Results to a Data Model Object Output Node
Write the results of a batch data transform to an existing data model object or one created through the output node. The object that holds the output is called a transform data model object. You can only write to a transform type data model object within a data transform. You can use a transform type data model object as input to another batch data transform and downstream processes such as identity resolution, calculated insights, and segmentation.
1. At the end of your batch data transform, click the Add Node button () and select **Output**.
- To use an existing data model object, select **Use Existing**. Select the object to write the results to, and then click **Apply**.
- To create a new data model object, select **Create New**.

Important
To write results to a DMO output node using a new DMO, select "Create New." If you create a new DMO from the Data Model tab, the DMO will not be available for selection.
2. For the required Object Name field, enter the name of your transform data model object.
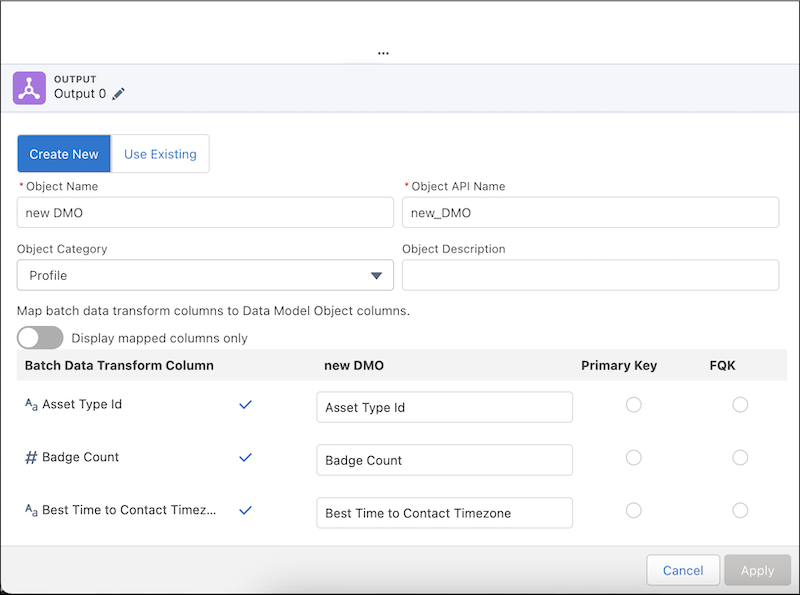
3. Choose which data model object fields to map to the batch data transform’s fields. Fields that share a name are automatically selected.

Note You can't map the system fields, Data Source and Data Source Object. If you edit a transform that has these fields manually mapped, remove them from the output node and save your changes.
1. When you map transform results to an output node, the transform’s currency (ex. USD, INR, GBP) is written to the output’s currency field.
4. Select a column to be the primary key.
You can't select a currency field as a primary key.
5. Select a column to be the fully qualified key (FQK).
To prevent having multiple DMO records with the same primary key value, use a fully qualified key to distinguish between them.
#### See Also
- [_Salesforce Help_: Data Model Objects](https://help.salesforce.com/s/articleView?id=data.c360_a_data_model_objects.htm&release=264.0.0&type=5 "Create, view, and manage data model objects (DMOs). DMOs are fundamental to Data 360. Familiarize yourself with the definitions, concepts, and resources related to DMOs before creating or working with them.")
- [_Salesforce Help_: Data Interpretation with Fully Qualified Keys](https://help.salesforce.com/s/articleView?id=data.c360_a_data_inter_fqk.htm&release=264.0.0&type=5 "Fully qualified keys help to accurately interpret data ingested from different sources. Each data stream is ingested into Data 360 with its specific keys and attributes. When multiple data streams are harmonized into a single data model object (DMO), the various keys can conflict and records can have same key values. Fully qualified keys avoid conflicts by adding key qualifier fields and interpreting the data accurately.")
# Zero Copy Data Federation
The Data 360 zero copy data federation is the process of querying data from multiple, physically distinct data sources. This approch allows users to treat disparate systems as a single logical system, called a federation, while maintaining the autonomy of each system. Importantly, data federation avoids duplicating data across system boundaries. Data 360.
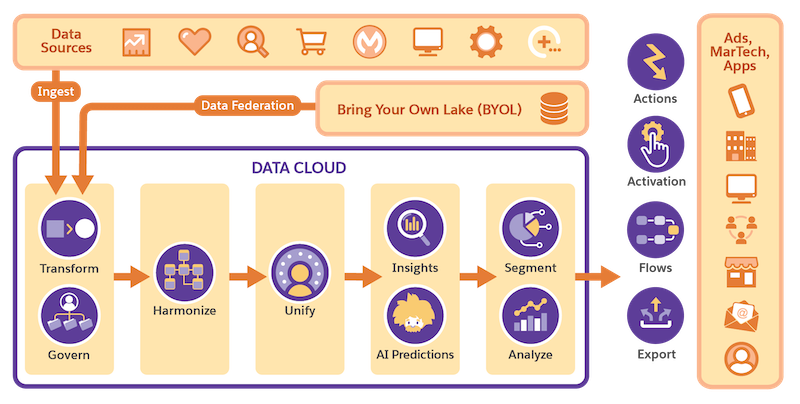
Each system involved in data federation consists of two primary components: the storage component and the compute component. The storage component is tasked with storing the data, while the compute component is responsible for querying data stored in the storage component. In some systems, the underlying data is organized using an open table format.
Data 360 supports data federation through two methods:
- Query Federation (Compute): When you launch a workflow that requires data from an external system, Data 360 sends SQL queries to the external system's compute engine. The external system executes the query and returns the relevant records to the workflow in Data 360. The records aren't retained after the work flow is complete.
- File Federation (Storage): Data 360 directly queries external storage systems, provided the data is organized using a supported open table format. Data 360 uses its own query engine (and compute) to get the necessary records for the workflow. Similar to query federation, the records aren't retained after the workflow is complete.
Regardless of whether data is ingested or federated, Data 360 creates a Data Lake Object (DLO). However, when using a zero copy connector, the DLO doesn't contain any actual data and acts as a pointer to the external physical table. Hence, DLOs created via zero copy connectors are called as external or virtual DLOs.
- **[Caching or Acceleration in Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_accelerated_data_lake_objects.htm&release=264.0.0&type=5)**
Caching retrieves data from the external source and temporarily stores it in a data lake object in Data 360. When you enable acceleration while creating a data stream, you turn on caching. We recommend caching when accessing large data sets or when data changes frequently. You can refresh the cached data at your preferred frequency.
- **[Compare Data Federation Methods](https://help.salesforce.com/s/articleView?id=data.c260_a_data_federation_compare_methods.htm&release=264.0.0&type=5)**
Data can be federated via live queries, accelerated queries to the local data cache, or via file federation. Each option supports different use cases. Performance, data freshness, and credit consumption considerations vary.
- **[Billing Considerations for Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_billing_considerations_for_data_federation.htm&release=264.0.0&type=5)**
Data Federation uses Data 360 to query and activate external warehouse data without copying it. Use of Data Federation impacts the consumption of credits in these usage types.
#### See Also
- [_Salesforce Developers_: Data 360 Integrations Guide](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-data-cloud-integrations.html)
- [_Salesforce Developers_: Amazon Redshift](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-redshift-connector.html)
- [_Salesforce Developers_: Databricks](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-databricks-connector.html)
- [_Salesforce Developers_: Google BigQuery](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-bigquery-connector.html)
- [_Salesforce Developers_: Snowflake](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-snowflake-connector.html)
- [_Salesforce Developers_: Apache Iceberg](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-apacheiceberg-connector.html)
- [_Salesforce Developers_: IBM watsonx.data](https://developer.salesforce.com/docs/data/data-cloud-int/guide/c360-a-watsonx-connector.html)
# Zero Copy Data Federation Supportability
Refer to the list of supported and unsupported features of Data 360 when you use zero copy data federation.
## Supported
These features of Data 360 are supported when federating data from external sources.
- Data spaces
- Batch data transforms
- Calculated Insights (Batch)
- Streaming Insights for related objects only
- Identity resolution
- Segmentation
- Activation
- Data Actions

Note You can't map an external data lake object (DLO) to an Individual or a Lead data model object (DMO) that has a Data Action or Data Share associated with it.
- Batch Predictions in Bring Your Own Model (BYOM)
- Data 360 Related Lists
- Querying external DLO via Data Explorer and Query APIs
- Related lists
- Field enrichments
- Search index

Note To use DMOs in a search index, they must be mapped from external DLOs that have acceleration or caching enabled. You can’t use DMOs that have mappings from a mix of native and external DLOs.
## Not Supported
You can’t use these features of Data 360 when federating data from external sources.
- Extending schema with formula fields or data type changes
- Changes in data types
- Data sharing of external DLOs and DMOs with an external data lake
- Rapid segmentation and activation
- Streaming data transforms
- Near real time identity resolution
- Streaming predictions in BYOM
- Changes to the source table schema (field name changes, capitalization changes)

Note At present, zero copydata federation supports a limited set of predicates for creating calculated insights and segments.
#### See Also
- [_Salesforce Help_: BYOL Data Federation](https://help.salesforce.com/s/articleView?id=data.c360_a_byol_data_federation.htm&release=264.0.0&type=5 "The Data 360 zero copy data federation is the process of querying data from multiple, physically distinct data sources. This approch allows users to treat disparate systems as a single logical system, called a federation, while maintaining the autonomy of each system. Importantly, data federation avoids duplicating data across system boundaries. Data 360.")
- [_Salesforce Help_: Data 360 Glossary of Terms](https://help.salesforce.com/s/articleView?id=data.c360_a_glossary_guide.htm&release=264.0.0&type=5 "Learn the definition of terms associated with Data 360.")