
Identity resolution processes rulesets as frequently as every 60 minutes to 24 hours, depending on the data source. Each data source is processed on its own timeline according to when data is received and how many changes accumulate.
To process all data sooner, run the ruleset manually or kick it off with an API command. Rulesets won’t run if no records have changed since the previous run.
| Data Source | Connectors | data preprocessing? | processing frequency |
|---|---|---|---|
|
Any ingestion connector | Yes | Up to 18 hours |
|
Streaming ingestion connectors
Any batch ingestion connector |
No, because the data stream only includes new and changed records | 1 hour or when 500 changes accumulate in change data capture, whichever is sooner |
| Federated Data |
Zero Copy Data Federation (Accelerated)
|
Yes | When accelerated data is received, as often as every 1 hour |
| Federated Data |
Zero Copy Data Federated (Non-accelerated)
|
Yes | Up to 24 hours |
| Real-time data | Data 360 Web SDK | No | Immediately |
For a complete list of connectors, see Data 360: Connectors and Integrations.
Data Preprocessing in Identity Resolution
Data from batch and federated sources is preprocessed to remove records that don't need to be match before source records are sent to identity resolution. This ensures that identity resolution is only processing records that are new or changed, and isn’t rerunning unchanged source records. Preprocessing helps identity resolution run rulesets faster in order to achieve incremental processing, and ensures that credits aren’t consumed by running identity resolution on records that have already been unified in their current form.
To determine if a record is new or changed, source records are converted to an MD5 hash value. The hash value of each record is compared to the hash values of records previously run by identity resolution. Only records with unique hash values are sent for processing by identity resolution.
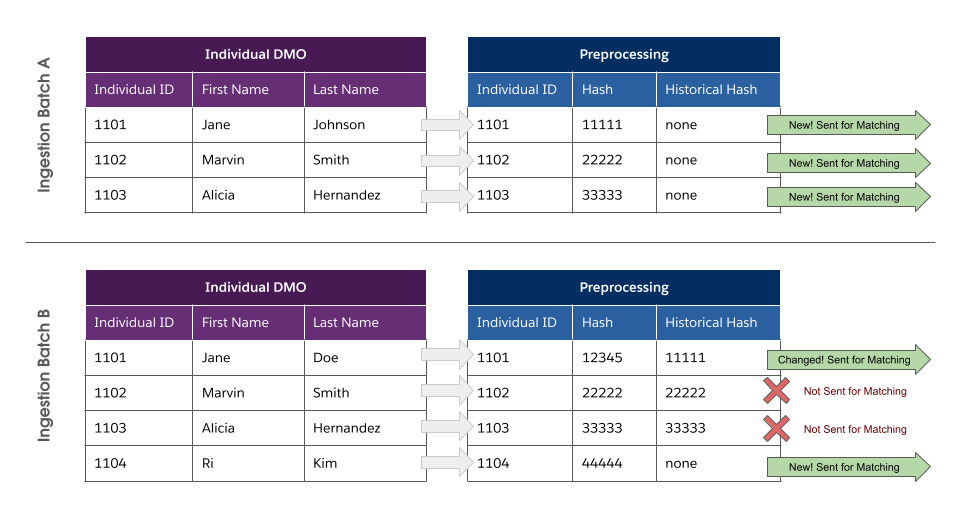
Record preprocessing prevents identity resolution from running unchanged records even if a data source runs a full refresh.