A right join includes all rows from the right and only matching rows from the left input data source objects. The join includes all matched rows in the data output when multiple rows match.

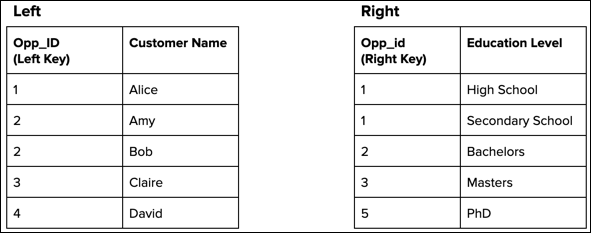
Our company's marketing team captures demographic data in an external data source for opportunities stored in Salesforce. To help create more targeted campaigns, the team is segmenting our current opportunities by the Education Level demographic. Let’s use a right join to add the opportunity data to the demographic data.
To illustrate how this batch data transform handles unmatched rows and duplicate keys, we included them in both input data sources.
After performing the right join based on the matching keys, the data transform produces the following output data.
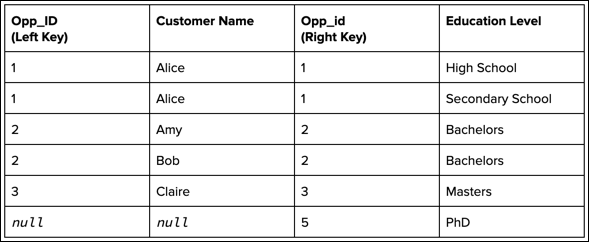
All rows from the right, including those without a match and those with multiple matches, are
included in the output. Because Opp_id 2 has two matches on
the left (Amy and Bob), the target contains a separate record for each of them. Also, because
Opp_id 5 doesn’t have a match, the Opp_ID and Customer Name
fields are null for that record.

Opp_id 1 in the following screenshot), don’t double count the
measures when aggregating the records. To prevent duplicate records, use a lookup instead of a
join.