| Pattern Type | Mode/Tool | Benefits | Considerations | Outcomes |
|---|---|---|---|---|
| Data Ingestion |
Real-Time:
|
|
|
Agentforce:
|
Streaming:
|
|
|
Agentforce:
|
|
Batch:
|
|
|
Agentforce:
|
|
| Zero Copy |
Live Query:
|
|
|
Agentforce:
|
Accelerated Query (Caching):
|
|
|
Agentforce:
|
|
File Federation:
|
|
|
Agentforce:
|
 #### Data Ingestion Methods
_Data Ingestion_ methods may vary, depending upon which connector you use to ingest your data. Some connectors offer a variety of ingestion methods, while others operate only in batch or streaming mode. For a complete list of _Data 360_ connectors and available methods, check out [Data 360\: Integrations and Connectors](https://help.salesforce.com/s/articleView?id=data.c360_a_sources_targets.htm&type=5).
- **Real-Time\:**
- Provides sub-second ingestion using _Change Data Capture (CDC)_
- Suitable for time-sensitive workflows (for example, fraud detection, personalization, and operational dashboards)
- Features push transformations and aggregations within _Data 360_, which helps to reduce downstream I/O and optimize compute usage
- Supports using incremental CDC to minimize data shuffling
- **Streaming\:**
- Provides ingestion every 1–3 minutes in small increments
- Balances freshness and cost
- Suitable for campaign orchestration, near-live engagement, and operational reporting
- Supports using micro-batches to control I/O spikes
- Aggregates data at the source (if possible) to reduce transfer volumes and optimize storage
- **Batch (Scheduled Loads)\:**
- Provides periodic ingestion of large datasets (for example, hourly, daily, and weekly)
- Provides cost-efficiency and reliability for historical datasets, regulatory reporting, and compliance use cases
- Ensures that compute locality is in the same region as the source storage to enhance performance and optimize costs
#### Architect Playbook
- **Data Ingestion Use Cases\:**
- **Generate Customer 360 Unified Profiles.** Build a single source of truth for customer identities and attributes.
- **Maintain regulatory compliance datasets.** Enforce governance, lineage, and auditability for sensitive data.
- **Centralize campaign orchestration.** Ensure that marketing, sales, and service all operate from consistent, trusted datasets.
- **Design Practices\:**
- Accommodate batch ingestion for historical or low-latency-tolerant needs (for example, archival reporting or periodic snapshots).
- Use CDC or streaming APIs to maintain freshness for operational and personalization workflows to ensure near real-time updates.
- Control storage and compute growth by applying incremental loads to optimize cost and efficiency (rather than reloading entire datasets).
- Align ingestion pipelines with compute locality and incremental processing to reduce network I/O.
- Apply transformations inside _Data 360_ to avoid moving raw data unnecessarily.
- **Cost Considerations\:**
- **Real-Time Ingestion** has the highest compute and pipeline costs, which may be justified for high-value, time-sensitive workflows (for example, personalization, operational dashboards, or Agentforce-driven actions).
- **Streaming Ingestion** has moderate compute and storage costs, which may be suitable for frequent updates that can tolerate slight delays (for example, campaign orchestration or operational reporting).
- **Batch Ingestion** has lower compute costs and predictable storage, which is suitable for historical datasets or low-frequency updates. Ingesting batch data from Salesforce orgs using certain connectors is free.
- **Refresh Mode** Allows you to select _Incremental Refresh_ mode, which reduces total ingestion and compute costs. At Salesforce, we recommend using _incremental refresh_ wherever possible to optimize efficiency across all ingestion types.
- **Cost** is also impacted by I/O volume from the source to _Data 360_. Optimizing batch sizes, partitions, and regional alignment reduces transfer costs and improves performance.
- **Industry Scenarios\:**
- **Finance\:** Ingestion datasets are required for _knowing your customer (KYC)_, _Anti Money Laundering (AML)_, and fraud detection where auditability and compliance are non-negotiable.
- **Healthcare\:** Use ingestion for patient identity resolution and HIPAA-compliant records, which enables secure, unified views.
- **Retail\:** Consolidate _point of sale (POS)_, eCommerce, and loyalty program data into unified profiles for segmentation and personalization.
- **Telecom\:** Support churn prevention and usage analytics with canonical, governed subscriber data.
#### Data Ingestion Method Decision Criteria
| Feature | Real-Time Ingestion | Streaming Ingestion | Batch Ingestion |
| :----------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | :------------------------------------------------------------------------------------------------------------------------------------------------------------ | :----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Latency and Freshness** | Features sub-second latency ingestion via Ingestion APIs with _Change Data Capture (CDC)_ support. Provides continuous streaming pipelines. Suitable for low-latency operational use cases. | Features micro-batch ingestion every 1–3 minutes via native connectors. Supports incremental updates. Slight latency is expected. | Data latency is expected. Allows scheduled large-volume loads. Features periodic ingestion (hourly, daily, and weekly). Not suitable for time-sensitive operations. |
| **Primary Use Cases** | Ideal for low-latency operational and personalization use cases. Use for time-sensitive workflows. Supports event-driven workflows. Use for real-time fraud alerts and operational alerts. | Suitable for moderately urgent processes. Use for campaign orchestration, near-live engagement, and operational reporting. Use for timely campaign triggers. | Cost-efficient for massive datasets. Reliable for historical analytics. Use for historical aggregation or regulated reporting workflows. Suitable for historical or low-velocity datasets. |
| **Architectural Complexity and I/O** | Includes high cost and complex architecture. Requires low-latency source systems. I/O intensive. High-volume sources can cause saturated pipelines. | Features simpler architecture than real-time. I/O is moderate. Suitable for predictable, repeated update patterns. Batch size impacts memory and computation. | Easy to implement. I/O intensive during load windows. Network throughput may become a bottleneck for large batches. |
| **Cost Considerations** | Includes the highest compute and pipeline costs. Justifiable for high-value, time-sensitive workflows only. | Includes moderate compute and storage costs. Provides a balanced cost vs freshness approach. Suitable for frequent updates that can tolerate slight delays. | Features lower compute costs and predictable storage. Recommended for historical datasets or low-frequency updates. Ingestion via Salesforce internal pipelines is free. |
| **Design Practices** | Use incremental CDC to minimize data shuffling. Filter and use selective fields to reduce overhead. | Use micro-batches to control I/O spikes. Consider windowed aggregation to reduce processing load. | Use for archival reporting or periodic snapshots. Ensure that compute locality is in the same region as source storage for cost optimization. |
### Zero Copy Data Federation
#### Zero Copy Use Cases
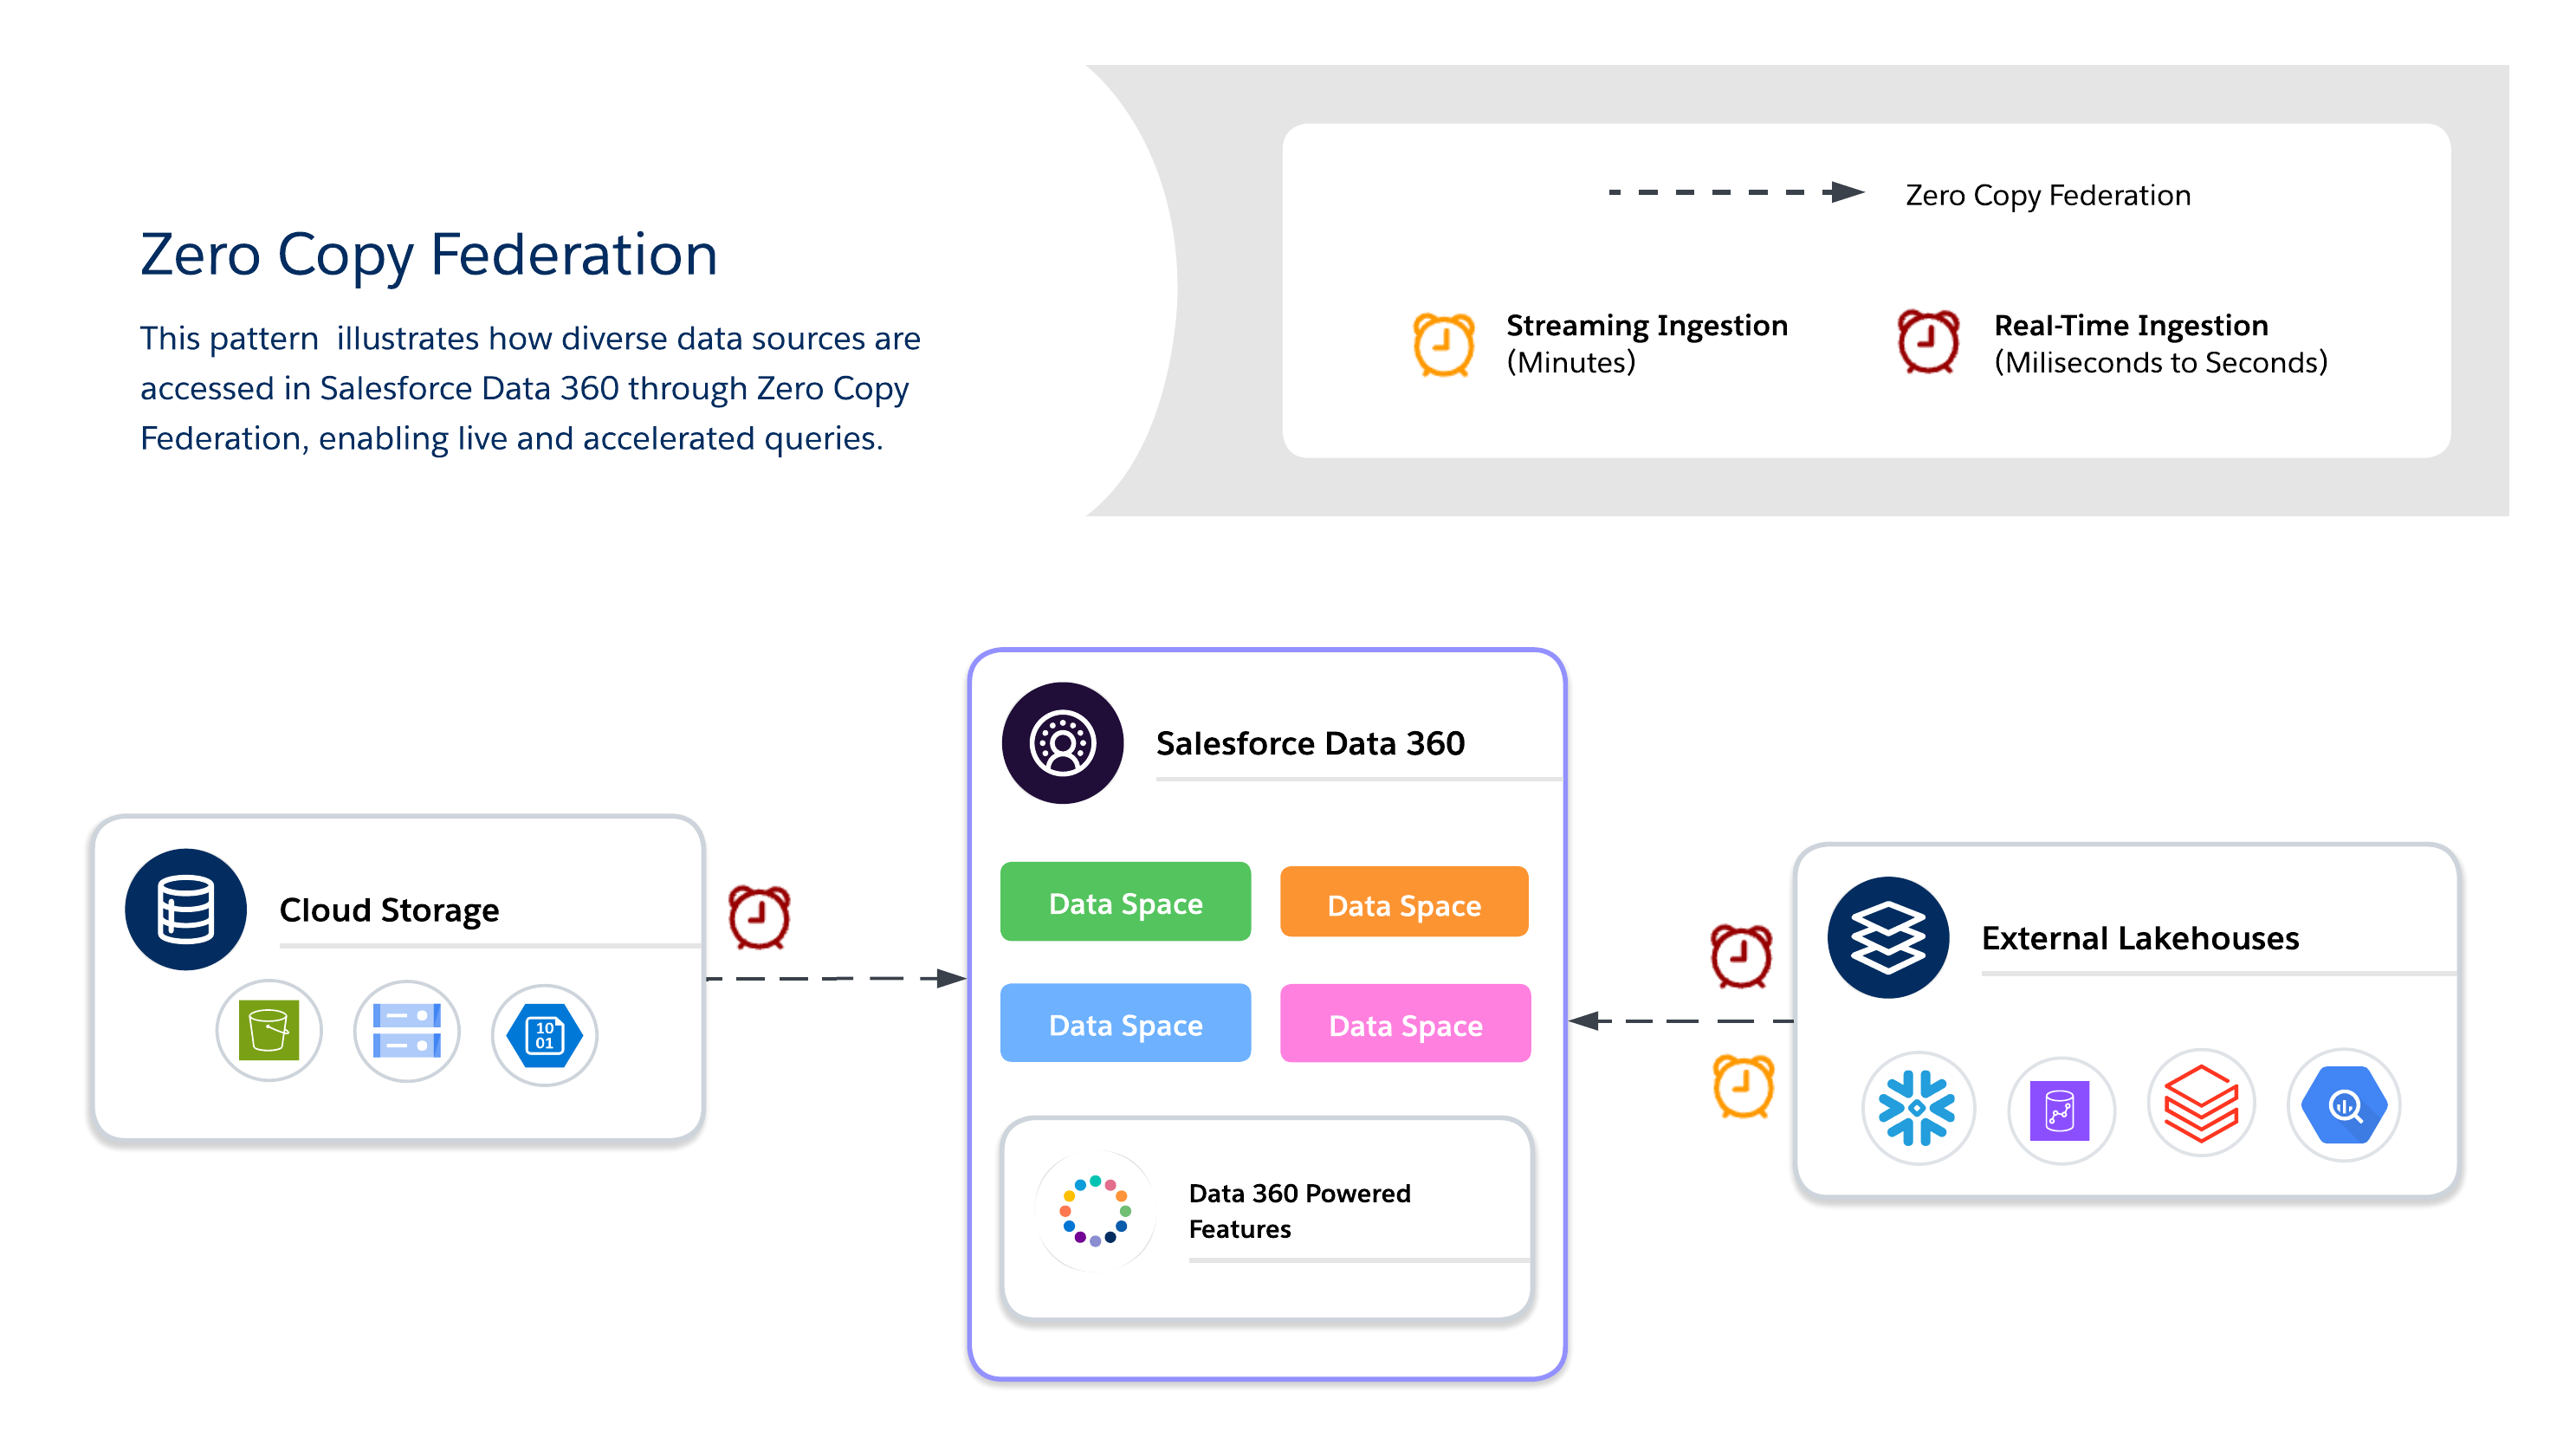
Use _Zero Copy_ for real-time querying of external systems without data duplication to enable agility, freshness, and scalable access to large or transient datasets. It's suitable for live dashboards, exploratory analytics, AI/ML model training, and real-time customer engagement directly through Salesforce _Data 360_.
 #### Zero Copy Methods
When using _Zero Copy_, architects must choose between three available data federation methods, each of which offers its own tradeoffs between freshness, performance, and cost.
- **Live Query**
- Runs queries directly against external systems (for example, _Snowflake_, _Google BigQuery_, _Redshift_, _Databricks_, and so on) with no data duplication.
- Minimizes data movement over the network and reduces I/O on the Salesforce _Data 360_ computation, which is optimal when predicates and aggregations can be pushed down.
- Suitable for real-time insights and low-latency operational dashboards.
- Dependent upon external system performance.
- **Caching (Accelerated Query)**
- Temporarily stores cached copies of federated data in Salesforce _Data 360_.
- Reduces repeated query costs and latency for frequently accessed datasets with configurable duration (minutes to days).
- Data isn't permanently copied or fully governed, so freshness is managed via scheduled refreshes from the source.
- _Incremental refresh_ supports upserts only. Deleted records aren't removed from the cache.
- Perform a full refresh periodically to ensure that the cache remains in sync with the source.
- **Note\:** The _Snowflake_ connector supports the _Unload_ function, which enhances acceleration rates by using a Snowflake-initiated staging bucket. This is enabled by default, but it can be disabled by editing the connection.
- **File Federation**
- Provides direct, read-only access to large-scale datasets in object stores (for example, _S3_ and _GCS_ with _Iceberg_).
- Suitable for AI/ML workloads, historical analytics, and petabyte-scale reporting without moving data.
- Query performance depends heavily on object format, partitioning, and network I/O. Large scans may generate substantial I/O if they aren't optimized.
#### Architect Playbook
- **Use Cases**
- **Real-time personalization and adaptive workflows** deliver dynamic offers, recommendations, and next-best actions as customer behaviors change.
- **Live dashboards and operational analytics** power business-critical dashboards and KPIs directly from external warehouses.
- **AI/ML model training with large external datasets** leverage petabyte-scale data from data lakes and warehouses without moving it via file federation.
- **Industry Scenarios**
- **Retail/Media\:** Enable personalized recommendations and real-time customer engagement by federating clickstream or content interaction data.
- **Finance\:** Run fraud detection and risk scoring in near-real time by querying external warehouses without duplicating sensitive data.
- **Tech/Enterprise\:** Support cross-cloud reporting, IT service dashboards, and operational analytics when datasets reside in multiple systems.
- **Design Practices**
- **Live Query**
- Use for high-QPS, low-latency queries when freshness is critical.
- Push predicates and aggregations to the external system to reduce data shuffling over the network.
- Avoid queries that unnecessarily scan massive data volumes.
- Consider partition pruning and filters instead.
- **File Federation**
- Access petabyte-scale datasets in object stores without ingestion.
- Minimize latency and egress costs by keeping object storage in the same Cloud region as Salesforce computation.
- Use partitioned, columnar formats (Parquet/ORC) and pushdown filters to reduce I/O and network transfer.
- Leverage query and predicate pushdown to filter and aggregate data at the source, which reduces data movement.
- Avoid cross-region data access—unless it's absolutely necessary—because it increases I/O, latency, and costs.
- **Caching (Accelerated Query)**
- Cache frequently accessed datasets to balance cost and performance.
- Configure refresh intervals to balance freshness vs. query cost.
- **Compliance\:** Enforce governance at the source by leveraging _row-level security (RLS)_ and masking policies directly within federated systems.
- Here are a few best practices for uniform RLS and masking across platforms\:
- **Use a Centralized Enterprise ID.** Map users and entities in Salesforce _Data 360_ to a unique, centralized enterprise identifier that corresponds to identities in external systems.
- **Align Security Policies.** Ensure that RLS and masking policies in federated systems are applied based on the mapped identity. This preserves compliance when querying external data.
- **Standardize Identity Schemas.** Maintain consistent identity attributes (email, user ID, customer ID, and so on) across all data sources to avoid mismatches and access violations.
- **Cost Considerations**
- **Live Query\:** In the pay-per-query model, costs accrue on external lake house computation, which may cause spikes with high QPS. This is suitable for freshness-critical use cases where the value is greater than the cost variability.
- **Accelerated Query (Caching)\:** This method lowers query cost (as compared to _Live Query)_ by reducing hits to the source system; however, it adds to batch data ingestion costs for filling and refreshing the cache. This is suitable for frequently-accessed datasets.
- **File Federation\:** This is the cheapest storage option as data in Object Store; however, query costs depend on the file size, partitioning, and pruning. This is suitable for historical or bulk data at petabyte scale.
#### Zero Copy Method Decision Criteria
| Decision Point | Live Query | Caching (Accelerated Query) | File Federation |
| :----------------------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Data Source Location** | External data lake houses (for example, _Snowflake_, _Google BigQuery_, _Redshift_, and _Databricks_) | External data lake houses (for example, _Snowflake_, _Google BigQuery_, _Redshift_, and _Databricks_) | Object Stores or Cloud data lakes (for example, _S3_, _ADLS_, and _GCS_), which often use open-table formats like _Iceberg_. |
| **Purpose/Use Case** | Suitable for interactive analysis and real-time dashboards. Suitable for real-time personalization and dynamic workflows. | Suitable for when queries are frequent, but slightly stale results are acceptable. Suitable for BI dashboards and segmentation. | Suitable for large-scale batch processing and AI/ML model training. Suitable for historical analytics and petabyte-scale reporting. |
| **Freshness/Latency** | Provides maximum freshness Runs queries directly in real time. Supports sub-second decisioning when the source system is optimized for low-latency queries with effective predicate pushdown. | Use when slightly stale results are acceptable. Freshness depends on the cache interval, which is configurable from 15 minutes to 7 days. | Suitable for batch-heavy, throughput-intensive jobs. Not suitable for real-time dashboarding. |
| **Access Pattern** | Suitable for infrequent or ad-hoc queries where freshness is critical and query volume is low. Costs spike significantly at high QPS, so it's important to evaluate caching (Accelerated Query) when query frequency is high. | Suitable for high-frequency read scenarios. Improves performance for frequent access patterns. | Provides r*ead-only* access. Suitable for petabyte-scale datasets without ingestion. |
| **Performance Drivers** | Highly dependent upon external source system performance. Suitable for when predicates and aggregations can be pushed down to the source. | Reduces latency when compared to repeated live queries. Performance depends on cache management and intervals. | Performance depends heavily on object format, partitioning, and external system throughput. Use partitioned, columnar formats (Parquet/ORC). |
| **Cost Implications** | This is a pay-per-query model, so costs accrue on external lake house computations. It's cost-effective for infrequent queries, but expenses may spike with high QPS volume. | The cost is lower than repeated live queries. It reduces the need to repeatedly query the external source, but it adds cache storage and refresh overhead. | This is the cheapest storage option. For same-region, same-cloud AWS setups (for example, _S3_ in US-East-1 with a _Data Cloud_ tenant that's also in US-East-1), credits aren't consumed for the rows that are accessed. Cross-region or cross-Cloud configurations (for example, _Azure_, _GCS_, or different _AWS_ regions) incur credit consumption for the rows that are accessed. Query costs also depend on file size, partitioning, and predicate pushdown optimization. |
| **Key Consideration** | Avoid unfiltered queries that scan massive data volumes unnecessarily. | This approach requires cache management. Not suitable for sub-second decisioning. | Query performance relies heavily on optimization via partitioning and predicate pushdown. |
### Hybrid Approach
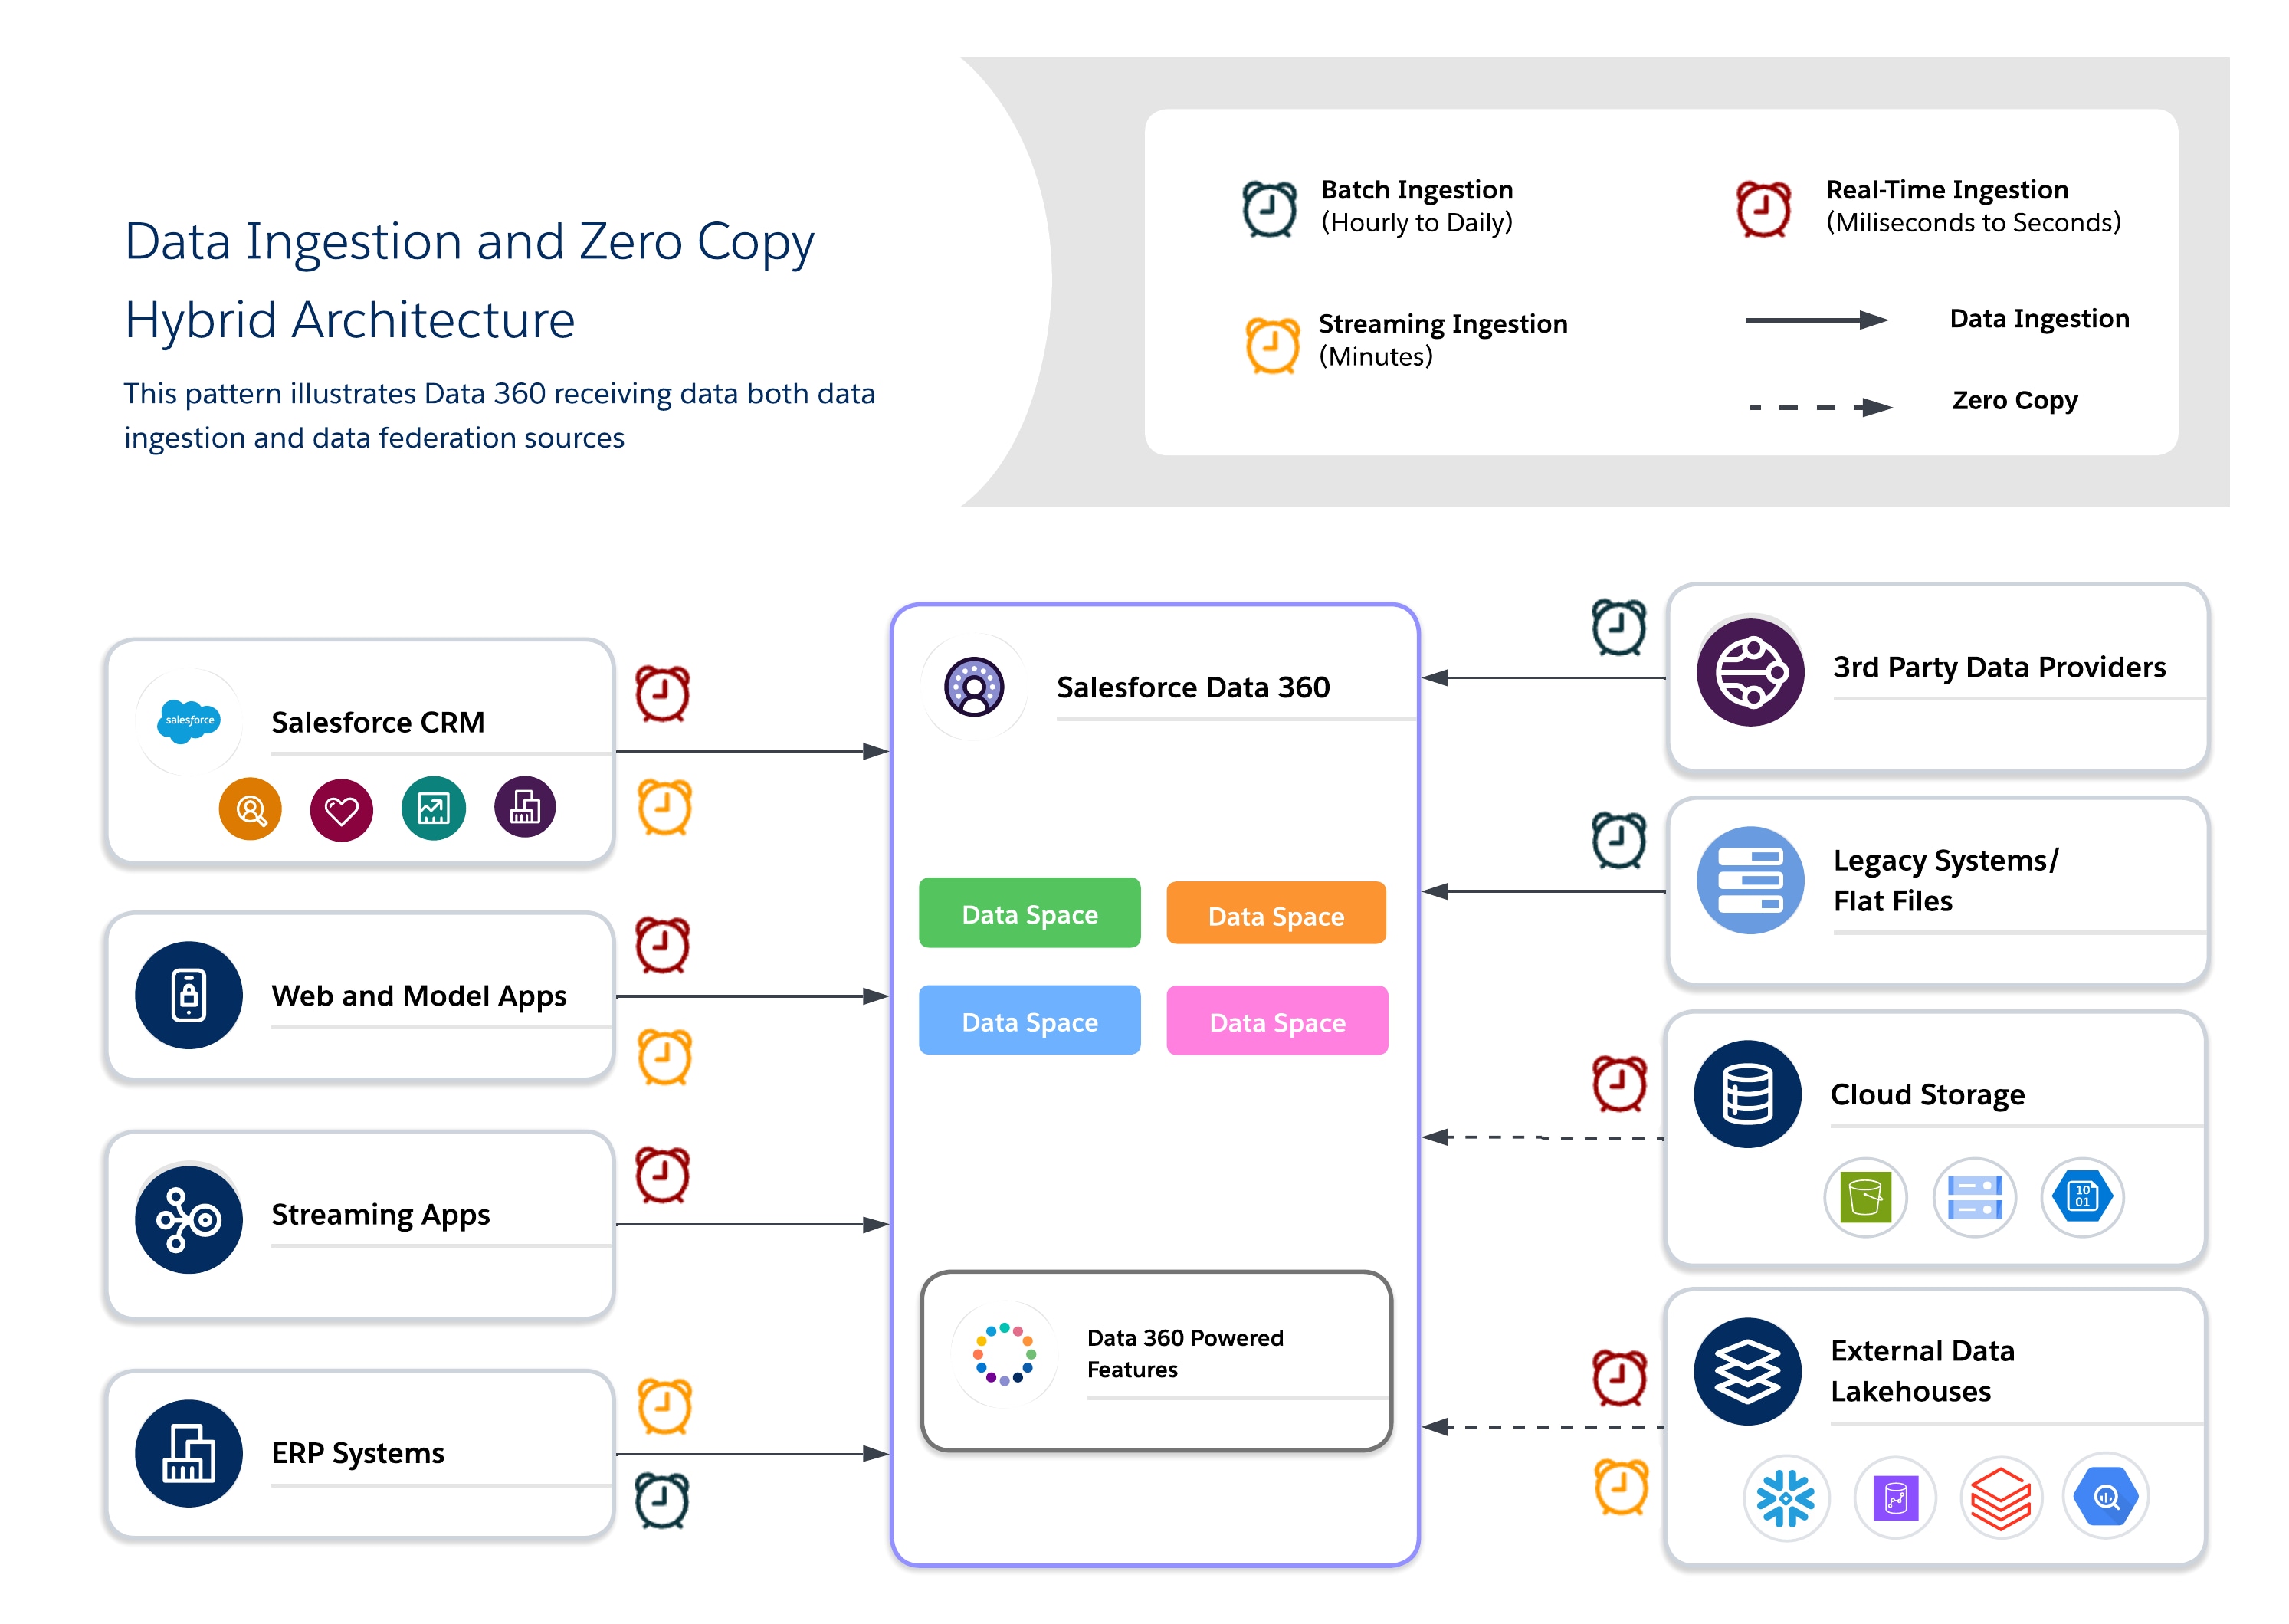
Hybrid architectures enable architects to anchor critical datasets in _Data 360_ for centralized governance while also leveraging federated queries for freshness, reduced duplication, and scalable access to large, external datasets. This approach balances I/O, compute locality, cost, and compliance requirements.
#### Hybrid Use Cases
Use a hybrid approach for balanced governance, freshness, and operational efficiency by combining data ingestion and zero copy to deliver real-time, actionable insights. Use ingestion for high-value, regulated datasets where traceability, RLS, and masking are required, and federation for ephemeral or high-volume datasets where freshness and performance are key.
 #### Architect Playbook
- **Use Cases**
- **Omni-channel engagement\:** Blend historical customer data with real-time behavior to deliver consistent, context-aware experiences.
- **AI/ML pipelines\:** Train models on curated, canonical datasets while enriching them with raw or real-time signals from external sources.
- **Mixed compliance and agility needs\:** Apply strict governance for sensitive data, and federation for operational agility.
- **Industry Scenarios**
- **Retail\:** Use _ingestion_ for identity resolution and profile unification, and _federation_ for real-time offers and personalization.
- **Healthcare\:** Maintain golden patient records via _ingestion_ while using _federation on_ IoT device streams and sensor data for immediate context.
- **Financial Services\:** Ingest regulated data into a compliance-governed lake while using _federation_ for external fraud-detection and risk-monitoring queries.
- **Design Practices**
- **Anchor Governance with Ingestion\:** Ingest high-value or regulated data into canonical models to ensure trust and compliance.
- **Use Federation for Freshness\:** Allows external lake houses to provide real-time or large-scale data access without duplication.
- **Balance Cost vs. Performance\:** Profile workloads to determine when to use _ingestion_ vs. _federation_, which minimizes unnecessary storage and query costs.
- **Apply Layered Governance\:** Enforce centralized governance for ingested data while leveraging the federated systems security controls (for example, RLS and masking).
- **Note\:** When you're designing hybrid pipelines, it's important to ensure incremental ingestion for historical datasets and push aggregations or filters to federated sources to optimize I/O and compute usage.
- **Cost Considerations**
- Weigh the total cost vs. performance by combining _ingestion_ for compliance or critical data with _federation_ when freshness is necessary.
- Account for I/O and compute distribution when mixing _ingestion_ and _federation_. To reduce the compute cost of repeated queries against source systems, use caching (Accelerated Query) for high-read, frequently-accessed federated datasets.
- Use this rule to guide the ingestion vs. federation decision\: when data is accessed frequently but changes infrequently, _Accelerated Query_ is typically more cost-effective. However, when data changes frequently (relative to access frequency), _Live Query_ or _ingestion_ is more appropriate. Here are a few cost examples\:
- **Acceleration wins\:** A dashboard that's built from 1M records and updated daily with \~10K changes is viewed 20 times per day. _Acceleration_ costs equate to roughly \~600 credits/month vs. \~4,200 credits/month for _Live Queries_.
- **Live Query wins\:** Segments that are published 20 times per day using data that changes every 30 minutes. _Live Queries_ cost roughly \~4,200 credits/month vs. \~28,800 credits/month for _acceleration_ at this refresh frequency.
## Use Case Decision Guide
Let's take a closer look at a few common archetypes that illustrate how to apply this logic.
- **The "Single Source of Truth" Archetype\: Centralize and Govern**
- **Scenario\:** You need to build compliant, unified _Customer 360_ profiles for your entire global enterprise. The data comes from a dozen different systems, it must adhere to strict _GDPR_ and _CCPA_ regulations, and it will serve as the source of truth for all marketing and service interactions.
- **Recommended Pattern\:** **Data Ingestion.** The priority here is governance, trust, and control. Ingesting the data into _Data 360_ is the only way to create a fully auditable, canonical profile that's insulated from the source systems.
- **The "Real-Time Insights" Archetype\: Analyze Without Moving**
- **Scenario\:** Your data science team needs to run exploratory queries on a massive, constantly updating transaction table in _Snowflake_. At the same time, your executive team wants a live _BI_ dashboard that's powered by that same data. Moving petabytes of data daily is slow and expensive.
- **Recommended Pattern\:** **Zero Copy Federation.** The priority here is speed, agility, and cost-efficiency at scale. _Zero Copy_ allows you to leverage the power of your existing data warehouse for real-time queries without the overhead and latency of data duplication.
- **The "Hybrid Intelligence" Archetype\: Govern the Core, Federate the Edge**
- **Scenario\:** You want to enrich your governed, ingested customer profiles with real-time behavioral signals (for example, website clicks) from a data lake. You need the stability of the core profile but the immediacy of the live data to power in-the-moment personalization.
- **Recommended Pattern\:** **A Hybrid Approach.** Use _Data Ingestion_ to create a stable, governed core for your customer data. Use _Zero Copy_ to federate the volatile, real-time "edge" data, and then join them together at query time for a complete, up-to-the-second view.
## The Path Forward
Enterprise data strategy is no longer focused on choosing a single integration pattern—it's about architecting controlled flexibility within an interoperable data ecosystem. The correct approach maps each source system to the pattern that best suits its freshness, governance, cost, and access requirements\:
- Ingest mission-critical, regulated datasets into Salesforce _Data Cloud_ for compliance, identity resolution, and operational workflows.
- Federate data via _Zero Copy_ for live, exploratory, and AI-driven analytics without duplicating storage.
- Apply _Caching (Accelerated Query)_ to reduce source system load and credit consumption when query frequency is high and data change frequency is low
Salesforce _Data 360_ on _Hyperforce_ delivers multi-region resilience and scalability. Its open lake house with _Iceberg_ tables enables computation separation and interoperability with platforms like _Snowflake_, _Databricks_, and _S3 Iceberg, which_ forms the backbone of a truly interoperable, multi-cloud data ecosystem.
As data ecosystems evolve, we must continuously balance freshness, cost, performance, and compliance to maintain architectural agility. That's why it's important to future-proof your platform by unifying ingested, governed data with federated access. This enables real-time intelligence, AI activation, and enterprise-scale personalization across Clouds, regions, and business domains.
Keep in mind that one-size-fits-all solutions don't suit most businesses. The optimal strategy maps the correct pattern to the correct business driver.
## About the Authors
**Yugandhar Bora** is a Software Engineering Architect at Salesforce who specializes in data architecture within the Data and Intelligence Applications platform. He leads _enterprise architecture review board (EARB)_ initiatives that focus on data governance and unified data models while also contributing to automated platform provisioning solutions.
**Jan Fernando** is a Principal Architect in the _Office of the Chief Architect (OCA)_ at Salesforce who joined Salesforce in 2012\. He brings a wealth of experience from his time in the startup ecosystem. Prior to joining the OCA, he spent over a decade in the _Platform_ organization, where he led several key technology transformations.